AWS Parallel Computing Service
Managed high performance computing at virtually any scale
Why AWS PCS?
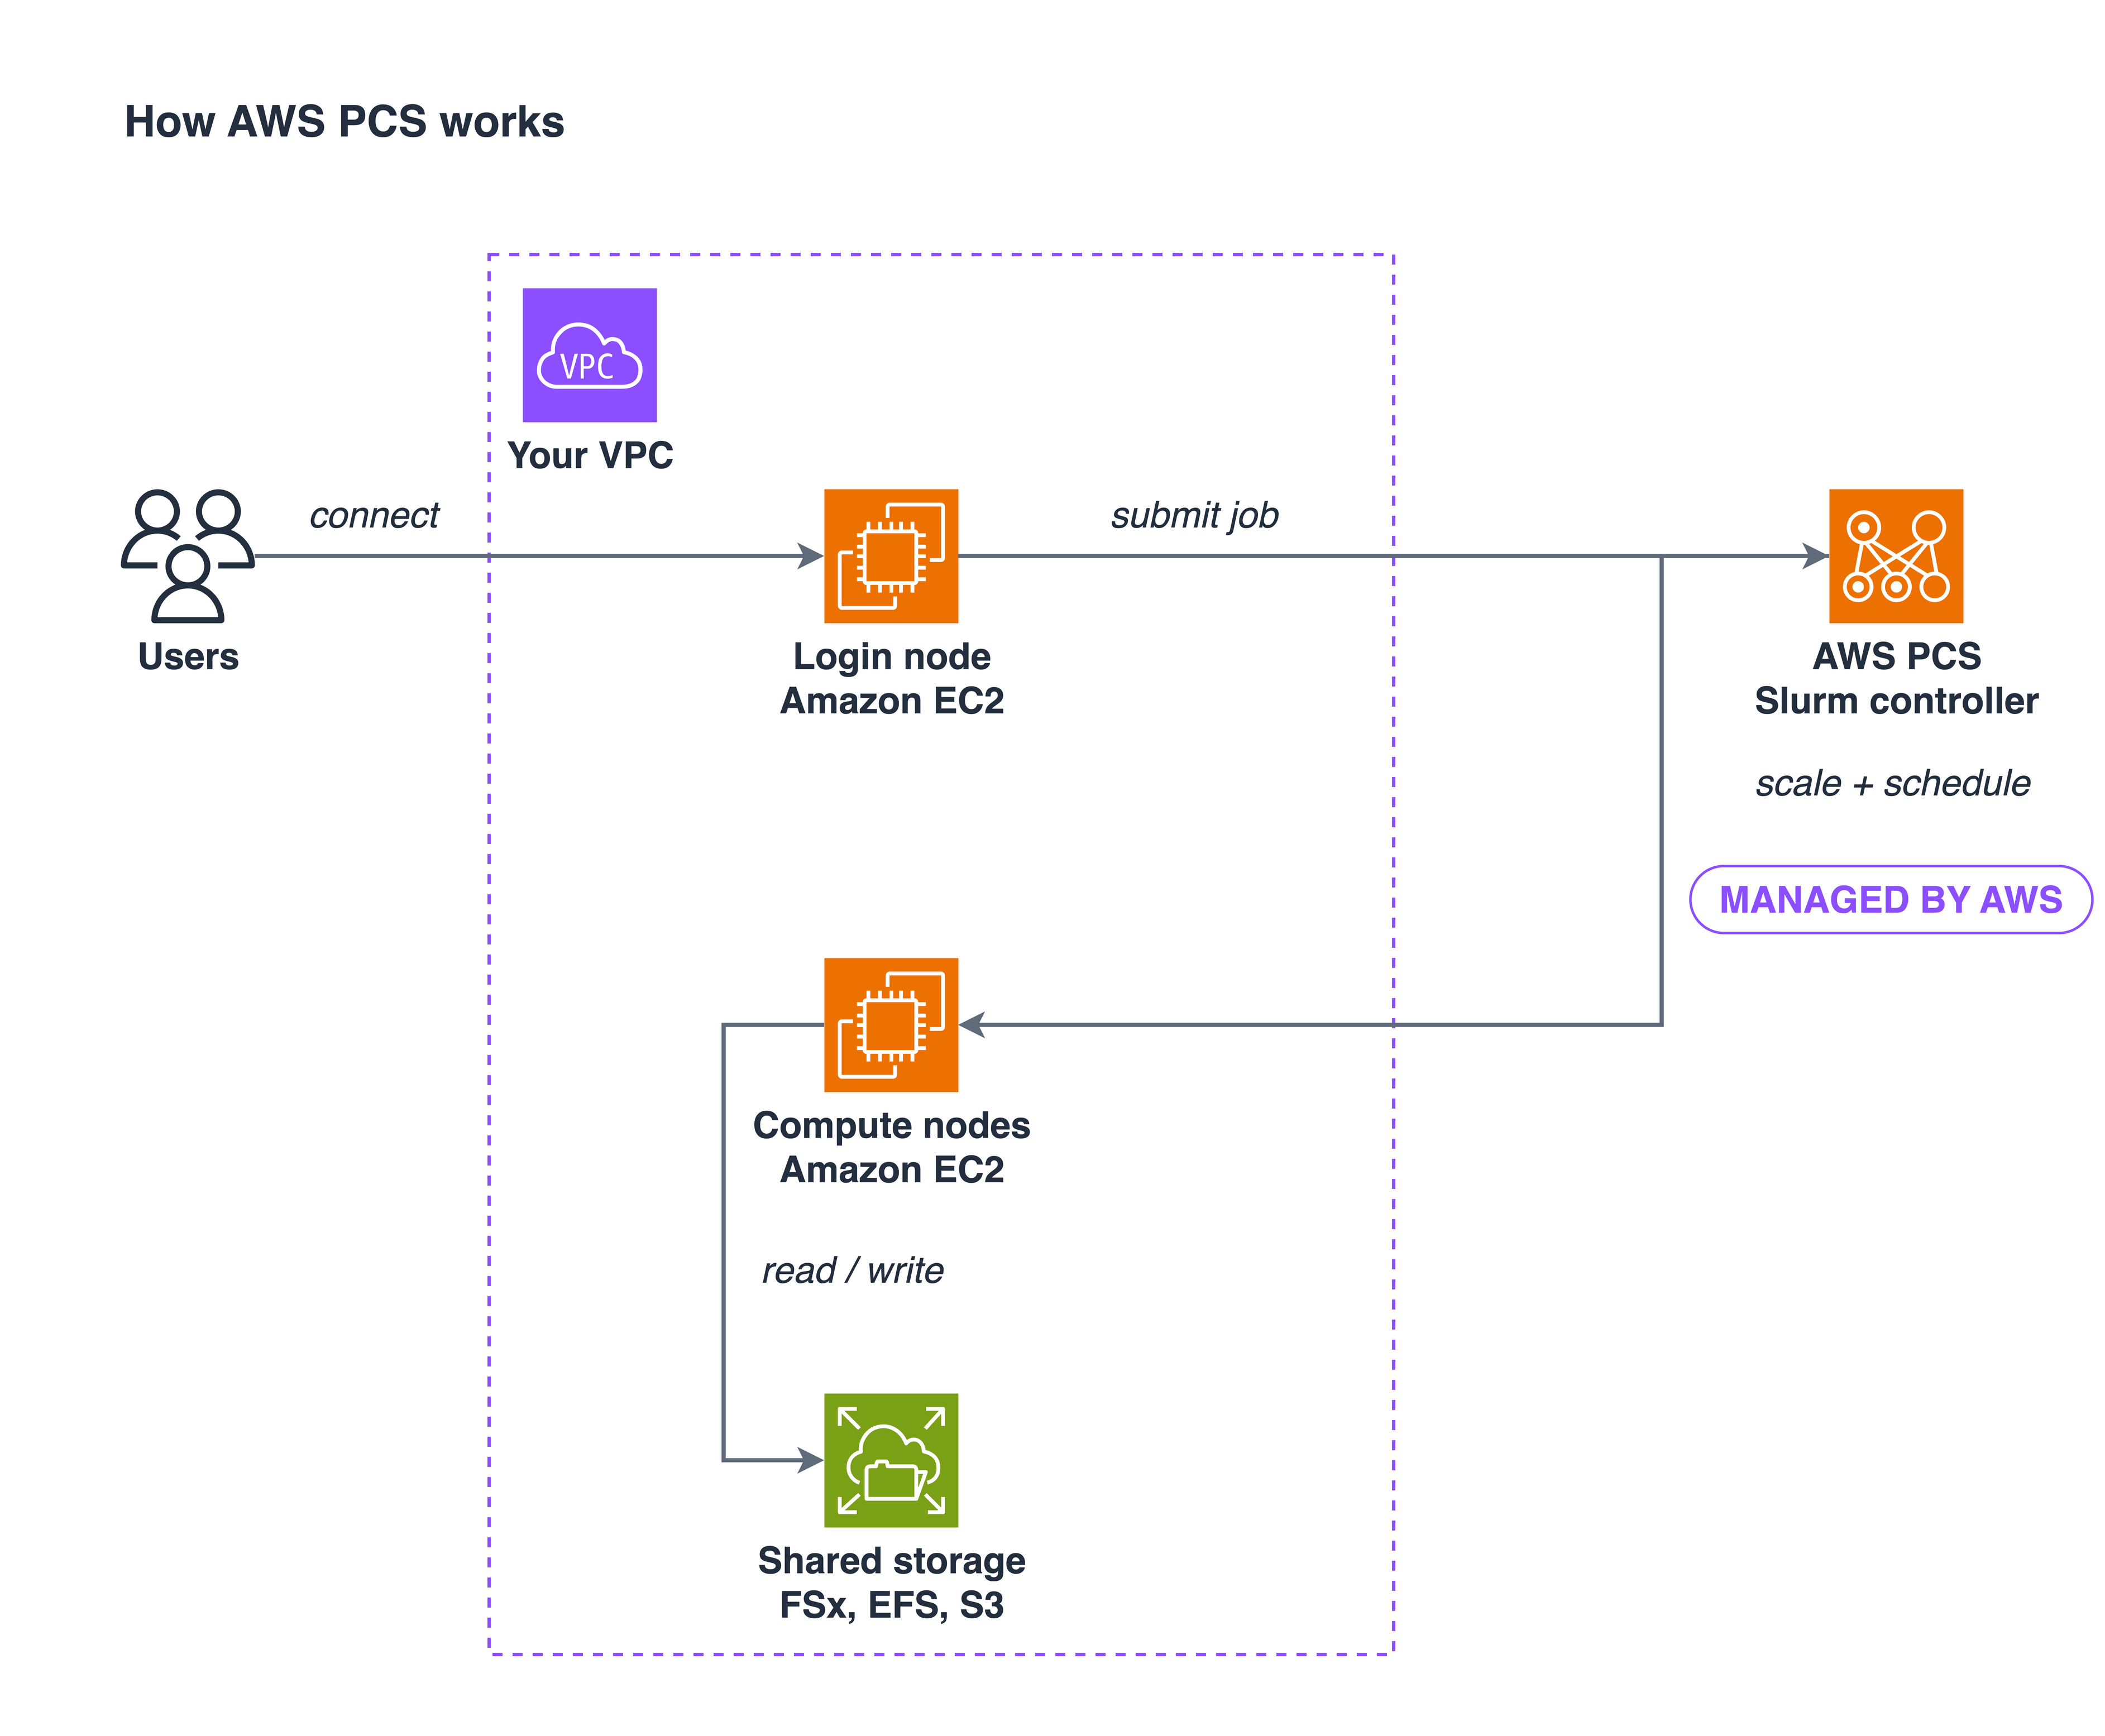
AWS Parallel Computing Service (AWS PCS) runs Slurm-based high performance computing (HPC) workloads on AWS without the operational overhead. AWS PCS runs and maintains the cluster control plane on your behalf, so you can focus on running your workloads rather than managing infrastructure. It monitors cluster health and fixes common issues automatically. You keep full control of the Amazon EC2 instances your cluster uses, and you can connect other AWS services for compute, storage, networking, and visualization. Your teams work in a familiar HPC environment and use the tools they already know.
Benefits
Use cases
Run engineering simulations
Train and fine-tune AI and ML models
Accelerate scientific research
Run financial risk and quantitative analysis
Design semiconductors and hardware (EDA)
Customers
Aionics
Aionics moved its computational chemistry clusters from AWS ParallelCluster to AWS PCS in August 2025. It runs separate CPU and GPU Slurm clusters so its team can focus on battery electrolyte research instead of infrastructure.
Tune Therapeutics
“Using AWS PCS, we can make decisions far more rapidly, which is critical for a biotech company.”
Harry Winters, Senior Software Engineer, Tune Therapeutics
Daiichi Sankyo
“AWS Parallel Computing Service gives us a sustainable, flexible HPC environment for drug discovery with far less administrative overhead, and it frees our researchers to focus on the science rather than managing infrastructure.”
Source: How Daiichi Sankyo modernized drug discovery using AWS Parallel Computing Service | AWS HPC Blog
Shell
“AWS PCS has changed how we approach high-performance computing. We spend less time managing infrastructure and more time innovating, spinning up capacity the moment we need it and delivering results 3-5x faster than before.”
Amazon Leo
“We migrated our EDA chip-design workloads from a managed LSF cluster to AWS PCS with Slurm, and it was more straightforward than we expected. Our biggest problem was compute power and scaling with so many jobs running — and that problem is completely gone. PCS just scales up when we need it, and we've cut costs by 30%, improved performance by 4x, and reduced operational overhead by 90%.”
Ekjot Basra, Amazon Leo Silicon Development