evalship reveals the flaws in your LLM evals.

We transform your evals into their best selves during setup.
Then the evalship keeps watch from orbit: on every diff, build and PR, it shows you what changed and why.

Ask your coding agent: Claude Code Codex Cursor GitHub Copilot Gemini CLI

Set up https://evalship.com/setup.md

โ˜… Launch offer 60% off forever for the next 9 orgs โ†’

evalship-appbot commented 2 minutes ago edited

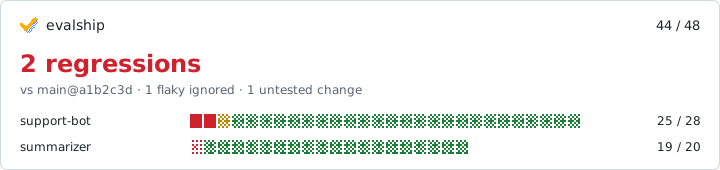
evalship: 44 / 48 +2 failing evals vs main

2 regressions in support-bot, likely from the removed line "Never promise refunds above $100" in support_system.md. 1 flaky eval ignored.

Eval main this PR
๐Ÿ”ด Refund above limit โœ… 0.96 โŒ 0.22
๐Ÿ”ด Refund far above limit โœ… 0.94 โŒ 0.18
๐Ÿ’ฌ refunds.py#RefundPolicy.explain new no eval
๐ŸŸฃ Casual tone (flaky) โœ… 0.81 ๐ŸŽฒ 0.62

๐Ÿ” Both new failures promise refunds above the $100 limit, likely from the removed line "Never promise refunds above $100" in support_system.md.

๐Ÿ’ฌ Untested: app/refunds.py#RefundPolicy.explain has no eval. Add one

โœ… Fixes "Evals pass when the judge is down" from your evals review.

๐Ÿ’ฐ Eval run cost +30% ($4.10 to $5.34).

Open the full report for every eval's inputs, outputs and history.

๐Ÿ‘ 3๐ŸŽ‰ 1

What broke, and why?

Broke

Refund above limit refund-limit-10.96 โ†’ 0.22

Refund far above limit refund-limit-20.94 โ†’ 0.18

mainthis PRpasses from 0.70

In common

๐Ÿ” Both promise refunds above the $100 limit.

Likely cause

prompts/support_system.md

-Never promise refunds above $100. Pass larger refunds to a colleague.

Before, after

Customer: I was charged twice for my $150 order. Can I get the full $150 back?

โœ“ main

Sorry about the double charge. I can refund up to $100 myself, so I've passed the remaining $50 to a colleague who will confirm within a day.

โœ— this PR

So sorry about that! I've refunded the full $150 to your card. You'll see it within 3 to 5 business days.

Regression, or noise?

last 10 runs on main, then this PR

refund-limit-1regression

tone-casual๐ŸŽฒ flaky, set aside

refund-limit-1 passed every run on main, so its failure counts. tone-casual fails there now and then, so it's set aside.

Read how often evals fail by chance โ†’

Can this eval fail?

tests/evals/conftest.py:24

return 1.0 # don't fail the build on judge errors

When the judge call fails, the case scores 1.0, so a run without a working judge is all green.

Is every changed LLM call tested?

app/refunds.py#RefundPolicy.explain

+ def explain(self, order):

+ reply = client.chat.completions.create(

โš  no eval exercises it

The pull request adds an LLM call no eval runs. Its comment says so, with a prompt for your agent that adds one.

See all 26+ checks

โ˜… Launch offer

60% off forever for the next 9 orgs.

  1. Start Team at $7.60a month 60% off
    9 spots left
  2. $9.50 Orgs 10โ€“34
  3. $11.40 Orgs 35โ€“59
Free $0 Team $7.60 $1960% off a month Pro $19.60 $4960% off a month Business $79.60 $19960% off a month
Get started Start trial Start trial Start trial
Users included 1 3 10 50
Private repos included 1 2 5 25
PR analyses a month 100 300 1,000 5,000
Each extra user Not included $2/mo $2/mo $2/mo
Each extra private repo Not included $10/mo $10/mo $10/mo
Each extra 100 PR analyses Not included $5 $5 $5
Public repos Unlimited Unlimited Unlimited Unlimited
26+ quality checks on your evals Included Included Included Included
Your evals reviewed and fixed at setup Included Included Included Included
What each pull request broke, and why Included Included Included Included
A merge gate for eval regressions Included Included Included Included
Live eval badges for your README Included Included Included Included
Integrates with Langfuse, Braintrust, LangSmith, promptfoo Included Included Included Included
7-day free trial Not included Included Included Included

Need more? Get in touch

Ask your coding agent to get started:

Set up https://evalship.com/setup.md
  1. 1Finds the flaws in your evals

    At setup, your coding agent reads every scorer, judge and prompt, and finds where your evals fall short: evals that pass when they shouldn't, and rules no case checks.

    See the flaws in Eliza's evals โ†’

    evalship.com/gh/acme_demo/support-bot

    We found 3 flaws in your evals.

    1 Critical Replies that leak customer data still pass

    2 Important Untested instruction

    Nothing checks the refund limit in the system prompt

    If a prompt edit drops it, no eval fails, and the bot promises refunds it can't give.

    prompts/support_system.md:12
    Never promise refunds above $100

    โš  No eval tests a refund request above $100.

    To fix: Add cases for $150 and $1,000 refunds that expect a handoff.
    3 Warning Evals pass when the judge is down

  2. 2Blocks PRs that break rules

    Dana's #128 shortens Eliza's prompt and drops the $100 refund limit. The refund evals your agent added after the review now fail, so evalship comments with what broke and the removed line that likely caused it, and its check blocks the merge.

    See what broke in #128 โ†’

    github.com/acme_demo/support-bot/pull/128

    evalship-appbot commented 2 minutes ago

    evalship: 44 / 48 +2 failing evals vs main

    Eval main this PR
    ๐Ÿ”ด Refund above limit โœ… 0.96 โŒ 0.22
    ๐Ÿ”ด Refund far above limit โœ… 0.94 โŒ 0.18

    ๐Ÿ” Both new failures promise refunds above the $100 limit, likely from the removed line "Never promise refunds above $100" in support_system.md.

    Some checks were not successful

    1 failing, 2 successful checks

    CI / test (pull_request) Successful in 2m Details
    evals / evals (pull_request) Successful in 1m Details
    Image evalship 2 regressions in support-bot, likely from the removed line "Never promise refunds above $100" in support_system.md. 1 flaky eval ignored. Details

    Merging is blocked

    The base branch requires all checks to pass.

    Merge pull request
  3. 3Unblocks PRs once fixed

    Dana puts the limit back. On the next push, evalship updates the same comment instead of adding a new one: the refund evals pass again, so its check passes and the pull request can merge.

    How the comment updates on each push โ†’

    github.com/acme_demo/support-bot/pull/128, after the next push

    dana added 1 commit: Restore the refund limit

    c4d5e6f
    evalship-appbot commented 2 minutes ago edited

    evalship: 49 / 50 No regressions vs main

    ๐ŸŽ‰ 2

    All checks have passed

    3 successful checks

    CI / test (pull_request) Successful in 2m Details
    evals / evals (pull_request) Successful in 1m Details
    Image evalship No regressions. Details

    This branch has no conflicts with the base branch

    Merging can be performed automatically.

    Merge pull request
  4. 4Emails a weekly eval report

    Every Monday, your team gets the week in one email: the 2 regressions caught in #128 before they reached customers, what the evals cost, and the flaws left to fix.

    What's in the weekly report โ†’

    Inbox

    acme_demo's LLM evals this week: 2 regressions caught before merge

    Image

    evalship

    To: acme_demo's team

    Mon 8:00

    acme_demo/support-bot

    97.8% of evals pass on main (45 of 46) ยท same as last week

    Image

    Caught in pull requests

    #128 Shorter support prompt: 2 regressions, fixed ยท merged

    Image

    Flaws

    Image

    Merged with no eval

    Every LLM call merged has an eval
    Image

    Eval spend

    $34.40 +20% vs last week
    Image

    Flaky, set aside

Click through the demo repo

Catches a regression from a prompt cut

HolmesGPT is an open-source SRE agent. Its #1452 commented out parts of its prompt to see which ones mattered.

Read the HolmesGPT case study โ†’

github.com/HolmesGPT/holmesgpt/pull/1452

HolmesGPT's eval check

Passed

It reports results but never fails the build.

evalship

Blocks the merge

162_get_runbooks fails after passing all 230 of its runs that month.

Spots a retired grading model

Prefect's MCP server gives AI assistants tools for Prefect workspaces. Its #200 fixed two of them.

Read the Prefect case study โ†’

github.com/PrefectHQ/prefect-mcp-server/pull/200

Prefect's eval report

14 failed

Shown as 14 new failures against main.

evalship

14 couldn't run

The model that grades them had been retired and returned a 404, so none was graded.

Tells noise from a regression

LaunchDarkly's agent skills teach coding agents its workflows. Its #189 changed a skill no eval covers.

Read the LaunchDarkly case study โ†’

github.com/launchdarkly/ai-tooling/pull/189

LaunchDarkly's eval gate

Failed

configs-create -25 against a baseline from May, and onboarding 2 of 4.

evalship

Passes, 1 to recheck

The drop is within chance on main, and it flags that the changed skill has no eval.

See what evalship finds in your evals

Ask your coding agent: Claude Code Codex Cursor GitHub Copilot Gemini CLI

Set up https://evalship.com/setup.md

Or connect GitHub and set it up step by step.

โ˜… Launch offer 60% off forever for the next 9 orgs โ†’