We're building search into a Java music library with plain Lucene, one step at a time.
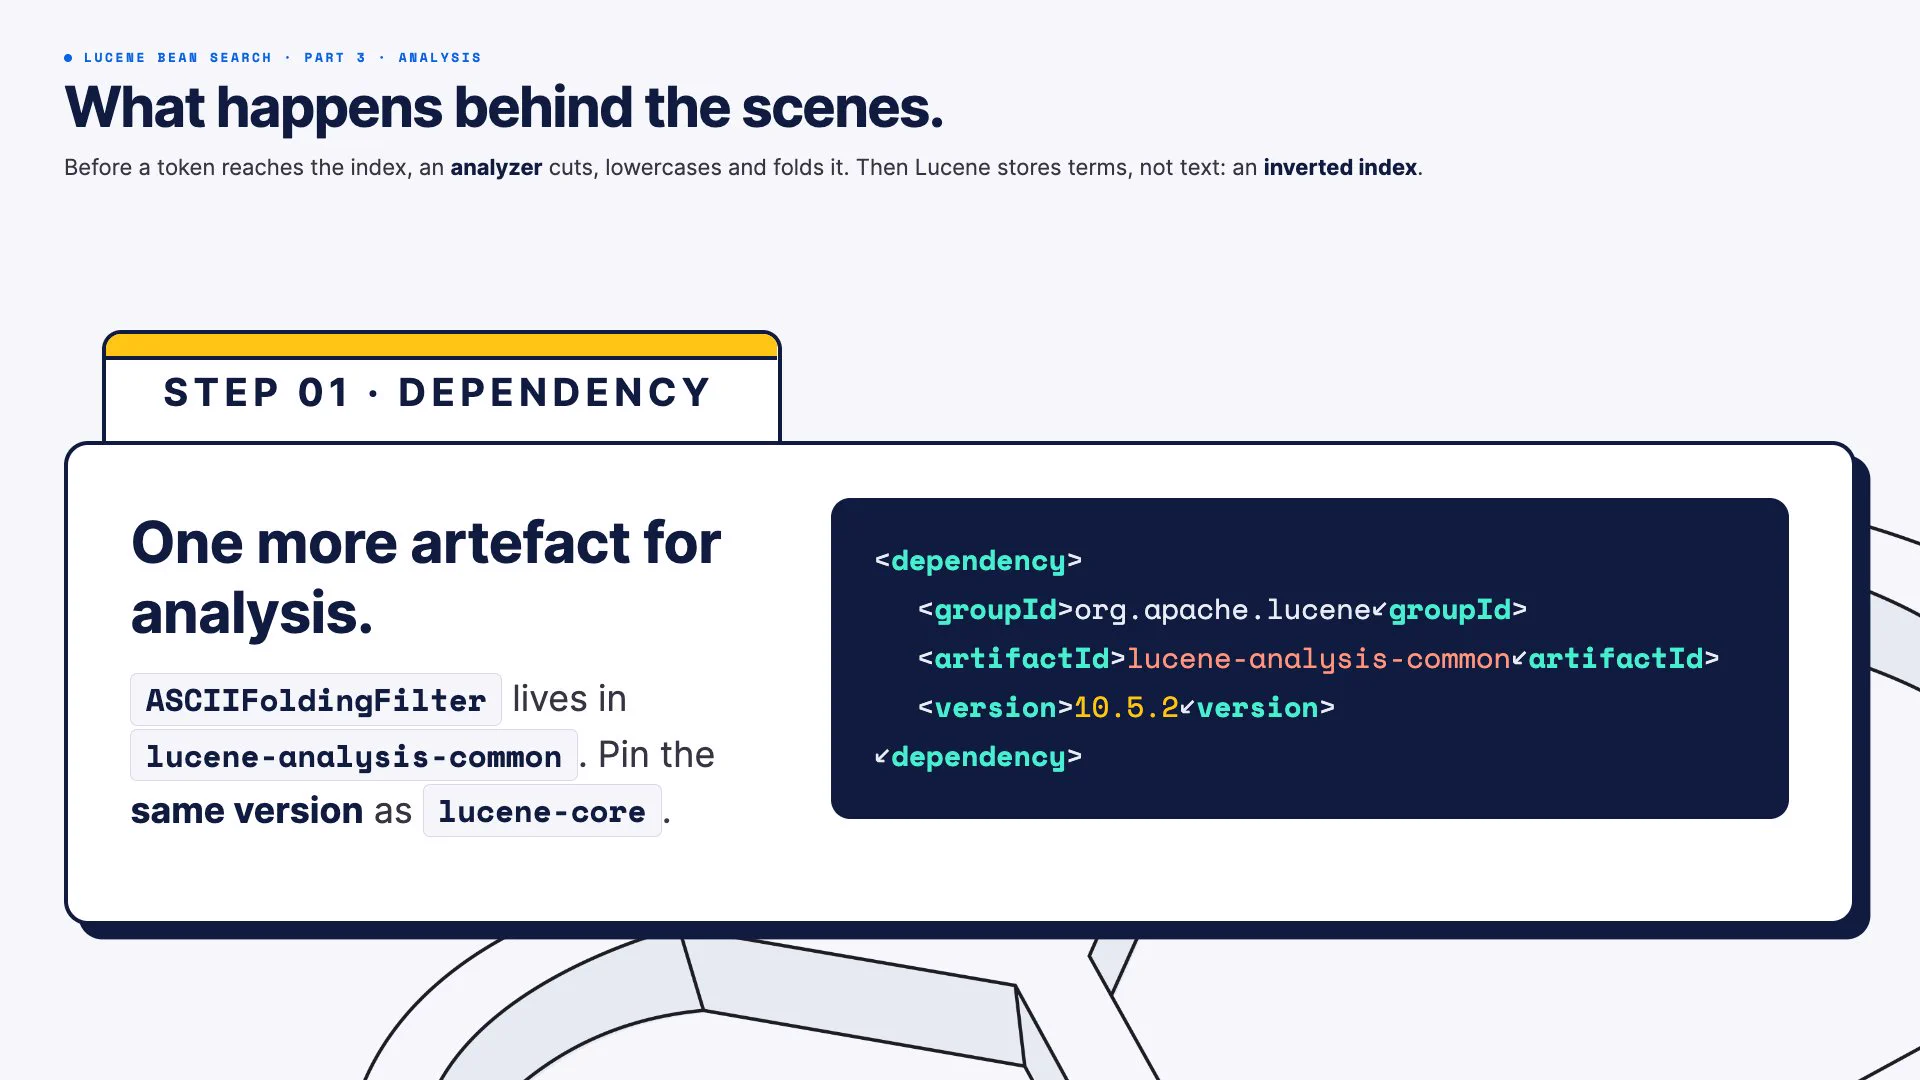
Next up is analysis: what happens to your text before it reaches the index. An analyzer cuts it into tokens, lowercases them and folds the accents away.
Step 1: add lucene-analysis-common for
Your beans are mapped. Now, who owns the index?
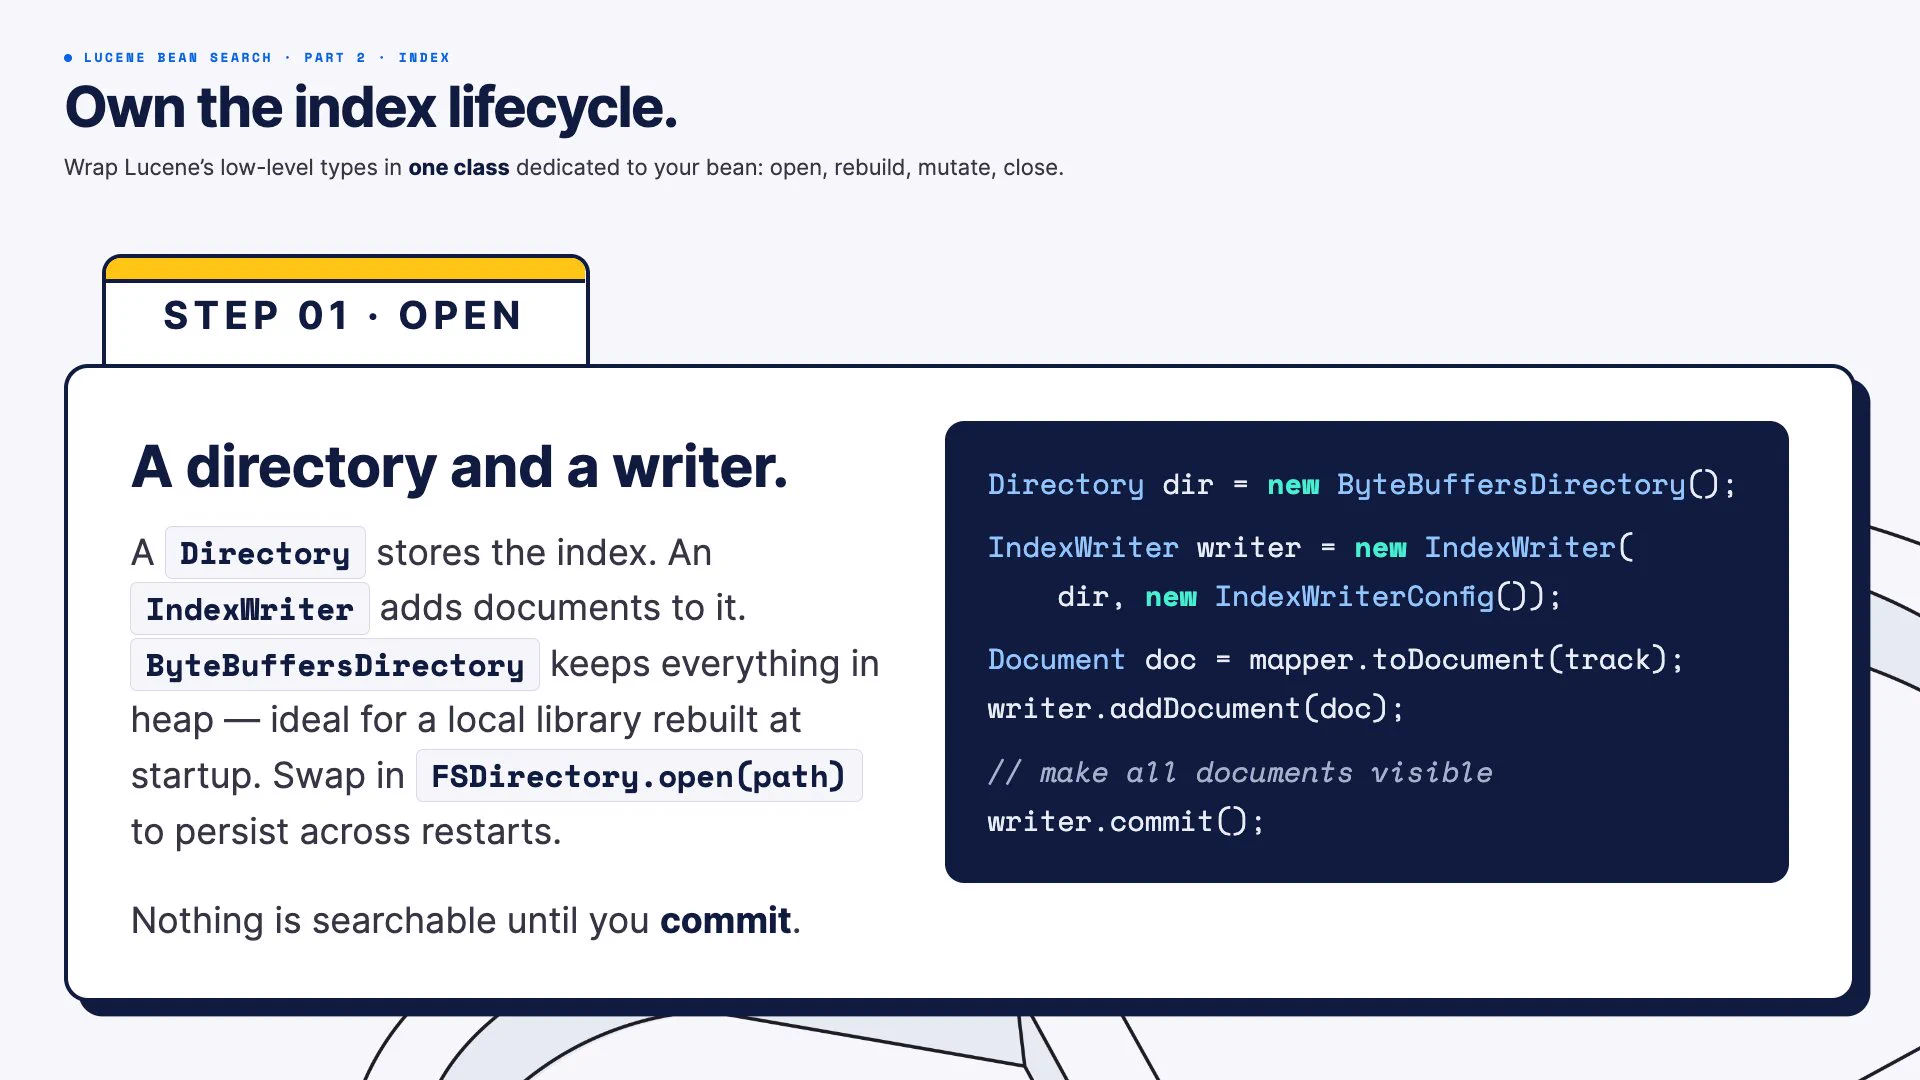
Step 1: wrap Directory + IndexWriter in a small class dedicated to your bean.
ByteBuffersDirectory for in-memory, FSDirectory to persist
Your beans are mapped. Now, who owns the index?
Step 1: wrap Directory + IndexWriter in a small class dedicated to your bean.
ByteBuffersDirectory for in-memory, FSDirectory to persist
Get any Java bean ready for Lucene in 3 steps
You have a Track bean. You need search.
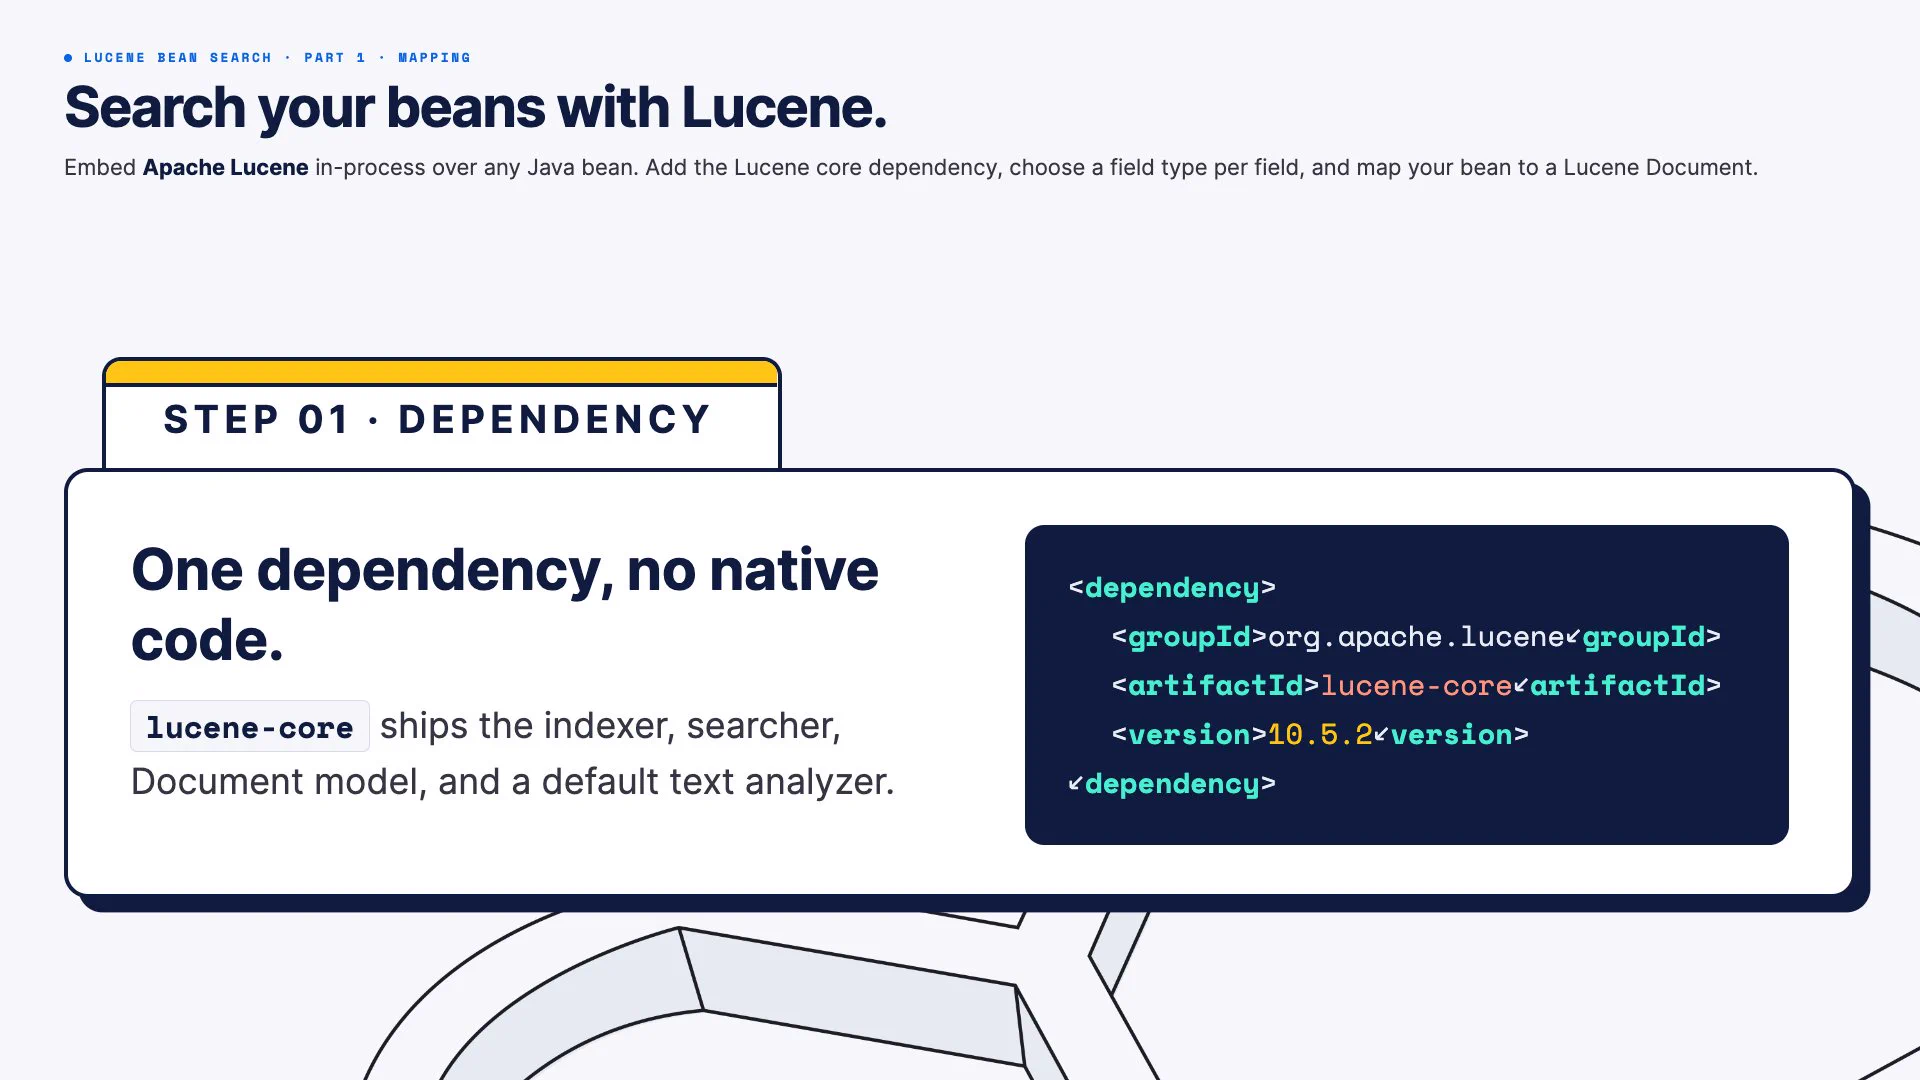
Step 1: embed Apache Lucene in-process. One dependency, no native code, no server to run.
Elasticsearch does this for you on top of Lucene. Here's what it looks like by hand 👇
Get any Java bean ready for Lucene in 3 steps
You have a Track bean. You need search.
Step 1: embed Apache Lucene in-process. One dependency, no native code, no server to run.
Elasticsearch does this for you on top of Lucene. Here's what it looks like by hand 👇