Pinned

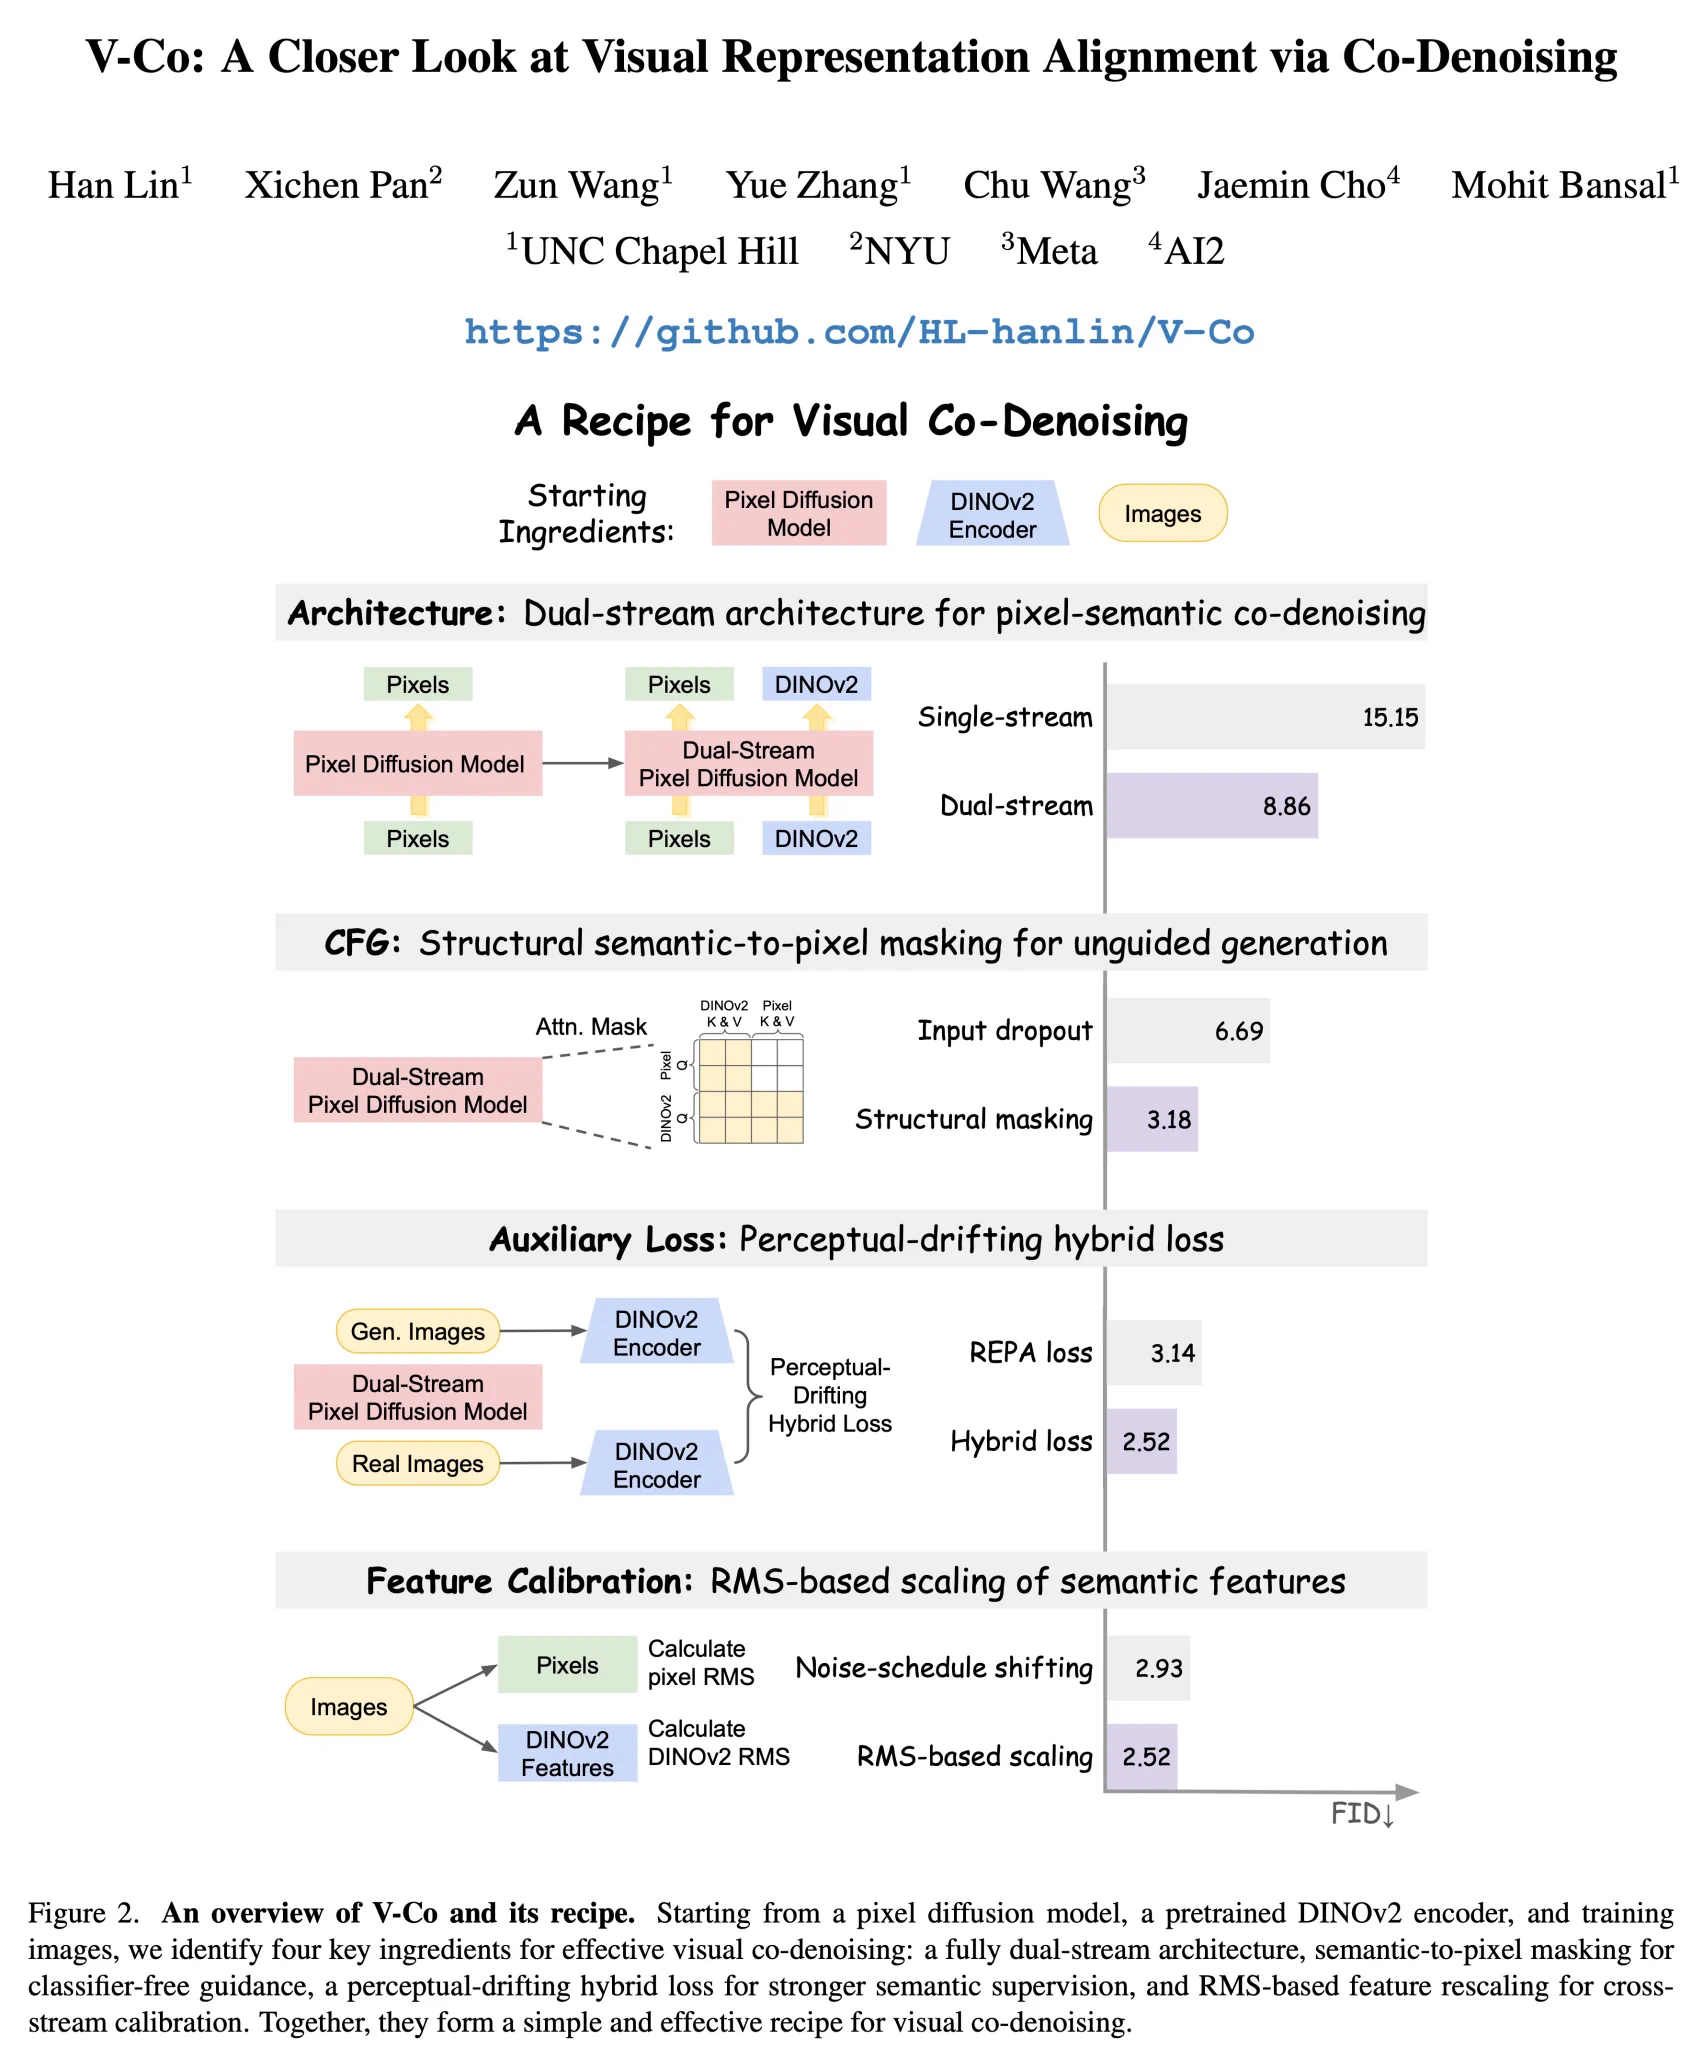
🚀 Excited to share V-Co, a diffusion model that jointly denoises pixels and pretrained semantic features (e.g., DINO).
We find a simple but effective recipe:
1️⃣ architecture matters a lot --> fully dual-stream JiT
2️⃣ CFG needs a better unconditional branch -->