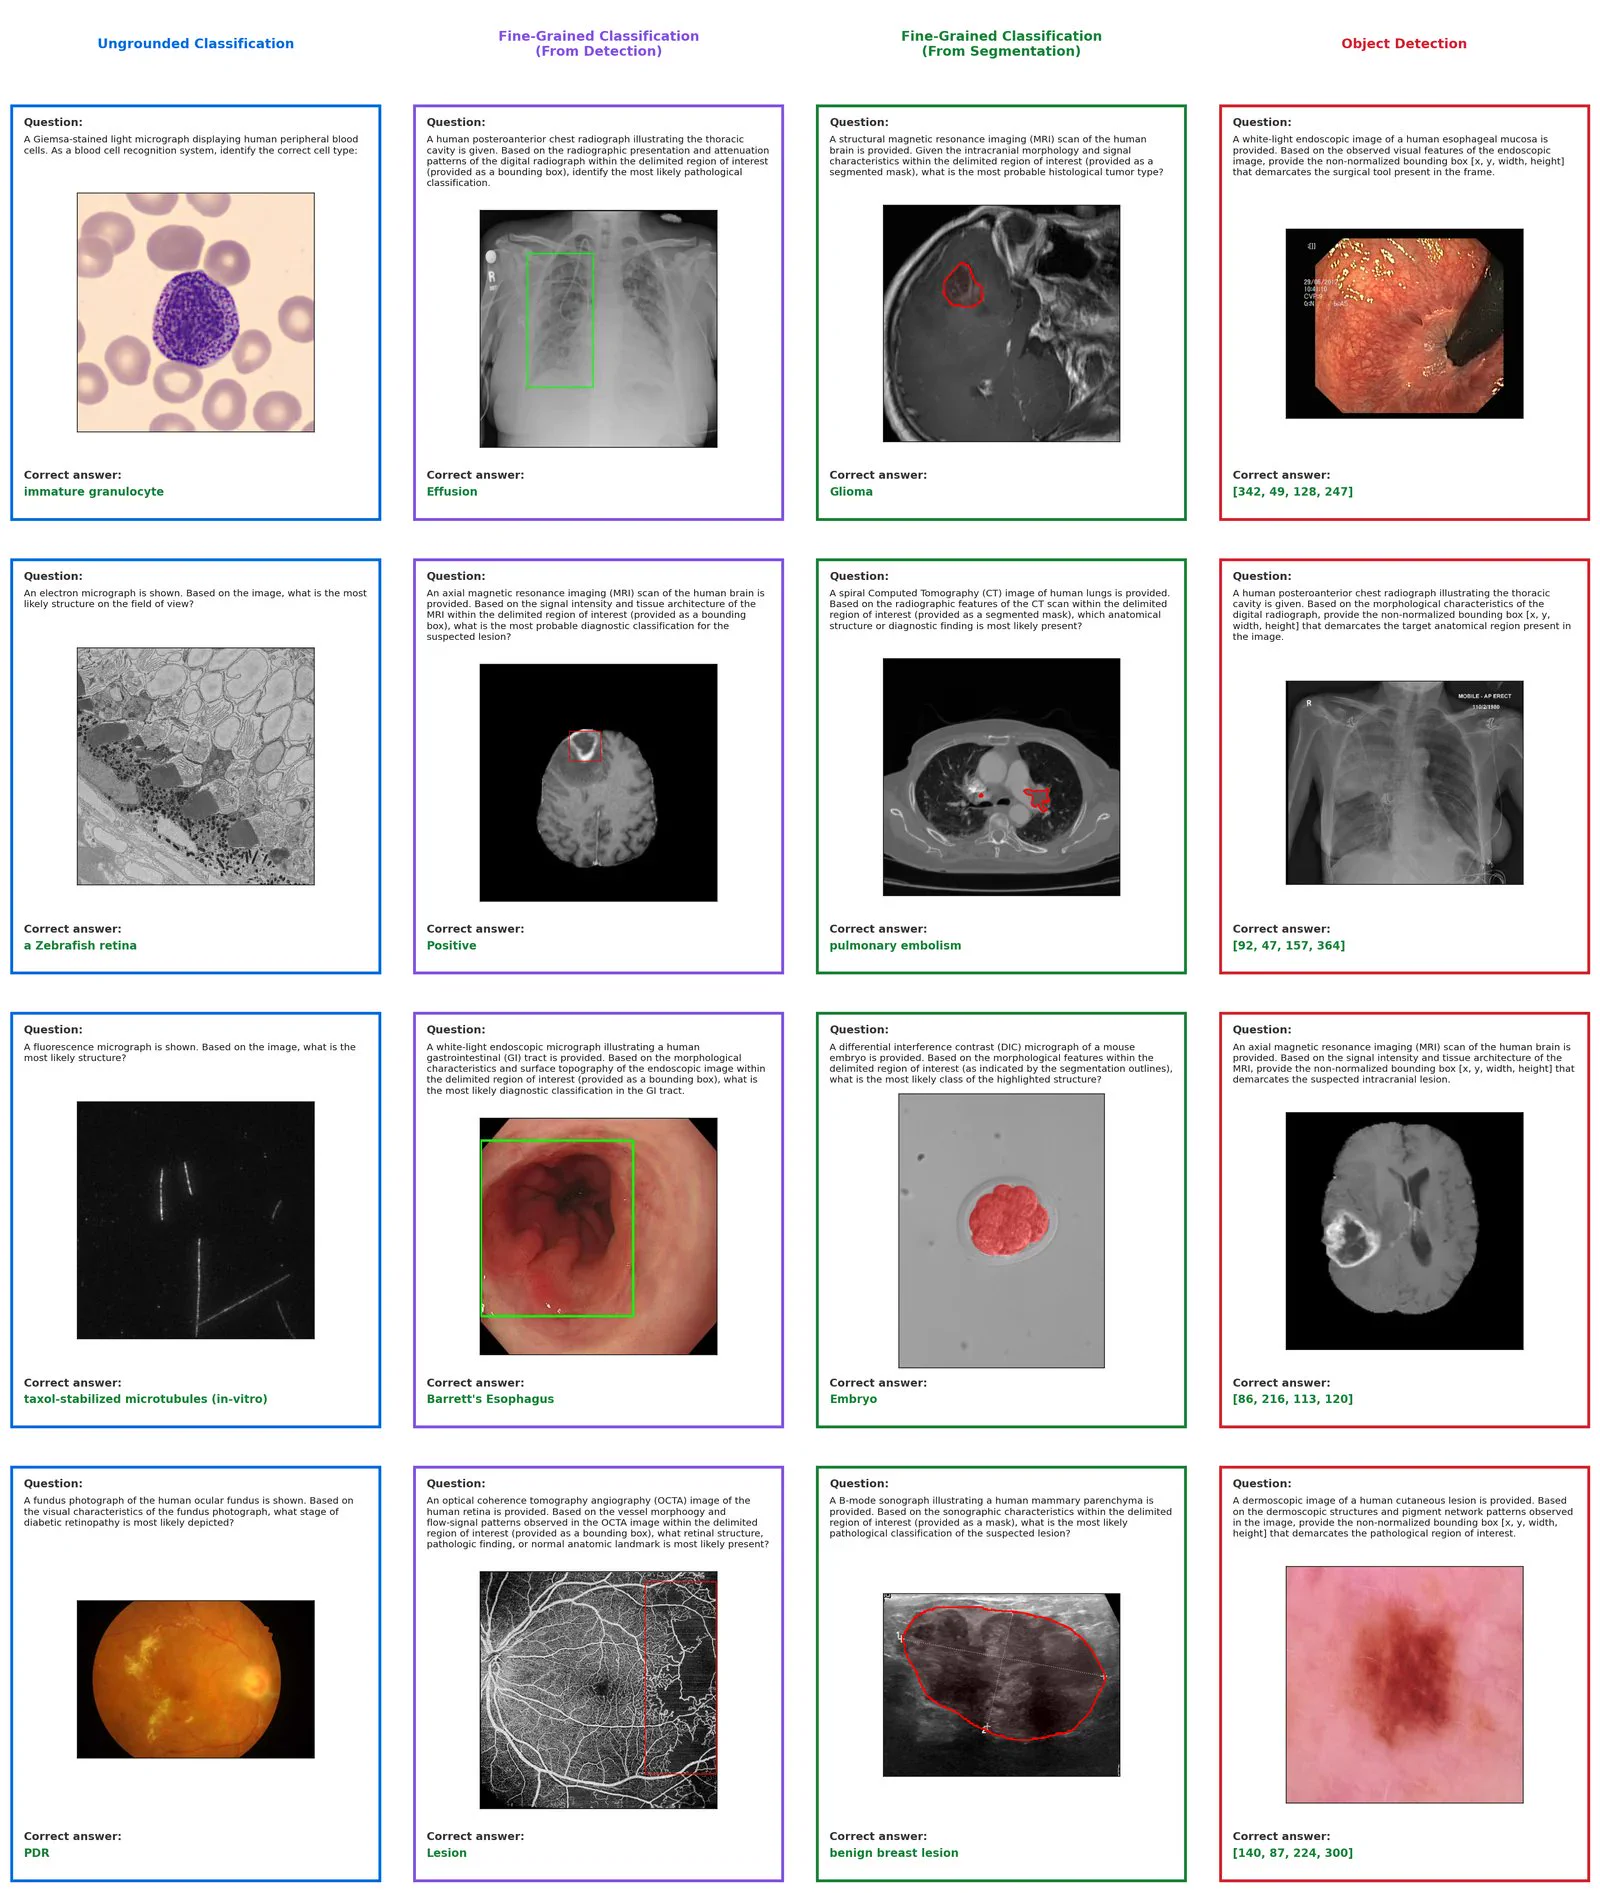
It's time to solve one of the biggest challenges in vision-language models.
Today's multimodal models can look at a biomedical image and give a convincing, sometimes correct, answer without actually understanding what they're seeing.
A model might answer the medical question