alphaXiv

Explore

Researchers

Sign In

MCP Server

Autoresearch

Browser Extension

BlogSend Feedback?

Follow the latest research

alphaXiv connects papers, researchers, and organizations, grounding its answers in the underlying work.
Sign up

Towards Looped Models Done Right Part II: Rethinking at Fixed Points

ImageCMUImageUSC
Benhao HuangBenhao HuangChufan ShiChufan Shi
EX
Eric Xing

Training looped language models to settle into fixed points enables terminal attention-cache sharing with little accuracy loss, reducing decoding memory as recurrence depth grows.

02 Oct 2026
2kviews8
Image

Finetuning with Sampling: SFT Learns Better Than You Think

ImageHarvard
Yilun DuYilun Du

Sampling expert examples to better match a model’s distribution lets supervised fine-tuning learn new skills while often preserving prior capabilities better than on-policy methods.

01 Oct 2026
536views
Image

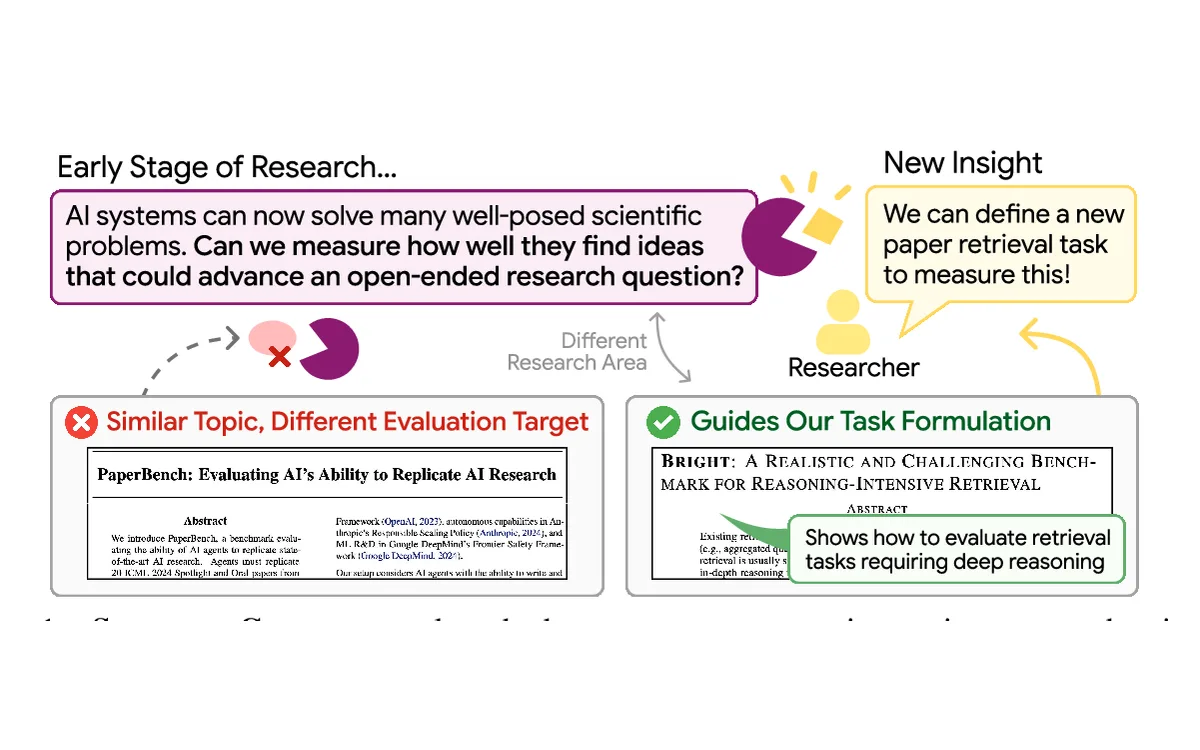
ScholarCatalyst: A Benchmark for Retrieving Papers That Inspire New Research

ImageStanford
Sohyeon KimSohyeon KimYoonho LeeYoonho LeeChelsea FinnChelsea Finn

Author-validated judgments from 184 researchers let teams test whether AI can find papers that genuinely inspire research, not merely match its topic.
01 Oct 2026
4kviews3
Image

Researchers to follow

View all
Alex L. Zhang

Alex L. Zhang

CS PhD Student

Massachusetts Institute of Technology, Research Fellow @ Prime Intellect

Yann LeCun

Yann LeCun

Executive Chairman

AMI - Advanced Machine Intelligence, Jacob T. Schwartz Professor, CS @ New York University
Li Fei-Fei

Li Fei-Fei

Co-Founder and CEO

World Labs, Founding Co-Director @ Stanford HAI, Sequoia Professor, CS @ Stanford University
Ion Stoica

Ion Stoica

Co-Founder & Executive Chairman

Anyscale, Co-Founder & Executive Chairman @ Databricks, Professor, CS @ UC Berkeley

Andrej Karpathy

Andrej Karpathy

Researcher

Anthropic

Kaiming He

Kaiming He

Distinguished Scientist

Google DeepMind, Associate Professor, EECS @ MIT

Chelsea Finn

Chelsea Finn

Co-Founder

Physical Intelligence, Assistant Professor, CS and EE @ Stanford University

Geoffrey Hinton

Geoffrey Hinton

Emeritus Professor, CS

University of Toronto

Are you a researcher? Find your profile

VISTA: A Visual Harness for Reasoning in an Interactive World

ImageMIT
Kaiming HeKaiming He

Multimodal agents can solve unfamiliar visual games more effectively when they can revisit past images and inspect details as they reason.

01 Oct 2026
215views
Image

Looped Diffusion Transformer

ImageSensetimeImageTsinghua
Ziwei LiuZiwei Liu

Repeating shared Transformer blocks lets text-to-image models refine visual constraints internally, improving generation quality without adding model parameters.

30 Sept 2026
1kviews
Image

Reconstruct, Practice, Go Real: Guided Self-Improvement for Embodied Agents

ImageUC BerkeleyImageMIT
Pieter AbbeelPieter Abbeel

Robots can improve reusable manipulation skills through simulated practice and failure feedback, raising success across 22 tasks before deployment on physical hardware.

01 Oct 2026
158views
Image

SkillRefiner: Offline Skill Refinement from Historical Agent Traces

ImageOpenHandsImageUT Austin
Anirudh KhatryAnirudh KhatryCalvin SmithCalvin SmithGraham NeubigGraham Neubig

Agents can improve reusable instructions from past successes and failures, enabling skill refinement when task replays are costly or impossible.

01 Oct 2026
2kviews
Image

Decoding Looped Transformers Better for (Almost) Free

ImageApple
Weihao LiuWeihao Liu

Using an earlier recurrent prediction to guide token selection lets looped language models improve accuracy or match full-depth performance with fewer iterations.

01 Oct 2026
1kviews
Image

Sharpening Tax in Post-Training

ImageUW–Madison
Changdae OhChangdae OhAzalia MirhoseiniAzalia Mirhoseini

Pre-trained language models can solve agentic tasks that post-trained versions miss when given enough attempts, revealing a coverage cost to post-training’s higher reliability.

01 Oct 2026
808views
Image

OneStreamer: Unifying Perception, Memory, and Proactive Response in Streaming Video Interaction

ImageNJUImageShanghai AI Lab
Limin WangLimin Wang

A streaming video model can retain time-stamped descriptions of past events, letting it answer later questions without revisiting those frames or losing recent visual context.

01 Oct 2026
115views
Image

UniWAM: Unified World-Action Model

Wenxuan SongWenxuan SongHaoang LiHaoang Li

Training robots alongside human egocentric videos improves out-of-distribution manipulation as data scales, revealing a path to transfer physical knowledge across embodiments.

01 Oct 2026
106views
Image

Researchers to follow

View all
John Schulman

John Schulman

Co-Founder and Chief Scientist

Thinking Machines

Andrew Ng

Andrew Ng

Managing Partner

AI Aspire, Managing General Partner @ AI Fund, Founder @ DeepLearning.AI, Adjunct Professor, CS @ Stanford University, Chairman and Co-Founder @ Coursera
Demis Hassabis

Demis Hassabis

Co-Founder & Chair

Google DeepMind, Chief Scientist @ Alphabet Inc.

Sergey Levine

Sergey Levine

Co-Founder

Physical Intelligence, Associate Professor, EECS @ UC Berkeley

Yoshua Bengio

Yoshua Bengio

President and Scientific Director

LawZero, Founder and Scientific Advisor @ Mila - Quebec Artificial Intelligence Institute, Canada CIFAR AI Chair @ CIFAR, Full Professor, CS @ Université de Montréal

Christopher D Manning

Christopher D Manning

General Partner

AIX Ventures, Senior Fellow, HAI @ Stanford University

Jeff Dean

Jeff Dean

CEO & Co-Founder

DiscoveryLoop

Yejin Choi

Yejin Choi

The Dieter Schwarz Foundation Professor, CS & Senior Fellow, HAI

Stanford University, Distinguished Scientist, Language and Cognition Research @ NVIDIA

Sphere Encoder 2

ImageUMDImageLLNL
Tom GoldsteinTom Goldstein

A single autoencoder can generate sharp ImageNet images in one pass, offering a simpler, faster alternative to many-step diffusion models.

01 Oct 2026
Image

World Motion Models: Flexible Sequence Modeling of SE(3) Trajectories

ImageUC BerkeleyImageHarvard
Qianqian WangQianqian WangTrevor DarrellTrevor Darrell

A single motion model can predict 3D scenes, generate robot actions, and retarget human movement by conditioning on whichever trajectories are known.

01 Oct 2026
Image

Tokenization: A Survey for Modern NLP

ImageGoogle
Marco CognettaMarco CognettaChristopher AkikiChristopher AkikiSachin KumarSachin Kumar

This survey maps how tokenization shapes language-model quality, multilingual fairness, efficiency, and security, giving researchers a guide to methods, evaluation, and open problems.

30 Sept 2026
5kviews
Image

Learning Functional Subspaces for Neural Network Compression

ImageColumbiaImageNYU
Yann LeCunYann LeCun

Learning which directions matter to a network’s outputs preserves language-model quality under aggressive compression, where conventional low-rank methods often fail.

30 Sept 2026
171views
Image

AutoCompact: Learning When to Compact Context in Long-Horizon Coding Agents

Longtao ZhengLongtao ZhengBo AnBo An

Coding agents that learn when to summarize stale history and what to preserve solve more repository tasks, even before their context windows fill.

01 Oct 2026
Image
Gemini 4 Argon: our next era of frontier intelligence
ImageDeepMind
Koray KavukcuogluKoray Kavukcuoglu

Early testers can use Argon to find and validate serious software vulnerabilities, including a flaw exposing hospital patients’ sensitive information that earlier frontier models missed.
30 Sept 2026
3kviews
Gemini 4 Argon: our next era of frontier intelligence

Invent a Dataset: Measuring Dataset Generation Abilities with Zero Seed Data

ImageAdaption Labs
Shivalika SinghShivalika SinghAndrija DjurisicAndrija DjurisicSara HookerSara Hooker

Generating training data from task descriptions alone could help researchers build high-quality, diverse datasets for capabilities with no existing examples.

01 Oct 2026
5kviews
Image

When Do Biological Reasoning Models Use Their Biological Inputs?

ImageHarvardImageMIT
Sham M. KakadeSham M. Kakade

Biological models can score well without relying on sequence data, so benchmark accuracy alone cannot show whether predictions reflect biological inputs.

01 Oct 2026
118views
Image

Recova: Agent-Guided Failure Recovery for Autonomous Robotic Manipulation

ImageUC San DiegoImageUT Austin
Yuke ZhuYuke Zhu

Robots can turn failed manipulation attempts into reusable recovery skills, improving task success and reducing the need for human intervention.

01 Oct 2026
Image
There are no more papers matching your filters at the moment.
Sign in

Assistant

Advertisement
Advertisement