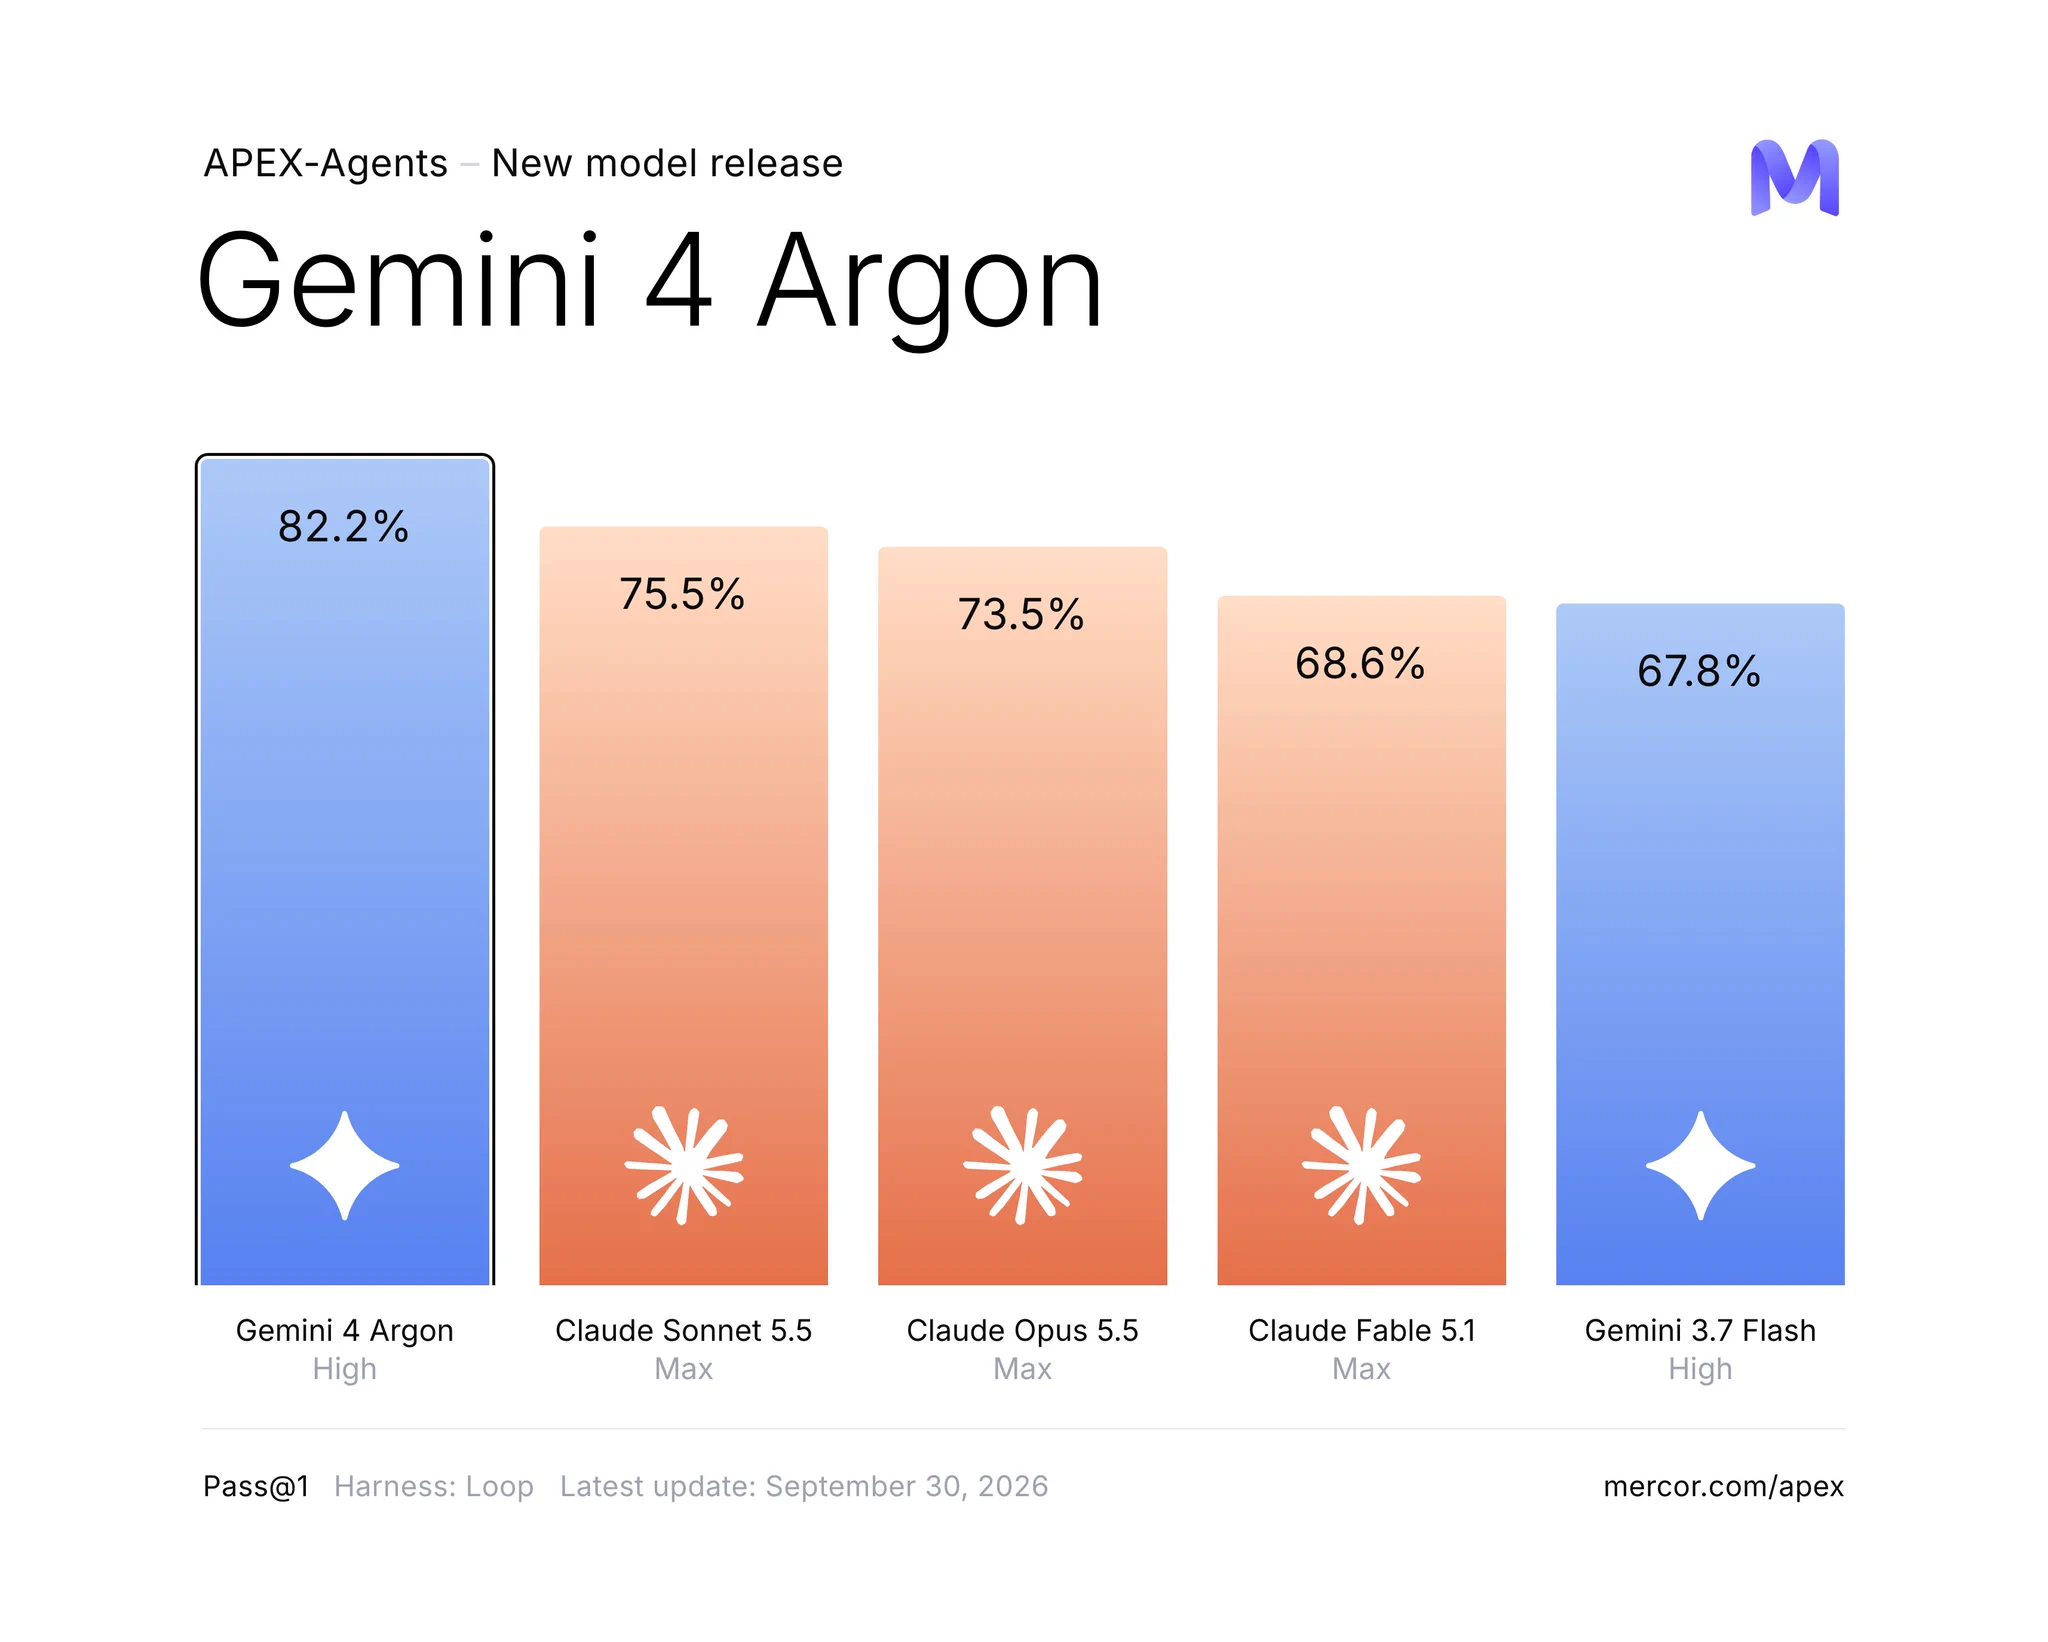
Gemini 4 Argon is the new #1 on APEX-Agents.
82.2% Pass@1 (#1)
87.9% Mean score (#1)
It is the first model to exceed 80% Pass@1. It is +6.7 pts over the prior #1, Sonnet 5.5, and +14.4 pts over the best prior model from DeepMind, Gemini 3.7 Flash (67.8%).
#𝟭 𝗶𝗻 𝗮𝗹𝗹
Voice agents need to work for everyone, whatever language we speak, however our names are spelled, wherever we live, and whatever specialized words we use.
Two new papers from @SierraPlatform's τ-voice team help put a number on that:
τ-Elicitation: Benchmarking for multi-turn
Introducing τ-Entity, a benchmark for how voice agents collect, verify, and correct the details callers give them.
In τ-Voice, capturing names and other identifying information was a recurring bottleneck: get a detail wrong, and authentication fails before the agent can help.
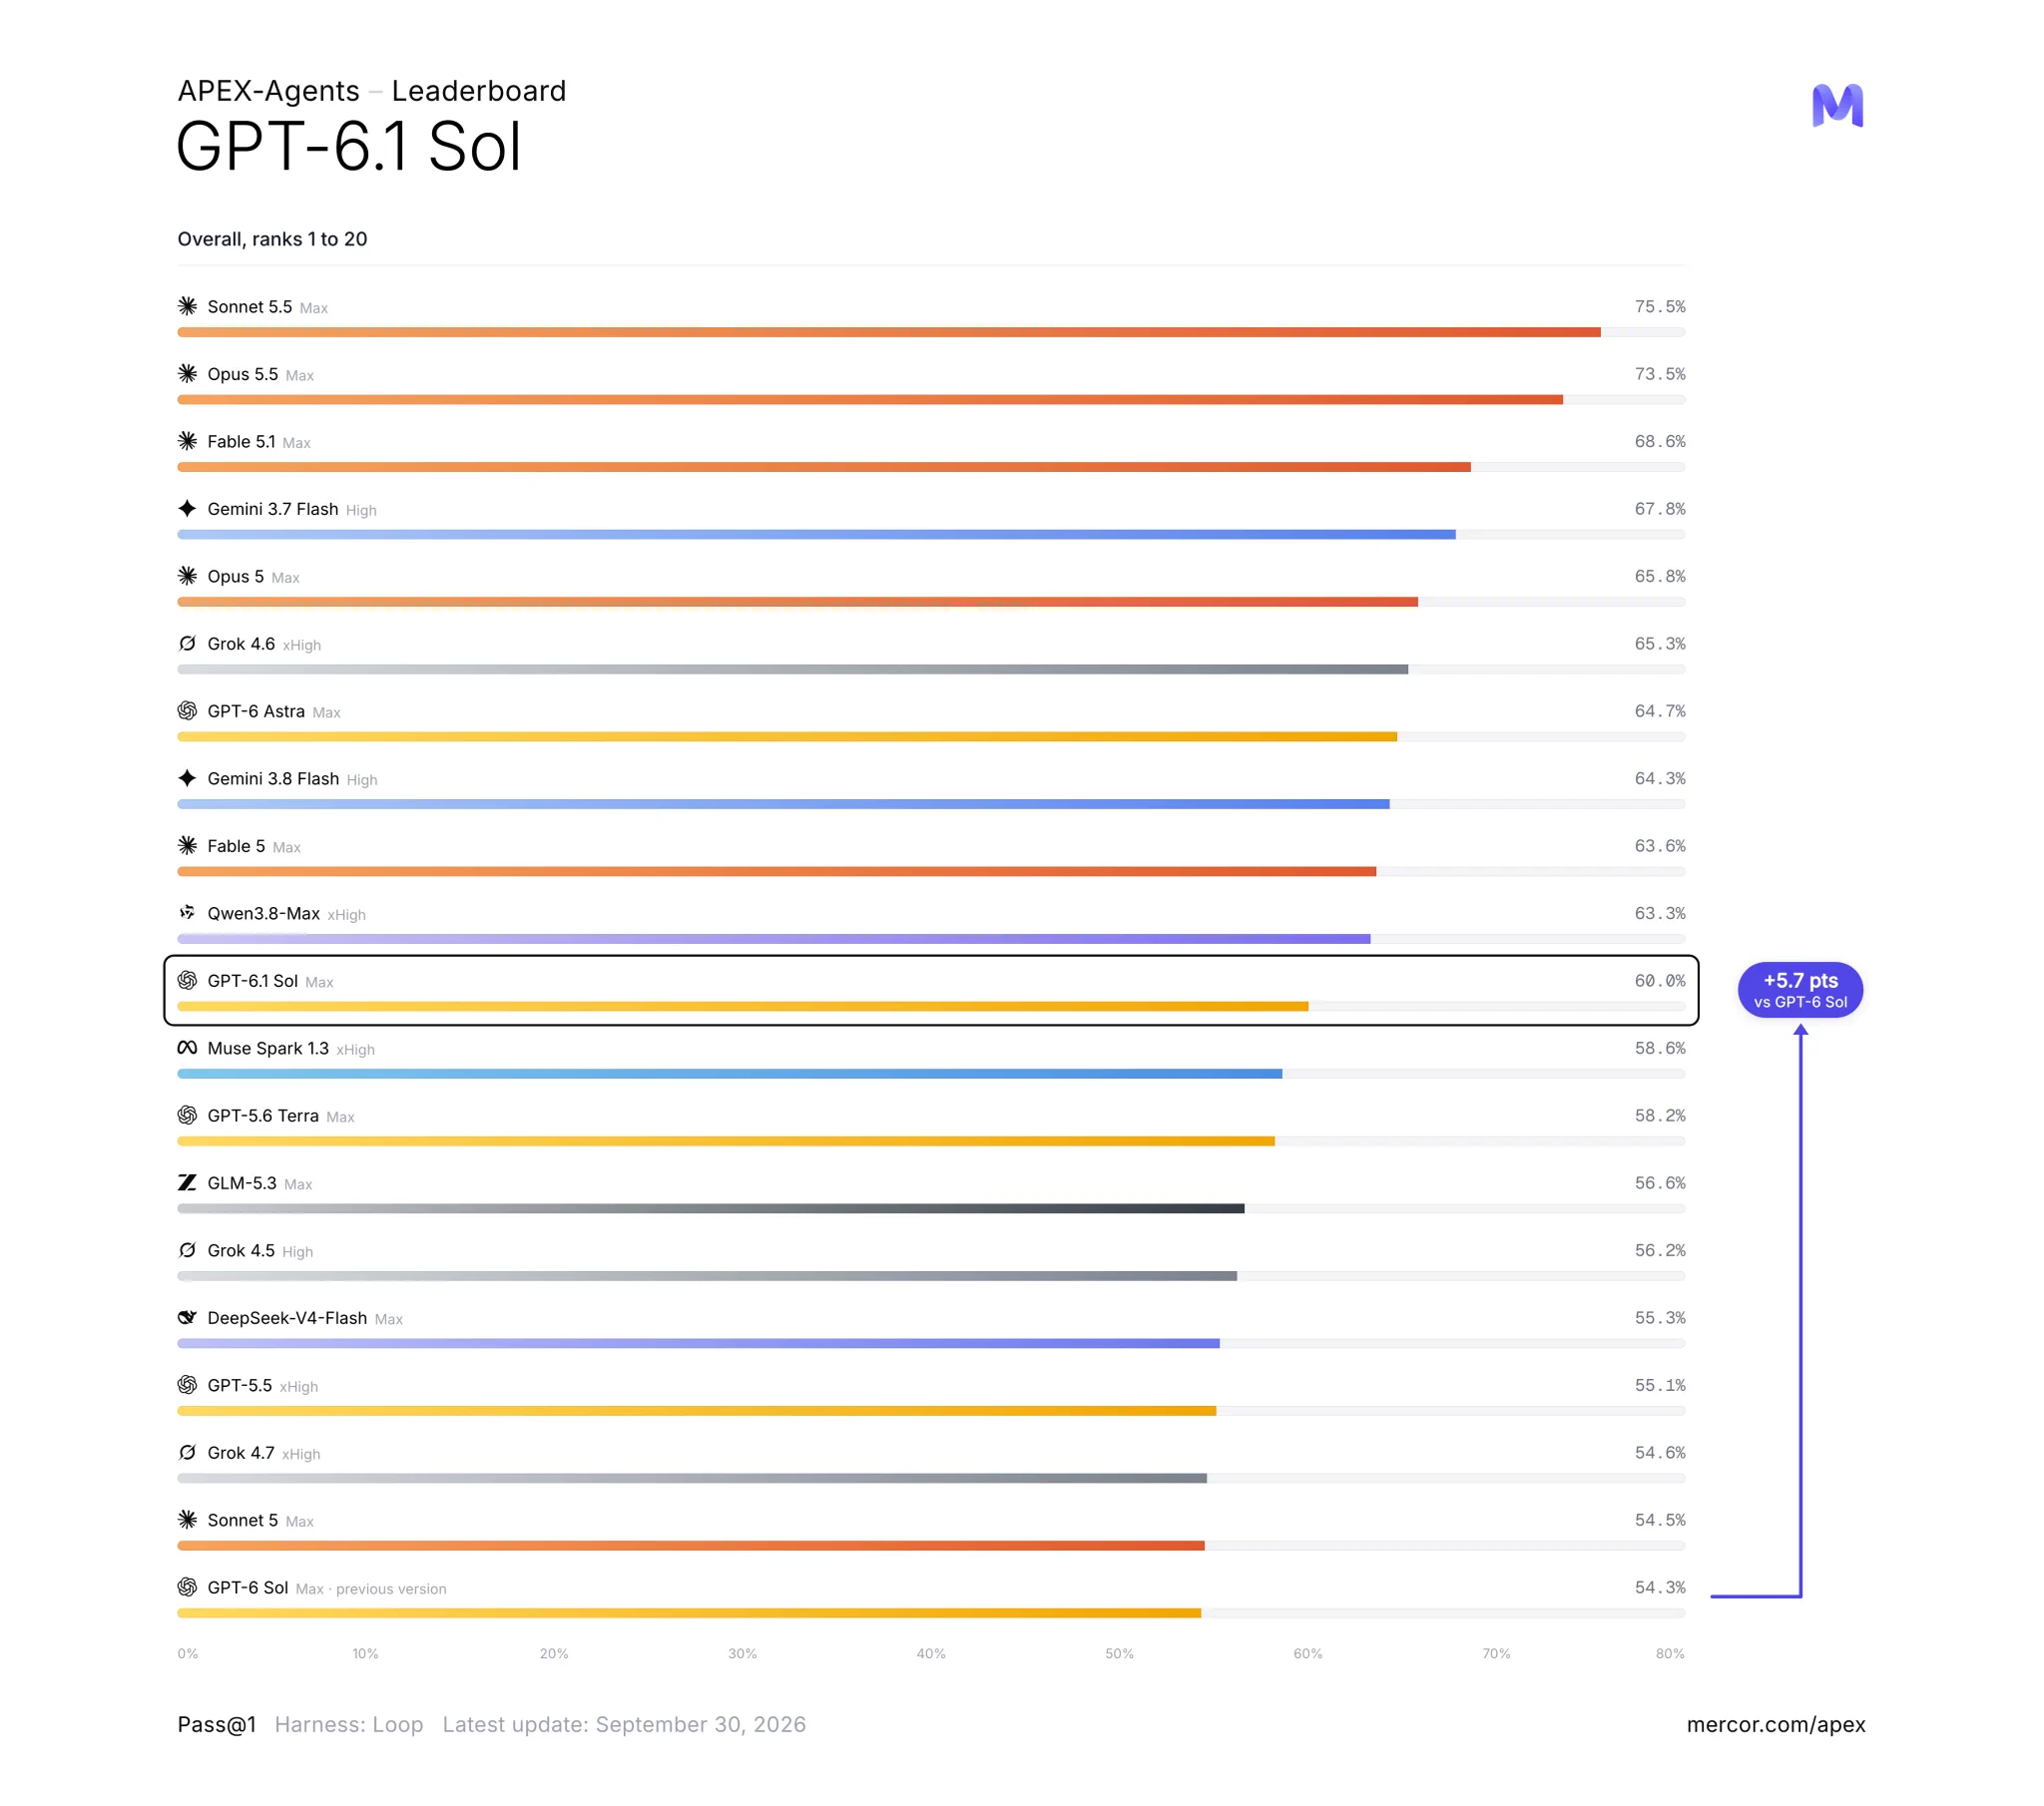
GPT-6.1 Sol scores 60.0% Pass@1 and 73.2% mean on APEX-Agents (#11), and 46.9% on APEX-SWE (#18).
@OpenAI says it nearly matches GPT-6 Astra on professional work "at one-fifth of Astra's standard input and output token prices."
That is consistent with what we’re seeing on APEX,
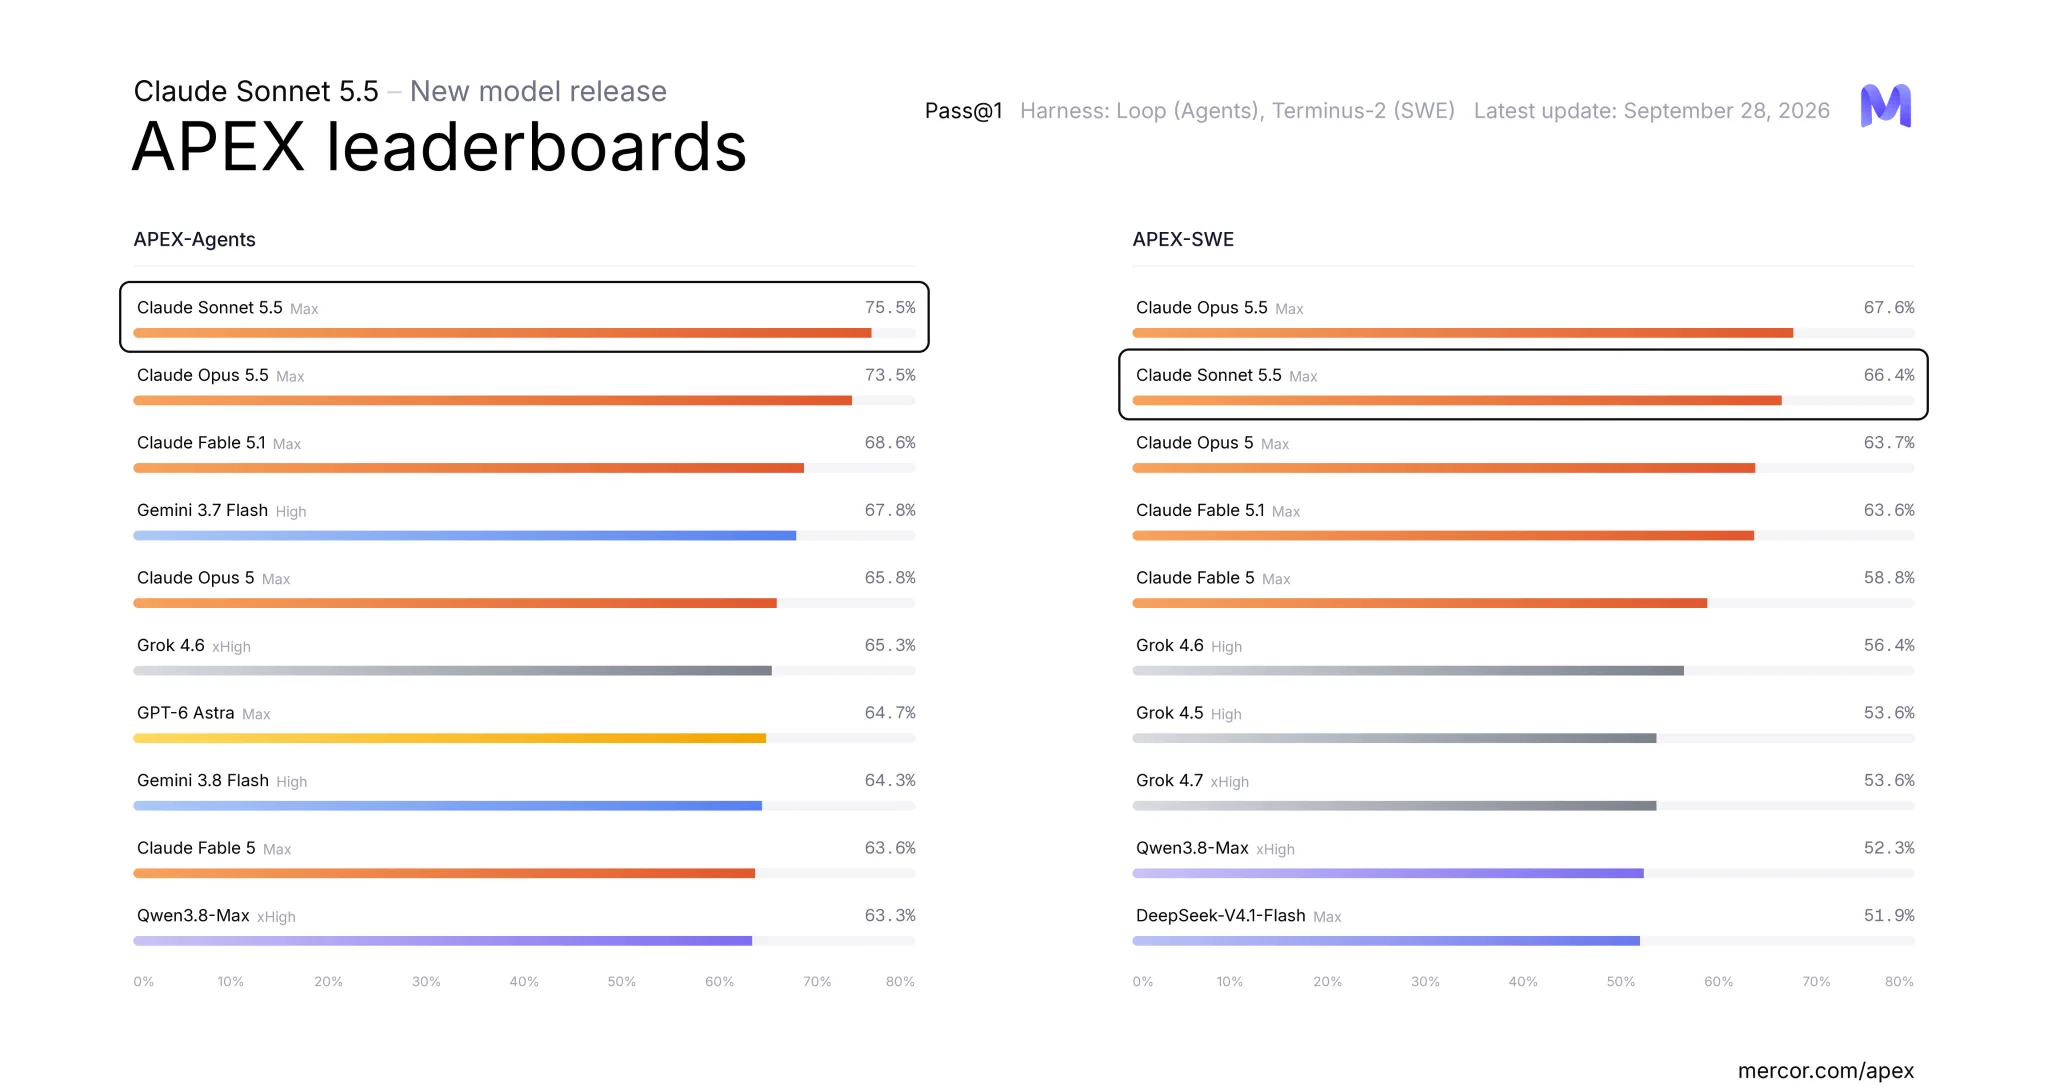
Claude Sonnet 5.5 debuts at #1 on APEX-Agents and #2 on APEX-SWE.
APEX-Agents:
75.5% Pass@1 (#1)
21 pt gain from from 54.5% for Sonnet 5
APEX-SWE:
66.4% Pass@1 (#2)
20 pt gain from 46.4% for Sonnet 5
Anthropic states Sonnet 5.5 at Max effort performs comparably to Opus
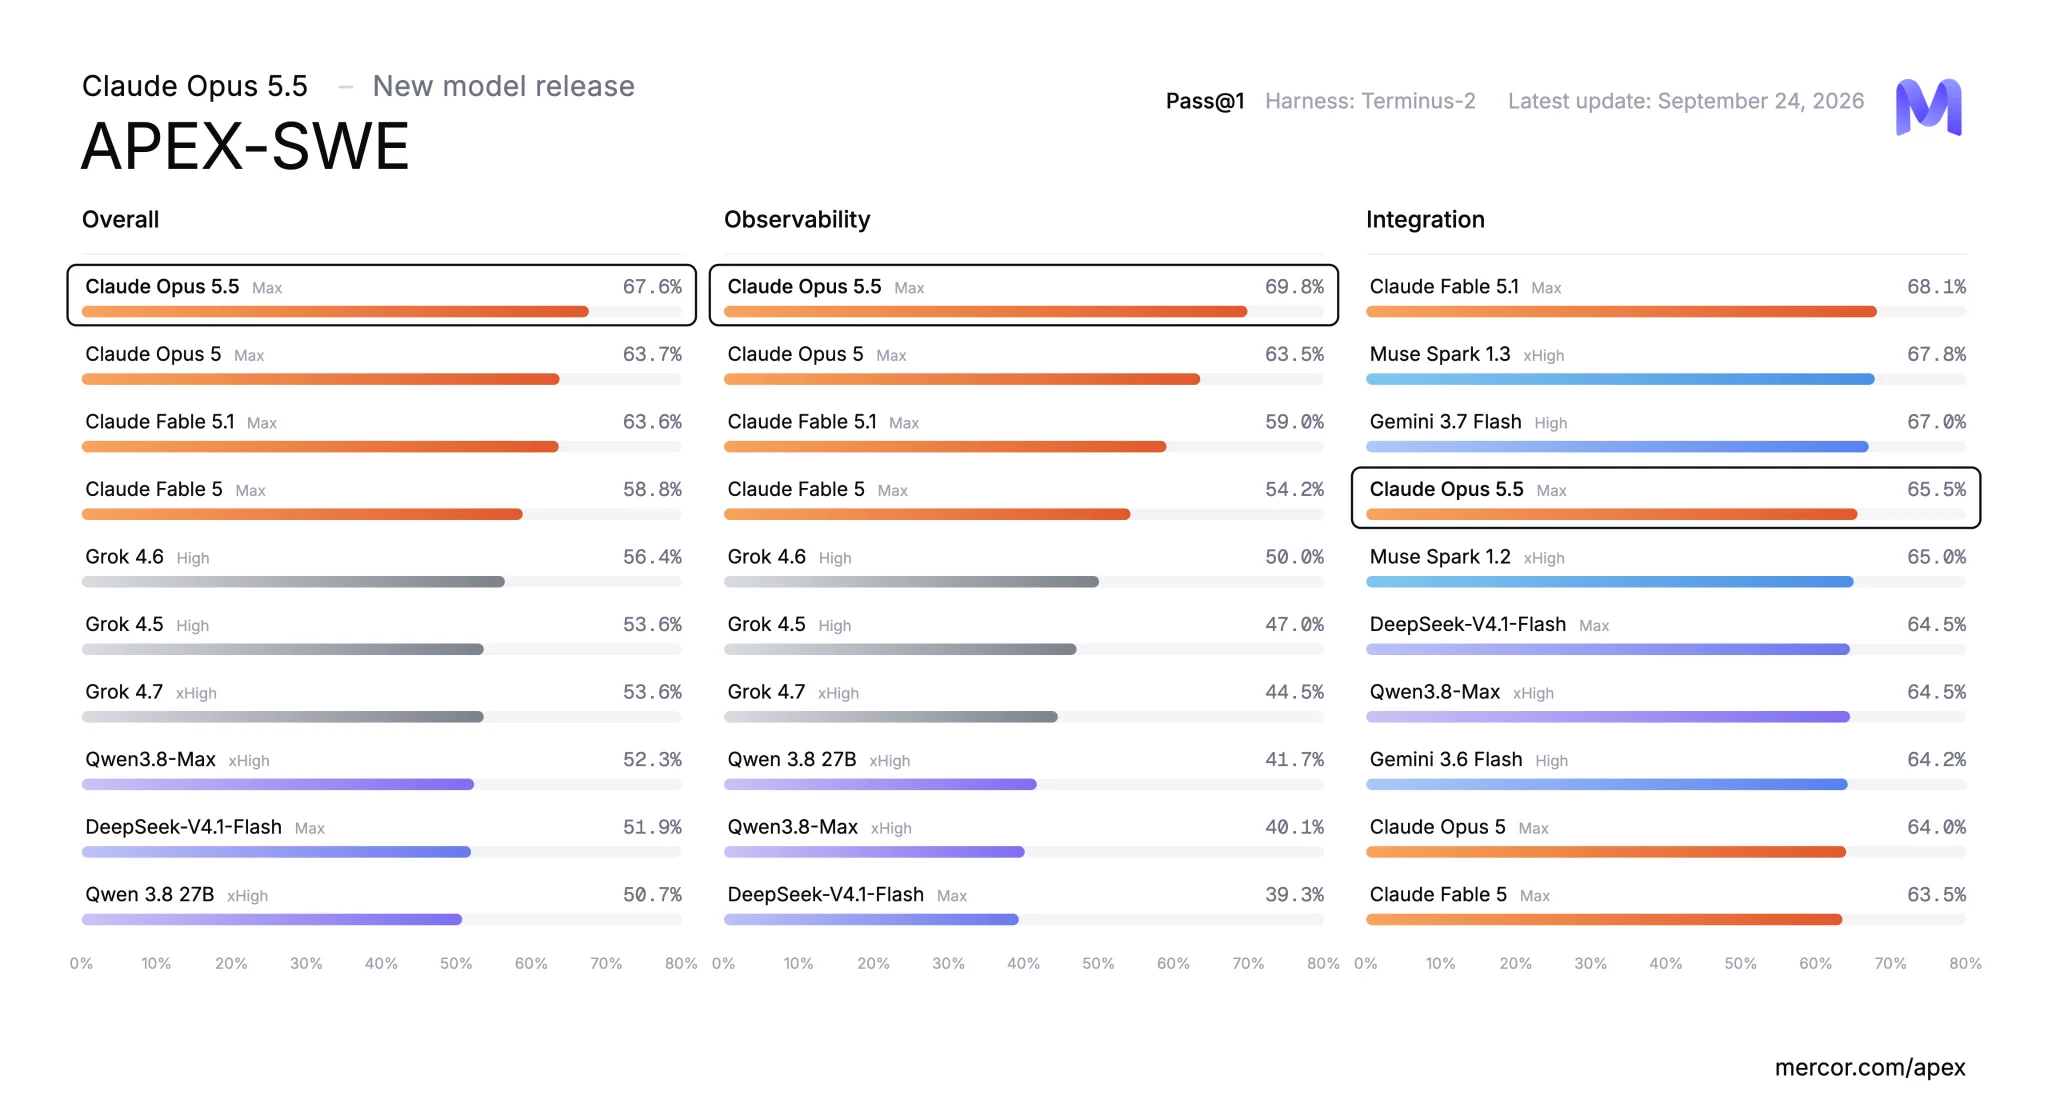
Claude Opus 5.5 is the new #1 on APEX-SWE.
Overall, Opus 5.5 scores 67.6% Pass@1, a +3.9 point gain over the previous leader, Opus 5, at 63.7%.
APEX-SWE measures observability, debugging from production telemetry, and integration, if a model can build an end-to-end system.