Pre-training is expensive. We make it efficient.
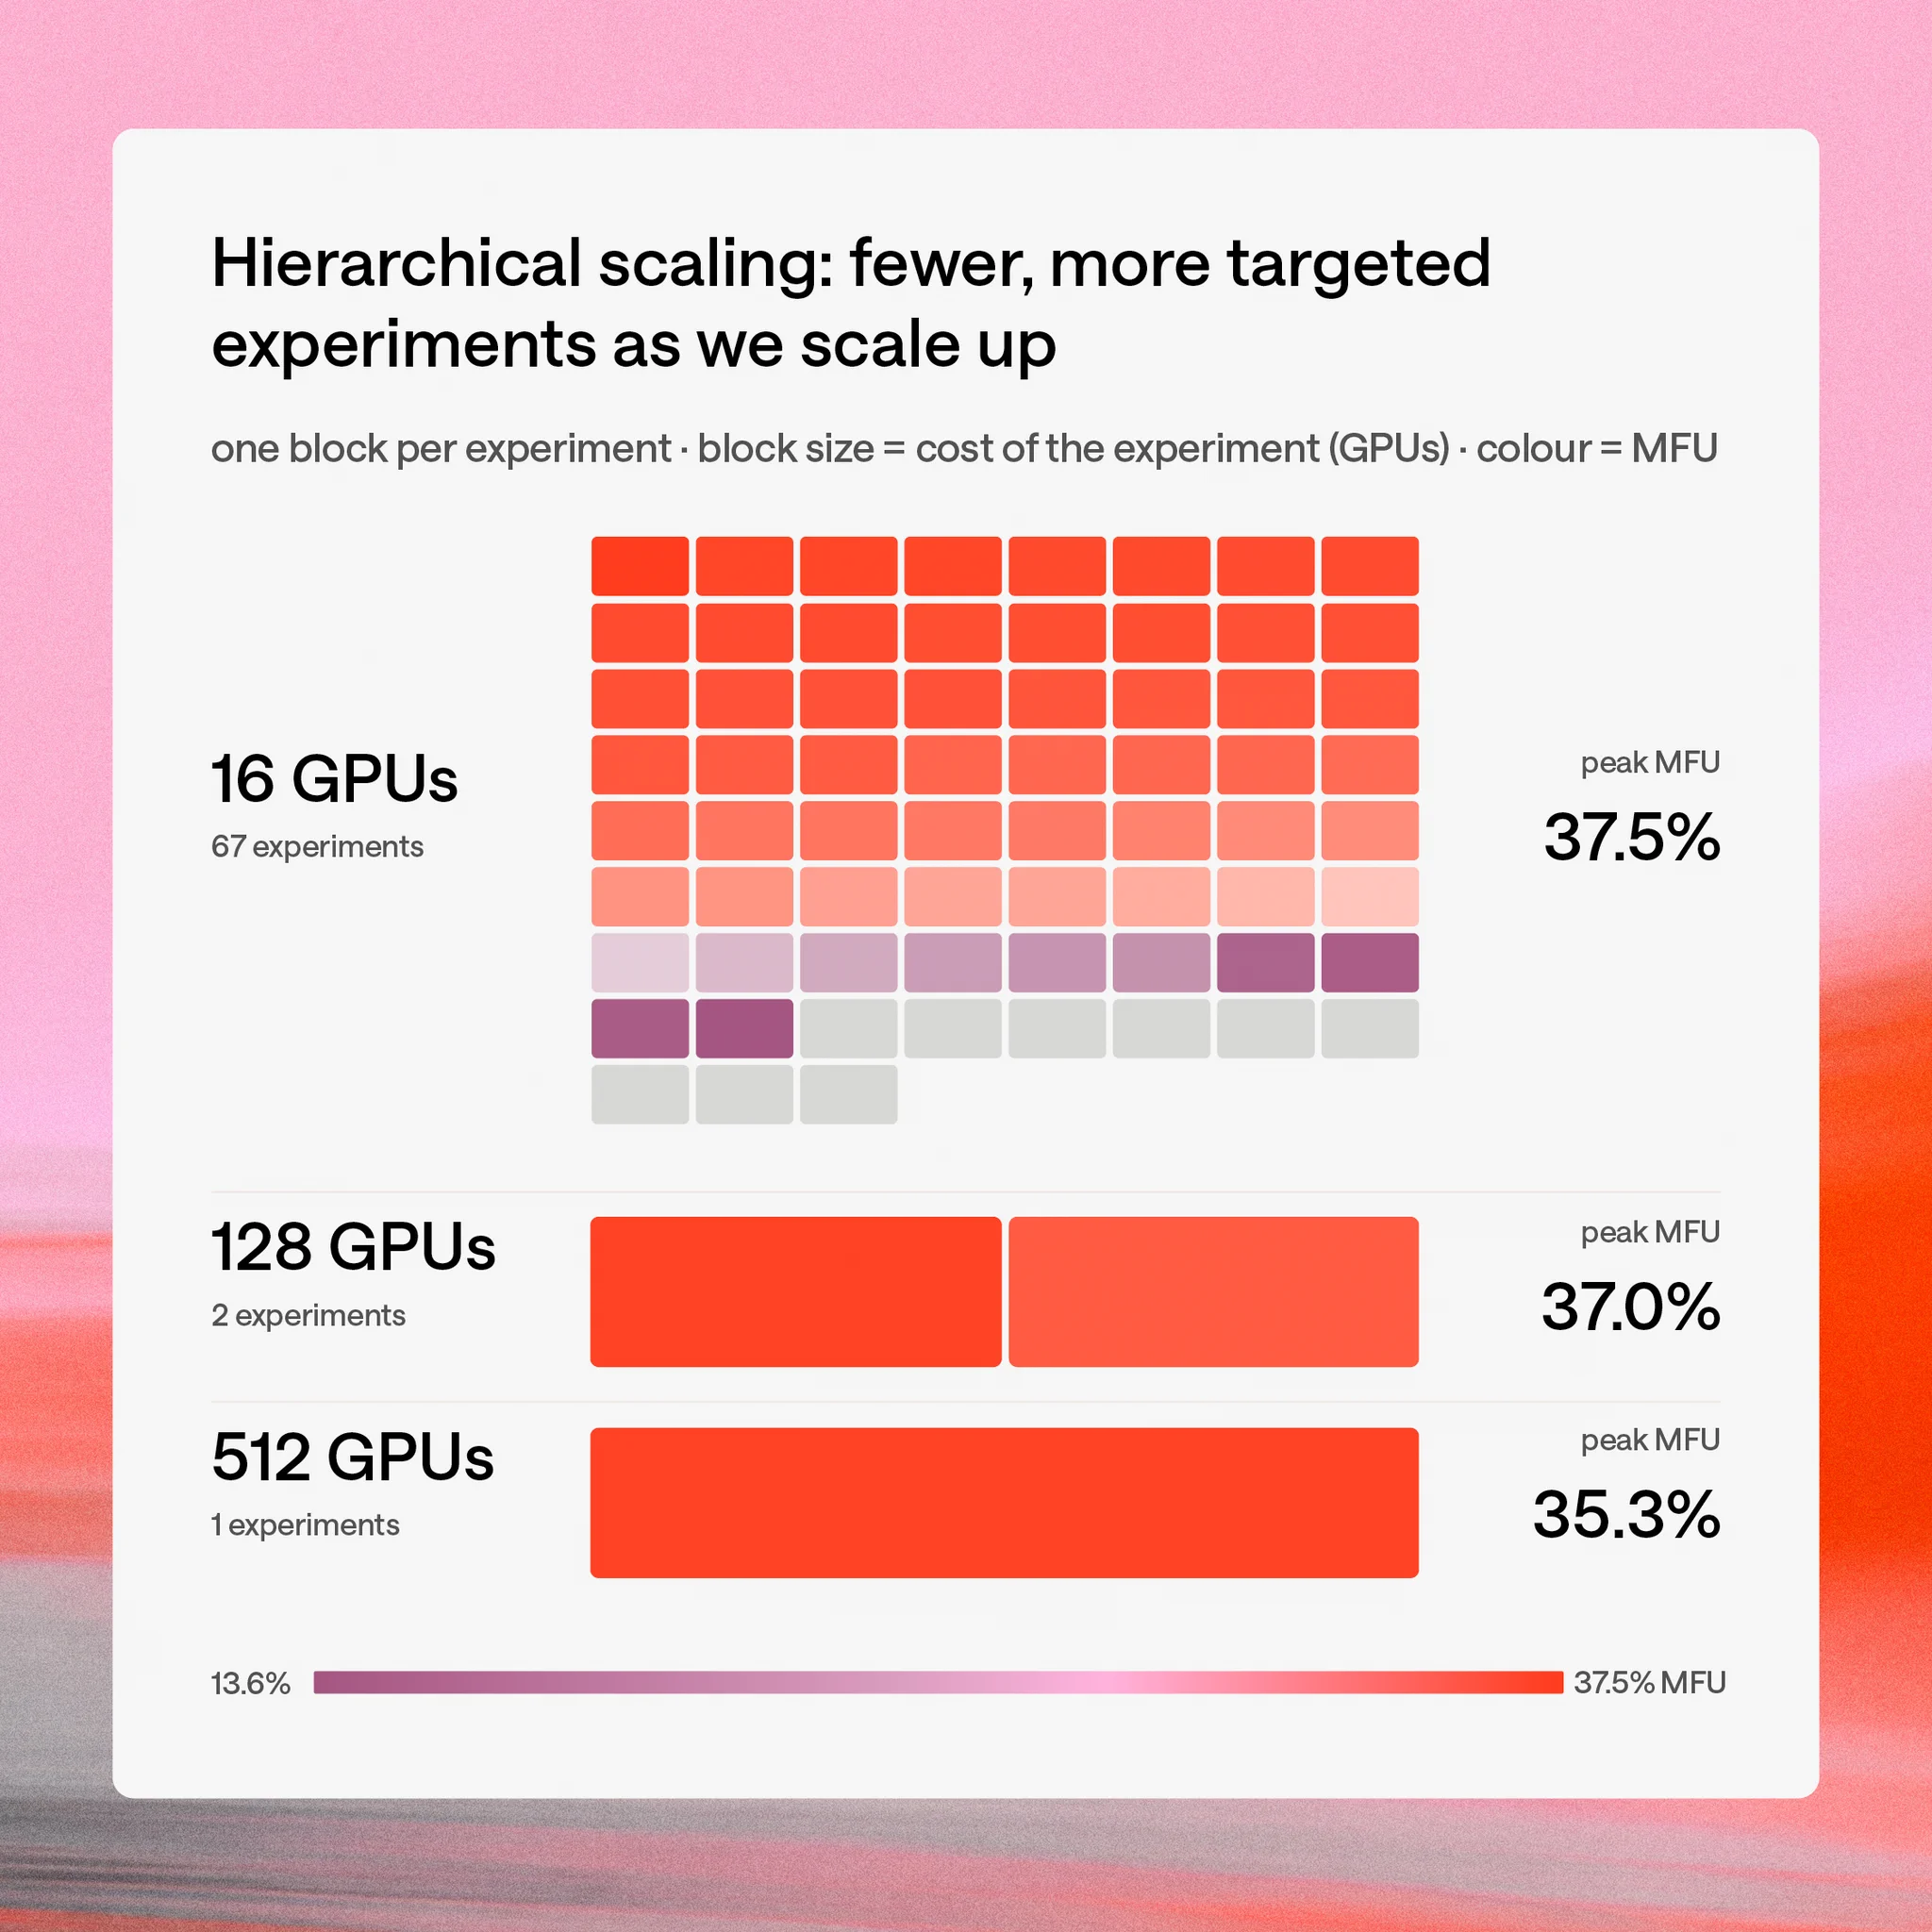
Our blog post explains our hierarchical approach to scaling pre-training. We’ll guide you through the choices we make at different GPU counts, taking a 30B-A3B MoE model from 16 - 512 B200 GPUs with 35% MFU & near-linear scaling.