<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://alanlusun.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://alanlusun.github.io/" rel="alternate" type="text/html" /><updated>2026-09-25T11:36:44-07:00</updated><id>https://alanlusun.github.io/feed.xml</id><title type="html">Changsheng Lu</title><subtitle>personal description</subtitle><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><entry><title type="html">Rigid Transformation in Euclidean Space</title><link href="https://alanlusun.github.io/posts/2022-06-21-Rigid-Transformation/" rel="alternate" type="text/html" title="Rigid Transformation in Euclidean Space" /><published>2022-06-20T00:00:00-07:00</published><updated>2022-06-20T00:00:00-07:00</updated><id>https://alanlusun.github.io/posts/Rigid-Transformation</id><content type="html" xml:base="https://alanlusun.github.io/posts/2022-06-21-Rigid-Transformation/"><![CDATA[<p><em>Author: Changsheng Lu (卢长胜)</em></p>

<h2 id="outline">Outline</h2>
<ul class="task-list">
  <li class="task-list-item"><input type="checkbox" class="task-list-item-checkbox" disabled="disabled" checked="checked" />Notations</li>
  <li class="task-list-item"><input type="checkbox" class="task-list-item-checkbox" disabled="disabled" checked="checked" />Rigid Transformation</li>
  <li class="task-list-item"><input type="checkbox" class="task-list-item-checkbox" disabled="disabled" checked="checked" />Pose Estimation</li>
  <li class="task-list-item"><input type="checkbox" class="task-list-item-checkbox" disabled="disabled" checked="checked" />Camera Relocalization</li>
</ul>

<h2 id="notations">Notations</h2>

<table>
  <thead>
    <tr>
      <th style="text-align: left"> </th>
      <th style="text-align: center">Definition</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">$SE(3)$</td>
      <td style="text-align: center">Rigid transformations in 3D Euclidean space</td>
    </tr>
    <tr>
      <td style="text-align: left">$R$</td>
      <td style="text-align: center">Rotation matrix</td>
    </tr>
    <tr>
      <td style="text-align: left">$t$</td>
      <td style="text-align: center">Translation (homogeneous coordinate $[x, y, 1]^{T}$)</td>
    </tr>
    <tr>
      <td style="text-align: left">$P \in SE(3)$</td>
      <td style="text-align: center">Pose (Orientation+Position) or rigid transformation</td>
    </tr>
  </tbody>
</table>

<h2 id="rigid-transformation">Rigid Transformation</h2>
<h3 id="kinematics">Kinematics</h3>
<p>The pose $P$ of an object or a rigid transformation $T$ can be represented by a $4 \times 4$ matrix<br />
\(T=\left[
  \begin{matrix}
    R &amp; t \\
    0 &amp; 1
  \end{matrix}
  \right]_{4 \times 4}\)<br />
Namely, $T=[R|t]$, or $T \in SE(3)$, $P \in SE(3)$.</p>

<p><strong>Coordinate system:</strong></p>
<ul>
  <li>world coordinate system</li>
  <li>camera coordinate system</li>
  <li>optical coordinate system (In many cases, it assumes to be same with camera coordinate system but in practice they are different.)</li>
  <li>object coordinate system</li>
</ul>

<p><strong>Left multiplication rule:</strong> $T=T^{n}\cdots T^{2}T^{1}$, if $T^i$ is the rigid transformation relative to same base coordinate system $O$. The transformation sequence is $T^{1},T^{2},\cdots,T^{n}$.</p>

<p><strong>Right multiplication rule:</strong> $T=T^{1}\cdots T^{n-1}T^{n}$, if $T^i$ is the rigid transformation relative to previous pose (or previous coordinate system $O_{i-1}$). The transformation sequence is $T^{1},T^{2},\cdots,T^{n}$.</p>

<p><strong>Inverse of rigid transformation:</strong> Assume $T=[R|t]$, then its inverse is $T^{-1}=[R^{-1}|-R^{-1}t]$. This could be easily proved by computing below linear system<br />
\(XT=I \\
X=T^{-1}=\left[
  \begin{matrix}
    R^{-1} &amp; -R^{-1}t \\
    0      &amp; 1
  \end{matrix}
  \right]\)<br />
It should note that, the inverse of rigid transformation $X$ can also be decomposed to <em>a translation transformation</em> followed by <em>a rotation transformation</em> as follows:<br />
\(X=\left[
  \begin{matrix}
    R^{-1} &amp; 0 \\
    0      &amp; 1
  \end{matrix}
  \right]
  \left[
  \begin{matrix}
    I &amp; -t \\
    0 &amp; 1
  \end{matrix}
  \right]\)<br />
This meets our direct imagination as we could firstly move object to a point in opposite direction and then rotate the object.</p>

<h2 id="pose-estimation">Pose Estimation</h2>
<p><strong>Ingredients:</strong> 1) two images of same scene ($I^a, I^b$) (captured at two different camera poses); 2) depth maps ($D^a, D^b$); 3) camera intrinsic parameters ($K$); 4) two sets of corresponding keypoints ($p^a_1,\cdots,p^a_n$) and ($p^b_1,\cdots,p^b_n$); 5) relative pose $T\in SE(3)$ between two camera poses.</p>

<p><strong>Tasks:</strong> 1) The relative pose could be estimated when knowing remaining conditions; 2) The depth could be estimated when knowing remaining conditions.</p>

<h2 id="camera-relocalization">Camera Relocalization</h2>
<p><strong>Camera relocalization</strong> task usually assumes the scene is given, the initial camera pose is given, and only the camera pose will change over time. Thus, we could estimate camera pose to realize camera relocalization, for example, calibrating camera pose to reference pose. Thus, we could estimate camera pose based on a pair of (reference image, current image) under such setting.</p>

<p>Inherently, camera relocalization is also a sub-problem of pose estimation. The <em>active viewpoint transfer</em> problem is exactly the <em>camera relocalization</em>.</p>

<h2 id="resources">Resources</h2>
<ul>
  <li><a href="https://leimao.github.io/article/Noise-Contrastive-Estimation/">Noise Contrastive Estimation</a></li>
  <li><a href="https://zhuanlan.zhihu.com/p/129076690">InfoNCE and CPC, 知乎</a></li>
  <li><a href="https://blog.csdn.net/m0_37876745/article/details/110933812?utm_medium=distribute.pc_aggpage_search_result.none-task-blog-2~aggregatepage~first_rank_ecpm_v1~rank_v31_ecpm-2-110933812.pc_agg_new_rank&amp;utm_term=infonce%E6%8D%9F%E5%A4%B1&amp;spm=1000.2123.3001.4430">CSDN</a></li>
</ul>

<h2 id="references">References</h2>
<p>[1] Gutmann, Michael, and Aapo Hyvärinen. “Noise-contrastive estimation: A new estimation principle for unnormalized statistical models.” Proceedings of the thirteenth international conference on artificial intelligence and statistics. JMLR Workshop and Conference Proceedings, 2010.<br />
[2] Mnih, Andriy, and Yee Whye Teh. “A fast and simple algorithm for training neural probabilistic language models.” arXiv preprint arXiv:1206.6426 (2012).<br />
[3] Mnih, Andriy, and Koray Kavukcuoglu. “Learning word embeddings efficiently with noise-contrastive estimation.” Advances in neural information processing systems 26 (2013).<br />
[4] Van den Oord, Aaron, Yazhe Li, and Oriol Vinyals. “Representation learning with contrastive predictive coding (CPC).” arXiv e-prints (2018): arXiv-1807.</p>]]></content><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><category term="Learning Notes" /></entry><entry><title type="html">A Glance of Noise Contrastive Estimation (NCE) and infoNCE</title><link href="https://alanlusun.github.io/posts/2022-03-10-NCE-infoNCE/" rel="alternate" type="text/html" title="A Glance of Noise Contrastive Estimation (NCE) and infoNCE" /><published>2022-03-10T00:00:00-08:00</published><updated>2022-03-10T00:00:00-08:00</updated><id>https://alanlusun.github.io/posts/NCE-infoNCE</id><content type="html" xml:base="https://alanlusun.github.io/posts/2022-03-10-NCE-infoNCE/"><![CDATA[<p><em>Author: Changsheng Lu (卢长胜)</em></p>

<h2 id="motivation">Motivation</h2>
<p>The softmax is nice normalizer whose formulation is $p=\exp(f^{\theta}(x))/\sum_{i}^{C}\exp(f^{\theta}_{i}(x))$. However, when $C$ is tremendous, it requires much time to compute the summation of all classes’ activations. To save time, the researchers propose to use <em>Noise Contrastive Estimation (NCE)</em> which samples negative noise for contrastive learning, thus we only need to compute the $c$-th activations for both postive sample and negative samples.</p>

<p>The key idea behind NCE [1,2,3] and also the following infoNCE [4] aim to maximize the activation value (or signal value) from postive samples while surpressing those values (or noise values) from negative samples, which forms contrastive learning. This has a solid mathematical proof in <a href="https://leimao.github.io/article/Noise-Contrastive-Estimation/">Noise Contrastive Estimation</a>.</p>

<h2 id="mathematical-formulation-for-nce-loss">Mathematical Formulation for NCE Loss</h2>
<p>\(J(\theta)=E_{w\sim P_{d}(w)}[\log \sigma(\triangle f^{\theta}(w))] + kE_{w \sim P_{noise}(w)}[\log (1- \sigma(\triangle f^{\theta}(w)))]\)<br />
where $\sigma=\frac{1}{1+e^{-1}}$ is the sigmoid function, $\triangle f^{\theta}(w) = f^{\theta}(w) - \log kP_{noise}(w)$. Its empirical form is<br />
\(\hat{J}(\theta)=\frac{1}{m}\sum_{i=1}^{m} \log \sigma(\triangle f^{\theta}(w_i)) +\frac{k}{n}\sum_{j=1}^{n} \log (1- \sigma(\triangle f^{\theta}(w_j)))\)<br />
where $m$ is the number of positive samples and $n$ is number of noise samples. $k$ is the draw number for noise.</p>

<p>Remarks: The former part of formulation is to maximize signal while the latter part is to supress noise, forming the contrastive learning.</p>

<h2 id="the-infonce-and-contrastive-predictive-coding-cpc">The infoNCE and Contrastive Predictive Coding (CPC)</h2>
<p>The infoNCE’s formulation is<br />
\(L_{infoNCE}=-E_{X} \log \frac{f_{k}(x_{t+k}, c_t)}{\sum_{x_{j} \in X} f_{k}(x_{j}, c_{t})}\)<br />
where $(x_{t+k}, c_t)$ is a postive pair, $(x_{j}, c_{t}), j=1,2,\cdots, |X|$ are negative pairs. $f_{k}(x_{t+k}, c_t)=\exp(.)$ is the model output.</p>

<p>CPC is used in language models which improves the feature representation ability by measuring a repres feature’s prediction ability over following words. <em>A good repres feature should preserve the important information contained in raw data while also have good prediction ability (for subsequent words)</em>, e.g., knowing several first words in a sentence will result in a guess for subsequent words. In [4], CPC is formed by <br />
\(f_{k}(x_{t+k}, c_{t}) = \exp (z^{T}_{t+k}W_{k}c_{t})\)<br />
where $z_{t+k}=g_{encoder}(x_{t+k})$, and $W_{k}c_{t}$ is a guess for $z_{t+k}$ by using $t$-th time step’s information $c_{t}$.</p>

<h2 id="resources">Resources</h2>
<ul>
  <li><a href="https://leimao.github.io/article/Noise-Contrastive-Estimation/">Noise Contrastive Estimation</a></li>
  <li><a href="https://zhuanlan.zhihu.com/p/129076690">InfoNCE and CPC, 知乎</a></li>
  <li><a href="https://blog.csdn.net/m0_37876745/article/details/110933812?utm_medium=distribute.pc_aggpage_search_result.none-task-blog-2~aggregatepage~first_rank_ecpm_v1~rank_v31_ecpm-2-110933812.pc_agg_new_rank&amp;utm_term=infonce%E6%8D%9F%E5%A4%B1&amp;spm=1000.2123.3001.4430">CSDN</a></li>
</ul>

<h2 id="references">References</h2>
<p>[1] Gutmann, Michael, and Aapo Hyvärinen. “Noise-contrastive estimation: A new estimation principle for unnormalized statistical models.” Proceedings of the thirteenth international conference on artificial intelligence and statistics. JMLR Workshop and Conference Proceedings, 2010.<br />
[2] Mnih, Andriy, and Yee Whye Teh. “A fast and simple algorithm for training neural probabilistic language models.” arXiv preprint arXiv:1206.6426 (2012).<br />
[3] Mnih, Andriy, and Koray Kavukcuoglu. “Learning word embeddings efficiently with noise-contrastive estimation.” Advances in neural information processing systems 26 (2013).<br />
[4] Van den Oord, Aaron, Yazhe Li, and Oriol Vinyals. “Representation learning with contrastive predictive coding (CPC).” arXiv e-prints (2018): arXiv-1807.</p>]]></content><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><category term="Learning Notes" /></entry><entry><title type="html">Techniques to Visualize Low-level Filters and Features</title><link href="https://alanlusun.github.io/posts/2021-12-07-Visualize-low-level-filters-and-features/" rel="alternate" type="text/html" title="Techniques to Visualize Low-level Filters and Features" /><published>2021-12-07T00:00:00-08:00</published><updated>2021-12-07T00:00:00-08:00</updated><id>https://alanlusun.github.io/posts/Visualize-low-level-filters-and-features</id><content type="html" xml:base="https://alanlusun.github.io/posts/2021-12-07-Visualize-low-level-filters-and-features/"><![CDATA[<h1 id="techniques-to-visualize-low-level-filters-and-features">Techniques to Visualize Low-level Filters and Features</h1>
<p><em>Author: Changsheng Lu (卢长胜)</em></p>

<h2 id="visualization-for-learned-filters-in-cnn">Visualization for Learned Filters in CNN</h2>
<p>In order to understand the internal representations learned by CNN, in many cases, we would like to visualize what CNN has learned in each layer, and especially see the trends from low-level to high-level. Since it’s trivial to directly map a feature map (by selecting a channel or merging all channels) to greyscale image (or RGB image), one is reasonable to see the max response w.r.t. a specific filter. The techniques include:</p>
<ul>
  <li>Learnable image editting. Firstly, we freeze the encoder’s parameters. Then, by taking a learnable noise image $I$ as input, we obtain the feature output $F^{l}$ from a specific fiter $K^l$. Let the loss be $L=\sum F^{l}$. Next, we could compute the gradients w.r.t. $I$ as $\partial L^l/\partial I$, and update image $I:=I+\eta\cdot\frac{\partial L^l}{\partial I}$. After several iterations, we are hopefully to acquire the image $I$ which enable the specific fiter $K^l$ to have maximal response. This method is kind of like <em>neural style transfer</em> [3], [4].</li>
</ul>

<h2 id="visualization-for-learned-feature-maps-in-cnn">Visualization for Learned Feature Maps in CNN</h2>
<ul>
  <li>CAM [1]</li>
  <li>Grad-CAM (preferred) [2]</li>
</ul>

<h2 id="some-materials">Some Materials</h2>
<ul>
  <li><a href="https://zhuanlan.zhihu.com/p/53683453">知乎</a></li>
</ul>

<h2 id="references">References</h2>
<p>[1] Zhou, Bolei, et al. “Learning deep features for discriminative localization.” Proceedings of the IEEE conference on computer vision and pattern recognition. 2016.<br />
[2] Selvaraju, Ramprasaath R., et al. “Grad-cam: Visual explanations from deep networks via gradient-based localization.” Proceedings of the IEEE international conference on computer vision. 2017.<br />
[3] Gatys, Leon A., Alexander S. Ecker, and Matthias Bethge. “Image style transfer using convolutional neural networks.” Proceedings of the IEEE conference on computer vision and pattern recognition. 2016.<br />
[4] Gatys, Leon, Alexander S. Ecker, and Matthias Bethge. “Texture synthesis using convolutional neural networks.” Advances in neural information processing systems 28 (2015): 262-270.<br />
[5]</p>]]></content><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><category term="Learning Notes" /></entry><entry><title type="html">Gaussian Process</title><link href="https://alanlusun.github.io/posts/2020-10-15-Gaussian-Process/" rel="alternate" type="text/html" title="Gaussian Process" /><published>2020-10-15T00:00:00-07:00</published><updated>2020-10-15T00:00:00-07:00</updated><id>https://alanlusun.github.io/posts/Gaussian-Process</id><content type="html" xml:base="https://alanlusun.github.io/posts/2020-10-15-Gaussian-Process/"><![CDATA[<h1 id="gaussian-process">Gaussian Process</h1>
<p><em>Author: Changsheng Lu (卢长胜)</em></p>

<h2 id="definition">Definition</h2>
<p>Gaussian process (GP) is a set of random variables following Gaussian distribution. Gaussian processes (GP) are <em>Bayesian nonparametric models</em> for continuous functions which allow for uncertainty quantification, interpretability, and the incorporation of expert knowledge. The theory and practice of GPs have flourished in the last decade, where researchers have looked into the expressiveness and efficiency of GP-based models and practitioners have applied them to a plethora of disciplines. In contrast, Bayesian Neural Network (BNN) is <em>Bayesian parametric model</em>.</p>

<h2 id="gaussian-process-for-machine-learning">Gaussian process for machine learning</h2>
<p>Essentially, it uses the correlation between training data and test data to model the prediction of test data, and each prediction is subject to a Gaussian distribution.</p>
<ul>
  <li>Tutorial can be found <a href="https://katbailey.github.io/post/gaussian-processes-for-dummies/">here</a></li>
  <li>Tutorial &amp; PPT &amp; Code <a href="https://github.com/GAMES-UChile/The_Art_of_Gaussian_Processes">here</a></li>
  <li><a href="https://bayesoptbook.com/">Bayessian Optimization Book</a></li>
</ul>

<h2 id="algorithm">Algorithm</h2>
<p>Before introducing the algorithm, we first define the squared exponential kernel $k$:</p>

\[k(A, B) = e^{-\frac{1}{2p}(a \ominus b)}= \left[ \begin{matrix}
  e^{-\frac{1}{2p}{\|a_1 - b_1\|}^2} &amp; e^{-\frac{1}{2p}{\|a_1 - b_2\|}^2} &amp; \cdots &amp; e^{-\frac{1}{2p}{\|a_1 - b_n\|}^2} \\
  e^{-\frac{1}{2p}{\|a_2 - b_1\|}^2} &amp; e^{-\frac{1}{2p}{\|a_2 - b_2\|}^2} &amp; \cdots &amp; e^{-\frac{1}{2p}{\|a_2 - b_n\|}^2} \\
  \cdots        &amp; \cdots        &amp; \cdots &amp; \cdots        \\
  e^{-\frac{1}{2p}{\|a_m - b_1\|}^2} &amp; e^{-\frac{1}{2p}{\|a_m - b_2\|}^2} &amp; \cdots &amp; e^{-\frac{1}{2p}{\|a_m - b_n\|}^2} 
\end{matrix} \right]\]

<p>where $A$ has $m$ data points and $B$ has $n$ data points, and each element $k_{ij}$ ranges from 0~1.</p>

<p>Assuming the training set is ${X_1, Y_1}$ and testing set is $X_2$, now our task is to predict the label $\hat{Y_2}$ of $X_2$. The prediction value of each data can be modeled to satisfy the Gaussian distribution according to Gaussian process, which can be formulated as:</p>

\[\left(\begin{matrix}
  f \\ f_s
\end{matrix}\right)
\sim 
\mathcal{N}\left( \left(\begin{matrix} \mu \\ \mu_s\end{matrix}\right), \left(\begin{matrix} K &amp; K_s \\ K^\text{T}_s &amp; K_{ss}\end{matrix}\right) \right)\]

<p><strong>The overall algorithm is as follows:</strong><br />
<strong>Step 1:</strong> compute variance $K_{ss}$ for testing data, $K_{ss} = e^{-\frac{1}{2p}(X_2 \ominus X_2)}$, with the size of $N \times N$.<br />
<strong>Step 2:</strong> (optional) compute prior</p>

\[L_{ss}L^{\text{T}}_{ss} = K_{ss}\]

\[f_{prior} = \mu_s + L_{ss}\mathcal{N}(0, I)\]

<p>where $L_{ss}$ can be obtained using Cholesky decomposition and $\mu_s$ is unknown so far (however we can assume to be zero here to visualize the $f_{prior}$). $f_{prior}$ has the size of $N \times 1$.<br />
<strong>Step 3:</strong> compute variance $K$ for training data, $K = e^{-\frac{1}{2p}(X_1 \ominus X_1)}$, with the size of $M \times M$.</p>

\[LL^{\text{T}} = K\]

<p>So that $L = CholeskyDecom(K)$, with the size of $M \times M$.<br />
<strong>Step 4:</strong> compute covariance between training data and testing data $K_s$, $K_s = e^{-\frac{1}{2p}(X_1 \ominus X_2)}$, with the size of $M \times N$.</p>

\[LL_{s} = K_s\]

<p>We can obtain $L_{s}=linearSolve(L, K_s)$, with the size of $M \times N$.<br />
<strong>Step 5:</strong> compute the mean at test points</p>

\[LL'=y\]

\[\mu_s = L^{\text{T}}_sL'\]

<p>where $\mu_s$ has the size of $N \times 1$.<br />
<strong>Step 6:</strong> compute the posterior</p>

\[L'_{ss}L'^{\text{T}}_{ss} = K_{ss}-L^{\text{T}}_sL_{s}\]

<p>so that 
\(L'_{ss}=CholeskyDecom(K_{ss}-L^{\text{T}}_sL_s)\)
has the size of $N \times N$. Then, the posterior function is
<!-- $L'_{ss}=CholeskyDecom(K_{ss}-L^{\text{T}}_sL_s)$, with the size of $N \times N$. The posterior function is  -->
<!-- ' is not supported in inline-math latex in github.io--></p>

\[f_{post} = \mu_s + L'_{ss}\mathcal{N}(0, I)\]

<p>The standard deviation can be computed by</p>

\[s2=diag(K_{ss}) - diag(L^{\text{T}}_sL_s)=diag(K_{ss}-L^{\text{T}}_sL_{s})\]

\[stdv = sqrt(s2)\]

<p>$diag(.)$ means utilizing the diagnal elements to form a vector so that $s2$ has the size of $N \times 1$. $stdv$ is the computed standard diviation. The oscillation range of posterior function can be written as</p>

\[\mu_s \pm j\cdot stdv\]

<p>For example, $\mu_s \pm 1\cdot stdv$, $\mu_s \pm 2\cdot stdv$, $\mu_s \pm 3\cdot stdv$, etc.</p>

<!-- Not use symbol ** in latex as it will cause error when posting in github.io. For example, $\mu_{s} \pm 1*stdv$, $\mu_{s} \pm 2*stdv$, $\mu_{s} \pm 3*stdv$, etc. -->]]></content><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><category term="Learning Notes" /><summary type="html"><![CDATA[Using Gaussian Process for prediction]]></summary></entry><entry><title type="html">Zero/One/Few Shot Learning</title><link href="https://alanlusun.github.io/posts/2020-09-10-Zero-One-Few-Shot-Learning/" rel="alternate" type="text/html" title="Zero/One/Few Shot Learning" /><published>2020-09-10T00:00:00-07:00</published><updated>2020-09-10T00:00:00-07:00</updated><id>https://alanlusun.github.io/posts/Zero-One-Few-Shot-Learning</id><content type="html" xml:base="https://alanlusun.github.io/posts/2020-09-10-Zero-One-Few-Shot-Learning/"><![CDATA[<h1 id="zeroonefew-shot-learning">Zero/One/Few Shot Learning</h1>
<p><em>Author: Changsheng Lu (卢长胜)</em></p>

<h2 id="1zero-shot-learning">1、Zero-shot Learning</h2>
<h3 id="problem-definition">Problem definition:</h3>
<p>Learning a model to work on unseen data when training and testing classes are disjoint. Taking the task of zero-shot object classification as an example, when training an object classifier, there is no training samples of target classes. While in testing phase, we expect the object classifier could recognize the unseen target object to be a new class.</p>

<h3 id="methods">Methods:</h3>
<ul>
  <li>Attribute-based method [1]</li>
  <li>Attribute Label Embedding (ALE) [2]</li>
  <li>Zero-shot Kernel Learning (ZSKL) [3]</li>
</ul>

<h3 id="dataset">Dataset:</h3>
<ul>
  <li><a href="https://cvml.ist.ac.at/AwA2/">Animals with Attributes (AWA)</a></li>
  <li></li>
</ul>

<h3 id="references">References</h3>
<p>[1] Lampert, Christoph H., Hannes Nickisch, and Stefan Harmeling. “Learning to detect unseen object classes by between-class attribute transfer.” In 2009 IEEE Conference on Computer Vision and Pattern Recognition, pp. 951-958. IEEE, 2009.<br />
[2] Akata, Zeynep, Florent Perronnin, Zaid Harchaoui, and Cordelia Schmid. “Label-embedding for attribute-based classification.” In Proceedings of the IEEE conference on computer vision and pattern recognition, pp. 819-826. 2013.<br />
[3] Zhang, Hongguang, and Piotr Koniusz. “Zero-shot kernel learning.” In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pp. 7670-7679. 2018.</p>

<h2 id="2few-shot-learning">2、Few-shot Learning</h2>
<h3 id="definition">Definition:</h3>
<p>Few-shot learning refers to understand new concepts from only a <em>few</em> examples.</p>

<h3 id="a-taxonomy-of-methods">A Taxonomy of Methods:</h3>
<ul>
  <li>Metric-based method (Prior knowledge about similarity)
    <ul>
      <li>Siamese Network (Koch et al., 2015) [2] (pairwise comparator + predefined distance metric)</li>
      <li>Triplet Network (Hoffer &amp; Ailon, 2015) [7] (pairwise comparator + predefined metric)</li>
      <li>Matching Network (Oriol et al., 2016) [3] (multi-class comparator + predefined metric)</li>
      <li>Prototype Network (Snell et al., 2017) [4] (multi-class comparator + predefined metric)</li>
      <li>Relation Networks (Santoro et al., 2016) [1] (use relation/similarity network in replace of pre-defined distance metric like [2-4, 7])</li>
    </ul>
  </li>
  <li>Optimization-based method (Prior knowledge about learning)<br />
Learn a model with a good parameter status (compared to directly use related model or randomly initialized model) to be easier to finetune or adapt.<br />
Methods:
    <ul>
      <li>Bayesian approach [8]</li>
      <li>Model-agnostic meta-learning (MAML) (Finn &amp; Levine, 2017) [5]</li>
    </ul>
  </li>
  <li>Data-based method (Prior knowledge about data)<br />
    1) Lean a generative model for family of classes or 2) Learn to synthesize new examples and train with augmented data</li>
</ul>

<h3 id="loss-functions">Loss functions</h3>
<ul>
  <li>Cross entropy loss<br />
$L = Ylog(P) + (1-Y)log(1-P)$</li>
  <li>Contrasive loss<br />
$L = (1-Y)\frac{1}{2}D^{2} + Y\frac{1}{2}{max(0, m-D)}^2$<br />
where $D$ is the distance function acted for embeddings. So the loss will decrease the distance D when the samples are from the same class, on the other hand when they are dissimilar it will try to increase D with a certain margin m. The margin purpose is to neglect samples that have larger distance than m, since we only want to focus on dissimilar samples that appear to be close.</li>
  <li>Triplet loss [7]<br />
$L = max(D(X, X^{+}) - D(X, X^{-}) + m, 0)$</li>
</ul>

<h3 id="dataset-1">Dataset:</h3>
<ul>
  <li><a href="https://github.com/brendenlake/omniglot">Omniglot</a> [6], the few-shot version of MNIST. This dataset has 1623 characters from 50 alphabets. In each class, there are 20 samples drawn by 20 peoples. Each image has size of 105 x 105.</li>
  <li>Mini-ImageNet [4]. This dataset has 60000 RGB images from 100 classes and the image resolution is 84 x 84.</li>
</ul>

<h3 id="useful-links">Useful links:</h3>
<ul>
  <li><a href="https://www.borealisai.com/en/blog/tutorial-2-few-shot-learning-and-meta-learning-i/">Tutorial about few-shot leanring and meta-learning I</a></li>
  <li><a href="https://www.borealisai.com/en/blog/tutorial-3-few-shot-learning-and-meta-learning-ii/">Tutorial about few-shot leanring and meta-learning II</a></li>
</ul>

<h3 id="references-1">References</h3>
<p>[1] Santoro A, Bartunov S, Botvinick M, et al. One-shot learning with memory-augmented neural networks[J]. arXiv preprint arXiv:1605.06065, 2016. <br />
[2] Koch, Gregory, Richard Zemel, and Ruslan Salakhutdinov. “Siamese neural networks for one-shot image recognition.” ICML Deep Learning Workshop. Vol. 2. 2015.<br />
[3] Oriol Vinyals, Charles Blundell, Tim Lillicrap, Daan Wierstra, et al. Matching networks for one shot learning. In Advances in Neural Information Processing Systems, pages 3630–3638, 2016.<br />
[4] Snell, Jake, Kevin Swersky, and Richard Zemel. “Prototypical networks for few-shot learning.” Advances in Neural Information Processing Systems. 2017.<br />
[5] Finn, Chelsea, Pieter Abbeel, and Sergey Levine. “Model-agnostic meta-learning for fast adaptation of deep networks.” Proceedings of the 34th International Conference on Machine Learning-Volume 70. JMLR. org, 2017.<br />
[6] Lake, Brenden, et al. “One shot learning of simple visual concepts.” Proceedings of the Annual Meeting of the Cognitive Science Society. Vol. 33. No. 33. 2011.<br />
[7] Hoffer, Elad, and Nir Ailon. “Deep metric learning using triplet network.” International Workshop on Similarity-Based Pattern Recognition. Springer, Cham, 2015.
[8] Fei-Fei, Li, Rob Fergus, and Pietro Perona. “One-shot learning of object categories.” IEEE transactions on pattern analysis and machine intelligence 28, no. 4 (2006): 594-611.</p>

<h2 id="3one-shot-learning">3、One-shot Learning</h2>
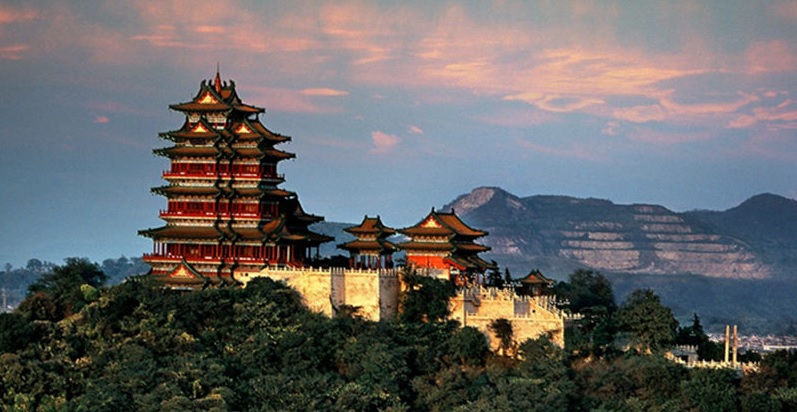
<p>One-shot learning is a particular case of few-shot learning when ‘shot’ $k = 1$.</p>]]></content><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><category term="Learning Notes" /><summary type="html"><![CDATA[quick cookbook on Zero/One/Few Shot Learning]]></summary></entry><entry><title type="html">阅江楼记</title><link href="https://alanlusun.github.io/posts/2020-02-02-Yuejiang-Tower/" rel="alternate" type="text/html" title="阅江楼记" /><published>2020-02-02T00:00:00-08:00</published><updated>2020-02-02T00:00:00-08:00</updated><id>https://alanlusun.github.io/posts/Yuejiang-Tower</id><content type="html" xml:base="https://alanlusun.github.io/posts/2020-02-02-Yuejiang-Tower/"><![CDATA[<p><em>天高地远</em><br />
<em>大江东流</em><br />
<em>浮云洒明暗</em><br />
<em>极目尽神州</em><br />
<em>南北山河界</em><br />
<em>因桥大一统</em><br />
<em>点点烈焰缀金龙</em><br />
<em>一贯长虹</em><br />
<em>何其汹汹</em><br />
<em>凭栏侧倚</em><br />
<em>微风桥头</em></p>

<p><em>青石古阶</em><br />
<em>桂树香飘</em><br />
<em>雄狮踞左右</em><br />
<em>万舸争上游</em><br />
<em>首尾地平线</em><br />
<em>白茫隐仙洲</em><br />
<em>一曲江水伴亭楼</em><br />
<em>风花雪月</em><br />
<em>高歌几首</em><br />
<em>世纪潮流</em><br />
<em>不畏西东</em></p>

<p>2014.9.20<br />
登阅江楼，南京</p>

<p><img src="https://alanlusun.github.io//images/post-images/2020/Yuejiang-Tower.jpg" width="100%" /></p>]]></content><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><category term="Poem" /><summary type="html"><![CDATA[点点烈焰缀金龙，一贯长虹，何其汹汹；凭栏侧倚，微风桥头]]></summary></entry><entry><title type="html">如果我是一个音乐家</title><link href="https://alanlusun.github.io/posts/2019-02-19-If-I-am-A-Musician/" rel="alternate" type="text/html" title="如果我是一个音乐家" /><published>2019-02-19T00:00:00-08:00</published><updated>2019-02-19T00:00:00-08:00</updated><id>https://alanlusun.github.io/posts/If-I-am-A-Musician</id><content type="html" xml:base="https://alanlusun.github.io/posts/2019-02-19-If-I-am-A-Musician/"><![CDATA[<p><em>如果我是一个音乐家</em><br />
<em>也能填词歌唱</em><br />
<em>唱出爱</em><br />
<em>唱出不一样的平凡</em></p>

<p><em>如果我是一个音乐家</em><br />
<em>也能抚琴轻弹</em><br />
<em>曲调悠扬</em><br />
<em>直到遇见她</em></p>

<p><em>如果我是一个音乐家</em><br />
<em>也能四处流浪</em><br />
<em>为穷人演奏</em><br />
<em>为自己加油</em></p>

<p><em>如果我是一个音乐家</em><br />
<em>也能传递能量</em><br />
<em>美如阳光</em><br />
<em>灿若莲花</em></p>

<p><em>如果我是一个音乐家</em><br />
<em>也能委婉表达</em><br />
<em>以上</em><br />
<em>便是生活的式样</em></p>]]></content><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><category term="Poem" /><summary type="html"><![CDATA[如果我是一个音乐家]]></summary></entry><entry><title type="html">Git Learning Note</title><link href="https://alanlusun.github.io/posts/2018-06-03-Git-Note/" rel="alternate" type="text/html" title="Git Learning Note" /><published>2018-06-03T00:00:00-07:00</published><updated>2018-06-03T00:00:00-07:00</updated><id>https://alanlusun.github.io/posts/Git-Note</id><content type="html" xml:base="https://alanlusun.github.io/posts/2018-06-03-Git-Note/"><![CDATA[<h1 id="my-git-learning-note">My Git Learning Note</h1>
<p><em>Author: Changsheng Lu (卢长胜)</em></p>

<h2 id="0install-git">0、Install Git</h2>
<p>i) download Git from <a href="https://git-scm.com/">official website</a> and install it in your computer. Please note that downloading suitable version according to the OS of your computer.<br />
ii) run the <strong>Git bash</strong> in your desired directory.</p>

<h2 id="1create-repository-in-two-ways">1、Create repository in two ways</h2>
<p>i) create a local repository by cloning repo from cloud. The default up-stream is the repo that you cloned.</p>
<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code>   <span class="c1"># option 1
</span>   <span class="n">git</span> <span class="n">clone</span> <span class="n">https</span><span class="p">:</span><span class="o">//</span><span class="n">github</span><span class="p">.</span><span class="n">com</span><span class="o">/</span><span class="n">AlanLuSun</span><span class="o">/</span><span class="n">Circle</span><span class="o">-</span><span class="n">detection</span><span class="p">.</span><span class="n">git</span>
   <span class="c1"># option 2 (recommended), use PAT to be free of authentication 
</span>   <span class="n">git</span> <span class="n">clone</span> <span class="n">https</span><span class="p">:</span><span class="o">//</span><span class="n">AlanLuSun</span><span class="p">:</span><span class="o">&lt;</span><span class="n">token</span><span class="o">&gt;@</span><span class="n">github</span><span class="p">.</span><span class="n">com</span><span class="o">/</span><span class="n">AlanLuSun</span><span class="o">/</span><span class="n">Circle</span><span class="o">-</span><span class="n">detection</span><span class="p">.</span><span class="n">git</span>  

   <span class="c1">#-------------------optional-------------------
</span>   <span class="c1"># option 1 
</span>   <span class="n">git</span> <span class="n">remote</span> <span class="n">add</span> <span class="n">origin</span> <span class="n">https</span><span class="p">:</span><span class="o">//</span><span class="n">github</span><span class="p">.</span><span class="n">com</span><span class="o">/</span><span class="n">AlanLuSun</span><span class="o">/</span><span class="n">Circle</span><span class="o">-</span><span class="n">detection</span><span class="p">.</span><span class="n">git</span>
   <span class="c1"># option 2 (recommended), use PAT to be free of authentication
</span>   <span class="n">git</span> <span class="n">remote</span> <span class="n">add</span> <span class="n">origin</span> <span class="n">https</span><span class="p">:</span><span class="o">//</span><span class="n">AlanLuSun</span><span class="p">:</span><span class="o">&lt;</span><span class="n">token</span><span class="o">&gt;@</span><span class="n">github</span><span class="p">.</span><span class="n">com</span><span class="o">/</span><span class="n">AlanLuSun</span><span class="o">/</span><span class="n">Circle</span><span class="o">-</span><span class="n">detection</span><span class="p">.</span><span class="n">git</span>  
   <span class="c1">#-------------------optional-------------------
</span>
   <span class="n">git</span> <span class="n">branch</span> <span class="o">-</span><span class="n">M</span> <span class="n">main</span>  
   <span class="n">git</span> <span class="n">push</span> <span class="o">-</span><span class="n">u</span> <span class="n">origin</span> <span class="n">main</span>
</code></pre></div></div>

<p>ii) create a local folder, and then initialize it with instructions as follows</p>
<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code>   <span class="n">git</span> <span class="n">init</span>  
   <span class="n">git</span> <span class="n">add</span> <span class="n">README</span><span class="p">.</span><span class="n">md</span> <span class="p">(</span><span class="ow">or</span> <span class="n">using</span> <span class="n">git</span> <span class="n">add</span> <span class="p">.</span> <span class="n">to</span> <span class="n">add</span> <span class="nb">all</span> <span class="n">files</span><span class="p">)</span>    
   <span class="n">git</span> <span class="n">commit</span> <span class="o">-</span><span class="n">m</span> <span class="s">"first commit"</span>  
   <span class="n">git</span> <span class="n">branch</span> <span class="o">-</span><span class="n">M</span> <span class="n">main</span>  

   <span class="c1"># option 1
</span>   <span class="n">git</span> <span class="n">remote</span> <span class="n">add</span> <span class="n">origin</span> <span class="n">https</span><span class="p">:</span><span class="o">//</span><span class="n">github</span><span class="p">.</span><span class="n">com</span><span class="o">/</span><span class="n">AlanLuSun</span><span class="o">/</span><span class="n">Circle</span><span class="o">-</span><span class="n">detection</span><span class="p">.</span><span class="n">git</span> 
   <span class="c1"># option 2 (recommended), use PAT to be free of authentication
</span>   <span class="n">git</span> <span class="n">remote</span> <span class="n">add</span> <span class="n">origin</span> <span class="n">https</span><span class="p">:</span><span class="o">//</span><span class="n">AlanLuSun</span><span class="p">:</span><span class="o">&lt;</span><span class="n">token</span><span class="o">&gt;@</span><span class="n">github</span><span class="p">.</span><span class="n">com</span><span class="o">/</span><span class="n">AlanLuSun</span><span class="o">/</span><span class="n">Circle</span><span class="o">-</span><span class="n">detection</span><span class="p">.</span><span class="n">git</span>

   <span class="n">git</span> <span class="n">push</span> <span class="o">-</span><span class="n">u</span> <span class="n">origin</span> <span class="n">main</span>
</code></pre></div></div>

<p><em>it should note that we need to specify the remote repo as up-stream by using <strong>git remote add origin …</strong></em></p>

<h2 id="2add-show-and-delete-remote-repos">2、Add, show and delete remote repos</h2>
<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># 1) not recommended
</span><span class="n">git</span> <span class="n">remote</span> <span class="n">add</span> <span class="n">mine</span> <span class="n">https</span><span class="p">:</span><span class="o">//</span><span class="n">github</span><span class="p">.</span><span class="n">com</span><span class="o">/</span><span class="n">AlanLuSun</span><span class="o">/</span><span class="n">Circle</span><span class="o">-</span><span class="n">detection</span><span class="p">.</span><span class="n">git</span>  
<span class="c1"># 2) (recommended) using the command which attaches **Personal Access Token (PAT)** for authentication,  
</span><span class="n">git</span> <span class="n">remote</span> <span class="n">add</span> <span class="n">mine</span> <span class="n">https</span><span class="p">:</span><span class="o">//</span><span class="n">AlanLuSun</span><span class="p">:</span><span class="o">&lt;</span><span class="n">token</span><span class="o">&gt;@</span><span class="n">github</span><span class="p">.</span><span class="n">com</span><span class="o">/</span><span class="n">AlanLuSun</span><span class="o">/</span><span class="n">Circle</span><span class="o">-</span><span class="n">detection</span><span class="p">.</span><span class="n">git</span>  
<span class="n">git</span> <span class="n">remote</span> <span class="o">-</span><span class="n">v</span>  
<span class="n">git</span> <span class="n">remote</span> <span class="n">remove</span> <span class="n">mine</span>
</code></pre></div></div>

<h2 id="3set-the-head-of-the-remote-up-stream-say-there-exists-two-remote-repos-mine-and-origin-and-we-wanna-set-origin-as-head">3、Set the head of the remote up-stream. say there exists two remote repos: mine and origin, and we wanna set origin as head.</h2>
<p>1) git remote set-head origin</p>

<h2 id="4add-files-to-staging-environment">4、Add files to staging environment</h2>
<p>1) git add . //add all files<br />
2) git add test.md //add test.md</p>

<h2 id="5make-a-commit-for-packaging-the-added-files">5、Make a commit for packaging the added files</h2>
<p>1) git commit -m “my commit”</p>

<h2 id="6build-or-delete-a-branch-and-switch-to-desired-branch">6、Build or delete a branch and switch to desired branch</h2>
<p>1) git branch my-branch-name<br />
2) git checkout my-branch-name //switch to branch <em>my-branch-name</em><br />
3) git checkout -b my-branch-name //this command line equals to above two<br />
4) git checkout master  //go back master branch<br />
5) git branch -d branch-name //delete fully merged branch<br />
git branch -D branch-name //delete a branch even if not merged</p>

<h2 id="7merge-branches-suppose-that-we-currently-are-at-master-branch-and-would-like-to-merge-new-branch">7、Merge branches. Suppose that we currently are at <em>master</em> branch and would like to merge <em>new-branch</em></h2>
<p>git merge new-branch</p>

<h2 id="8pull-remote-repo-into-local-repo-which-aims-to-synchronize-local-repo-and-remote-repo">8、Pull remote repo into local repo, which aims to synchronize local repo and remote repo</h2>
<p>1) git fetch origin master<br />
2) git merge origin/master //merge to local branch<br />
3) git pull origin master //this command line equals to above two lines<br />
above command lines can deal with the case of when remote files are different with local files which will lead to push problems.</p>

<h2 id="9automatically-create-a-new-branch-repo-for-remote-master-we-first-create-a-new-branch-for-local-master-and-then-push-it-to-remote-repo">9、Automatically create a new branch repo for remote master. We first create a <em>new-branch</em> for local <em>master</em>, and then push it to remote repo</h2>
<p>1) git checkout -b new-branch<br />
2) …//do something<br />
3) git push origin new-branch //note that current branch is <em>new-branch</em> instead of <em>master</em></p>

<h2 id="10show-current-status">10、Show current status</h2>
<p>1) git status</p>

<h2 id="11configure-user-information">11、Configure user information</h2>
<p>1) configuring user information in local repository<br />
git config –local user.name AlanLuSun<br />
git config –local user.email xxx<br />
we can find the <strong>config</strong> file in .git/<br />
1) configuring user information globally<br />
git config –global user.name AlanLuSun<br />
git config –global user.email xxx<br />
we can find the <strong>.gitconfig</strong> in C:/Users/14545/</p>

<h2 id="12">12、</h2>]]></content><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><category term="Learning Notes" /><summary type="html"><![CDATA[How to use Git from scratch]]></summary></entry><entry><title type="html">大学篇-月过无华</title><link href="https://alanlusun.github.io/posts/2017-09-17-My-College/" rel="alternate" type="text/html" title="大学篇-月过无华" /><published>2017-09-17T00:00:00-07:00</published><updated>2017-09-17T00:00:00-07:00</updated><id>https://alanlusun.github.io/posts/My-College</id><content type="html" xml:base="https://alanlusun.github.io/posts/2017-09-17-My-College/"><![CDATA[<p>文章难在开头，就这样动笔吧。在四牌楼的大礼堂领取到毕业证书的那时起，望着飘扬的旗帜和高挂着的毕业庆典横幅，就一直寻思着写一篇阶段性的小结。对于大学之路的蜿蜒曲折，花落花开，很难做好一个完备的描述，那么我们就简言简述了。</p>

<h1 id="悸动">悸动</h1>
<p>如果青春期是表征了生理方面成长到成熟的重要阶段，那么相对来说，大学这个“青春期”似乎来的晚了些。在我的大学期间，经历非常多感动的瞬间，或快乐，或激动，或受挫，或领悟，或不舍，或庆幸，或失望，或自信昂扬……各种日子交织在脑海，形成一道道亮丽的风景线，没有对错，都是值得，它们都教会了我们成长。</p>

<p>在二零一三年的这个时候，和父亲一起坐车来到南京站，一下车便可以看到很多热情的东大志愿者负责接泊，它们引导着我们坐上了校车。第一眼中的东南大学，是九龙湖校区南门的端庄大气，然后校车途经梅园到桃园，到达了我们所住的桃七，在后来的日子里会发现桃七舍管阿姨待学生们都非常好。东大九龙湖校区大到可以让我迷失方向，在到学校的第一天晚上，我便骑着自行车把整个校园里里外外兜了一圈，认了一遍，晚风拂面，月光皎洁。</p>

<p>我们宿舍的同学来自五湖四海，河南，福建，台湾和江苏。彼此的交流和生活，让我们互相了解，互相帮助，互相学习和互相欣赏。我们周围寝室玩的非常欢，唯一我显得不入流的地方是不会玩游戏，但我会动象棋和打篮球呀。</p>

<p>认识这一片土地，与在这片土地上遇见了一群并肩成长的同学，是一件多么美好的事情。在这里的每一寸光阴，和遇见，都值得我们珍惜。</p>

<h1 id="成长">成长</h1>
<p>经过大学的系统的学习，让我们学会的东西非常多，里面包括但不局限于专业知识，还有学会生活自理并热爱生活，如何与人和睦相处并妥当处理周遭发生的事物，如何学会自主学习并提高解决问题的能力，如何提高自身的修养。我们学校的校训是止于至善，而我们都知道它来自《大学》，大学之道，在明明德，在亲民，在止于至善。至善是极高的人生境界，到此则为止，反而言之，就是这是难以甚至不可到达，里面透露的哲学是指出了一个人生方向，并激励我们不断持之以恒，勤于自勉，不断努力和勇攀高峰。那么在我们的大学里，应该或多或少，让我们前进了一点。</p>

<p>在我的大学一开始，大一上学期有一门课给予我无限的启迪，每当我遇到学习壁垒或者措手不及的事情时，我都会想起它，那便是《C/C++程序设计》。对我们大部分同学而言，这是一个在大学以前未接触过的新的学科，它能够帮助我们学会运用计算机来解决实际问题。我还记得我的第一个程序是在ubuntu下实现1加到100，那是无比令人兴奋的事情，你还记的你的第一个计算机程序吗，也许应该也是和我一样的感觉。在这里我想穿插一个小故事。在小学的时候，大概那时是我刚学完乘除法，一位上高中的老哥曾经给我出过一个数学题目，那便是计算从1加到100，我算了一个下午，从1开始加，草稿纸写的满满，那时就想这题目为什么这么难，由于计算复杂，因此到最后算错了。当公布答案时，运用头尾相加 (1+100 = 2 + 99 = … = 101) 的方法，非常巧妙的解决这个问题时，我那时的表情就是一个惊叹号。对数学的热爱也大概始于那个时候，自此便给我一个很重要的启迪，要善于寻找事物中的内在规律。后来呀，我读到了高斯的故事，才知道原来这个办法是高斯想出来的。看到能够运用计算机解决一个从1加到100的数学问题，而且是有故事的数学问题，自然会让人印象非常深刻。</p>

<p>但这只是一个开头，紧接着，在我们都还萌萌懂懂的学着数组的语法的时候，团队任务来了。李骏扬老师给我们一个选题列表，要求自由组队，并从中选题。那时的我们看看题目，个个很有趣，有做一个迷宫呀，数独呀，有分形 (分形算法)呀，图像缩放呀，计算器呀，求圆周率并且精度达到几千位呀等等。</p>

<p><img src="/images/post-images/2017-09/1.jpg" align="center" style="width:300px" title="唯美的分形图" /></p>

<p>这一门课，直接把我们拔到了一个能够进行项目设计和实现的高度。我非常清楚的记得，我们小组那时候选的是中等难度的图像缩放。也许现在看来，大家会觉得这个太简单了，在matlab或者opencv中函数一调，不就完美解决问题了吗？但在当时，我们水平很有限，却要实现的是原理性的设计和操作。首先要学会图像的像素级操作，然后便是学习，理解并运用一些知识，理论。例如会用到最临近插值，双线性插值，卷积运算等。在那时候，完成这个项目超出了我们能力，因为我们的能力还只是会操作简单的数组。也正因为如此，那段时间过得无比充实，我们翻阅了大量的书籍和文献，经常小组成员一起讨论、分工并解决问题，编写并调试了大量的代码，做了很多的每周一次的报告……</p>

<p><img src="/images/post-images/2017-09/2.png" align="center" style="width:300px" title="图像缩放plus旋转变换" /></p>

<p>经过这一次的驱动型训练，让我们受益匪浅，它的意义不仅仅在于我们做完了一个项目，编写了一个程序，而在于提高了我们自主学习，分析问题和解决问题的能力。在后来，我们会遇到许许多多的困难，无论难度大小，我们都不曾退却，反而更多的是怀揣着一颗拥抱挑战，勇往直前的心。那么，人生路上遇到形形色色的问题时，也是一样的。在后来，我们做过更多的好玩的东西，如五子连珠游戏，旅行商问题，旅游地图的路径规划等等。</p>

<p><img src="/images/post-images/2017-09/3.png" align="center" title="TSP示例(NP-Complete问题)" /></p>

<p>我们大学里面的课程很多，还记得高等数学，大学物理，几何与代数，计算方法，信号与系统，数电，模电，计算机网络，微机原理，自动控制原理，运动控制，过程控制等等。学习这一系列的课程，都是循序渐进的，前者为后者做铺垫。在大学里，需要明确的是，考试成绩并不意味着真正掌握里面的知识，更不意味着会用。同时，在大学里，需要的是全方位的提高，每个人结合自己的兴趣，朝着适合自己的方向努力。</p>

<p>在大学的时候，印象最深的竞赛是高等数学竞赛，智能车比赛和电子设计竞赛。在大一的时候，有一个大家都熟悉又望而兴叹的比赛，它名叫高等数学竞赛。我也很好奇，进入大学发现大家对高等数学很感冒，并不是很多人喜欢数学。其实高等数学没有想象那么困难，反而很生动形象，当初教我们高数的马老师每次上课都是洋溢着笑容的，也很风趣。高等数学比赛首先需要通过校级选拔，然后才能代表学校参加省级比赛。那个时候，学校为了准备省赛，每周末花一天的时间为我们培训，因此大一下学期几乎很少自由时间。数学系的老师轮流登场，讲解相关知识。参加高等数学竞赛是非常幸苦的，要花很多的时间练习并想解决问题的办法，有些问题常常很难想到解法。但是到最后，参加省赛时会发现，赛题比校赛还简单！另外，获得高等数学竞赛省一等奖保研加分很丰厚的，喜欢数学的同学们多多注意。大二的时候，该是智能车比赛了。智能车是自动化系举办的一个比赛，由于很有趣，全校各个专业的同学都会热情参与，里面有时还可以碰到经管、人文专业的同学。做智能车最记忆犹新的便是同学们一起调车了。从最开始不懂单片机，传感器和电路，到一步步了解，以及设计赛道识别算法，让小车智能的在赛道上赛跑，这一系列的变化，都是我们逐步成长的过程。做智能车最开始大家都会为硬件感到头疼，到后面就是寻路算法以及如何跑的更快而头疼。但如果能够完成这整个比赛，那么每个同学都会对硬件，嵌入式软件和信号处理都有较好的理解。到了大三，我们还参加了电子设计竞赛。电子设计竞赛非常注重团队合作，需要在很短的时间内完成作品，是很富有挑战性和趣味性的。由于我做的是测控题，每次都非常有趣。例如激光打靶，倒立摆系统等。电子设计竞赛需要暑期培训一个月，坚持才是硬道理，能够留存并最后参加比赛的队伍都值得我们骄傲，因为这背后需要付出无数的汗水，合作，坚持和智慧。大学里，很多同学对竞赛是怀着敬而远之的心态，不敢触碰。其实世界上最难的事情，不是事情本身，而是是否勇敢的迈出了第一步。如果敢于参加，结果总不会太差；就像爱笑的孩子，运气总不会太差。</p>

<p>在大三暑期，我们都需要实习，那时记得为此参加了华为南京研究所的一轮机试，四轮面试。相对与正式工作的员工，我们实习生的实习生活是快乐轻松的。在实习中，可以初步接触得到工作同事们的日常；可以了解到包含的岗位以及要求；可以感受到工作环境和生活日常；可以了解企业文化和认识职场同事。实习生活，能够帮助我们认识工作，进而认识自己适合哪些工作。为将来求职做进一步的准备。</p>

<p>在大四这一年，就是做研究做学术的一年，在这里，都要感谢夏思宇老师对我的培养和指导，才能够一步步走来。也许在临近毕业前期，我们的一篇论文被IEEE ICIP接收，从而带来了很多的殊荣，但是其中仍有很多可以完善的工作。并且我发现，在这种殊荣的背后，导师的培养非常重要。如果导师对学生进行适当的引导，那么在本科阶段，很多做出优秀成果的同学都可以发表出不错的论文。在大四这一年，我初步的并系统的接受了一定的科研训练，从开始确定研究课题，到后面大量阅读国内外相关文献，总结、探索并提出自己的方法，优化和扩展，取得效果，论文撰写，修改，论文接收，注册，参加会议并做报告。这一系列的过程，都能够让我们收获颇多。同时，对于在最开始还未接触过论文的我们是多么令人向往，因此努力是值得的，因为能够参与到这么一段激动人心的科研训练中来。</p>

<h1 id="话别">话别</h1>
<p>时间在回忆的时候，总是过得特别快。大学里有诸多的点点滴滴，充实着脑海，有很多熟悉的转角和片刻，总能和过去的某个地点和时间对上号。在大学里，我们经历很多的事情和锻炼，学习了很多的知识和技能，提高了自我的认知和修养。而这一切，都在为明天做好铺垫。未来，也会如同那晴空下飘扬的旗帜一般，鲜红炽热。这个夏天，我的大学篇，断断续续的写了好些日子，每一天的晚上，都是皓月当空，而柔和皎洁的月光总是透过窗户跃然于床边，朴实无华。</p>]]></content><author><name>Changsheng Lu &lt;br&gt; 卢长胜</name><email>ChangshengLuu@gmail.com</email></author><category term="College Life" /><summary type="html"><![CDATA[文章难在开头，就这样动笔吧~~]]></summary></entry></feed>