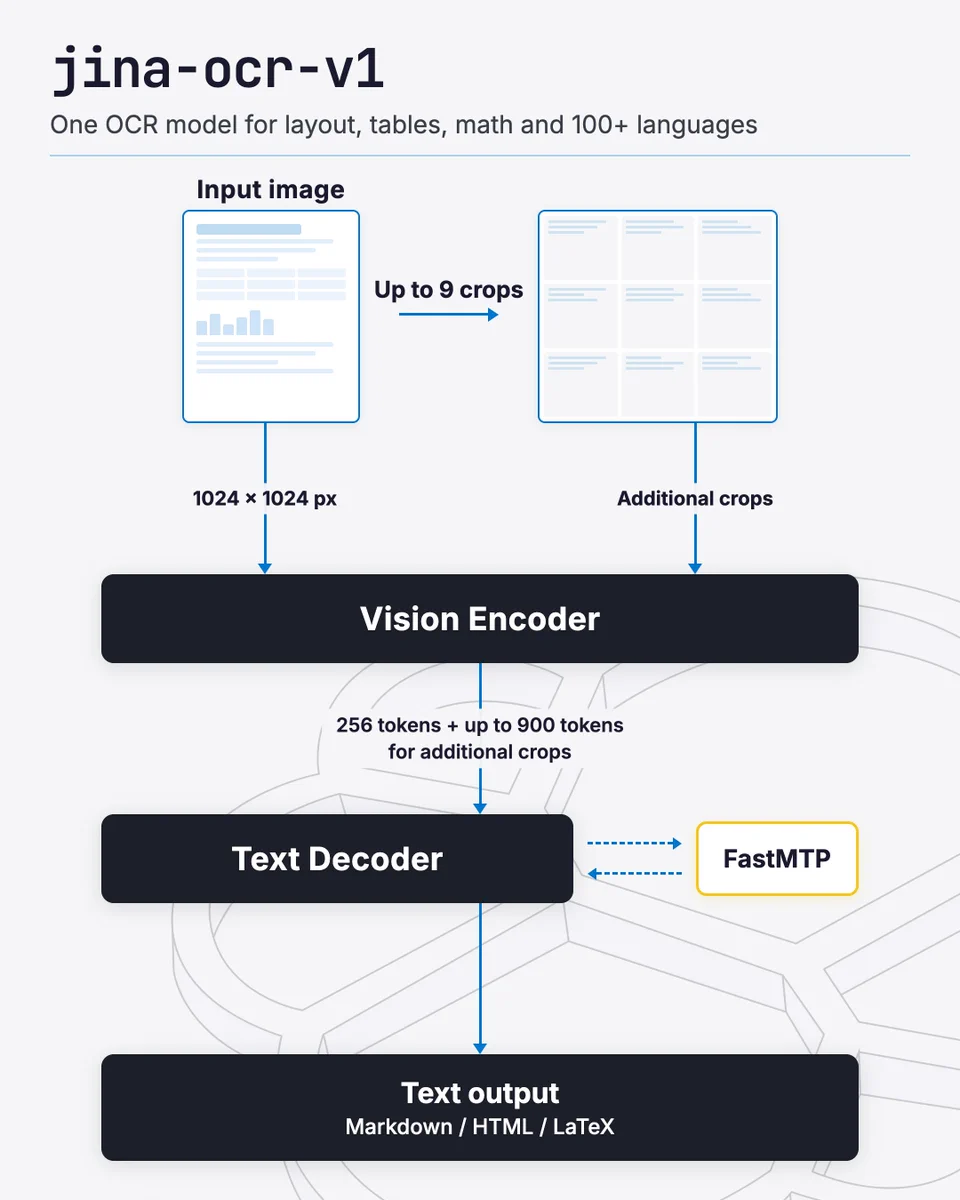
jina-ocr-v1 is now available.
One model covers what otherwise takes a pipeline in OCR: layout, tables, math, handwriting, 100+ languages.
- Scores 83.4 on olmOCR-bench: highest of any OCR model under 600M active parameters
- Scores 91.14 on OmniDocBench, ahead of GPT-5.2
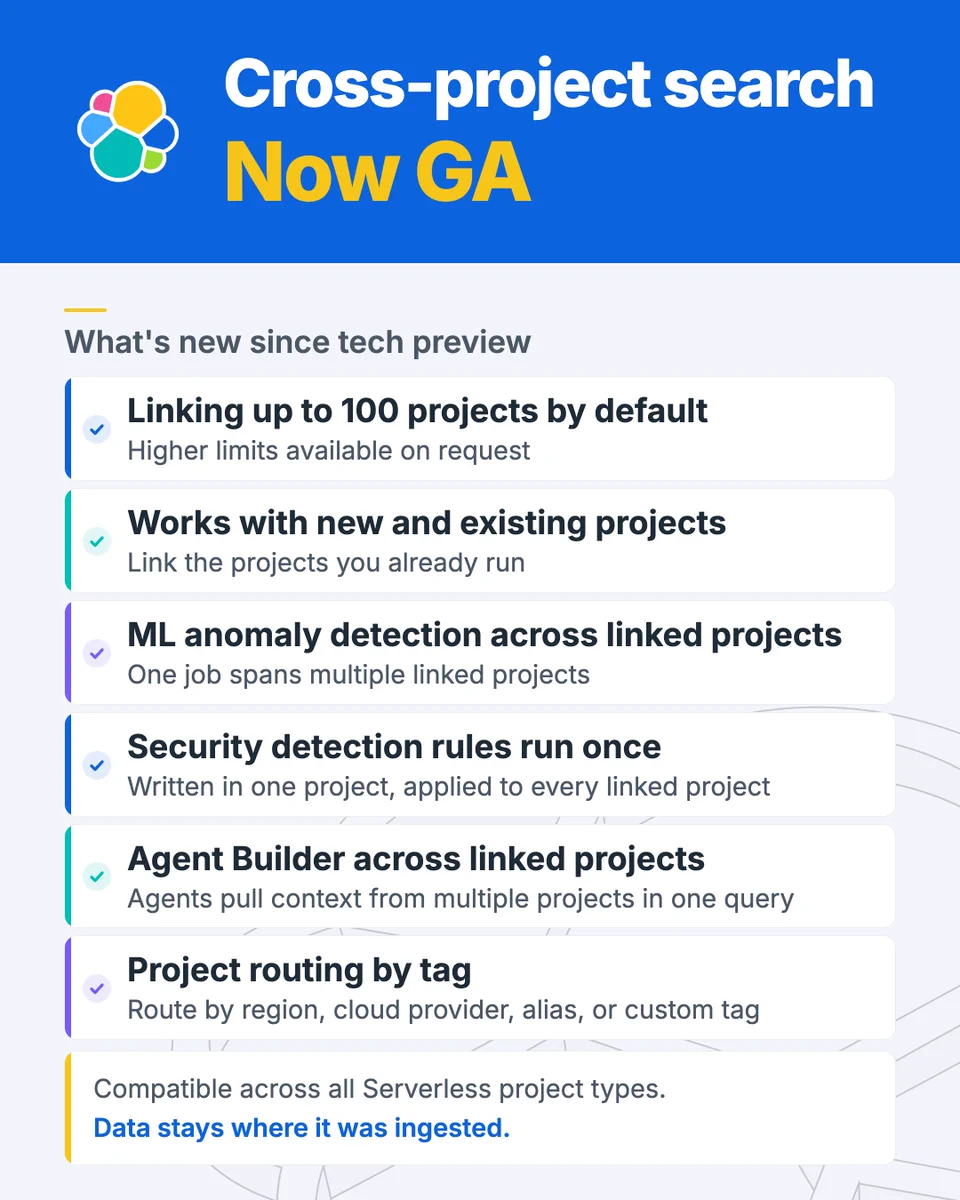
Cross-project search is GA on Elastic Cloud Serverless.
Search across serverless projects in different regions and cloud providers without moving data.
You can now link up to 100 projects by default (higher limits on request) from project settings in the Elastic Cloud console.
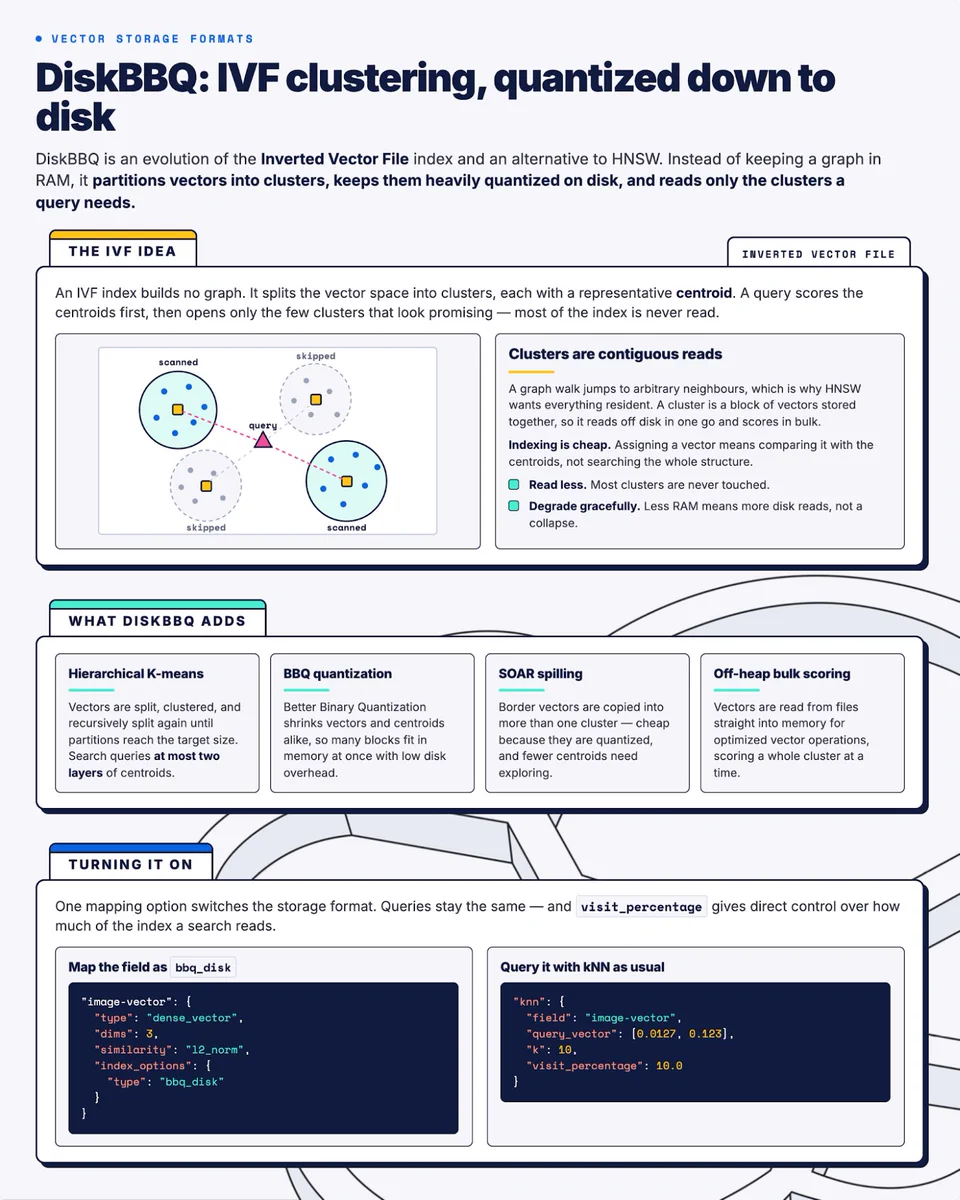
HNSW buys fast search by keeping every vector in RAM.
It needs them there to index too, because indexing means querying the graph you're still building.
DiskBBQ takes the other route:
- Hierarchical k-means groups similar vectors into small clusters
- BBQ compresses each