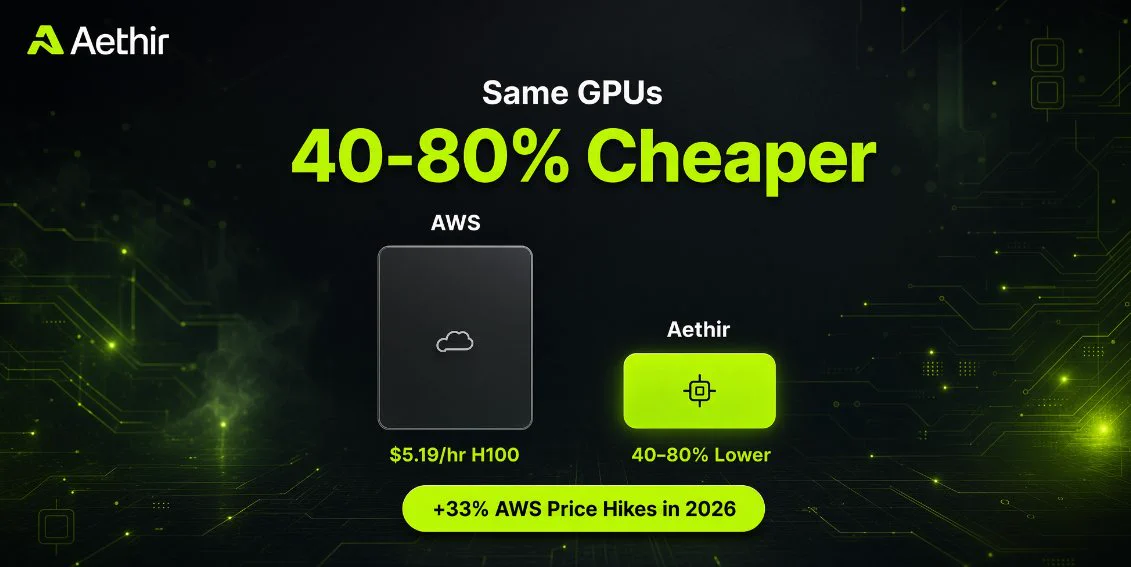
AWS raised GPU prices twice in 2026: 15% in January, another 20% in July.
That is more than 33% year-to-date on the same silicon.
H100 capacity on P5 instances now runs $5.191 an hour, and B300 sits at $14.04 per accelerator-hour🧵
Procurement time is the cost nobody includes in the comparison.
Getting a large GPU allocation from a hyperscaler can mean quota requests, account reviews, regional availability checks, and a multi-year commitment term before a single job actually runs.
Aethir aggregates
Meta’s Muse AI app hit 2.8 million downloads in its first 12 days across the US and Canada. On iOS in those two markets, Muse drew 1.8 million downloads, compared with ChatGPT’s 1.3 million in the same early window, per Apptopia data reported by Reuters.
Every download becomes
Inference quality is partly a serving problem.
A model that answers brilliantly in 900 milliseconds loses to one that answers well in 200, and distance is the variable you actually control.
Aethir runs 430,000 GPU containers across 200+ locations in 94 countries, which means
Industry GPU lead times sit at 36-52 weeks. Aethir provisions enterprise-grade GPU clusters much faster.
That is the operational argument for decentralized infrastructure. When B300 clusters are available across multiple locations, provisioning time shrinks to a procurement