Pinned

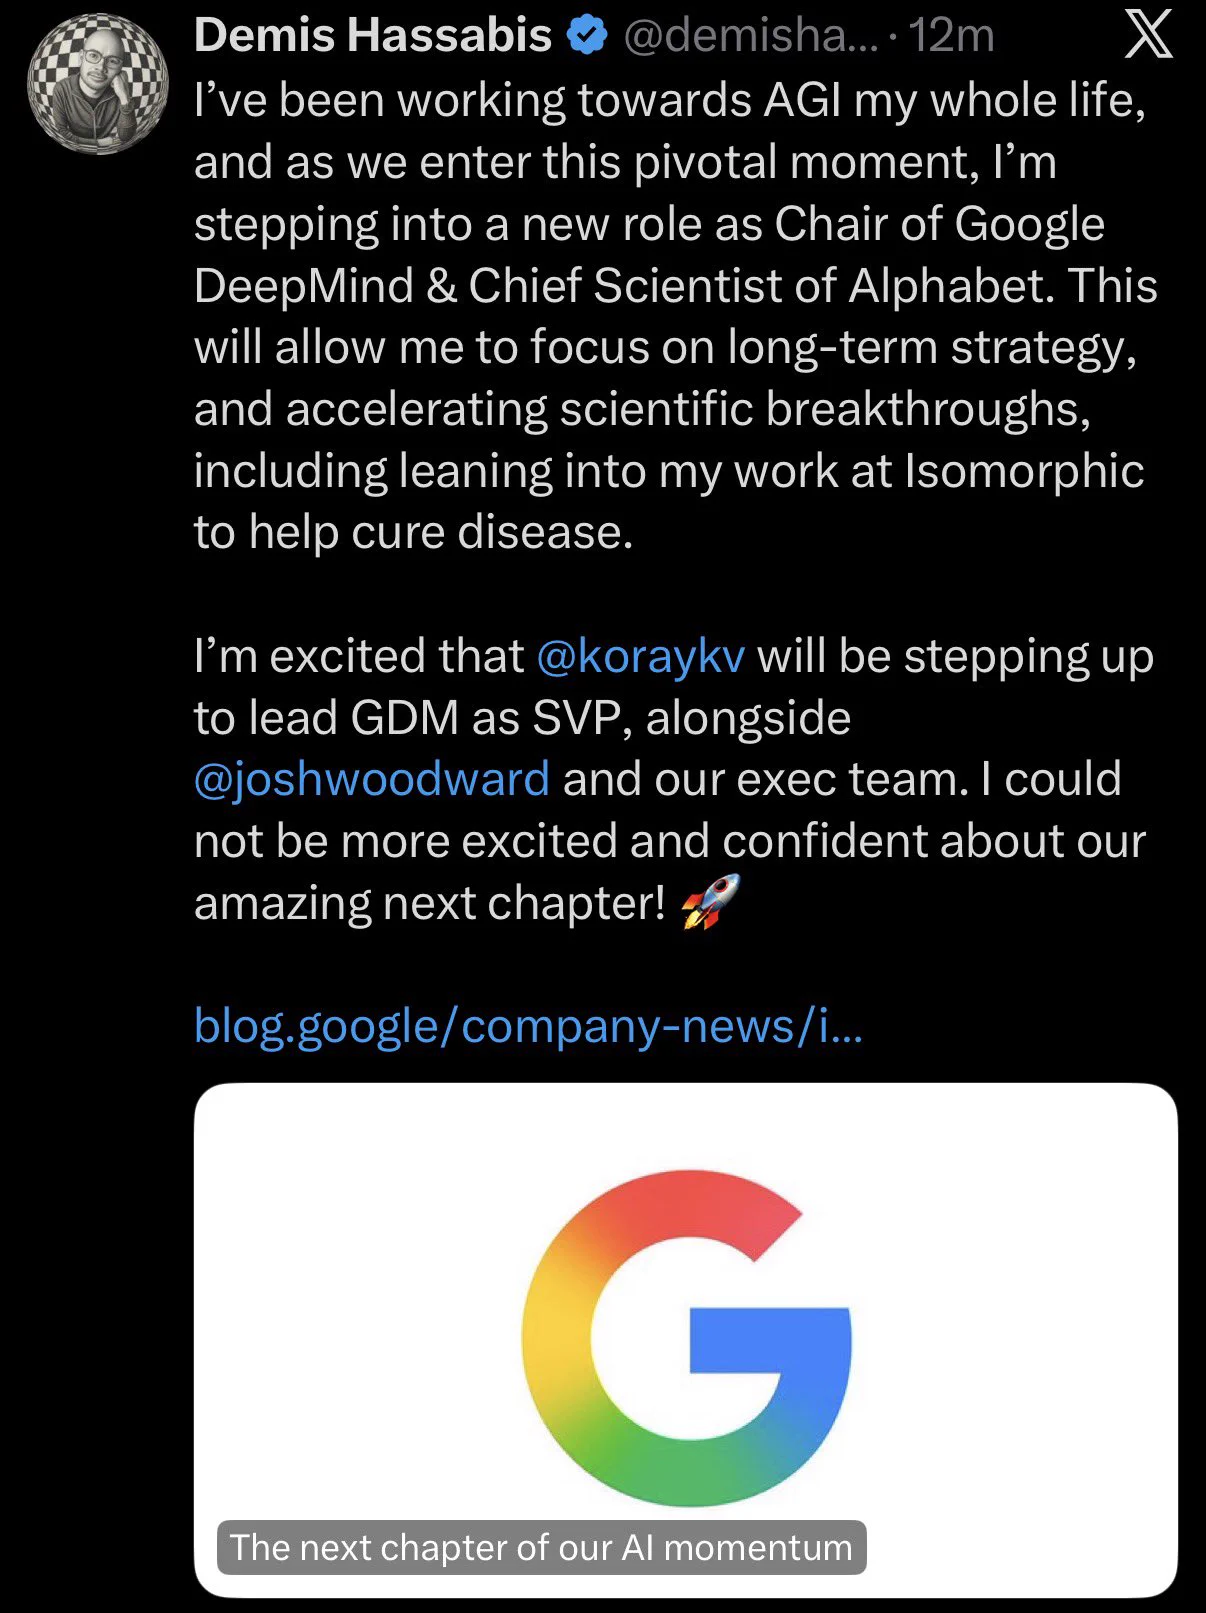
Assembling a team at DeepMind in London.
Scaling up RL for post-training is working, but right now it's still mostly hacks and dark arts (pretraining circa 2019).
Pre-training wasn't always scaling laws and log-log plots; someone had to find the simplicity.
We aim to do the