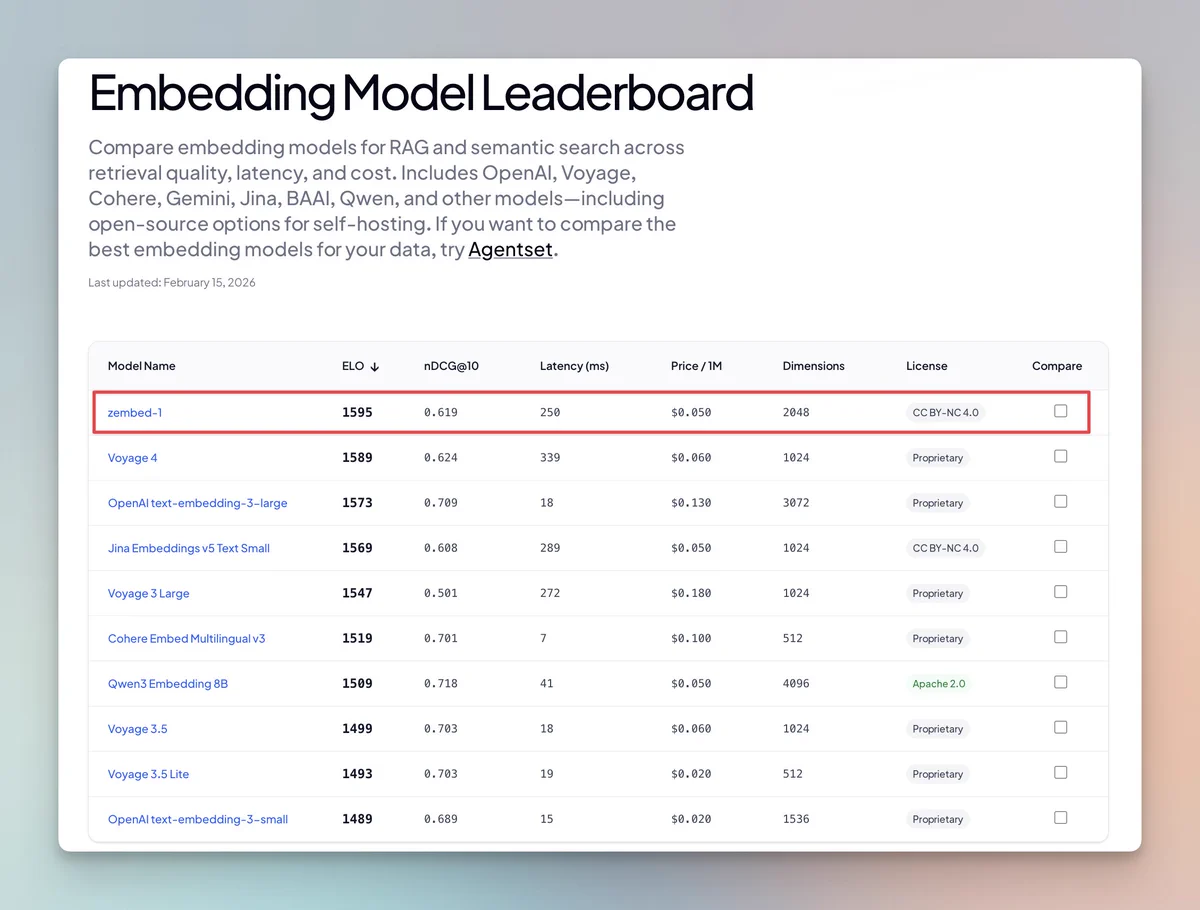
ZeroEntropy recently released zembed-1. We ran it through our embedding leaderboard - it's now #1!
0.946 NDCG@10. 55–80% win rate across 16 models.
Impressive work by @ZeroEntropy_AI!
Full breakdown below.
We tested Claude Opus 4.6 for RAG.
Key takeaways:
- Best for for factual, doc-based Q&A
- Clear upgrade over 4.5 on harder questions
More context is in the blog:
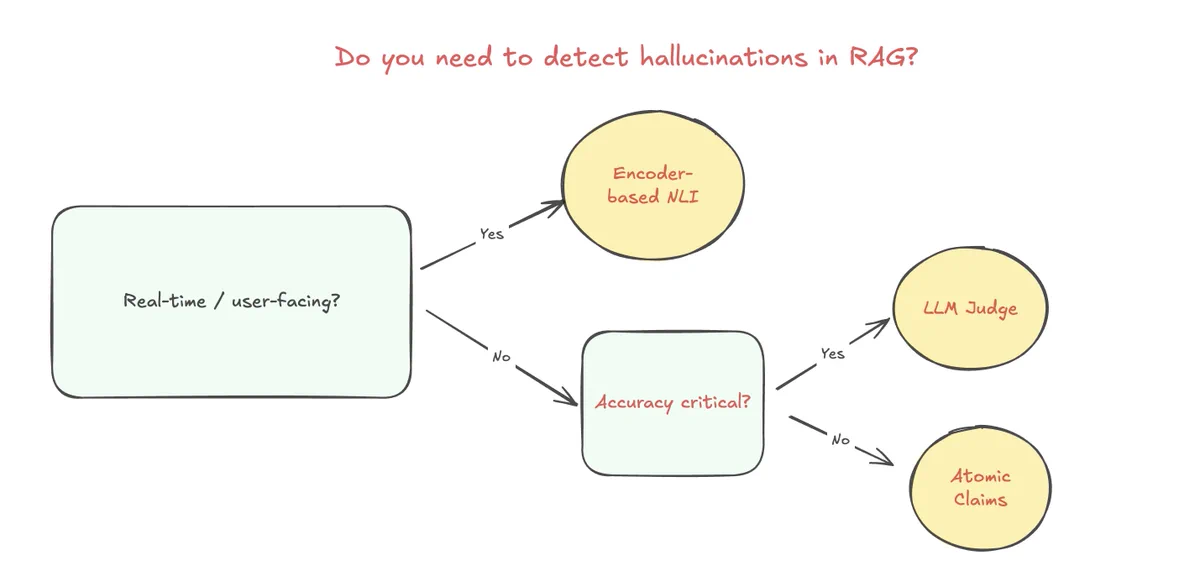
We tested different ways to detect hallucinations in RAG.
LLM judges, atomic claims, encoder-based NLI.
Each comes with clear trade-offs in accuracy, latency, and cost.
Write-up + benchmarks: