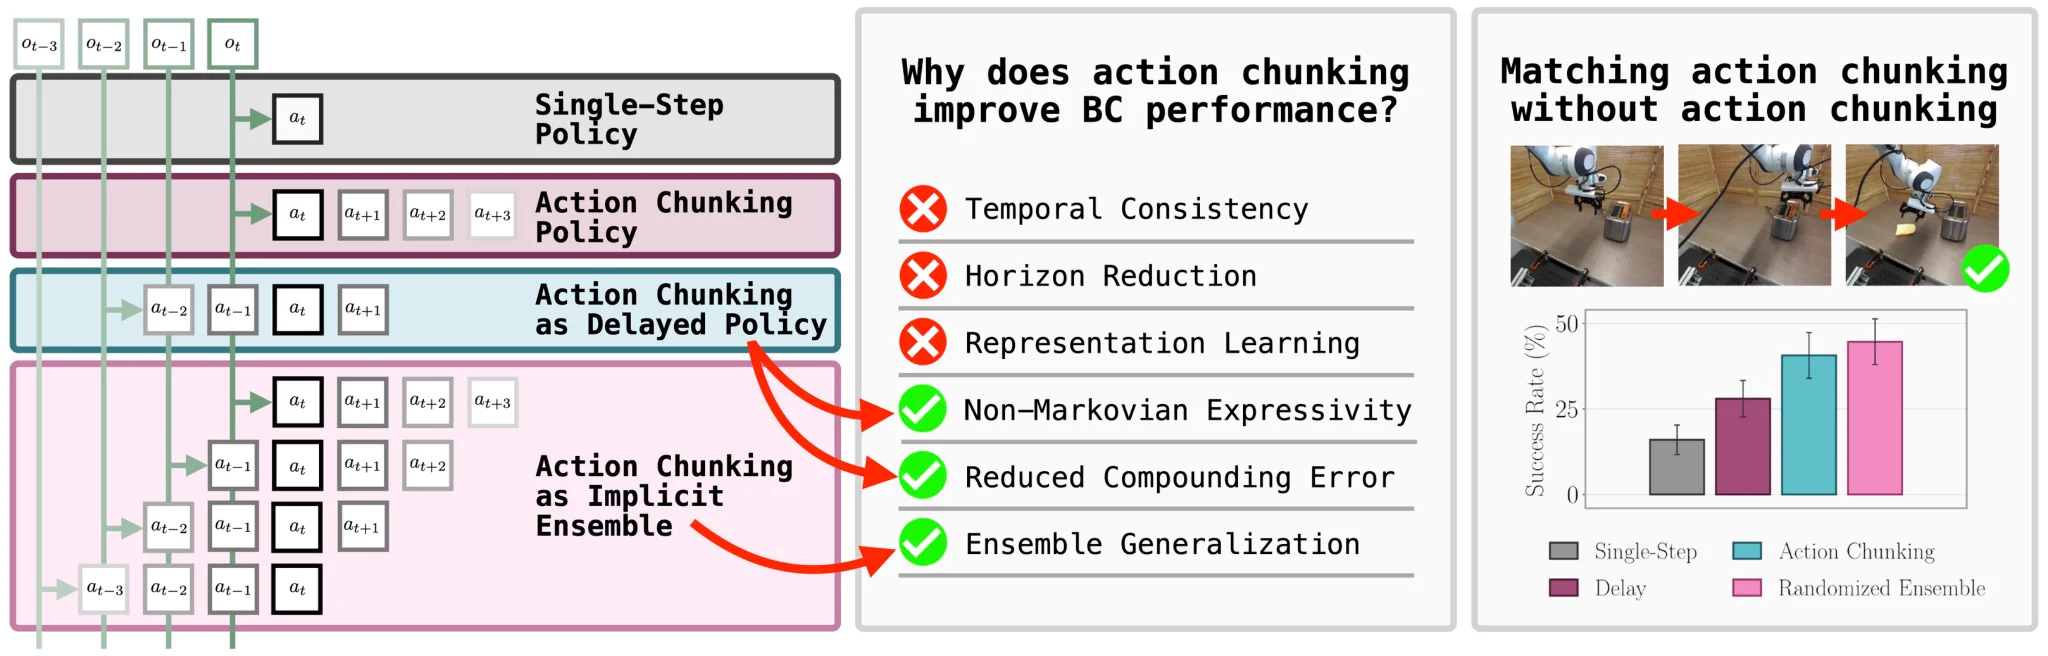
Latency in VLA inference means that, to achieve smooth execution, actions must be computed from past observations. How does this delay affect RL finetuning, and can we still RL finetune effectively under this delay?
See our latest work for some answers!
…rl-intermediate-information.github.io