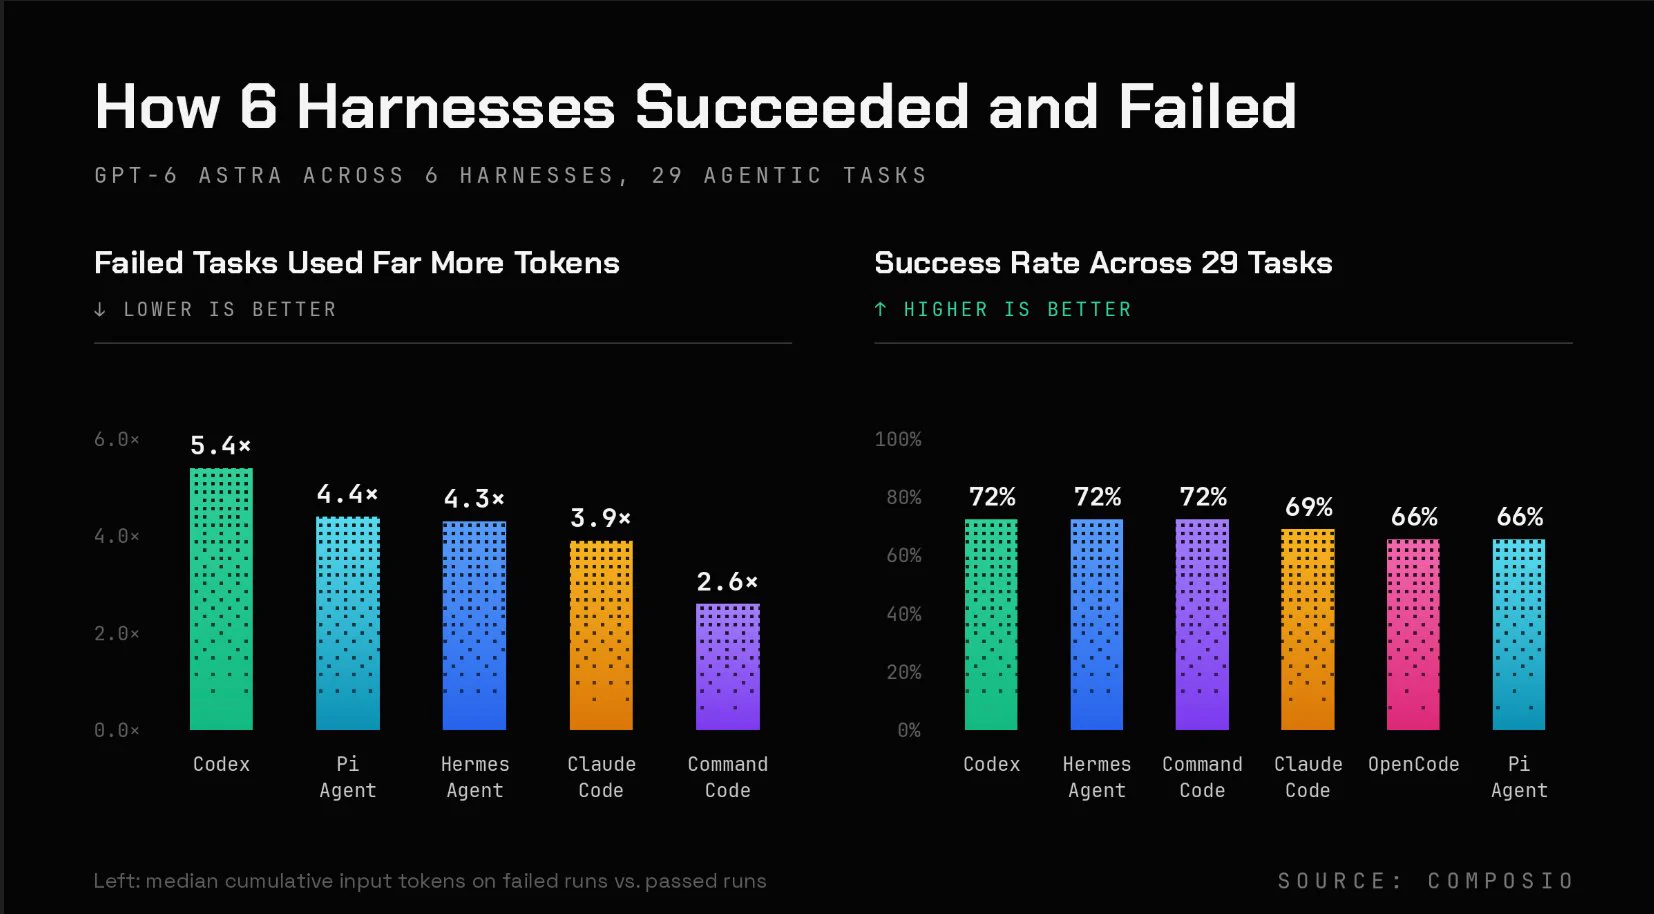
We ran GPT-6 Astra across 6 agent harnesses (Codex, Claude Code, OpenCode, Hermes Agent, Pi Agent, Command Code) on 29 challenging agentic tasks.
Most harnesses succeeded at similar rates. But when they failed, they used 3–5x as many tokens, depending on the harness. 🧵🧵🧵