Your AI tools launch directory. Ship smarter.
A startup directory and product launch platform for AI tools. Discover new launches, compare workflows, and submit your startup for free.
- Launches today
- 11
- Active directory
- 61
- Top categories
- 20
Daily launches
Curated drops land daily. Spot new AI products before the crowd.
Quality filters
Only practical, usable tools. No noise, no empty hype.
Community signals
Real upvotes drive trending. The strongest tools rise.
Launching today
Quiver is an agentic developer marketing system built for technical founders, developer marketing teams and the agents working alongside them. It gives developer marketing the architecture engineers already expect: a source of truth, version history, explicit states, APIs, observability and feedback loops. The system connects product context, customer research, campaigns, content, tasks and performance in one controlled place, so everything a team learns, creates, ships and measures stays connected rather than scattering across chats, documents and separate tools. Quiver is offered in two forms: a managed hosted product with built-in tasks and managed team access, and a free, MIT-licensed self-hosted edition that teams run on their own infrastructure. Quiver starts from a blunt observation about how marketing usually arrives at a technical founder: as vibes and disconnected tactics. One chat holds the positioning, a document holds the plan, customer evidence lives somewhere else, content loses its history the moment it ships, and performance gets reported and then disappears before the next decision is made. The website frames the gap directly, noting that just posting more is not an architecture. The practical consequence is that each marketing cycle tends to restart from scratch rather than compound on what came before, because nothing preserves the evidence, the decisions and the results in one place. Quiver responds by giving the whole marketing operation state, structure and memory, so people and agents can work inside the same controlled system instead of rebuilding context every time. The foundation of Quiver is a set of primitives presented as the actual operating properties of the product rather than a metaphor painted over a chatbot. The first is a source of truth: positioning, ICP, messaging, customer language, proof points and hypotheses all live in one active product context that every agent can draw on. The second is version control for decisions: every change to context and artifacts is versioned and restorable, agents can propose updates, and a person decides what becomes true. The third is a state machine for production workflow: work moves through Draft, Review, Approved, Live and Archived, so finished work is not lost inside chat history. Together these primitives mean the same context and the same production discipline that engineers expect from their own systems are applied to marketing work. Two further primitives connect Quiver to the rest of a team's stack and to real outcomes. Interfaces: Quiver publishes approved content as structured JSON through a public Content API, and an MCP interface lets the agents a team already uses operate Quiver through a real tool surface. That combination allows Quiver to remain the source of truth while a company's own website keeps ownership of presentation. Observability: the plan, research, content, tasks and performance stay connected, so a team can trace what shipped and what happened next instead of treating reporting as a dead end. Feedback loops then close the cycle: outcomes are logged, what worked is captured, and proposed context changes are reviewed before that learning shapes the next cycle, with humans approving what enters the system. The runtime is organized around the idea that the system gets better because the work stays connected. Quiver does not train a mystery model on a company. Instead it preserves the evidence, decisions, shipped work and results that should inform what happens next, and keeps the team in control of what becomes part of the system. The work runs in four steps. First, give the system context: start with the product, audience, positioning, customer language, proof and hypotheses rather than a blank chat window. Second, operate the work: research, sessions, artifacts, content and tasks stay connected to the initiative they are meant to move forward. Third, ship through explicit states: review what agents create, approve what is true, and publish finished work without collapsing generation and production into one step. Fourth, feed results back in: measure the outcome, preserve the learning and improve the context and decisions behind the next cycle, with human approval at the point where proposals become truth. Viewed by function, Quiver describes itself in four ways. For your agents, it provides operators rather than chat tabs: agents get durable context, operational state and tools, and teams can use purpose-built Strategy, Create, Feedback, Analyze and Optimize sessions or connect an external agent through MCP, with the work landing in the system instead of disappearing with the conversation. For your content, it is infrastructure rather than a text box: content keeps its versions, publish state, SEO and social metadata, distribution history, repurposing lineage and metrics, and the Content API serves approved work as structured JSON. For your customer evidence, it is research that changes the system: calls, surveys, reviews and field notes become themes, Voice of Customer quotes, product signals and evidence for or against active hypotheses, and that language is then made available to the agents doing the next piece of work. For your results, it is a loop that actually closes: when work goes live, Quiver creates the reminder to measure it, teams log quantitative results and qualitative notes, synthesize what worked, and review proposed context updates before they affect future sessions. Getting started follows three bootstrap steps. First, initialize the context: paste your website or describe the product, and Quiver drafts the starting context, which you review and make your own by checking the assumptions. Second, connect your model: bring an Anthropic, OpenAI, Google, OpenRouter or any OpenAI-compatible account and choose the model that fits each job, with your provider account determining model cost and the policy governing model usage. Third, start operating: open a session, connect an MCP client or begin with research, knowing that every action starts from the same approved context and writes back to the same system. Several boundaries are stated explicitly. Quiver is not a replacement for a CMS, CRM or analytics tool; it describes itself as the context and decision layer around those systems, using its Content API, MCP interface and publishing workflows to preserve the reasoning, approvals and learning that individual tools often leave disconnected. It also differs from using a standalone model chat directly, because a standalone chat starts with only the context supplied to that conversation, whereas Quiver gives every session and connected agent the same approved, versioned source of truth and then connects the resulting work to campaigns, publishing states and results. It also distinguishes approved knowledge from assumptions: context and artifacts keep their version history and explicit state, and agent proposals do not silently become truth, because a person reviews and approves what enters the active context or moves from draft to live. On deployment, Quiver offers two paths. The Open Source edition is the self-hosted foundation for technical founders and startups comfortable owning the stack, priced at $0 forever with unlimited seats on your own infrastructure: you host the app and database, maintain the deployment and bring your own model account, and you deploy and expose the MCP server code yourself. The hosted editions are run for you. Founder costs $49 per month for up to three seats, or $490 per year billed annually with two months free, and is described as a ready-to-use shared system for a technical founder and up to two teammates. Team costs $99 per month with unlimited seats, or $990 per year billed annually with two months free, and is the expanding hosted team product with room for the whole company. Founder and Team differ only by seats. Hosted plans add built-in tasks, assignments and reminders, a ready-to-invite shared workspace, managed authentication, infrastructure and updates, and a ready-to-connect MCP endpoint with OAuth or scoped tokens. All hosted plans include a 14-day trial, card required, cancel any time. Across editions the same capability list applies: versioned product context with restore, Strategy, Create, Feedback, Analyze and Optimize modes, versioned artifacts with approval and publish states, campaigns linking sessions, research, content and results, customer research synthesis and a Voice of Customer library, hypothesis evidence tracking, a content calendar with SEO/social metadata and repurposing, distribution records and content metric history, a public Content API for approved content, performance synthesis and reviewed context proposals, and BYOK with per-job model selection. The takeaway Quiver reinforces throughout is simple: stop rebuilding the context. By keeping context, work, decisions and learning connected in one approved system, a developer marketing operation gains a system of record that both the human team and its agents can operate from, so each cycle improves the context and the decisions behind the next instead of starting over.
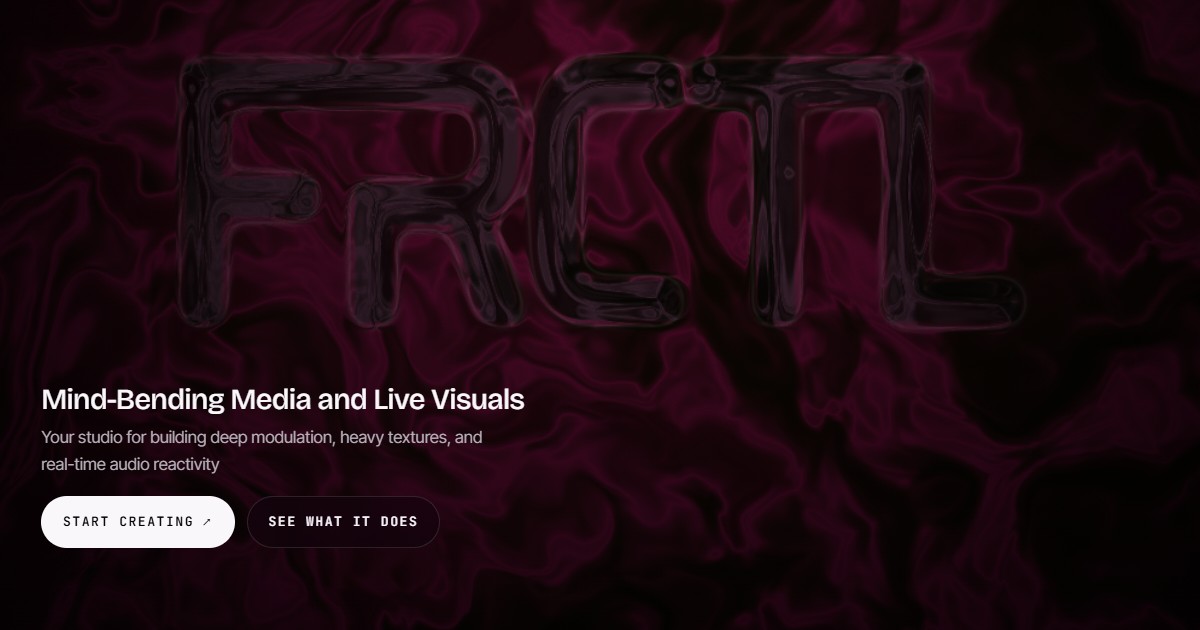
FRCTL is a browser-based VJ studio built for DJs and visual artists who need live, audio-reactive visuals on screen. It describes itself as one engine for everything an artist ships and runs in the browser: you can import your own footage or create generative shader scenes, build a look, and then either pull deliverables such as cover art, a Spotify Canvas or a social clip, or run the loop live with direct full-screen output. FRCTL positions itself as a studio for building deep modulation, heavy textures and real-time audio reactivity, and its tagline invites you to fold it, flip it, glitch it and warp it. The problem FRCTL addresses is fragmentation. Making VJ-style visuals traditionally means switching between tools: one environment for generative or shader-based creation, another for exporting stills and clips, a separate rig for live performance, and yet another place to sell or share presets. Artists who want a signature look usually have to rebuild it at every stage. FRCTL condenses creation, performance and monetization into a single browser-based environment, so the same look can be exported as content or pushed live to a screen. Its free tier deliberately removes the usual barrier: the whole toolkit, no watermark, and full access to both Studio and Live, with limits applied only to file exports. Inside the Creative Studio, FRCTL provides every effect, shader and preset slot with no watermark, and the plan comparison states that the creative power is the same across tiers, with resolution and export length being what changes. The platform advertises 190+ effects with infinite modulation, meaning parameters can be driven and layered continuously rather than applied as static filters, and audio can be routed into any parameter so sound directly controls the image. Artists can start from generative shader scenes or import their own footage as source material, then stack effects and modulation to build heavy textures and deep movement. Unlimited saved presets let a creator maintain a personal library of looks, and the FAQ confirms that presets, saved projects and custom effects remain entirely yours and open normally even if a subscription is cancelled. Live mode delivers real-time performance and audio reactivity directly in the browser. Performers can run their loops with direct full-screen output, sending the visual to the screen without leaving the tool, and live mode also supports camera and canvas capture so a performance can mix captured camera input with the generative canvas. Real-time audio reactivity is the core of the live rig: audio is routed into any parameter, so reactive visuals respond to the music as it plays. The desktop build extends this with live output to Spout and NDI, the routing standards used to send visuals into other applications and into stage, venue or broadcast workflows. From a finished look, FRCTL produces concrete deliverables: cover art, a Spotify Canvas or a social clip. Export capability scales by plan. Free covers 1080p at 30fps with a two-minute timeline cap; Creator moves to 1080p at 60fps with a ten-minute cap; Pro reaches 4K at 60fps with hour-long exports, plus keyed exports with transparency. Pro also unlocks the desktop build for local 4K MP4 rendering. Alongside exports, the Collective is where users sell, share and collaborate: artists can sell presets or loops in the Collective or post and comment on the member feed. Creator and Pro include the commercial license required for paid client work and monetized deliverables, along with version history for projects. FRCTL's overall approach is to run everything from one engine in the browser, so the same creative work flows from studio to export to stage. The workflow described is: import footage or create generative shader scenes, build a look using effects and modulation, then either export cover art, a Spotify Canvas or a social clip, or run the loop live with direct full-screen output. Audio reactivity, camera capture and canvas capture all operate inside that same live environment, and on desktop the same visuals can be routed out through Spout or NDI or rendered locally as 4K MP4. The benefits follow directly from that structure. Artists work in a single tool instead of assembling a chain of separate applications, and they keep ownership of their presets, saved projects and custom effects regardless of subscription status. Because audio can be routed into any parameter, visuals move with the music rather than requiring manual triggering. Because the free tier has no watermark and includes the full toolkit, creators can evaluate the complete creative range before paying, while the commercial license on Creator and Pro gives clear legal clearance for paid client work. Export tiers then scale resolution, frame rate and length as a project grows from a social clip to a 4K, hour-long render. Concrete use cases include running live visuals for DJ sets and club or venue performances with real-time audio reactivity and full-screen output; producing social clips from a saved look; creating a Spotify Canvas for a release; pulling cover art from the same project; and delivering paid client or brand work under a commercial license. Creators can also sell presets and packs in the Collective, post and comment on the member feed, or take part in the partner program, where ambassadors run FRCTL in their sets, events such as festivals, venues, labels and agencies use it for stage visuals and workshops, and brands explore integrations, hardware and designs. Target users are described plan by plan: the Free tier is for anyone making visuals, Creator is aimed at flow artists, small DJs and content creators, and Pro is built for promoters, venues, active DJs and small event brands. A Lifetime tier that includes everything in Pro as a one-time purchase is listed as coming soon. FRCTL runs in the browser, with a desktop build that adds local 4K MP4 rendering and live output to Spout and NDI. Commercial use, selling in the Collective and version history are included from the Creator tier upward, and the first seven days of Pro are free as a trial. In short, FRCTL is one browser-based engine for building audio-reactive looks and then either shipping them as content or performing them live. Its promise is create, perform, monetize and collaborate in a single place, with the full creative toolkit available free and resolution, licensing and routing scaling up through the paid tiers.
ShroomPen is a browser writing assistant that opens right where you are writing, inside the page you are already working in. It can use the page you are on, or other pages you pick, so you never have to explain everything again in a separate AI chat. It performs four actions on the text in front of you — Reply, Rewrite, Fix Grammar, and Translate — and it is aimed at day-job writing rather than personal prose: a support reply, a billing answer, a quote, or a form's long answer, where the facts matter more than the prose. ShroomPen ships as a Chrome extension that you open with Ctrl+Q, and it works on any normal website, such as your inbox, a CMS, a support tool, or a doc in the browser. The problem ShroomPen targets is that everyday writing help usually lives somewhere else. You leave the page, open a separate AI chat, and paste in context that is already open in other tabs, or you re-explain everything from scratch. ShroomPen stays on the page instead, and lets you point it at the exact pages and tabs that hold the details. The second half of the problem is privacy. Work writing often carries customer names, order numbers, delivery dates, billing details, and proposal facts, and sending that material to a cloud service is not always acceptable. ShroomPen is described as a privacy-first browser writing assistant that lets you instantly reply, rewrite, fix grammar, or translate text across any website without sending sensitive data to the cloud. It is designed to balance AI convenience with data privacy by keeping all your page, field, tab, and session context securely on your device, giving you complete control over your everyday web workflow. Whatever is in the field is what ShroomPen works on. You pick an action and can see the before and the after. Reply answers the message in front of you, and your rough note is the brief. Rewrite produces clearer and more natural text with the same meaning. Fix Grammar corrects spelling and punctuation in the language you wrote. Translate lets you pick the language, and only the text you chose is replaced. The site demonstrates this with a live chat example: an agent types a rough note that says the order looks delayed and might arrive tomorrow, and after pressing Reply the field holds a finished answer that opens with a greeting, cites order #4821, states that UPS has it in transit, and gives the updated delivery date. The customer's name, order number, and delivery date are already filled in, so the agent never has to go looking through tabs for them. ShroomPen builds its draft from the sources you tick. It can use the current page, selected tabs, the field itself, selected text, and session recents. As the site puts it, invoices, docs, notes, and a CRM page can be ticked when they hold the details, and the text is built from them; untick one and it loses what only that tab knew. A proposal example shows this in practice: while drafting in a document at docs.example.com, the assistant can draw on a customer notes page from a CRM and a feature page from a product site, and the resulting paragraph talks about a shared inbox, saved replies, and ticket history, and notes that this matches the customer notes. Because the context is chosen rather than scraped wholesale, you decide exactly which pages contribute facts to the draft, and which stay out of it. That is what makes the output specific instead of vague. Privacy and control are treated as first-class features. Provider settings stay in Chrome extension local storage, and generation requests go directly from the extension to the endpoint you configure. In v0 there is no ShroomPen backend: no required ShroomPen account, no hosted model, no extension telemetry, no ads, and no ShroomPen server path. Source control is explicit, meaning current page and tab text are read only when those sources are enabled. ShroomPen also stays out of password fields and other sensitive inputs, with disabled domains and sensitive-field exclusions keeping risky surfaces out of the flow. The first time you open it, ShroomPen tells you what it can read and waits for you to agree; after that it only opens when you ask, and you choose which page or tab it uses each time. You can open the request before it goes out and read exactly what your provider will receive, with your key hidden, and edits made there apply to that one request. If you want ShroomPen to leave a site alone entirely, you add that site to the off list in settings and it will not open there at all. The overall workflow is deliberately short. First you install the Chrome extension. Then you connect a provider: sign in with OpenRouter, or add an OpenAI, Anthropic, Gemini, or OpenAI-compatible key. No ShroomPen account or hosted model is required. Finally you write — open ShroomPen with Ctrl+Q and attach only the context you want. If you prefer to run a model on your own machine, you can, as long as it speaks the OpenAI API: point ShroomPen at your local server the way you would any other provider, and no key is needed. The result always comes back in ShroomPen first, so nothing is changed automatically. You decide whether to copy the text, drop it in where your cursor is, or replace the text you had selected. The benefits follow from that design. Because the draft is assembled from the pages you attach, the facts travel with the text: names, order numbers, dates, and product details arrive in the right place without a search through open tabs. That means fewer vague statements and less time spent hunting for past replies and context, and it produces faster, more consistent answers for the people receiving them. Your rough note is enough of a brief to produce a finished, on-message reply. Just as importantly, you stay in the page you were working in, so there is no tab-switching to a separate chat and no re-explaining of background. Since context is limited to what you enable, and the request goes straight from the extension to your chosen provider, you keep a clear view of what leaves your browser and what does not. The use cases described are practical ones. A support agent handling a live chat can press Reply and get an answer that already contains the customer's name, the order number, and the delivery date pulled from the tabs holding that information. Someone drafting a proposal in a browser document can attach a CRM notes tab and a product feature page and get a paragraph that matches the customer's stated pain points rather than generic claims. A billing answer, a quote, or the long answer in a form can be produced the same way, with the underlying facts fixed in place. Fix Grammar is for polishing text you already wrote in your own language, and Translate replaces only the text you selected, in the language you pick. The site frames all of this as writing where the facts have to be right, as opposed to birthday notes, toasts, or a cover letter's opening, which it says you should write yourself. ShroomPen is therefore for people whose work writing has to sound like them and also has to be correct, on sites they already use. Integration is through the browser: it opens on any normal website, including inboxes, CMS tools, support tools, and browser documents, and stays off pages the browser keeps to itself, such as settings and the extension store. On the provider side it connects to OpenRouter, OpenAI, Anthropic, Gemini, or any OpenAI-compatible endpoint, including a local server that speaks the OpenAI API. Pricing as listed is a Live Free plan at $0, covering page, field, selected text, selected tabs, and session recents context, the Provider Request Preview before or after generation, and no required ShroomPen account, extension telemetry, ads, application backend, or hosted model. The takeaway is that ShroomPen brings AI writing to the place the writing actually happens, with the facts you select attached and nothing else. It replies, rewrites, fixes grammar, and translates on the page, keeps the context on your device, and routes requests only to the provider you configure. For anyone who writes support replies, billing answers, quotes, or proposals where accuracy matters, it is a way to get a finished draft without leaving the page and without handing over more information than you chose.
SocialGPT is an AI-powered video creation and editing tool that works through conversation. Its own site frames the promise as "Your ideas. In motion." and "Create and edit with AI. Make it yours," while its Product Hunt tagline describes the core interaction as editing videos by chatting with your timeline. You upload your footage, tell SocialGPT what you want changed, and it applies those changes for you. It is built for creators and business owners who want to make videos without learning every editing tool, so the emphasis falls on direction rather than technical operation — as the site puts it, "SocialGPT. You direct." Video editing has traditionally demanded both time and familiarity with complex software. The Product Hunt description is explicit about the audience this creates friction for: creators and business owners who want to make videos but do not want to learn every editing tool. For those users, the barrier is rarely a shortage of ideas — it is execution. Turning raw footage into a finished, polished clip normally requires knowing where the cuts should go, how to add captions, when to bring in B-roll, and how to layer music and sound effects on top. Each of those steps is its own skill, and together they represent a learning curve that many people never get past. SocialGPT addresses that gap by letting the editing instructions be given in plain conversation instead of through a dense interface full of panels, tracks, and settings. The result is a workflow where the person supplies the creative direction and the tool handles the mechanics of applying it to the timeline, which lowers the barrier enough that someone can ship a video without first becoming an editor. The central capability is chat-based editing. You upload your footage and then simply tell SocialGPT what to change. Instead of hunting through menus or manually dragging clips into position, you describe the edit you want in the same way you would brief an editor on your team. The Product Hunt description emphasises that this is not a one-shot process: you keep refining through chat, which means you can review what the tool produced, describe the next adjustment, and iterate until the video matches what you had in mind. That loop of describe, review, refine is what makes the chat interface practical rather than a novelty — small corrections are as easy to request as large ones. The website reinforces this conversational model with the line "SocialGPT. You direct." — positioning the user as the director and the AI as the one carrying out the instructions. Chat is not the only way to work. SocialGPT also lets you edit the timeline yourself, so a chat-based instruction and a manual adjustment can live in the same project. This dual approach matters because different tasks suit different methods: a broad instruction such as tightening a cut is natural to say out loud, while a precise trim or the exact placement of a clip may be faster to handle by hand on the timeline. Because both options are available in the same place, you are not forced to choose between a fully automated tool and a fully manual one. You can direct with words and step in directly whenever you prefer, which keeps the user in control of the final result rather than surrendering the whole edit to automation. SocialGPT handles a set of specific editing tasks that the product description calls out directly. It can tighten the cut, which shortens and sharpens a video by removing slack. It can add captions, so the spoken content of a video is displayed on screen. It can bring in B-roll, the supplementary footage that plays alongside the main shot. It can also bring in music and sound effects, giving a video its audio bed and its accents. Each of these is expressed as an instruction you can give in chat rather than as a separate tool you need to open, buy, or learn. Taken together they cover the most common finishing steps required to turn raw footage into a postable clip, which is why the chat interface can plausibly replace a substantial portion of manual editing work for the audience the product targets. The product's distinctive approach is that it treats editing as a conversation with your timeline rather than a fixed pipeline. Instead of presenting a rigid set of templates or a single automated "make me a video" button, SocialGPT is built around iterative direction: you say what to change, review the result, and keep refining. The timeline stays visible and editable throughout, so the AI and the user operate on the same object and the conversation and the edit remain in sync. The site's framing — "Create and edit with AI. Make it yours." — captures both halves of that idea. Creation and editing are AI-assisted, but the output is meant to be shaped by the person directing it, not handed over wholesale. The phrase "You direct" is the clearest statement of the underlying methodology: the human sets intent, the system executes, and the loop repeats until the video is right. The most concrete benefit stated in the available content is the ability to make videos without learning every editing tool — the learning curve is effectively replaced by a description of what you want. That changes who can produce video. Creators and business owners can go from raw footage to a finished clip without first building editing expertise, which means the work can stay focused on the idea rather than the software. The site also describes SocialGPT in terms of managing and growing your social media presence with AI-powered insights, tying the editing workflow to a broader social media outcome rather than treating editing as an isolated task. Because refinement happens through chat, improvements are also fast and incremental: each round of feedback is a sentence rather than a rebuild, so the distance between a rough draft and a finished video shrinks noticeably. Use cases follow directly from those stated capabilities. A creator with a folder of raw footage can upload it and ask SocialGPT to tighten the cut, producing a shorter, punchier edit without manually scanning the timeline for dead air. A business owner with a product or promotional clip can add captions so the message reads clearly, then bring in B-roll to illustrate the points being made. Anyone assembling a finished social clip can layer in music for tone and sound effects for emphasis without sourcing and timing them by hand. When a chat instruction gets close but not quite right, the timeline is there for a final manual touch-up, letting the user dial in the exact result themselves. Across all of these, the common thread is producing video content for social media faster than a conventional edit would allow, while still growing a presence that benefits from the platform's AI-powered insights. SocialGPT is explicitly aimed at creators and business owners, and its Product Hunt topics place it in Social Media, Artificial Intelligence, and Photo & Video. Access is through the web app at app.gpt.social, where new users sign up with email or continue with Google. Signing up requires agreeing to the Terms of Use and Privacy Policy, and there is an optional checkbox to receive product updates and tips. Existing users sign in from the same page, and the product also maintains a presence on Product Hunt. No pricing details are stated in the available content. In short, SocialGPT is a chat-driven video editor: you upload footage, describe the changes you want, and refine the result by talking to your timeline or by editing it yourself. For creators and business owners who want to make videos without learning every editing tool, that combination of conversational direction and hands-on control is the core value proposition.

Jango is a macOS application for testing multi-user applications with AI participants instead of people. It gives your app a cast of AI users, and each cast member gets its own isolated browser, its own account, a goal and a memory. You point Jango at your development URL and watch those participants sign in, navigate your app, fill forms and take actions in real time — from posting in a social feed, to placing test orders in a sandbox order book, to updating shared tasks. Jango is built for developers and teams who need to exercise the parts of an application that only appear when more than one person is involved, and it runs on macOS for both Apple silicon and Intel Macs. The problem Jango addresses is that a large class of application behaviour simply cannot be tested alone. Messaging and communities, marketplaces and order books, and teams and collaboration all depend on other people showing up, holding their own accounts and doing something at the same time as someone else. Coordinating a group of testers for every change is slow and impractical, particularly for solo developers who are building these features without a testing team. Even when testers are available, the context around a test — who the participants were, what they did and what the app showed — tends to be lost and has to be rebuilt the next day. Jango is designed to remove the wait and to keep that context instead of discarding it. At the centre of the product is the cast. Each participant receives its own account and an isolated browser session, so buyers, sellers, teammates and market participants can hold separate identities inside the same running application. You assign roles and goals — a buyer places a test order, a seller lists an item, a teammate updates a task — and the participants act through their own browsers to accomplish them. Cast members are not limited to chatting: they operate your web app the way a user would, navigating pages, clicking controls, filling forms, selecting options and uploading supplied images, with actions depending on the controls Jango can observe in your app. The product is explicit that these are AI participants acting through real browser sessions rather than real people, and that they help you exercise interactions and explore scenarios rather than replace research with real users. Setting up a scenario follows three explicit steps. First you give Jango a place to go: you add your development URL and test accounts, and each participant gets its own isolated browser. Next you choose who shows up, assigning roles and goals such as a buyer placing a test order, a seller listing an item or a teammate updating a task, and each participant acts through their own browser. Finally you join in and check both sides — you use your app alongside the participants, inspect their screens, pause when something breaks and save the cast for your next change. You can log into your app as yourself while the cast uses its assigned accounts, give directions to participants, pause them or take control of any user's screen. The documentation shows the same idea through the CLI, where a command can direct a participant, for example asking one participant to invite another to a group. Every run is designed to leave something useful behind. Jango keeps three kinds of context you would otherwise rebuild tomorrow: known identities (roles, relationships and encrypted login state), observed app controls (reusable hints with execution history) and run evidence (activity, observable checks and comparisons). A run can therefore leave behind a repeatable situation, a navigation hint backed by an actual action, and evidence that an expected message appeared. At the end of a session Jango produces a report containing actions, errors and screenshots, and paid plans add multi-user checks and saved checkpoints. Casts themselves can be saved, so the same participants, accounts and goals can be brought back for the next change to the app. Jango is meant to fit where you already build. You can use the dashboard, launch from your terminal with the Jango CLI, or give your coding assistant access through MCP, and the cast and its memory stay together across those entry points. For AI sessions you can connect OpenAI, Anthropic or Vercel AI Gateway. You can bring your own AI key — in which case your AI provider bills you directly and Jango charges no extra on any plan — or buy prepaid managed AI credits from Account settings, with no subscription needed. The application ships with Node.js and Chromium bundled, along with the browsers and tools Jango needs, so no separate Node or Playwright installation is required. Updates are handled automatically on macOS: Jango checks for and downloads them in the background and installs them when you restart immediately or quit later, saving your workspace before installation, with a manual Help → Check for updates option available as well. The outcome for users is being able to test the parts of an app that need other people without waiting for other people. Instead of scheduling testers, you define a cast once and reuse it: casts can be saved for the next change, and run evidence and checkpoints carry forward, so the situation you created becomes repeatable rather than something you rebuild each time. Because participants each have a separate browser and account, you can observe both sides of an interaction at once — a buyer and a seller, or a group of collaborators — pause when something breaks and inspect the exact screen where it happened. Jango states plainly what it does not replace: AI participants help you exercise interactions and explore scenarios, but they are not a substitute for research with real users. Jango's published use cases cover social app testing (invitations, conversations, community roles and shared activity, exercised alongside your own test account), chat app testing (messaging and group chat flows without coordinating a group of testers, by directing AI participants in separate browsers and joining the conversation yourself), collaboration testing (team invitations, shared tasks and role-based workflows in collaborative web apps without gathering a testing team), and order books and marketplaces (sandbox order books and marketplace workflows where separate AI participants navigate pages, fill forms and submit test orders). It also publishes a guide for the solo developer: a practical workflow for testing social and collaborative apps alone using separate accounts, purposeful scenarios, AI participants and checks across browsers. The homepage illustrates an order book scenario in which a buyer selects Buy, enters three units at $100 and submits a limit order, a seller offers two units at $99 and checks the resulting fill, and a market participant places another test order and reviews the updated book. Jango is aimed at developers and teams building multi-user web applications, and it is positioned especially for solo developers testing social and collaborative apps without a testing team. It is available for macOS on Apple silicon and Intel, with a separate build for each, and the version listed on the site is 1.1.1, signed with the company's Apple developer certificate and notarised by Apple. Pricing has three tiers. Free costs $0 and includes three participants per session, one project, your own AI key and managed AI credits at cost plus 20%. Pro costs $9 per month and is described as a founding price that stays the same for as long as you subscribe; it includes 12 participants per session, unlimited projects, multi-user checks and saved checkpoints, and managed AI credits at cost plus 10%. Enterprise is custom priced for larger casts, participant limits set with you, custom limits, invoiced billing, negotiated managed AI rates, support terms and direct support. Jango also documents its limits and data handling: use test accounts in apps you control, and note that canvas-only apps, popup sign-in flows and CAPTCHA may need a different integration. Your account keeps projects, evidence and browser checkpoints in the cloud, browsers run on your computer, sign-in credentials use your operating system's credential protection, relevant page text, goals and participant memories are sent to your selected AI provider, and browser destinations are restricted to your configured app origins. In short, Jango replaces the wait for other people with a reusable cast of AI participants that each hold their own browser and account, pursue the goals you give them inside your development URL, and leave behind evidence, memory and reports you can build on.

Wand is a software-building environment designed around the human voice. It is aimed at builders who think faster than they type, and its purpose is to let those builders think out loud instead of stopping to translate their ideas into prompts. The product takes natural speech and shapes it into work, which you then authorize as a build and review, all inside one quiet, generative environment. Rather than treating the keyboard as the primary instrument for creating software, Wand treats the voice as the input, with the intention that the distance between having an idea and having software narrows considerably. Its tagline, building software at the speed of thought, describes that intention directly: the thinking itself becomes the raw material for the build. The problem Wand sets out to solve is described in its own words: the keyboard is becoming the bottleneck. For people whose ideas arrive faster than their hands can type them, the act of writing a prompt becomes a translation step — a pause in which a fluid thought has to be converted into structured text before anything can happen. That pause interrupts momentum and forces ideas to be compressed before they are even fully formed. Wand's stated answer is to remove that translation step by capturing speech instead. Its description frames the shift as a broader change in how software gets made, closing with the claim that this is the post-keyboard era — a period in which speaking, rather than typing, is the way builders get their work started. The first thing Wand changes is how an idea is expressed. Instead of writing a prompt, you speak. Wand's description invites you to think out loud rather than stopping to translate your ideas into prompts. This matters because speaking is generally faster and less structured than typing: you can describe intent, context, and nuance in one continuous stream rather than assembling a carefully worded request. The product is explicitly designed to accept that looser, more conversational form of input. In practice this means the entry point to building software becomes conversation rather than composition, and the user is not required to pre-format their thinking before Wand can act on it. Wand also explicitly accommodates non-linear speech. Its description tells users they can ramble, react, and change their mind mid-sentence, and that Wand keeps up. This is a meaningful design decision: most input methods reward a single, well-formed request, whereas spoken thinking is naturally full of detours, corrections, and second thoughts. By keeping up with that unstructured flow, Wand removes the pressure to get the wording right the first time. A builder can start describing one approach, hear themselves say it, react to it, and pivot to a different one without abandoning the session or starting over. The conversation, in other words, can be as messy as thinking usually is. From that spoken thinking, Wand moves to producing work. The stated flow is to speak naturally, shape your thinking into work, authorize a build, and review it — all within one quiet, generative environment. The word authorize suggests a deliberate approval step: the builder remains in control of when the thinking becomes an actual build, rather than the tool acting without consent. The review step closes the loop, giving the user a chance to look at the result inside the same environment where the idea was spoken. Describing the environment as quiet is notable too: rather than scattering the work across a stack of noisy tools, Wand frames the whole cycle — speaking, shaping, authorizing, reviewing — as taking place in one focused, generative space. Wand's overall approach can be summarized as replacing typed prompts with spoken intent. The methodology is voice-first: you speak rather than type, you are allowed to be unstructured, and the product's job is to keep up and convert that thinking into software. Once the thinking has been shaped into work, the builder authorizes a build and then reviews it. That sequence — speak, shape, authorize, review — is the entire described workflow, and every part of it is presented as happening in a single generative environment rather than across multiple disconnected steps. The emphasis throughout is on removing the friction between thinking and building, so that the builder's own pace of thought, rather than their typing speed, sets the rhythm of the work. The benefits Wand points to follow directly from that approach. Because you no longer have to translate ideas into prompts, you do not have to stop in order to record them; the thinking itself is the input. Because you can ramble and change your mind mid-sentence, you are not punished for thinking in a non-linear way. And because the entire cycle happens in one quiet generative environment, the work stays in a single context instead of being split between brainstorming, prompting, building, and reviewing in separate places. The overall outcome Wand describes is software built at the speed of thought, by people who would otherwise be held back by how quickly they can type. The concrete scenarios Wand's description implies are all variations on a builder working through an idea out loud. One is starting a new piece of software by speaking about what it should do, rather than writing a specification or a prompt first. Another is working through an idea in a rambling, exploratory way — talking it out, reacting to your own description, and changing direction mid-sentence while Wand keeps up. A third is shaping that spoken thinking into work and then authorizing the build once you are satisfied with the direction. A fourth is reviewing the resulting build in the same quiet, generative environment where the idea began. Across all of these, the common thread is that the builder is speaking instead of typing from the very first moment of the process through to the review stage. Wand's stated audience is builders — specifically, builders who think faster than they type. That framing puts the product in the hands of people whose bottleneck is input speed rather than clarity of thought: makers and developers who already know what they want to create and lose time in the act of describing it. Wand is available on the web at wand.dance, where the site offers get started and sign in entry points, and it was launched on Product Hunt under the topics Productivity, Developer Tools, and Artificial Intelligence. Wand's value proposition rests on a simple observation: the keyboard is becoming the bottleneck, and speaking is a faster way to move an idea into software. By letting builders think out loud, ramble, and change their minds mid-sentence, and by turning that speech into work that can be authorized as a build and reviewed in one quiet generative environment, Wand aims to make the builder's thinking — not their typing — the thing that sets the pace. Its promise is software built at the speed of thought, in what it calls the post-keyboard era.
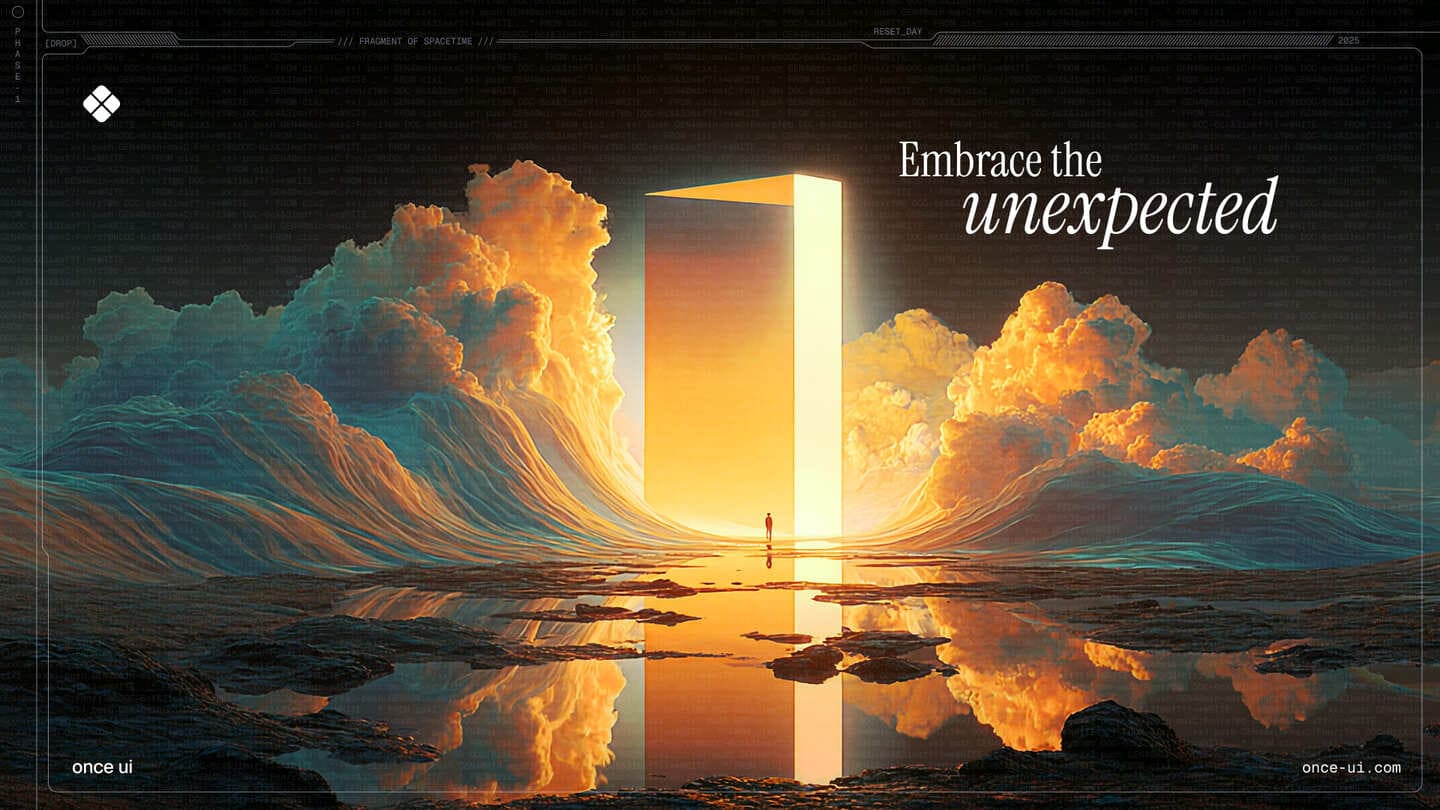
Once UI 2.0 is an open-source design system for building polished React products with less repetitive code. It is built with Next.js and Supabase and is presented as the agentic design system, aimed at indie creators, developers, design engineers and the AI coding agents that work alongside them. The main purpose of the system is to let you compose layouts with readable primitives, rely on a shared system of components and design tokens, and keep the result consistent as your product grows. It ships with fully functional apps assembled from copy-paste React code, organized as components, blocks, layouts and pages. Building a React product usually means re-deciding the same details over and over: spacing, typography, color, borders, surfaces and states. Every new screen or feature adds another place where the interface can drift away from the rest of the product. Once UI addresses this by providing a single system that everything is composed from, so consistency becomes a property of the building blocks rather than something you have to police by hand. Version 2.0 extends the same idea to a second audience: coding agents. Because agents now write a large share of application code, the design system has to be legible to them as well as to people. That is why Once UI 2.0 ships with a component catalog, compact rules and task guides, so an agent can use the system correctly, while the foundations and predictable APIs keep the output understandable for the person reviewing it. The most visible idea in Once UI 2.0 is stated on the site as Any look. One system. It is demonstrated through a die-rolling interaction: you roll, the whole page changes, and the code does not. Each roll corresponds to one of twenty looks, tracked as a deck that fills up as you collect them, and every look has its own address such as once-ui.com/?face=20. The default look, number 20, is called Natural 20 and is described as the one where you rolled the whole system. It is displayed with a neutral gray, an emerald brand color, an orange accent, a playful border treatment, contrast options described as solid and flat, a filled surface, and Geist used for headings, body text and labels. The demonstration exists to show that a fixed set of design decisions can drive radically different visual results without any change to the underlying React code. The look is configuration; the system stays the same. Once UI's building blocks are organized in layers. Components, blocks, layouts and pages are the levels named in the project's own description, and the promise is that you ship fully functional apps with copy-paste React code. Blocks have their own documentation with a quick start entry, and they are larger composed units built from components, while layouts and pages assemble those into complete screens. Because everything is drawn from the same shared component set and design tokens, a page put together from blocks inherits the system's behavior and look rather than introducing new one-off styling. Readable primitives are the foundation of the composing experience: you write layouts using primitives that you can read and reason about, which keeps the markup approachable and the intent visible. The wider product line reflects this layering too, listing Stack marked as New alongside Once UI Core, Once UI Blocks and Orbit Core. Version 2.0 is framed as an update that gives both you and your coding agent a clearer way to work. Three artifacts are named as enabling that: a component catalog, compact rules and task guides. The component catalog gives an agent a structured inventory of what exists in the system, so it can reach for a real component instead of inventing a new one. Compact rules are short, explicit constraints describing how the system should be used, which matters because agents perform better with a small, unambiguous rule set than with a long specification scattered across documentation. Task guides walk through how to accomplish specific jobs with the system, giving an agent a procedural path from a request to a correct implementation. Together these artifacts help agents use the design system correctly. On the human side, the foundations and predictable APIs make the output easier to understand, so reviewing, extending and debugging agent-written code stays tractable. The overall approach is that the design system, not the individual screen, is the source of truth. A shared layer of components and design tokens carries the decisions — color, type, surface, border and contrast — and the components and blocks consume those decisions rather than hard-coding them. That is what makes the roll the die, the whole page changes, the code does not demonstration possible: the look is applied through the system rather than written into each page. The same architecture is what lets a coding agent participate safely. Because there is a catalog to select from, rules to follow and guides to work from, the agent operates inside the system rather than around it, and because the APIs are predictable, a developer can read what the agent produced without having to reverse engineer it. The project is documented publicly, with Documentation, Roadmap and Changelog all linked from the site, and the GitHub organization is described as shipping in public. The stated outcome is polished React products built with less repetitive code, and consistency that holds as your product grows. Instead of restyling each new screen, you compose it from the same components and tokens, which reduces the surface area where visual drift can appear. For teams adopting agents, the benefit is that generated output is easier to understand because it is expressed in the system's own vocabulary, using foundations and APIs the system defines. The site also points to a broader benefit of working this way: the system is used by real, shipped products rather than being only a demo. Aveiro, Frametic, IQON, Hoshina, La Femme Kosmetik, a developer portfolio by Divyanshu Dhruv, and the Dopler Store swag store are all presented under Built with Once UI, spanning a creator platform, motion for the web, a monitoring app, a property claim platform, a beauty brand, an individual portfolio and an ecommerce store. Concrete scenarios follow from those examples. A creator platform like Aveiro needs a large, consistent surface area across many screens and states. Frametic, described as motion for the web, is a scenario where a design system has to coexist with animation. IQON is a monitoring app, where dense data displays benefit from predictable layout primitives. Hoshina is a property claim platform, a case where a workflow-heavy product needs consistent forms and content structure. La Femme Kosmetik is a beauty brand, where the token-driven look system allows the same system to produce a distinct visual identity. A developer portfolio such as Divyanshu Dhruv's and a swag store like Dopler Store show the range at the small and commercial ends. Beyond those, the free starting points — Magic Portfolio, Magic Docs, Once UI Starter and Once UI Figma — suggest entry scenarios: a portfolio site, a documentation site, a fresh project scaffold, and design work in Figma alongside the code. Once UI is aimed at indie creators, design engineers and developers building React products, as well as the coding agents they work with. The site's own community is named the Design Engineers Club, described as 5,000 readers every week, a Discord that answers, and a GitHub that ships in public. The stack is stated directly: Next.js and Supabase, with React code delivered as copy-paste components, blocks, layouts and pages. Figma is part of the ecosystem through Once UI Figma, and the project is supported by Claude and Sentry. The product line includes Stack, marked as New, along with Once UI Core, Once UI Blocks and Orbit Core, plus a group labelled Free containing Magic Portfolio, Magic Docs, Once UI Starter and Once UI Figma, with a separate Pricing page linked from the site. Once UI is a product by Dopler. Once UI 2.0 treats consistency as something the system enforces rather than something the developer remembers. Its twenty interchangeable looks show that one system can drive any visual identity while the React code stays unchanged, and its component catalog, compact rules and task guides extend that same discipline to AI coding agents. For developers and design engineers building with Next.js and Supabase, that means polished products with less repetitive code; for their agents, it means a system they can actually follow; and for both, it means code that stays easier to understand as the product grows.
Fit Receipt is a private digital lookbook and virtual fitting room built for the NUDE lingerie collection, where a shopper can browse the collection, open product detail, and try pieces on virtually before deciding. The experience is framed around a single principle stated on the page: start with your life, then choose the bra. Instead of leading with a product grid, the fitting room first learns how you will actually wear the piece, then moves on to styles and the whole-set budget. Any answer you give can be changed later, and the person using it — not the software — keeps the final decision. On Product Hunt it is described simply as a lingerie fitting room that shows its reasoning. Buying lingerie without a fitting room is a guessing game: sizing, shape and comfort are hard to judge from pictures, and recommendations are often opaque. Fit Receipt addresses that by making reasoning visible rather than hidden. Every pick carries an AI judgment receipt, so the shopper can follow the case from a real life brief to a receipt-backed draft. At the same time, the product treats privacy as a design constraint rather than an afterthought: the text you type stays in the browser's memory only and is never sent to a model, photos stay in your browser, and there is no server photo storage. That combination — transparent reasoning plus local-only photos — is what distinguishes the fitting room from a conventional try-on widget. The first step in the room is a needs-first flow. A prompt asks, "What would you like to solve this time?", inviting the shopper to describe the situation in their own words. That text stays in the browser's memory only and is never sent to a model. The options presented underneath are the needs you confirm, so the system works from what the shopper explicitly agrees to rather than from inferences. Two entry points are offered: Confirm my needs, or Fill in a demo case for people who want to see the flow with example inputs first. Because every answer can be changed, the brief remains a living document that the shopper can revise as their thinking develops. The ordering matters — lifestyle and use case come before styles and the whole-set budget — so the product set under consideration is scoped to how the piece will actually be worn. Once the brief is confirmed, the room supports browsing the collection, viewing product detail, and trying on virtually. Each pick that emerges from this process is attached to an AI judgment receipt, a written trace of how the choice was reached. The Product Hunt listing frames the whole experience as a case that runs from a real life brief to a receipt-backed draft, with the person keeping the final say. The receipt is therefore best understood as an accountability layer: it records what was judged and why, so the shopper is reviewing an explained draft rather than accepting an unexplained recommendation. The reasoning behind those receipts comes from JEV (TypeSafe), described as a judgment model that scores trade-offs with calibrated confidence in roughly 300 milliseconds — explicitly not essays. JEV is invoked by the agent, which knows when to call it. If the model's confidence is low, the result stays unresolved instead of being forced into a definitive answer, and the judgments that are produced get recorded. Importantly, the fitting room works without JEV as well, so the judgment layer is an enhancement rather than a hard dependency. This division of labour is stated plainly: the agent handles chat, while code protects facts and pricing. In other words, conversational flexibility never gets to override the deterministic parts of the experience such as product facts and prices. The privacy model is the other half of the architecture. JEV sees typed fields and never the photo, so the judgment step operates on structured inputs rather than imagery. Photos stay in your browser, and there is no server photo storage of any kind. Text entered into the brief likewise stays in the browser's memory only and is never sent to a model. The API is rate-limited, and the build is hosted on Vercel and released as open source. Fit Receipt is described as a reference implementation, which is why these boundaries — what the agent may decide, what the model may see, and what never leaves the device — are made explicit rather than left to be assumed. For the shopper, the outcomes follow from those choices. Recommendations arrive as a draft with reasoning attached, so decisions can be reviewed rather than merely accepted. Uncertainty is surfaced instead of hidden: when confidence is low, the item is left unresolved rather than dressed up as a conclusion. Judgments are recorded, which means the case can be revisited after any answer is changed. And because photos and typed notes remain on the device, trying styles on virtually does not require handing personal images to a server. Concrete use cases follow the flow described on the page. A shopper can open the fitting room with a real-life brief, describe how they intend to wear the piece, and confirm the needs the room should solve for; from there they browse the collection, open product detail, and try items on virtually. Someone who wants to understand the mechanics first can fill in a demo case and watch a case move from brief to receipt-backed draft. A shopper who is unsure can revise any answer and see how the recorded judgments change. Developers and evaluators have a further use case: Fit Receipt is an open-source reference implementation on Vercel that demonstrates how an agent can call a judgment model such as JEV, keep low-confidence results unresolved, and keep facts and pricing under code control. Cross-border shoppers are served too, since the room ships from Taiwan with pricing shown in both currencies. On the audience and commercial side, the room is aimed at lingerie shoppers — and anyone who wants a fitting experience that shows its reasoning while keeping photos local. The technology stack, as described, includes JEV (TypeSafe) as the judgment model, a rate-limited API, Vercel for hosting, and open-source code. Pricing on the page is presented in Taiwanese dollars, with US dollar amounts shown as approximate conversions at NT$31.76 = US$1 (Bank of Taiwan spot rate, Sep 21, 2026), and prices are charged in NT$ at checkout. Orders ship from Taiwan with free shipping over NT$3,000 in Asia and NT$5,000 to Europe and the Americas, arriving in 7–10 business days; overseas orders cannot be returned. Taken together, Fit Receipt pairs a virtual lingerie fitting room with a receipt for every pick, so the shopper always sees the reasoning behind a recommendation instead of a black box. The brief comes first, the person keeps the final say, low confidence stays unresolved, and photos never leave the browser — a fitting room that shows its work.
Squints is a set of design tools for the live web. It is a free Chrome extension for design engineers that puts design tools on top of any live web page, bringing Figma's measuring tools and more into the browser. With Squints you can measure spacing, drag out guides, overlay a column grid, pick colours in any format, see the font that actually rendered, and slow down or scrub any animation. It is free, requires no account, and does no tracking. Squints is added to Chrome from the Chrome Web Store. Design is moving into code. The decisions that used to be settled in a design file — spacing, type, colour and motion — now get made in the browser, where the tools for looking closely never followed. Squints brings them. That is the gap the product addresses: when layout, typography, colour and motion are decided on a live page rather than in a design file, the people making those decisions need a way to look closely at what the browser has actually rendered. Reading an exact box, checking the gap to the next element, overlaying a reference grid, confirming which font really rendered, or slowing an animation down are all normal parts of settling a design in a design file. Squints puts those same kinds of checks onto the live web page, so the page itself becomes the place where the decision can be verified. It is a free Chrome extension for design engineers, installed directly from the Chrome Web Store. Inspection is the foundation. Squints lets you inspect anything on the page: you can read its box, and the gap to the next one. That turns spacing into something that can be read rather than estimated, and it gives an exact reference for the distance between one element and the next, which is usually the number that matters when a layout has to be matched or corrected. Rulers and guides build on that reading. You drag them out like in Figma, and they snap, so reference lines land on real positions rather than approximate ones. A column grid can be overlaid over the real page, and Squints remembers that grid per site, which means the same grid is available again the next time you look at that site instead of having to be set up from scratch. Squints also lets you draw on the page: arrows, boxes and notes, placed where it matters. Annotation therefore stays attached to the exact element or area it refers to, rather than being described somewhere else. Colour picking is similarly direct: you can pick any colour, in every format, plus the token behind it. Having every format covers the practical need to read a colour the way a given context requires, while the token behind it connects the picked value to the design system it belongs to. Font identification answers a question that comes up constantly on live pages: Squints identifies any font — the one that really rendered, with metrics. That is the font the browser actually used, not the one that was asked for, together with its metrics. Motion is handled too. You can slow motion down, playing every animation at a tenth of its speed, which makes movement that passes too quickly at full speed possible to watch and judge. Finally, you can capture the result: a screenshot or a recording, marks or not. Capturing with the marks keeps the measurement, drawing or annotation visible in the record, while capturing without them gives a clean version of the same view. Taken together, Squints works on top of the page you are already viewing rather than in a separate file or a detached inspection surface. The tools are applied to the live web page itself: the box you read, the guides you drag, the grid you overlay, the marks you draw, the colour you pick, the font you identify, the animation you slow and the capture you take all relate to what is actually rendered in the browser. Squints is delivered as a free Chrome extension, so there is no account to create and no tracking to consider before using it. Because the column grid is remembered per site, the extension also carries some continuity between sessions on the same site, which supports repeat checks rather than one-off looks. The benefit is that design decisions made in the browser can be made with precision. Spacing can be measured rather than guessed, and the gap to the next element can be read. Alignment can be checked against snapping rulers and guides dragged out as they would be in a design file. A column structure can be verified against the real page, with the grid ready again next time on that site. Colours can be read in whichever format is needed and traced to the token behind them. Typography issues can be traced to the font that actually rendered, with metrics, instead of the font that was requested. Motion can be slowed to a tenth of its speed so it can be evaluated rather than missed. And any of these can end in a screenshot or a recording, with or without marks. Because the extension is free, requires no account and does no tracking, none of this depends on a purchase or a sign-up. Use cases follow the decisions the tools support. When a layout has been built in code and its spacing needs checking, Squints lets you read the box of any element and the gap to the next one. When alignment has to be judged against a reference, guides can be dragged out and snapped into place, like in Figma. When a page has to hold to a column structure, a column grid can be overlaid over the real page, and Squints remembers it for that site. When feedback is needed on a live page, arrows, boxes and notes can be drawn where it matters. When a colour has to be read or documented, it can be picked in every format along with the token behind it. When type does not look right, the font that really rendered can be identified with metrics. When an animation needs reviewing, it can be slowed to a tenth of its speed. And when any of that needs to be shared, a screenshot or a recording can be captured, with or without marks. Squints is for design engineers, and it is a Chrome extension, distributed through the Chrome Web Store where it can be added to Chrome with a single action. It runs on live web pages, which is where its tools apply. It is free, with no account and no tracking. No paid tiers, subscriptions or further pricing details are stated in the product's own description. Its Product Hunt topics place it alongside design tools, productivity and developer tools, which reflects the work it supports: looking closely at a page, checking the details of a build, and doing so without leaving the browser. The summary is simple: Squints brings design tools to the live web. Inspecting boxes and gaps, dragging out snapping rulers and guides, overlaying a remembered column grid, drawing arrows, boxes and notes on the page, picking colours in every format with the token behind them, identifying the font that really rendered with metrics, slowing every animation to a tenth of its speed, and capturing a screenshot or recording with or without marks — all of it on any live web page, free, with no account and no tracking, from a Chrome extension built for design engineers.

Kapshot is a screen recorder for macOS that turns ordinary screen captures into polished, presentation-ready videos. It is built for anyone who shares their screen — content creators, developers, educators, and product teams — who need professional-looking demos, tutorials, walkthroughs, and presentations without spending hours in a separate video editor. You record your screen normally, and Kapshot automatically zooms into clicks, smooths your cursor, and frames every shot, so the finished recording looks as though it was edited on a timeline. The promise on the site is simple: record your screen, get a polished video. The usual workflow for a screencast is slow and awkward. You record your screen, then open a video editor to add zooms, fix the cursor, and frame every interaction by hand. That editing work costs hours and demands skills that many people who simply want to share their screen do not have. One testimonial on the site frames the math bluntly: "$19 lifetime is cheap for what editing zooms and cursor framing manually costs in hours." Kapshot removes that extra step entirely by doing the polish automatically while you record, so the result looks intentional instead of like a raw screen grab. Auto-zoom is the feature that gives recordings their edited feel. When you click something, Kapshot zooms in on that area so viewers do not miss it, then eases back out. Zoom runs from 1x to 4x with cinematic easing, and rapid clicks in the same spot are handled with smart clustering — instead of a series of jarring jumps, they become one smooth zoom. The cursor receives the same treatment. Kapshot replaces your real pointer with a clean, smooth cursor that glides instead of jittering, using spring physics. You can choose the cursor size from 16 to 200 pixels, toggle click animations, and add ripples that show exactly where you clicked. Styled backgrounds place your recording on a customizable canvas so it looks like a product demo rather than a raw screen grab. You can pick from background presets — the site describes seven background presets and, elsewhere, five gradient presets — or use your own image, then apply padding, rounded corners, and drop shadows. The built-in editor means you do not need any extra apps. It offers trim and cut, timeline scrubbing, and the ability to adjust zoom segments, all with a real-time preview, so what you see in the editor is exactly what you get in the file. Auto-zoom segments are already placed when the editor opens. Recording itself is deliberately minimal. A compact capture bar appears, where you choose Display or Window and toggle the camera; an optional camera overlay can be included during recording. A minimal floating dock controls the recording and is never captured in the video, so it stays out of the way while you present. Capture runs at 60 FPS natively through ScreenCaptureKit, keeping fast scrolls and animations fluid. Export is one click: the finished recording becomes an H.264 MP4 with CRF 18 quality encoding, yuv420p pixel format, and fast start so the file plays while it loads, with no render queues. Kapshot also lists support for MP4, WebM, MOV, MKV, and AVI files. Everything — recording, editing, and exporting — happens locally on your Mac, and no data is sent to any server. The overall approach is captured in four steps that run inside one app. First, Launch: a compact capture bar appears, you choose Display or Window, then toggle the camera. Second, Record: a minimal floating dock controls the recording, and the dock itself is never captured. Third, Edit: the editor opens with your recording on a styled canvas, with auto-zoom segments already placed. Fourth, Export: you click Export MP4, and the video is H.264 encoded and optimized for fast sharing. The core idea is that Kapshot does the polish automatically while you record, rather than asking you to reconstruct it afterwards in a timeline. The outcomes are direct. Recordings look professionally edited without any timeline work, so viewers see exactly where you clicked instead of losing track of a jittery pointer. Because the zooms, cursor treatment, backgrounds, and framing are applied automatically, you skip the hours of manual editing that zooms and cursor framing normally cost. The editor's real-time preview means there is no guesswork about the final result, and the one-click MP4 export removes render queues from the process. Because everything happens locally on your Mac, your recordings, edits, and exports stay on your machine. The site names four groups who share their screen. Content creators use Kapshot for tutorial and demo videos that look professional. Developers use it for feature walkthroughs and bug reproductions. Educators use it for screencasts for courses and lessons. Product teams use it for polished demos for launches and presentations. In each case the workflow is the same: launch the capture bar, record with the floating dock, review the auto-zoomed result on a styled canvas in the editor, then export a shareable MP4. Kapshot is a native macOS app that requires macOS 14 or later and runs on Apple silicon and Intel. Capture is done through ScreenCaptureKit at 60 FPS, and the output is MP4 (H.264) with CRF 18 and faststart. Windows and Linux are listed as planned. Pricing is a one-time purchase: a launch price of $19 instead of the regular $49, with one-time payment, no subscription, all pro features unlocked, lifetime updates, and a 14-day money-back guarantee if it does not fit how you work. If you have already bought it, the download link is on the site. The FAQ notes that you launch Kapshot from your Applications folder, that the recording dock hides itself and is never captured, that every feature is optional, and that recordings, editing, and exporting all happen locally. Kapshot's value proposition is that polish happens while you record rather than after. Auto-zoom, cursor smoothing, styled backgrounds, a built-in editor, and one-click MP4 export all live in a single macOS app, so your screen recordings look like you meant it — without a timeline, a render queue, or a second editing tool.
PixVerse R2 is a real-time world model that generates continuously evolving audiovisual worlds instead of fixed video clips. Powered by PixVerse, it invites people to step into worlds they can shape, exploring live experiences where characters, scenes, and stories respond in real time. The product brings multimodal understanding, long-horizon context modeling, and responsive audiovisual generation into a unified world model. Its central purpose is to advance interactive world models, so that users are not merely watching a rendered result but interacting with a world that keeps generating what happens next — powering everything from interactive stories and characters to playable generative worlds. Most generative video produces clips: a prompt goes in, a fixed piece of footage comes out, and the sequence is over. That format works for passive viewing, but it does not support the feeling of being inside a world that keeps responding. PixVerse R2 is positioned as a different approach. Instead of delivering a fixed clip, it produces continuous visual streams that respond instantly to user input. The company describes the step forward as scaling to longer, more coherent, and more controllable experiences. The underlying problem is one of continuity and control: interactions should matter, earlier moments should still count later in the session, and the world should keep unfolding coherently rather than resetting with every new request. One of the core capabilities is multimodal input during generation. PixVerse R2 accepts text, images, audio, and actions while it is generating, which means the user is not limited to writing a single prompt before the experience begins. These different input types can shape what the world does as the session proceeds: text can describe what should happen or how the world should change, images can contribute visual reference, audio is part of the audiovisual stream being produced, and actions let the user interact with the world directly. This multimodal understanding is one of the three pillars the company names — alongside long-horizon context modeling and responsive audiovisual generation — combined into a single world model. The practical benefit is that control is continuous rather than front-loaded: the world can be steered while it is running, not only before it starts. A second pillar is long-horizon context modeling. PixVerse R2 remembers what happened earlier in the session and carries those changes forward in real time. That memory is what allows an experience to accumulate rather than restart: a change made earlier remains part of the world state as the session continues. The model interprets each interaction and maintains a coherent world state, so the world does not lose track of what came before as it generates what happens next. This is described as scaling to longer, more coherent, and more controllable experiences, which matters especially for anything story-driven, where continuity is the difference between a string of disconnected moments and an experience that holds together over time. The third pillar is responsive audiovisual generation. PixVerse R2 produces continuous visual streams, and the product is described as an audiovisual world model, meaning the output is generated in response to input rather than rendered once and fixed. Two feature groups are highlighted on the site. Evolving Worlds lets users shape worlds through real-time interaction, with coherent characters, scenes, and stories. Lifelike Characters focuses on creating memorable characters with expressive personalities and lifelike presence for story-driven experiences. Together, these describe the surface the user actually meets: a world that evolves as it is interacted with, populated by characters whose presence is intended to feel lifelike and to support narrative. The product's overall approach is described as a unified world model. PixVerse brings multimodal understanding, long-horizon context modeling, and responsive audiovisual generation into one system. In operation it interprets each interaction, maintains a coherent world state, and continuously generates what happens next. That three-step cycle — interpret, maintain, generate — is the methodology that distinguishes R2 from clip-based generation. Rather than treating each request as an isolated render, the system treats the session as a continuous stream of interactions against an evolving state, which is what allows earlier events to be carried forward and new input to be absorbed while generation is already underway. The stated benefits follow from that design. Experiences can be longer and more coherent, and users have more control over what happens as a session unfolds. Because the world remembers and responds in real time, it can support interactive stories in which the experience responds to the user, characters with expressive personalities and lifelike presence, and playable generative worlds. The company frames the result as powering everything from interactive stories and characters to playable generative worlds — a spectrum that ranges from story-driven experiences to worlds the user can actively play in. Concrete experiences are surfaced through a gallery of live worlds, and a number of them are named on the homepage. Chef of the Midnight Hearth, Your Mafia Husband, and NYC Bilingual Japanese Teacher illustrate character-driven scenarios: a midnight-hearth cooking setting, a story scenario built around a character, and a bilingual teaching character. ECHOES OF ABERRATION and ZERO MARK appear alongside them. Other gallery entries include Dragon Riding, Ocarina of Time, Winter Palace, Escape the Warzone, Prairie Overdrive, Wukong's Pilgrimage, The Airstrip, and Future Nexus, each presented with an Explore action. A visitor can press Play Now to open a preset experience directly, use autoExplore, or go to the gallery to browse more live experiences, characters, and story worlds, which the site frames as a way to find your next experience. PixVerse R2 is delivered as a web experience. Users reach it through the PixVerse R2 site, where they can play now, explore individual presets, and browse the gallery of live experiences. A blog post linked from the page covers the technical framing — scaling real-time omni world models — for readers who want the deeper perspective behind the product. The Product Hunt listing places it under Developer Tools and Artificial Intelligence alongside Games, and the site's own keywords reference AI, video generation, realtime, WebRTC, and streaming, indicating that real-time delivery is central to how the experience reaches users. No pricing or plan details are stated in the material reviewed here. In short, PixVerse R2 is a real-time world model rather than a clip generator. It accepts text, images, audio, and actions while generating, remembers what happened earlier in a session, and carries those changes forward, so that characters, scenes, and stories respond in real time. By unifying multimodal understanding, long-horizon context modeling, and responsive audiovisual generation, it aims at longer, more coherent, more controllable experiences — from interactive stories and lifelike characters to playable generative worlds you can step into and shape.
The archive
Flan helps couples and young professionals see their financial future, not just past spending. Visual projection-first budgeting, shared goals, and life-event planning. Available on iOS and the web, coming soon to Android.
Playly.ai is a no-code gamified marketing platform that empowers businesses to create interactive experiences that capture attention, increase customer engagement, and drive measurable results. Built for modern marketers, agencies, brands, and businesses of all sizes, Playly.ai transforms traditional marketing campaigns into engaging experiences that audiences genuinely enjoy participating in. Today's customers expect more than static advertisements and conventional lead forms. They want meaningful interactions that are personalized, memorable, and rewarding. Playly.ai helps businesses meet these expectations by enabling them to build interactive campaigns using ready-to-use templates such as quizzes, Spin & Win, scratch cards, polls, memory games, puzzles, prediction games, personality tests, and more—all without writing a single line of code.Whether you're generating leads, launching a product, promoting an event, growing your email list, collecting zero-party data, or increasing customer participation, Playly.ai provides the tools to create campaigns that turn passive visitors into active participants. Every interaction becomes an opportunity to engage audiences, gather valuable customer insights, and improve marketing performance.Designed with simplicity and flexibility in mind, Playly.ai allows marketers to customize games with their own branding, messaging, rewards, and campaign goals. Interactive experiences can be embedded on websites, landing pages, email campaigns, social media, QR codes, digital ads, and event activations, making it easy to engage customers across multiple touchpoints.Our mission is to make marketing more interactive, engaging, and enjoyable. We believe the future of marketing isn't about interrupting audiences with more advertisements it's about creating experiences that invite participation and build stronger customer relationships.Through our blog, Playly.ai shares practical insights, industry trends, campaign ideas, gamification strategies, customer engagement techniques, and interactive marketing best practices to help businesses stay ahead in an increasingly competitive digital landscape. From retail and real estate to healthcare, education, banking, hospitality, SaaS, and events, we explore how gamification can be applied across industries to improve engagement, generate quality leads, and increase conversions.At Playly.ai, we're helping brands rethink the way they connect with their audiences one interactive experience at a time.Marketing That People Want to Play.
Floot MCP is a connector that turns Claude, ChatGPT, or Cursor into an app-building environment. You add Floot to your AI, describe the product you want, and Floot builds the whole thing — backend, database, and hosting included. According to the website, you go from chat to a live app in minutes, with no git, no terminal, and no build credits required. Floot describes itself as a way to turn ideas into products without coding, all on one platform, and it gives your AI a ready-to-use workspace complete with a database, user logins, hosting, and a live URL, with nothing to install or configure. Most AI app builders come with hidden costs and hidden complexity. The website's comparison table contrasts Floot with "others" on four fronts: token cost, ease of use, all-in-one platform, and hosting. Floot uses flat plans rather than per-token pricing, while other tools are described on the page as pay-per-token, which "adds up fast." Floot says no technical background is needed, whereas others are described as a "headache for non-coders." It positions itself as an all-in-one platform with everything built-in, in contrast to tools that require many external services, and it claims hosting that "scales with you" versus limited hosting elsewhere. Because your existing Claude or ChatGPT subscription does the thinking, Floot does not charge based on AI usage. Credits apply only to the optional Floot agent and AI image generation. Step one is connecting Floot to Claude, ChatGPT, or Cursor as a connector. Once connected, you prompt your AI with what you want, and Floot handles the technical layer: git, terminals, and build credits never enter the picture. The product listing states there is nothing to install or configure, and the connector can also be added to Cursor and other tools. The site headline frames the promise directly: "Build apps in Claude. ChatGPT. Cursor. Get it live in minutes." This matters because the AI you already use does the reasoning and code generation, while Floot supplies the workspace that makes the output actually run — so the barrier to shipping is a conversation rather than a development environment. Floot includes the backend essentials by default. Your app can save information in a database, let users create accounts, and run recurring tasks automatically. The website's illustration shows a database with 1,204 records saved, 32 users signed up, and a recurring task running daily at 9:00 — each marked as set up, with the note that Floot handles all of this for you. Hosting is built in as well: the app is live at its own link, such as orderbook.app, and the platform says hosting scales with you. Because the database, authentication, and hosting arrive pre-wired rather than as separate services to buy and connect, you spend your time on the product instead of the plumbing. Publishing is one click. Your project goes live on the web and in the app stores, with the site showing a web address alongside App Store and Google Play. Emails and notifications are built in too — you can send emails, receipts, updates, and notifications from your app without setting up extra tools, and the on-page example shows a receipt being sent to a customer. Floot also makes apps easy for search engines like Google to understand and discover, with SEO essentials built in automatically; the site illustrates this with a bakery order tracker appearing as a top result for the query. Finally, Floot integrates your tools: Stripe payments, Google login, Zapier, and thousands of other services, with the platform guiding you through setup step by step. The workflow is deliberately linear, and the site lays it out in four steps. First, connect Floot to Claude, ChatGPT, or Cursor as a connector. Second, prompt your AI to build your project — the walkthrough uses an order book app live at orderbook.app with an "Order now" action. Third, keep refining until it is exactly what you want; the example shows a follow-up instruction as simple as "Make the headline bigger." Fourth, publish on both web and mobile. The published walkthrough is titled "How to use Floot MCP: a walkthrough of building and publishing a real app from a chat," and the section is headed "From chat to live app," promising "One conversation with your AI. A real app with a database, live at its own link." Updates keep coming from the same conversation, so shipping a change is a matter of describing it to the AI you already use rather than switching tools or redeploying by hand. The stated benefits follow from that design: a flat, predictable price instead of per-token billing that "adds up fast"; a workflow that needs no technical background; one platform instead of a stack of external services; and hosting that scales as your product grows. You get a real app with a database, live at its own link, and you can publish the same project to the web, iOS, and Android before continuing to iterate. Keeping updates in the same conversation means the gap between an idea and a change in production stays short. The company's own video content frames the result as "vibe coding has never been more efficient." Concrete scenarios appear throughout the site. A bakery builds an order tracker — the on-page example shows orderbook.app with the tagline "Fresh bread, daily," an order book where customers click "Order now," and a customer receiving a receipt by email. The same flow covers a storefront published to a web address and then to the App Store and Google Play. Recurring tasks suit anything that needs to run on a schedule, such as a job that runs daily at 9:00, while accounts and a database cover products where users sign up and data accumulates. Payment-driven apps connect Stripe, sign-in can use Google login, and automation can extend through Zapier. Each of these starts the same way: a prompt inside the AI. Floot is offered on flat plans rather than per-token charges, and credits apply only to the optional Floot agent and AI image generation. A launch promotion offered 30% off your first month on the Product Hunt launch page. Floot is backed by Y Combinator. Product Hunt lists it under Developer Tools, Artificial Intelligence, and No-Code, and the connector works with Claude, ChatGPT, and Cursor as well as other tools. Integration options named on the site include Stripe payments, Google login, and Zapier, along with thousands of other services. The takeaway is straightforward: Floot MCP lets you build and ship full-stack web and mobile apps from inside the AI chat you already use, with the database, logins, hosting, and live URL supplied for you. No git, no terminal, no build credits — just describe the app, refine it in conversation, and publish it to the web, iOS, and Android.
Opaline is a team-wide, message-level analytics product for coding agent sessions, built specifically for teams that work with Claude Code and Codex. Its stated purpose is to track token cost, time, and skill usage for every single message across a team's sessions, so that the full history of how people use coding agents stops being a black box. The homepage frames this simply: pull back the curtain on your coding sessions, and turn teammate struggle into learning. Opaline is aimed at engineering teams rather than individual hobbyists — its product demo is populated with a team of three named members, a set of shared repositories, and the models those sessions run on. Rather than reporting only an aggregate monthly figure, it attributes activity down to the level of individual messages, sessions, agent runs, and the people behind them. Coding agents have become both a real line item and a real part of how software gets written, yet the way teams usually measure them is coarse. A provider dashboard typically shows an aggregate spend number with little context: which teammate generated it, which repository it belongs to, which model consumed it, or what actually happened inside the session. On a shared team account, that missing attribution makes it hard to hold any grounded conversation about usage. Opaline's answer is to treat agent sessions as an analytics problem, the same way product teams treat user behaviour. Where product analytics reveals how users move through an application, Opaline reveals how colleagues move through their coding agent sessions: where the spend lands, where sessions run long, and where the language exchanged between developer and agent starts to signal friction. The stated intent is that observable teammate struggle becomes learning rather than an invisible cost. The core of the product is the analytics dashboard, and the demo shows exactly what it reports. For a selected date range — the example covers August 1 to August 31, 2026, at a Daily granularity — Opaline surfaces headline figures: API Cost, Sessions, Agent runs, and Language signals. In the demo those read $3,200.99 in API cost, 85 sessions, 1,864 agent runs, and 385 language signals. Beneath the headline numbers sits an API Cost chart plotted daily and expressed in UTC, so cost can be read day by day and compared against when work actually happened. Sessions and agent runs indicate volume — how many conversations were held and how many individual agent executions occurred — independently of what they cost. Together these counters answer the first question any team lead asks: how much are we using, how much is it costing, and when is that happening. Opaline's defining characteristic is the resolution of its data: it tracks token cost, time, and skill usage for every single message, not merely per session or per month. That per-message granularity matters because a session is rarely uniform — it may open with a cheap planning exchange and then spend most of its budget on long, iterative back-and-forth. Message-level token cost shows where inside a conversation the spend actually accumulates. Time tracking shows how long those exchanges take, which is a different measure of effort from cost. Skill usage tracking captures which capabilities the agent drew on across messages. Because every message carries these attributes, the totals on the dashboard can be decomposed downward rather than taken on faith, and any aggregate figure can be traced back to the specific exchanges that produced it. Language signals are the most distinctive metric in the product, and they are what the product's tagline hints at: the ability to catch every "You're absolutely right" from the model and every blunt, frustrated reply from a teammate. Alongside cost and time, Opaline counts these signals — 385 of them in the demo period — turning the tone of a session into something measurable. The purpose is not surveillance for its own sake but the homepage's stated goal of turning teammate struggle into learning. Repeated friction, an agent that keeps agreeing without solving the problem, or a developer who has clearly hit a wall are all patterns that show up in language before they show up in a cost report. By counting and surfacing them next to spend and activity data, Opaline lets a team treat signs of struggle as something to act on — reviewing the session, sharing what worked, or adjusting how the agent is used. Opaline breaks usage down along three axes, each shown with both an absolute value and a share of the total. The Members view lists each teammate's API cost and percentage: in the demo Rafa at $1,175.59 (37%), Evren at $1,046.61 (33%), and Marc at $978.79 (31%), across a team of three. The Repositories view attributes the same cost to codebases — evrendom/rudel at $3,104.04 (97%) and opalinehq/athena at $96.95 (3%) across two repositories — which makes the concentration of spend immediately legible. The Models view shows which model consumed the budget: GPT 5.6 Sol at $2,051.43 (64%) and Fable 5 at $1,149.56 (36%), across two models. Read together, these three breakdowns answer who, where, and on what, and they make comparisons between members, repositories, and models concrete rather than anecdotal. Opaline is distributed as an open-source command-line tool. The site labels it MIT OSS, links to its repository at github.com/opalinehq/cli, and states that it can be launched with a single command: npx opaline@latest. That command is the entry point for collecting session data from a team's Claude Code and Codex usage, which then feeds the team-wide analytics view. The demo dashboard — explicitly labelled as a product demo — supports selecting a date range and a granularity such as Daily, and presents cost over time in UTC. Publishing the source under a permissive MIT licence means teams can inspect what the tool does and how it gathers data before running it. The overall approach is deliberately reminiscent of product analytics tooling: instrument the sessions, collect message-level events, then aggregate them into team, repository, and model views on a dashboard. The benefits follow directly from that structure. Teams gain attribution: instead of a single bill, they see cost split by member, repository, and model, so it is clear where usage is concentrated. They gain resolution: token cost, time, and skill usage attached to every message make it possible to understand why a session was expensive, not just that it was. They gain an early-warning layer through language signals, which surface frustration and unproductive loops that a cost report alone would never show. And they gain a shared vocabulary for discussing agent usage, because the dashboard's figures can be referenced in a team conversation rather than debated from impressions. The homepage's framing sums up the intended outcome: turning the struggle that appears inside sessions into something the team can learn from. Concrete scenarios follow from the demo layout. A team lead reviewing an unusually expensive month can open the Members view to see whether cost is distributed or concentrated on one person, then switch to Repositories to identify which codebase is driving it. An engineering manager can compare models in the Models view to see how budget splits between them. A developer who notices a high count of language signals can go back to the sessions behind them and examine where a conversation with the agent went sideways. A team onboarding new members can use the member and repository breakdowns to understand how agent usage spreads as more people adopt it. And because the figures are daily and expressed in UTC, they can be lined up against a sprint or a release window to see how cost tracks with periods of intense work. Opaline is built for teams rather than solo users: the demo is populated with three named members, shared repositories, and multiple models, and its tagline describes it as "PostHog for team Claude Code and Codex sessions." It is a developer tool first — installed and run from the command line via npx opaline@latest — so its natural audience is engineers, engineering leads, and platform or developer-experience teams already using Claude Code and Codex at work. The site lists it as MIT OSS with source on GitHub, and the site itself is generated with Astro. No pricing tiers or plan details are presented on the website, so the commercial model is not stated there; the distribution facts that are visible are the open-source licence, the CLI install command, and the hosted analytics dashboard the demo illustrates. Opaline's value proposition is narrow and clear: it makes a team's Claude Code and Codex sessions observable at the level of the individual message. By tracking token cost, time, and skill usage for every message, and by rolling those up into team-wide views of members, repositories, and models, it replaces a single opaque spend number with an attributed, explorable picture of how agents are actually being used. Language signals add a dimension that cost and timing cannot capture on their own, exposing the friction and struggle that precede wasted budget. Distributed as MIT open source and runnable with npx opaline@latest, it is aimed at engineering teams that have already adopted coding agents and now want to understand them. The promise is the one on the page: pull back the curtain, and turn teammate struggle into learning.
CtrlOps is a local-first desktop application for managing Linux servers from one screen with AI assistance. It brings an AI-assisted terminal, visual file management, real-time infrastructure monitoring, security auditing, access management, and single-click deployments together in a single app. The product is designed for developers, DevOps engineers, technical leads, founders, and non-terminal users who need to run one server or an entire fleet without juggling terminal tabs, remembering IP addresses, or opening separate SFTP clients. Its stated purpose is to give teams full visibility across all their servers in one place, in a tool intuitive enough for a non-terminal person to use, without making the team dependent on a single engineer to keep everything running. The founders built CtrlOps after running an IT service company. They were designers and product people at heart who understood interfaces and users, and every client they worked with had their own server. To check anything, even something as simple as why a server was slow by looking at memory and CPU, someone had to open a terminal, remember the right IP, find the right credentials, and log in separately, every single time, for every client. With a minimum of seven to ten projects and forty-plus servers running each month, there was no unified view and no quick way to know what was happening across the infrastructure without pulling in the one person on the team who knew how to navigate it all. Everything ran through him; if he was unavailable, the team was blind. CtrlOps was built to answer one question: why does managing Linux servers have to feel like this, and why is there no tool that gives full visibility across all servers, feels intuitive for a non-terminal person, and does not create dependency on a single engineer? They built it first for themselves, then made it for everyone. The AI terminal is the centerpiece of the app. Instead of memorizing command syntax, users describe what they need in plain English and CtrlOps translates it into the commands that will run against the selected server. Crucially, it is built as AI with a human in the loop: every command is shown for review and must be approved before it executes. For example, asking to clear disk space on prod-web surfaces a specific command such as sudo apt clean combined with journalctl --vacuum-size=200M, with Run and Edit options available. Web search and MCP servers are built into the terminal, along with one-click saved scripts. Reviewers repeatedly highlight the approval step as the reason they trust the tool: asking in plain English, seeing the exact command before it runs, and approving it is described as the whole game when AI touches live infrastructure. A related scripts feature lets users save, reuse, and run scripts directly from the panel, and one reviewer calls the playbook feature underrated because common fixes can be configured once and then triggered in a single click. The security audit capability runs twenty-five checks over SSH against a server and produces a hardening score. The interface summarizes results in a single line such as seventeen passed, five warnings, and zero failed. Beyond the score, CtrlOps generates a PDF audit report and provides fix commands for every issue found; those fixes wait for user approval before running. Separately, the access management feature scans an entire fleet to show who can log in to which server and who holds sudo privileges. When someone leaves a team, their access can be removed from every server at once rather than being revoked server by server. Any level of roles and access can be assigned without touching the terminal. This directly addresses the question the Product Hunt description opens with: do you actually know who has access to your servers right now? A reviewer in an HR role noted that offboarding, which previously required back-and-forth with the technical team, can now be checked and flagged in about two minutes. Multi-server management keeps the whole fleet in one app so users switch between servers by alias and no longer track IPs by hand. The interface shows entries such as prod-web at ubuntu@54.236.240.26 alongside auth-service and db-01, and reviewers single out named servers instead of IPs as a small but brilliant usability decision. Real-time infrastructure monitoring displays live CPU, memory, disk, and network metrics for every server, giving an at-a-glance view of what each machine is doing. The visual file manager lets users upload, download, and unzip in one click, replacing scp and separate SFTP clients; users can open a config file and edit it directly. Single-click deployment requires no scripts and no CI/CD setup: the user fills one form with a GitHub repository, environment variables, and a domain, and the app goes live with PM2, Nginx, and SSL handled automatically. The product also covers backups that prove they ran and makes every log file findable and searchable without SSH. CtrlOps connects to any server over SSH, so the provider does not matter. It is shown working with AWS, Google Cloud, Azure, DigitalOcean, and any VPS. The architecture is deliberately local-first: CtrlOps speaks SSH directly to your fleet, with no service in between to breach and no vendor lock-in, no cloud bridge, and no telemetry. No agent needs to be installed on the servers themselves, a detail reviewers say sold them immediately. Zero data sharing is the design principle: the app runs entirely on the user's machine, and SSH keys, server IPs, and credentials never touch a cloud. It needs only the user's SSH key, never AWS IAM credentials, a GCP service account, or Azure credentials. Sensitive data and SSH keys are stored only on the device, so servers can be managed without uploading secrets anywhere. The whole flow is human-approved: nothing runs before the user sees and approves it. The stated outcome is that the same servers require far less of the week: the work does not go away, it simply stops taking an afternoon. Users get every server in one window, deployments from GitHub in minutes, CPU, memory, and disk values at a glance, every log found for them, commands expressed in plain English, file movement by dragging, visibility into who can reach every server, faster onboarding of developers, and backups that prove they ran. Reviewers describe the practical results: doing in ten minutes what used to take an hour; catching two issues on a staging environment before they became outages; no longer stressing over deployments; and replacing a mess of SSH tabs and random bash scripts. One commenter argues the plain-English terminal lowers the barrier so developers can own their environment instead of depending on a single DevOps hero, describing it as a shift in team dynamics rather than just tooling. CtrlOps is used across a range of concrete scenarios. A UI/UX designer who does not write code and does not know DevOps used the AI terminal to be walked through deployment step by step and put a website live alone for the first time, after previously waiting on a friend to handle server work. A solo founder building a product used it to manage every deployment personally, eliminating hiring, favors, and waiting on someone else's calendar. A DevOps professional managing multiple client servers reports using the file manager more than the AI features, because editing a config inside one app removes a separate login and window. An HR team member uses SSH management to check and flag access removal within about two minutes of someone leaving. Teams also run it on staging environments before moving production over, and use it to onboard new developers quickly. CtrlOps reports being trusted by more than seven hundred engineers in over one hundred sixty countries and holds a 4.8 out of 5 rating on G2. It installs as a desktop application: a Mac build with separate downloads for Apple Silicon (M1 through M5) and Intel x64 (Core i5, i7, i9), a Windows build distributed through the Microsoft Store, and a Linux option. Pricing starts free, with a one-month free trial that requires no credit card; lifetime subscriptions are also available, as mentioned in a user review. The stack centers on direct SSH connections using ED25519 keys, with PM2, Nginx, and SSL handled during deployments, plus built-in web search and MCP servers in the AI terminal. CtrlOps takes the daily reality of managing Linux servers, logging in, checking resources, reading logs, moving files, controlling access, deploying apps, and hardening machines, and consolidates it into one local-first desktop app driven by an AI terminal that always asks permission first. Its core promise is visibility and control across an entire fleet without sacrificing privacy: your credentials never leave your machine, no agents are installed on your servers, and nothing runs without your approval.
NotchPop is a native macOS productivity app that turns the black bar at the top of your Mac into a Dynamic Island-style surface. Clicking the notch opens a home screen for your whole day: media controls, a drop shelf for files, searchable clipboard history, focus timers, calendar and reminders, weather, Mac vitals, developer activity and live revenue. NotchPop is built for people who live in the top edge of their screen, including developers, indie makers, creators and anyone who wants their Mac to show them what matters without opening another window. Its stated purpose is to bring the file shelf, clipboard history, media island, focus timers, calendar and live activity into your notch or floating island, with or without a notch. The notch has always been a piece of hardware that takes up space without giving anything back. NotchPop's answer is to give that black rectangle a job. Rather than spreading information across menu bar apps, browser tabs, dashboards and separate utilities, NotchPop puts the things you glance at most into one place at the top of the screen. The site frames the problem around attention by asking what is going on in your notch. Instead of switching away to check a sale, a build, a timer or a clipboard item, you glance up. The app is designed so the notch stays black while you work and only grows into the ears beside the camera when something is worth a glance, then tucks back in once you are done. It also works on Macs without a notch: on an iMac, Mac mini, Mac Studio, external display or older MacBook, NotchPop becomes a floating island with the same tools and interactions. Media is the headline feature. Now playing shows artwork on the left and a visualizer in the artwork's own colour on the right, and it works with Spotify, Apple Music or a YouTube tab, meaning anything that plays. You can play, pause, skip and see artwork without leaving what you are in. Alongside media, NotchPop runs focus timers directly in the top edge: a 25 minute Pomodoro session, a countdown or a stopwatch ticks away beside the camera so you never open anything to check it. The site highlights that a running session stays on the top edge, meaning the thing you are actually working on keeps the screen, described as focus that never covers your work. Presets shown in the demo include a 5 minute coffee break, a 10 minute break, a 25 minute sprint and a hydration nudge. NotchPop includes a clipboard history of the last fifty things you copied. You can pin the ones you keep reaching for, search the rest, and copy any of them back with a click. The page shows examples including a URL, a colour value and a git command. Clipboard monitoring is off by default, transient or concealed items are ignored, and only items you pin are persisted, and the FAQ states that clipboard history and file conversion are processed locally rather than uploaded. Next to it is the file shelf: a shelf for files in transit. You drag anything to the notch from the desktop, then drop it wherever it needs to go. Together these two tools replace the small utilities many Mac users install separately. The rest of NotchPop is a set of live data modules. Today's revenue adds up sales from Stripe, Dodo, Polar or AdSense in the ear so the dashboard tab can stay closed. Live visitors shows who is on your site right now, from Google Analytics or DataFast. Dev servers counts every local server you have running in the ear and is one click from opening in your browser. Mac vitals puts CPU on one side and battery on the other, with a green bolt while it charges. There is hourly and weekly weather, calendar and reminders side by side, and live developer activity covering Claude, Codex and Cursor usage and streaks. Each module fetches its own live data straight from the provider, which the site contrasts with decorative numbers pretending to be real. NotchPop is a native Mac app built with Swift and SwiftUI. It follows macOS system behaviour and uses native frameworks for audio, calendar, Keychain storage and more, which is what allows it to sit at the top edge of the screen. The product is organised around extensions: over 20 native extensions ship inside NotchPop, each built like a full Mac app. You turn on what you want and turn off what you don't, whenever you want, and the extension set covers agents, music, file sharing, revenue, code generation tracking, messaging replies, audio control, meeting tools, weather and more. Permissions are requested by feature: Calendar for agenda and meeting alerts, Accessibility for WhatsApp replies and volume keys, Full Disk Access for new iMessage and WhatsApp messages, and Automation for media controls. You can use the rest of the app without enabling unrelated permissions. API keys are masked on screen and stored in your Mac's Keychain, never in a plain settings file. You can pin the tools you use, hide the ones you don't, reorder them and drag them exactly where you want them. The outcome NotchPop promises is a Mac that surfaces information instead of hiding it. Because the notch stays black while you work and only expands when something matters, the app is designed to stay useful without becoming busy, a stated goal in the FAQ. You stop opening dashboards just to check revenue, stop hunting for something you copied earlier, stop switching apps to control music, and stop keeping a timer window floating over the work you are trying to read. Everything is local-first: the site states that nothing leaves your Mac, and local-first data handling is listed as part of the purchase. The result is fewer windows, fewer menu bar icons and one consistent place to glance. Concrete scenarios run throughout the site. A developer starts a 25 minute focus session from the notch, watches Claude, Codex or Cursor progress in the ear, and opens a local dev server with one click without leaving the editor. An indie maker keeps an eye on Stripe, Polar, Dodo or AdSense revenue and Google Analytics or DataFast visitor counts without opening a dashboard. A writer drags a file onto the notch to hold it in transit, then drops it where it needs to go, and pulls a git command back out of clipboard history. Anyone on a call can use the Google Meet or Zoom extensions to join with one tap and see a meeting countdown. Someone replying to WhatsApp or iMessage does it from the notch instead of switching apps. And because NotchPop becomes a floating island on machines without a notch, the same workflows apply on an iMac, Mac mini, Mac Studio, external display or older MacBook. NotchPop is aimed at Mac users who want their top edge to be productive, reflected in the Product Hunt topics Mac, Productivity, YouTube and Menu Bar Apps. Integrations and extensions named on the site include Spotify, Apple Music, YouTube, LocalSend, Stripe, Polar.sh, Dodo Payments, Google AdSense, Google Analytics, DataFast, Claude Code, OpenAI Codex, Cursor AI, xAI Grok, iMessage, WhatsApp, Google Meet, Zoom and Live Weather, plus Finder Services, Audio Control, Clipboard History, Focus and Hydration, and Agents. The tech stack is Swift and SwiftUI with native macOS frameworks including Keychain. Requirements are macOS 14 Sonoma or newer. Pricing is a one-time purchase of $3.99 with a 7-day free trial, billed once with free updates forever, available for 1 Mac, 2 Macs or 5 Macs, and including every built-in tool, notch and floating-island modes, future app updates and local-first data handling. There is no subscription. NotchPop takes a piece of hardware that does nothing and turns it into the most glanceable surface on your Mac. It combines a media island, a file shelf, clipboard history, focus timers, calendar, weather, live revenue, analytics and developer activity into a single black bar at the top of the screen, works with or without a notch, keeps your data local, and costs $3.99 once. If you keep reaching for the top of your screen, NotchPop is designed to already be there.
Maximem Synap is a memory and context management layer for AI agents, shipped as a developer SDK, a REST API, and a hosted MCP endpoint. You send Synap the conversation as it happens, and before your agent replies you ask what is known about this person; Synap returns a short, ranked set of facts, formatted and ready for the prompt. The product is aimed at teams building agents for customer support, sales, voice, healthcare, and multi-agent workflows, so that every conversation does not start from zero. Synap handles entity resolution, temporal reasoning, and multi-level scoping automatically, and the company states there is no vector database to run, no extraction pipeline to build, no retrieval ranker to tune, and no scoping logic to get right - those are the product. Reported accuracy is 92% on LongMemEval and 93.2% on LoCoMo, with in-conversation retrieval under 15ms at P75. Synap exists because agents forget, and the site treats that as an architecture problem rather than an interface nitpick. The listed symptoms are concrete: the agent re-asks for information the user already gave, recommends what the user already rejected, contradicts itself across sessions, or compensates by stuffing everything into the prompt, which produces slow replies and a blown token budget. The company frames these failures as tickets, refunds, and churn. It also argues that every alternative has been tried and each one stops short. A bigger context window runs into U-shaped attention, so models lose the middle; quality falls as the window fills and cost grows quadratically because history is replayed every turn. A vector database and RAG finds text that looks alike but has no view of what is current, no record of where a fact came from, and no idea that 'Acme' and 'Acme Corp' are one company. Agent skills steady a procedure but do not supply a fact - across 528 matched runs, the skill was steadying the procedure 65.7% of the time and supplying a missing fact 4.5% of the time. Summarising as you go compounds losses, and doing it properly means entity extraction, temporal reasoning, contradiction handling and validation, at which point you have built a memory system. Building it in-house is possible, but retrieval is the easy part; the months go into deciding what to keep, resolving entities, handling contradictions, and keeping tenants apart, then maintaining all of it forever. Every one of these workarounds is described as a stand-in for a missing layer. Synap treats memory as three layers rather than one bucket. Short-term memory is the current session, the working memory that most memory tools provide. Long-term memory persists across sessions, per person - the layer a user means when they say an agent remembers them. Organisational memory is shared across users and tenants: policies, product facts, and pricing, meaning company knowledge rather than personal knowledge. The company states that most memory tools give you the session and that the value sits in the two layers above it. Scoping enforces that structure: a request sees its own level and every level above it, never below and never sideways. The out-of-the-box hierarchy is Client, Customer, User - shared product knowledge visible to everyone, tenant-level policies, teams and shared projects, and the facts, preferences and episodes private to one person. One person's memory does not reach another person's session and one tenant's does not reach another tenant's. When three levels is not the right shape, teams can define a custom hierarchy at any depth with the names they already use, such as Hospital, Department, Clinician, Patient. On the read side, Synap focuses on anticipatory retrieval. Context is pre-fetched while the conversation is still going, so it is ready before the agent asks, at under 15ms at P75 in-conversation. That matters most for voice agents, which stay conversational instead of pausing mid-turn. Retrieval is also described as resilient: a bad day for one part of the system is not an outage, and retrieval nets across all stores. Agentic compaction keeps context lean as conversations grow, so cost does not balloon and quality does not rot; it keeps the signal, drops the noise, and tells you when it worked. Validation is part of the pitch, since compaction is reported rather than assumed. Together, these read-side capabilities are what the company presents as the difference between storing memory and actively managing context, and they are the reason a growing conversation does not automatically mean a growing prompt. On the write side, a conversation turn does not land in a database. It runs through a pipeline that turns raw dialogue into structured, scoped memory: asynchronous ingest, extraction of structure rather than raw text, and storage across vector, graph, and file stores - vectors for semantic similarity, a graph for entity relationships, and files for documents and raw material. The write call returns before any of that happens, so it never blocks the agent. What governs the pipeline is a custom context architecture generated for each agent, controlling extraction, scoping, retention and more, rather than a one-size schema. Structured capture and entity resolution mean that 'Sarah', 'Sarah Chen' and 'SC' resolve to one person automatically, and references such as 'my manager' are linked across sessions. Temporal awareness weights recent context higher than stale context. Conscious forgetting processes retractions and contradictions, and because a change never destroys the previous version, every memory can be traced back through provenance. Consolidation runs as background cycles on the stores in three tiers - meditation, a light pass every few hours; nap, a deeper pass once a day; and sleep during quiet hours for deep consolidation and conscious forgetting. Synap's distinctive approach is that it treats memory as an active context-management problem layered on top of storage, rather than a storage problem alone. It works in two calls: you record the conversation as it happens, and before your agent replies you fetch what is known, receiving formatted context ready for the prompt. Everything the pipeline does behind that write call is invisible to the agent - extraction, scoping, retention, and consolidation run behind it. The memory architecture itself is generated for your specific agent instead of being fitted to a universal memory model, which the company contrasts with approaches built on extracted facts plus embeddings or on a temporal knowledge graph. Reads mostly never leave your process because context is pre-fetched while the conversation is still going. The framework is described as native across 23 agent frameworks, with adapters that let developers install the SDK, configure an API key, and start managing context in a few lines of code. The stated outcomes are reliability, cost control, and speed. Agents remember every user across sessions, channels, and months rather than the last twenty turns, so they stop re-asking for information and stop recommending what was already rejected. They remember the organisation through shared policies, product knowledge, and team context made visible to the agents that should see them and isolated from the users and tenants that should not. Context stays lean as conversations grow, which means the token bill does not balloon and quality does not rot; compaction keeps signal over noise and reports when it worked. Context arriving before the agent asks keeps voice agents conversational. Accuracy is reported at 92% on LongMemEval - the benchmark that tests whether a memory system retrieves the right fact from a long conversation and holds that accuracy as the conversation grows - and 93.2% on LoCoMo, with the methodology published and the eval harness open source so teams can run it against any system they are evaluating. Synap is not limited to a fixed list of applications. The site names customer support and sales agents, voice concierges, healthcare assistants, and multi-agent workflows among the places teams run it today, with dedicated use-case pages for healthcare, customer support, sales, voice AI, and multi-agent systems. In support and sales, the relevant value is recall of what a customer said in earlier sessions so an agent does not reopen a resolved issue or contradict a previous answer. In voice, the value is latency: sub-15ms P75 in-conversation retrieval keeps a voice agent conversational instead of pausing to think. In healthcare, the scoping model and custom hierarchy matter - the site illustrates a Hospital, Department, Clinician, Patient shape. In multi-agent workflows, shared organisational context reaches the agents that should see it while per-user and per-tenant memories stay isolated. The primary audience is developers and teams building AI agents who need production-grade memory without building it themselves. Synap provides Python and TypeScript SDKs, a REST API usable from any language, a hosted MCP endpoint for no-code platforms, and a CLI. The documentation states that most developers are up and running in under five minutes. Native integrations cover 23 agent frameworks, including LangChain, LangGraph, LlamaIndex, OpenAI Agents, Pydantic AI, CrewAI, AutoGen, Google ADK, Haystack, Agno, Semantic Kernel, Microsoft Agent Framework, NeMo Agent Toolkit, LiveKit Agents, Pipecat, Claude Agent SDK, Mastra, Vercel AI SDK, Vercel eve, Strands Agents, CAMEL-AI, Smolagents, and deepagents. Security includes encryption in transit and at rest, strict tenant isolation, BYOK for model providers, and on-premise, self-hosted, and air-gapped options, with PII posture applied per kind of data and down to what an individual API key may see. Enterprise plans add VPC and private deployment, SSO and SAML, configurable RBAC, and custom SLAs. The free tier requires no credit card and supports Google or GitHub sign-in, and the SDK plus the benchmark eval harnesses are open source on GitHub. For teams whose agents need to remember, Maximem Synap packages the whole problem - what to keep, how to scope it, when to retrieve it, and when to let it go - into a memory and context layer with reported benchmark accuracy of 92% on LongMemEval and 93.2% on LoCoMo, in-conversation retrieval under 15ms at P75, and native coverage of 23 agent frameworks. It replaces the workarounds teams currently reach for, including larger context windows, vector RAG, agent skills, rolling summaries, or a homegrown system, with a two-call interface and background consolidation, so that every conversation no longer starts from zero.
LockLines is a macOS app for designing plain-text lock screen messages that fit the small message area macOS provides. It is built for moments when a locked Mac needs to explain itself before anyone reaches the desktop: owner notes, contact information, asset labels, test machines, shared Macs, or any other message that has to be readable at the lock screen. The app follows a simple four-step workflow — visible text, scroll text, preview, copy — and ends with a complete plain-text message that is ready to paste into macOS Lock Screen settings. LockLines is available as a download on the Mac App Store, and its purpose is narrow on purpose: to make the short message your Mac shows when it is locked both accurate and readable, instead of cramped, truncated, or unclear. macOS gives a locked Mac only a small area for a lock screen message, and that constraint shapes everything about how such a message should be written. A long block of text does not present well there; the part a reader sees first is limited, and anything that runs beyond it becomes something the reader has to actively scroll to discover. At the same time, the situations that call for a lock screen message often need more than a single short line. A lost laptop may need a return prompt and, further down, pickup instructions. A shared office machine may need an asset label and a note about who to contact. Writing that text blind — composing it somewhere else and pasting it into System Settings — makes it very hard to know what will actually appear on the first screen and how the rest of the message will read after scrolling. LockLines exists to remove that guesswork by letting you see both states before you commit to a message. The developer's own account of the app's origin describes how an OnyX lock screen option led to experiments with multiline messages, aligned text, and scroll-down owner details, experiments that eventually became LockLines. LockLines begins with the first screen message: the visible text people see before they scroll. The app is designed around shaping that line or short block deliberately, because it is the only part that is guaranteed to be seen at a glance. Typical first-screen content includes a return prompt or an owner contact teaser, and the app's editors are set up for exactly this kind of short, high-value text. Rather than treating the lock screen message as one undifferentiated blob of characters, LockLines keeps the visible portion separate and editable in its own right, so you can tune the wording that matters most without disturbing the rest of the message. Users can also decorate the text, and the visible message editor includes repeated-character border controls for building simple visual framing out of plain characters that a lock screen can render. The second part of the message is the scroll-down detail: the longer owner note, pickup instructions, asset label, or test-machine details that appear after scrolling. LockLines gives this content its own editor, separate from the first-screen message, and displays it with styled plain-text boxes so the structure of the longer text stays legible while you write it. Because everything must ultimately be plain text, the styling in LockLines is achieved with plain-text techniques rather than system fonts or rich formatting — the app is about arranging characters so that the result reads clearly once pasted into the Lock Screen settings, not about adding graphics. Handled this way, the scroll-down section can carry the practical instructions that would overwhelm the first screen, without hiding them entirely: the reader gets a short visible prompt and, one scroll later, the full context they need. LockLines separates the first visible message from the scrollable details and then shows both inside a lock screen preview, so you can switch between the visible and scroll previews and understand the layout before copying anything. The visible preview corresponds to the first-screen message editor; the scroll preview shows the scrollable message details with their styled plain-text boxes, matching what a reader would find after scrolling. This two-state preview is the heart of the app's approach: it is an attempt to reproduce the exact lock screen states rather than an approximation, so that the gap between what you compose and what appears on the locked Mac is as small as possible. A short intro walkthrough also explains the plain-text lock screen workflow to new users, making the four-step process of visible text, scroll text, preview, and copy clear from the start. The overall method in LockLines follows the same sequence shown in its screenshots: visible text, scroll text, preview, copy. First you write the first screen message that people see before they scroll. Next you add the scroll-down details that appear after scrolling. Then you preview both states, switching between the visible and scroll previews so the lock screen layout is understandable before you copy anything. Finally you copy the complete plain-text message and paste it into the macOS Lock Screen settings. Nothing about the output is proprietary or locked in: it is plain text, which is what System Settings expects, so the message you design in LockLines moves directly into the place where macOS shows it. What LockLines adds is not a new format but a reliable way to preview and compose within the constraints of the existing one. The benefit of working this way is predictability. A lock screen message is usually written once and then left in place, which makes it expensive to get wrong: if the first visible line is unclear or the essential detail is buried too far down, nobody notices until the situation the message was meant for actually happens. By previewing both states and keeping the visible message separate from the scroll-down details, LockLines helps ensure the part that gets read first is the part that matters most, and that the rest of the message is still there for anyone who scrolls. The result is a lock screen message that remains readable in the small area macOS allows — one that turns a found device, a shared asset, or a test machine into something understandable rather than anonymous. LockLines is described as useful anywhere a locked Mac needs context. Its listed scenarios include lost Mac return instructions, so that a found device carries a prompt explaining how to get it back; owner contact notes, for machines that travel; school and office asset labels, marking which organisation or department a Mac belongs to; conference or demo machines, which are often picked up and put down by strangers; and repair intake or lab devices, where a locked machine needs to identify its purpose and its owner. The app also supports scroll-down prompts for longer messages, which covers cases where the first screen alone cannot say everything — for example a short return prompt in the visible message followed by fuller pickup instructions in the scrollable detail. The app is aimed at Mac users who need a locked machine to communicate something: owners of laptops that might be lost, IT and operations staff who label and manage shared hardware, schools and offices, conference and demo organisers, repair shops, and labs. LockLines is made by Ihor July, described as a cybersecurity expert and reverse engineer focused on secure, privacy-respecting macOS tools. The same developer also builds Parall, DockLock Lite, App Trust Preview, and App Archiver for Mac users who care about predictable native utilities. LockLines itself is distributed through the Mac App Store, with a support contact available from the website, and the developer has published a write-up of the app's origin — My Mac Apps Story, Part 5 — describing how experiments with multiline messages, aligned text, and scroll-down owner details led to the app. LockLines is a focused macOS utility for a specific problem: the lock screen message area is small, and the text you put there has to fit and read well. By separating the first visible message from the scrollable details, decorating the text where it helps, previewing both lock screen states, and producing a clean plain-text result to paste into System Settings, it replaces guesswork with a previewable workflow. For anyone who leaves a note on a locked Mac — a return prompt, an owner contact, an asset label, or test-machine details — LockLines is a small, purpose-built tool for making sure that note does what it was written to do.
AutonomyAI is a platform for Autonomous Product Delivery — an approach in which product managers and product designers build directly against a real production codebase instead of handing specifications to engineering. Its delivery layer, Fei Studio, connects to your repository, learns how your team writes code, and turns product ideas into production-ready product updates. The stated purpose is to turn product managers and product designers into product builders: the people who spec a change can also ship it, while engineers stay focused on what only they can build and simply approve the resulting pull request. AutonomyAI describes itself as the OS for building in production and positions Fei Studio as a second lane to production that runs alongside engineering. The company says it is trusted by 170+ product teams, and it offers a Playground where teams can sign up and try the workflow. AutonomyAI frames its product around a single observation: writing code got 10x faster, but shipping stayed the same speed. Every change still goes through engineering, so a product manager can spec a feature in an afternoon and then watch it wait in the backlog for a quarter. AI coding tools make engineers faster, but only engineers can ship, so the backlog keeps growing anyway. Meanwhile, app builders produce demos that cannot touch a real codebase, which means the work either gets redone from scratch or dies. AutonomyAI's contrast is that a coding agent — Claude Code, Cursor or any similar tool — starts from the same place but hands the work back to engineering, whereas Fei Studio hands engineers one click. In its own words, a coding agent writes the code and then waits for an engineer to pick it up, set up the environment, review and fix the code and ship it, and the result may still miss what the PM actually meant, sending round two back through the queue. Codebase ingestion is the first step of the workflow. Fei Studio plugs into your repository and models how your engineers write code — components, standards, design system, APIs, hooks and architecture — so that every task is built the way your team would build it, not from a generic AI template. The site states that you connect your git provider with no manual configuration, and that CSS, API, SSO and DB connections are all ingested. This understanding is described as taking under two minutes, and the model is self-updating as your codebase evolves. This matters because it is the difference between output that matches your product's look and feel automatically and output that needs manual setup; the comparison table lists "your product's look & feel" as auto-ingested and "reuses your existing components" as supported, against competitor tools that require a developer or cannot start from an existing codebase at all. Task execution turns ideas into production-ready product updates. Fei Studio takes raw product ideas — from prompts, PRDs, screenshots, tickets or Figma — and turns them into codebase-aligned variants and testable implementation options before generating production-ready output. It breaks ideas into structured plans based on your infrastructure, then translates those plans into real system changes and pull requests. The website describes the process as 36+ orchestrated steps per task with transparent output. Because the plans are built from your own infrastructure rather than a blank slate, the variants and options it produces are aligned to your codebase from the start, which is what allows the final output to be reviewable by engineering rather than a throwaway prototype. Production grade output is the third pillar. Every task produces production-ready code, a clean PR and full specs, all built to match your codebase, so engineering reviews and merges. Fei Studio generates production quality code to your standards, opens clean pull requests ready for engineering review, and includes full specs and change history for complete context. The comparison against other tools emphasizes the combination: output per task is code plus preview plus PR, and branches, commits and PRs are handled for you. Live preview of changes is included, so a non-technical teammate can see the rendered result before an engineer ever looks at the diff, while the code that reaches review is real production code rather than a prototype. The review step is deliberately lightweight — "your engineer clicks approve. That's the whole path." AutonomyAI's distinctive methodology is running the whole product loop as one system on your real codebase: discover, plan, build, ship, repeat. The newest piece is Discover Mode, which starts the loop before the ticket exists. It researches your analytics, tickets, customer calls and code to find what to build, and then the system plans, builds, verifies and hands your engineers a review-ready PR. After it ships, Fei Studio measures the result and proposes the next build. Critically, the Product Hunt description states that every merge makes it smarter — the system accumulates knowledge from the work that actually lands in production. The website also lists an Agent Knowledge Hub, which appears in the comparison table as something the competing coding tools and app builders do not offer. Fei Studio can also work inside any AI agent: a new MCP Server means Claude Code, Cursor or any MCP client can connect to it, so the delivery layer is available wherever your team already works. The stated outcome is delivery speed that finally matches the speed of code generation. Because product managers and designers have direct access to production, features no longer queue behind engineering capacity, and because output arrives as a clean PR with specs and change history, engineering keeps control of the merge. Engineers stop rebuilding from scratch, stop setting up environments for prototype handoffs and stop chasing misunderstood specs; they review and approve instead. AutonomyAI's own product team is the proof point it offers: the team opened 50+ PRs against its production codebase, writing zero code, and an engineer approved every merge. The headline for this is "Better Delivery, Built with Autonomy" — the promise that the people who spec a change are the people who ship it. AutonomyAI lists a broad set of use cases. Validate Product Ideas covers testing whether an idea is worth building. Improve Existing Features covers enhancing existing screens rather than starting from scratch. Turn Support Feedback Into Changes and Create Stakeholder Demos cover the path from customer signal to a demonstrable result. Accelerate Feature Delivery and Build Enterprise Customizations address delivery throughput and enterprise-specific requirements. Refactor Legacy Interfaces, Redesign Elements and Design System Alignment address modernizing and keeping consistency in existing UI. Prototype With Real Code and Explore UX Improvements cover hands-on experimentation. There are also role-based entry points: PMs can "ship features, not just specs," designers can "design in the real product," and engineers can "stop rebuilding from scratch." AutonomyAI is aimed at product teams — product managers, product designers and engineers working in the same delivery loop — with a separate Enterprise offering. The website names SolarEdge, SolarWinds, Augury, Salt, Taro, Deeto, Scytale, Symtrain, Plantwatchers, Allyable, i4, Midhub, Salesbrick, Commit, Lyncues, Trapica, Samplead, BlueBricks, MalamTeam, DeepSeas, IronVest, Mending, Nielsen, Simpology and Mesh VI among the 170+ product teams it says trust it. Integrations and inputs that are explicitly mentioned include your git provider, CSS, API, SSO and DB connections, plus PRDs, screenshots, tickets, Figma and prompts as task inputs. Fei Studio also connects to AI agents through its MCP Server, naming Claude Code and Cursor. Pricing is stated simply as per task, in contrast to the per seat plus usage, per credit and per subscription or per token models listed for the comparison tools; the comparison notes that competitor capabilities and pricing are as of September 2026. A Playground is available at studio.autonomyai.io/sign-up. In short, AutonomyAI's primary value proposition is that Autonomous Product Delivery closes the gap between fast code generation and slow shipping by running the entire product loop — discover, plan, build, ship, repeat — as one system on your real codebase, so product and design teams can build into production while engineers keep the final approval.

ChoreDivider is an iPhone app that splits housework by what it actually costs each of you, rather than by whose turn someone thinks it is. It is built for shared households, including couples, flatshares and families, where several people depend on the same recurring chores getting done. The app asks each person privately how draining a task feels for them, then balances time and effort across 14 days so that minutes stay even and nobody repeatedly gets the chore they dread. Every assignment shows why it is fair. It is free to start and available for iPhone. The problem it addresses is a familiar one in any shared home. Shared to-do lists only record what got ticked off; they never capture how draining the task was for the person who did it. What is left is a feeling of unfairness that no checklist can settle. As ChoreDivider frames it, whoever does more knows it, and whoever does less doesn't notice. The argument every shared household has had, "I feel like I always end up with the exhausting half," is rarely about the number of boxes ticked. It is about the cost behind each box, and about whether that cost is visible to anyone else. ChoreDivider is designed to make that cost visible and to let the split follow it, so fairness becomes something the household can see instead of something it has to keep score about in its head. The central mechanism is a private rating. Each person says what drains them, and they say it privately. The app presents one task at a time, for example a bathroom deep clean at 35 minutes, weekly, and asks: how draining is this for you? The scale runs from 1, meaning you barely notice it, to 10, meaning it wipes you out. Crucially, nobody sees your number until everyone has rated that task; your rating stays sealed until, for example, Marie rates it too. That sealing matters, because it means nobody anchors anybody else and neither person can simply copy the other's answer. The numbers that come out therefore reflect the genuine personal cost of a chore rather than a negotiated position. As the app notes, you report how much a task costs you, not how important it is. Once everyone has rated, the split follows those numbers. The app balances time and effort across 14 days, dealing each day's chores so that minutes stay even over that period and no one person keeps drawing the chore they dread. Because the balancing works across a two-week window rather than strictly day by day, a heavy task on one day does not have to be answered by a heavy task the next. Fairness is measured over the period, which is what allows the app to keep minutes even while still steering the chores each person minds most away from them. Alongside the allocation, ChoreDivider explains itself. Every assignment shows why it is fair, and every task explains how it got there. The Split screen lists who gets what, in minutes, along with the reason why each chore landed with that person. There are no points and no leaderboard. The app does not turn housework into a competition or a game; it simply shows the cost of the work and how the app responded to it, so the reasoning is available to everyone in the household rather than hidden inside an algorithm. Three screens do most of the work. Today shows what is on you today and the last 14 days in a single ring, so the current day is visible against the recent history the balancing is based on. Rate is where your number from 1 to 10 is entered, sealed until everyone has rated. Split shows who gets what, in minutes, and the reason why. Beyond recurring chores, one-off projects live in Projects: each person ranks the items and the separate lists merge into one shared order, rather than one person's list simply winning. The app syncs automatically between phones over iCloud, and it also works offline, catching up when you are back online. The unique approach here is the order of operations. Most chore apps ask how hard a chore is once, for everyone, and then divide the list. ChoreDivider asks each of you, in private, how draining that chore is for you specifically, holds the answers sealed until all of you have finished, and only then deals the chores out. Fairness is therefore defined by each person's felt cost rather than by an abstract difficulty rating, and it is demonstrated rather than asserted: because every assignment carries its reason, the household can inspect the outcome instead of having to take it on faith. The sealing step is what protects the integrity of that process, since no rating can be shaped by another person's answer. The stated outcome is straightforward: nobody's quietly doing more. Because minutes are balanced over 14 days and each task is dealt around what drains the people involved, the person who finds a chore exhausting is less likely to keep drawing it while the person who barely notices it takes it on. Because ratings are private and sealed, the conversation stops being about who rated what and becomes about the result those ratings produced. And because every assignment explains itself, the household has an answer ready when someone feels they always end up with the exhausting half, instead of a dispute that a checklist cannot settle. The use cases map directly onto the households the app describes. Two partners sharing a home can each rate recurring chores, with the weekly 35-minute bathroom deep clean as the example shown, and let ChoreDivider deal them so minutes stay even over 14 days. Flatshares and families work the same way, which means more than two people can each rate and each receive a share that matches what drains them. Households that also have one-off work rather than recurring chores can put those items in Projects, rank them, and merge the lists into one shared order. And any household that recognises the feeling of always ending up with the exhausting half has a concrete workflow: rate privately, wait until everyone has rated, then read the split and the reasons behind it. ChoreDivider is an iPhone app, free to start, downloadable from the App Store. It is aimed at people who share a household and the work that comes with it, including couples, flatshares and families, and who want the division of that work to follow what each person actually minds doing. It syncs over iCloud, works offline and catches up when you are back online. The interface is deliberately spare: three screens, Today, Rate and Split, cover most of the work, and there is no points system or leaderboard to maintain. In short, ChoreDivider reframes the chore chart. Instead of tracking who ticked off what, it records what each task costs each person, keeps those ratings sealed until everyone has answered, balances minutes and effort across 14 days, and then tells you why every chore landed where it did. The result is a household split based on real, privately expressed cost rather than on turn-taking, and one that comes with its own explanation every time. Free to start on iPhone, it is built for anyone who would rather stop keeping score in their head.

Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS are two new text-to-speech models added to the Gemini family, described by Google as its most expressive audio generation models yet. The models generate custom character voices and direct scene dialogue across Google AI Studio, the Gemini API, Gemini Enterprise, Gemini Notebook, and Google Vids. Gemini 3.8 Flash TTS is built for deep creative direction and character design, while Gemini 3.8 Flash-Lite TTS is built for high-volume, cost-efficient scale. Google frames the release as a shift that transforms voice generation from static presets into a dynamic creative studio, serving creators, developers, and enterprises who want to produce richer, more expressive audio experiences. The models complement the fast-growing Gemini Audio family, which already includes 3.5 Live Translate, 3.5 Transcribe, 3.8 Live, and 3.8 Live Extended Thinking. The problem the announcement frames is that voice generation has traditionally been locked to static presets, which limits how much a creator can shape a character, a narrator, or an agent's personality. Google states these models enable richer, more expressive audio experiences while also improving user experiences in products such as Gemini Notebook and Google Vids. The intended outcomes are high-quality audiobooks, podcasts, and real-time voice agents at scale, plus global dubbing and media localization with nuanced regional accents. Creating and customizing voices is the first pillar of the release. Google says the models let teams scale up from 30 original voices to an infinite library, so an entirely original character voice or a consistent brand ambassador can be produced as needed. Generative voice design in Gemini 3.8 Flash TTS lets users create bespoke voices from scratch by customizing role, accent, and voice characteristics across more than 100 languages and dialects using natural language prompting; Google's examples include bringing a dramatic, fire-breathing dragon to life or crafting a charismatic narrator with a distinct regional cadence. Beyond generated voices, an expansive voice library offers 2,000+ production-ready voices with broad language coverage, including regional varieties such as Mexican Spanish, Quebec French, and Scots English. Voice replication lets users recreate consistent vocal profiles from just a 30-second audio sample of their own voice or a voice they have the rights to use, backed by built-in consent verification, SynthID watermarking, and C2PA credentials intended to protect both developers and their vocal talent. A save-and-scale capability lets users save and manage the custom voices they designed, ensuring consistent performance and minimal drift across ongoing projects. Voice remixing is listed as coming soon: users will be able to pick a voice from the voice library and fine-tune timbre, pitch, pace, and accent, using prompts such as "add subtle Southern US accent" or "soften the delivery" to dial in specific characteristics. Once a voice is chosen, both models provide precise control over how each line is delivered. Users can direct performance line by line by writing their own stage directions or letting Gemini steer delivery with natural script cues, covering everything from a calm customer service agent to a whispered suspense scene. Long-form generation maintains high voice quality, natural pacing, and character timbre across hours of continuous audio with minimal speaker drift, which Google calls ideal for podcasts and audiobooks. Native two-speaker scene staging directs multi-turn conversations seamlessly from a single script, whether for a podcast or dramatic storytelling, while keeping both voices distinctly separated with natural conversational turn-taking. Scripted vocal bursts and backchanneling add realistic conversational texture through non-verbal cues such as , , and , plus active-listening interjections like |mhm| or |yeah|, enabling precise comedic timing and reaction beats. The overall approach is prompt-driven and script-driven: natural language prompts turn descriptions of role, accent, and character into vocal personas from scratch, and written scripts become fully performed dialogue scenes with directable delivery. Google positions these models as delivering expressive, high-quality speech generation built for global scale. Gemini 3.8 Flash TTS secured the number one overall spot on Hume AI's Voice Design Benchmark with a score of 71.4 and also led in accent modeling at 60.8. Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS took the number one and number two spots respectively on Hume AI's Overall Quality Index, and Google reports major improvements on use cases such as long-form content and dual-speaker screenplay control compared with Gemini 3.1 Flash TTS. In blind human preference evaluations on Voice Arena, the models secured top positions among competitors in key global languages including Japanese, Brazilian Portuguese, Vietnamese, Modern Standard Arabic, Mexican Spanish, and Hindi, with support for over 100 languages. For users, the stated benefits center on expressive, natural-sounding output that can be produced at scale without sacrificing reliability or consistency. Creators get granular creative control instead of preset-bound voices; developers get speech generation they can deploy into voice interfaces and voice agents; enterprises get multilingual reach and cost-efficient volume. Because the models maintain quality across hours of audio and keep two speakers clearly separated, teams can produce long-form and conversational content that holds together from beginning to end. Built-in safety tooling, including watermarking, is presented as a way to keep generated audio secure and to help prevent misinformation while still allowing ambitious creative work. Concrete scenarios described in the announcement include high-quality audiobooks, podcasts, games, immersive audiobooks, interactive media, and real-time voice agents at scale. Developers can experience the speech generation capabilities in the Google AI Studio audio playground, which is built like a voice design workspace where they can prompt entirely new vocal identities from scratch or replicate their own voice and then bring them into a dual-speaker screenplay editor to direct line-by-line delivery. Google's partners are integrating the models to accelerate global dubbing, localize media with nuanced regional accents, and power conversational voice agents at scale. Example voices demonstrated in the announcement include a high-energy DJ voice from Melbourne, a super-tinny monotone robot voice, and a Japanese dragon brought to life. Gemini 3.8 Flash TTS is rolling out for developers in the Gemini API and Google AI Studio, for enterprises coming soon via API in Gemini Enterprise, and for everyone in Gemini Notebook. Gemini 3.8 Flash-Lite TTS rolls out starting the same day for developers in the Gemini API and Google AI Studio, for enterprises coming soon via API in Gemini Enterprise, and for everyone in Google Vids. Through the Gemini API, developer platforms such as Agora, LiveKit, Pipecat, and Vercel enable developers to build and deploy high-performance speech generation experiences with ease. Google is also partnering with companies including Figma, HeyGen, Linguana, Wondercraft, 99.co, and Ollang. Voice replication through AI Studio is not available in Illinois, Texas, EEA, UK, Switzerland, and India. No pricing details are given in the announcement. Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS take text-to-speech beyond static presets by pairing natural-language voice design and voice replication with line-by-line performance direction, long-form stability, native two-speaker staging, and availability through Google AI Studio, the Gemini API, Gemini Notebook, and Google Vids. For anyone producing audio at any scale, the promise is expressive, natural-sounding speech with the control of a director and the safeguards of an enterprise platform.
IntellAgents.io is a single AI agent platform for customer communication. It answers inbound calls, places outbound calls, and handles conversations across WhatsApp, Instagram, Facebook, Telegram, and a website widget — all live 24/7, in over 36 languages, drawing from one knowledge base that a business sets up once. The system is built for companies that want every customer request answered promptly without staffing a round-the-clock support desk, and it covers both AI agents and human operators in the same system. The product is positioned around a specific, common failure: missed calls and slow replies. As the site puts it, most businesses juggle a different tool for every channel — one for phone support, another for WhatsApp, another for the website chatbot. That fragmentation means leads wait, messages sit unanswered overnight, and context is scattered across tools. IntellAgents replaces all of it with one AI agent that covers the phone line, the social inboxes, and the website at the same time, so a customer writing in French at 1:30 AM gets the same quality of answer as someone calling during business hours. The stated goal is simple: stop losing customers to missed calls and slow replies. Call handling is the core of the platform. The Inbound Call Handling capability means the AI answers every customer call instantly, 24/7 — no queue and no missed calls. Phone numbers and SIP support make it a complete voice agent for your line: it answers every inbound call and can place outbound ones too. A 24/7 hour availability promise means agents handle every inquiry around the clock, across every time zone, without fatigue. Language coverage spans over 36 languages, so the AI communicates fluently with customers without needing a translator; the platform's plans offer three languages on Starter, up to five on Pro, and unlimited languages on Business. Beyond voice, IntellAgents connects the messaging channels where customers already are. Facebook Messenger conversations are handled without anyone watching the inbox. Instagram DMs are answered the moment they arrive, day or night. Telegram is supported through your own Telegram bot, connected in a couple of clicks. WhatsApp Business gets two-way conversations answered automatically. On the website, a single snippet drops in a widget where visitors can either type to the agent or start a live voice call with it without leaving the page. Connecting a channel takes a couple of clicks — no developer and no separate bot to train for each one. A unified knowledge base sits behind all of it. All conversations — calls, DMs, comments — feed into a single unified source, and updating once reflects everywhere. Chat Summaries are generated instantly after every interaction, giving a clear and concise record so your team always knows exactly what happened. Escalation Workflows detect when a human touch is needed and route the conversation to the right person instantly with full context. Every escalation, follow-up, complaint, or callback can be logged as a ticket mid-call on a Requests board, where tickets move across New, Triage, In Progress, and Resolved and are tagged with the channel they arrived on. It works the same whether the request came in on phone, chat, or email, so nothing falls through the cracks. The platform's defining approach is unification. IntellAgents unifies AI agents, human operators, customer history, and escalation workflows into one system. AI resolves requests instantly, and when a human is needed, the conversation hands off with full context so the team never starts from zero. Rather than deploying a separate bot per channel, businesses configure the agent once against a single knowledge base and let it operate everywhere their customers are — from the first phone call to the last DM. The stated outcome is straightforward: cut support costs and never miss a lead. One AI system handles calls, messages, and follow-ups across every channel automatically, reducing support costs, responding instantly, and freeing the team to focus on what matters most. The AI agent service can answer common questions, qualify leads, book appointments, and support customers 24/7, and it can transfer the customer to a real person when needed. Plan descriptions frame the value in terms of headcount: Starter handles up to 60% of repetitive calls automatically, Pro is positioned as replacing one to two support agents on repeat queries across all channels, and Business as replacing three to five support agents with full call and chat automation at scale. The site lists industry starting points that suggest where the product is applied: Restaurant, Dental Clinic, Orders & E-commerce, Salon & Spa, Auto Service, Call Center, Bank, IT Company, and Telecom, plus a Custom Board option. A typical scenario is an overnight social inbox: a customer asks in Spanish at 11:42 PM whether the business is open tomorrow and gets an answer; a question in Russian at 4:07 AM about consultation pricing is answered too; an Instagram DM at 2:15 AM about north-side delivery is handled; a Facebook question in French at 1:30 AM about weekend delivery is answered. During a call, an agent can log an escalation, follow-up, complaint, or callback as a ticket without leaving the conversation. Pricing is published in monthly and annual terms, with annual saving 20%. A social-channels-only option is listed at $20/mo with approximately 3,000 AI replies included per month. The Starter plan is $45/mo with 200 minutes per month, $0.12/min after that, and 7,500 AI replies per month, including inbound calls 24/7, basic FAQ responses, call summaries, one knowledge base, three languages, and basic human handoff. Pro is $149/mo with 700 minutes, 25,000 AI replies, inbound and outbound calls, Instagram, Facebook, WhatsApp and Telegram, a unified knowledge base, human handoff and escalation, up to five languages, and follow-up workflows. Business is $449/mo with 2,000 minutes, 75,000 AI replies, task creation and CRM sync, advanced call routing, unlimited languages, priority support, and advanced analytics. Enterprise offers a custom setup with unlimited minutes, multi-agent setup, custom workflows, branded voice, CRM/API integrations, advanced routing, and dedicated support. Extra minutes are billed at $0.12/min on all plans, and no credit card is required to start. In short, IntellAgents.io brings the phone line, the social inboxes, and the website widget under one AI agent driven by a single knowledge base. By answering every call and every message 24/7 in the customer's own language, escalating to people only when it matters, and logging every request on one board, it lets a business respond instantly across every channel without adding headcount.
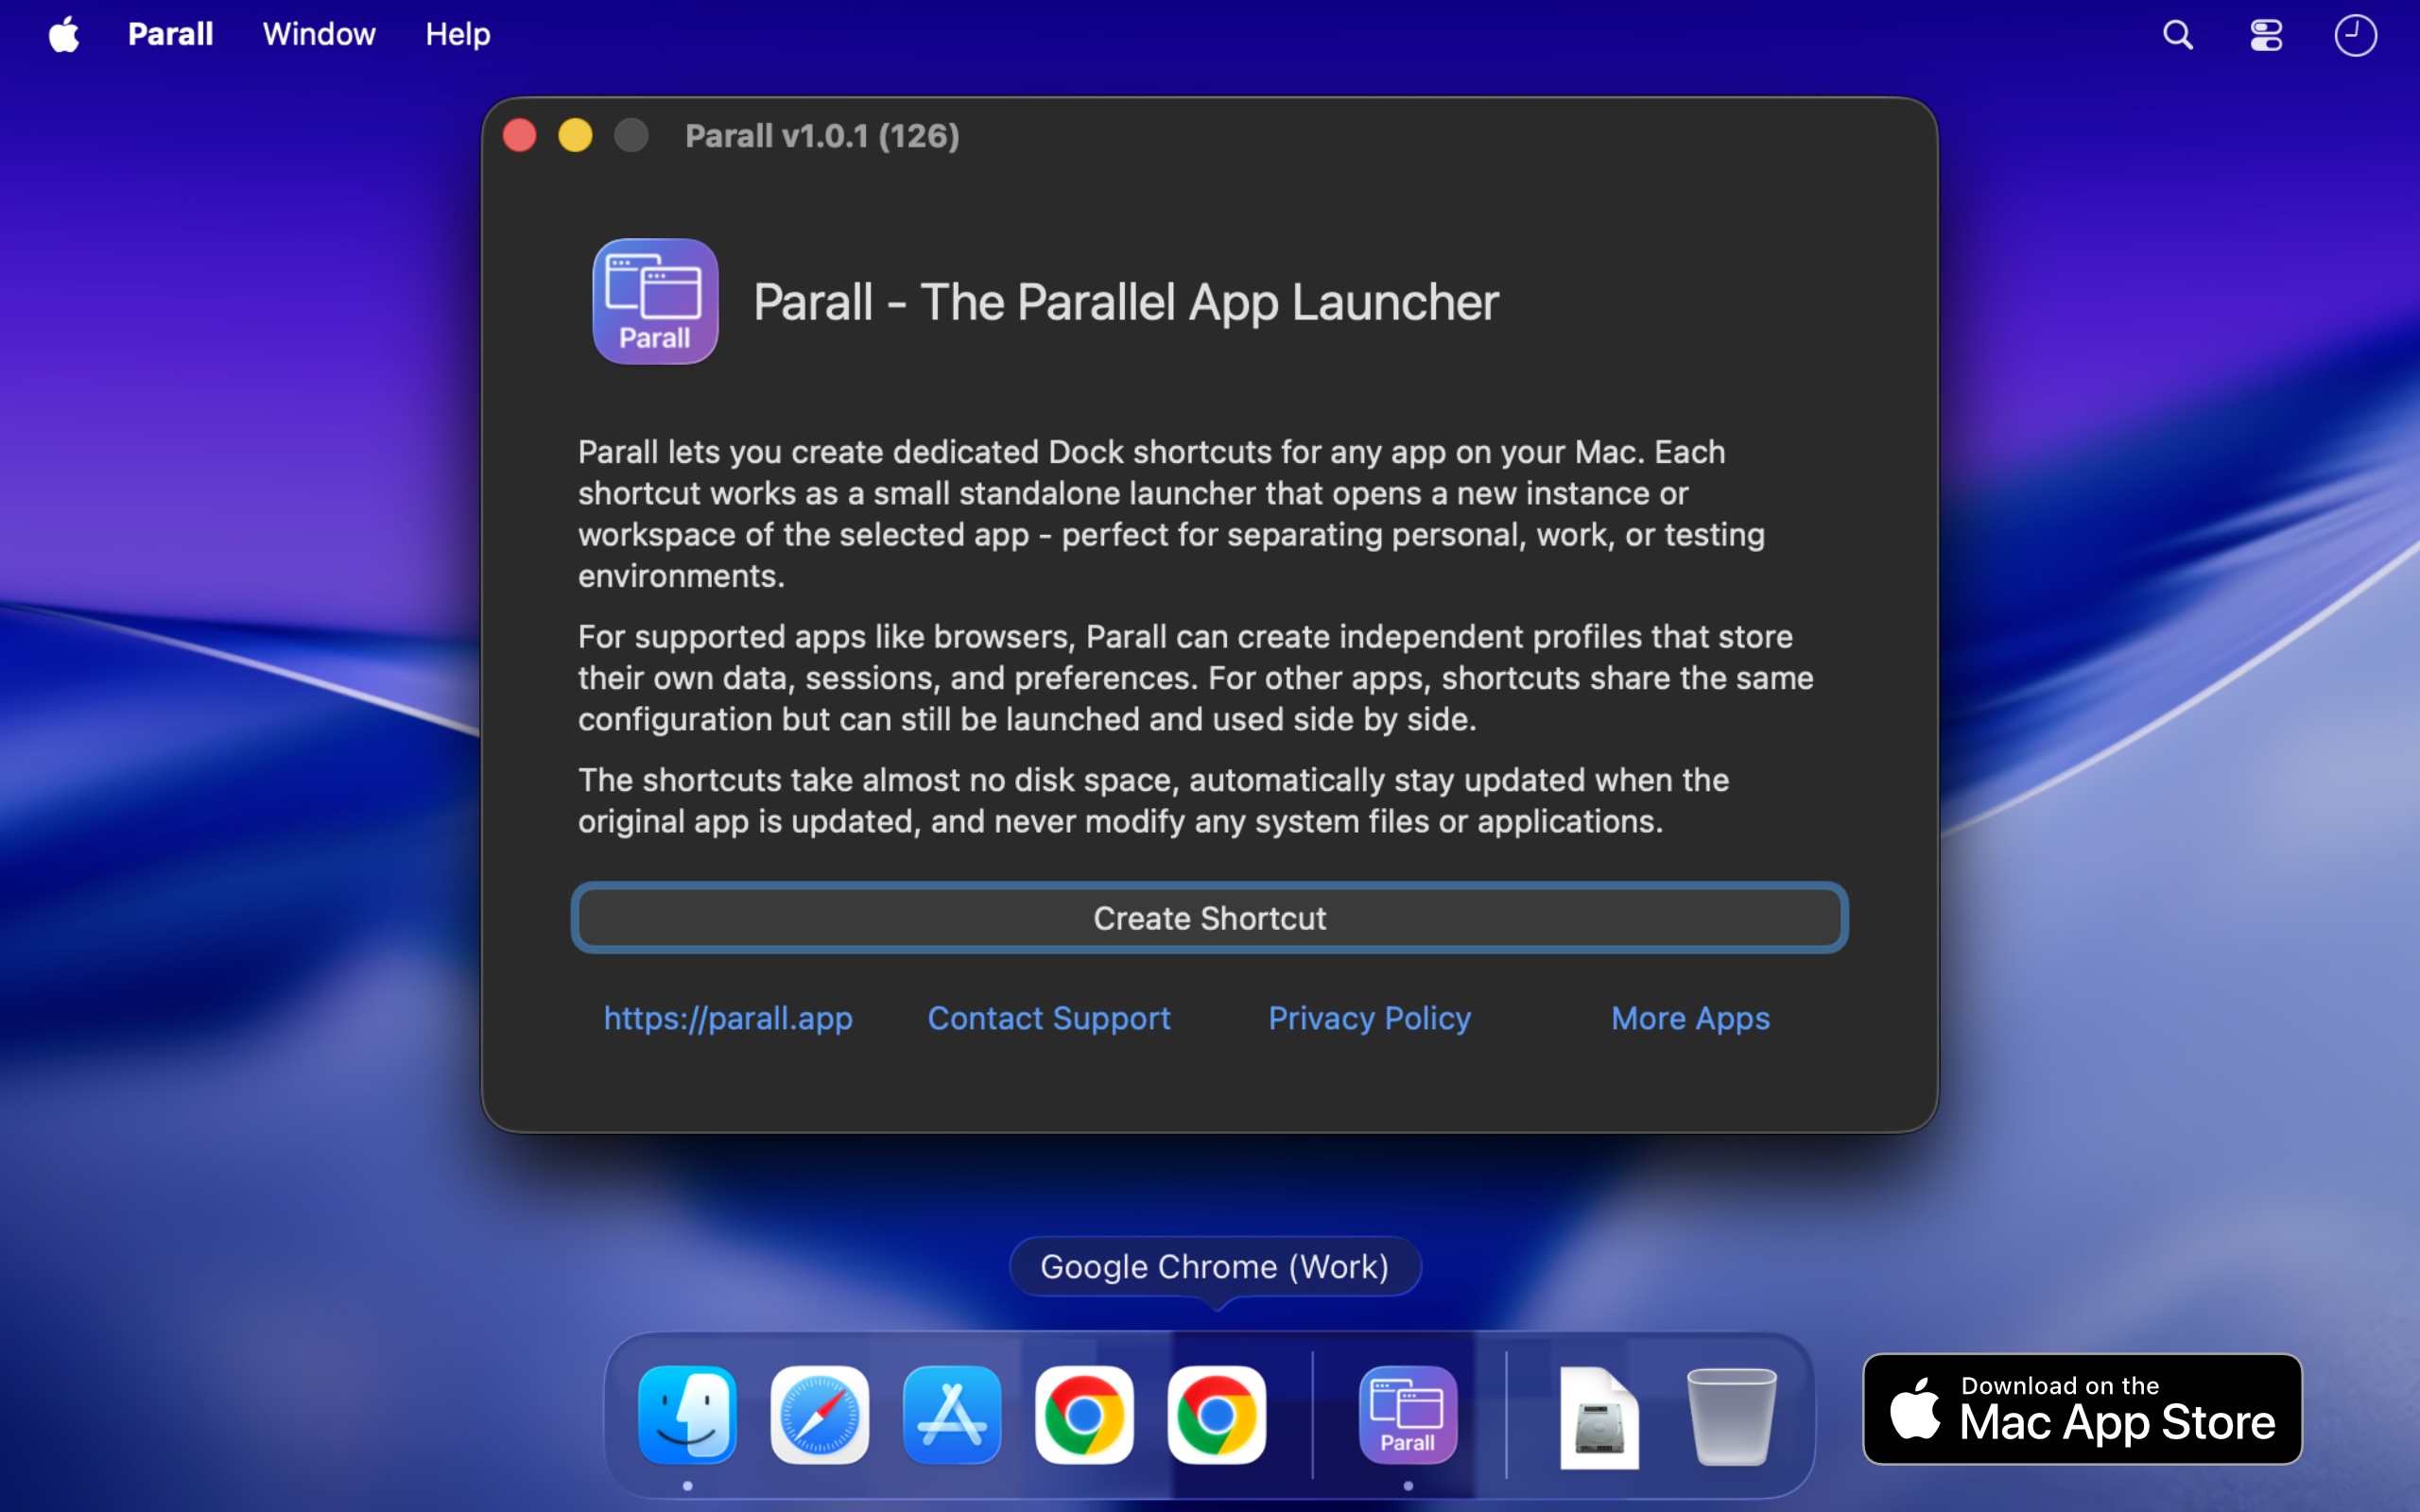
Parall is a native macOS utility that lets you run multiple independent instances of supported apps on the same Mac, each launching with its own name and Dock icon. Where the target app supports it, those instances can also use separate accounts, profiles, data folders, and storage locations. Beyond applications, Parall turns any website URL into a Web App Shortcut and can also create shortcuts that open files, folders, and command-line tools. It is built for Mac users who need genuinely separate workspaces for multiple accounts, browser profiles, client setups, or development environments, without logging in and out or changing how their existing apps work. The problem Parall addresses is built into how macOS handles running applications. macOS gives a regular app one usable running identity, so launching it again cannot reliably produce a separate instance with its own Dock icon and Spaces behavior. App data is stored wherever the app decides, which means accounts, profiles, and working data often cannot be moved to an external drive, cloud storage, or an easy-to-access folder. To use more than one account, users usually have to log out and log back in every time. Parall exists because there was no easy, polished way for regular users to run truly independent app instances, and it became the first tool of its kind designed specifically to solve that problem without copying or modifying the target app. Parall's central capability is separate instances with their own identity. You can run multiple supported instances side by side instead of being limited to one, give each instance its own data folder, account set, profile, or storage location, and pin each one with its own name and icon so macOS treats it like a distinct app. Supported families include Electron, Eclipse, Chrome, and Firefox based apps, including sandboxed apps, with named examples such as Slack, Notion, VS Code, Cursor, OBS, Dropbox, and Philips Hue Sync. Parall shortcuts are small macOS launcher app bundles that directly execute the installed target app's binary; they do not contain a copy of the target app, and they are not sandboxed by design because they must launch the original application directly. Parall also turns websites into native app-like shortcuts. Any URL can become a Web App Shortcut with its own Dock identity, and you can set custom data paths and web app storage paths for those shortcuts. Website shortcuts run on native WebKit, without Electron or a bundled Chrome engine. MS Teams and WhatsApp web apps are supported with notifications, unread badges, and an optional menu bar background mode, and version 2.4.4 enlarged the Web App catalogue, while 2.4.3 added full-screen Web App video support and 2.4.5 added Command-R page reload in web apps. This means a website can behave like an installed Mac app, with storage kept where you choose. Dock and menu bar control is another major feature group. Parall extracts icons from any app or file so shortcuts can use custom icons, draws labels on top of shortcut icons, and lets you name each shortcut individually. You can apply per-shortcut Dock effects and animations, override appearance with Follow System, Light, or Dark mode regardless of the macOS system setting, and add an optional menu bar icon for any shortcut while the target app is running. Menu bar icon appearance can be customized with scale, grayscale, and template mask options. For supported Chrome-based browsers, Parall controls full screen menu bar behavior, and it offers experimental control of Dock icon visibility. Advanced launch configuration rounds out the toolkit. You can run command-line tools from the Dock with custom arguments and environment variables, define custom environment variables per shortcut, override HOME for compatible apps with a containerized structure, and adjust advanced Info.plist parameter overrides for each shortcut for experienced users. File and folder shortcuts open in their default app, and Web App Shortcut mode, command shortcut mode, and file and folder shortcuts cover different launching needs. Parall's engine grew from research rather than a recipe. Its core could not be assembled from public documentation because the app behaviour it depends on is undocumented, so the developer spent years reverse engineering macOS app architecture, testing individual apps, and refining an engine around what actually works. Parall's compatibility profiles come from observing how each target app launches, stores data, handles separate processes, and interacts with the Dock, and the same work makes shortcuts function correctly when opened through Spotlight, Raycast, and Alfred. There are currently 124 compatibility records, and the app is verified and tested through macOS 27 Golden Gate, working from macOS 10.11 onward. Crucially, Parall never edits or freezes the target app, does not use private APIs, and does not inject or patch code, so the original app stays signed and its built-in updater keeps working; after an update, all shortcuts use the new version when restarted, which matters because app updates often patch security vulnerabilities. Privacy is a deliberate design choice. Parall works locally and offline, has no automatic telemetry, no background daemons, no Electron runtime, and no bundled Chrome engine, and it does not modify your system files or original apps. The result is a native, human-led tool that runs quietly on your Mac without phoning home or altering the software you already use. The benefits show up clearly in how people describe using it. Reviewers report running work and personal versions of apps side by side, keeping multiple clients signed in at once, giving each Chrome or Vivaldi profile its own Dock icon, and running several Claude desktop or Claude Code instances in parallel without logging in and out. Others use it for separate Cursor IDE logins and extensions for different client accounts, multiple OBS instances with separate data, separate Philips Hue Sync instances for different display setups, and multiple Emacs instances with different command-line arguments, environment variables, icons, and app names. One reviewer notes that setting it up took under a minute and then could be left alone, and another highlights using it on a shared family desktop to give different Chrome profiles their own Dock icons. Parall is aimed at Mac users who juggle multiple accounts across different apps: developers, freelancers and agencies working with several clients, people separating company and personal accounts, and anyone who wants an alternative to repeated logouts or fast user switching. It is distributed through the Mac App Store with Family Sharing, requires macOS 10.11 through macOS 27 Golden Gate, and includes a published compatibility table plus an option to ask about a specific app before purchasing. One reviewer describes it as the best $9.99 they had spent on an app. Parall is developed by Ihor July, a cybersecurity expert and reverse engineer who also builds DockLock Pro, App Trust Preview, LockLines, and App Archiver. In short, Parall gives macOS the missing control for running the same app as separate instances with separate data, accounts, and Dock identities, plus a way to turn any website into a Web App Shortcut, all through lightweight shortcuts that leave the original apps signed, updateable, and untouched.
Harness Manager is a native Mac application that keeps an AI coding stack under control from one workspace. Instead of tracking tools, connections, and updates across many separate windows and tabs, users open a single app that shows what is installed, what is running, and what needs attention. From there they can discover harnesses, MCPs, and skills; install and update coding tools such as Claude Code, Codex, OpenCode, and Pi; inspect provider configuration, MCP servers, skills, and processes; and compare AI models across 31 ranking collections. It is built for developers and anyone who works with AI coding tools regularly and wants a clearer view of their setup. The app is free and open source, licensed under Apache 2.0. AI coding setups have grown quickly and unevenly. A typical developer may run several harnesses side by side, each with its own installation path, version history, and configuration. MCP servers add another layer of connections, skills add reusable instructions, and new models arrive constantly with different strengths for coding, design, reasoning, or local use. Keeping track of all of it often means keeping twenty browser tabs open, scrolling changelogs, and manually checking versions. It is easy to lose sight of which tools are actually installed, which ones have updates waiting, and where a broken installation or configuration problem is hiding. Harness Manager addresses that sprawl by putting the whole stack in one place so the next move — an update, a new skill, a model comparison — is visible rather than buried. The Discover screen is where new pieces of a workflow are found. Users browse harnesses, MCPs, and skills by popularity, moving from familiar tools like Claude Code and Codex to options they have not tried yet. Each entry is presented with install options, so the step from discovering a tool to having it on the machine is short. The app covers a broad catalog of harnesses, including Claude Code, Codex, Gemini CLI, Cursor, OpenCode, Warp, Antigravity, Antigravity IDE, T3 Code, Conductor, Superset, Paseo, cmux, Orca, Herdr, and Emdash. MCP servers and skills are discoverable through the same lens, which means connections and reusable instructions can be found and added without leaving the app. Popularity ordering gives a practical starting point when the ecosystem feels too large to survey manually. The workspace answers three questions at a glance: what is installed, what is running, and what needs an update. The update flow is deliberately transparent. Users see installed versions, compare them with available updates, and review the command that will run before deciding when it runs. Nothing is applied silently; the decision stays with the person at the keyboard. Harness Manager also automatically detects what is already installed on the Mac, checks versions and paths, and diagnoses broken installations or configuration issues. That makes it useful not only for adding new tools but for maintaining the ones already in daily use. When a tool fails to launch or a configuration drifts, the diagnostics surface the problem instead of leaving it to guesswork. The rest of a setup is shown in plain sight. Providers appear as local configuration signals, so it is clear how tools are pointed at the services they use. MCP servers are listed as the connections belonging to the tools, making it easier to see what each harness can reach. Skills are shown as reusable instructions, the building blocks that shape how a tool behaves. Running processes complete the picture by showing what is active and where it is running. Crucially, this information sits alongside the tools that use it rather than in a separate configuration file or terminal session. Grouping configuration with the tools it belongs to reduces the mental overhead of remembering which setting applies to which harness. Benchmarks and rankings turn model selection into a comparison rather than a hunt. The app presents 31 ranked collections covering general capability through creative and specialist work. General collections include Smartest, Coding, Agents, Fastest, Low latency, Cheapest, and Free. Development collections cover Design, UI components, Full-stack apps, Mobile apps, Tool calling, and Long-context reasoning. Reasoning and knowledge collections span Reasoning, Math, Science, Writing, Instruction following, RAG, and SQL and analysis. Deployment collections include Local, Open-source, Small and fast, Long context, Vision, and Uncensored. Creative and specialist collections cover Data visualization, SVG, Game development, 3D, and Roleplay. Seven comparison metrics are available, including intelligence, coding, agentic performance, design, speed, latency, and context. Rankings data is provided by Modelgrep. The app is explicit that rankings are a starting point and results depend on the task. The Harness Briefing keeps the ecosystem readable without opening twenty tabs. It gathers publisher news, community finds, and official releases into one native page. Sources include OpenAI, Google Developers, Simon Willison, Hacker News, and project releases. Every story links back to its source, so readers can verify and read further, and articles are read inside the app. The intent is to go beyond the changelog — new harnesses, useful ideas, and the story behind a release — so that staying current is a matter of checking one screen rather than monitoring many feeds. Getting started takes three steps. First, download, drag, and open: Harness Manager moves to Applications and the workspace opens, with no build tools required. Second, see the existing stack: the app finds supported tools and configuration already on the Mac and brings them into one view. Third, make the next move: review an update, discover a skill, or compare models for the next project. The app requires macOS 14 or later and runs on both Apple silicon and Intel Macs. It is distributed as an early preview build that is not yet notarized, so macOS may require approval in Privacy & Security on first launch. The project is free to use, inspect, and modify under the Apache 2.0 license, with source available on GitHub. Benefits follow directly from consolidation. Users spend less time on setup management and more time building, because the state of the stack — installations, versions, connections, skills, and processes — is visible in one place. Updates become a deliberate decision rather than a surprise, since the command is reviewed before it runs. Diagnostics reduce the time lost to broken installations and configuration issues. Model comparison shortens the path from a new task to a sensible starting model, and the briefing replaces scattered reading with a single sourced feed. For teams and individuals who depend on AI coding tools every day, the outcome is a stack that stays sorted and a workflow that keeps moving. Use cases span the daily rhythm of working with AI coding tools. A developer setting up a new Mac can let Harness Manager detect existing installations and fill in what is missing from the Discover screen. Someone maintaining several harnesses can check installed versions, compare available updates, and review the command before applying it. A user troubleshooting a tool that will not start can look for broken installations or configuration issues and inspect provider configuration, MCP servers, and processes. When starting a new project, they can browse ranking collections to shortlist a coding or reasoning model. And when they want to keep up with the ecosystem, they can read the briefing's sourced stories in the app. The app is aimed at developers and AI tool users who run coding harnesses on a Mac and want their environment legible rather than scattered. It supports a catalog that includes Claude Code, Codex, Gemini CLI, Cursor, OpenCode, Warp, Antigravity, Antigravity IDE, T3 Code, Conductor, Superset, Paseo, cmux, Orca, Herdr, and Emdash. Requirements are macOS 14 or later on Apple silicon or Intel hardware. Harness Manager is free and open source under Apache 2.0, available as a direct download from GitHub, and supported by an invitation to star the project if it helps keep a stack moving. It is also listed on Product Hunt. Harness Manager's value proposition is simple: one workspace for an AI coding stack. It combines discovery of harnesses, MCPs, and skills with update control, configuration visibility, diagnostics, model rankings, and an ecosystem briefing, all in a native Mac app that is free and open source. The result is less setup to manage and more space to build.
Preview a specific room change in your own photo before buying, painting, or remodeling. Upload a room photo, describe a change to furniture, walls, flooring, or style, and optionally add a product or material reference image. Free use is available, with paid image credits for additional generations.
Lightmeter is a pocket film camera app for iPhone that captures natural, raw photos with authentic film looks. The site describes it in a single line: a real light meter when you carry film, and a film camera when you don't. That dual purpose sits at the centre of the product. It is made for everyday moments rather than specialist shoots, and it deliberately avoids the heavy processing that most modern phone cameras apply. The stated approach is zero-AI processing with no HDR, producing natural colors and authentic grains. Film looks are built on true RAW capture, so grain, halation and color behave like film rather than like a filter laid over a flat photo. The problem Lightmeter addresses is visible in almost every photo taken on a modern phone. Before a file ever reaches the gallery it has typically passed through HDR merging, AI scene detection and multi-frame stacking, all of which smooth texture, lift shadows and flatten the contrast that analog photography depends on. In response, a large number of apps offer a film look as a colour grade applied on top of that already-processed image — a filter over a flat photo, in Lightmeter's own phrasing. That is an aesthetic layer rather than a photographic process, and it tends to look uniform across very different lighting conditions. Lightmeter's site makes the distinction concrete with a side-by-side comparison of the same scene: one frame labelled Shot on lightmeter, and the second showing the same scene straight off the sensor, ungraded. The implication being made is that the film character comes from the capture and the look working together, not from a preset applied at the end. The film looks are the most visible part of the app, and the site lists twelve of them by name: NGT2266, Ink E6, Classic 64, Cine 50, Dusk, Daybreak, Bloom, Ember, Retro 400, Mono X400, Mono 3200 and Mono P400. They are presented as film looks inspired by real film stocks and artists, which places them in the tradition of emulating specific emulsions rather than inventing arbitrary colour treatments. The naming spans both colour and monochrome — the Mono looks sit clearly alongside the colour ones — so the library covers black-and-white and colour shooting alike. Crucially, the Product Hunt description states that these looks are built on true RAW capture, and that grain, halation and color behave like film rather than like a filter on a flat photo. Halation, the reddish bleed that appears around bright highlights on film, and grain that responds as film does, are the details that separate an emulation from a simple grade. The hero imagery on the site shows a film look already loaded in the shutter row, indicating that a look is chosen in the app before you shoot. The dual role of the app is what its tagline turns on. When you are carrying film, Lightmeter works as a real light meter — a tool for reading light so you can set exposure on a film camera. When you are not carrying film, it becomes the camera itself, shooting with the film looks described above. The site's hero image shows this split directly: two iPhones side by side, one showing a building against a blue sky in the viewfinder, the other showing the shutter row with a film look loaded. The page's own metadata lists the related capabilities as a light meter app, an iPhone light meter, an exposure calculator, a reflected light meter and the sunny 16 rule — the vocabulary of traditional photographic metering. In other words, the app meets analog photographers in the workflow they already use rather than asking them to abandon it. Privacy is stated as a design principle rather than an add-on. The site's copy reads: private by design, no signup — the app has no tracking, no ads, and collects no data. The Product Hunt description repeats the point and adds that nothing leaves your phone. There is no account to create, no analytics profile being built and no advertising identifier to manage. For a camera app this matters more than it might in other categories, because photographs are among the most personal files on a phone. The absence of a signup step also removes friction at the point of use: the app can be opened and used without an onboarding flow, an email address or a login. The promise is a closed loop — open, capture, save — that stays on the device. The methodology Lightmeter describes is a chain rather than a single trick. Capture comes first and stays deliberately unprocessed: zero-AI processing and no HDR mean the app is not merging frames or making scene-based decisions for you. That leaves a true RAW capture as the foundation. The film look is then applied against that RAW data rather than against a finished image, which is why the site can claim that grain, halation and color behave like film. Because the grain and halation are properties of the look applied to raw capture, they respond to the image rather than sitting on top of it uniformly. The site reinforces the point with its comparison pair: one frame shot on Lightmeter and one raw frame with no Lightmeter. Nothing in the described workflow depends on the cloud, an AI model or a server, which is consistent with the no-signup, no-tracking position. The practical benefit is a photograph that keeps the texture, contrast and colour behaviour associated with film rather than the smoothed, evenly lit look of computational photography. Colors stay natural because HDR and AI processing are not lifting and flattening them. Grain and halation appear where film would show them. The film look library gives a consistent result to choose from rather than a slider to tune, which suits people who want the character of a particular stock without a colour-grading session afterwards. The privacy posture is a benefit in its own right: no account, no ads, no tracking, no data collected, and nothing leaving the phone. And the dual light-meter and camera role means a single app covers both the film-shooting day and the digital one. Concrete scenarios follow from what the site shows. The first is metering: a photographer loading a roll of film and using Lightmeter to read the light and calculate exposure before setting the camera. The second is the everyday moment — the pocket film camera half of the tagline — where a phone is what is at hand and the goal is a film-looking photograph rather than a processed one: a hill path at dawn, a barista working under warm pendant lights, a cyclist passing flowering trees, an iced coffee on a cafe table. The collage also includes black-and-white frames, such as a concrete facade with balconies cutting diagonally across the frame and glaciers winding between Himalayan ridges seen from the air, which map to the Mono looks. And for anyone comparing results, the graded-versus-raw pairing is itself a use case: seeing exactly what the film look contributes to an otherwise ungraded capture. Lightmeter is aimed at photographers and photography-inclined casual shooters on iPhone. The Product Hunt topics list iOS, Photography and Photo & Video, and the only download route offered on the site is the App Store, with an Apple badge and a QR code linking to the listing for Lightmeter - Pocket Film Camera. The site is presented in English, and the publisher listing credits Aakash Goel. No pricing, subscription tiers or free-plan details are stated on the page, so nothing can be claimed about cost. No third-party integrations are mentioned either. The audience described by the copy is twofold: people who carry film and need a meter, and people who do not carry film but want film-looking photographs from the phone they already have. Taken together, Lightmeter's proposition is narrow and clearly stated: a single iPhone app that meters light for film shooters and shoots film-look photographs for everyone else, using zero-AI processing, no HDR and true RAW capture as the foundation, with grain, halation and color that behave like film rather than a filter on a flat photo. Twelve named looks inspired by real film stocks and artists provide the visual range, while the no-signup, no-tracking, no-ads, no-data-collection design keeps the workflow entirely on the device. The primary value is film character for everyday moments, without AI and without an account.
Naise AI is an AI teammate for marketing. From one brief, it runs social media management, image generation, influencer campaigns, PR media outreach, and market research across every channel, in any language and any market. The website states that the strategy stays with your team while Naise handles the repetitive execution work, so founders and lean teams get the output of a full marketing department without the overhead of building one. Naise AI is headquartered in Singapore and positions itself as going from a cold start to live campaigns quickly, with no waiting on asset approvals or agency onboarding. Much of the site is framed around the cost of doing marketing manually. Naise states that marketing managers spend 80% of their week on execution — drafting, scheduling, outreach, and reporting — leaving little time to drive strategy. Startup founders are described as needing the team they cannot afford to hire, doing the work they do not have time to do. The comparison table sets out the alternatives: human contractors cost $4K–$8K per role, are available business hours only, and take one to two weeks to hire; traditional agencies charge $10K+ monthly retainers and need two to four weeks of onboarding. Naise is listed as available 24/7, immediate to start, at fractional cost, executing in minutes and requiring no management. The site also distinguishes Naise from AI writing tools such as Jasper or Copy.ai, noting that writing tools produce text and hand it back to you, whereas Naise does the whole job: research, copy, visuals, creator outreach, scheduling, press pitching, and reporting. The Social Media Management agent builds data-driven content calendars on top of live market research. Before writing a single caption, Naise researches which formats drive the most engagement in your niche, finds your audience's optimal posting windows, and surfaces trending topics in real time. It then writes the copy, generates visuals, and schedules posts across Instagram, TikTok, Facebook, and LinkedIn, with captions localized per platform and auto-scheduled everywhere. Supporting tools are exposed individually too: trending topics and hooks, image generation, the content calendar and post scheduling, and live performance analytics that track engagement and growth across all channels at once, so a single brief produces both a plan and the assets to execute it. The Image Generation agent produces on-brand visuals at the speed of a prompt, with no designer and no brief-to-agency back-and-forth. It creates campaign key visuals, product shots, and story graphics locked to your brand guidelines — brand colors, fonts, and rules are applied automatically — and generates them at the correct spec for every platform, with multiple style variations per campaign for A/B testing. The Influencer Campaign agent covers the full lifecycle: discovery from a pool of 10M+ verified global creators matched by niche and reach, then automated outreach, negotiation, and contracting, then content approval and scheduled posting, finishing with live ROI tracking on reach, views, and conversions per creator and per campaign. Naise says this removes the agency middleman and the manual spreadsheets, and one testimonial describes checking campaign delivery in about ten minutes instead of going through every creator manually. The PR Media agent handles press coverage in any language and any market. It drafts localized press releases, distributes them to the right outlets without manual pitching, and monitors coverage and sentiment across every region in real time; one brief is said to cover the globe with no agency retainer. Supporting tools include targeted media lists that match outlets and journalists to your story, brand news and media monitoring that tracks every mention of your brand across the web, and hashtag campaign analysis that measures the reach and sentiment of campaign hashtags. The Market Research agent runs company-specific intelligence rather than generic reports: a brand audit that positions you against category leaders and surfaces clear gaps, competitor analysis that maps messaging and content playbooks in real time, and trend signals that feed directly into briefs and content calendars. A free audit reads your last 30 posts, analyses social media presence across channels, identifies competitors, and builds a brand profile, viewable after signing up with a verified email. Naise describes its approach as one brief flowing through different "flavors" of the same agent. The Product Hunt listing describes the setup as locking in brand guidelines with Persistent Memory, selecting a Prompt Playbook, and letting the platform handle the execution. Persistent Memory is highlighted by a customer testimonial as what sets Naise apart from generic AI tools: once guidelines are uploaded, brand voice and aesthetic stay locked in permanently, so large campaigns deploy with consistently on-brand messaging across every platform. Agencies can hold a separate brand voice and memory per client, batch-launch campaigns across all accounts in one session, and send white-label reports directly to clients. A 60-second walkthrough shows Naise taking a single brief and turning it into a live multi-channel campaign in under five minutes. The stated outcomes centre on time and cost. The site reports an average of 97 minutes from first prompt to live campaign, and the Product Hunt listing describes going from a cold start to live campaigns in under 24 hours while saving 40+ hours a week and cutting marketing costs. The comparison table claims total annual savings of up to $150K versus hiring a full in-house team, alongside 24/7 availability, immediate start, minutes-long execution, expert-level cross-channel coverage, and always-consistent output. Marketing managers are promised a full content calendar from a single brief and a live ROI dashboard for every running campaign, while agency clients receive white-label reports. Naise also lists SEO, AEO, GEO (answer engine and generative engine optimization), performance marketing, and predictive modelling as flavors shipping in upcoming releases. Naise publishes four role-based use cases. For marketing agencies, Naise acts as a silent operator for every client account so one team's output is multiplied across ten, with separate brand voice and memory per client, batch-launched campaigns, and white-label reports sent to clients. For marketing managers, it handles drafting, scheduling, outreach, and reporting so time goes to strategy, with a full content calendar from a single brief, captions localized per platform and auto-scheduled everywhere, and a live ROI dashboard. For startup founders, it is positioned as the team they cannot afford to hire: first campaign live in a matter of minutes, no marketing experience needed to start, and scaling as the team and budget grow. For e-commerce brands, every product launch becomes a full go-to-market campaign automatically, from launch-day key visuals to influencer seeding and press outreach, with AI-generated product visuals for every platform size, influencer seeding at scale, and localized product copy for global storefronts. Naise AI runs on the web. Content is written, localized, and scheduled for Instagram, TikTok, Facebook, and LinkedIn, with each caption adapted to the platform it goes out on; influencer discovery covers Instagram and TikTok creators, and PR coverage is tracked across news outlets in every market you target. The site says 1,000+ founders and marketers have joined and lists marketing leaders at 5-hour Energy, BenQ, Elixir Esports, Moonton, SKIN1004, T-Tracing, and ZOWIE. Pricing has three tiers, each running the full agent suite and starting with a 3-day free trial: Entry at $59.90 per month (currently shown at an early-access price of $39.90 for one month) with 2 campaigns; Middle at $119 per month, discounted to $88.80, with 6 campaigns and 3× AI usage capacity; and Advanced at $199 per month, discounted to $150, with 16 campaigns and 8× AI usage capacity. Every plan includes unlimited creator reach, unlimited outreach, AI trained on your brand voice, and PDF reports and exports, with yearly billing offering two months free and enterprise custom pricing on request. Naise AI's core proposition is simple: one AI teammate runs the marketing busywork across social, influencer, and PR in any language and any market, while your team keeps the strategy. For lean teams and founders, that means campaigns live in minutes rather than weeks, brand consistency enforced by persistent memory, and marketing output that scales without scaling headcount.
Solid gives AI agents their own computers, accounts, and budgets so that long-running, complex jobs can be handed over and finished without the user needing to supervise every step. You bring the goal and the ground rules; the agents work out the steps, check the result, and report back. The product is described as being built for complex, long-running work for you and your team, rather than being a personal assistant: agents can build apps, automate workflows, and tackle work you lack the time or expertise for. They pick and set up their own real machines, create accounts, and pay for services, and they use your apps either through APIs or by logging in like a person. Close your laptop, and Solid owns the job from start to finish. The context Solid addresses is the gap between a chat window and a completed piece of work. Conventional assistants stop when the conversation closes, and many agent products depend on prebuilt connectors, which means they only work with tools that someone has already integrated. Solid's premise is that the agent should instead handle the setup and the troubleshooting itself. As the site puts it, agents connect to any tool the job needs, build what is missing, and check the result, with no prebuilt connectors required. That matters because the real friction in delegating work is rarely the initial request — it is the tool access, the account sign-ups, the failed steps, and the loose ends that a person would otherwise have to chase. Solid is designed so that users describe a job in plain language and receive finished work they can review, ready to use or share. The first autonomy area is self-sufficiency. Solid's agents choose the tools and handle the setup, including for software you have never used, on the stated principle that if a person can use it, they can too. They operate their own devices, which the site lists as Windows and macOS computers, Linux servers, iPhones, and Android phones. They maintain their own accounts, such as Google and Apple accounts, and they can sign up for and pay for services within the budget and approval rules you define. Because they do not need a prebuilt connector, you are not limited to a connector list: agents can connect through an API, build a missing integration, or operate a website, desktop application, or phone app directly. This means a job can proceed even when the right tool was never officially integrated. Two further autonomy areas cover failure and learning. Self-healing: if a tool fails or their setup breaks, agents can investigate, make a repair, and check that the job runs again. When they need help, they explain what is blocking progress rather than silently stalling, and users can also talk to a real person on the Solid team. Self-improving: agents keep the fixes that worked and learn from team corrections, and those lessons change how they use tools and approach future jobs. Solid states that agents remember your team's instructions and feedback across jobs, so when you correct how something is done, they keep that lesson and apply it the next time it is relevant. The practical effect is that explanations do not have to be repeated every time, and the agent's approach to shared context improves over time. The fourth autonomy area is self-scaling. Agents can bring in help and manage it: they create more Solid agents or bring in agents such as Codex and Claude Code, divide the work across any tools the job needs, coordinate the team, and return one checked result. For users this means a large job does not have to be decomposed and managed by hand. The agent acts as the coordinator, parceling out portions of the work and collecting the outcomes into a single verified deliverable that a person can review. In one of the site's illustrations, a Solid agent gathers results from other agents working across business tools and hands one checked result to a person, which is the intended pattern for larger workloads. Overall, Solid works as a meta-agent: it can see and manage its own workspace within the access you give it, so you can ask what is running, why it is needed, or how much a job cost at any time, and it can break down the AI usage, machines, and purchases used for the job. The workflow begins with a plain-language description of the job; for example, asking for a dashboard update triggers a sequence in which the agent connects to Gmail and HubSpot, researches on LinkedIn, builds the dashboard, deploys it, and verifies the data. Agents keep working after you close your laptop, then message you with the result, ready to use or share, and they will ask when they need a decision. Boundaries are set by you: you choose what agents can access and which actions require approval, so you might let them research and draft while requiring approval before sending a message, buying a service, or deploying a change. The outcomes described are about delegation with control. Users can hand over work that they lack the time or expertise to do, while retaining oversight through access controls, budgets, approval rules, and the ability to review work along the way. Because agents check their own results and revise from feedback, and because they explain what is blocking progress when they cannot proceed, the user is not required to monitor every step. Because they remember team instructions, the cost of briefing does not have to be paid again for each job. And because the whole monthly payment becomes one balance for AI usage, machines, and purchases, there is no separate platform fee layered on top, which keeps cost accountability inside the budget and approval rules the user defines. Solid publishes a set of example workflows. In sales demos, agents turn customer meeting notes into a tested demo and return the hosted link in your conversation, following steps from reading the notes and mapping the buyer's workflow to building with sample data, hosting and testing the app, and returning the link and test results. In LinkedIn lead generation, agents research accounts using your ideal customer profile, show the evidence, draft outreach for approval, follow up on approved messages, book qualified meetings, and update the CRM. In AI product evaluation, agents build eval scenarios and success criteria, run them after each release or change, simulate users completing real tasks, judge outcomes against expected behavior, and report what passed, failed, and why. In production bug resolution, agents investigate the alert, reproduce the issue, assess impact, write and test a fix, open a pull request for engineer approval, and verify recovery after deployment. In customer support, agents read a stalled ticket, gather the full customer history, find the cause across systems, apply the fix within your policies, and confirm and record the resolution. A customer service resolution workflow is also listed among the finished-job examples. Solid says builders and operators at companies including Revolut, ElevenLabs, EY, British Airways, Stanford, Berkeley, NVIDIA, MIT, Swiggy, NYU, and the Government Digital Service use it, and the product is aimed at individuals and teams with complex, long-running work. Pricing has three monthly subscriptions: Starter at $40 per month for getting started with a focused task, a simple app, or a small workflow; Pro at $160 per month for regular work, active app building, and more room to test and iterate; and Max at $640 per month for heavier workloads, larger apps, and several projects running at once. The full monthly payment becomes one balance for AI usage, machines, and purchases your agents make, with no extra platform fee, and a trial starts with $20 on Solid. For developers, the Solid API lets you deploy always-on agents inside your product or as the product, keeping context, working across approved systems, building missing pieces, and carrying long-running jobs under the controls you set. For enterprises, you can set access, budgets, policies, and approvals across your workspace and run on Solid Cloud, in your own VPC, or on-premises, with availability depending on your setup. Taken together, Solid's proposition is that agents should own a job end to end rather than assist inside a single conversation. By giving agents their own machines, accounts, and budgets — and by adding self-healing, self-improvement, and the ability to scale with additional agents — Solid targets work that is too long-running and too multi-step for a chat-based assistant. The control layer is what makes the delegation practical: you set budgets, access, policies, and approvals, agents report what they used and what they need, and you get finished work delivered back to you.

CodeSpotlight is a plugin for IntelliJ IDEA that turns ordinary code selection into a customizable animated visual focus. Rather than leaving selected code with a flat highlight, the plugin surrounds the selection with glowing borders, moving lights, and smooth visual effects so that the code currently being discussed becomes the obvious center of attention on screen. It is designed for people who show code to an audience — coding YouTubers, tutors, instructors, course creators, livestreamers, and technical presenters — and for anyone who wants selected code to be impossible to miss. Its purpose is straightforward: select code, focus attention, and customize the look, all without leaving the editor or changing a single line of the source file. Presenting code is harder than it looks. A cursor alone is easy to lose on a busy screen, and the default selection highlight in a code editor is subtle by design — it is meant to support editing, not to survive a compressed video, a projector, or a livestream where viewers may be watching on a phone. As a result, viewers of technical tutorials, live coding sessions, screen recordings, and code demonstrations can struggle to follow which lines are being explained at any given moment. CodeSpotlight addresses that visibility gap. It keeps the developer's normal workflow intact while adding a configurable visual focus layer around the current selection, so the audience's eye is guided to the right place. According to the plugin's own overview, the goal is to help selected code remain visually easy to follow during presentations, technical tutorials, screen recordings, live coding, code demonstrations, reviews, and everyday development workflows. At its core, CodeSpotlight visually highlights selected code, including multi-line selections, which matters because real explanations often span a whole method, a loop, or a block rather than a single word. Crucially, the plugin preserves IntelliJ IDEA's normal selection and editing behavior: the text still behaves like ordinary IntelliJ IDEA code, and the plugin simply adds a configurable visual focus layer around the current selection. The animated effects are drawn as an overlay, so there is no need to modify source code, insert markers, or maintain a separate presentation copy of a file. For developers who present from their real project, that means the code they demonstrate is the same code they ship. CodeSpotlight offers multiple animation styles so the effect can match the tone and pace of a session. The free tier includes Traveling Border, Pulse, Breathing Glow, and Static Glow. CodeSpotlight Pro expands this with Travel + Pulse, Energy Sweep, Aurora, and Orbit, alongside everything available in the free tier. Traveling Border sends movement around the edge of the selection, which naturally draws the eye without covering the code itself. Pulse and Breathing Glow create rhythmic brightness changes that keep attention on a region while it is being explained. Static Glow provides a steady, non-moving highlight for situations where motion would be distracting. The additional Pro modes — Energy Sweep, Aurora, and Orbit — give presenters more distinctive looks to choose from when they want a signature style. Appearance controls let developers tune how the focus layer looks. The free tier ships with built-in color presets, and Pro adds custom primary and secondary colors for full control over the palette. Border thickness, glow radius, corner radius, and glow intensity can all be adjusted, so the effect can range from a thin outline to a soft, wide halo that frames the selection without obscuring it. These parameters matter because readability changes with context: a bright glow that works on a large monitor may need to be dialed down for a compressed recording, while a subtle outline may need to be strengthened for a projector. Because every control lives in the IDE settings, presenters can quickly match the effect to their recording setup, their editor theme, and their audience. Animation behavior is configurable as well. Users can choose the animation mode and speed, adjust moving light segments, and set the animation frames per second. Light trail controls add a trailing effect behind moving elements; the free tier covers a standard trail plus trail enablement, while Pro adds advanced trail length and intensity/fade controls. Moving light segments range from one in the free tier to one to four in Pro, which changes the density and feel of the motion — a single traveling light reads as a clean pointer, whereas several segments create a richer, more energetic look. The visual controls in the free tier include speed, glow intensity, border thickness, glow radius, corner radius, and animation FPS, and Pro includes everything from the free tier. To avoid re-tuning settings for every recording, CodeSpotlight supports saved presets: up to two in the free tier and unlimited presets with Pro. Presets make it practical to keep a distinct look for tutorials, another for livestreams, and another for client demos, and to switch between them rather than rebuilding the configuration each time. Two further Pro capabilities round out the package. Focus Mode, refined in version 1.0.1 with a darker selected-code surface and an unchanged surrounding editor, isolates attention on the current selection. Pro also includes the optional CodeSpotlight Dark editor color-scheme integration, so the surrounding editor can match the visual treatment. Configuration lives entirely inside the IDE. The workflow is: open Settings, go to Tools → Animated Selection (CodeSpotlight), enable animated selection, choose colors and animation mode, adjust the available visual parameters, then return to the editor and select code. Changes appear instantly, so there is no restart-and-check loop. The plugin's stated design principle is to stay out of the way — your code remains native IntelliJ IDEA code while the plugin adds a configurable visual focus layer around the current selection, and both appearance and animation settings are available directly inside IntelliJ IDEA. The plugin notes that everything can be customized from IntelliJ IDEA Settings with no code changes required. The plugin is explicitly aimed at situations where code is watched rather than just written. That includes technical presentations where a room needs to follow the active block, tutorials and course content where the explanation should track the highlighted lines, screen recordings where compression can wash out subtle selection highlights, live coding streams where viewers join mid-session, and code demonstrations and reviews where a reviewer wants to point at a specific region while discussing it. It also applies to everyday development workflows, since the same visual focus can make it easier for a developer to keep track of what they have selected in a large file, even when nobody else is watching. CodeSpotlight is compatible with IntelliJ IDEA, Android Studio, and 13 more IntelliJ-based products, and it is distributed through the JetBrains Marketplace. It is built for coding YouTubers, tutors, instructors, course creators, livestreamers, technical presenters, and developers who want to make their code impossible to miss. The plugin follows a free-plus-Pro model: animated selection highlighting, the four base animation modes, built-in color presets, one moving light segment, a standard light trail, core visual controls, up to two saved presets, and an optional CodeSpotlight Dark color-scheme integration are available without a paid plan. Some features require a paid subscription, and the Pro tier unlocks additional animation modes, custom primary and secondary colors, one to four moving light segments, advanced trail length and intensity/fade controls, Focus Mode, unlimited saved presets, and the included editor color scheme. Version 1.0.1 was released on 21 Sep 2026, and the plugin is published by the vendor CodeSpotlight. CodeSpotlight's value proposition is simple: make your selected code the visual focus. By combining animated highlighting, configurable appearance and animation controls, saved presets, and an optional Focus Mode inside IntelliJ IDEA, it makes code easier to follow for anyone watching — without altering the code itself. Select. Focus. Customize. Code.
Dub Program Marketplace is a destination where you can browse and apply to the best SaaS affiliate programs and start monetizing your audience today. According to the marketplace, it lets partners explore the variety of SaaS affiliate programs available and begin monetizing their traffic or audience immediately. The marketplace features world-class companies such as Wispr Flow, Framer, Granola, Superhuman, and CodeRabbit, among many others. Every program listing presents the partner company's logo and name, a short description of what the company does, the reward structure it offers, and a link to the company's website, so prospective affiliates can understand a program before deciding to apply. The marketplace is part of Dub, which is described as the modern link attribution platform for short links, conversion tracking, and affiliate programs. Affiliate programs are one of the most common ways for creators, publishers, and website owners to earn revenue from an audience, but discovering programs, comparing their reward structures, and knowing which companies actually run partner programs can be time-consuming. Dub Program Marketplace consolidates SaaS affiliate programs into a single, browsable destination. Rather than searching company by company, visitors can explore programs that are already organized into categories and curated sections. The marketplace is headlined as offering the best SaaS affiliate programs in 2026 and is aimed at anyone who wants to turn their traffic or audience into income through affiliate partnerships. By presenting each program alongside its reward details, the marketplace makes it easier to evaluate which opportunities are worth applying to. The core of the marketplace is a collection of program listings. Each listing shows the partner company's logo and name, a concise description of the product or service, the reward structure, and a link to the company's website, along with a short call to action such as "View" for the specific program. This consistent presentation means that a visitor can quickly scan multiple programs and understand the essential facts of each one. For example, a listing for Superhuman describes it as the AI productivity suite that gives you superpowers everywhere you work, and states its reward as 35% per sale for 1 year. A listing for beehiiv describes it as access to the best tools available in email, helping your newsletter scale and monetize like never before, with rewards of 50% per sale for 1 year, up to $15,000 per customer. This level of detail helps affiliates compare programs at a glance before applying. Programs in the marketplace are organized into categories to help visitors find opportunities that match their audience. The categories displayed include AI, Fitness, Marketing, FinTech, DevTools, Support, Design, Ecommerce, Consumer, and Education, and each one has a dedicated view with a "View all" link. Within categories, visitors can explore representative programs; for instance, the AI category features Viktor.com, FLORA, Runable, Marblism, and CodeRabbit, while the Design category features Framer, LottieFiles, Betterpic, CleanShot, and Hedra. In addition to categories, the marketplace highlights other sections such as Most popular and New, each with its own "View all" link, so visitors can discover both established and recently added programs. Sorting options are exposed through links such as sortBy popularity and sortBy recency, allowing visitors to browse programs ordered by popularity or by how recently they were added. Reward structures in the marketplace vary widely, and each program's listing makes the terms explicit. Superhuman offers 35% per sale for 1 year, beehiiv offers 50% per sale for 1 year up to $15,000 per customer, Granola offers $20 per lead, Polymarket offers $10 when a referral makes their first deposit plus 20% revshare on their Perps trading fees, Framer offers 50% per sale for 1 year, and Runable offers 100% per sale for 4 months. Wispr Flow offers 25% per sale for 1 year and Viktor.com offers 15% per sale for 1 year. Other examples include CodeRabbit at $30 per lead, Marblism at 30% per sale for the customer's lifetime, and Weav at 30% per sale for 2 years, alongside models such as 15% per sale for 1 year for Privy and 25% per sale for the customer's lifetime for Superlist. Because these terms are shown directly on each listing, visitors can compare commission percentages, durations, and payout types across programs. Using the marketplace follows a straightforward flow. A visitor arrives at the marketplace, browses programs either through the curated sections or the category views, and reviews each listing's description, reward structure, and linked website. From there, the visitor can move to a program's dedicated page to apply. The marketplace is part of Dub, the modern link attribution platform for short links, conversion tracking, and affiliate programs, and Dub itself also appears as a program in the Marketing category with rewards of 30% per sale for 1 year. Dub's own description notes that it provides short links, conversion tracking, and affiliate program infrastructure, which is the same domain the marketplace serves for companies and partners. For creators, publishers, and marketers, the marketplace's main benefit is the ability to find and apply to SaaS affiliate programs from a single place and start monetizing their audience. Because programs are grouped by category and by popularity and recency, visitors can more easily find opportunities aligned with the topics their audience already cares about. Because reward terms are shown on each listing, visitors can make a more informed decision about which programs to pursue. Featured companies include names such as Wispr Flow, Framer, Granola, Superhuman, and CodeRabbit, which the marketplace presents as world-class companies, giving participants access to established brands to partner with. Concrete scenarios emerge from the categories and examples in the marketplace. A creator who runs an email newsletter and wants to earn from email-related tools can explore the email and marketing programs, such as beehiiv, which is built to help newsletters scale and monetize. A designer or design-focused content creator can browse the Design category and consider programs like Framer, a no-code website builder, or LottieFiles, CleanShot, and Hedra. A developer or technical writer can look at the DevTools category, which includes Fillout, Replo, Knock, Anything, and Zernio. Someone writing about artificial intelligence can explore the AI category, which lists Viktor.com, FLORA, Runable, Marblism, and CodeRabbit. People interested in finance and trading can review the FinTech category, which features TradeZella, Kick, Pinnacle Odds Dropper, Carry, and Papermark, and those covering health and fitness can browse the Fitness category, which includes Superpower, pliability, Rythm Health, Hundred Health, and MoldCo. In each case, the workflow is the same: browse the relevant category, review the reward terms on the listing, and apply to the program. The marketplace is aimed at affiliates, partners, creators, publishers, and anyone with traffic or an audience to monetize, since it invites visitors to "start monetizing your traffic/audience today." It serves both sides of an affiliate relationship: companies that want partners and individuals who want to earn from promoting SaaS products. Programs span many industries including AI, Fitness, Marketing, FinTech, DevTools, Support, Design, Ecommerce, Consumer, and Education. The marketplace states that it features world-class companies like Wispr Flow, Framer, Granola, Superhuman, and CodeRabbit, and more. The marketplace pages offer Log in and Sign Up actions for users who want to participate. No specific pricing, tech stack details, or integrations are stated in the provided content for the marketplace itself. Overall, Dub Program Marketplace is a central place to browse and apply to SaaS affiliate programs, organized into categories and curated sections such as Most popular and New, with each listing presenting the partner company's description, reward structure, and website. For anyone looking to turn their traffic or audience into income through affiliate partnerships, it offers a straightforward way to discover, compare, and apply to programs from a range of companies.
Speechka is a real-time voice translation app that lets you speak naturally in one language while other people hear you in theirs. Instead of captions or transcripts, Speechka listens to what you say, translates it, and delivers the result as spoken words in your own voice, so your identity and speaking style carry across every language. The product is built for live conversations of all kinds — online meetings, calls, livestreams, conferences, keynotes, workshops, and classrooms — and it is available as a desktop app for macOS and Windows, as well as directly in the browser. Speechka supports translation both ways between 44 languages, and its stated purpose is to remove language as an obstacle in the middle of a conversation. Most multilingual communication today relies on subtitles, captions, or transcripts. Those tools force listeners to read instead of listen, shift attention away from the speaker, and break the natural rhythm of a conversation. Speechka was built specifically as an alternative to that approach: as the site puts it, it is built for conversations, not subtitles. By turning translated text back into natural speech that plays in real time, Speechka aims to keep multilingual conversations fluid rather than turning them into delayed, disjointed voice messages. The outcome the product is designed to deliver is simple: no subtitles to follow and no repeating yourself, just conversations that keep moving even when the people involved do not share a language. Speechka's core capability is real-time voice translation. You speak in your own language, and the people you are talking to hear you in theirs. The translation is described as low-latency and is designed for meetings, calls, conferences, and live conversations. Alongside raw speed, Speechka emphasizes flow: it listens, translates, and delivers every sentence in sequence, which is meant to keep conversations smooth, natural, and easy to follow. The second core capability is the Personal voice. Rather than substituting a generic AI narrator, Speechka preserves your own voice across languages, including your speaking style and your natural accent. To set this up, you record a short sample of your voice — the app records up to 10 seconds of your voice — and that sample is then used for your translations. You can listen to the recording, re-record it if needed, and replace or remove your recorded voice at any time. Speechka's translation engine is described as context-aware. Instead of processing isolated words, it works with complete ideas, recognizing context, sentence structure, tone, and intent so that translated speech sounds natural rather than robotic or fragmented. This matters most in live settings, where literal word-for-word output quickly becomes hard to follow. Speechka also handles something subtler: timing. It automatically manages pauses, sentence boundaries, and playback timing so that translated speech follows the rhythm of a real conversation instead of arriving in awkward chunks. Related to this is ordered playback, where every translated sentence is delivered in the correct order. That ordering keeps multilingual conversations clear even when more than one person is speaking, so listeners always hear statements in the sequence in which they were actually made. Speechka offers two distinct ways to use its translation, described in its FAQ. Listen Mode plays the translated speech only for you, through your headphones or speakers. Broadcast Mode sends the translated speech directly to the other participants through your microphone, so they hear the translation while you continue speaking naturally. There are also two quality modes to choose from. Faster is optimized for the lowest possible latency and is positioned as ideal for fast-paced conversations. High quality prioritizes the most natural voice generation and translation quality, and is recommended for presentations, meetings, podcasts, and professional communication. Language coverage spans 44 languages, including English, Spanish, French, German, Italian, Portuguese, Chinese, Japanese, Korean, Arabic, Hindi, Russian, Ukrainian, Bengali, Bulgarian, Croatian, Czech, Danish, Dutch, Finnish, Georgian, Greek, Gujarati, Hebrew, Hungarian, Indonesian, Kannada, Malay, Malayalam, Marathi, Norwegian, Punjabi, Polish, Romanian, Slovak, Swedish, Tagalog, Tamil, Telugu, Thai, and Turkish. The overall workflow is deliberately short. You choose the languages you want to translate between — the site notes that you can translate both ways between 44 languages — then create your personal voice by recording a short sample, and then start translating. From there, Speechka listens to your speech, translates it in real time, and plays the result back in your voice, either privately to you in Listen Mode or out to the call in Broadcast Mode. Speechka is designed to integrate with the communication tools people already use rather than asking them to switch platforms. Because it works with virtually any application that accepts microphone input, the same workflow carries across video conferencing software, chat and voice platforms, browser-based meetings, livestreaming software, and many other communication platforms. It ships as a desktop app for macOS and Windows, and the same core experience can be tried directly in the browser, where the demo provides your first 5 free minutes before prompting you to download the app and complete your account. The benefits Speechka describes all come back to removing friction from live multilingual conversation. People who speak different languages can participate in the same meeting or call without one side reading captions or waiting for a delayed voice message. Because translations arrive in your own voice, listeners hear the person they are talking to rather than a generic synthetic narrator, which preserves your identity and speaking style across languages. In online meetings, the promise is that daily stand-ups, client calls, and remote workshops keep moving without anyone slowing down to repeat themselves. For conferences, keynotes, and workshops, a single presentation can reach a multilingual audience without interrupting the flow of the presentation. For livestreamers, it means going live for a global audience in your own language without creating separate streams, subtitles, or dubbed recordings. The choice between Faster and High quality modes lets users trade a little latency for more natural voice output when a presentation or a professional conversation calls for it. Speechka's own materials name a set of concrete scenarios. Online meetings are the first and most obvious: daily stand-ups, client calls, and remote workshops where participants speak different languages. Conferences, keynotes, workshops, classrooms, and international events are called out for presenting in your own language while the translated voice is delivered to a multilingual audience in real time. Livestreaming is another: streaming on Twitch, YouTube, Kick, TikTok, or your own platform while Speechka translates your voice live for viewers, so every viewer hears the same content naturally translated into their language and spoken in your own voice. The product is also positioned for professional communication such as sales calls, podcasts, and customer calls — the contact form even invites people to describe how Speechka should fit into their meetings, streams, conferences, or customer calls. Finally, the browser experience is a way to test the entire flow — choosing languages, creating a voice, and starting translation — before committing to the desktop app. Speechka is aimed at anyone who communicates across languages regularly: people running meetings, presenting at conferences, hosting livestreams, working in sales, or taking customer calls with international participants. On the integration side, it is shown working alongside Zoom, Google Meet, Microsoft Teams, Slack, Discord, Webex, and OBS, and it is described as compatible with virtually any application that accepts microphone input, including browser-based meetings and livestreaming software. Platform support covers a desktop app for macOS and Windows, plus a browser experience for free trial translation. Pricing starts with a free trial: 7 days free with 10 credits, with no feature limitations, enough to explore Speechka with real meetings, calls, presentations, or livestreams. Beyond the trial, a Pro subscription costs $19.99 per month and includes 180 credits every month. Additional credits can be purchased at any time without changing the subscription: 60 credits for $9.99, 180 credits for $24.99, or 360 credits for $39.99. Speechka's value proposition is straightforward: speak naturally in your own language and be heard in someone else's — in your own voice, in real time, in the tools you already use. By replacing subtitles and delayed transcripts with natural translated speech, keeping your Personal voice, handling context and timing, and working across 44 languages and virtually any app that accepts a microphone, Speechka is designed to make language a detail of the conversation rather than a barrier to it.
ToneBird is a socially fluent AI reply assistant for Mac and Windows that helps you answer messages without getting stuck on words. It understands your relationships, what you have already said, and where you left off, then drafts the next reply in your voice directly inside Gmail, Slack, WhatsApp, iMessage, Discord, WeChat, Lark, Google Chat, X, Reddit, LinkedIn, Instagram and other apps you already type in. Instead of leaving the conversation, building a giant prompt, explaining the backstory and bringing the output back, ToneBird works beside the reply box. You open a reply, choose the wording that fits, tweak it if needed, and insert it into the conversation before reviewing and sending it yourself. Replying well sounds simple until context is involved. A client asks for the price you agreed on weeks ago, your manager asks for an update on something that already slipped once, or a customer pushes back on a renewal increase you have discussed before. A good answer depends on the relationship, the history and the commitments, and the apps people type in rarely keep that context available at the moment of writing. Generic AI assistants can produce fluent text, but they start from a blank page, so the person writing has to re-explain who they are talking to and what happened previously. ToneBird is built on the idea that the right reply starts with the context, and that the context already lives in your conversations and your files. Relationship memory is the core of the product. ToneBird uses your earlier conversations when drafting a reply, including the date you promised to confirm or the request a person made after a deadline slipped. It also pulls in facts from your files: when a client asks for the agreed price, ToneBird can find it in your connected proposal and include it in the draft. The interface shows a "Knowledge Recalled" panel, so you can see what the assistant remembered for that specific reply, such as a checkpoint that was requested, a scope change from last quarter, or a previously reported issue. You retain control over what is kept: facts and writing preferences learned from the conversation are surfaced for review, and you choose what to save. ToneBird also adapts wording to the person you are replying to. A client waiting on a deadline needs a different reply from a teammate checking in, and the assistant uses your past conversations with each person to adjust the phrasing. For any message, ToneBird can produce several options so you can compare three replies, then tweak the one you want before inserting it. Tweak controls include More Precise, Warmer and Add Humor, and there are context switches for Internal or external replies plus sliders for Directness, Formality and Warmth. Saved preferences such as "keep replies concise" carry into later conversations, so you skip the introduction and start from your own style. ToneBird is designed to follow you across apps and languages rather than pulling you into another tool. It works beside readable reply fields in apps such as Gmail, Slack, WhatsApp, iMessage, Discord, WeChat, Lark and X. When a message arrives in another language, ToneBird can draft the reply and show a translation, as in the example where a customer writes in Spanish and the assistant produces a Spanish answer with an English translation underneath. Beyond replying, ToneBird turns the conversation into follow-up work: when you and another person agree on a time, it prepares the event in Apple Calendar or Google Calendar from your chat, and a follow-up list gathers promised quotes, unanswered questions and dates to confirm in one place, marked by the app they came from. ToneBird also lists English, Español, 中文 and 日本語 among its available languages. The overall workflow is deliberately short. You click the orb, or press Option twice on Mac or Ctrl twice on Windows, while you are in a reply field. ToneBird reads the thread, recalls relevant context from your relationships and files, and shows suggestions; you click the arrows or use the left and right arrow keys to move between replies, tweak the wording, and then insert it into the reply box. Inserting is not sending. ToneBird does not send messages for you: the draft goes into the reply box, and you review it and use the app's own send button, so the final decision always stays with you. The benefits follow from that approach. You do not have to be stuck on words again, and you do not have to postpone a reply because you cannot face reconstructing the context. Promises, prices and dates that would otherwise require digging through old threads or documents are brought forward automatically, which reduces the risk of contradicting yourself or repeating an issue that was already raised. Because the assistant keeps your voice intact rather than making every reply sound generically "better", the person on the other side of the conversation experiences a consistent version of you, whether they are a customer, a manager or a teammate. Follow-ups that would normally be forgotten become visible tasks, and scheduling happens from the conversation itself instead of in a separate calendar app. Concrete scenarios show how this plays out. In Slack, a manager asks for a launch plan by Friday after a previous slip; ToneBird drafts a reply that commits to a core plan by Friday with a checkpoint later that day. In WhatsApp, a customer says a renewal increase is hard to approve; ToneBird recalls that the scope changed last quarter and drafts a reply that offers to work through the renewal over coffee near the customer's office, with proposed times. In Gmail, a customer writes in Spanish about a repeated export problem; ToneBird drafts a Spanish reply apologising and committing to check workspace permissions and send findings before 4 PM, with an English translation. When the customer later confirms Thursday at 4, ToneBird prepares a 30-minute proposal review event that can be added to Apple Calendar or Google Calendar, and the resulting task list reminds you to send a revised quote or confirm a delivery date. ToneBird is for people whose work happens in email and chat apps, including customer-facing and sales conversations, client renewals, manager and teammate updates, and anyone who needs to reply across several apps and sometimes several languages in the same day. It runs as a downloadable app for Mac and Windows, chosen on the download page, and it works beside readable reply fields in supported apps, though support depends on the app and some fields may not be readable. Your tone profile, person cards, learned corrections and usage counts live on your device, and you can export or delete them any time in Settings. On data handling, the model provider receives the context and instructions needed for your reply: with a managed model ToneBird forwards the request, and with your own model key writing requests go directly to that provider. Pricing starts free, and scales through Standard at $9.90 per month with 100 uses every day and 100 contacts, Pro at $39.90 per month with 1,000 uses every day and 1,000 contacts, and Enterprise with custom pricing for your team; billing is monthly or annual, with about 20 percent saved annually. ToneBird's primary value is that it turns the context you already have into the reply you need next. It remembers your relationships, retrieves relevant facts from past conversations and connected documents, adapts the wording to the person and keeps your voice intact, all inside the apps where the conversation is already happening. You pick a suggestion, tweak it, insert it, and send it yourself. Free to start and with room to grow, ToneBird is aimed at anyone who wants to stop being stuck on words without handing over control of what gets sent.
RankControl is an AI SEO platform that produces content designed to be recommended by AI search engines such as ChatGPT, Claude, Perplexity, Gemini and Grok, while also ranking on Google. The articles it creates publish as native posts on the customer's own domain, not on a subdomain, so the site keeps full SEO equity and earns links from high-DR sites. It combines content creation, AI visibility tracking, backlink earning and analytics in a single platform with one flat plan. The goal, as the site puts it, is to be the answer in AI search and the result on Google. Buyers now ask AI before they buy, and most brands are not even in the conversation. RankControl frames this as a gap: your competitors show up in AI answers and on Google, while many brands remain invisible to AI search even when they already rank on Google, because AI systems use different signals such as entity authority, citation patterns and content depth. The platform describes a shift from ten blue links, where ranking number one won the click, to AI answers that replace links, where citations replace rankings. Agencies, the site notes, burn months and thousands of dollars, cited at $5K+ per month, for results that arrive slowly. Discovery and setup are handled by Radar and the tracking layer. RankControl scans your tone, products and competitors so everything it produces reads like your brand, then tracks how ChatGPT, Perplexity, Claude, Gemini, Grok and Google AI Mode answer your market's questions. Radar surfaces every question in your market where AI names someone else, described on the site as answers where a competitor was named instead of you. It tracks up to ten competitors and ranks topics by opportunity, so you can see not only that you are missing from AI answers but why, and which gaps are worth closing first. The brand-learning component, Sounds Like You, learns voice, products and competitors from your site so content matches your brand from day one. Content creation is handled by Forge, which writes content AI trusts: 1,500 to 4,000+ word guides that are brand-matched and citation-optimized, built to answer the questions Radar found. RankControl supports 26 content formats, and sample articles shown on the site span explainers, listicles and statistics posts across travel, software, tech and coffee. Drafts go through an approval workflow where you review, comment and approve with one click; auto-publish is off by default. Articles then go live on your site as native posts through a five-minute plugin setup with no code changes. Content Refresh flags pages when rankings or citations slip and rewrites them on your approval. Visibility monitoring is covered by Sentinel, which runs weekly checks on every tracked query and competitor and sends a notification the moment something changes. Citation Signals tells you when an AI engine cites you or a competitor, turning every mention into something you can act on, and lets you search citations by platform, query or competitor in one click. Brand Perception rates every AI mention as positive, neutral or negative with the wording behind it. Citation Sources shows who the engines cite for your queries, whether that is you, your competitors, Reddit, YouTube or editorial sites. The Google AI Overviews view shows when Google's AI answer appears for your keywords and whether your page is one of its sources, while the AI Crawlers view shows which AI bots read which pages and alerts you the day one of them gets locked out. Analytics ties it together by showing which AI assistant sent each visitor, with traffic, crawls and rankings in one view. Growth is built around backlinks. RankControl drafts outreach emails with AI and supports link exchanges, with managed backlinks available as an add-on at $350 per month. Every new backlink is tracked as it lands, and rankings and citations are reported per published page, so you can see which articles are producing results. The platform also includes Link Control for tracking backlinks and managing outreach opportunities in one place, and Competitor Recon for tracking competitor citations across all AI models to find the gaps. As AI models begin recommending you, you can see exactly which answers name you and which models send the traffic, meaning the right people arrive already convinced. The methodology is a six-step playbook that runs from setup to traffic. In steps one and two you lock in your brand and spot the gaps; in steps three and four you draft, approve and publish on your own domain; in steps five and six you earn backlinks and compound your authority. Seven AI agents plan, build and publish the work, and the Agent Pipeline lets you watch every move with a full audit trail. Because AI models have memory, the more authoritative content you publish, the more they trust your brand. The site illustrates this compounding effect as first citations appearing around month one, trust compounding threefold by month three, and default answer status by month six. The stated outcomes are traffic from two channels at once. The homepage reports 10K+ pages published, 5K+ AI and Google citations tracked, 66 search platforms monitored, and an average time to go live of five minutes, along with a linked case study citing +375% traffic in 90 days. The comparison table positions RankControl at $400 per month all-inclusive against agencies at $5K+ per month and competitors at $800 to $2,200 per month, with time to results of 30 to 90 days, a full review workflow, every agent action logged, content hosted on your own domain, Google AI Overviews shown per keyword, and MCP, CLI and API access included. It positions the platform as saving $55K in year one versus agency retainers. Typical scenarios follow the product's own workflow. A marketing team starts a free trial, connects its CMS with the five-minute plugin, and lets RankControl scan the site to learn voice, products and competitors. Radar then lists market questions where competitors are named instead of the brand, and Forge drafts guides targeting those questions. The team reviews and approves drafts, the articles publish as native posts, and Sentinel plus Citation Signals notify them when an AI engine starts citing them. AI-drafted outreach emails go out to earn backlinks, and analytics show which AI assistant sent each visitor. Teams can also run the whole thing from their own AI agent through MCP, the CLI or the API. RankControl is positioned for marketing and SEO teams, and for brands that want AI visibility without paying agency retainers; the comparison repeatedly contrasts it with agencies and with competitors that are software only. It offers a 7-day free trial, one flat plan at $400 per month all-inclusive, an optional dedicated strategist at $1,500 per month, and managed backlinks at $350 per month. Integrations include Cloudflare, Google Search Console, Bing Webmaster, Gmail, Postiz, Buffer, Zapier, n8n, Make and Google Analytics, plus CMS publishing into WordPress, Shopify, Webflow, Ghost, Framer, Wix, Notion and headless Next.js sites via the Content API. MCP, CLI and API access is included, with 80+ tools and one command to connect. In short, RankControl is built on the premise that citations compound and competitors cannot easily catch up. Rather than stopping at telling you where you are mentioned, it runs the full lifecycle: create content that AI and Google recommend, publish it on your own domain, track visibility across ChatGPT, Perplexity, Claude, Gemini, Grok and Google AI Mode, earn backlinks, and measure what comes back. Being the answer, not just a ranking, is the value proposition it sells.
GBrain is an AI memory and workspace product for teams that use several AI tools at once. The website describes it as one workspace the whole team prompts together, with one memory synced to every AI they use. The product is made up of four parts — Memory, Tools, Skills and Workspace — and the team is expected to use all four at once. GBrain is sold per workspace rather than per person, so the whole team can be invited in and share the same conversation and the same memory. It is priced at $99 for the first month and then $199 a month, billed monthly, and it can be stopped any time from the workspace's own billing page. The problem GBrain addresses is that AI tools tend to keep separate memories and separate configuration. The Product Hunt description explains the situation directly: GBrain gives you a memory and a set of connected accounts that every AI can reach. Without that, writing a note in one tool has no effect on another, and connecting an account such as Gmail has to be repeated for each tool, often with a key placed in a config file. GBrain's answer is to hold the memory and the connections in one place so that Claude Code, ChatGPT, Cursor and other AIs can all reach the same context, and so that a team does not have to re-establish the same setup for every assistant it uses. Memory is described as what the workspace knows about the team and the work, kept in files the team owns. The memory is a folder of markdown files that you can read, correct and take with you. Because the files are plain markdown, the team can inspect exactly what the workspace has learned rather than trusting an opaque store, and can correct anything that looks wrong. The company states that leaving takes the notes with you: everything the workspace has learned is plain markdown in a folder you can copy, and the open source parts are free to run yourself. That makes the memory both portable and auditable, which matters for a shared team asset that accumulates over time and is meant to outlive any single tool the team happens to be using. Tools are the accounts the workspace reaches, along with what each AI may do with them. The site says email, calendar and the web are connected once, and the Product Hunt description gives the concrete example that connecting Gmail once lets Cursor search it with no key in a config file. Because the connections live in the workspace rather than in each individual tool's configuration, a new AI does not have to be given its own credentials for services the team already connected. The permission model is part of the Tools concept: the workspace defines what each AI may do with the accounts it can reach, so access is decided once in the workspace rather than separately inside every assistant. Skills are the jobs the workspace knows how to run, on demand or on a schedule. The launch offer lists skills already installed, meaning a new workspace arrives with jobs ready to run rather than requiring the team to build them from scratch. Scheduled work is called out separately in the offer as work that runs while you sleep. This turns the memory and the connected tools into something that acts — a skill can use what the workspace knows and the accounts it can reach to carry out a job at a chosen time, without someone having to trigger it manually. An on-demand skill, by contrast, is run when the team asks for it. Workspace is the room a team works in, and the server underneath it. This is where the multiplayer aspect lives: the whole team is in one workspace, sharing the same conversation and the same memory, and adding the rest of the team costs nothing extra. The workspace also handles model choice — models from Anthropic and OpenAI can be switched any time — and the company states that it can run on your own inference or ours. Because the workspace sits on the company's servers, there is nothing to install: the site says you sign in and the workspace is running in about two minutes. The overall approach is to keep one shared memory and one set of connected accounts, then let every AI the team uses read from and write to that same store. Memory is held as a folder of markdown files; Tools hold the accounts and the permissions over them; Skills hold the jobs that can be run on demand or on a schedule; and the Workspace is the shared room and the server that ties it together. The company supports this with onboarding and support direct from the team, and the offer includes $100 of usage credit a month for AI and metered tools such as web search and page crawling. Practically, the benefits stated on the page are about teamwork, cost and portability. A single price covers the workspace and everyone invited into it, so adding the rest of the team costs nothing extra and no one works in a separate silo. The monthly $100 usage credit pays for the AI models the workspace thinks with and for metered tools such as web search and page crawling, and the workspace tells you before you run out rather than after. Because the memory is a markdown folder, knowledge built up in the workspace can be copied and taken along, and the open source parts can be run yourself. Several concrete workflows are described in the material. Writing a note in Claude Code means ChatGPT knows it, because both reach the same memory. Connecting Gmail once lets Cursor search it without a key in a config file. Scheduled skills run work while the team sleeps. An email, calendar and web connection made once serves every AI in the workspace. A team that signs in gets a running workspace in about two minutes, with onboarding and support direct from the company, and everyone can prompt together in the same room against the same memory while switching between Anthropic and OpenAI models as needed. GBrain is aimed at teams that share AI work rather than individuals working alone. The Product Hunt launch price is $99 for the first month and then $199 a month, billed monthly, and it can be stopped any time from the workspace's billing page. The price is per workspace, not per person, and covers everyone invited into it; it includes $100 of usage credit each month, with more purchasable from the billing page. The launch link stops selling that price on September 29, and a workspace started before then keeps the price it started on. The takeaway is straightforward: GBrain gives a team one place to keep what it knows and one place to connect the accounts it works with, then syncs both to every AI the team uses. The memory stays in markdown files the team owns and can take with it, models can be swapped between Anthropic and OpenAI, skills can run on demand or on a schedule, and the whole team shares one workspace at one price.
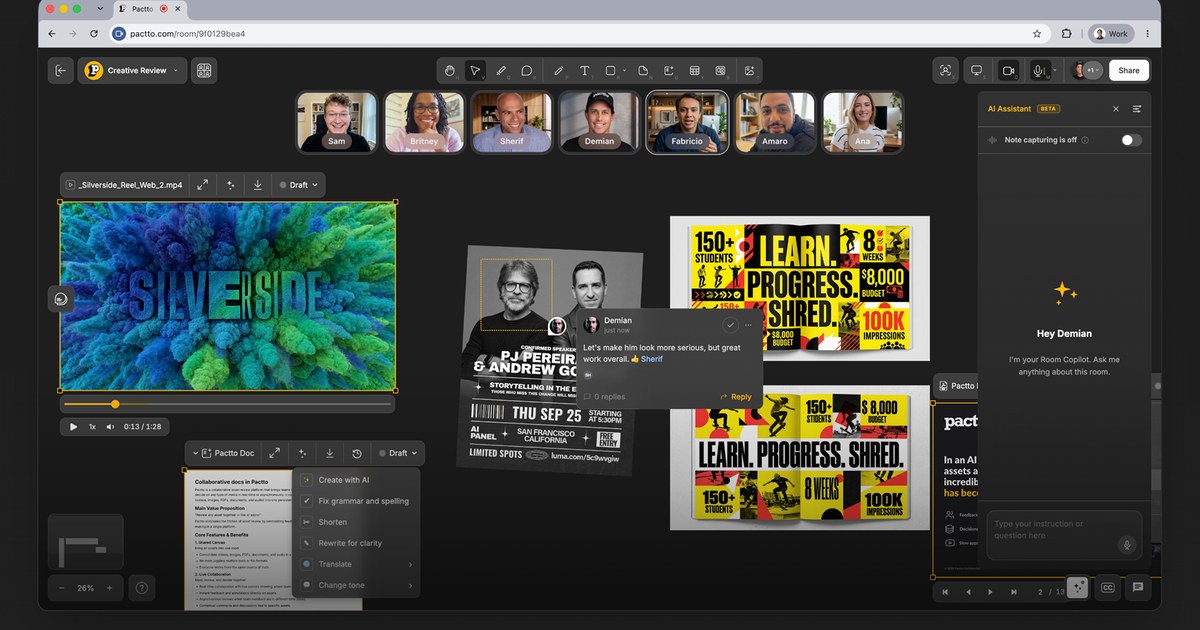
Pactto is an AI-native platform for creative teams to present their work at studio quality, review assets with the assistance of AI agents that understand creative intent and capture every note, and then turn that feedback into changes, live. Each Pactto room is a persistent workspace for a project, campaign, client, or team where assets, people, discussions, decisions, and AI context live together. It is built so that a whole team sees the same work, hears the same conversation, and makes decisions together inside one shared context instead of scattering them across separate tools. The problem Pactto sets out to solve is described plainly on the site: with AI, assets are created faster than ever, but the review process has not caught up. Feedback is scattered everywhere, decisions get lost after sessions, approval cycles take forever, and versioning has reached insanity, so humans and traditional review processes become the bottleneck. Video calls and async review tools each only cover part of the job. Unlike Zoom or Google Meet, where context disappears when the call ends, Pactto rooms remember everything — every conversation, every decision, every piece of feedback — so context does not disappear, it compounds. At the center of the product are persistent creative rooms. Each room is a smart canvas that supports videos, images, PDFs, SVGs, audio, and multi-screen sharing, and it is assisted by an AI agent that is always available with full context. Rooms persist for every project so teams can meet, collaborate, present work at the same time, and access the room memory at any time. Because the canvas holds every asset, board, and decision, work is reviewed at full quality rather than through a compressed screen share, and multiple people can share screens simultaneously — for example an editor in Premiere on one side and a designer in Figma on the other, with the director watching and guiding both. Live Editing is the feature the company describes as unique: say it and watch it change, right in front of everyone. The AI assistant is always listening, building context, suggesting actions, and taking action. A director can say that the pacing feels slow or that the color on the hero shot is too cool; the assistant captures that as a structured comment with full context and then suggests a warmer grade that can be applied in one click so the image updates on the canvas while everyone watches. The same assistant can generate three alternative hero shots, create a doc with all the action items from a session, or execute commands such as creating a doc with all tasks for a specific person, or moving all images to the right and all sticky notes to the left. Teams can add their own rules and customize the assistant's behavior per room to match their workflow. Review tools extend well beyond text. Users can draw directly on any frame with lines, shapes, text, or freehand, pin comments to specific frames or frame ranges, and even speak comments instead of typing them. The assistant sees those annotations and builds on them, turning feedback into edits, summaries, and tasks in the browser. Statuses can be tracked visually on a board or via agents, docs update live, and approvals get tracked. Room memory is what makes the context compound: come back next week for a follow-up review and the AI already knows what was discussed, what was decided, and what still needs attention — in the company's words, the room is the notes. Real-time translation removes language barriers: the assistant transcribes the conversation in real time, separated by speaker and timestamp, and translates it live into each participant's language, supporting English, Português, Español, French, 中文, 日本語, 한국어, Deutsch, Bahasa Indonesia, Italiano, and العربية. Pactto organizes its approach around three things every creative team does — present, review, and approve — and accelerates all of them in one place. For presenting, video plays at studio quality for everyone at the same time without lag, color-accurate and frame-accurate, with no compression artifacts and no dropped frames. For reviewing, voice comments go in and agents act live, capture and act happen in the same room and the same breath, and everyone watches the same frame through synced playback. For approving, decisions happen inside the room, docs update live, approvals are tracked, and rooms persist so every decision, asset, and version stays exactly where it was left. Assets arrive from local drag and drop, from Adobe Frame.io through a partnership with Adobe, from Google Drive, and via Google Sign In, with Dropbox and Air listed as coming soon. The stated outcome for teams is faster delivery: the company cites teams delivering work in days instead of weeks and moving from v1 to vFinal faster than ever. Approvals happen before the conversation ends rather than after a cycle of uploading v3, waiting for notes, uploading v4, and starting over. Because the room keeps every decision and the AI keeps every note, nobody has to pull up notes from last time, and no nuance is lost while someone scrambles to write feedback down. Every stakeholder gets notified, every status gets updated, and everything moves forward. Testimonials on the site describe Pactto as a candidate to become the operating system of the new creative process, and as a new interface for creative teams producing work using AI. Pactto lists a wide range of use cases, each framed as one room used a different way. Creative agencies can run their most complex AI projects in one room, managing every asset, board, and decision and tracking images, video, and PDFs from v1 to launch. Podcast teams can give every episode its own room, brief it, review the cut at real quality, generate cover art, and map every social short in every format. Roundtables can host recurring group sessions in a persistent room where the AI keeps summaries and action items and new members catch up on full history. Language tutors can keep one room per student, share materials, mark up pronunciation and grammar, and let the AI keep every correction and vocabulary list. Sports and mental coaching use frame-accurate video review, live annotation of form, and a room per athlete where training logs and commitments build week over week. Architects present renders, plans, and PDFs at full resolution and get sign-off live. Founders can pitch investors in a room that captures every question and follow up in the room rather than with an attachment. Event organizers can track roles, sponsor commitments, and the run of show in live tables and boards. Pactto is aimed at distributed creative teams and the people around them: directors, editors, designers, producers, agencies, podcast teams, coaches, tutors, architects, founders, and event organizers, along with the clients and reviewers who need to participate. Reviewers and clients do not have to pay on Pro — unlimited guests can be invited to a room with a link without an account or a paid seat. On the free plan there is no guest link, so people join by direct invite only. The free plan costs $0 with no card required and includes two active rooms, all editing and commenting tools, 5GB of storage, five members with room access, 60-minute meetings, 10 one-time AI credits, 60 minutes of live translation, and room memory that remembers the most recent session. Pro costs $19 per month billed annually ($228 a year) or $25 billed monthly and adds unlimited rooms and guests, 500GB of storage, persistent room memory, unlimited meeting summaries and guest sessions, 100 AI credits monthly, eight hours of live translation, integrations with Frame.io, Google Drive and Air, and CLI access that lets teams point Claude Code or Codex at a room to read or write its contents from the terminal. Security features include end-to-end encryption, SOC 2 in progress, and encryption on AWS S3 buckets, and fully white-labeled deployments are offered for agencies and enterprises that want to present Pactto under their own brand. Pactto's primary promise is a single persistent room where creative teams present at the quality their work deserves, review with an AI agent that understands creative intent and captures every note, act on feedback live, and approve before the conversation ends — with context that compounds instead of disappearing.
thestory.run is a web app that coaches employees to write their own LinkedIn posts. Its stated purpose is to be a writing coach for corporate influencers — the people whose job quietly includes LinkedIn, from founders and salespeople to recruiters, engineers and experts. The coach asks questions, helps a person find the story inside a rough thought, and hands them a structure to write into. It never writes the post, and it never rewrites your words. Most AI tools take over the writing; thestory.run flips that relationship so the person stays the writer and the tool stays the coach. The product opens with a blunt observation: "We stopped writing." Three problems are named. First, AI slop is real — the site cites that 81% of long-form posts on LinkedIn are likely AI-written, and argues the personality is gone even when the AI "has your voice." Second, people are too busy to think: it is not that you have nothing to say, it is that nobody asked you the right question about it. Third, people use AI wrong — let it write for you and you slowly lose your own voice and the ability to put a thought into words. The result, as the site puts it, is that writing goes from something you liked to one more task to get over with. thestory.run's stated belief is that AI is here to support humans, not replace them: leave the edits to AI, and you be the superstar. The core experience is one real session that runs from a messy thought to a finished post, in three steps: share a rough thought, talk it through, write it yourself. You drop in the raw thoughts and the coach helps you uncover the story behind them, making the point you do not see yet. It asks one question at a time — in the example shown, it answers an observation with "That's an interesting observation, I bet you've watched it play out somewhere specific. What did that look like?" — and then picks up on the honest line the writer had not said out loud. Once your thoughts are out, the coach lays out the arc that helps you tell the story. The example arc has three beats: open on the moment, name what's really going on, and the pivot. Then you write it, and the coach turns editor: it marks what carries the post and what to try. The marks shown include "Keep · your spine" (the whole post in six words, let it stand) and "Move · your opener" (sharper than the meeting scene, open on it). The coach can move your opener to the top reversibly, with an undo, and the framing the product uses is 100% you, 0% coach — the words on the page are the writer's. Between the posts, the coach keeps the week moving so you never have to guess what to do next. A weekly to-do shows the plan at a glance, such as one post on leadership and shaping a saved team culture idea. Daily reflections offer a nudge from your coach — for example, "What have you changed your mind about in remote work?" — with an answer link. A posting streak and activity calendar track momentum (the example shows five weeks in a row, with the message "Showing up is the whole game"), and achievement stickers such as "posted on every topic" keep you accountable without guilt. A "finish drafts while they're hot" area surfaces drafts with labels like leadership/fresh/nearly there, or culture/a few lines in, and asks whether you are ready to write this one. For teams, thestory.run treats corporate influencing as a team sport. Most people start alone, and bring the team when they are ready. A team sees who is posting, on which theme, and what is still uncovered — but drafts, ideas and coach conversations stay private to the writer, not their teammates, not their admin, not their boss. Three team features are described. Campaigns: an admin sets a theme and a window, such as a hiring push, a launch or a conference, and the coach folds it into everyone's week as something to draw on; nobody gets handed a post to write. The team calendar shows who is posting, on what, and which days nobody has taken, so the team spreads out instead of everyone publishing on Tuesday. Wins: people share what landed, if and when they want to, and colleagues cheer, because watching a colleague's post open a real door is what gets the next person writing. The unique approach is what the product calls the writing tool that refuses to write. The coach asks one question at a time, underlines the strong lines you already wrote, and offers a structure to write into rather than a draft to approve. Every word you publish is a word you wrote. There is exactly one exception, called cheat-mode, and you have to reach for it on purpose: activated on a piece you have already started, the coach writes the post from what you brought — your rough thought, your conversation, the lines you kept, the arc you agreed on, and a few of your own published posts so it can hear how you write. Cheat-mode spends one of a small monthly allowance: one cheat for every four posts in your plan, never more than three a month. The post is marked permanently as coach-written and does not count toward your progress. Publishing is also opt-in: the product posts to LinkedIn only if you ask it to, on a post you have already written and read, and it never publishes anything you have not pressed the button on; you can also publish by hand and simply tell the app it happened. The benefit the product promises is that what you publish sounds like you, because you wrote it. Testers quoted on the site describe writing with the coach as feeling like therapy, like writing in a notebook that helps you think better, and as a conversation style that moves one step at a time. One tester's complaint about writing with AI today — "90% of what AI writes, I rewrite it, because it's not how I would write" — is contrasted with a founder's reaction to her first coached draft: "Wow, I kinda wrote it in one breath. I didn't know I can do that." Other quotes say the tool makes people want to write again, helps them find the substance instead of "some blah blah," and offers guidance for people who feel they do not have the time or capacity to think freely. Concrete workflows described in the content include turning a messy observation into a finished post in one coaching session; keeping a weekly posting rhythm with a plan, daily reflections and a streak; rescuing drafts that are nearly there or only a few lines in; coordinating a team around a campaign window such as a hiring push, launch or conference so several people write on the same theme without anyone being handed words; and spreading posts across a week with the team calendar so days like Thursday are not left open. thestory.run is aimed at people who post under their own name at work — founders, salespeople, recruiters, engineers and experts — and at teams that want corporate influencing to work company-wide. It is free forever for teams of five people or fewer, with everything included: people, channels and every feature, no credit card, no trial clock, no feature gates. From the sixth person it becomes pay as you go at 1 euro per coaching session plus tax, and nothing else; prices are in euros, and checkout in over 150 countries lets you pay in your own currency, with Stripe doing the conversion at its own rate and a small currency fee. It is built by Swat.io GmbH in Vienna, Austria, operated under the GDPR and the Austrian Data Protection Act, and runs in the European Union, with the privacy policy and data processing agreement published on the site; privacy is enforced in the data layer rather than hidden in the interface. Swat.io is a social media management tool more than 18,000 people use, built by fifty people over fifteen years with no investors and behind social media for 1,700+ brands; it provides the content calendar, community management and insights, while thestory.run is the other half — the coach that helps a person find and write the post in the first place. The takeaway: thestory.run is built for teams whose people already have things to say but do not know how to say them. Instead of generating posts and leaving a human to edit the machine, it coaches each person to write in their own voice, keeps the week moving between posts, and lets teams coordinate themes without handing anyone words.

Anomalo Analyst is a team of AI agents that monitor your data around the clock and give you insights on anything that is happening in the data and why it matters. According to Anomalo, you connect your data warehouse or data lake and start getting data insights without writing SQL queries or refreshing dashboards. The product is built for data teams and for the people who depend on them: instead of asking analysts to hunt for what changed, Anomalo Analyst proactively publishes a continuous feed of trends, anomalies, and shifts, then lets anyone dig deeper with plain-language follow-up questions. Its stated purpose is captured in the product's own framing — your data is always talking, and Anomalo Analyst makes sure you do not miss what it is saying. Data changes constantly, and the volume of that change is the problem Anomalo Analyst addresses. In most organizations the burden falls on people to notice what moved: someone has to write a query, wait on a dashboard to refresh, or file a ticket with a data team and wait for an answer. Anomalo's messaging is explicit that most AI tools ask you to find the insight, while Anomalo Analyst finds it for you. The traditional approach means meaningful business changes can go unnoticed until someone happens to ask the right question, and raw alerts from monitoring systems often add noise rather than clarity — an alert is not the same thing as an explanation of what happened and why it matters. Anomalo also says the product helps distinguish real business changes from broken data, because a genuine shift and a data problem can look identical until someone checks. Detection starts with statistical modeling rather than LLMs. Anomalo states that its statistical modeling, not LLMs, scans every table for meaningful changes such as new values that appeared, trends that reversed, or drift that occurred, and more, then ranks every change with a magnitude score. That ranking gives the AI agent a prioritized list of real changes rather than an undifferentiated pile of events. Because the scanning is statistical and automated, it runs across every table rather than only the handful of metrics someone remembered to instrument, and the magnitude score lets the system separate small fluctuations from changes large enough to be worth a person's attention. Once changes are ranked, a team of specialized AI agents takes over: they monitor the data, detect what has changed, decide what matters, and write up the finding in an analyst-grade report, so what reaches you is a polished insight rather than a raw alert. The AI agent investigates the ranked changes, digs into historical context, and writes a report revealing what happened, what the data shows, and why it matters. A dedicated verification agent then reads every report line by line and checks each claim against the data before it reaches you — hallucinations get caught and corrected, not published. That verification step matters because the report is meant to be trusted as a written finding: Anomalo says it helps you tell a real change apart from broken data, and it checks each claim against the data rather than publishing unverified model output. Insights are proactively published to you. Anomalo describes a news feed of everything meaningful that changed in your data, delivered to your homepage and your inbox, all without prompting, plus a personalized digest of what actually changed — the trends, anomalies, and shifts that matter to your work — so you can be the most insightful person on your team without logging in. When an insight catches your eye, you dive deeper with follow-up questions and analyses in natural language instead of filing a ticket. Anomalo states the product gets smarter the more you use it: giving feedback when an insight was useful, or noting that you look at your data differently, is saved to memory, making every insight and conversation sharper. Findings can also be shared — any insight or analyst conversation can be shared with a link, and recipients can view it immediately after signing in, with no warehouse access needed. The overall flow is deliberately short. You connect your data platform and select the tables you care about; Anomalo Analyst analyzes and profiles your tables automatically and asks a few quick questions to personalize your insights; the AI agents learn from your data's history and watch your tables every day for meaningful changes; and you can dive deeper into any change or insight at any time with natural-language follow-ups. Anomalo describes onboarding as telling it what you care about, having it find the right tables and start monitoring, and going from signup to your first insight in minutes. The distinguishing methodology, in the company's own words, is that most AI tools ask you to find the insight while Anomalo Analyst finds it for you — the system does the monitoring, the prioritization, the contextual explanation, and the verification, and delivers the finished insight rather than a raw alert. Anomalo frames the benefit around being informed without effort: you show up informed, you know before anyone asks, and you can be the one with the answer. A continuous feed of trends, anomalies, and shifts arrives without writing a query, waiting on a dashboard, or filing a ticket with your data team. Because every claim in a report is verified against the data before publication, the insights you act on have been checked. And because a dedicated verification agent exists specifically to catch and correct hallucinations, the workflow is designed so the reader does not have to independently re-check the numbers in a report before using it. Concrete scenarios follow from the described workflow. A data team connects its warehouse and lets Anomalo Analyst profile and monitor the tables they care about, then reviews a continuous feed of what shifted. A person preparing for a meeting checks their personalized digest and arrives already aware of the trend that reversed or the new value that appeared. Someone who sees an insight they do not fully understand asks a follow-up question in plain language rather than opening a ticket. When an insight is relevant to a manager or teammate, it is shared as a link the recipient can open immediately after signing in — even without warehouse access. Over time, feedback on which insights were useful, and how the user looks at their data, is saved to memory so subsequent insights and conversations are sharper. Anomalo Analyst is presented for data teams and for anyone who needs to know what is happening in the data. The site says it is trusted by data teams and shows organizations including Aritzia, Atlassian, Block, Buzz, Casey's, Discover, Equifax, Evidation, Faire, Fandom, HomeToGo, Lebara, and Notion. On the data side, Anomalo describes connecting a data warehouse or data lake, and the Product Hunt listing names Snowflake, Databricks, or BigQuery. Access is via the web, and the call to action throughout is Start for Free, alongside links to request a demo to see autonomous agents in action. That is the core value proposition Anomalo Analyst reinforces at every step: your data is always talking, and a team of AI agents monitoring it around the clock means you do not miss what it is saying. Detection runs on statistical modeling, explanations arrive as analyst-grade reports with each claim verified against the data, delivery happens proactively to your feed and inbox, and investigation happens in plain language rather than in tickets. For data teams and the people around them, the outcome Anomalo promises is simple and specific: you show up informed, and you are the one with the answer.
Googlebook is the first laptop designed for Gemini Intelligence, built to bring Google's AI services and Android phone integration together in one portable computer. It is crafted with premium materials for powerful performance and syncs effortlessly with your phone. Googlebook is aimed at people who want their laptop and their Android phone to behave like a single connected system, and it is ready from day one with a full suite of premium Gemini services and 5 TB of cloud storage. Pricing starts from $899, and the device can be pre-ordered now through the website. The lineup covers laptops and accessories. Most people move constantly between a phone and a laptop, and that switch carries a cost. Files and screenshots have to be transferred, tasks get interrupted, and documents are hunted down by cryptic filenames rather than by what they actually contain. Typing out thoughts often produces messy text littered with filler words, and searching usually means leaving whatever you were doing. Googlebook is positioned against exactly that friction: less time transferring, more time creating. Instead of treating the phone and the computer as two separate islands, it treats them as one workspace, and instead of treating AI as a separate app you go and visit, it places Gemini directly into the pointer, the keyboard and the screen in front of you. On the hardware side, Googlebook is supercharged with powerful processors like Intel Core Ultra and Snapdragon X Elite. Configurations start from 16 GB RAM and from 256 GB of storage, and the laptop is rated for up to 14 hours of battery life while weighing under 2.85 LBS. It is built with premium materials including aluminium, magnesium and carbon fiber, and OEM brand marks shown include HP, Dell Technologies, Lenovo, Acer and ASUS. Two distinctive hardware details stand out. The Glowbar is described as functional, beautiful and uniquely Google, acting as an at-a-glance indicator of your battery life and charging status. The G Key provides one-touch searches with a dedicated key, so answers are always right at hand. Intelligence is the defining layer of the machine: the best of Gemini meets a whole new kind of laptop. The pointer becomes more than a pointer, acting as a magic wand, and wiggling it activates Gemini so you can select anything to ask, create and compare effortlessly. Rambler turns messy thoughts into tidy text by removing filler words like "um" and adding formatting to clean up your stream of consciousness, so you can just talk naturally, review and send. Googlebook also meets you in the moment, with proactive suggestions that appear with your next move based on what is on your screen, surfacing exactly what you need when you need it. Smart file search lets you search files and photos by their actual content, so you can stop hunting for cryptic filenames. Gemini Live turns "Hey Google" into a live conversation where you can talk, share your screen or brainstorm with zero typing required, and you can close your to-dos even when your laptop is closed with the agent in the Gemini app. Because it is designed around Android, Googlebook focuses on syncing effortlessly with your Android phone, so you can jump between phone and laptop without skipping a beat. Cast My Apps makes it easier to stay in the zone by letting you open your phone's apps directly on Googlebook, so you can handle quick tasks without ever leaving your screen. Continue On lets you start a task on your Android phone and finish it on Googlebook, keeping your momentum and picking up exactly where you left off. Quick Access lets you find your phone's files directly from your laptop, so if you need that mobile screenshot for an email you can get it instantly with no transfers needed. The laptop also opens the wider app ecosystem: through the Google Play Store you get access to millions of your favorite apps and tools. The site groups these as Best of Google, including Gemini, Gemini Notebook, Antigravity, Google Drive, Gmail and Google Docs; Creativity, including Adobe Photoshop, Adobe Lightroom, BandLab, Canva, CapCut and Luminar; Productivity, including Notion, Notability, Microsoft Copilot, Adobe Acrobat, Dropbox and Fantastical; and Streaming, including YouTube, YouTube Music, Spotify, Netflix, HBO Max and Disney+. There are also thousands of games: you can play mobile hits like Clash Royale on Google Play, or stream PC heavyweights like ARC Raiders via GeForce NOW. Security is built in rather than added on. Googlebook is designed with built-in protection that helps keep viruses, malware and hackers out. The Titan C chip keeps your device, passwords and personal data safe with dedicated security built into every laptop, and secure authentication lets you unlock your Googlebook with your face or your fingerprint, with the laptop instantly recognizing you. Buyers also get extra perks included: Googlebook offers up to $300+ in apps you love, unlocking a curated collection of apps right at your fingertips, available for a limited time. The outcome for users is a machine that removes the small frictions that add up across a working day. Quick tasks no longer force you to pick up your phone, because phone apps can be opened on the laptop screen. Screenshots, files and photos are reachable from the laptop without transfers. Work that begins on the phone can be completed on the laptop without restarting it. Filler-heavy speech becomes formatted text ready to send. Files are found by what is inside them rather than by their names. Suggestions arrive based on what is already on screen. Conversations, screen sharing and brainstorming happen by voice. Errands get closed even when the lid is shut. Concrete scenarios follow from those capabilities. Someone drafting a message can wiggle the pointer to activate Gemini, dictate naturally, let Rambler clean up the filler words and send the tidied text. Someone who needs a mobile screenshot for an email can pull it from the phone with Quick Access instead of transferring it. Someone who starts an edit on their Android phone can continue on Googlebook and finish the job using Continue On. A user looking for a photo or document they only remember by content can search using smart file search rather than by filename. A person in a call can use Gemini Live to talk, share their screen or brainstorm without typing. In the evening, the same laptop can run streaming apps or games, from Google Play mobile titles to PC games streamed via GeForce NOW. Googlebook is aimed at Android phone owners who want a laptop that behaves like a companion rather than a separate device: people who value premium build materials, long battery life and a light chassis under 2.85 LBS, and who want Gemini Intelligence available at a wiggle of the pointer. It draws on processors such as Intel Core Ultra and Snapdragon X Elite, runs apps through the Google Play Store, and includes 5 TB of cloud storage along with premium Gemini services. Pricing starts from $899, and the device is available for pre-order; the full lineup covers laptops and accessories, and visitors can sign up for updates by entering a name and email address. Googlebook's primary value proposition is the combination of a premium laptop and Gemini Intelligence that reaches into the pointer, the keyboard and the screen, joined to an Android phone that stays in sync. With the Glowbar, a dedicated G Key, face or fingerprint unlock and the Titan C chip, it is a machine designed for performance and protection, while Cast My Apps, Continue On and Quick Access erase the distance between phone and laptop. Readiness from day one with premium Gemini services and 5 TB of storage rounds out the pitch.
SereneDB is an open-source, real-time search analytics database that combines ultra-fast full-text search and fast analytics in a single engine. It is built for teams that need to search and analyze large volumes of data — such as logs, tables, files, and object storage — without running separate systems for search and analytics. The product offers a PostgreSQL-compatible frontend, so users can keep their existing SQL, drivers, and Elastic clients while working with full-text, vector, and hybrid search alongside relational data. According to the product's own description, it is the result of 12 years of development and is released under the Apache 2.0 license. The stated positioning is straightforward: one database that does ultra-fast full-text search and fast analytics in one engine, aimed at teams who would otherwise operate two systems. Traditionally, teams that need both search and analytics run two separate systems — for example, a search engine such as Elasticsearch alongside an analytical database such as ClickHouse — and move data between them with ETL pipelines. SereneDB's stated purpose is to remove that second system and the ETL between them by doing ultra-fast full-text search and fast analytics in one engine. The Product Hunt description says the company's public benchmark shows it outperforming Elasticsearch, ClickHouse, and Postgres search extensions, and indexing 1 billion logs in under 8 minutes at roughly 10x less disk usage. Apache 2.0 licensing, methodology, and raw results are public, so teams can evaluate those claims directly rather than taking them on faith. On the search side, SereneDB offers four related capabilities. Full-text search provides BM25 ranking over both tables and files, the classic relevance-ranking approach used for keyword search. Vector search is supported through ANN (approximate nearest neighbor) indexes that sit beside relational data, so semantic similarity lookups can live in the same database as structured records. Hybrid search combines BM25 and vector scores in a single query, letting teams blend keyword relevance and semantic similarity instead of choosing one or the other. Finally, Postgres search support means teams keep their existing drivers and their SQL rather than rewriting queries for a new search system. For analytics and data, SereneDB is designed to work on fresh data rather than overnight snapshots. Real-time analytics let users aggregate fresh data with no nightly job, which matters for dashboards and monitoring that need current numbers. As an OLAP database it performs columnar scans over billions of rows, the access pattern typical of large-scale analytical queries. Search over a data lake lets users index object storage in place instead of copying it into another system. And zero-ETL search lets queries run against remote sources where they live, further reducing the need to duplicate data or build synchronization pipelines. SereneDB also positions itself for AI and agent workloads. It is described as a database for AI agents, offering agent-ready SQL over every source, so agents can query data through SQL rather than through bespoke connectors. As a RAG database, it acts as the retrieval layer for grounded answers, supplying the context an AI application needs. Documentation search lets teams search over docs and knowledge bases, and the company's own blog describes how documentation content can be turned into tools for agents. Architecturally, SereneDB unifies search and analytics with a columnar engine, vectorized SQL execution, and hybrid storage behind a PostgreSQL-compatible frontend. That combination is what allows full-text, vector, and hybrid search to run next to analytical queries inside one engine. Compatibility is central to the approach: the database is Postgres- and Elastic-compatible, so teams keep their SQL, their drivers, and their Elastic clients. Installation is presented as straightforward — the quick-start command is a curl script — and the site lists Docker, Linux, and SereneUI as options, with documentation covering quick start, indexes, query syntax, statements, and clients. The stated benefits follow from that single-engine design. Teams can drop a second system and the ETL between it and their primary database, which simplifies the architecture and removes a class of data-synchronization problems. Because compatibility is preserved, there is no rewrite: existing SQL, drivers, and Elastic clients continue to work. The performance claims are significant — outperforming Elasticsearch, ClickHouse, and Postgres search extensions in the company's public benchmark, indexing 1 billion logs in under 8 minutes, and using roughly 10x less disk — which, if it holds for a given workload, translates into faster indexing and lower storage cost. Apache 2.0 licensing, together with public methodology and raw results, gives teams a way to verify the claims before committing. Aggregating fresh data without nightly jobs also means analytics reflect the current state rather than yesterday's snapshot. Concrete scenarios described by the product include both search workloads and analytics workloads over very large datasets. The company's published comparisons run 92 search and analytics queries over 100M, 1B, and 10B OpenTelemetry logs on a single instance, both against ClickHouse and against the Lucene world (Elasticsearch, OpenSearch, CrateDB) — clearly a log search-and-analytics scenario. Other described scenarios include building retrieval layers for RAG pipelines where an AI application needs grounded context; powering documentation and knowledge base search that can also be exposed to agents as tools; running real-time analytics on fresh data without waiting for a nightly batch job; searching over a data lake by indexing object storage in place; and querying remote data sources where they live instead of copying them first. SereneDB targets developers, data engineers, and platform teams who operate search and analytical infrastructure, as well as teams building AI agents that need SQL access to data. Integrations mentioned in the content include PostgreSQL drivers and Elastic clients, plus a documented LangChain integration for RAG. Because the database is Postgres- and Elastic-compatible, existing client libraries continue to work. The site lists Docker, Linux, and SereneUI as installation options, the quick start is a single curl command, and the documentation covers quick start, indexes, query syntax, statements, and clients. The project is open source under the Apache 2.0 license, with a public GitHub repository listed at 806 stars and public benchmarks; no commercial pricing plans are stated in the provided content. SereneDB's primary value proposition is consolidation: one database that performs ultra-fast full-text and vector search together with fast, real-time analytics behind a PostgreSQL-compatible frontend, so teams can eliminate a second system and the ETL between them. It is open source under Apache 2.0, and its benchmark methodology and raw results are public.
WZRD is an AI workspace built for teams and creators who work with documents, slides, forms and sheets. Its central promise is that these everyday business artifacts should not be static files that people simply read, scroll through or fill in; instead, WZRD turns them into interactive, conversational experiences that talk back. The platform lets a user upload existing work or generate new material from a prompt, and then reshapes that material into an AI experience that end users can engage with directly. WZRD is described as an AI-native workspace that produces AI presentations in minutes, smart form flows, smart sheets with structured generation, and AI-crafted smart documents. In short, it is a single AI workspace where the documents a business already relies on become responsive, voice-enabled assets. Most business communication still runs on static formats. A slide deck is presented once and then sits inert as a file. A form is a passive set of fields that a respondent has to interpret and manually complete. A spreadsheet holds numbers that rarely explain themselves. A document is read, not conversed with. WZRD addresses this gap by making the output conversational and responsive rather than fixed. The problem it targets is the distance between the information a team has produced and the ability of an audience to engage with that information. By converting documents, slides, forms and sheets into AI experiences, WZRD aims to keep the audience involved instead of leaving them as passive readers or viewers. That shift matters for teams and creators who need their work — pitches, reports, intake forms, analyses — to be understood and used, not just delivered. On the presentation side, WZRD generates AI presentations in minutes and brands them as slides that talk back. The idea is to give slides a voice that walks people through the story, so instead of a silent deck the audience is guided through the narrative. Users can drop a file to start or browse their documents, and WZRD will work from existing material rather than requiring everything to be built from scratch. For documents, WZRD produces AI-crafted smart documents — written artifacts that, like the rest of the output, remain conversational and engage every user rather than being one-directional text. Both formats are generated with AI and can originate either from an uploaded file or from a prompt, which means the same workspace can be used to refresh existing content or to create something entirely new. WZRD also covers the data-collection and data-explanation sides of business work. Its forms are described as smart form flows that collect answers by speaking or typing, so a respondent is not limited to typing into fields — they can answer out loud, and the output stays conversational and responsive. Sheets, meanwhile, are smart sheets with structured generation, and they explain numbers out loud. Rather than leaving a reader to interpret a grid of figures, a WZRD sheet can narrate what the numbers mean. These two capabilities extend the same underlying principle — that business artifacts should be able to communicate — into the workflows of gathering information and understanding quantitative results. Voice is a first-class part of the product. The site invites users to tap to talk, and the product is positioned around talking to your business with AI voice agents. That means the experiences WZRD produces are not limited to text on a page: a person can speak to the material and receive a spoken or conversational response. Combined with the description that the output stays conversational and responsive, this points to an approach where the finished artifact behaves more like an interface than a file. Whether the artifact is a form gathering spoken answers, a sheet explaining figures out loud, or slides walking someone through a story, the common thread is a two-way interaction rather than a one-way read. WZRD's overall method is deliberately simple to start. A user begins by answering the question of what they are building today, then either drops a file or clicks to browse their documents. The supported starting formats listed on the site are XLS, CSV, PPT, PDF and DOCS, which means spreadsheets, presentations, PDFs and word-processor documents can all serve as the raw material. From there, the user can generate with AI, producing slides, forms, sheets or docs as needed. Alternatively, material can be created from a prompt without an existing file. The result is then turned into an AI experience that users can engage with — an experience that stays conversational and responsive. This workflow keeps the entry point familiar (upload what you already have) while changing the destination (an interactive AI artifact instead of a static file). The benefit WZRD claims for its users is a more engaged audience and less friction in producing polished business material. AI presentations arrive in minutes rather than requiring hours of manual formatting. Forms gather answers by voice or by typing, which can make responding easier. Sheets articulate their own numbers. Documents engage every user instead of sitting unread. For teams and creators, that combination means the work they publish continues to communicate after it is sent, and the people on the other end have a way to interact with it. The output remaining conversational and responsive is the through-line: the same material that used to be inert now responds. Concrete scenarios follow directly from the four formats. A team preparing a pitch or internal briefing can turn an existing PPT or PDF into slides that talk back, walking the audience through the story rather than leaving them to read the deck alone. A business collecting information can build smart form flows that accept spoken or typed answers, which suits intake, feedback or discovery processes. An analyst or operator can use smart sheets with structured generation so that a spreadsheet explains its numbers out loud instead of requiring the reader to decode them. A writer or team lead can produce AI-crafted smart documents that engage readers conversationally. And because users can upload existing work, all of these scenarios can start from material a team has already created and then be reshaped into an AI experience. WZRD states its audience plainly: it is for teams and creators working with documents, slides, forms and sheets. The site does not detail specific integrations, a public technology stack, or pricing plans, so those remain unspecified here. What is stated about getting started is the supported input formats — XLS, CSV, PPT, PDF and DOCS — along with two creation paths, uploading a file or generating from a prompt. The product was also launched on Product Hunt, which is referenced on the site as a live launch page. WZRD's core value proposition is straightforward: an AI workspace where the documents, slides, forms and sheets a team already works with are regenerated as AI experiences that talk back. By combining generation from a prompt or an uploaded file with voice-enabled, conversational output across four common business formats, WZRD aims to move everyday material from static delivery to responsive engagement.

gg-friggin-ez is a fast, free, drop-in multilingual profanity and toxicity screener for Node.js. It is powered by System 1 models such as TypeSafe AI's Jev and Laya, and it is built to catch leetspeak, ASCII drawings, character spacing, and romanized profanity across all languages, with native support explicitly called out for Kannada, Telugu, Tamil, Hindi, and Bengali. The project targets developers and engineering teams that need to screen user-generated text for profanity and toxicity in real time and at scale, and its stated goal is to be fast and cheap enough to run on every single message rather than only on a sampled fraction of traffic. The product grew out of a moderation problem the maker encountered while working in the real-money gaming industry, where chat moderation never had a good answer because existing options were too slow, too expensive, or too dumb to catch anything past a static keyword list. The maker frames the history simply. Pre-LLM approaches were fast but brittle, and traditional filters and ML/NLP models struggled with Romanized Indic text, slang, ASCII art, and creative evasion. Large language models were smart but too expensive to run at scale. System 1 models such as Jev and Laya changed the trade-off: they are single forward-pass decision engines built for real-time classification, offering sub-500ms end-to-end latency, deterministic output, and costs measured in pennies per million tokens. gg-friggin-ez was built around that shift, and it is designed for teams that need a real moderation answer rather than a keyword list. The headline capability is evasion-proof detection. According to the maker, the screener catches Romanized Indic profanity, leetspeak and ASCII-art evasion, and character-spacing tricks that are designed to slip past a keyword list. That is the genuinely hard version of the problem: not catching a plainly spelled swear word, but catching the many deliberately obfuscated ways people write the same word so that substring or keyword matching will not fire. The product also claims broad multilingual coverage across all languages, and it highlights native Indic support for Kannada, Telugu, Tamil, Hindi, and Bengali, which are languages where romanized and mixed-script input is common in chat and where static filters tend to be weakest. gg-friggin-ez converts its toxicity assessment into deterministic moderation actions: ALLOW, REVIEW, CENSOR, or BAN. Nothing happens silently. Every call returns the probability plus reasoning before a backend acts on anything, AUTO_BAN only fires at high confidence, and ambiguous content is routed to review instead of being instantly banned. Alongside the decision, the screener returns rich telemetry, including confidence scores, evasion detection flags, and a primary language classification, so a team can see not just what was flagged but why and in which language. The maker points to a Scunthorpe-style test case showing that a contextual model returns an ALLOW result for the sentence "I live in Scunthorpe", unlike substring matching, which can trip on innocent words. Performance and cost are central to the pitch. Moderation is described as sub-500ms, and the cost is stated as roughly $0.000042 per message when using Jev at $0.042 per million tokens, or $0 inference cost when self-hosting the open-source models. Those numbers matter at scale: a screener that costs a tiny fraction of a cent per message can be applied to every message in a chat stream rather than to a sample, which is precisely what makes real-time moderation practical in high-volume environments where a single stream may carry thousands of messages. gg-friggin-ez ships with TypeSafe AI's Jev as the default out-of-the-box engine, but the architecture is fully decoupled, so the pipeline can be pointed at your own System 1 models. Under the hood, the approach is to use System 1 models as single forward-pass decision engines, which is what produces the combination of real-time latency, deterministic output, and low inference cost. Instead of matching substrings, the model makes a contextual judgement and returns probability and reasoning that the surrounding application can act on, with the option to send uncertain cases to a human instead of taking an irreversible action. The stated benefits follow from those design choices. Because a false positive may still be routed to review rather than triggering an instant ban, the maker argues that recall matters more than precision for this problem: missing a toxic or profane message that is then viewed by potentially thousands of people on a livestream platform is worse than flagging something for a human to check. The maker also reports early benchmark evidence, 97.6% overall accuracy (41 of 42 cases) and 94.4% accuracy on Indic and romanized text across 14 languages, while noting that the 42-message sample (three per language) should be treated as early evidence rather than a rigorous study. In that set, no benign messages were auto-banned, and the closest thing to a false positive was one Bhojpuri line landing in review instead of an instant allow. Concrete use cases named in the content include chat moderation in real-money gaming, where wrongly muted or banned players carry their own support cost, and livestream platform chat, where a missed toxic message can be seen by thousands of viewers at once. More broadly, because the product is a Node.js package, it fits any backend that receives user-generated text and needs a moderation decision before it acts, with the option to route uncertain cases to human review rather than taking automatic action on ambiguous content. The primary audience is developers building chat or user-generated content systems in Node.js, especially teams operating in multilingual environments that include Indic languages. The package is installed with 'npm i gg-friggin-ez', the source lives on GitHub, and a demo is hosted on GitHub Pages. It is 100% free and open source, and the maker lists GitHub Copilot and Jev among the tools used by the launch team. Because the engine is pluggable, a team can start with the default Jev engine and later point the pipeline at self-hosted open-source models to reach $0 inference cost. In short, gg-friggin-ez packages an evasion-aware, multilingual, context-based profanity and toxicity screener into a free, drop-in Node.js package. Its value proposition is the combination of sub-500ms latency, ultra-low per-message cost, deterministic ALLOW/REVIEW/CENSOR/BAN actions, and telemetry that explains every decision, so that moderation can run on every message instead of a sample.
Plane Agents are AI teammates that join your Plane workspace as members. Instead of prompting a chatbot for a one-off answer, teams give an Agent a job: they assign it work items, mention it in conversations, trigger it when work changes, or run it on a schedule. Plane Agents take on repetitive, context-heavy workflows 24/7, responding to changes, coordinating next steps, and acting across Plane and the connected tools a team already uses. They triage requests, draft specs, run standups, flag delivery risks, and handle a lot more of the recurring work that keeps coming back across planning, delivery, reporting, and operations. Plane Agents are designed for the work that keeps coming back. Across planning, delivery, reporting, and operations, teams repeatedly collect progress, chase blockers, write specs, sort incoming requests, and watch for slipping timelines. That work is context-heavy: it depends on what changed, who is involved, and what the current state of a project is. Because it repeats, it is easy to let slide, and because it is context-heavy, it is expensive to do well by hand. Plane Agents take on that recurring load so the same coordination work does not have to be redone manually week after week. As Plane frames it, the work keeps coming, so put an Agent on it. Agents are built around four decisions. First, define what it owns: teams start from a template or create an Agent from scratch, giving it a name, a clear responsibility, and the outcome it should work toward. Second, give it a playbook: describe how the work should be done, what a good result looks like, and which boundaries it should follow, then add the right skills and choose the model behind it. Third, choose when it starts: an Agent can be brought into work through an assignment or a mention, or it can start automatically when work-item changes occur or on a schedule, with filters that decide exactly when it should run. Fourth, connect its working context: choose the Plane projects, trusted web sources, and connected tools the Agent can use, and decide which connected account it should work through. Plane also ships ready-made Agents for the work that keeps coming back across planning, delivery, reporting, and operations, which teams can then adapt to their own triggers and context. The Standup Agent collects progress, blockers, and next steps from the team and turns them into a concise update that highlights what matters most; it works on Slack, Gmail, and Projects, with skills in progress tracking and team summarization. The Delivery Risk Agent monitors work for stalls, blockers, dependencies, and slipping timelines so teams can identify and address delivery risks early; it works on Github, Slack, and Projects, with skills in risk detection and dependency tracking. The Spec Agent turns rough ideas and requests into structured requirements, identifies gaps, and asks the right questions to make the scope clear; it works on Figma, Wiki, and Pages, with skills in PRD writing and product clarity. The Request Triage Agent reviews incoming work, identifies duplicates, adds relevant context, and routes each request to the right team or workflow; it works on Slack, Projects, and Intake, with skills in request analysis and duplicate detection. The Customer Feedback Agent groups customer feedback into meaningful themes, surfaces recurring insights, and connects them to relevant issues, projects, or ongoing work; it works on Slack, Projects, and Wiki, with skills in feedback analysis and theme clustering. Agents show up when the work does. A team member can assign an Agent to a work item, and it receives the relevant context and starts working on the job. An Agent can be mentioned inside a work item conversation to ask for information, prepare, or take the next step. It can also be triggered from change: an Agent starts when work is created, updated, changes state, gets reassigned, or removed. Agents can connect work across tools, using selected connected tools and trusted work sources to get context. And recurring work can be put on a schedule, so reviews, reports, checks, and follow-ups run automatically on a fixed or custom schedule. In every case the Agent acts with context and returns the result in Plane. Control and visibility are part of the model rather than an afterthought. Teams set the boundaries: they choose each Agent's reach by selecting the Plane projects, trusted work sources, and connected tools available to it. They choose whose access it uses, giving connected tools access through a person's account or through a service account managed by the team. They can also see where credits go, tracking adoption, response and completion rate, average time to complete, and consumption by Agent. That means a team can see when an Agent starts, what it returns, and when it needs human input, which keeps automated work accountable and observable instead of opaque. The payoff is that recurring, context-heavy coordination stops consuming human attention. Standups become concise updates instead of a manual chase for status. Delivery risks surface early because stalls, blockers, dependencies, and slipping timelines are monitored continuously. Rough ideas turn into structured requirements with gaps identified before work begins. Incoming requests are deduplicated, enriched with context, and routed to the right team or workflow. Customer feedback is clustered into themes and connected to the issues and projects it relates to. Because Agents respond to changes and can run on schedules around the clock, they keep pace with work as it evolves rather than waiting for the next meeting to catch up. Concrete scenarios follow directly from the available Agents. A team can schedule a Standup Agent to collect progress, blockers, and next steps and publish a concise update highlighting what matters most. A Delivery Risk Agent can watch work for stalls, blockers, dependencies, and slipping timelines so a delivery lead sees risk early. A Spec Agent can take a rough request in Figma, a Wiki, or Pages and turn it into a structured spec, asking the right questions where scope is unclear. A Request Triage Agent can sit on intake and Slack, deduplicate incoming requests, add relevant context, and route each one. A Customer Feedback Agent can cluster feedback from Slack, Projects, and Wiki and connect recurring themes to existing issues and projects. More broadly, any review, report, check, or follow-up that repeats can be placed on a fixed or custom schedule. Plane Agents are aimed at teams that already run their work in Plane and want recurring coordination handled automatically. Plane states that more than 50,000 teams use the product, and the site names customers including Sony, Accenture, SSI, Texelis, Stark Bank, Aramco, Dolby, Mirador Therapeutics, Amazon, République Française, Government of Lithuania, and Power Integrations. Agents work with connected tools such as Slack, Gmail, Github, and Figma, alongside Plane Projects, Wiki, Pages, and Intake. Plane is available on the web, with downloads for Mac, Windows, iOS, and Android, and the site lists compliance with GDPR, HIPAA, ISO 27001, and SOC 2. Agents run on the AI credits included in every paid plan, and teams can get started free or book a demo. Plane Agents turn repetitive, context-heavy coordination into always-on teammate work. Rather than prompting for a one-off answer, you give an Agent a job: assign it work, mention it, trigger it when work changes, or put it on a schedule. It then acts with context across Plane and your connected tools, within boundaries and with visibility that the team controls.
Edyt is a lightweight desktop app for Mac and Windows that adds AI actions to any text field. You select text, press a shortcut, and the result appears in place, right where your cursor is. It is aimed at anyone who writes across many different programs each day, such as email clients, browsers, notes apps, and chat apps. The available actions are Rewrite, Proofread, Alternatives, Explain, Translate, and Use Prompt, and the product positions itself as AI that lives right where you write. A free plan is described as enough for most people, while Pro removes the usage limits. Writing rarely stays inside one application. A reply is drafted in email, a paragraph is tightened in a document, a question is answered in a chat window, and a contract arrives as a PDF. Conventional AI tools and grammar checkers require copying text out, switching windows, and pasting results back. Edyt is built around avoiding all of that: the site describes selecting text in any app with no copying and no switching windows. The developers also argue their approach beats a traditional proofreader in specific ways, saying Edyt does better at explaining text, sounding like you, offering a genuinely free tier, working in every app on a Mac, and staying out of your way. There is a further gap the product targets: text you cannot even select, such as a PDF, a screenshot, or a shared screen. Rewrite polishes tone, grammar, and clarity in place, and the listing adds that Rewrite keeps your tone and follows your instructions. Proofread is built for catching mistakes thoroughly. Select the text, press Control+Shift+H, and every issue is flagged in place and grouped by kind on the left. The down arrow moves between issues and Enter fixes one; you can also fix them all at once. The text stays editable, so you can type and then re-check to catch anything new, and Insert pastes the result back in, formatted, right where it came from. The demo shows a correctness control, an ignore option, and an easy-to-read word count as the changes are reviewed. Alternatives answers the question of how else to phrase something. Select the text, press Control+Shift+L, and Edyt suggests options, listing several ways to say the same thing. If none of them fit, Show another produces a genuinely new one, never a repeat. You move between options with the down arrow and press Enter to open Insert or Copy, so a suggestion can go straight into the app or onto the clipboard. Explain takes the opposite direction and focuses on understanding. Press Control+Shift+X and definitions appear on the left with the explanation on the right. You can ask a follow-up question, which keeps the conversation going, so an explanation can deepen as far as you need. The site sums both up with the lines See it several ways and Understand instantly. Translate handles messages written in other languages. Select the message, press Control+Shift+T, and the meaning is rendered in your own language; select it again with the same shortcut and choose their language to reply. Insert drops the translation into the reply box and you send it. Recent languages are shown for quick switching, and you can ask how to adjust a translation if the wording is not quite right, which is useful for client conversations where precision matters. Use Prompt runs your own saved prompts on anything you select. Press Control+Shift+J and Edyt runs your last prompt right away, or you pick another prompt from the list on the left. Personalized prompts remember how you like things phrased, you can ask follow-up questions to refine the result, and Insert drops it straight into the document with no retyping. The listing adds that saved prompts follow your account to every machine. Not all text can be selected. Edyt's screen reading mode covers that case: hold Option on Mac or Alt on Windows and drag over a PDF, a screenshot, or a shared screen. Edyt reads the text on your device, using Apple's built-in recognition on Mac and the built-in Windows OCR on Windows, so the image never leaves your device. On Mac this uses the Screen Recording permission, only to capture the area you drag; Windows asks for no extra permission. Once the text is read, the same actions apply, so you can explain, proofread, translate, or run a prompt. In one demo a lease agreement PDF is dragged over and an automatic renewal clause is explained in plain language, including the 60 days' written notice requirement, followed by a direct question about the deadline. Edyt's workflow is described in three steps. First you select your text by highlighting anything in any app, such as email, docs, or chats, without copying or switching windows. Second, you press Control+Shift+Space to bring up the toolbar and pick the action you want. Third, Edyt calls the AI and drops the result right where your cursor is, described as instant and in place. Each action also has its own shortcut for speed: Control+Shift+C for Rewrite, Control+Shift+H for Proofread, Control+Shift+L for Alternatives, Control+Shift+X for Explain, Control+Shift+T for Translate, and Control+Shift+J for Use Prompt. Every action's shortcut can be remapped, and you can write your own prompts and organize them in your library from your dashboard. The stated benefits follow from that design. Results land where the cursor is, so there is nothing to copy and no window to switch to. Rewrite keeps your tone while it cleans up grammar and clarity, which matters when the writing has to still sound like you. Alternatives produces phrasing better than what you typed without you having to hunt for it yourself. Explain and Translate go as deep as you ask, because each result can be followed up with another question. Proofread can fix every issue at once or one at a time, in text that remains editable. Use Prompt turns your own preferences into reusable instructions, and saved prompts follow your account to every machine you use. The demos on the site map onto everyday tasks. In a chat, someone asks a colleague to look over an email to a client because the grammar is a mess; Edyt fixes it in seconds. Another demo proofreads an essay saved as Reflections.docx, flagging repeated words and awkward phrasing in place while the writer keeps editing. A third shows a client email being reworded several ways before it is sent. In a messaging app, a Spanish message about billing terms and an auto-renewal clause is translated so it can be answered in English. A lease agreement PDF is dragged over to explain an automatic renewal clause and its notice deadline. And in a document editor, a saved prompt rewrites a weekly sync announcement into tighter, more focused wording. Edyt is for people who write in many apps rather than one: email, documents, chats, and browsers, on Mac and Windows. On Mac it runs on macOS 12.3 (Monterey) or later, on both Apple Silicon and Intel. On Windows it runs on Windows 10 or later, 64-bit, currently as a beta, and the Product Hunt listing notes Ubuntu is next. It works inside any app with an editable text field. The free plan includes generous daily, weekly, and monthly usage with no credit card required, and Pro removes the limits for unlimited use. Edyt is not on the Mac App Store because reading and typing text in other apps needs macOS's Accessibility API, which does not work inside the App Store sandbox, so it is distributed directly from the site, signed and notarized by Apple. Privacy is stated plainly. Your text is sent over an encrypted connection for processing and then discarded; Edyt says it never stores it, logs it, or uses it to train AI models, with details on a Security page. The screen reading feature is handled on the device itself, so images never leave it. The footer repeats the same commitments: signed on Mac and Windows, your text is never stored, and never used to train AI models. Edyt's proposition is narrow and clear: AI for text, wherever it happens to live. By putting Rewrite, Proofread, Alternatives, Explain, Translate, and your own saved prompts behind a single shortcut inside any app, and by adding on-device reading for text that cannot be selected at all, it removes the copying, window switching, and friction that usually sit between you and a finished sentence.

Grok 4.7 is SpaceXAI's most powerful model for coding and knowledge work. It is built to work longer on difficult tasks, to check its own work more carefully, and it comes with the company's best-calibrated safeguards to date. SpaceXAI states that it is served at the same price and speed as Grok 4.6 and that it is highly competitive in its class. The model is available today in Cursor and in Grok Build, and it can also be reached through the Grok API, third-party coding harnesses, and model routers and cloud platforms, so teams can adopt it inside the tools they already use. The context for the release is the growing demand for models that can stay productive across long, multi-step jobs rather than only short prompts. SpaceXAI highlights CursorBench 4.0, a benchmark that stresses longer-running coding tasks, and notes that Grok 4.7 sits at the frontier in price-performance there. A second theme is professional knowledge work: in GDPval and AA Briefcase, the model is asked to work on tasks done by professionals such as lawyers, nurses, and financial analysts. Grok 4.7 improves on Grok 4.6 on both benchmarks and performs comparably to other frontier models, addressing the gap between short-answer demos and the extended work real jobs require. Grok 4.7 uses a new, larger base model compared with Grok 4.6. It was trained with a longer reinforcement learning run on a harder mix of tasks, weighted toward problems that take many hours to complete. As a result, the model is better at verifying its own work and at managing longer context, two capabilities that matter when a single task spans many steps. SpaceXAI also trained Grok 4.7 to natively understand the Grok Bot harness, which makes it better at conversational tasks and general knowledge work alongside its coding strengths. Together these changes describe a model tuned for endurance rather than one-shot answers. Across benchmarks, SpaceXAI positions Grok 4.7 as strong in several distinct domains. On software engineering it scores 46.3% on CursorBench 4.0, 71.0% on DeepSWE v1.1, with an asterisk marking a high-effort score, and 37.6% on Terminal-Bench 4.0. On electrical engineering it reaches 64.0% on EEBench. For professional knowledge work, it scores 1,657 on AA Briefcase v1.1 and an Elo score of 1,735 on GDPval. It also records 19.6% on the Harvey Legal Agent Benchmark and 56.7% on HealthBench Professional. The announcement compares these figures with Grok 4.6, GPT-5.6 Sol, and Fable 5.1, and notes that Grok 4.7 is better at creating documents and presentations. Safety and cybersecurity receive a dedicated section in the announcement. Grok 4.7 was built with an entirely new safeguard stack, and SpaceXAI describes it as the strongest model it has tested on refusals and jailbreak resistance. In dual-use domains such as cybersecurity and biological work, the company says it leads on both utility for benign tasks and safe refusal on dangerous ones, topping LatchBio's biosafety benchmark at 62.4%. On HackerBench v0.3, SpaceXAI's benchmark for risky and malicious cyber tasks, the model allows only 3.3% of risky dual-use prompts through while rarely blocking legitimate security work, giving it the highest safety score on that benchmark. The company frames this balance as important for defenders, who need the model to be useful on legitimate security work. SpaceXAI has also started giving select cybersecurity partners invite-only access to Grok 4.7's red-team capabilities for defense research. This detail shows that the safeguard work is not only a matter of refusal behavior but also of controlled enablement, where trusted partners can use the model for defensive security research while risky dual-use prompts are largely rejected for everyone else. Combined with the stated jailbreak resistance and calibrated refusals, the release frames safety as a core part of the model's design rather than an afterthought layered on top. The overall approach behind Grok 4.7 can be summarized from the announcement's own description: a larger base model, a longer reinforcement learning run on a harder task mix, and explicit training to verify its own work and handle longer context. Native understanding of the Grok Bot harness is another part of that methodology, aimed at conversational and general knowledge work. The commercial angle is equally deliberate, with the model served at the same price and speed as Grok 4.6 while the company reports frontier-level price-performance on longer-running coding tasks. For teams needing more throughput, SpaceXAI also serves a fast variant with twice the output speed at twice the price. The stated benefits follow from those design choices. Because the model works longer on difficult tasks and checks its own work more carefully, users can delegate multi-step jobs with more confidence that intermediate steps will be verified. Because it manages longer context and understands the Grok Bot harness, it can carry conversational and knowledge-work tasks that span more material. SpaceXAI also reports improvements in creating documents and presentations, and in benchmarks modeled on the work of lawyers, nurses, and financial analysts. Finally, the price and speed parity with Grok 4.6 means the capability gains arrive without a corresponding increase in cost per token for standard usage. Concrete scenarios appear throughout the announcement. Coding is first, both in Cursor and in Grok Build, where the model can be tried for free, and through third-party coding harnesses. Longer-running coding tasks are the specific focus of CursorBench 4.0, where the model is positioned at the frontier in price-performance. Multi-hour terminal work is represented by Terminal-Bench 4.0. Professional knowledge work includes the tasks measured by GDPval and AA Briefcase, described as work done by lawyers, nurses, and financial analysts, as well as the Harvey Legal Agent Benchmark and HealthBench Professional. Cybersecurity defense is another scenario, including invite-only red-team access for select partners. Electrical engineering is covered by EEBench. Grok 4.7 targets developers and teams doing coding and knowledge work. It ships in Cursor and Grok Build on day one, and is also available through the Grok API, third-party coding harnesses, and model routers and cloud platforms. Pricing starts at $2 per million input tokens and $6 per million output tokens, with a fast variant at twice the output speed for twice the price. A free trial is offered through Grok Build at x.ai/build, and the announcement also includes a CLI install command. SpaceXAI points users to its Console for creating an API key and to docs.x.ai for documentation. In short, Grok 4.7 is presented as SpaceXAI's most capable model for coding and knowledge work, combining a larger base model and longer reinforcement learning with a new safeguard stack. It works longer on difficult tasks, verifies its own work more carefully, and is served at the same price and speed as Grok 4.6 while claiming a frontier position on price-performance for longer-running coding tasks. For developers and professionals who need a model that can stay on task, balance capability with safety, and fit into existing tools, that combination is the core value proposition.
PixelCrew is a design platform built around a crew of specialized AI agents. You write a brief in free text — a landing page, a product dashboard, a design system, or a pitch deck — and the crew coordinates on it to ship production-quality design. Each agent has a named specialization, a defined scope, and a clear handoff, and together they work sequentially and with context, the way a real team does. What comes back is production-ready HTML and Tailwind, a complete design system, and the documentation your engineering team needs to ship or hand to any developer. The average delivery is 25–45 minutes. Most teams face the same trade-off: generic templates that look like everyone else's product, or bespoke design that takes weeks of studio time. PixelCrew's stated bigger picture is an internet where nothing feels generic, because bespoke costs minutes instead of weeks. Instead of prompting a single model for a one-shot page, a structured crew runs structured discovery, makes creative decisions, and builds the deliverable in a defined sequence. That means design decisions are grounded in research rather than assumptions, and every screen and edge case is resolved before anything reaches you. The crew is made up of named specialists. Elena is the Researcher and Strategy agent, and she is the first to run: she reads your brief and executes structured discovery, producing audience personas, a competitive analysis and gap mapping, jobs-to-be-done mapping, and an information architecture recommendation. She hands Marcus a validated research foundation, not assumptions, in the form of a research-brief output file. Marcus is the Director for Art Direction and runs second. He takes Elena's research and makes creative decisions about visual direction, brand language, and layout approach. He writes three distinct visual pitches, selects the strongest, and produces a full creative brief with palette, typography, layout direction, and section-by-section composition guidance, delivered as a creative brief document and moodboard. Mira is the Designer for UX Architecture and runs third. She takes Marcus's creative brief and builds the blueprint: wireframes, user flows, information architecture, and a section-by-section spec, output as wireframes.html, ux-flow.json, and a nav-spec. Every screen and every edge case is resolved, with all states resolved, and the build crew then turns that blueprint into production HTML. Because the handoffs are explicit and each agent works from the previous agent's document, the brief carries context forward instead of being reinterpreted at every step. After Mira, the build crew takes over. Copy and the design system take shape together: the crew writes the copy and assembles the design system — tokens, type scale, color, and components — so that design happens inside the system, not around it. Then every screen goes through a QA audit and a final review pass; issues get flagged, revised, and rechecked before anything reaches you. The documented final outputs include landing-page.html, design-system.json, tokens, components, and docs, alongside the research, creative brief, wireframe, copy, and QA report files generated along the way. PixelCrew's approach is best understood as a pipeline with a visible cast of agents: brief in, deliverable out. The crew runs in sequence, you provide context, the agents coordinate, and you receive production-quality output you can ship or hand to a developer. While it runs, you can watch the agents discuss decisions. The workflow is documented as seven steps: submit your brief, Elena maps the research, Marcus sets creative direction, Mira builds the wireframe, copy and the design system take shape, QA audit and final review, and finally you receive production output. That structure is what separates it from a single prompt-to-page tool: research, art direction, UX architecture, copy, design system, and QA are handled as distinct, connected stages. The benefits follow from that structure. You do not need to know how to prompt a model step by step, and you do not need a template — you describe what you need in free text and the agents read your intent. The outputs are files engineers can use directly, such as landing-page.html, design-system.json, tokens, components, and documentation, so the work can be shipped as-is or handed to any developer. Because research and creative decisions are validated and documented, and because a QA audit and review pass happen before delivery, you receive production-quality design rather than a rough draft. Concrete scenarios where PixelCrew is used come from the demonstration projects produced from written briefs. After Dark is a neighborhood coffee shop site for a business with no marketing team, briefed to feel like the room — dark, warm, unhurried — with menu, hours, and atmosphere shipped as production HTML. Modena Coupé is a luxury automotive landing page in an editorial register with full-bleed photography, serif display type, performance stats, and a request-information flow. MicroProject is a working task manager UI for small teams with list views, a project sidebar, shared lists, and overdue states, built on directly by the team. Geisha Porto is a coffee roastery and jazz listening lounge site with a product catalog including harvest data, a vinyl audio archive, and a rooftop terrace section in a Swiss editorial layout. The site notes that the business names and brands shown are illustrative and are not clients or endorsements. The stated brief types are landing pages, product dashboards, design systems, and pitch decks. PixelCrew is free while in alpha. You bring your own key: you create a key at openrouter.ai, paste it into PixelCrew once, and set your own spend limit. OpenRouter is the recommended path, and Anthropic and Google Gemini keys work too. A typical brief costs a few dollars in model usage, billed by your key provider rather than by PixelCrew, with no subscription, no markup, and no card on file. The alpha plan includes the full agent crew, unlimited briefs during alpha, HTML and Tailwind output, and support for landing pages, dashboards, and design systems. A Pro plan is coming soon with hosted keys, zero setup, no API key required, model costs included in one bill, a priority processing queue, brief history and versioning, and team seats. An Enterprise tier for teams that ship at scale is described with custom agent configuration, your design system baked in, SSO and security review, and invoice billing. PixelCrew's core value proposition is that a written brief becomes a production-quality deliverable in minutes, produced by a crew of specialized agents that research, decide, build, and review in sequence. You get production-ready HTML and Tailwind, a complete design system, and documentation you can hand to any developer, without templates, without a subscription during alpha, and without paying a markup on model usage.

Keet is a personal learning platform that describes itself as an app to generate courses on any topic. Rather than offering a fixed catalog of pre-recorded classes, it produces personalized, interactive courses that combine short explainer videos with Duolingo-style games and quizzes. Each generated course comes with a structured roadmap, so learners move through bite-sized lessons and build towards real understanding instead of jumping between disconnected resources. The product is backed by Y Combinator and is available as a download for iOS, where users create an account and start building courses on subjects ranging from mathematics and physics to history and engineering. Most online learning platforms ask you to choose from the catalog they already have. If the subject you care about is niche, such as the history of San Francisco, Mongol war tactics or the mechanics of modern rocket engines, the material you want may not exist as a structured, interactive course at all, leaving learners to assemble scattered articles and videos on their own. Keet approaches the problem from the other direction: the topic comes first, and the course is generated around it. The site states that Keet is different from other learning apps because it lets you generate personalized, interactive courses on any topic that have a structured roadmap to follow. That combination of arbitrary subject matter plus a roadmap is the core of the product's promise, and it is why the platform frames itself as personal rather than catalog-based. Course creation starts with a topic. The website shows examples across several disciplines: Topology under Mathematics, Quantum Physics under Physics, Yankee Traders under History and Modern Rockets under Engineering, alongside cover art for The Big Bang, History of San Francisco, Mongol War Tactics and History of New York City. When you create a course, you can customize it: Keet lets you set the desired depth, complexity and narration style, so the same subject can be generated at different levels and delivered in the style you prefer. Getting started is described simply on the site: download Keet and create an account to start building personalized courses. Finished courses appear as cards with cover art, such as Introduction to Topology, History of San Francisco, Yankee Traders and Modern Rocket Engines. Each course generates with a set of lessons that contain videos and quizzes to help you learn. The videos are short explainer videos, and the lessons are deliberately brief. The sample Topology curriculum lists lessons such as Sets and Subsets, Limits of Visualizing Sets, Paradoxes and the Universal Set, Set Operations as Boolean Logic, Complements and Subtraction, Element-Chasing Proofs and The Empty Set and Vacuous Truth, each marked at around four minutes. The accompanying quizzes test what the video has just covered, so understanding is checked immediately rather than at the end of a long module. Watching a short explanation and then answering questions about it keeps the learner active, which is why the format pairs a video with testing at every step instead of separating teaching and assessment. Testing is delivered through games. Each lesson has several games that you can play to test your knowledge, and the site lists the formats available: Multiple Choice, Swipe, Order, Connections and Custom. Multiple Choice, for example, presents a question such as what the primary function of mitochondria in a cell is, offering options including protein synthesis, cell division, energy production through ATP synthesis and DNA replication, followed by a Check button to confirm the answer. Moving between formats, from swiping to ordering items to finding connections, turns review into something closer to Duolingo-style practice than a conventional quiz, which makes repetition more engaging and helps knowledge stick through varied recall. Courses have structured roadmaps, which are the backbone of how the material is organised. In the Topology example, the roadmap is divided into modules, and each module into lessons. Module 1, Abstract Set Theory, contains Lesson 1 Sets and Subsets, Lesson 2 Functions and Preimages, Lesson 3 Equivalence Relations and Lesson 4 Cardinality and Infinity. Module 2, Topological Spaces, covers Topological Spaces, Closed Sets and Closures and Topological Bases. Module 3, Continuity and Space Construction, includes Continuous Functions plus Subspace and Product Topologies. Module 4, Topological Properties, closes with Connectedness, Compactness and Hausdorff Spaces. Modules carry their own sticker artwork, and lessons list their individual topics and durations. The roadmap makes it easy to learn in bite-sized chunks, because each lesson is a small, finishable unit placed in a defined order that builds towards real understanding of the whole subject rather than offering isolated facts. Overall, Keet works in a generate-then-follow loop. You name a topic, adjust depth, complexity and narration style, and Keet generates a course: a set of lessons containing explainer videos and quizzes, grouped into modules that form a roadmap, with games attached to each lesson for practice. From there the experience is guided. The roadmap tells you what comes next, the video explains it, the quiz confirms it and the games reinforce it. Because the course is generated rather than curated from an existing library, the same mechanism applies whether the subject is a formal academic field like topology or a narrower historical topic. Access begins in the iOS app, where creating an account is the first step. For learners, the practical benefit is that the subject they actually want to study is the one they get a course about, with a structure that removes the guesswork of where to start and what to cover next. Lessons of roughly four minutes fit into spare moments, so progress does not require blocking out long study sessions. Quizzes and games provide immediate testing, which turns passive watching into active recall and gives fast feedback on what has been absorbed. Customisable depth, complexity and narration style mean the same topic can be matched to different levels of prior knowledge, so a beginner and a more advanced learner can generate different courses from the same subject and work at a pace and tone that suits them. The examples on the site hint at the range of use cases. A learner curious about mathematics can generate Introduction to Topology and work through abstract set theory, topological spaces, continuity and space construction, and topological properties in order. Someone interested in history can build courses such as History of San Francisco, History of New York City, Yankee Traders or Mongol War Tactics. A physics enthusiast can generate Quantum Physics, and an engineering-minded learner can study Modern Rockets or Modern Rocket Engines, or start from a topic like The Big Bang. In each case the workflow is the same: pick the topic, customise the course, then follow the roadmap lesson by lesson, watching explainer videos and playing the games that come with each lesson. Keet is positioned as a personal learning platform for anyone who wants to learn about a subject on demand, and the examples span academic disciplines, history and engineering, which suggests it is aimed at curious, self-directed learners rather than institutions. The product is downloaded for iOS, and iOS is the only platform named on the site, with the download linked to the App Store. Cost is described on the site in terms of credits rather than a subscription: if you sign up now you get two free courses, and after that you need to purchase credits to generate more courses. The site also notes that Keet is backed by Y Combinator. Keet's value proposition is straightforward: generate a personalized, interactive course on any topic, then learn it through short explainer videos, quizzes and Duolingo-style games arranged on a structured roadmap. It replaces the search for scattered material with a generated curriculum that is customisable in depth, complexity and narration style, and it makes progress tangible through modules, lessons and games. For learners who want a specific subject taught in a bite-sized, interactive format, from topology to the history of San Francisco, Keet offers to build the course on demand.
Hola AI is an AI voicemail app and AI call assistant that answers your missed calls, talks to callers naturally, filters spam, and sends you a clear summary in seconds. It is designed for busy professionals and anyone who cannot pick up every call but still wants to stay reachable. The product records and transcribes conversations, helps you understand why someone called, and gives you the context you need before calling back. Hola AI works with your existing number, so you do not need a new number; your unanswered calls are simply forwarded to Hola AI, which takes over when you cannot pick up. It is available as a mobile app on the App Store and Google Play, and it can send summaries via app, SMS, or email. Traditional voicemail is passive and robotic. It records every cold pitch, robocall, and telemarketer, leaving you to guess who called until you listen through minutes of static audio. As the website puts it, old voicemail “records everything and filters nothing.” That means important calls can be buried under junk, and you waste time replaying unclear audio just to find out whether a message matters. Hola AI was built to change that experience by being proactive and human: it listens and talks like a human, filters the noise, understands intent, and sends you only what is worth your attention. Instead of treating every call the same, it separates real opportunities from spam and gives you an actionable summary you can skim instantly. One core feature group is human-like call answering and automatic spam filtering. Hola AI answers calls like a human, even when your phone is off or in flight mode. It talks to your callers, understands why they called, and makes them feel heard instead of ignored. At the same time, it filters spam automatically, so you no longer waste time on robocalls or cold pitches. Hola AI filters out junk before it reaches you. This combination means you can stay reachable without picking up every call, and you only receive messages that are worth your attention. The comparison table on the website highlights that Hola AI talks like a human while traditional voicemail just records sound, and Hola AI filters junk automatically while traditional voicemail records spam too. Another feature group is instant summaries and call context. You get a concise summary of who called, why, and how important it is. This is actionable text rather than long audio, so you can understand the purpose of a call in seconds. Hola AI can send the summary via app, SMS, or email. It also captures intent and next steps, and it records and transcribes conversations. That means you can read why someone called and what they need before you decide whether to call back. Instead of replaying and guessing, you can skim and act instantly. For professionals who are in meetings, with clients, or otherwise unavailable, this makes it possible to triage calls quickly and respond to the most important ones first. Hola AI also offers multiple personalities and strong privacy controls. You can personalise how it responds and choose how it sounds: sharp for work, warm for friends, or witty with spam. This lets you match the tone to the caller and the context, so callers get an appropriate experience. On the privacy side, all recordings and transcripts are encrypted and stored safely. The website states that recordings and transcripts stay encrypted end-to-end, and you have full control: you can delete any call or wipe everything anytime from the app. Hola AI also works with your existing number. You do not need a new number; your unanswered calls are simply forwarded to Hola AI, which takes over when you cannot pick up. The overall approach is to upgrade voicemail from a passive recording system into an active AI call assistant. When you cannot answer, Hola AI answers like a human, even when your phone is off or in flight mode. It talks to your callers, understands why they called, filters spam, and sends you a short summary via app, SMS, or email. The website’s comparison table contrasts this with traditional voicemail across several dimensions: how it responds, spam filtering, what you receive, tone and personality, your effort, availability, and call context. Hola AI responds by talking like a human; it filters junk automatically; it sends a short text summary; it offers customisable tone based on caller; it lets you skim and act instantly; it works in flight mode or when the phone is off; and it captures intent and next steps. This methodology is what allows Hola AI to be proactive instead of passive. The benefits for users are directly tied to staying reachable without picking up every call. You can skip spam and still catch every opportunity. You never miss an important call again, because Hola AI handles the greeting and sends you a summary instantly. You avoid replaying long, unclear audio and instead get a short summary you can read in seconds. You can filter out robocalls and cold pitches automatically, so your time is spent on real conversations. You can personalise the tone so work calls, friends, and spam are handled differently. You get privacy and security through end-to-end encryption and the ability to delete recordings or transcripts at any time. And because Hola AI works even when your phone is off or in flight mode, your availability is no longer limited by whether your phone is on. Real-world use cases appear throughout the website. A legal partner used to miss urgent calls when in court; now Hola AI handles the greeting and sends a text summary instantly, which the user calls a life-saver. A freelance creative uses the “Witty” personality for spam; it wastes telemarketers’ time while the user focuses on work. A real estate agent showing houses cannot talk, so Hola AI asks the right questions, and the agent can see exactly who is a serious lead by reading the summary. More broadly, Hola AI is for anyone who wants to skip spam and catch opportunities, for people whose phone is off or in flight mode, and for users who want to keep their existing number and simply forward unanswered calls. It also works as an AI call assistant that handles calls for you when you want more than voicemail. Hola AI is trusted by busy professionals, including legal partners, freelance creatives, and real estate agents, according to the testimonials on the website. It is available as an app on the App Store and Google Play, and summaries can arrive via app, SMS, or email. The product works with your existing number, so no new number is required. The website footer notes that it is powered by ElevenLabs Grants. Pricing is subscription-based: new customers get a limited-time 50% off offer at $4.99 per month for the first 6 months, then $9.99 per month. The site also mentions saving 17% more annually, and you can cancel anytime. The offer is described as limited-time, and the website encourages users to install the app, connect their number, and watch it in action. In summary, Hola AI replaces old, passive voicemail with a proactive AI voicemail assistant that answers calls, filters spam, and sends instant summaries. Its primary value proposition is that you never miss an important call again while avoiding the time waste of robocalls, cold pitches, and long audio messages. By talking to callers naturally, capturing context, and delivering actionable text summaries, Hola AI helps busy professionals stay reachable on their own terms, with privacy controls and an existing-number setup that make it easy to adopt.
Fez is a desktop app for Mac where several AI agents work together as members of one workspace, and the room itself does the managing. Each agent is its own member with its own identity, model and skills, and rather than switching between separate assistants you talk in a channel. The room decides who takes a message, whether the work is done, and whether you need to read the reply at all. It is an early-stage app for macOS on Apple silicon, MIT licensed, built on nostr and on Jev, a judgment model created by TypeSafe. Fez is aimed at people who want a team of agents to behave like teammates in a shared room rather than like tools waiting to be dispatched. Most agent apps give you one assistant. Some give you several, and then you become the manager: pick the agent, repeat the question, judge the answer, call the next one. That management work — routing, checking, and deciding whether a message even deserves a response — is exactly the overhead that makes multi-agent setups tiring. Fez takes that job away from the user and hands it to the room. Instead of you choosing which agent should respond, the room reads the message and picks the agent, or nobody. Instead of you checking whether the answer is complete, the room checks it against what you asked. Instead of you deciding whether a thanks needs a full reply, the room decides, and a thanks gets a reaction rather than a paragraph, with no turn and no cost. The routing engine is a judgment model called Jev, built by TypeSafe. Every message in a Fez channel goes to Jev. It does not write; it decides. For each message it produces a calibrated probability in under a second and at a fraction of a cent, which means chat models only run when there is real work to do. The app's own demo surfaces three sequential judgments: who takes it (a probability of 0.95 in the example, with the room picking the agent or nobody), is it done (0.94, where the answer is checked against what you asked and signed off silently), and does it need a reply (0.08, where a small acknowledgement is enough). Fez published routing results from one pass with three agents against frozen fixtures: 96 of 97 routed to the right agent, a 184 ms median decision, and $0.002 for the whole run — figures the app explicitly notes are not a universal guarantee. The roster is where the agents live. Fez ships with @fez, the guide, described as docile and helpful: it knows its way around, and when you mention @fez in a channel it brings in the teammate the work belongs to. The published roster also lists @drift and @quill. Each agent is its own member with its own identity, its own model, and its own skills, so a channel can hold several agents at once without them collapsing into one voice. The recorded demo follows two agents, two models, two keys and one thread over seven minutes. Because each agent is a member with a distinct identity rather than an option in a dropdown, the conversation reads like a room with participants who have their own lanes. Identity in Fez is not an account. On first launch the app generates a keypair, and every agent has one too. Every message is signed by the key that posted it, and because nobody issued the keys, nobody can suspend them. Everything lives on a nostr relay rather than inside the app: you can run one on your laptop or on a server, and Fez is simply a window onto it. The relay, not the client, keeps the record — the app sums up the interaction model as mentioning an agent with @, pressing Enter to have it answer, and pressing Esc while the relay remembers. Fez's approach is to make the room, not the user, the manager. A message arrives, Jev judges it, and based on that judgment the room either assigns it to an agent, marks it done, downgrades it to a reaction, or lets it pass. Chat models are invoked only when the judgment says there is work worth doing, which keeps cost and latency down. The app frames this as three questions asked in sequence: who takes it, is it done, and does it need a reply. The guide agent @fez sits at the front door, so a question can be asked of @fez and the work is handed to whichever teammate owns it. Underneath, keys and signed messages keep authorship clear, and the nostr relay keeps the record outside the app. For users, the benefit is that multi-agent work stops requiring a human dispatcher. You no longer have to pick the agent, repeat the question, judge the answer and call the next one, because the room handles routing, verification and the decision about whether a reply is warranted. Serving the judgment from Jev keeps decisions under a second and at a fraction of a cent, so lightweight messages don't need to spin up a chat model. And because identity is a self-generated keypair stored against a relay you can host yourself, there is no account to create and no central party who can suspend your identity. Concrete use cases follow the app's own framing. You ask a question in a channel and let the room decide which agent, if any, should take it. You mention @fez and it brings in the right teammate for the work. You run several agents with different models in one thread, as in the recorded demo of two agents, two models and two keys in seven minutes. You send a low-stakes message such as a thank-you, and the room answers with a reaction instead of spending a turn. You self-host a nostr relay on a laptop or a server and use Fez as the window onto that shared conversation record. Fez is a Mac app for Apple silicon, downloaded as fez-macos-arm64.dmg from its GitHub releases. It is released under the MIT license with all code on GitHub, and the project tags itself as Mac, open source and artificial intelligence, built on nostr and Jev. Updates are distributed as new releases with notes on what changed. There is no stated pricing beyond the free download of an MIT-licensed app, and no account system — the only setup is a keypair generated on first launch and a nostr relay to point at. The audience the content speaks to is people who want to keep their agent conversations in a shared room on infrastructure they control rather than on a hosted account. Fez's core idea is simple and specific: agents belong in a room, and the room should do the managing. By routing messages through a fast, cheap judgment model, checking whether work is done, and deciding whether a reply is even needed, it removes the dispatcher role from the user. With keypair identities, signed messages and nostr relay storage, the whole conversation stays legible and portable — a chat room where a team of agents works, and the room does the managing.
WeWeb MCP is a Model Context Protocol integration that connects the AI agent you already use to WeWeb, a visual no-code app builder. Point Claude Code, Cursor, Codex, Antigravity, ChatGPT, or any MCP-compatible agent at WeWeb and it builds the pages, workflows, data models, tables, auth, and integrations for a real WeWeb project. It is designed for teams and builders who want AI speed while staying in control: the agent runs on your account, your model, and your tokens, and every change it makes lands in a visual editor you can review and edit yourself. The tool turns briefs, designs, and app logic into a working project, and it uses no WeWeb credits. Agentic development, often described as vibe coding, can produce applications quickly, but it frequently leaves builders unsure about what actually changed inside their app. WeWeb MCP is positioned against that black-box experience. The product page promises the speed of vibe coding without the mystery of what changed, and it argues that moving fast should not create maintenance debt for a team or for your future self. Instead of generating an opaque codebase, the agent writes into a structured WeWeb project where every page, workflow, data model, and integration stays visible in a visual editor. That combination of AI generation and visual review is the core problem the product addresses. Any MCP-compatible agent can be connected, and the product page highlights several specific clients. Claude Code can plan and build in WeWeb using Claude's reasoning. Codex turns GPT-powered build plans into WeWeb apps. Antigravity builds with Gemini and Google models inside WeWeb, while Cursor lets you use Cursor's agent and your model of choice. ChatGPT is also listed as a supported agent. Because the integration runs on your account, your model, and your tokens, you are not locked into a vendor-supplied model, and the documentation link provided on the page covers installation of WeWeb MCP. The AI client section presents these agents side by side, emphasizing that you connect the agent you already use rather than adopting a new one. Getting started follows three documented steps. First, you add the server configuration to your MCP client settings, pasting a small JSON block that defines a weweb-ai server and runs it through npx with mcp-remote pointing at the WeWeb MCP endpoint. Second, you sign in to WeWeb and authorize access so the agent can call tools on your project. Third, you pick your project and build: you ask your agent to list workspaces and projects, switch to the right one, and then describe what you want. The page gives an example prompt asking the agent to list WeWeb workspaces, switch to a project, and help build a dashboard page. Control is a first-class part of the product. You decide how much of the app the AI can touch, letting the agent work across the full project or keeping it focused on one specific page, workflow, database, or design-system task. You also control what happens next: you review the agent's output inside WeWeb and then either keep prompting or edit the result yourself in the visual editor. This scoping means an agent can be granted broad access for large build-outs or narrow access when you only want a single change, and the review step keeps a human in the loop before changes are accepted. To avoid the generic AI look, including what the page calls purple gradients, WeWeb MCP lets you give the agent your visual rules before it builds. You can import the design rules that define your brand's design DNA from Figma, Google Stitch, Claude Design, or design.md into WeWeb. From there, you create a component system using shadcn, React references, or custom coded components to build reusable blocks with no-code properties. Starting from a brand design system means generated screens inherit your existing palette, components, and conventions rather than default styling, which reduces rework after generation and keeps output consistent with what your team already ships. The PRD to app workflow shows how product intent becomes a structured application. The agent reads a brief and moves from user journeys to screens, creating the pages, forms, states, and flows users need. It then moves from data to backend structure, mapping the database, fields, relationships, auth, storage, and backend workflows behind the app. Finally, it moves from business rules to integrations, where Slack alerts, email triggers, CRM updates, API calls, and approval flows become part of how the app works. Crucially, the first version is not the final word: you can keep working with your agent or open the visual editor to inspect, adjust, and shape the app yourself after generation. WeWeb MCP also works across a broader MCP stack. You can pair WeWeb with a backend MCP such as Xano, Supabase, or Airtable MCP, or with any APIs, to build the WeWeb frontend in context or bring data into the WeWeb backend. Product context can be turned into screens using docs, transcripts, websites, Figma files, or media assets to create onboarding, dashboards, and forms. A separate refactor workflow helps teams move fast without maintenance debt: the agent can find unused variables, outdated workflows, test components, and leftover build artifacts, and it can standardize naming across pages, components, workflows, API requests, tables, and fields. When the app is ready, WeWeb MCP supports going live on your terms. You can deploy in one click and launch on your custom domain while WeWeb handles hosting and infrastructure, or you can export the code and self-host it on your own infrastructure when you need full control. The product is free to start, and the page offers both a sign-up to start for free and a way to request a demo. It is marketed as agentic development for teams that want AI speed and visual control, and the page notes it is trusted by Fortune 500 companies such as PwC, La Poste, L'Oreal, JLL, Qonto, Decathlon, Carrefour, and Biwaki by BNP Paribas. Users report benefits that extend beyond speed. A digital project manager at PwC says adopting WeWeb revolutionized how the organization approaches application development, empowering teams to deliver more innovative, secure, and compliant solutions faster and more effectively. The CEO of Shunpo notes that no-code does not mean low-performance and that WeWeb makes it possible to build bigger things that were not possible with other tools. A CEO of ALOE Digital Solutions describes the platform as powerful, versatile, and intuitive after trying many no and low-code app builders. Together these outcomes point to AI-assisted building that remains maintainable, reviewable, and owned by the team that created it. The primary value proposition of WeWeb MCP is straightforward: your AI agent builds the app while you stay in control. You bring the agent, the model, and the tokens; WeWeb provides the project structure and the visual editor where every generated page, workflow, data model, and integration can be reviewed and changed. Design system import, PRD-to-app generation, backend MCP pairing, refactoring, and flexible deployment make the workflow useful from first prototype through launch. Because nothing is a black box, teams can adopt agentic development without giving up visibility, editability, or ownership of the applications they ship.
PostSider is a social media publishing platform built for both humans and AI agents. It lets you schedule and publish content across more than 30 networks from a single calendar, or hand the keys to an AI agent that drafts, schedules and publishes on your behalf through MCP, a REST API or SDKs. The platform combines a drag-and-drop content calendar, a media library, analytics, team seats and approvals, agent access and automation in one place, so users do not have to juggle multiple tools to run their social presence. PostSider describes itself as being for agentic builders and their AI agents, solo founders and creators, and agencies running many brands and channels at once, plus everyone who wants to publish their content a different way. The problem PostSider addresses is that publishing to social media usually means opening each network separately, or stitching together per-platform integrations in code. PostSider's own positioning is that scheduling and publishing across more than 30 networks happens from one calendar, and that connecting an agent requires no per-platform glue code; the site uses the phrases "no glue code" and "no per-platform glue code, ever." It frames the choice as four ways to publish: the dashboard, the API, the SDK and MCP. For teams used to per-channel billing, the FAQ contrasts PostSider's flat tiers with per-channel pricing, noting that adding another network costs nothing until you cross a tier, which it says is usually cheaper than per-channel pricing beyond four channels. For people working by hand, PostSider centres on a drag-and-drop calendar that the site describes as "a calendar you actually enjoy." Users plan a whole month at a glance, drag posts across days and channels, duplicate a post to another network, and let the queue publish. The listed capabilities include drag and drop across days and channels, composing once and tailoring per platform, a media library with live previews, and queues with best-time scheduling. A "this week" view shows slots such as Monday on X at 9:00, Tuesday on Instagram at 12:00 and Facebook at 17:00, Wednesday and Thursday on LinkedIn at 8:30 and Friday on YouTube at 15:00. For agents, PostSider provides what it calls an agent bridge built on MCP. The bridge exposes publishing and analytics as tools that any MCP agent can call, so an agent can draft, schedule and publish. The site lists Claude, ChatGPT/Codex, Gemini, Cursor, OpenClaw, Hermes Agent and "+ any MCP agent" as compatible. Alongside this, typed REST API clients and SDKs let developers call the platform directly from their own pipelines. The same secure authentication is used for humans and agents, and one integration is meant to cover every network. The site documents 60 API requests per minute. PostSider says it supports more than 30 networks and that new networks are added all the time. Named on the page are X, Instagram, Facebook, LinkedIn, Bluesky, Mastodon, Lemmy, Farcaster, Nostr, YouTube, TikTok, Twitch, Discord, Telegram, Slack, WordPress, Medium, Dev.to, Hashnode, Ghost, Blogger, Write.as, Notion, Mataroa, Listmonk, Pinterest, Dribbble, Google Business, Whop and Moltbook. The stated approach is to publish the same content everywhere or fine-tune per channel, with one payload going to every network and tailoring per platform applied automatically. Analytics track reach and performance across every channel in one view, with advanced analytics and automated queues and sets on higher plans. On security, PostSider says it treats access like infrastructure. Every channel token is encrypted at rest with AES-256-GCM, requests are hardened and validated against SSRF and CSRF, rate limiting provides abuse and overage protection, and tokens are isolated per channel with least-privilege access. The same hardened core is said to protect humans and agents alike. Getting started is described as a three-step process. First, connect your channels: link 30+ networks in a click, with tokens encrypted and isolated per channel. Second, create it yourself or let your agent: compose in the editor, or let your MCP agent draft posts and fill the queue. Third, schedule and publish on autopilot: pick times or use best-time queues, and PostSider publishes everywhere for you. The site promises you can be "live in minutes," whether you publish yourself or hand the work to an agent. The benefits the site claims follow directly from that structure: one calendar instead of many tools, four ways to publish (dashboard, API, SDK, MCP), a single integration covering every network rather than per-platform glue code, and the ability to publish yourself or let an agent take the wheel. For teams, unlimited team members on the Team plan and above, approval workflows and multi-user roles mean publishing can be shared and reviewed without leaving the platform. Because the same authentication serves humans and agents, an agent can take on the same work a person would do in the calendar. Concrete workflows are shown on the site. In one example, Claude, connected via PostSider MCP, is given a photo and the instruction "Create me a post for Instagram with this photo"; the agent replies that it drafted the post with the photo and queued it for Tuesday at 12:00. Another workflow is a creator planning a whole month at a glance, dragging posts between days and channels and letting queues publish. Agencies use approvals, seats and shared queues across many brands and channels. Developers call the typed REST API and SDKs from their own pipelines at a documented 60 requests per minute. And teams switching tools connect their channels to PostSider in parallel, rebuild their posting slots, bring their queue over manually or via CSV import, run both tools for one overlap week, then cancel the old one. PostSider states plainly who it is for: agentic builders and their AI agents; creators, including solo founders; and agencies running many brands and channels at once with approvals, seats and shared queues, plus everyone who wants to publish their content a different way. Plans start with a 7-day full trial and no credit card. Standard is $20/month for 1 seat, 5 channels and 400 posts per month; Team is $35/month for unlimited team members, 10 channels and unlimited posts; Pro is $45/month for 30 channels with an AI post checker and rewrite, auto-plugs and first comments, CSV bulk import, snippets and templates, webhooks, priority publishing and an audit log; Ultimate is $90/month for 100 channels, custom OAuth apps and priority support. Every plan includes the calendar, the agent bridge and the API. The site also addresses switching: users coming from Buffer or Hootsuite can connect channels to PostSider in parallel, rebuild posting slots, bring their queue over manually or via CSV import, run both tools for one overlap week and then cancel the old one. Alongside the product, PostSider publishes free browser tools, including best time to post, a hashtag counter, a bio link preview, an image size cheat sheet, an engagement rate calculator and a fancy text generator, plus a blog published weekly. PostSider is built by one person, Lukasz Blania, a solo founder building from Poland under Lumi Zone, and support emails land with the person who wrote the code. In short, PostSider is a social media scheduling platform where the calendar serves humans and the MCP server, REST API and SDKs serve agents. It covers 30+ networks from one calendar, adds analytics, approvals and team seats, encrypts channel tokens with AES-256-GCM, and uses flat monthly pricing rather than per-channel billing. Whether you plan to publish yourself or let an agent draft and queue the work, the promise is the same: run your social media on autopilot from one place.
Simha Digital is an AI-powered SEO analytics workspace that brings all of a project's SEO together — Google Search Console, Google Analytics 4, PageSpeed Insights, Chrome UX Report and a site crawl — and turns it into a plan of what to fix first. It covers six or more data sources in one workspace, eight audit categories and more than sixty rules, and adds a check of how visible a site is in AI answers. Its stated purpose is clear insights, real strategy and sustainable growth, and its positioning is that it tells you what to fix, not just what is wrong. Most SEO tooling surfaces problems and leaves the prioritisation to the person reading the report. Simha Digital frames the problem differently: SEO data is scattered across Search Console, Analytics 4, PageSpeed, real-user Chrome UX data and crawls, and the real question is which of hundreds of issues actually matters for traffic. The site also points to a second shift: search is moving into ChatGPT, Perplexity and Google AI Overviews, so being found, read and quoted by AI engines is becoming part of SEO. Simha Digital's answer is to combine the classic data sources with AI-search checks, give the site one score, order the work by traffic at stake, and explain what changed and why — including whether ChatGPT-style answers cite your site, and who gets cited instead. The workspace starts with site health and priorities: one 0–100 score for the whole site and a task list ordered by impact, so the first item on the list is the thing that should grow traffic most. Technical audit by template then crawls the site and groups hundreds of issues into a handful of root causes — duplicate titles, missing H1s, broken links, canonicals — with the affected URLs listed for each and a fix attached. Instead of working through issue-by-issue lists, the audit is organised by template, so a root cause shared by many pages is handled once. The site states eight audit categories and sixty-plus rules behind this, and the interface preview shows an example SEO health score of 86/100 alongside site health and priorities, technical audit by template, and speed and Core Web Vitals panels. Speed and Core Web Vitals use PageSpeed plus real-user Chrome UX data for key pages, covering LCP, CLS and INP along with what slows them down — a way to see both lab and field performance rather than one number. Growth points and revenue add a commercial layer: queries that are one push away from page one, plus leads and revenue from organic search pulled from Analytics 4, so you can see whether SEO pays off rather than only whether rankings moved. A large part of the product is AI search — GEO and AEO. Readiness for AI engines (GEO) asks whether AI crawlers are allowed in, whether there is an llms.txt, and whether pages have structured data, clear headings and answers an engine can quote, producing a 0–100 readiness score with concrete fixes per page. The checks listed include crawler access for GPTBot, ClaudeBot, PerplexityBot, Google-Extended and more, llms.txt, schema.org markup, FAQ and author signals, and quotable content such as answer-first paragraphs, tables and definitions. Visibility in AI answers (AEO) goes further and tracks how often your site appears in AI Overviews and AI Mode, impressions and clicks from those surfaces, the queries where you appear and the ones where you do not, an AI-visibility trend per query, and where competitors are cited instead of you — updated as new data comes in. The output side of the workspace is a report and plan written by AI: a rebuildable snapshot for any period, including problems, solutions, growth points and a detailed AI summary of what changed and why. Alongside it runs an AI assistant, available 24/7 on your own data, which you can ask why traffic dropped or which queries are the easiest wins — it answers from your own audit, queries and traffic rather than from generic advice. The overall workflow is described in three steps: connect your website by adding your domain and connecting your data sources; see what matters by running an audit and discovering opportunities; then take the next step by setting priorities and working with the AI assistant. What the product presents as its distinctive approach is that GEO and AEO findings land in the same plan as everything else, prioritised by traffic at stake — no separate tool and no separate report for AI search. The stated outcomes are faster decisions and visible growth: a single health score to track, a prioritised list instead of an issue backlog, and an explanation of changes so you know why numbers moved. Because AI-search readiness and AI-answer visibility feed the same plan, the work needed to be read and cited by AI engines is ranked next to technical and content fixes rather than treated as a separate project. Concrete scenarios described or shown on the site include connecting Search Console and Analytics 4 for a site and running a crawl to get one health score; using the template-level audit to clear duplicate titles, missing H1s, broken links and canonical problems across many URLs at once; checking Core Web Vitals for key pages using PageSpeed and real-user data; auditing crawler access, llms.txt, schema and quotable content per page to improve GEO; monitoring AI Overviews and AI Mode for the queries where you appear and where competitors are cited instead; asking the assistant why traffic dropped; and reviewing a rebuildable AI-written report of problems, solutions and growth points for a chosen period. Plans are three: Starter at $19.90 per month for up to 5 projects with a 7-day free trial, Pro at $39.90 per month for up to 10 projects, and Turbo at $79.90 per month for 20 projects, then $3.59 per project. Every plan lists the same core capabilities — all data sources and audit, Core Web Vitals and priorities, the AI project assistant and unlimited checks — and you can cancel anytime. Project limits suggest the workspace is used by people running SEO across several sites, from validating an idea through to growing traffic. In short, Simha Digital packages SEO data collection, technical auditing, Core Web Vitals, AI-search readiness and AI-answer visibility into one workspace, then converts all of it into a single score, a plan ordered by impact, and an AI assistant that answers questions from your own data — so the question shifts from what is wrong to what to fix first.
Milliseconds.ai is an API that turns text and images into decisions. You send text or an image, and the platform returns labels, fields, scores, or yes/no answers as structured data. The product is built around a small model the team calls decision-machine-1, and it is designed specifically for the parts of an application that need an answer rather than a conversation. The company describes the service as delivering "AI decisions, classification and extraction via a simple API." It is available through REST endpoints, SDKs, and a CLI, so developers can call it from TypeScript, Python, or the terminal and receive typed responses. Typical jobs described on the site include routing emails, reading invoice fields, and checking returns against a policy, as well as more playful applications such as building a hot-dog identification empire. The landing page frames the product with the line "Small model. Big decisions." and the supporting idea "Enough words. Try it, stat!" — the emphasis being on delivering the decision itself rather than a long piece of generated prose. The problem Milliseconds.ai addresses is the gap between general language models and the small, concrete decisions applications need to make on every request. The website contrasts a typical verbose model reply — "Certainly! Let's delve into a comprehensive overview of this invoice and its many fascinating details…" — with what a system actually needs: just the fields, invoice number, vendor, total, and currency, ready for the next step. The product exists for "the parts of your app that need an answer," where the goal is not open-ended conversation but a label, a score, a boolean, or a set of validated fields. The framing "Less blah. More done." captures this directly: instead of parsing free-form text after the fact, an application can receive structured data it can immediately act on. This matters because routing, prioritization, validation, and record writing all depend on machine-readable outputs rather than paragraphs of explanation. The site summarizes this as "Very small decisions. Very real work." The platform exposes a set of purpose-built decision endpoints. The yes/no endpoint answers a boolean question about a piece of text — for example, flagging messages that need a faster response — and returns both the boolean answer and a probability of urgency, so an application can raise a ticket's priority. The classify endpoint assigns a label from a set of choices: given support queues, it can return a label such as "billing" along with a probability (0.74 in the recorded example) and a confidence value, plus scores for the other candidate labels such as shipping, technical, and other. The rate endpoint turns subjective input like customer frustration into a sortable score on a defined scale; the example returns a reported score of 1.998 on a 0–3 scale, a level, a confidence figure, and per-level scores across calm, annoyed, angry, and furious. The answer endpoint locates a specific span of text in response to a question — for example, finding the shipment destination in a status update — and returns the answer text together with a probability and start and end source offsets, so an application can show where the answer came from. Extraction and entity recognition form a second group of capabilities. The extract endpoint maps unstructured text to the fields in your records. In the recorded invoice example, it returns a structured object with invoice_number, vendor, total, and currency — four fields described as ready for validation before writing a record. The entities endpoint identifies people, organizations, and references in a document; the claim-note example returns four typed entities (a person name, an organization, a claim id, and a date), each with a type, the matched text, and a probability score, described on the site as "typed values for search and record matching." Together these endpoints cover two of the most common document-intake needs: pulling out defined fields, and recognizing the named things inside free text. A third capability is verification. The verify endpoint checks a proposed value against source text. In the documented example it compares a proposed deductible against policy text and returns matches: false with a probability of 0.00, because the source says $500 while the proposed value is $1,000, and it returns the found value ["$500"]. This lets a workflow confirm that a value is actually supported by the source document before it is accepted — the kind of check required in insurance or finance processes where an extracted number must be traceable back to the text it came from. Overall, the product follows a simple INPUT → DECISION → ACTION model. Text or an image goes in; the model produces a decision in the form of a label, a score, a boolean, a text span, a set of fields, or a list of entities; the application then acts on that structured output. Every response is designed to be consumed by code: boolean answers with probabilities, labels with probability and confidence, scores with per-level breakdowns, answers with source offsets, extracted fields as key-value data, and entities with type, text, and probability. The site notes that uncertainty is surfaced rather than hidden — for instance, "nearly tied levels signal uncertainty," so a queue-ranking system can keep that ambiguity visible. Developers integrate through REST endpoints, TypeScript or Python SDKs, or the CLI and receive typed responses. There is also a path for coding agents: installing skills that teach an agent which API to call and how to evaluate results. The benefits described on the site centre on speed, structure, and cost. Because the model is small and purpose-built, responses arrive as data rather than prose, removing the parsing step between a model call and an application action. Because outputs are structured and include probabilities and confidence, applications can make ranking, routing, and validation decisions with a stated level of certainty. Cost is a headline benefit: production usage is priced at $0.04 per million input tokens, with no charge for output tokens, and free test keys include 125M free input tokens per month with no card required. The website frames the economics as "Big ideas. Small bill." and repeats the free allowance as "Free free free — yours to build with." The site presents several concrete scenarios. Support triage combines the pieces: "A label selects the queue. A score sets priority. A boolean flags urgency." Document intake works as a pipeline: "Extract fields, check values against the source, then validate before writing a record." In the Invoice Desk demo, invoice text is turned into a vendor, invoice number, and total, which are then compared with the purchase order so a team can see what needs attention — the example record matches PO-208. In the Sales Intake demo, an inbound message is separated from support tickets and vendor pitches, given a suggested destination of Sales because it is a demo request with budget stated and a near-term start, and the budget, timing, and need are surfaced for follow-up. In the Private Share demo, names and emails are found in a transcript so personal details can be redacted while the bug report stays useful — detected details are reviewed before sharing, with a toggle between the original and the redacted version. Other stated examples include checking returns against a policy, routing emails, and identifying hot dogs. Milliseconds.ai is aimed at developers and teams building applications that need classification, extraction, and decisions at the point of request — the people who would otherwise wire a general-purpose model into a workflow and then parse its output. The website addresses them directly: "You bring the idea. Build something fast." Integration options explicitly named are the REST API, the TypeScript SDK, the Python SDK, the CLI, and skills for coding agents. Pricing is split between a free tier of 125M free input tokens per month on test keys with no card required, and production at $0.04 per million input tokens with output tokens free. Demos let visitors try working apps and inspect their results, token usage, and inference cost, and visitors can try requests on the site without an API key. In summary, Milliseconds.ai takes the small, repetitive decisions that applications make — is this urgent, which queue does this belong to, how frustrated is this customer, where is the shipment going, what are the invoice fields, who and what are mentioned here, does this value match the source — and returns them as structured, probability-bearing data through one fast API. The combination of a small purpose-built model, typed structured outputs, built-in verification, coding-agent skills, and a free tier with inexpensive production pricing is what the product offers to teams that need answers rather than conversation.
gr.Workflow is a visual, node-based AI pipeline builder built into Gradio. It lets you chain together Hugging Face Spaces, models, datasets, and your own Python functions on a drag-and-drop canvas. The simplest possible Workflow app is a single line of code: gr.Workflow().launch(). You then open the app, drag Spaces, models, and datasets from the sidebar onto the canvas, connect their ports, and hit Run. The guide describes gr.Workflow as already being a complete Gradio app that must be created at the top level and cannot be nested inside a gr.Blocks context. It is designed for people who want to assemble multi-step AI pipelines visually while keeping their own Python code available as callable nodes on the same canvas. Building an AI pipeline has traditionally meant writing glue code to move data between models and services, downloading weights, and rebuilding the entire pipeline whenever a better model appears. Gradio Workflow is presented as a way around that: pipelines are assembled from nodes on a visual canvas, intermediate inputs and outputs can be inspected, and better models can be swapped in without rebuilding the workflow. Because the nodes call hosted Spaces, models, and datasets, nothing has to be downloaded. The finished pipeline is not locked inside a private session either. It can be shared with a URL or run via a REST API, and its topology is stored in a portable workflow.json file that a coding agent can write or edit, which means workflows can also be created programmatically. On the canvas, a workflow is organized into three node collections, which the guide defines precisely. References are the inputs: uploaded files, editable text, and literal values. Operators are the processing steps: Spaces, models, datasets, and Python functions. Subjects are the outputs, the results being created. As you add, remove, or change nodes and edges, a workflow.json file is automatically created next to the Python script that created the Workflow; you can pass graph= if you want to save it somewhere else. That autosave behavior means the canvas and the file stay in sync without manual export. Node geometry is optional too: include x and y on every node to control how the graph is arranged the first time someone opens it, or leave them out and the canvas auto-arranges the layout instead. Your own Python code becomes part of the pipeline through bind=. Functions passed via bind= appear as callable nodes on the canvas, and Gradio inspects the function signature to auto-generate input and output ports. The guide gives the example of a summarize function that takes a string and returns a string; using a dictionary, for example bind={"My Summarizer": summarize}, gives the node an explicit name. Signature inference is intentionally simple. Parameters annotated as int or float become number ports, bool becomes boolean, and strings, unannotated parameters, and other annotations default to text. Gradio initially generates one output port for each bound function, and any media ports or multiple outputs must be defined explicitly in the workflow JSON. Bound functions can also be wired together in code with edges, a list of (from_fn, to_fn) tuples referring to functions in bind=, using fn_name.port_label to target a specific port when a node has multiple inputs or outputs. The guide notes that edges= only connects bound Python functions while generating a new workflow: it cannot create edges to Space, model, or dataset nodes, it is ignored when the workflow file already exists, and the file must be deleted to regenerate the initial topology. Workflows can also be loaded from disk. Passing a graph= path such as graph="workflow.json" loads a saved workflow topology; the canvas reads from that file on each page load and autosaves back to it whenever nodes or edges change, and if the file does not exist yet it is created on the first authorized edit. The guide is explicit that bind= does not automatically add or wire functions into an existing graph: to combine an existing graph with bound functions you either add the functions from the canvas Functions menu, or include an operator with "kind": "fn" whose "fn" value exactly matches a key passed through bind=. Layout remains flexible for viewers: the file's arrangement is only a starting point, each visitor is free to drag and resize cards, that arrangement is saved in the visitor's own browser rather than in the file, and workflow.json is never rewritten with it. Height is measured from the rendered card, and width is the default every viewer starts from, with a writer's resize becoming the new default the next time an edit is saved. Under the hood, the workflow JSON defines a schema_version, a name, the three node collections, and a list of edges that connect node IDs and port IDs with a stated type. Operators come in four kinds. A space node calls a Gradio Space on the Hub via gradio_client, configured with space_id and endpoint. A model node calls a Hugging Face model via InferenceClient, configured with model_id and a supported endpoint such as text_to_image, while pipeline_tag is also stored for discovery and compatibility with older graphs. A dataset node pulls one row from a Hub dataset per run, selected by the row_index input, configured with dataset_id, dataset_config, and dataset_split. An fn node calls a Python function whose fn value matches a key passed via bind=. Ports are typed so the canvas can validate connections, with support for image, audio, video, text, number, boolean, gallery, file, json, model3d, and any; any is a compatibility fallback that can connect to every port type, and file and any usually come from API schema inference rather than being offered as reference or subject templates in the canvas picker. Pipelines can also fan out: one reference can feed multiple operators simultaneously, and when you run the workflow in the interactive canvas, operators at the same dependency depth run in parallel. The guide adds that when the same workflow is invoked through its generated Gradio API, the server currently executes those branches sequentially. The benefits described in the guide follow directly from this design. Because nodes are wired on a canvas rather than buried in code, intermediate inputs and outputs can be inspected while a pipeline runs, which makes multi-step AI systems easier to debug and reason about. Because each operator is a separate node, a better model can be swapped in without rebuilding the workflow. Nothing needs to be downloaded, since the operators call hosted Spaces, models, and datasets. Shipping is flexible: share links and the ordinary local URL are run-only, while launch() also prints a private write-access URL for editing and saving the workflow, which the guide advises keeping private because edits affect the workflow seen by every visitor. Finally, the workflow.json file is both an autosave artifact and a programmable surface, so the same topology can be authored by hand, by a coding agent, or by bind= and edges= declarations in Python. The guide's fan-out example is a concrete, described workflow: a single product photo reference is fed into four FLUX Kontext branches, showing how one input can drive multiple image transforms at once. Text pipelines are demonstrated in the edges example, where a clean function that strips and lowercases text is wired into a tag function that prefixes the processed text. Model nodes such as black-forest-labs/FLUX.1-schnell with the text_to_image endpoint illustrate text-to-image generation inside a workflow, while dataset nodes make it possible to run a pipeline over a specific row of a Hub dataset, controlled by row_index. Because the same app can be shared with a URL or invoked through a generated Gradio API, the guide frames Workflows both as an interactive canvas for building and inspecting a pipeline and as a deployable app that others can run without editing it. The product is aimed at people building AI pipelines in Python: the guide's code samples are Python throughout, and the canvas is an extension of the Gradio app that the function nodes live in. Integrations called out in the content are the Hugging Face ecosystem, including Spaces on the Hub through gradio_client, models through InferenceClient, and Hub datasets, together with your own Python functions and the generated Gradio API. The relevant technology stack therefore includes Python, Gradio itself, gradio_client, InferenceClient, and REST access to the running app. The guide positions gr.Workflow as part of Gradio's Additional Features, sitting alongside the library's other tutorials and guides, and it must be created at the top level as its own app. No pricing or plan details are stated in the material reviewed here. In short, gr.Workflow brings a visual, node-based editing experience to AI pipelines without taking developers out of Python. You drag Spaces, models, datasets, and your own functions onto a canvas, connect typed ports, and run the result as a Gradio app that can be shared with a URL or called through a REST API. The topology is portable in workflow.json, editable by hand or by a coding agent, and free of downloads because the heavy lifting happens on hosted Hugging Face resources. The primary value proposition is straightforward: build, inspect, and iterate on multi-step AI pipelines visually, and swap in better models without rebuilding the workflow.

Jev is a frontier model from TypeSafe AI's System One family that takes unstructured state as input and returns typed probabilistic decisions as output. Instead of generating text the way a conventional language model does, Jev answers with Choice, Score, and Noul results that carry calibrated probabilities your code can act on directly. That makes it a decision engine rather than a writing engine: the output is meant to be consumed by a program, not read by a person. The product is positioned for software automation, and it is described as being available to everyone at console.typesafe.ai with no waitlist. The problem Jev addresses is the mismatch between text generation and software decision-making. When an application needs an answer inside a code path, a generated paragraph of prose is not directly usable: something has to read it, interpret it, and convert it into something a program can branch on. That interpretation layer adds latency, cost, and ambiguity. Jev sidesteps it by returning typed answers and calibrated probabilities instead of text, so the result arrives in a shape that software can consume immediately. For teams already running comparable LLM workflows, the described gains are considerable: roughly 20-200x faster responses and 40-400x lower cost, with output tokens free. That combination matters most where decisions have to happen repeatedly, at volume, and inside automated systems where waiting on a text response is impractical. The core output formats named in the product description are Choice, Score, and Noul answers. These are the typed conclusions Jev returns in place of prose. A Choice answer is one of the explicitly named result types; a Score answer is another; and a Noul answer is the third. Because these results arrive as types rather than free-form sentences, the calling code does not have to guess at structure or parse language before it can use the result. This is the central design idea behind the product: the model's answer is already in a format that software automation can act on, so the integration between model and program is direct rather than mediated by an interpretation step. Alongside the typed answers, Jev returns calibrated probabilities. Calibration is what makes a probabilistic result useful in code: the probability attached to an answer is meant to reflect how likely that answer actually is, so a caller can use the probability rather than treating every model output as equally trustworthy. The description emphasises that these are probabilities your code can act on, which puts the decision about thresholds and behaviour in the application's hands. Instead of asking a language model a question and hoping the phrasing is stable enough to parse, a system can receive a typed answer with a probability attached and handle it programmatically as part of its normal logic. Performance comes from parallel sampling, the mechanism the description credits for Jev's response times of roughly 70-500ms. That latency band is the practical difference between a decision that can sit inside an interactive or high-throughput workflow and one that cannot. The same description quantifies the comparison against comparable LLM workflows: about 20-200x faster and 40-400x cheaper, with output tokens free. Those figures describe a different operating regime for the same class of decision task. Workloads that were previously constrained by per-call latency or per-token cost can be run more often, in more places, and closer to the moment the decision is actually needed. Overall, Jev's approach can be summarised as unstructured state in, typed probabilistic decisions out. It is a System One frontier model from TypeSafe AI, and the interface it offers is deliberately narrower than general text generation: it produces conclusions rather than commentary. That narrower contract is what allows the surrounding software to treat Jev as a component rather than a conversational partner. The model absorbs messy, unstructured input state and resolves it into one of the named answer forms, carrying a calibrated probability, delivered quickly enough and cheaply enough to be embedded in automated decision loops. The benefits described for users follow directly from those design choices. Speed means decisions can be made inside time-sensitive paths. Lower cost per decision means automation can be applied more broadly without the economics breaking down. Free output tokens remove a line item that scales with usage. Typed outputs with calibrated probabilities reduce the engineering work of interpreting model responses and make it practical to wire a decision directly into application logic. And availability without a waitlist means a team can evaluate the model by going to console.typesafe.ai and signing in rather than joining a queue. The use cases that follow from the description centre on software automation. Any workflow where a program needs to reach a decision from unstructured state and then act on that decision is a candidate: the caller supplies the state, Jev returns a typed Choice, Score, or Noul answer with a calibrated probability, and the surrounding code responds. The stated comparison class is comparable LLM workflows, which suggests the intended fit is where teams currently route decisions through a text-generating model and then interpret the output. Where a decision has to be made repeatedly at volume, the described latency and cost profile makes Jev a practical alternative to that pattern. Access is through the console at console.typesafe.ai, which is the official website for the product. The console supports signing in with Google, or alternatively requesting an email code instead of using a Google account, and continued use is governed by TypeSafe AI's terms of use and privacy policy. The target users are developers and engineering teams building software automation that depends on structured, probabilistic decisions rather than generated text. No pricing plan details, technology stack, or third-party integrations are stated in the available content. In summary, Jev is best understood as a decision model rather than a text model. It takes unstructured state and returns typed Choice, Score, and Noul answers with calibrated probabilities, uses parallel sampling to deliver responses in roughly 70-500ms, and is described as about 20-200x faster and 40-400x cheaper than comparable LLM workflows, with output tokens free. For software automation that needs decisions in a form code can act on, that combination of structure, calibration, speed, and cost is the primary value proposition.

slop-grader is a rule-based command line tool that evaluates documents against custom rulesets and produces document scores and line-by-line flags to guide auto-fixing with an AI agent. It is built for anyone who writes, edits, or reviews text and wants that work checked against an explicit, repeatable standard rather than a vague impression. The tool is open source, runs locally in a terminal, and is designed around the idea that you curate a ruleset for your own use case and then reuse it as a powerful way to grade text consistently. Rather than rewriting a document for you, slop-grader grades it, tells you which lines failed which rules, and hands off instructions that an AI agent can act on to produce sharper copy. The context behind slop-grader is the flood of AI-generated writing. Text produced quickly by large language models tends to be padded with filler, stacked with buzzwords, and vague about what it actually promises. Reviewing that text by hand is slow, subjective, and inconsistent: two readers can disagree about whether the same paragraph is clear, and nobody notices a slow drift in tone across a long document until a reader finally complains. slop-grader takes a different position by making each check explicit. Instead of asking whether a document reads well, you express what you care about as a rule, and the tool answers that rule for every line it reviews. The result is a score plus a list of specific lines that need attention, which makes the standard applied to a document visible and repeatable. The heart of the product is the ruleset. Rules are written in plain language and can be anything you are able to phrase as a question. Some rules are evaluated line by line, such as "Does this line make a promise that requires a legal disclaimer?" Others are evaluated across the entire document, such as "Does the opening earn the reader's next 30 seconds?" That flexibility means the same tool can cover very different jobs: SEO checks on a page, legal clause review, tone of address, or keeping a formal or informal register consistent. A concrete example given by the maker is German address: keeping "Du" versus "Sie" consistent throughout a document. Because rules are yours to define, words that are buzzwords in one industry but completely normal in another are handled by simply writing the rule that fits your use case. slop-grader also ships with built-in rules, so you do not have to start from nothing. The included checks cover English grammar, German grammar, and AI filler detection. The maker notes that once you have built a curated ruleset for your use case, the tool becomes very powerful, and there is a built-in skill in the repository for creating custom rules, published as a SKILL markdown file on GitHub. That skill is intended to help you author the plain-language rules your workflow needs, whether they concern promises and disclaimers, openings that hold attention, SEO conditions, legal clauses, or tone of address. The output format is deliberately practical. slop-grader produces document scores and a list of flagged lines together with instructions that you can paste directly into an AI agent to fix the document. The tool flags its outputs as prompts so that agents can draft the fixes. This matters because a line-level flag makes it much easier to see exactly what needs fixing instead of rewriting an entire document from scratch. One product detail worth knowing is that when a rule fires on a line, the tool does not explain why it thinks the rule was violated. The maker's suggested workaround is to create separate rules for each check; the AI agent receiving the output is then very good at inferring the underlying problem from the flagged lines. Under the hood, slop-grader runs on Jev, available at typesafe.ai, which is described as a new AI model that is different from an LLM. Jev is a so-called System One model specialized in answering structured questions. That specialization is what makes the rule-by-rule approach practical: every rule is matched against every line separately, and because of the model's design that evaluation stays both cheap and fast. Checking a document takes seconds and costs less than a cent. Because evaluation happens on a remote model, the maker notes that text is evaluated on an external AI server, which is a relevant consideration when you decide what to run through the tool. The practical benefits follow directly from that design. Grading is consistent because the same rules are applied to every document and every line, so the standard does not drift between reviewers or between sessions. Feedback is precise because it arrives as flagged lines rather than a general verdict, which narrows the editing work to the specific places that broke a rule. The pipeline is fast and inexpensive enough that running a full check on a document takes seconds and costs less than a cent, so it can be part of a regular workflow rather than an occasional deep review. And because the output is written as instructions for an agent, the handoff from "this line is wrong" to "here is a sharper version" is automated rather than manual. Day-to-day, the maker describes using slop-grader to catch AI filler in launch copy, to strip buzzwords from landing pages, and to score narrative flow in launch emails. Those examples show the range: launch copy is checked for filler, landing pages are checked for buzzword density, and launch emails are graded on whether the narrative flows. Beyond those, the ruleset model supports SEO checks on content, review of legal clauses and disclaimers, and tone-of-address enforcement such as keeping German "Du" versus "Sie" consistent across a document. In each case the workflow is the same: run the document through your ruleset, read the score and the flagged lines, then paste the flagged output and instructions into an AI agent so it can draft the fixes. Getting started has a few stated requirements. You need Node.js installed on your machine, and you need an account with either TypeSafe or OpenRouter, since the evaluation runs on Jev. The tool is open source and is distributed as a CLI, and it is listed as free. The project lives on GitHub, and the maker has also published a skill for creating custom rules in the repository. It was launched on Product Hunt and is categorized as a command line tool, with topics covering writing, advertising, artificial intelligence, and GitHub. Text is evaluated on an external AI server, which users should factor into what documents they submit. The takeaway is that slop-grader reframes text review as a linting problem for prose. By turning what you care about into plain-language questions, evaluating them line by line and document-wide with a fast, low-cost structured-question model, and emitting flagged lines alongside agent-ready instructions, it replaces subjective rewriting with a score, a precise list of problem lines, and a clear path to an automated fix.
AppGrowthKit is an AI screenshot maker for the Apple App Store and Google Play. It generates App Store and Google Play screenshot sets from your real app screens, combining AI layouts and copy, localization, app icons, and store-ready export inside one workspace. Built for indie developers and teams, its core product is an AI screenshot maker: you upload your app screens, add device frames, headlines, and backgrounds, or let AI draft the layouts and copy for you, and then export store-ready assets for your Apple App Store and Google Play listings. The product positions itself as the place where polished App Store screenshots are created in minutes rather than hours, without design experience and without moving between multiple tools. The problem AppGrowthKit addresses is the fragmented store-asset workflow. Preparing a listing traditionally means stitching together several separate tools: the product itself names Figma, Canva, Fastlane Frameit, and a separate caption document as the pieces developers commonly combine just to produce a single screenshot set, followed by manual resizing and reformatting for App Store Connect and Google Play Console. General design canvases such as Figma and Canva are not store-export products, and template tools such as AppLaunchpad leave you adapting a library of templates rather than working from your real app screens. AppScreens is described as stronger at console upload automation, and AppLaunchFlow as a wider launch suite covering ASO copy, video, rank tracking, and store connections. AppGrowthKit is positioned as the focused screenshot and icon workspace that replaces the store-asset handoff between those tools, so the last mile of a launch stops being a design project. The primary feature group is the AI screenshot workflow. You drop in raw app screens and tell AppGrowthKit what your product does; AI then plans the layout, writes store copy, and applies backgrounds, device frames, and spacing directly on your canvas. The workflow is split into three explicit actions. Plan lets AI draft the layout, headlines, and style before anything changes on your canvas, so you review the direction first. Build applies edits across all of your screens from one prompt, which keeps a multi-screen set visually consistent without editing every screen individually. Chat lets you ask for ideas or feedback without touching your design. Because the draft lands on your canvas rather than in a locked template, you stay in control: you can review the draft, edit anything, and export when it looks right. A second feature group is AI localization for editable screenshot sets. You choose a market and let AI translate and adapt your editable screenshot copy. The stated behaviour is that your layouts, real app screens, and layers stay exactly where you put them, so every locale starts from a working master rather than a rebuild. Adapt generates natural localized titles, subtitles, and custom text for each market. Preserve keeps your layout, images, and editable layers intact across versions. Review lets you fine-tune each version in the canvas before exporting the final set. AppGrowthKit covers 42 App Store locales: you design the English master, pick a market, let AI adapt titles and captions for that locale, and then export each set in the sizes Apple and Google require. A third feature group is app icon generation. You describe the feeling, subject, and style you want, and AppGrowthKit AI generates several app-icon directions at once so you can compare a real set of options before choosing the one that belongs beside your screenshots. Describe starts with a simple prompt, which you can enhance when you want more art direction. Explore generates one, two, or four icon directions in a single pass. Download keeps the winners and saves the generated icons when you are ready. The product also lists Apple-ready icon exports as part of the app icon feature set, and publishes a free app icon size generator alongside the core editor. A fourth feature group is the layer-based design editor that turns raw screens into store-ready visuals. You upload your app screenshots, add polished layouts, and prepare assets for every store, layering text, backgrounds, and device frames on one canvas. Layers let you organize screenshots, frames, text, and backgrounds in a single workspace. Properties let you tune fonts, colors, spacing, and sizing without leaving the editor. Preview shows you store-ready output before you export. Custom fonts and gradients are listed as part of the screenshot feature set, and the editor is described as Figma-like with no locked grid. Device frames are handled as a dedicated capability. AppGrowthKit ships frames for iPhone 17, iPhone Air, and Pro Max, with every device frame scaled and ready to use. You pick from the latest iPhone, iPad, and Android frames, choose a finish, drop in your screenshot, and keep moving. Devices are described as kept up to date, colors let you match the frame finish to your app's look, and scale means a dropped-in screenshot is sized correctly every time. You can also use your own screenshots with these frames and customize colors, text, and layout. The export capability closes the loop. You download all your screenshots at once in the exact format Apple and Google require, with no resizing, reformatting, or second tool. Formats are built in for Apple and Google specs. Batch export pulls every screen in your project at once. Ship means you can download and upload straight to App Store Connect or Play Console. AppGrowthKit supports the Apple App Store and Google Play and exports store-ready screenshots for iPhone, iPad, and Android apps. Overall, the methodology is prompt-and-canvas rather than template-and-export. The fastest described path is to upload raw captures once, generate an AI draft, edit the first three screens, and export App Store and Google Play sizes from the same project, replacing the combination of Figma, Canva, Fastlane Frameit, and a separate caption document. AI drafts the plan before anything changes, one prompt applies edits across all screens, and chat provides ideas or feedback without touching the design, so the developer remains the decision-maker. The product states plainly that it is built for developers, not designers, and that no design experience is required: you can arrange screens and text with the layer editor, or describe your app and let AI draft layouts and copy you can fine-tune before export. Beyond the editor, AppGrowthKit publishes free tools for the rest of a launch, including an app icon size generator, an ASO character counter, and live App Store charts. The outcomes described for users centre on speed and control. Screenshots move from hours to minutes; consistent sets are produced without hand-editing each screen; localized versions start from a working master so layouts do not need rebuilding per market; and exports arrive in the exact formats and dimensions Apple and Google require, removing manual resizing or reformatting in another tool. Users can see store-ready output in preview before exporting, and can use their own screenshots, device frames, colors, and text until the listing looks the way they want. Concrete use cases described in the content include preparing a single app launch with Launch Pass and deciding on a subscription afterwards; running repeated launches, ongoing work, and iteration on Pro with 750 AI credits per month; comparing one, two, or four AI-generated app icon directions before picking one to sit beside the screenshots; localizing an App Store screenshot set into other languages by designing an English master, picking a market, and letting AI adapt titles and captions while layouts and app screens stay in place; producing store-ready iOS and Android screenshots quickly by uploading raw captures once, generating an AI draft, editing the first three screens, and exporting both stores' sizes from the same project; and using Grok Bot for competitor research and first-draft captions while AppGrowthKit places those words onto real app screens with device frames, localization, and exact store exports. On plans and audience, AppGrowthKit targets indie developers and teams. Launch Pass is a $9.99 one-time purchase for a single launch with unlimited projects, unlimited store exports, 250 AI credits, and support included. Pro is described as $8.33 per month billed at $99.99 per year (a 44% saving) and elsewhere as $14.99 per month, for repeated launches, ongoing work, and iteration, with 750 AI credits per month, unlimited projects, unlimited store exports, and support included. Both plans cover AI localization for editable screenshot sets, the design editor with layers, all device frames and models, custom fonts and gradients, AI app icon generation, and Apple-ready icon exports. The editor is focused on App Store and Google Play screenshots today, and AppGrowthKit states that is where it does its best work. In summary, AppGrowthKit's value proposition is a single AI screenshot and icon workspace for App Store and Google Play listings: upload real app screens, let AI draft layouts, headlines, and localized copy on an editable canvas, and export every size Apple and Google require in one click, built for developers and teams who want polished store assets without design software, manual resizing, or templates to fight with.
Cronhq is a distributed cron scheduler that fires webhooks on a schedule. You point Cronhq at a webhook URL, and it calls it at the times you define, retries it when it fails, and pages you when something breaks — and again the moment it recovers. It is designed for developers and engineering teams who need scheduled tasks to run exactly once, even when more than one server or worker is running the same schedule. Rather than maintaining crontab entries by hand across machines, you create a job through the API or the dashboard, and Cronhq takes care of execution, retries, logging, and alerting. The product's own promise is simple and direct: cron jobs that actually run. The problem Cronhq addresses is that cron jobs fail in silence. If two servers run the same crontab, the same billing job can fire twice, which means duplicate charges or duplicate records. If a job dies, nobody notices for weeks, because a missing run produces no error message, no alert, and no trace — there is simply nothing to see. Standard crontabs provide no coordination between workers that could prevent double execution, no retry logic, no durable execution history, and no alerting when a run stops happening. Teams are left to write their own locking, their own backoff, and their own monitoring, or to accept that some scheduled work will quietly stop running. Cronhq is built around one guarantee — exactly-once execution, enforced by Postgres locks rather than best-effort behavior — and then wraps the surrounding operational needs, such as retries, signed webhook delivery, heartbeat monitoring, and deduplicated alerts, into the same system. Cronhq's first capability area covers the integrity and observability of the calls it makes. Every request Cronhq sends carries an X-Cronhq-Signature header, computed as an HMAC-SHA256 over timestamp.body, along with an X-Cronhq-Timestamp header. Each job gets its own secret, and you can rotate that secret at any time with no downtime, so a leaked key does not force you to tear down and recreate the job. On the receiving end, this lets you verify that a scheduled call genuinely came from Cronhq before acting on it, which matters for anything that touches money, data, or infrastructure. Running alongside that is the heartbeat monitor: you ping a URL on every run, and if the expected window — the period plus a grace interval — is missed, Cronhq flips the monitor to DOWN and pages you once. Cronhq describes this as cron's inverse: proof of absence rather than proof of presence. The second capability group is about managing schedules as part of your codebase rather than as clicks in a UI. The Cronhq CLI installs with npm i -g cronhq, or runs directly with npx cronhq --help. Running npx cronhq sync reconciles a cronhq.yaml file in your repository — it creates, updates, and prunes jobs so your schedules live in version control and move through review like any other change. Running npx cronhq tail live-streams executions straight to your terminal, so you can watch a job's output without leaving your editor or shell. Inside the dashboard, a ⌘K command palette lets you type schedules in plain English: writing "every weekday at 9am" returns the valid cron expression 0 9 * * 1-5, with a plain-English preview so you can confirm the schedule is right before saving it. The third group covers what happens after a run fails. Retries are built in with backoff, configured as a max retry count and delay per job, so a transient failure gets a few more attempts at increasing intervals instead of being written off immediately. The terminal status and the last error always land in the job's history, which means the postmortem writes itself. Every execution is logged with its status, duration, HTTP code, and response body, newest first, searchable, and retained — the job's history belongs to you and stays available. Alerts are deduplicated to avoid noise: a failure alert fires on the third bad run in an hour, not on the first, and the recovery alert fires on the first success after a streak. That is a deliberate design choice illustrated in Cronhq's own diagrams, where repeated failures after an alert stay silent, and a recovery message such as "nightly-rollup recovered after 3 failures. Last 6 runs: all 2xx." closes the loop. Alerts can be wired to email or Slack. The mechanism behind Cronhq's central guarantee is a Postgres lock. Two workers can never fire the same scheduled execution: each run is claimed through a database lock before it proceeds, so a duplicate worker simply loses the race and does nothing. If a worker crashes mid-job, the lock expires and another worker picks the execution up. This is what makes the exactly-once claim structural rather than aspirational — the coordination lives in the database that both workers already trust, not in a best-effort in-memory flag. Around that core, Cronhq schedules, delivers, retries, records, and alerts, and the whole system is built in Rust on Postgres. It is MIT-licensed and self-hostable, running the same image Cronhq runs in production. For teams that rely on scheduled work, the outcome is that jobs stop disappearing without anyone noticing. Duplicate executions from racing workers are eliminated by the lock-based claim, so a nightly billing job fires once instead of twice. Transient failures are absorbed by retries with backoff, while permanent failures surface in a searchable execution history complete with HTTP codes and response bodies. Alerting is deliberately quiet: one page on the third failure in an hour and one on recovery, so the signal is that something is actually wrong rather than that a single run flaked. Heartbeat monitors extend the same coverage to jobs Cronhq does not run itself, turning a silent absence into a page. And because schedules can live in a cronhq.yaml file and reconcile through the CLI, they become reviewable artifacts in the repository rather than configuration that only exists in a dashboard. Scheduled webhooks are the core workflow: a nightly rollup job, a nightly digest, a metrics refresh, a queue drain, a cache warm, a cleanup job, or a health poll, each configured with a name, a cron schedule, a webhook URL, and a timezone such as America/New_York. Jobs that run elsewhere — on your own infrastructure or another provider — can still be covered by pointing a heartbeat monitor at an endpoint you ping on every run, so if the ping window is missed, you are paged. Teams that want their schedules under version control use npx cronhq sync against a cronhq.yaml file, and teams that prefer watching from a terminal use npx cronhq tail to live-stream executions. Anyone who needs to sanity-check a schedule quickly can type the schedule in English into the ⌘K command palette and get the cron expression back with a plain-English preview. Cronhq is aimed at developers, engineering teams, and anyone running scheduled work in a distributed system, and it is listed among Developer Tools, Open Source, SaaS, and GitHub topics. Delivery is by webhook, so it integrates with any HTTP endpoint, including your own API; alerts go to email or Slack. The stack is Rust on Postgres. Cronhq is MIT-licensed and self-hostable using the same image the hosted service runs, and it offers a free tier covering 5 jobs. Getting started takes four steps on one screen: sign up with an email to receive a one-time link that mints a 36-character API key starting with chq_, create a job with a schedule and URL, watch executions arrive in the log, and wire up email or Slack alerts. In short, Cronhq exists to make one promise true: cron jobs that actually run. It enforces exactly-once execution with Postgres locks, retries failures with backoff, signs every webhook with HMAC-SHA256, monitors jobs it does not run via heartbeat pings, and alerts once on failure and once on recovery. Built in Rust on Postgres, MIT-licensed and self-hostable, with a free tier of 5 jobs, it gives teams a scheduler that treats reliability as the starting point rather than an afterthought.
Jevtown is a social network where people write and 10,000 AI personas read. You post a text, a listing, a product or a headline, and within seconds the town reacts: most scroll past, some like, repost, block, write to the seller or buy. The purpose of the product is to let a writer see how an audience would respond before publishing anywhere that actually matters. Every reader is a computed persona with a name, an age, a job and a city, and the English-speaking town is described as having 10,002 residents. Jevtown is aimed at anyone who writes for an audience — someone drafting a social post, a seller writing a listing, a maker describing a product or a writer testing a headline — and it requires no sign-in to use. The problem Jevtown addresses is the uncertainty that comes before publishing. Once a post, a listing or a headline is out in the world, the reaction is already public: readers scroll past, or they stop, or they block, or they buy, and there is no way to take that back. Jevtown moves that moment of truth earlier. Instead of guessing how a piece of writing will land, you can watch a simulated town react to it in seconds and then decide whether the text is worth publishing at all. The product puts it plainly: a weak text dies for half a cent and a good one reaches everyone in 14 seconds. The same logic applies to a marketplace listing, where the difference between two ways of writing the same item can decide whether buyers write to the seller or smell a scam. Jevtown accepts four kinds of input, each selectable from a single composer: Post, Listing, Product and Headline. The composer allows up to 2,000 characters, shown as a live counter labelled 0 / 2000. When you submit, the English-speaking town reads it — 10,002 residents — and you will see who likes, reposts or blocks it. The site also demonstrates a Ukrainian town: the homepage opens with a saved example labelled "A saved example · the Ukrainian residents" alongside a 01 / 02 selector, and residents in the sample feed carry Ukrainian names and cities such as Dnipro and Zhytomyr. Each resident is identified by a first name, an age, an occupation and a city — for instance Zoe, 20, a student in New York, or Yurii, 56, a nurse in Zhytomyr — and their individual reactions are listed next to their profile. The core mechanic is a wave system that decides how far a piece of writing travels. A post first goes to the 600 residents it should matter to, and it reaches the next 1,500 only if more readers were glad than annoyed. From there it can keep climbing: the feed shows posts that were seen 600 times, 2,100 times, 5,100 times and up to 10,001 or 10,002 times. A listing in the saved example went into a second wave and reached 2,100 personas after readers responded well to it. This staged distribution means that a weak text stops early while a good one reaches everyone, and the counts of how many people saw, stopped, were glad, were sorry, reposted, clicked or bought are reported for each post. Every stage is measured in a small, consistent vocabulary of reactions. Readers can scroll past, stop, be glad, be sorry, repost the post, click a headline, write to the seller, smell a scam or buy the product. The saved iPhone listing shows the pattern: 2,100 saw it, 142 wrote to the seller and 6 smelled a scam, with a Replay control and a visibility setting offering "To the public feed" or "By link only". Because the residents are computed personas rather than anonymous visitors, Jevtown can break their behaviour down by interest, job, age, city and budget, and tell you who stopped, liked, reposted or blocked your text. In the sample feed you can see individual reactions attributed to named residents, such as Iryna, 37, a copywriter in Dnipro who bought it. Jevtown's unique approach is to make the audience itself the product. Beyond feed reactions, a listing or product can be tested with a price ladder: prices can be named in ₴, $, € or £, and every resident who stops at the product is asked for the highest of those prices they would pay. The result shows how many buyers each price gets and which one earns the most — described as a demand curve over a product's price ladder. For listings, Jevtown also reports the questions buyers would ask first. The whole experience runs on the web without sign-in, costs as little as half a cent for a text that dies early, and can show a finished result in 14 seconds. The public feed itself can be sorted by Latest or Travelled furthest, and at the time of writing displayed 148 texts seen 260,005 times. The benefit for a user is a decision made before publication instead of after. Instead of publishing and waiting, you get an immediate reading of whether the text connects and who it connects with: the people who stopped, the people who were glad, the people who reposted and the people who blocked. Sellers learn the questions buyers would ask first, which can be answered inside the listing itself, and they get a view of which price point earns the most. Headlines can be compared by how many people stopped and clicked versus how many were sorry. Because each experiment is cheap and fast, a writer can afford to test several versions of the same text and keep the one the town responds to. The clearest use case shown on the site is a marketplace listing. The same iPhone 13 listing is written two ways — one version offering full details and payment on inspection, the other demanding advance payment only — and the site shows how the town reacts to each, including the number of personas who wrote to the seller and the number who smelled a scam. Another use case is the headline: the feed shows headlines such as "New research solves cancer" that were seen 600 times, with hundreds of residents stopping and dozens clicking. Products can be tested with the price ladder to compare demand at different prices, and general posts — opinions, jokes, technical write-ups, ideas — can be run through the town to see whether the audience stops, is glad, reposts or simply scrolls past. Jevtown is for people who write for an audience and want a fast read on it before going public: sellers writing marketplace listings, marketers writing headlines, makers writing product descriptions and anyone posting to a social feed. The product runs in the browser, requires no sign-in and costs as little as half a cent for a text that dies early. The sample content on the site covers both an English-speaking town of 10,002 residents and a Ukrainian town, and prices for the price ladder can be expressed in hryvnia, dollars, euros or pounds. The site mentions no third-party integrations and does not describe a technical stack, so the experience appears to be entirely self-contained. Jevtown is a sandbox for writing in public without the consequences: a town of 10,000 computed residents who read your post, listing, product or headline in seconds and tell you — by scrolling past, stopping, liking, reposting, blocking, writing to the seller or buying — whether the text is worth publishing. A weak text dies for half a cent; a good one reaches everyone in 14 seconds.
AI Creative Insights is a platform from Entropik — the team behind Decode — that tests creatives with Neuro AI to predict attention, emotion, and conversion impact before budget goes live. Users upload any ad, banner, OOH, or video creative, and the platform predicts how people will respond before media spend is committed. Its stated purpose is to predict creative winners before you spend, so that creative decisions are led by data instead of guesswork. The product sits alongside Entropik's other platform offerings — AI Moderator, Consumer Insights, and User Research — and is used on the web, with a sign-up entry point and a request-a-demo path for teams that want a walkthrough with the vendor. Decode frames the problem it addresses as a set of broken creative practices. Creative decisions, in the product's own comparison, are subjective and inconsistent; testing is slow and difficult to scale; media spend is inefficient because it is committed before anyone knows how a creative performs; insight depth is limited; and comparing creatives to one another is difficult. The product sets out a direct alternative for each of these: AI-led predictive creative evaluation instead of subjective judgement, instant AI-powered analysis at scale instead of slow and hard-to-scale testing, optimization of creatives before launch instead of inefficient media spend, creative performance scoring instead of limited insight depth, and benchmarking against category norms instead of difficult comparisons. The position the page takes is straightforward: creatives shouldn't be a gamble, and the data should lead. The first of the four key capabilities is Predictive Attention AI. It compares creatives and predicts attention, recall, and resonance before launch, letting teams test variations, forecast performance, and choose the version that drives maximum impact. The listed sub-capabilities are predicting performance, testing variants at scale, benchmarking against category, and getting second-by-second clarity. The value of this grouping is that instead of committing budget to a single creative and learning afterwards, a marketing team can evaluate several versions at once and see which one is expected to hold attention and land the message. This is the capability that most directly supports the promise of choosing the creative winner before spend begins. The second capability is Emotion Simulation, which is about understanding how people actually feel while watching a creative. It visualizes emotional highs and lows second by second and uncovers what triggers engagement or drop-offs. The sub-capabilities listed under it are measuring emotional response, tracking emotion flow, checking brand safety, and connecting emotion to intent. The usefulness here is diagnostic: a second-by-second emotion curve shows where attention and feeling rise, and equally where a viewer disengages, which is exactly the kind of moment-level feedback that is hard to obtain from traditional testing. Connecting emotion to intent extends that reading beyond how a creative feels into what it is likely to drive. The third capability is Visual Hierarchy Heatmaps. These show where people look first and what catches or loses attention, so layouts, storytelling, and branding can be optimized with evidence instead of assumptions. The page lists four things these heatmaps help with: seeing where people look, ensuring message visibility, removing distractions, and comparing layouts. For a creative or design team, this means the arrangement of a banner, a video frame, or an out-of-home layout can be judged on what is actually noticed rather than what was intended. If a brand mark or call to action is being overlooked, the heatmap surfaces that before the asset goes to media. The fourth capability is Prescriptive AI Suggestions. These are actionable recommendations that tell you exactly how to improve performance, including what to change, why it matters, and what impact it will drive. The supporting points are getting improvement recommendations, understanding why performance changes, prioritizing high-impact changes, and building clearer briefs. Rather than stopping at a score, the platform is described as closing the loop from diagnosis to action, and the brief-building point shows the output is intended to feed back into creative development, not just into a one-off decision. A distinct element of the platform is Synthetic Audience. Users can build reusable synthetic audiences, apply them across every AI Creative Insights evaluation, and compare predictions persona by persona before spending on media. The page shows an audience selector with example audiences such as Gen Z Shopper, Urban Professional, Family Buyer, and Value Buyer, together with a predicted score and sub-scores for Attention, Clarity, and CTA Focus. Fit is banded into Strong fit (75+), Moderate fit (55–74), and Weak fit (below 55). This makes it possible to see the same creative through different audience eyes and to identify which segments a creative fits before media is committed. Beyond the four headline capabilities, the page groups deeper creative intelligence into three areas. Attention Metrics track where users look first, how long they stay, and the journey their eyes follow, broken into first fixation (the exact element that grabs attention first), attention duration (how long users focus on key visual elements), and visual path and retention (the flow of eye movement and what holds attention longest). Engagement and Comprehension measures emotional impact, message clarity, and how well a creative drives brand recall and purchase intent, through emotion mapping, message clarity, and brand recall and purchase intent. Comparative Intelligence benchmarks performance against competitors, audiences, and past campaigns, through industry and competitor benchmarking, channel and demographic comparisons, and historical trends and performance insights. The workflow is described as running from upload to uplift in four steps: upload creative by dragging and dropping any format, AI analysis, optimize, and validate — with the stated aim of launching only high-performers. The intelligence behind every insight is attributed to a set of Entropik technologies named on the page: Facial Expression Analysis, Eye Gaze Tracking, and Voice Emotion Analysis. These are presented as Emotion, Behaviour, and Gen AI capabilities that let teams capture, interpret, and act on customer signals, and the platform is described as using facial coding and eye tracking to measure creative effectiveness, eliminating guesswork from every campaign. Reported outcomes on the page include 95% predictive attention accuracy, 32% testing cost reduction, 4X faster research timelines, and 40% CTR improvement. The platform says it is used by 150+ forward-thinking brands, and a set of testimonials speaks to different disciplines: a consultant citing versatile UI/UX analysis tools that help design teams make data-driven decisions more scientifically, a consumer science professional noting that facial coding uncovered emotional responses to packaging, a head of digital experience highlighting eye-tracking technology and AOI metrics, a brand manager who changed pack design based on platform recommendations, and a money-transfer and transactions experience head commenting on the support provided. Success stories referenced include a global fast-food brand that reduced media research timelines by 4X, a global beverage company using AI moderator-led qualitative research for RTD experience optimization, and a UK-based financial institution that optimized its digital onboarding experience using Decode by Entropik. Stated use cases include OOH Testing to maximize out-of-home advertising impact, Banner Testing to make every banner ad impossible to ignore, AI Creative Recommendations to let AI guide creative excellence, Creative Testing to transform creative development with AI-powered testing, and AD Testing to test ads before they go live. The page addresses research teams, marketing teams, product teams, and UX/design teams, and lists industries served as CPG, Technology & Software, Healthcare & Pharma, Financial Services, and Retail & E-Commerce. Teams can start through a sign-up link or request a demo with name, business email, contact number, and LinkedIn URL. In summary, AI Creative Insights by Decode turns creative evaluation into a predictive, evidence-led process: upload a creative, see predicted attention, emotion, and score by audience, understand what to change and why, and compare against category norms before media budget goes live.
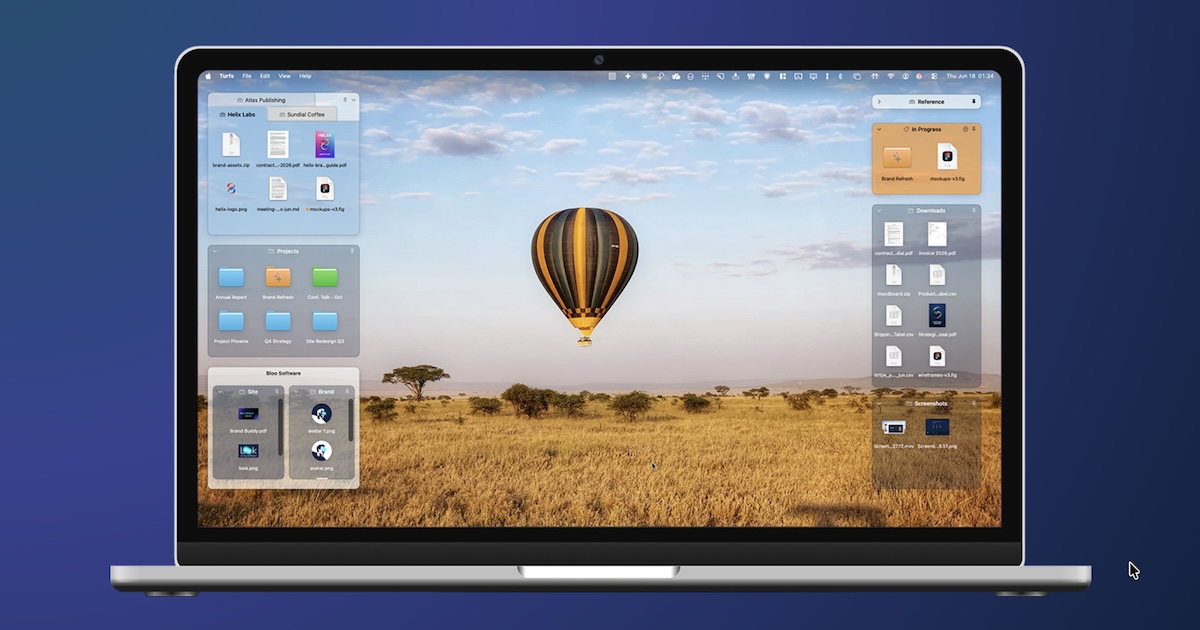
Turfs is a native desktop organizer for macOS that turns the Mac desktop into a set of defined, labeled areas. Each area, called a turf, holds content pulled from across your Mac so that frequently used files, folders, and references stay visible, accessible, and arranged with intent. Turfs is built for people who use the desktop as a working surface rather than as a dumping ground, and for anyone who wants a clutter-free wallpaper without giving up quick access to their material. A turf can be backed by a real folder on disk, by a Finder tag, or it can be a purely virtual grouping of hand-picked items. Turfs replaces Finder's own desktop icon layer with its own, so the desktop behaves the way you define it while still obeying standard macOS conventions. For years, Windows users have organized their desktops with Stardock Fences, a tool that has been available since 2009 and has accumulated roughly twenty million downloads. Fences taught a generation of PC users that the desktop could be more than a pile of shortcuts: it could be defined areas, labeled groups, and files arranged with intent. Many of those users later moved to the Mac and expected to find an equivalent. They waited. Apple shipped Stacks, which groups desktop files by file type, an arrangement that rarely matches how people actually think about their work. Apple shipped Tags, but tags are effectively invisible until a sidebar is opened. As a result, the Mac desktop in 2026 works almost exactly the way it did in 2007. Third-party attempts such as iCollections arrived, stalled, and faded, and Stardock itself looked at porting Fences to the Mac and walked away. Turfs exists to close that gap. Turfs offers three kinds of areas, each with its own behavior. A folder turf is backed by a real folder on disk: when you drag a file into it, the file physically moves into that folder. The filesystem stays clean, and the file has a real home that is visible right on the desktop. A tag turf is backed by a Finder tag instead: when you drag a file into it, the file receives that tag, and the turf displays every file carrying that tag from anywhere on your Mac. The file itself does not move, so a tag turf acts as a live, system-wide view. A collection turf is a virtual grouping: files dragged into it appear inside the turf but remain exactly where they are on disk. Because collection turfs never relocate anything, they are the safest option when you want to gather items without touching the underlying filesystem. Every turf type can be combined on the same desktop, so you can mix permanent folders, tag-driven views, and temporary collections depending on what each area is for. Turfs is designed to feel native rather than like a Windows port. Quick Look opens with the spacebar, Get Info with Cmd-I, and Trash with Cmd-Delete. You can drag files from a turf to any app, use alias arrows, use folder paper-peek, and access the full context menu. The desktop's standard interactions keep working because Turfs leans on macOS conventions throughout. Files that you do not place inside a turf stay exactly where you left them as loose icons, and when you move a turf over them, those loose icons dodge out of the way rather than being swallowed by the area. Turfs also stays put through Show Desktop, and you decide what Mission Control does with your turfs. Because Turfs replaces Finder's own desktop icon layer rather than sitting on top of it, it can never be sandboxed or sold through the Mac App Store — the desktop really is the surface it owns. Every detail of a turf can be customized. You can set the background color, opacity, border, and corner radius, and choose whether labels are visible. A hover-only mode keeps the desktop visually clean while the areas remain in reach, and snapping options let turfs snap to a grid or to other turfs. Behavior can differ per Space, so a turf can appear on all Spaces or be pinned to one. Tabbed turfs let several groups share a single area. The settings are grouped into four panels: General covers launch, Dock, roll-up, and tabbed turfs; Appearance covers color, opacity, border, and hover mode; Desktop covers icon size, snap grid, and snap sensitivity; and Spaces controls whether turfs show on all Spaces or follow individual Spaces. When you want an area available but out of the way, you can roll any turf up into a thin strip that shows just its name and item count, and one click or a hover brings it back to full size — useful for references, archives, or anything you want close without giving up screen space. Turfs works by taking over the desktop icon layer from Finder and drawing its own areas in its place. Your wallpaper still shows through, and Mission Control still works, so the change is to how the desktop is organized rather than to how macOS behaves. Turfs stay in place through Show Desktop, and Mission Control's treatment of them is up to you. Turfs is local-first: it has no accounts, collects nothing about you or your files, and runs no servers. Its only network activity is an update check and a one-time first-run count that fetches a small file from GitHub, carrying no information about you. Your turfs are stored in a single JSON file in ~/Library/Application Support/. Quitting Turfs returns your desktop to exactly the way macOS shipped it. The practical benefit is a desktop that reflects how you work. Material scattered across your Mac becomes reachable from the surface you already look at, organized into named areas instead of one undifferentiated field of icons. Because folder turfs keep real files in real folders, your filesystem stays tidy while your desktop stays useful. Because tag turfs follow Finder tags, a single area can surface matching files from anywhere on the machine without copying or moving anything. Because collection turfs are virtual, you can organize aggressively without risk, since nothing is relocated on disk. Customization, roll-up, and hover mode mean the organization never has to cost you visible screen space, and the local-first design means organizing your desktop does not require an account, a subscription, or a connection. Several workflows fit Turfs naturally. A project turf can be folder-backed so that dragging in drafts and assets files them into the actual project directory. Reference material — PDFs, screenshots, spec sheets — can live in a tag turf that keeps every tagged file one glance away no matter where it sits on disk. A collection turf works well as a temporary staging area for files gathered during a task, since nothing moves until you decide it should. Rolled-up turfs suit archives and reference sets that should remain at hand without occupying the desktop. Per-Space behavior lets one arrangement serve a work Space and a different one serve another. And for anyone who simply wants an uncluttered wallpaper, hover-only turfs keep the desktop clean until the moment you need something. Turfs is aimed at Mac users who treat the desktop as a working surface, particularly people who came from Windows and miss Fences-style organization, along with anyone who has looked for a Mac equivalent and found the alternatives lacking. It requires macOS 14 Sonoma or later, with Apple Silicon recommended. Turfs is distributed as a direct download, signed with a Developer ID certificate and notarized by Apple; the site lists nine releases since 15 June 2026, with version 1.2.1 on 7 September as the most recent at the time of writing. Pricing is $29 as a one-time purchase with a 10-day free trial that requires no card. The license includes unlimited turfs from day one, all three turf types, full appearance customization, and free updates forever, delivered as a license key that works offline without an account. There is no subscription and no renewal. Turfs gives the Mac the desktop organizer Windows users have had for years: defined, labeled areas that keep material from across the machine accessible and arranged on purpose. Folder, tag, and collection turfs cover permanent filing, system-wide tag views, and risk-free virtual grouping; native macOS interactions, deep customization, roll-up, and per-Space behavior make the areas fit real work; and a local-first design with a single JSON file keeps it private and reversible. At $29 once with a 10-day trial and no account required, it is a straightforward way to make the desktop a feature rather than a mess.
