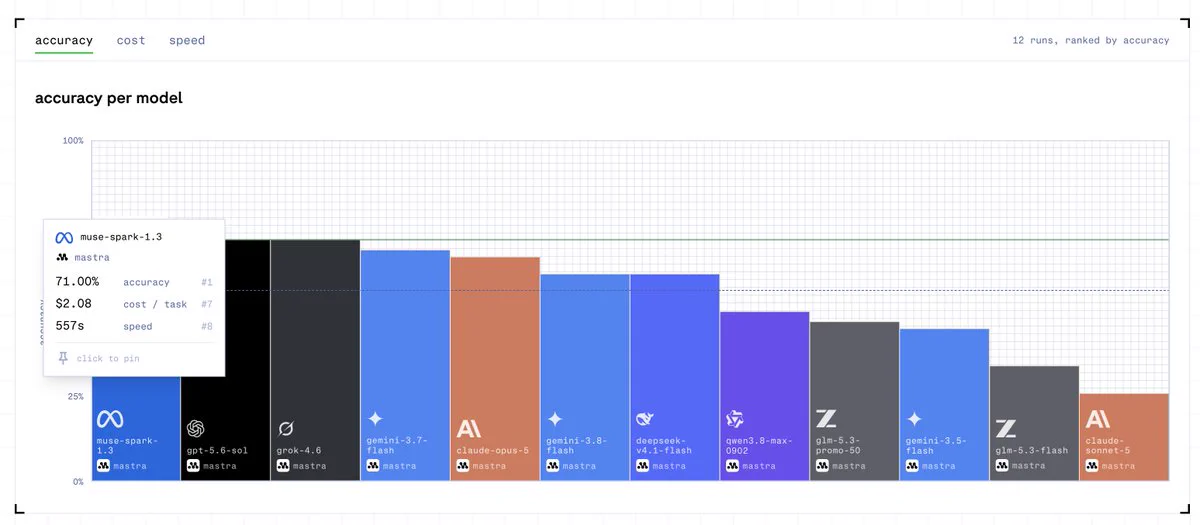
Introducing our Browser Agent Evals.
We benchmark frontier and open models using various harnesses on computer-use tasks.
Our evals are fully open source and reproducible via our Evals CLI.
Muse Spark 1.3 from @Meta tops the charts in our Browser Agent benchmarks using the @mastra agent harness.
In this harness, Muse outperforms Opus 5 in cost, speed, and accuracy.
We got early access to Fable 5.1 and evaluated it extensively across our internal benchmarks.
It outperformed all other frontier models (including Fable 5) on accuracy scoring 92.11%, while being 60% cheaper than Fable 5 per task.
Create agent-ready web apps for the WebMCP Challenge → goo.gle/4qpDQYV
We're excited to see ChatGPT supporting WebMCP, the experimental standard that lets users and AI agents navigate websites together. In the @OpenAIDevs WebMCP Challenge you can experiment with it and