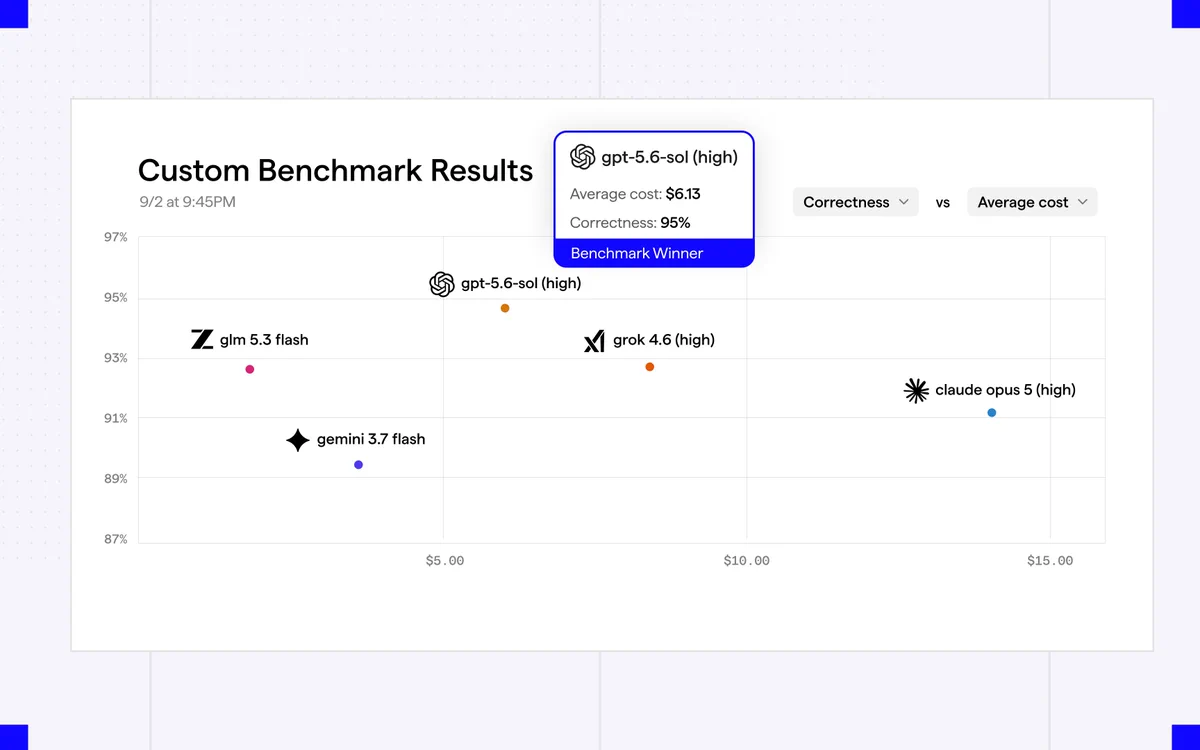
Introducing Factory Benchmarks: The first model bench generated from your own coding tasks.
Measure, test and improve coding agents by replaying past agent runs, and cut cost-per-PR by 63%+
Here’s how it works 🧵
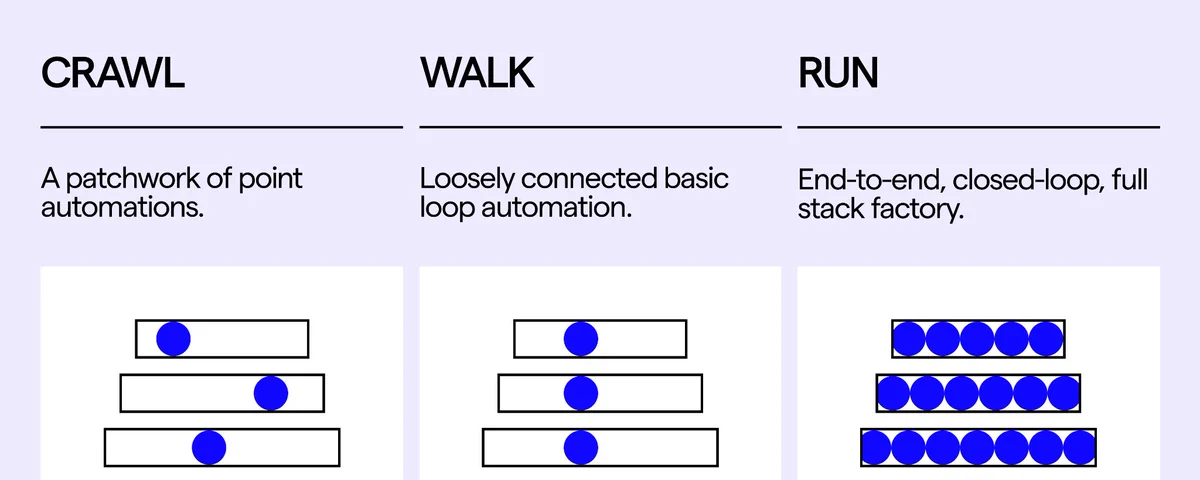
The software factory approach is getting pretty popular, but it can be daunting to adopt all at once.
Let's go through “crawl, walk, run” steps for making the transition from local, interactive agents to automated cloud development.
Warp now has built-in support for the Grok Build CLI.
- Use Warp's rich input for agent prompts, with support for longer pasted prompts and multi-cursor
- Use /remote-control to share your agent session to another device
- Access the file explorer and code review panels
Our company’s cost-per-PR dropped from $80 to $30 by switching to GPT 5.6 Sol.
We built a benchmark to replay our team's agent runs across model providers. GPT 5.6 Sol got the highest code quality at a 66% lower cost vs. our old default (Claude Opus 5).
I’m excited to finally announce the newest edition my Stanford course 𝗧𝗵𝗲 𝗠𝗼𝗱𝗲𝗿𝗻 𝗦𝗼𝗳𝘁𝘄𝗮𝗿𝗲 𝗗𝗲𝘃𝗲𝗹𝗼𝗽𝗲𝗿. It has been 9 months in the making.
Last November, with the release of Claude Opus 4.5, coding agents experienced a step function improvement in