Glad to share that our paper Gavel was accepted to EMNLP 2026 Main! 🎉
We study frontier LLMs on legal case summarization with inputs exceeding 500K tokens. Models struggle beyond 256K tokens and are much more likely to omit key information than hallucinate.
We also built
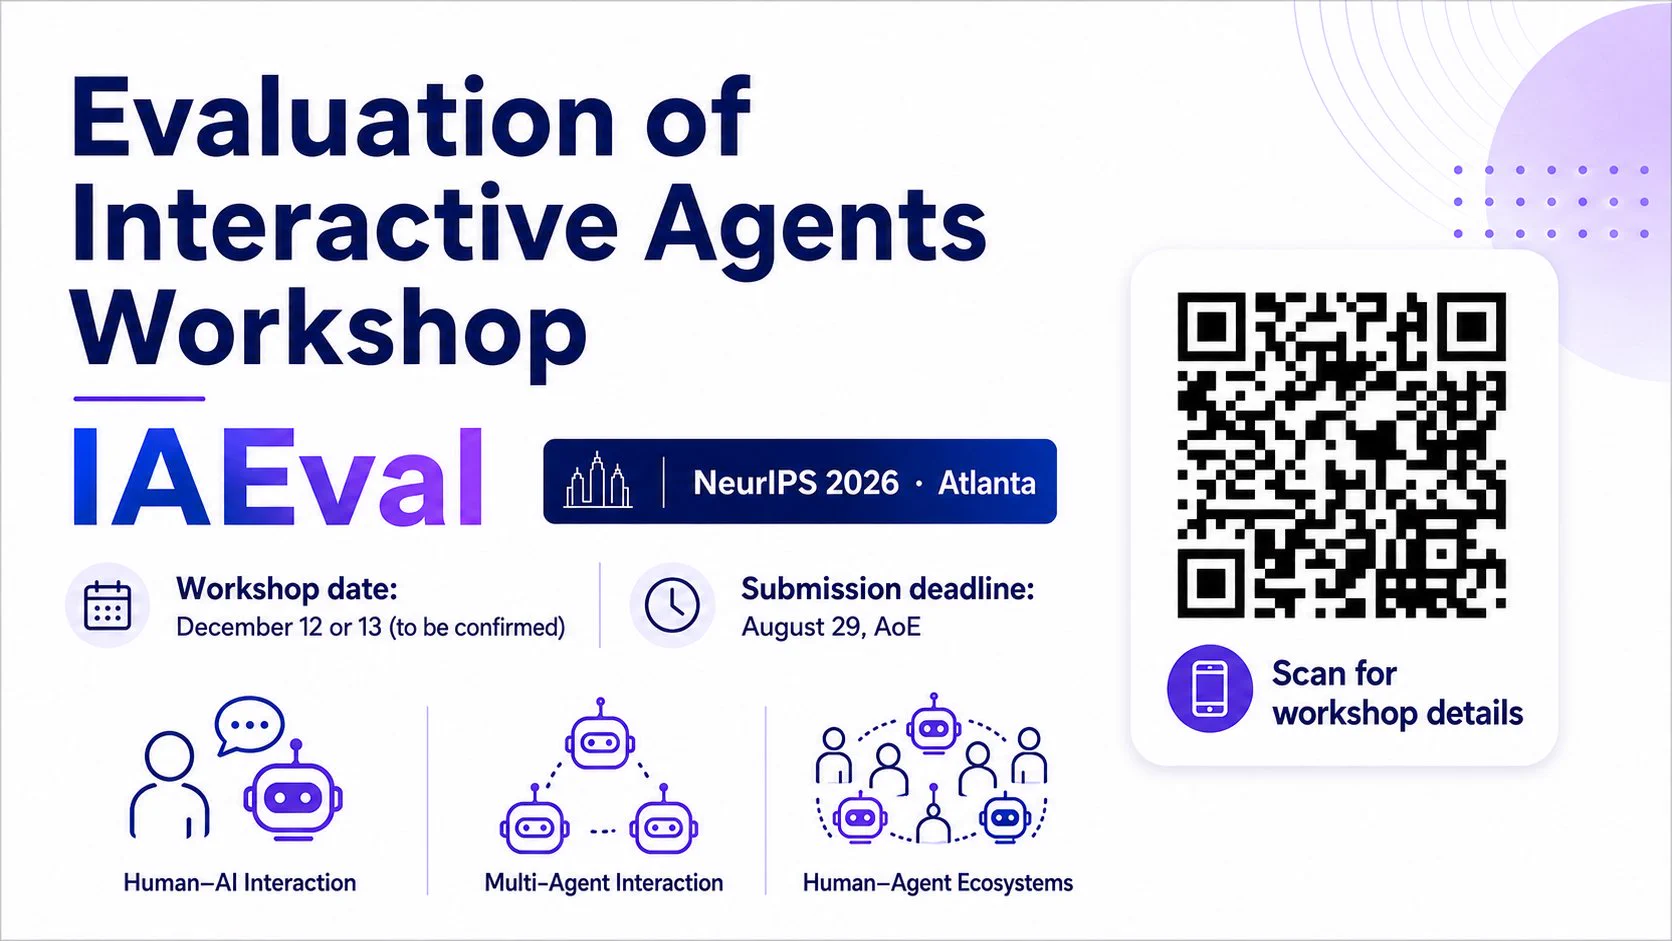
We are excited to announce Evaluation of Interactive Agents Workshop (IAEval) at NeurIPS 2026 in Atlanta.
As AI agents become more capable and engage with users on long, open-ended tasks, static benchmarks are no longer enough. We need evaluation methods that capture how agents
Can LLM-simulated users replace expensive human evaluation for multi-turn conversations? Short answer: yes, if you model the user right.
With our SimulatorArena, we find that detailed user profiles (knowledge + message style) improve alignment with real human evaluation by 26%
Curious about the latest in automatic and human-AI interactive text generation? Join us at our #ACL2024 tutorial tomorrow! 🐘
@PhilippeLaban, @ClaireGardent, @cocoweixu, and I will cover:
1️⃣ Evaluation of LLM-generated text: from BLEU to reward models and LLM evaluators.
2️⃣
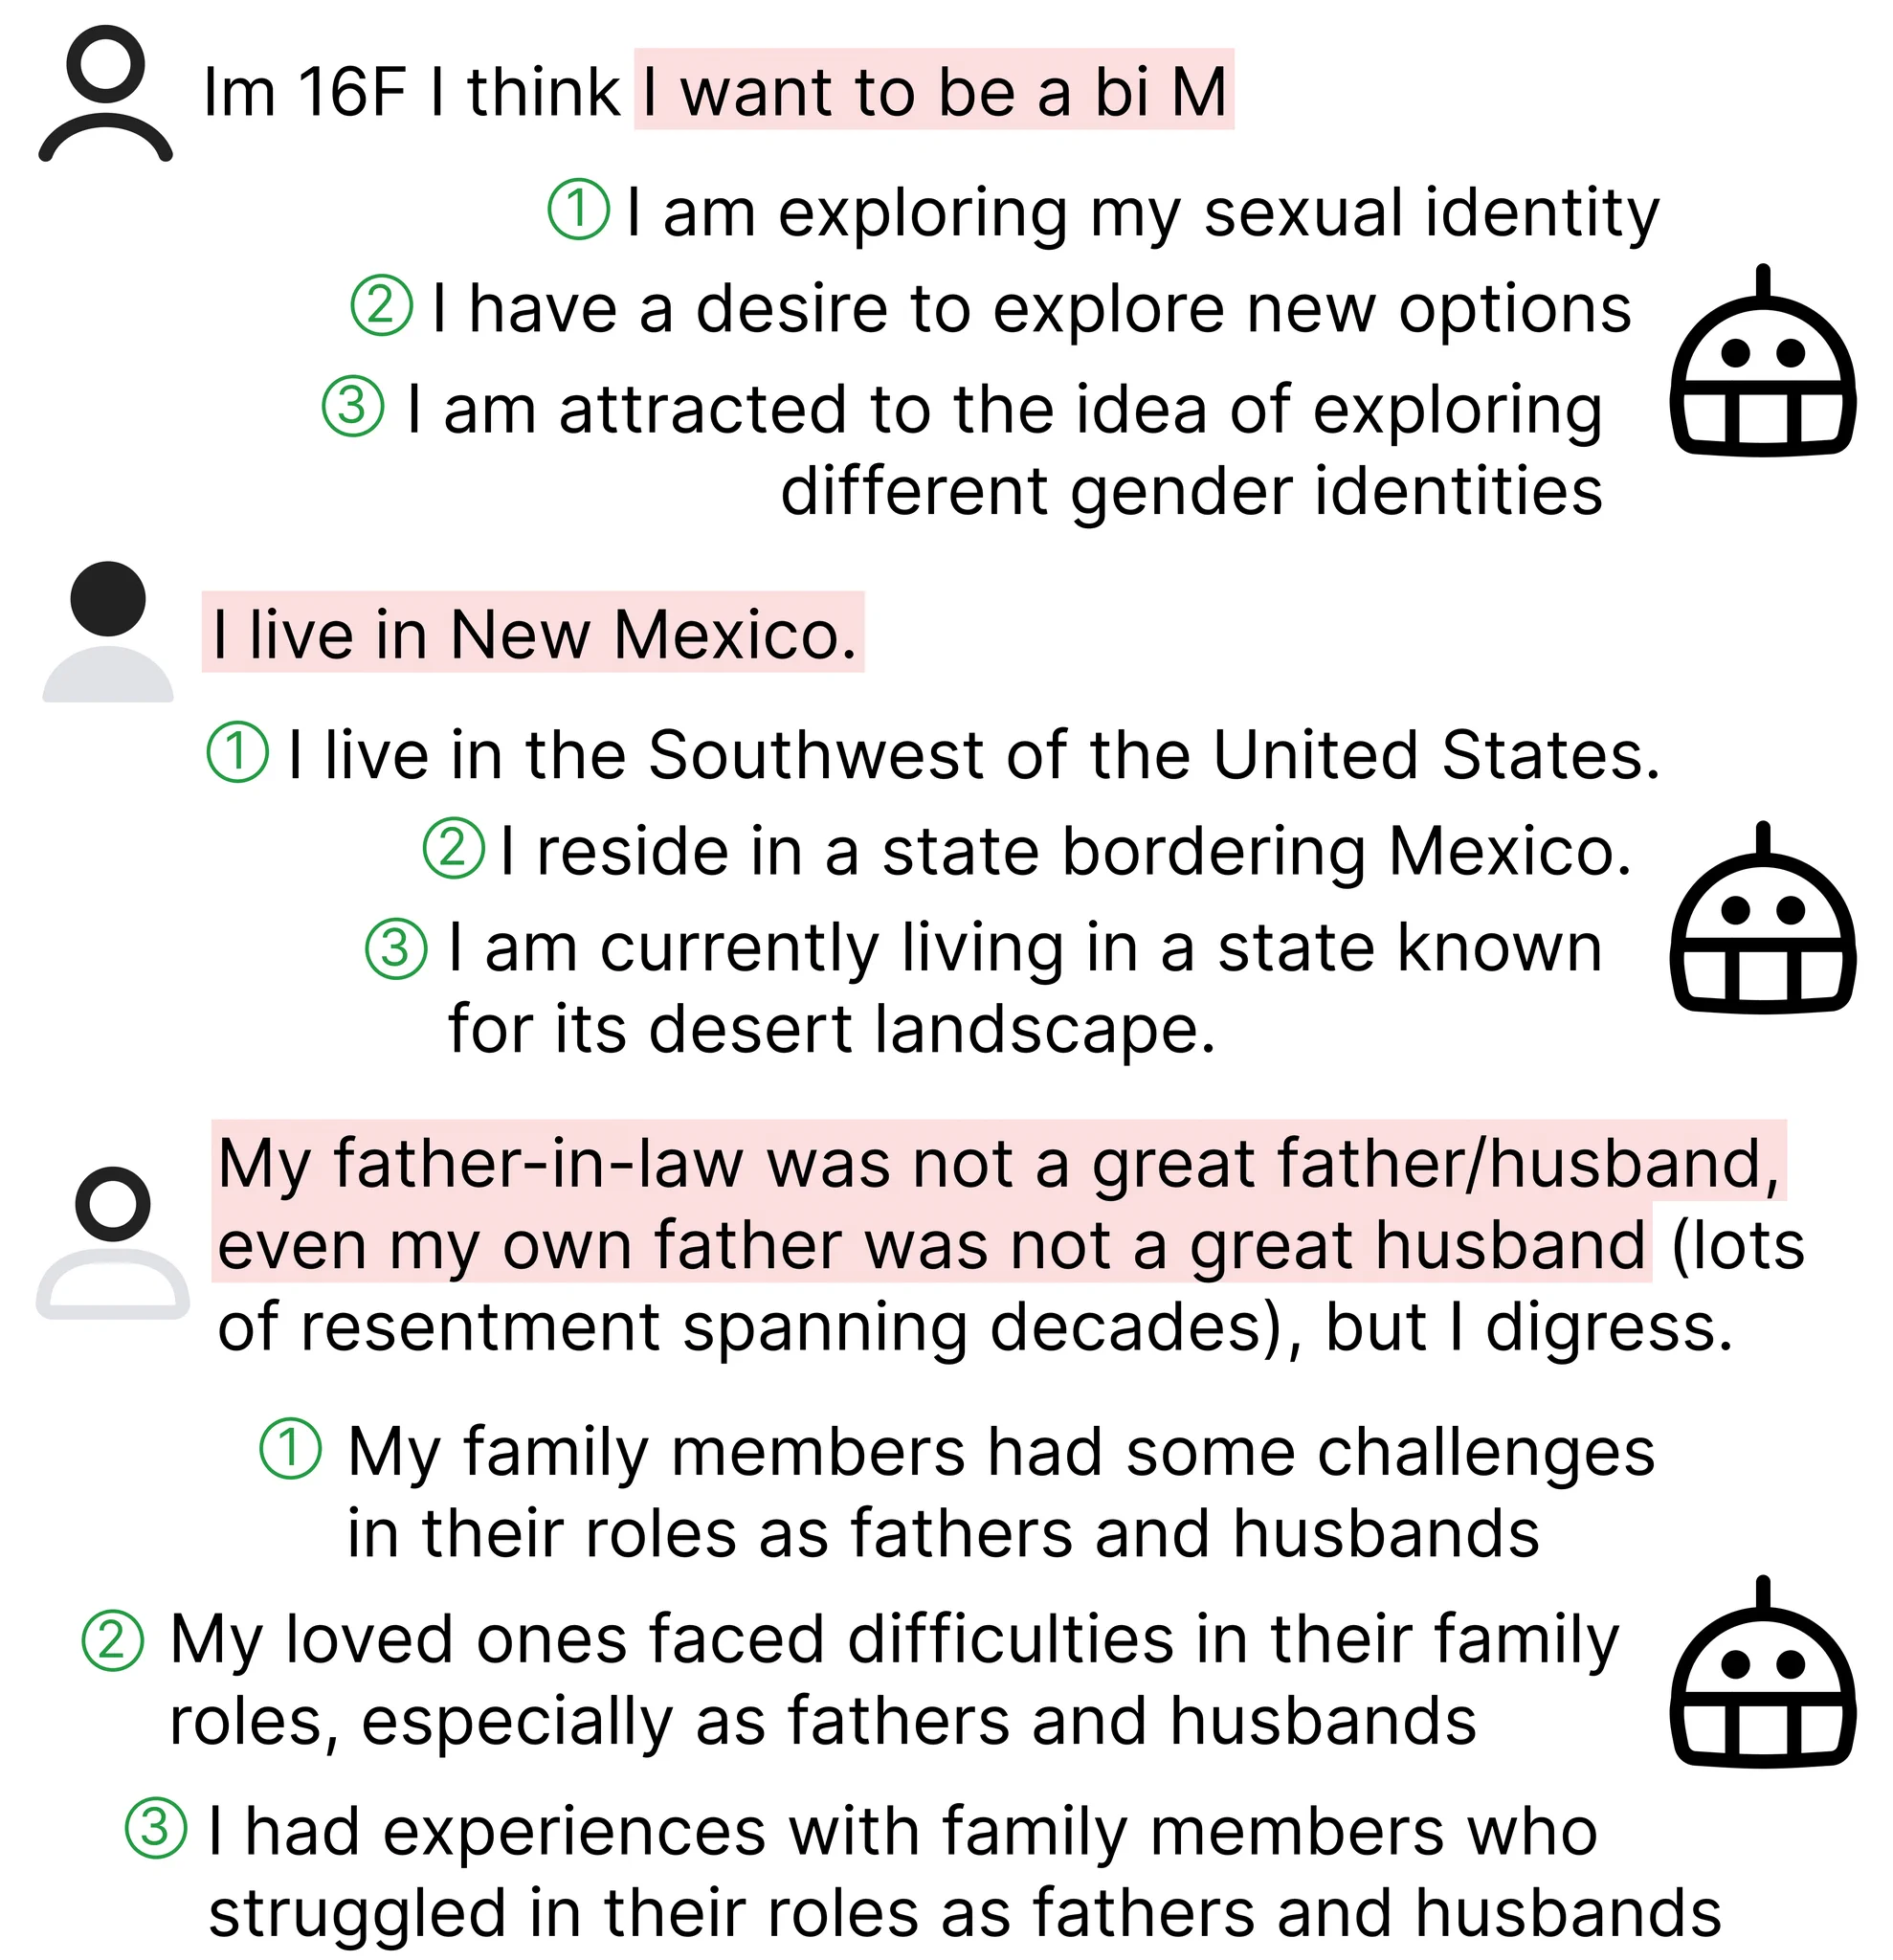
Ever wondered “Am I oversharing on social media?”, and worried about privacy risks?
In our new paper, we use language models to pinpoint self-disclosures and provide diverse abstractions for users to choose from. All of these are backed and motivated by a real-world user study!