

Harness True Model PotentialTransform Every Spark of Inspiration into Reality
Model Space
Browse curated topics and jump straight into the best-fit models for every workflow.


AI Tools
Your all-in-one AI design toolkit for seamless, high-quality content generation
Flux 2
FLUX 2 Max from Black Forest Labs delivers production-grade text-to-image generation with enhanced realism, sharper text rendering, and native editing for reliable, repeatable results

Wan 2.2 5B Video
Wan 2.2 I2V 5B converts images into high-quality 720P videos using a 5B image-to-video model for AI video generation

Minimax Speech 2.8
MiniMax Speech 2.8 HD is a high-definition text-to-speech model with natural and expressive voice synthesis for premium audio quality

Ltx 2 19B Lipsync
LTX-2 Lipsync generates synchronized talking head videos from a reference image and audio input. Powered by the 19B DiT architecture, it produces high-fidelity lip-synced videos with natural head mov…

Image Upscaler
AI Image Upscaler that enhances image resolution to 4K or 8K while improving detail and clarity for photos and graphics
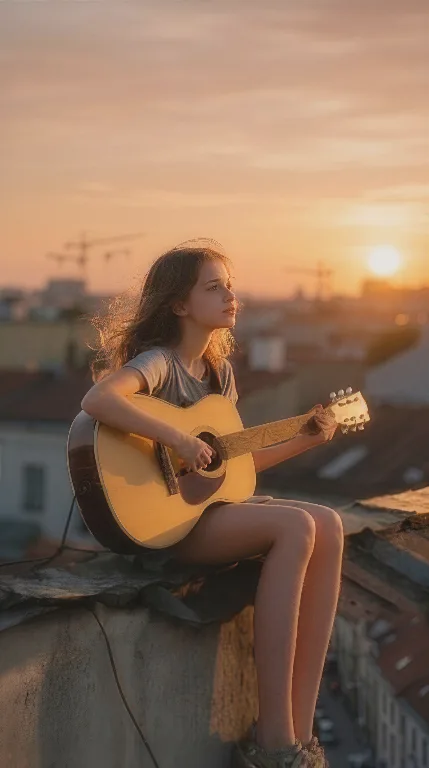 Before
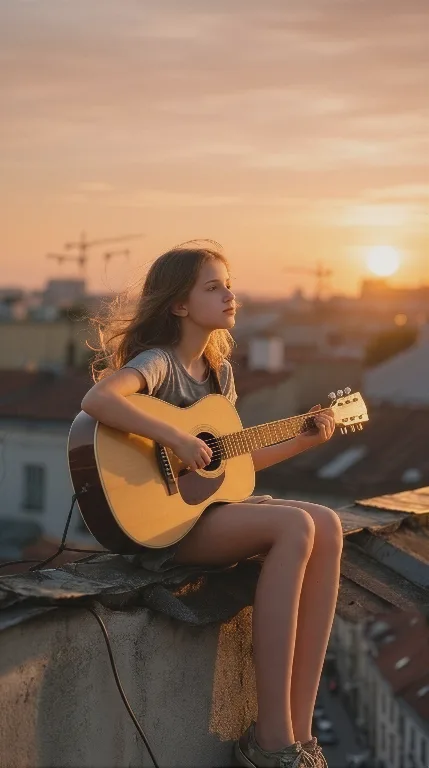 After
Image Background Remover
Powerful AI background remover that outputs high-quality transparent PNGs for e-commerce, graphics, and design
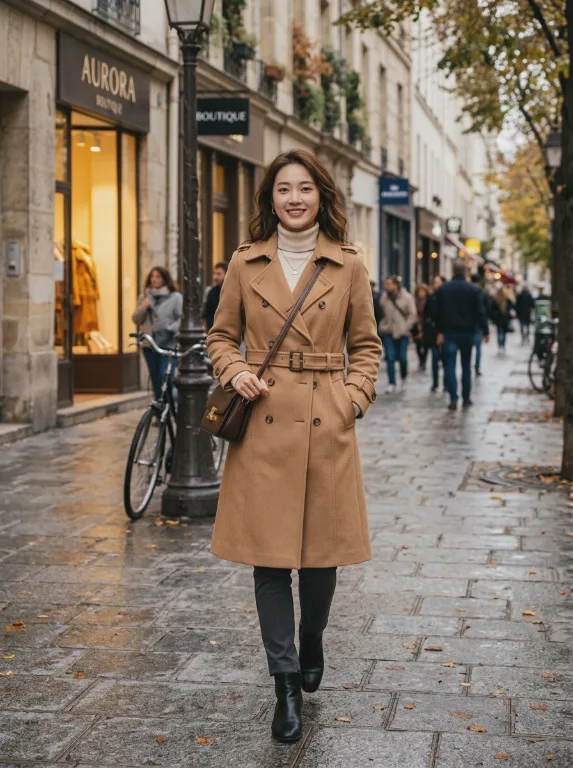 Before
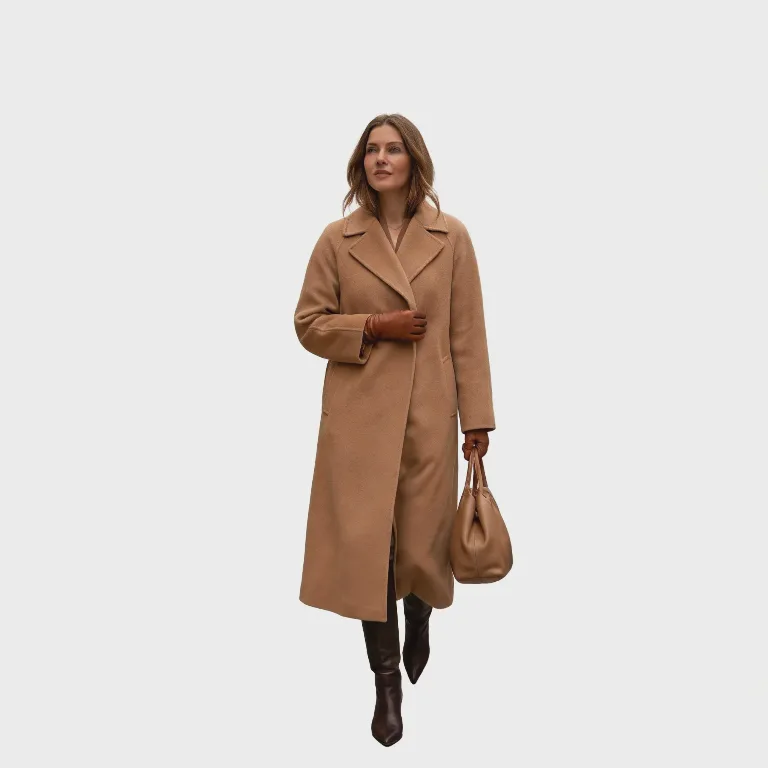 After
Video Translate
HeyGen Video Translate: AI video translation into 70+ languages and 175+ dialects with no voice actors or dubbing. Fast, accurate, easy to use at $0.0375/sec. Ready-to-use REST API, no coldstarts, af…
 Before
 After
Voice Clone
Clone a voice profile for reusable narration, dubbing, or character performance.

AI Virtual Presenter
Use AI Virtual Presenter as a ready-to-run avatar workflow in Studio.

Industry
Explore curated AI models selected for the real production needs of each industry.
General
Common utility tools for asset cleanup, translation, enhancement, and prompt preparation.

Seedance 2.0
ByteDance
# Seedance 2.0: ByteDance's Unified Audio-Video Generation & Editing - Full Review Seedance 2.0 (this catalog entry: `seedance-2-0`) is ByteDance's second-generation Seedance video model, released February 12, 2026. It is built on a **unified multimodal audio-video joint architecture** that handles both generation and editing, accepting up to **9 images, 3 videos, and 3 audio segments** plus natural-language instructions in a single request. Here's the short version: Seedance 2.0 is the most input-flexible video model in the market - draft, edit, and sync video and audio using prompts, images, or reference videos, all in one architecture. It features prompt-driven camera planning (the model plans camera moves from instructions), precise instruction following, and stable subject consistency even for complex stories. It is live in Doubao, Dreamina (即梦), Volcano Ark, and rolled into CapCut in March 2026. The honest caveats: the multi-input flexibility is powerful but increases prompt complexity, and quality claims need your own narrative testing. This guide covers model overview, core features, technical specifications, capability comparison, core advantages, recommended use cases, example prompts, selection recommendations, workflow, and my verdict. --- ## Quick Facts | Attribute | Value | |---|---| | Catalog slug | `seedance-2-0` | | Developer | ByteDance Seed | | Release | February 12, 2026 | | Architecture | Unified multimodal audio-video joint | | Inputs | Up to 9 images + 3 videos + 3 audio + natural language | | Tasks | Generation + editing | | Camera | Prompt-driven camera planning | | Consistency | Subject consistency | | Access | Doubao, Dreamina, Volcano Ark, CapCut | | Self-hosting | No | ## Table of Contents 1. [Model Overview](#1-model-overview) 2. [Core Features](#2-core-features) 3. [Technical Specifications](#3-technical-specifications) 4. [Capability Comparison](#4-capability-comparison) 5. [Core Advantages](#5-core-advantages) 6. [Recommended Use Cases](#6-recommended-use-cases) 7. [Example Prompts](#7-example-prompts) 8. [Selection Recommendations](#8-selection-recommendations) 9. [Workflow: Draft, Edit, Sync](#9-workflow-draft-edit-sync) 10. [The Bottom Line](#10-the-bottom-line) 11. [FAQ](#faq) 12. [Sources & Further Reading](#sources--further-reading) --- ## 1. Model Overview Seedance 2.0 is ByteDance Seed's flagship video model, released February 12, 2026, following the audio-video joint generation breakthrough of Seedance 1.5 pro. The 2.0 generation's defining move is **unification**: one multimodal architecture for generation and editing, accepting a rich mix of inputs - up to 9 images, 3 videos, and 3 audio segments plus natural-language instructions. The official release highlights controllability: precise adherence to generation and editing instructions, stable subject consistency for complex stories with rich character interactions, and prompt-driven camera planning - the model plans camera movements automatically from your instructions. Distribution is broad: Doubao and Dreamina at launch, Volcano Ark (ModelArk) for developers, and CapCut from March 2026 - making it the most consumer-reachable ByteDance video model yet. ## 2. Core Features **Unified generation + editing.** One architecture for both tasks. **Rich multi-input.** Up to 9 images, 3 videos, and 3 audio segments in one request. **Prompt-driven camera planning.** The model plans camera moves from instructions. **Precise instruction following.** Generation and editing instructions executed faithfully. **Subject consistency.** Stable identity across complex stories and interactions. **Audio-video joint architecture.** Sound generated with visuals. **Broad distribution.** Doubao, Dreamina, Volcano Ark, CapCut. ## 3. Technical Specifications | Specification | Detail | |---|---| | Model | Seedance 2.0 | | Architecture | Unified multimodal audio-video joint | | Max inputs | 9 images + 3 videos + 3 audio | | Instructions | Natural language | | Tasks | Generation + editing | | Camera | Prompt-driven planning | | Release | February 12, 2026 | | Access | Doubao, Dreamina, Volcano Ark, CapCut | > **Note:** A standard variant targeting highest output quality was listed on some gateways in April 2026. Verify model IDs and tiers on Volcano Ark. ## 4. Capability Comparison | Capability | Seedance 2.0 | Seedance 1.5 Pro | Vidu Q3 | HappyHorse 1.0 | |---|---|---|---|---| | Input flexibility | **9 img + 3 video + 3 audio** | Text/image | Text/image/reference | Image/reference | | Editing | **Yes (unified)** | No | No | Yes (V2V/SV2V) | | Camera planning | **Prompt-driven** | Autonomous | Frame-level | Cinematic | | Multi-input generation | **Yes** | No | No | No | | Distribution | **Doubao/Dreamina/CapCut** | Dreamina/Doubao | Vidu | Beta | | Open weights | No | No | No | No | **Reading the table honestly:** Seedance 2.0's input flexibility and unified editing are category-leading. HappyHorse has the subject-editing suite; Vidu Q3 has 16-second clips; 1.5 Pro has dialect voice. ## 5. Core Advantages 1. **Input richness.** 9 images + 3 videos + 3 audio in one request - no other major model matches this. 2. **Unified generation and editing.** Draft and refine in one architecture. 3. **Prompt-driven camera planning.** Camera direction from instructions, not keyframes. 4. **Subject consistency.** Identity holds across complex stories. 5. **Audio-video joint.** Sound with visuals by construction. 6. **Consumer reach.** Doubao, Dreamina, and CapCut distribution. ## 6. Recommended Use Cases - **Complex narratives**: stories with rich character interactions and detailed action. - **Video editing**: instruction-based edits of existing clips with reference video/audio. - **Multi-reference generation**: images + audio driving a new video. - **Creator workflows**: CapCut/Dreamina users drafting and syncing content. - **Advertising**: precise instruction adherence for campaign assets. ## 7. Example Prompts **1. Multi-input generation** ```text Using the character from image 1, the environment from image 2, and the voice style from audio 1, create a 10-second scene where the character walks through the environment and speaks the provided line. ``` **2. Camera-planned edit** ```text Edit this video: change the camera to a slow dolly-in during the second dialogue line, then hold a close-up for the reaction. Keep the characters and audio unchanged. ``` **3. Reference video + audio** ```text Use video 1 as motion reference and audio 1 as the dialogue track. Generate a new scene in the style of image 1 with matching lip sync. ``` **Prompting guidance:** - Map inputs explicitly ("character from image 1, environment from image 2") - the model honors clear mapping. - Describe camera language directly; prompt-driven planning responds to it. - For edits, state constants before changes. ## 8. Selection Recommendations **Choose Seedance 2.0 if:** - Multi-input generation (images + videos + audio) is core to your work. - You want unified generation and editing in one model. - You are in the ByteDance ecosystem (Doubao, Dreamina, CapCut, Volcano). **Choose HappyHorse 1.0 if:** - Subject insertion (S2V/SV2V) matters more than input richness. **Choose Vidu Q3 if:** - 16-second single clips and four-track audio are the priority. **Choose Seedance 1.5 Pro if:** - Dialect lip sync (Sichuanese/Cantonese) is the requirement. ## 9. Workflow: Draft, Edit, Sync ```mermaid flowchart LR A[Brief] --> B[Gather inputs: images/video/audio] B --> C[Natural-language instruction] C --> D[Generate or edit] D --> E{Camera check} E -- Off --> F[Add camera language] F --> C E -- OK --> G{Consistency check} G -- Drift --> H[Re-map inputs] H --> C G -- OK --> I[Export] ``` **Practical notes:** - Plan input mapping before writing the prompt - richness requires organization. - Use prompt-driven camera language instead of manual keyframes where possible. - Validate subject identity across multi-input generations; the model is strong but not perfect. ## 10. The Bottom Line > **Verdict: Buy for multi-input, unified video work - the most flexible video model in the market.** Seedance 2.0's 9+3+3 input envelope, unified generation-editing architecture, and prompt-driven camera planning make it the most capable all-rounder in the category, and CapCut/Doubao distribution puts it in millions of hands. It is not the dialect specialist (1.5 Pro), the editing suite (HappyHorse), or the longest clip (Vidu Q3), and hosted-only. But for complex, input-rich video creation and editing, it is the model to standardize on. ## Sources & Further Reading - [Seedance 2.0 Official Launch - ByteDance Seed](https://seed.bytedance.com/en/blog/seedance-2-0-%E6%AD%A3%E5%BC%8F%E5%8F%91%E5%B8%83) - [Seedance 2.0 正式发布 - ByteDance Seed (Chinese)](https://seed.bytedance.com/zh/blog/seedance-2-0-%E6%AD%A3%E5%BC%8F%E5%8F%91%E5%B8%83) - [Seedance 2.0 rollout coverage - Beijing Daily](https://xinwen.bjd.com.cn/content/s698d71c1e4b0687a28912a01.html) - [Seedance 2.0 in CapCut - TechCrunch](https://techcrunch.com/2026/03/26/bytedances-new-ai-video-generation-model-dreamina-seedance-2-0-comes-to-capcut/) --- *Information reflects ByteDance Seed's official release materials as of August 2026. Model tiers and API IDs vary by platform; verify on Volcano Ark.*

Veo 3.1
Google Veo 3.1 converts text prompts into videos with synchronized audio at native 1080p for high-quality outputs
Inspiration
Ignite your imagination through a showcase of real-world creations shared by fellow users

Avatar Portrait 207

Cinematic Drift 208
Still Frame 209

3D Study 210

Robot Protects Bird From Storm
Avatar Portrait 211

Isometric Bloom
Cinematic Drift 212
Still Frame 213
3D Study 214
Avatar Portrait 215
Cinematic Drift 216
Still Frame 217
3D Study 218
Avatar Portrait 219
Cinematic Drift 220

Amber Workshop
Still Frame 221
3D Study 222
Avatar Portrait 223
What Our Users Say
Real voices, real transformations—see why professionals trust us to power their creativity
Matt
Digital Artist
The layout and tools help me explore variations fast without losing consistency.
Sarah
Designer
Great defaults and clean results. The workflow feels polished and predictable.
David
Creator
I can jump from inspiration to production-ready assets with minimal friction.
Emily
Prompt Engineer
The model selection and utilities make iteration quick and enjoyable.
Frequently Asked Questions
MuseSpark brings image, video, audio, 3D, avatar, and text workflows into one workspace, so you can move from first idea to production-ready assets without stitching together separate tools.
Start in Model Space when you want to compare base models and control how content is generated. Start in AI Tools when you want ready-made workflows for jobs like editing, translation, effects, or marketing assets.
Choose based on output type, visual style, speed, and cost. A practical flow is to compare candidates in Model Space, review real examples in Inspiration, then lock in the model that matches your quality and turnaround needs.
No. You can start with simple prompts and built-in workflows, then add references, aspect ratio, duration, or style controls only when you need finer output control.
In many cases, yes, but commercial usage depends on the model or tool you select and on whether you have rights to the source assets you upload. Check the relevant model or tool details before shipping client or brand work.
Speed depends on the model, queue state, resolution, and output length. Image jobs are usually fastest, while longer video or audio generations take more time, especially at higher quality settings.
Credits are consumed according to the model or tool you run and the settings you choose. You can review available plans on the Pricing page and track actual usage from your account after each run.
Yes. MuseSpark offers API access for supported capabilities, making it easier to connect generation workflows with internal tools, automation, or customer-facing products.

