Your AI tools launch directory. Ship smarter.
A startup directory and product launch platform for AI tools. Discover new launches, compare workflows, and submit your startup for free.
- Launches today
- 8
- Active directory
- 58
- Top categories
- 20
Daily launches
Curated drops land daily. Spot new AI products before the crowd.
Quality filters
Only practical, usable tools. No noise, no empty hype.
Community signals
Real upvotes drive trending. The strongest tools rise.
Launching today
Voiskey is an AI voice typing tool that turns natural speech into polished, ready-to-send text. Rather than transcribing your words literally, Voiskey starts from what you meant, shaping a rough spoken thought into text that fits where it is going and who is reading it. The product is described simply as "AI voice typing that understands your meaning, not just your words" — you speak naturally and Voiskey returns polished, ready-to-send text for messages, emails, notes, documents, AI prompts and more. It is built for anyone who thinks faster than they type and wants their spoken thoughts to arrive already cleaned up and ready to use, while still sounding like them. Voiskey is available on macOS, Windows, iOS and Android. The problem Voiskey targets is the gap between thinking and typing. Speaking is fast, but the keyboard slows thoughts down: the site compares a keyboard at 45 wpm with Voiskey voice at 220+ wpm and describes the result as 5x faster than typing. Typing also forces you to compose while you capture, which is why so many everyday writing tasks stall at the start — the first draft is the hardest part, the first sentence is the hardest, ideas hit fast while drafting is slow, tickets pile up faster than you can type, meeting details are easy to forget, and prompting an AI can take longer than coding. Voiskey attacks that gap by letting you think out loud and handing back something finished, so the friction of getting words out of your head and into a usable form is removed from the process. The first capability Voiskey is built around is understanding rather than merely listening. You speak the way you naturally would, and Voiskey catches the fillers, stumbles, changes of mind and grammar slips that ordinary dictation tends to leave in. This matters because unedited speech is messy: people restart sentences, circle back, correct themselves mid-thought and rely on verbal filler while they think. A tool that only transcribes leaves you cleaning up the mess by hand. Voiskey handles that cleanup as part of the transcription, so the text you get back reflects what you were trying to say rather than a verbatim record of how you said it. The second capability is adaptation. Voiskey is described as knowing what you are going for and automatically tailoring the formatting, tone and word choice so every output fits your intent and is ready to send. In practice that means the same spoken thought can arrive shaped differently depending on its destination: casual with a friend, composed with a colleague, or technical with an AI. Instead of speaking stiffly in order to produce formal text, or writing longhand to hit the right register, you speak naturally and Voiskey adjusts the output so it lands correctly for the context. Because the output is already formatted and ready to send, the step between speaking and hitting send is where the time is saved. Voiskey also learns your style and works across languages and AI tools. It learns your names, jargon and spelling preferences so your words always land in your style — useful for people with specialist vocabulary, recurring names or particular spellings they do not want corrected. It converts voice to native-sounding text in 100+ languages: you can speak in your own language when you need to translate, and Voiskey turns your voice into fluent, native text across those languages. Voiskey also lets you tell your AI what to build just by speaking: you talk through what you want to build or change, and Voiskey turns it into a clean AI-ready prompt with files, paths, commands and key details captured. That last capability is aimed at workflows where the prompt itself has become the slow part. Overall, Voiskey's approach is to meet you wherever you already type. The site states that Voiskey works anywhere on your computer and in any language: wherever you type, however you speak, Voiskey is ready when you are. There is one voice experience across every device, so the same way of working carries across macOS, Windows, iOS and Android rather than being tied to a single machine or a single app. You speak naturally, Voiskey interprets the meaning and the intended destination, and it delivers text in the form that destination requires — the core methodology being that it works from intent rather than from literal audio. The benefits Voiskey claims are speed and readiness. It is 5x faster than typing by the site's own comparison, letting you get your thoughts out before the keyboard slows them down. Output arrives cleaned up and ready to send, so there is no separate editing pass to remove fillers or restructure sentences. And because Voiskey learns your names, jargon and spelling preferences, the result still sounds like you rather than like generic machine output. For people whose work is largely written — replies, updates, notes, drafts, prompts — the combination of speaking at speed and receiving finished text changes how much writing can be done in the same amount of time. Voiskey lists concrete scenarios for its use. Engineers can prompt their AI tools by speaking, turning talk into prompts, commits and design docs, addressing the observation that prompting now takes longer than coding. Sales teams use it for call notes, CRM updates and replies, since the faster the follow-up, the warmer the deal. Customer support uses it to keep language clear across tickets, live chats and help articles. Writers and creators turn spoken ideas into posts, scripts and book chapters. Students capture lecture notes, essays and emails, getting past the difficulty of the first draft. Founders produce updates, replies and job posts at startup speed. Legal and consulting professionals turn their insights into memos, client letters and contracts. By task type, Voiskey is used for messages such as texts, DMs and quick replies; emails, where you speak a rough draft and Voiskey shapes it into clear, structured writing; notes, capturing reminders, quick lists and random ideas the moment they show up; meetings, capturing decisions, action items and follow-ups; and team updates, handoffs and action items. Voiskey's primary audience, as described on the site, includes engineers, sales teams, customer support teams, writers and creators, students, founders, and legal and consulting professionals — essentially anyone whose day involves producing written text. It runs on macOS, Windows, iOS and Android, supports over 100 languages, and is free to start. During its launch, joining gives a free month of Pro. The site positions it as a general-purpose voice layer rather than a single-app feature: it works anywhere on your computer, in any language, and the same experience follows you across every device. Voiskey's core value proposition is straightforward: speak it rough, send it right. By understanding meaning rather than only words, adapting formatting, tone and word choice to the destination, learning each user's names, jargon and spelling, and operating across four platforms and 100+ languages, Voiskey removes the friction between thinking and finished writing — at a claimed 5x the speed of typing, with output that arrives ready to send and still sounds like the person who said it.
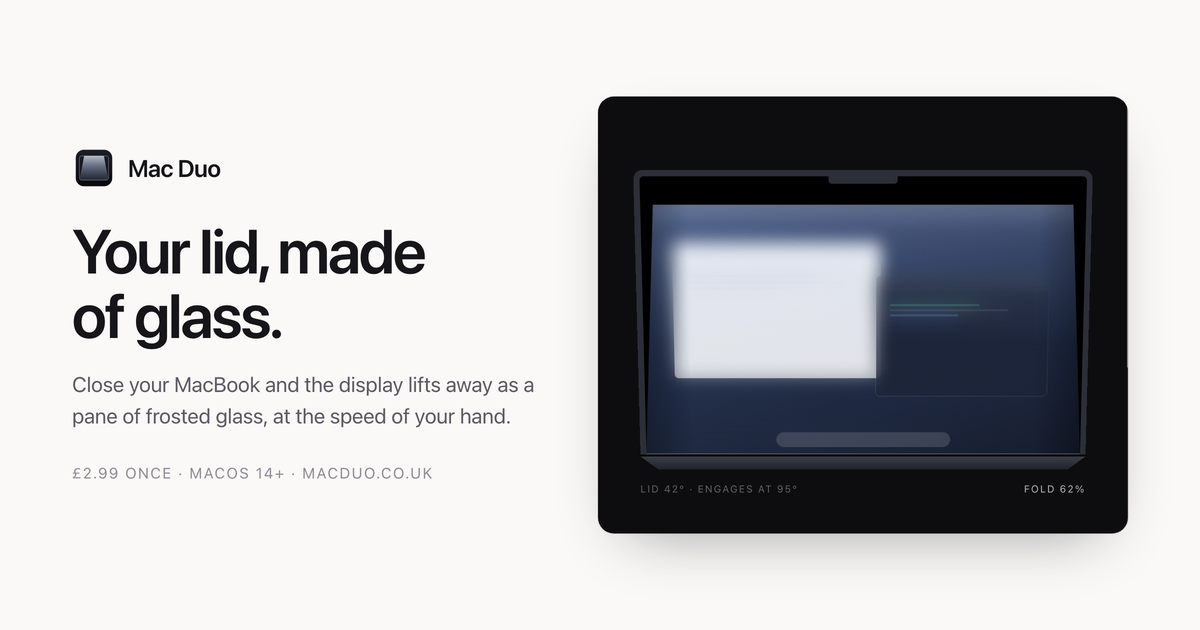
Mac Duo is a macOS app that turns your display into a pane of frosted glass as you close the lid. Close your MacBook and the display lifts away as a pane of frosted glass, moving at the speed of your hand: stop, and it stops; open it again and the whole thing retraces itself. The site describes the app as producing "a material" and "a small event, every time" — a pane of frosted glass, hinged along the bottom edge of your display and moved by your lid. It sits quietly in the menu bar, and it is aimed squarely at MacBook owners who want a distinctive, physical-feeling effect attached to an everyday action rather than a static overlay painted over their screen. The idea comes from the fold on iPhone Duo, recreated on a MacBook, and the site is deliberate about how that effect is built. Rather than being painted over a screenshot, the glass is modelled — it lifts, leans and catches the light. That distinction runs through everything described on the page: the team repeatedly contrasts what Mac Duo does with a blur laid on top of a capture. What the app delivers is a small, repeated moment that accompanies opening and closing a laptop: a hinge-driven material that behaves like a real pane of glass sitting above the screen, with a gap that opens and closes in step with the lid. Every behaviour documented on the site — engagement angles, frost growth, grain in the material — follows from that framing of glass as a material rather than a filter. The first capability is that your lid moves it, and nothing else does. The fold reads the lid-angle sensor directly. Move slowly and it moves slowly. Stop halfway and it holds there. Reverse, and it unfolds. The page shows a live readout of the lid angle alongside the fold position, and notes that Responsiveness and Hinge sensitivity decide how tightly the fold tracks your hand. Because the same lid angle always means the same glass, opening the lid retraces the closing animation exactly, which makes the effect fully reversible and predictable rather than a one-way animation that plays when the lid opens or closes. The second capability is clear where it touches, frosted where it lifts. The pane lifts off the display as it tilts. The gap is nothing at the hinge and grows toward the top, so the bottom of your screen stays almost untouched while the top frosts over. The site illustrates this with a diagram showing the gap driving the frost, noting a value such as 0.20 at the top, and stresses that the frost climbs with the gap between pane and screen: the bottom of your display stays clear and the top goes milky. Closely tied to this is the third capability — etched glass, not a blur. Grain sits in the material and there are no highlights, because etched glass scatters light rather than reflecting it. The app explicitly positions itself as "not a blur laid over a screenshot." Inside the app, you can see every change without closing a thing. A live picture of the material sits beside the controls, with a scrubber that runs the fold by hand, so the effect can be inspected without repeatedly opening and closing the laptop. Frost, Perspective and Edge softness shape the glass, while Responsiveness and Hinge sensitivity decide how tightly it tracks. Intensity offers Low, Medium and High with those sliders underneath, and the glass can match your system appearance or stay light or dark. Play the fold to watch the whole thing, and Reset puts every setting back. The app can also show the live lid angle in the menu bar, where it sits quietly. How the product works overall is set out in the details section. Lid sensor: Mac Duo reads the hinge angle from the Mac's own sensor — the fold engages at 95° and is complete by 12°, and the same angle always means the same glass, so opening retraces closing exactly. Live display: your screen is captured and the glass is rendered over it with Metal, so windows and wallpaper move as one surface rather than as layers. At rest: nothing runs while the lid is still — no background work, and no cost to leaving it on. Screen Recording permission is required and, the site says plainly, is not optional: the glass is built out of your live display, so without that permission there is nothing to render. Several benefits follow directly from that design. On privacy, the display is read to build the glass and those frames stay in memory — nothing is written to disk and nothing is sent anywhere. Capture runs only while the lid is in motion and stops the moment it settles. Mac Duo has no analytics, accounts or tracking; its only network connection is an optional software-update check against macduo.co.uk, which can be turned off at any time. There is no account, no licence key and no trial countdown: you pay, download the disk image, drag it to Applications, and the app is yours on up to five Macs, with a refund available on request. On performance, the site states that it does nothing at all when the lid is not moving — no background work, no polling — and that while animating it takes about 1.5 ms a frame on an M3 at full resolution, with room to spare at 120 fps. In practice, Mac Duo is used in the moment you close and open your MacBook lid: the fold engages as the lid passes the engagement angle, tracks the motion of your hand, holds when you stop halfway, and unfolds when you reverse. The app window supports inspecting and tuning the material without closing anything — a live picture sits beside the controls, a scrubber runs the fold by hand, Play plays the whole fold and Reset restores every setting. The menu bar keeps the live lid angle visible if you want it, and the software can be installed on up to five of your own Macs. The site also presents the effect recorded live, with no cuts, as a demonstration of how it behaves in real time. Requirements and details are documented in advance. Mac Duo needs macOS 14.0 Sonoma or later and any Mac with a built-in display. Apple silicon MacBooks get the full effect because they carry the lid-angle sensor the animation is driven by. Intel MacBooks work, but fall back to a timed animation on lid open and close rather than tracking the hinge continuously. Desktop Macs have no lid, so there is no effect. The download is a universal binary at 2.3 MB. Pricing is a single payment of £2.99 covering up to five Macs, with a refund on request. One rough edge is stated up front: the build is not yet notarized by Apple, so the first launch will warn that macOS cannot verify the app is free of malware — the workaround is to open System Settings → Privacy & Security, scroll down and click Open Anyway, which is only needed once. Mac Duo's proposition is narrow and specific: turn your display into a pane of frosted glass as you close the lid, driven by the hinge sensor so it moves at the speed of your hand. It is a material rather than a blur or a screenshot overlay — it lifts, leans and catches the light, frosted where it lifts and clear where it touches, with grain instead of highlights. It runs only while the lid is moving, keeps everything on your Mac, needs no account or licence key, and costs £2.99 once for up to five Macs.
PeekPaste is a native clipboard manager for Mac, built by LucidBit, that keeps a thoughtful history of what you copy — text, code, links, images, colours and files — and brings it back with a simple gesture. Move your pointer to the edge of the screen and a panel of your recent clips slides in over your work; choose one and it goes straight back into the app you were in. It is designed for macOS 14 (Sonoma) or later as a native Apple Silicon (arm64) app, and it is aimed at anyone who copies and pastes throughout the day and wants that history to be instantly, unobtrusively reachable. The clipboard on macOS is a single slot: the moment you copy something new, whatever was there before is gone. That is fine until you need a snippet you copied half an hour ago, an address you copied before a phone call, or a screenshot that is still sitting somewhere on your desktop. The usual workarounds — keeping a scratch document, re-copying from the source app, or taking another screenshot — all cost attention. PeekPaste's answer is to treat the clipboard as something worth remembering. It stores your history locally, presents each item in a form that matches what it actually is, and makes retrieving it a matter of one small gesture rather than a search through other applications. The trigger is deliberately physical. Push your pointer against an edge of the screen and PeekPaste appears over whatever you were doing. You choose which edge, how long the pointer has to dwell there before the panel opens, and you can turn the edge trigger off entirely in favour of a global keyboard shortcut — or use both together. Hovering a card and pressing Space opens a full preview of the clip; move to the next card and the preview follows. Because the panel is an overlay rather than a window, there is no Dock icon and no window to manage, and light mode, dark mode and Reduce Motion are all respected. Each clip is presented for what it is. Code is syntax-highlighted, links carry their title and preview, colours become swatches, and files remain files; every item also remembers the app it came from. That context matters when a history grows, because a colour or a file name is far easier to recognise visually than it is as an anonymous row of text. Previewing before pasting means you can confirm the right clip — full-size images, readable documents, highlighted code — without leaving the app you are working in. Screenshots are a special case that PeekPaste handles on-device. Text inside captured images is recognised on your Mac and made searchable, so a screenshot of an error message, a receipt or a slide can be found by searching for words that appear inside the picture, exactly as if that text had been copied normally. The recognition runs locally; nothing about the image or the extracted text is uploaded. Beyond raw history, PeekPaste offers structure. You can pin the clips you reach for constantly, file the rest into categories you name and colour yourself, and filter the history when you need to narrow things down. You control how long clips are kept — a week, a month, a year, or forever — and older items clear themselves when their time is up. Transforms let you change the way a clip leaves the app: strip formatting so pasted text matches its destination, change case, trim whitespace, or encode a URL, all without touching the original. Privacy is a design decision rather than a setting. PeekPaste has no analytics, no account and no clipboard sync server; everything is local and stays on your Mac. When a password manager marks content as confidential, macOS flags it and PeekPaste honours that flag — the clip can be pasted again but is never legible on screen. You can also switch off password capture entirely, name specific apps that PeekPaste should never record from, or mark an individual clip as sensitive. When you copy a web link, PeekPaste can fetch that link's preview; your clipboard contents are not otherwise sent to LucidBit. If you want automatic pasting, PeekPaste asks for Accessibility permission so it can return to the app you were using and send the paste command for you — and you can skip that entirely, in which case the clip is simply placed on your clipboard ready to paste normally. The overall approach is gesture-first and local-first. Rather than asking you to learn a new place to look, PeekPaste borrows the edge of the screen you already use and stays out of the way until you summon it. Rather than sending your clipboard to a service, it keeps everything on the machine and gives you explicit controls over what is remembered. And rather than treating all clips as interchangeable strings, it renders each one in a form that reflects its type and origin. The benefit is time and attention. The thing you copied is still there when you need it, whether that was a minute or a month ago, and retrieving it takes a gesture rather than a detour. Because every item is previewed in its natural form, you paste with confidence instead of guesswork. Because retention, categories and pins are yours to configure, the history stays useful instead of becoming another inbox to manage. And because nothing leaves the Mac, using it does not require trusting a cloud service with your clipboard. Concrete workflows show where this matters. A developer copying functions, commands and configuration values keeps a syntax-highlighted, searchable trail of snippets that can be pasted again without returning to the source file. Someone reviewing an error message that arrived as a screenshot can search for the words inside the image rather than retyping them. A designer working with colours can revisit a swatch copied earlier and paste it into a document or codebase. Anyone collecting research can find a link by its title and preview instead of by its URL characters. Clips can be dragged directly into any app, or dropped on the Desktop to be saved as a file. And for people handling sensitive material, the app rules and confidentiality handling mean a searchable history can exist without a password manager's output ever being legible on screen. PeekPaste is a Mac-only, native arm64 build requiring macOS 14 (Sonoma) or later. Pricing is a one-time $9.99 purchase with a 7-day free trial; there is no subscription, every feature is unlocked from day one, lifetime updates are included, and no account is required. It is available from the Mac App Store or through Lemon Squeezy, with secure checkout via App Store local pricing or Lemon Squeezy in USD, powered by Stripe. A Product Hunt launch offer of $6.99 (30% off) using code PEEKPASTEPH was valid until September 30 for the first 50 redemptions. It will suit developers, designers, writers, researchers and privacy-conscious Mac users who want clipboard history that is fast to summon and stays on the machine. PeekPaste takes the most disposable part of a Mac workflow — the single clipboard slot — and turns it into a private, searchable, gesture-accessible history of text, code, links, images, colours and files. Your clipboard, within reach, and nothing of it anywhere but your Mac.
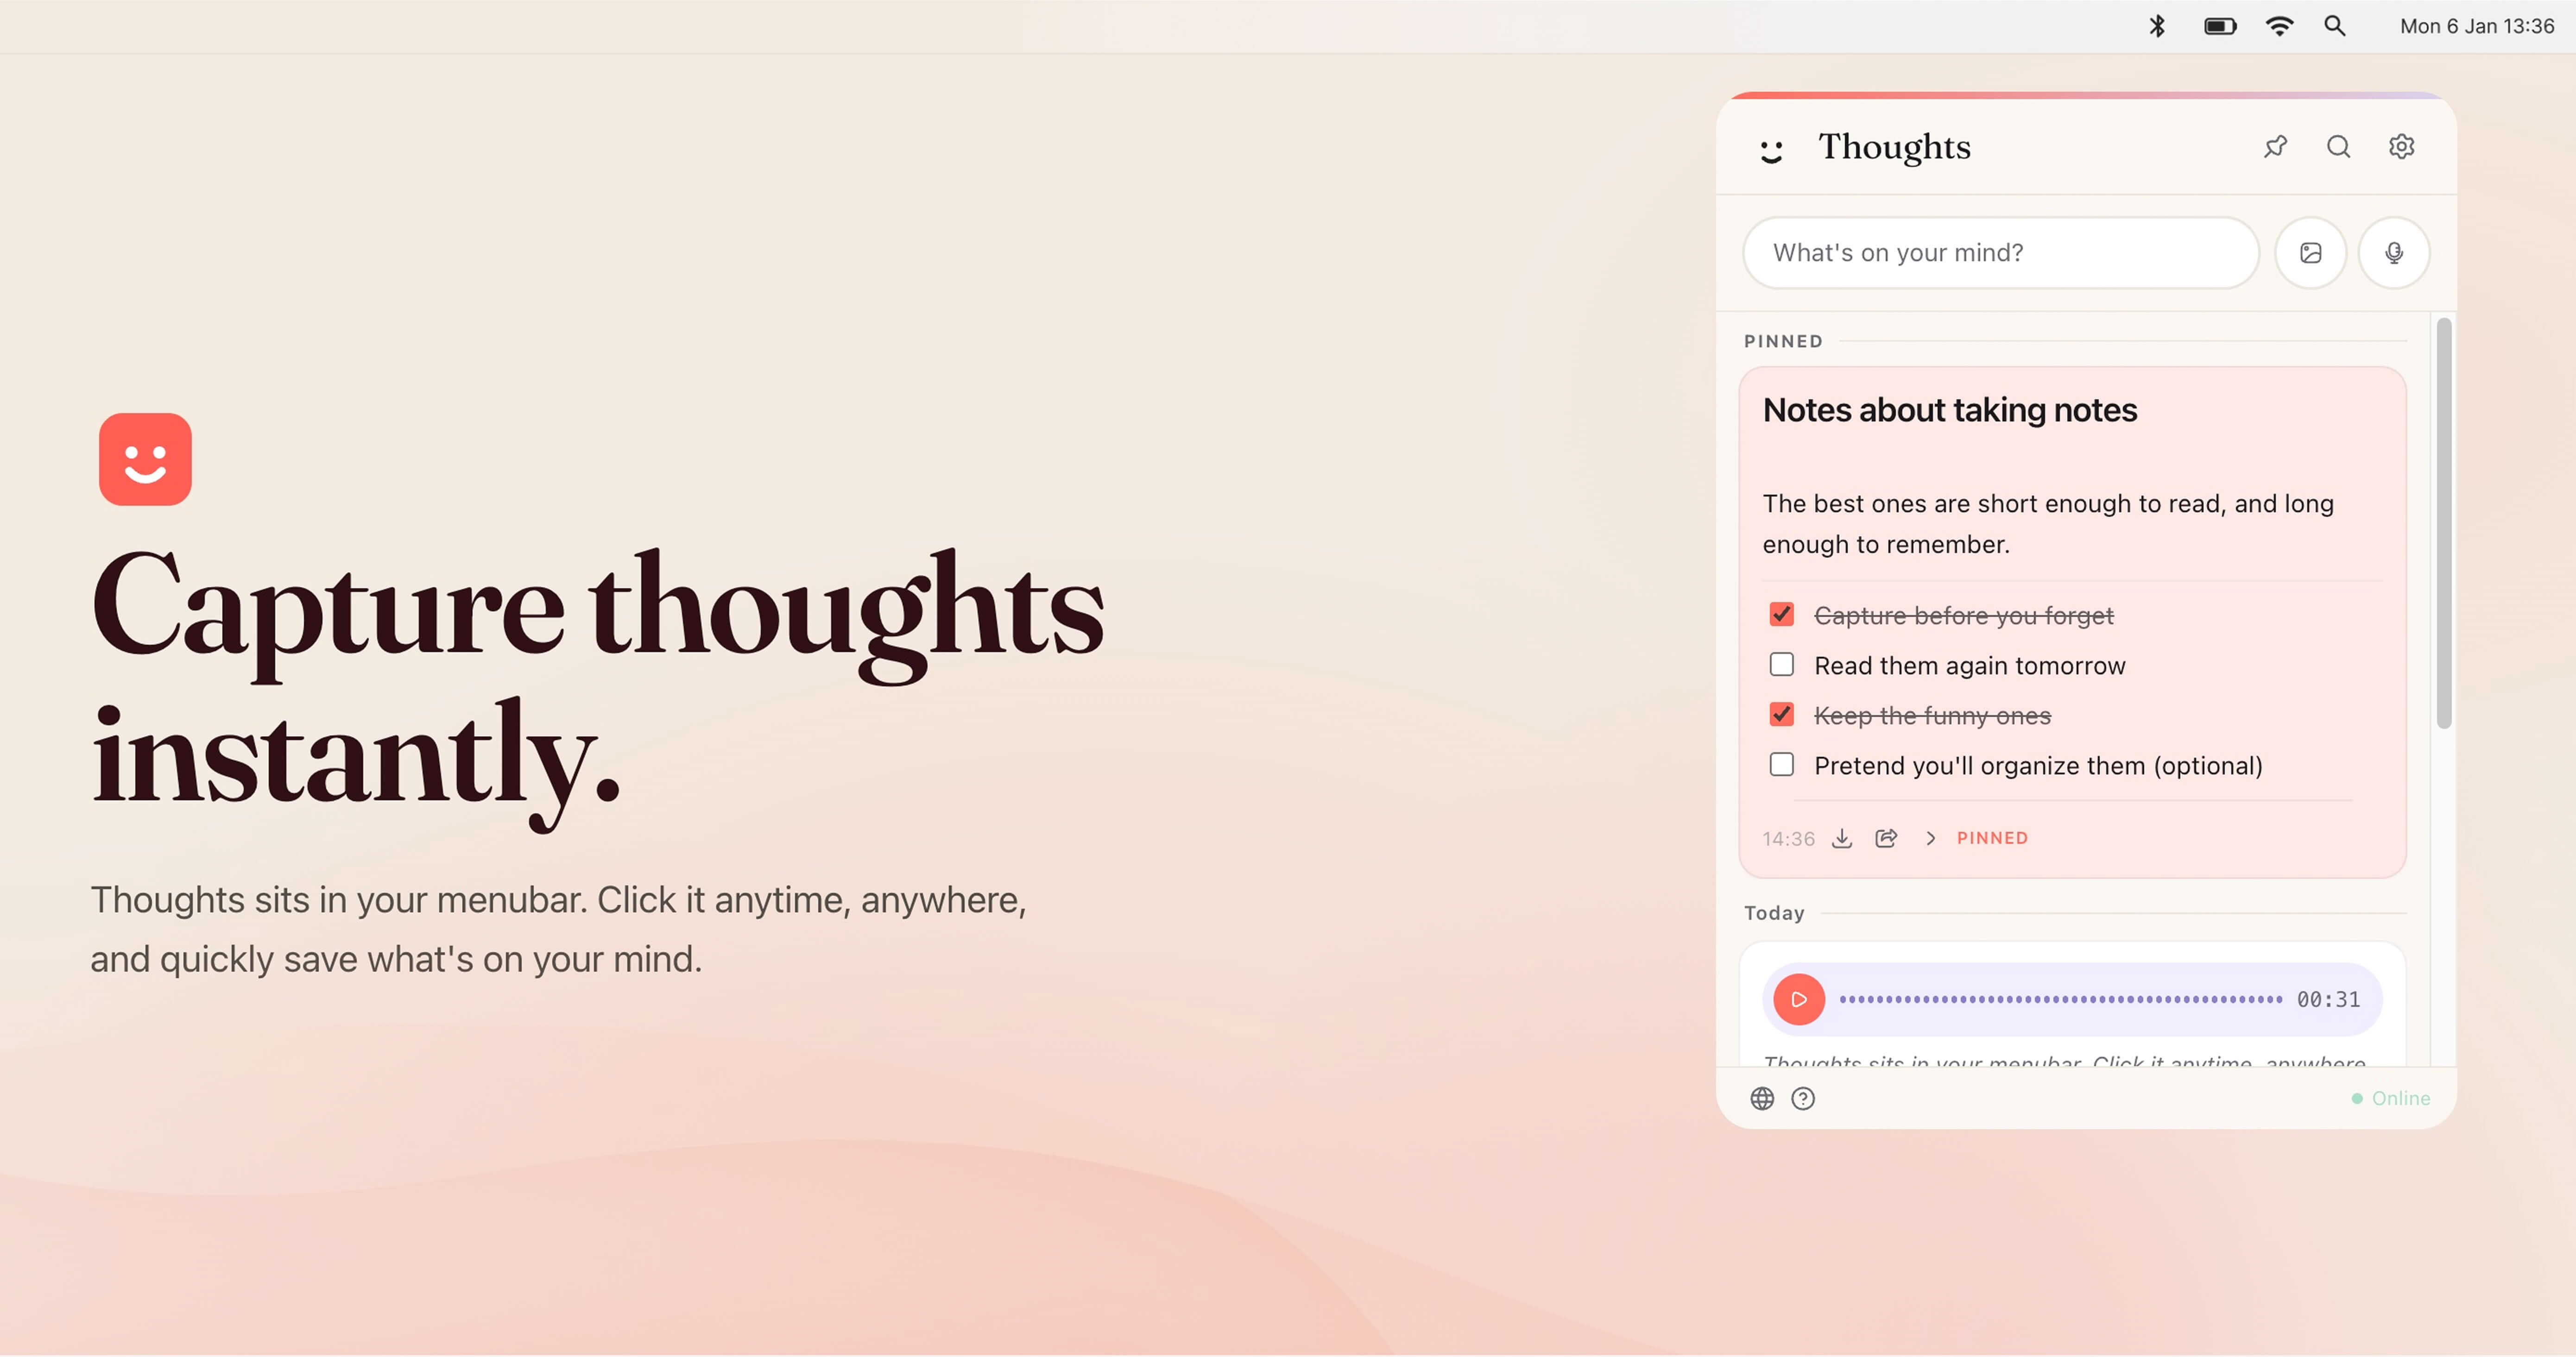
Thoughts for Mac is a menubar application that helps Mac users capture thoughts instantly. It sits in the macOS menubar, so you can click it anytime, anywhere, and quickly save what is on your mind without opening a separate full-screen app. The product is designed as a fun small multi-tool for your menubar, allowing you to keep notes quickly using text, images, and voice. It captures structured text notes, checklists, code blocks, standalone links with previews, voice recordings, images, and text-like files such as TXT and CSV. It is intended for Mac users who want a fast, low-friction way to record ideas, tasks, links, screenshots, and voice memos while staying in their current workflow. The app requires no account, saves notes and settings locally on your Mac, and can connect to your own OpenAI, Claude, or Gemini API key for AI-powered actions. Traditional note-taking often requires switching away from what you are doing, opening a separate application, and finding the right place to type. That context switch can cause fleeting ideas to be lost. Thoughts addresses this by living in the menubar, making capture available from anywhere on your Mac. A custom shortcut provides instant access, so you can open Thoughts without hunting through the Dock or Applications folder. Because notes and settings are saved locally on your Mac and media files are stored in the app's user data folder, you do not need an account to start capturing. Browser preview mode is session-only, meaning notes there are temporary, which reinforces that the desktop app is the primary place for persistent local notes. This local-first approach is useful for people who want quick capture without committing to a cloud account or subscription. The core of Thoughts is flexible capture. You can use the Write it feature to type structured text notes, checklists, code blocks, and standalone links that appear with previews. The Drag in an image feature lets you bring images into your notes, and the Talk to it feature lets you capture voice recordings. The app supports voice-to-text and image-to-text, along with screenshot capturing. On desktop builds, Thoughts can also receive shared text, images, and audio from URL schemes, open-with actions, macOS Services, and native imports. This range of input methods matters because thoughts do not always arrive as typed text; sometimes they are a screenshot, a voice memo, a link, or a quick checklist. By supporting multiple formats in one menubar app, Thoughts aims to reduce the friction of choosing a different tool for each type of content. AI-powered actions are optional and use your own API key. You can connect OpenAI, Claude, or Gemini in Settings. With a connected key, Thoughts can help transcribe audio, context images to text, and perform simple text transforms such as capitalization, translations, and spelling fixes. The app lists AI actions for shortening, lengthening, summarizing, fixing spelling, translating, converting case, transcribing voice notes, and extracting text from images. Claude is available for text actions, while transcription support depends on the provider. This bring-your-own-key model means the AI features are not tied to a separate Thoughts subscription; instead, you use the provider and key you already have. It is useful for turning a voice recording into searchable text, pulling text out of a screenshot, or quickly rewriting a note without leaving the menubar. Thoughts also helps you find and keep important content. You can search across notes, links, screenshots, and image names instantly. Pinned Thoughts let you keep important notes at the top of your list, which is useful for recurring tasks, key references, or ideas you return to often. Export and share options allow you to share notes as text or export audio recordings whenever you want them. From Settings you can export all notes as JSON. Individual notes can be exported in the best available format: text notes as TXT, image notes as image files, PDF attachments as PDF, and voice notes as MP3 in the desktop app. Light and dark mode let Thoughts adapt to whichever you prefer. These features make the app not just a capture tool but also a lightweight system for retrieving, prioritizing, and moving your notes out when needed. Overall, Thoughts works as a menubar-first, local-first note capture utility. You trigger it from the menubar or your own custom shortcut, then save content using text, voice, images, screenshots, links, or supported files. Notes and settings are stored locally on your Mac, and media files are saved in the app's user data folder. No account is required. The optional AI layer is separate: you bring your own OpenAI, Claude, or Gemini API key, and the app sends requests to those providers for actions such as transcription, OCR, summaries, translations, and rewrites. The desktop app can receive shared content through macOS mechanisms like URL schemes, open-with, and Services. This combination of native macOS integration, local storage, and optional third-party AI makes Thoughts a compact multi-tool rather than a full project management or collaboration suite. For users, the main benefit is speed and convenience. Thoughts sits where you already are, so capturing a thought takes a click or a custom shortcut instead of opening another app. Supporting text, images, and voice means you can choose the fastest input for the moment. Local storage and no account requirement give you control over where notes live. The bring-your-own-key approach avoids a mandatory AI subscription, letting you use the provider account you already have. Search, pinning, and export options help you manage accumulated notes and avoid lock-in, because you can export all notes as JSON or individual notes in formats like TXT, image, PDF, and MP3. Light and dark mode keep the app comfortable in different environments. Together these benefits support a low-friction capture habit without adding another cloud account or complex setup. Concrete use cases include capturing a quick thought while working in another application, recording a voice note and later transcribing it to text, dragging in an image or taking a screenshot and extracting text from it, and using text transforms to shorten, lengthen, summarize, fix spelling, translate, or change case. You can save standalone links with previews for later reference, create checklists for tasks, or store code blocks for development notes. Pinned Thoughts can keep important notes at the top for ongoing projects. When you need to share or archive, you can export notes as text or export audio recordings, and you can export all notes from Settings as JSON. Because desktop builds can receive shared text, images, and audio from URL schemes, open-with, macOS Services, and native imports, Thoughts can also fit into existing macOS sharing workflows. Thoughts is aimed at Mac users, particularly those focused on productivity and writing. It suits people who want to capture notes quickly from the menubar using text, images, or voice, and who may already have an OpenAI, Claude, or Gemini API key for AI-powered actions. The app is native macOS and integrates with those AI providers through your own key. It also supports macOS sharing mechanisms such as URL schemes, open-with, macOS Services, and native imports on desktop builds. Pricing is free: Thoughts is free to download and use, including future updates, with no subscription for the app itself. AI features require your own API key, so any costs from OpenAI, Gemini, or Claude are separate. Notes and settings are saved locally, and no account is required. In summary, Thoughts for Mac is a free, native macOS menubar app for instant note capture. It lets you save text, images, screenshots, links, voice recordings, and supported files without leaving your current workflow. Search, pinning, export, light and dark mode, and a custom shortcut make notes easy to retrieve and manage. Optional AI actions through your own OpenAI, Claude, or Gemini key add transcription, image-to-text, summaries, translations, and text fixes without a separate app subscription. The primary value proposition is fast, local-first capture with flexible input and optional AI, all from a small menubar multi-tool.
tiun. is an AI-native backend built for AI and SaaS companies, giving builders one system for authentication, payments, customer database, and analytics. According to the website, tiun gives AI and SaaS companies the backend they need to ship, scale, and grow their business in one unified platform, replacing a patchwork of single-purpose services with an ecosystem of services that are designed to work together from the start. The product is aimed at builders — developers and founders — who want to launch paid products quickly, and its public materials state that with one install command you can launch a paid product the same day you start building. The problem tiun addresses is the hidden complexity created by single-purpose tools. The website states that using separate services for auth, billing, customer data, and analytics creates multiple accounts, scattered data, and costs that compound as you scale. Builders are left maintaining business logic just to keep systems in sync, which makes the insights they need harder to reach. tiun describes itself as the backend powering the AI engineering era, and its stated approach is to remove that glue work: no webhook logic and no business logic to handle, because the services are designed to work together. This matters because every hour spent wiring up sync logic between disconnected tools is an hour not spent building the product itself, and because scattered data hides the very signals — who signs up, who pays, and how the product is used — that a company needs in order to price and grow. Authentication is the first of the core service groups. tiun provides sign up, login, and logout as simple and secure user authentication that is ready to use out of the box. It also ships User Button and User Profile components, which give users a dropdown menu to access their account so they can manage their profile and security settings without custom UI work. Multifactor authentication is supported through SMS passcodes, email, and social SSO. Together these pieces cover the account lifecycle that a paid product needs on day one, from creating an account to protecting it with a second factor or a social identity provider, and they remove the need for a builder to assemble and maintain that surface area themselves. Payments and billing form the second group, and tiun's stated promise is that you can start billing without writing payment code or wrangling webhooks. Users can create products and billing plans and accept one-time payments, subscriptions, and usage-based billing from day one. Checkout components are pre-built and ready to drop in as an overlay, so users never leave your page during the purchase flow. tiun also acts as your Merchant of Record: it processes your payments, pays out monthly, and includes tax compliance and chargebacks. The website compares transaction fees, showing tiun transaction fees of 2.9% + $0.30 and a total of roughly 3.4% + $0.30 in its example for international transactions. Because billing sits inside the same platform as the customer database, subscription state does not have to be reconciled across separate services. The customer database is the third group, and tiun states that every user, transaction, and session is stored in one place, with no syncing between tools. User management keeps each customer's subscription status up to date and stored with their user data, so builders do not have to build or maintain complex synchronization logic. Advanced event and session tracking records how users move through your product: every login, purchase, and product interaction is logged at the profile level. The platform also handles transactional emails for key user actions such as confirmations, password resets, and purchases, and it gives customers an invoice history where they can access, view, and download receipts and invoices from their user profile. Users can manage their own plans — upgrading, downgrading, or cancelling directly, with no support ticket required — and Data APIs provide one queryable API built on a consistent model, kept in sync and ready to plug into your stack. AI Analytics turns that shared data into something the whole team can act on. Because all data lives in one place, tiun says you can finally see the full picture: who is signing up, who is paying, how they use your product, where they get value, and how to price your product. The company frames this as one system that your entire team — business, engineering, product, and marketing — can work with, rather than a set of disconnected dashboards. For a SaaS or AI company this is significant because pricing, product, and go-to-market decisions all depend on the same underlying facts about customers, and having them in a single system reduces the friction of getting answers. Integration is handled through skills and the Model Context Protocol. The stated workflow is to install tiun's skills, connect the MCP, and let the AI agent do the hard work. The command shown on the site is npx skills add https://mcp.tiun.business, with deeper instructions in tiun's documentation. A customer testimonial on the site, from David Becker, founding member at Braintonic, describes trying the MCP integration and finding that it worked so well there was no backend, no webhooks, and no custom logic. Another, from Ferdinand Meyer, founder at moss, says he tried integrating tiun for a side project and it worked like a charm, calling it an absolute no brainer for future solo builders and founders. This agent-first installation is tiun's distinctive approach: rather than asking a developer to hand-wire several services together, it exposes the whole backend to an AI agent that performs the setup. The benefits follow from consolidation. Builders get a single system instead of multiple accounts and scattered data, and they avoid the compounding costs the site associates with maintaining several tools. The Product Hunt summary states the practical outcome plainly: one system for auth, payments, customer data, and analytics, one command to install, and the ability to launch a paid product the same day you start building. Because subscription status, events, sessions, and transactions live together, the insights needed to price and grow a product are reachable without extra integration work. The website also presents a case study: Res Publica increased their user base by 21% in the last 12 months by introducing usage-based billing with tiun, with Martin Stedler, CEO at Res Publica, Cicero, quoted alongside it. Concrete use cases described in the content include solo builders and founders starting a side project who need authentication and billing without building a backend, and new AI or SaaS products that need to launch a paid offering on the same day that development begins. Usage-based billing is a stated scenario: the Res Publica case study describes a company that grew its user base after introducing usage-based billing with tiun. Teams are another: business, engineering, product, and marketing functions are each named as groups that can work with the same unified system and the analytics it produces. Companies that want to accept one-time payments, subscriptions, or usage-based billing from day one, and that want tax compliance and chargebacks handled through a Merchant of Record arrangement, are also directly addressed by the payments offering. tiun is positioned for AI and SaaS companies and for builders generally — developers, founders, and operators who would otherwise assemble separate tools. The site notes that the company is supported by investors, founders, and operators. On integration, the platform connects through the Model Context Protocol and skills installed with a single command, and it is presented alongside a section labelled "INTEGRATE tiun with," although no specific third-party integrations are named in the content provided. Pricing information points to a dedicated pricing page and a "why tiun" comparison page; the visible fee example is 2.9% + $0.30 in transaction fees, with a total of roughly 3.4% + $0.30 for international transactions. Access starts with a "Try for free" action that leads to my.tiun.business, and documentation lives at docs.tiun.io. Taken together, tiun's value proposition is a single, AI-native backend that removes the seams between authentication, payments, customer data, and analytics. By installing skills and connecting MCP, builders let an agent wire up the backend, so there is no webhook logic and no business logic to maintain. The result, as the site puts it, is one system for auth, payments, customer database, and analytics — one that an entire team can work with, and that lets a builder launch a paid product the same day they start building.
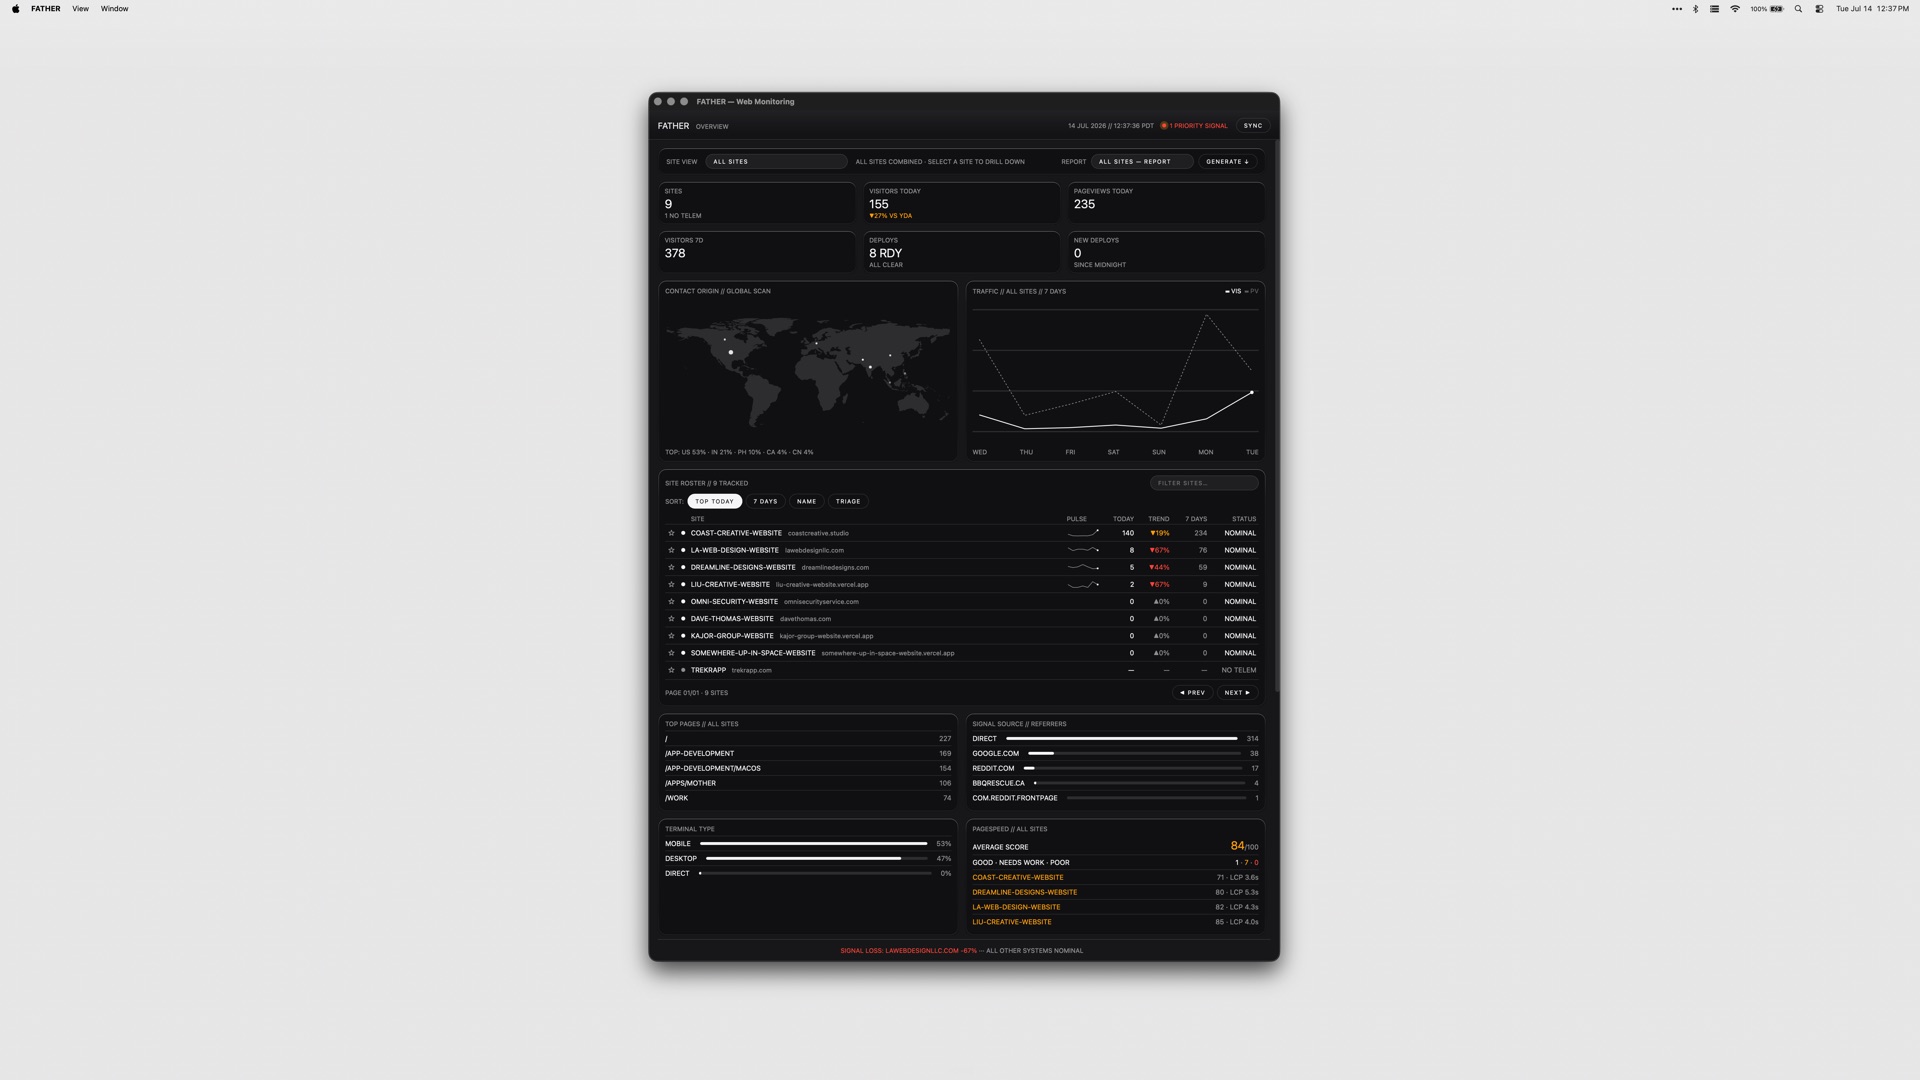
FATHER is a macOS web-monitoring app built as mission control for Vercel sites and deployments. It is designed for teams that ship on Vercel and need one place to watch the whole fleet instead of checking multiple dashboards by hand. Once you connect your Vercel account, the dashboard fills itself with deployments, uptime and speed metrics, live. Product Hunt describes it as a Mac dashboard for site traffic, deploys, uptime and SEO, while the developer's site frames it as a mission-control dashboard for your sites and deployments, built for teams shipping on Vercel. FATHER watches the fleet so you don't have to, and its stated goal is to make sure you know a site is down before your clients do. It runs as a universal app on Apple Silicon and Intel Macs. The underlying problem FATHER addresses is visibility. When a team ships on Vercel, the signals that matter — whether a build succeeded, whether traffic is arriving, whether a site is up, how fast it responds, how it ranks in search — are spread across the Vercel dashboard, Search Console, Bing, and other tools. Watching all of those manually means someone has to remember to look, and by the time a human notices a failed build or an outage, a client has usually already noticed it first. The product's framing is blunt about this: you should know a site is down before your clients do. Failing builds, expired SSL certificates, lapsing domain renewals and failing GitHub checks are all things that can take a site down or break it quietly, and each one lives in a different place. FATHER pulls those signals into a single Mac dashboard and pushes alerts to you when something needs your attention, rather than waiting for you to go looking. FATHER's data foundation is the Vercel API. Deploy tracking, speed metrics and uptime metrics all come from that API, which is why connecting your account token makes your projects appear automatically — there is no manual configuration of each project required to get started. Product Hunt's description notes that connecting your account makes every project fill in live with traffic, deploys, uptime and PageSpeed scores. Sites that are hosted somewhere other than Vercel can still be added manually, which gives them basic status checks alongside the Vercel projects. That combination means the app can act as one dashboard even for a mixed portfolio, while the deepest data — live deployments, speed and uptime from Vercel — applies to the projects actually running on Vercel. Because the connection is made with an account token, setup is a one-time linking step rather than an ongoing sync task. The dashboard's core view is the fleet at a glance: the status, uptime and response of every site on one screen. Instead of opening a hosting panel and reading project by project, you see the whole set at once and can spot the one that is off. Deploy tracking sits alongside that view and works live from Vercel, letting you watch builds progress as they run and catch failures the moment they land. The menu bar carries the same signal outside the window. The F shows a dot while builds are running and turns red when something needs you, so the state of the fleet is legible from the top of the screen without the dashboard being open. Together these three pieces cover the everyday loop of shipping: watch the build, confirm the site is up, and notice immediately when either stops being true. Alerts that find you are a deliberate part of the design: notifications fire even when the dashboard is closed. Product Hunt's description is specific about the failure case — when a build fails, the menu-bar F turns red and a notification fires, even with the window closed, so you know a site is down before your clients do. Beyond deploys and uptime, FATHER aggregates SEO signals: Search Console and Bing show clicks, rankings and indexing, which is the search-side view of how each site is performing. Operational housekeeping is covered too. SSL and domain renewals get a countdown, so a certificate or domain that is about to lapse shows up as something with a deadline rather than a surprise, and failing GitHub checks get flagged. Between them, these features put the search picture and the maintenance picture in the same place as the deploy and uptime picture. The overall approach is a single Mac app that acts as a reading layer over services you already use. You connect your Vercel account with a token; the app pulls deploy, speed and uptime data through the Vercel API and fills the dashboard automatically. Vercel-hosted projects appear on their own, and non-Vercel sites can be added manually for basic status checks. Search Console and Bing supply the SEO data, so ranking and indexing information lands next to hosting information. Alerts are delivered through system notifications and through the menu-bar item, which is what allows them to reach you when the dashboard window is not open. Tokens stay on your Mac, which the product presents as the security posture for the connection. FATHER is part of a suite of four apps that share the same set of themes, and it is sold as a one-time purchase rather than a subscription. The outcome FATHER aims for is fewer surprises. Because builds, uptime, response, traffic, PageSpeed scores, search clicks, rankings, indexing, SSL and domain deadlines and GitHub checks are all surfaced in one dashboard and through notifications, the things that normally get discovered late — a failed deploy, a site that has gone down, a certificate about to expire — get discovered as they happen. That is directly tied to the product's stated promise of knowing a site is down before clients do, which matters most for teams whose sites are the work they have delivered to someone else. Running in the menu bar means the status of the fleet is available at a glance throughout the day without opening anything, and the red F is a persistent, low-effort signal that something needs attention. The one-time purchase and the fact that tokens stay on your Mac keep the model straightforward: you buy the app, connect your account, and the data is read from services you already have. Concrete use cases follow from how the app is built. A studio or agency that ships client sites on Vercel can keep the whole portfolio on one screen and rely on notifications to learn about a failed build or an outage without polling hosting panels. A developer mid-deploy can watch the build progress live from Vercel and see the menu-bar F hold a dot while it runs, then turn red if it fails. A site owner tracking search performance can read Search Console and Bing clicks, rankings and indexing next to uptime and response, without switching tools. Anyone responsible for maintenance can use the SSL and domain countdown to act before a renewal lapses. Teams that also host sites outside Vercel can add those manually for basic status checks and keep them in the same fleet view. And because notifications fire with the dashboard closed, the app works as a background watch rather than a window you have to remember to open. FATHER is aimed at teams shipping on Vercel — the Product Hunt description describes it as being for teams, and the site repeats that framing. It is a macOS application and universal, running on both Apple Silicon and Intel Macs, with no other platforms listed. Its integrations are the services it reads: the Vercel API for deploy tracking and for speed and uptime metrics, Google Search Console and Bing for clicks, rankings and indexing, and GitHub, whose failing checks get flagged. Pricing is a one-time $7.99, or $22.99 for the full suite of all four apps from the same studio; no subscription is mentioned. The app ships with the same set of themes as the rest of the suite, and the tokens for the connection stay on your Mac. FATHER's value proposition is one screen and one alert channel for everything that can go wrong with a Vercel-hosted site. It does not ask you to change how you ship; it connects to the services you already run on and reads them back to you live — deployments, uptime, speed, traffic, search performance, renewals and checks — with a menu-bar indicator and notifications that reach you whether or not the dashboard is open. For teams whose clients depend on the sites they ship, that turns monitoring from something you remember to do into something that finds you first.

Anthropologic is a consumer research platform that describes itself as "the zero distance consumer research platform." According to its Product Hunt listing, it reads the whole internet through its Human Context Protocol to uncover consumer, category and cultural truths. The platform bundles nine workflows and covers 239 markets and more than 100 languages, with the promise of research, innovation and foresight answers delivered in minutes. On the website, those workflows are presented as a Quickstart menu of launchable tools — Trends, Discourse, Digital Segmentation, Foresight Simulator, Creative Evaluation, Synthetic Survey, Ask an Anthropologist, Brand Performance and Cultural Semiotics — plus an Innovation workflow marked "coming soon." Anthropologic frames itself against three existing approaches to understanding consumers. Traditional research, in its own words, is deep but slow. Social listening is fast but shallow. Large language models are fluent but culturally blind. Each of these has a cost: slow research struggles to keep pace with a category that moves week to week, fast social listening captures volume but not meaning, and fluent AI output can sound authoritative while missing the cultural codes that actually govern behaviour. Anthropologic positions its Human Context Protocol as the answer to that gap — a way to read the internet at scale while retaining cultural context, so that the resulting insight is both broad and grounded. The stated outcome is consumer, category and cultural truth, available in minutes rather than through a lengthy research cycle. The platform's discovery workflows are designed to map what is happening in a category. Trends shows what is moving in a category, backed by social proof and search patterns — the site illustrates this with search volumes and behavioural statistics such as 1,220 monthly UK searches for alcohol-free club nights, 36,000 US stores stocking overnight oats, and a 300% spike in sherbet-toned product searches every March. Discourse captures what people think, say and feel, organised around positions, tensions and narratives, which lets a team see not just that a topic is popular but where opinion is splitting. Digital Segmentation builds psychographic segmentation based on online behaviours, grouping audiences by what they actually do online rather than by demographic boxes alone. The Foresight Simulator uncovers probable future scenarios reshaping a category, giving teams a structured way to think about what comes next. Anthropologic also provides evaluation and simulation workflows. Creative Evaluation scores a video ad for cultural strength, grounded in signals, endorser and pillars — a way to test creative before it goes live. Synthetic Survey simulates consumer responses at scale using cultural ontologies, which points to quantitative-feeling answers without fielding a traditional questionnaire. Ask an Anthropologist interprets an insight using cultural codes, effectively putting an interpretive layer on top of a finding. Brand Performance shows how a brand performs across Social, Search and LLM, extending brand tracking into the places where consumers now encounter and describe brands, including AI-generated answers. Cultural Semiotics reads a space in a market — the codes that govern it, the tensions between those codes, and where a brand can stand. This is the most interpretive of the available workflows and speaks directly to the platform's claim of cultural, rather than merely behavioural, understanding. Innovation, listed on the site as coming soon, is described as identifying opportunity spaces through convergence modelling and developing novel concepts. Alongside the workflows, the site publishes Research Thinking — foresight pieces such as Death of the Sugar High, Future of Fashion is Value, Medicalized Mouth, Rolling Forward: Future of Film, Beyond Classrooms' Four Walls, Redesigned: Future of Aging, The End of Quiet, Future of Sportswear, Beauty after GLP-1, Fitness: Algorithmically mediated and Future of Wearables. The unifying mechanism is the Human Context Protocol, which Anthropologic describes as the way it reads the whole internet. Rather than sampling a narrow panel or scraping a single platform, the platform is presented as reading internet-scale data and interpreting it through cultural context. That combination is what allows it to operate across 239 markets and more than 100 languages without treating every market as an English-language default. The workflow structure — nine launchable tools on the Quickstart screen — means a user starts from a question type (what is moving, what people think, how a category might evolve, how a brand performs) and the platform returns an answer in minutes. Cultural ontologies underpin the synthetic survey capability and cultural codes underpin the Ask an Anthropologist capability, so interpretation is built into the product rather than left entirely to the user. For users, the stated benefit is speed and depth at the same time. Research that would traditionally take a long cycle is framed as an answer in minutes, while retaining the cultural grounding that distinguishes it from raw social listening or uncontextualised LLM output. Because the workflows cover discovery, segmentation, creative testing, brand tracking and foresight, a team can move from spotting a shift to interpreting it, testing creative against it and modelling what comes next without switching tools. The trend material shown on the site illustrates the granularity involved: 64% of Gen Z drinking mainly at home, up from 42%; 80%+ of UK Gen Z luxury buyers choosing pre-owned over new; 62% of Gen Z shopping secondhand in 2025; and 55% of UK Gen Z streetwear leaning toward visible status signalling. Concrete scenarios follow directly from the workflow list. A brand team wanting to know whether a behaviour is genuinely accelerating can run Trends and check the social proof and search patterns behind it. A strategist trying to understand a polarised conversation can run Discourse to see the positions, tensions and narratives at play. A team entering a new market can use Cultural Semiotics to read the codes governing that space and find where a brand can credibly stand. A creative team can score a video ad for cultural strength before launch. An insights team can simulate consumer responses at scale with Synthetic Survey, then use Ask an Anthropologist to interpret a specific finding through cultural codes. A brand tracking a launch can monitor performance across Social, Search and LLM in one view, and a foresight function can examine probable future scenarios with the Foresight Simulator. Anthropologic's framing points to research, innovation and foresight teams as its primary audience — the people who need consumer, category and cultural truth, and who currently choose between depth and speed. The breadth of 239 markets and 100+ languages also speaks to global brand, marketing and insights functions working across many markets at once. On the technical side, the site's cookie consent notice lists Stripe (fraud prevention, session and device identification) and Google Analytics (visitor, session and campaign measurement), indicating that the platform uses Stripe and Google Analytics on its own web property. No pricing or plan details appear in the provided content, and no integration partners are named. Anthropologic's core proposition is zero distance: closing the gap between the consumer and the decision by reading the whole internet through a Human Context Protocol and returning consumer, category and cultural truths in minutes rather than weeks. Nine workflows, 239 markets and 100+ languages are the mechanics; cultural context at internet scale is the value.
Sierra's multimodal agents are AI agents built for customer conversations that bring voice, text, and visuals into the same interaction. Instead of forcing a customer to choose a single medium, the agent automatically shifts between modes as the conversation requires. Voice is used when a customer wants to explain what they need, a visual when it helps to compare options side by side, and text when someone wants to reference something later. Sierra frames the result as an interface that morphs with the conversation, so customers get the best of each medium without having to pick just one. The agents are intended for companies that handle customer interactions and want those interactions to feel continuous rather than fragmented. The problem these agents address is familiar to anyone who has tried to complete a purchase or a change over the phone. Sierra uses the example of upgrading a mobile plan: a representative talks through models, colors, storage sizes, and monthly rates, and the customer is left comparing all of it in their head and picking a phone they cannot picture. The call is genuinely good for parts of the task, because it is easier to say what you actually need and to ask questions than it is over text. But the customer cannot see the thing they are about to buy, and that gap makes the decision harder and slower than it needs to be. Sierra's multimodal agents are described as closing that gap by bringing voice, text, and visuals into the same conversation. Connecting multiple channels is not, in Sierra's framing, the difficult part. The real trick is knowing which modality to use when: voice to explain what you need, a visual to compare options side by side, or text when you want to reference something later. Agents built on Sierra anticipate what is needed for each conversation and automatically shift between modes. Crucially, that switching happens without making the customer start over or repeat themselves, which is what usually happens when an interaction moves between a phone call, a chat window, and a self-service screen. The interface is meant to follow the conversation rather than the other way around, so the customer never has to re-explain context that the agent already has. Concrete examples show how that plays out in practice. If a flight is disrupted and a customer calls the airline to get a new flight, instead of a representative reading alternate options off one by one, the options appear laid out with departure times, layovers, and pricing right in the conversation. The customer picks one, and the agent keeps going from there. Choosing a seat works the same way: the customer sees the seat map and taps the seat they want. And for times when it is easier to talk than to type, the customer can switch to voice and explain exactly what they need, with the agent capturing those details instead of asking the person to type a paragraph into a text box. Multimodal agents also follow Sierra's approach of one agent for every surface. You can build your agent once and deploy it across all channels, and the same is true of multimodal components: once you build a visual component, your agent can use it everywhere it lives. That approach extends to Sierra's MCP UI integration, which lets you bring interactive components such as product cards, comparison tables, calendars, and forms directly into the conversation. Your team designs and hosts those components, so you decide how they look, what they show, and when they change. When you make an update, it is automatically reflected everywhere without needing to redeploy or maintain different versions for each platform. When something needs more room, a component can expand to full screen to show calendars, long comparison tables, multi-step forms, and more. This matters because the interface can scale with the complexity of a task without the customer ever leaving the conversation. The underlying idea is that the conversation is the interface: the customer says what they need and the agent figures out the rest, using whichever mode of communication fits the moment. Multimodality is the mechanism that lets that principle hold true across tasks that involve talking, reading, comparing, and tapping to confirm. For customers, the outcome is that they do not have to choose. On a single call, a customer can talk through what they need, glance at a screen to compare their options, and tap to confirm, without ever pausing the conversation to switch tools. That continuity removes the repetition and dead ends that usually come with moving between a phone call and a screen. For the businesses deploying these agents, the stated benefit is that multimodal experiences are as easy to build and deploy as they are for customers to use, thanks to the build-once, deploy-everywhere model and components that are owned and updated centrally. Use cases described in the content include telecommunications journeys such as upgrading a mobile plan, where the customer talks through models, colors, storage sizes, and monthly rates while seeing the options rather than holding them in their head. Travel is another: rebooking a disrupted flight while alternate options with departure times, layovers, and pricing appear in the conversation, and selecting a seat by tapping a seat map. Forms, calendars, product cards, and comparison tables can all be embedded where a conversation needs them, including multi-step forms that can expand to full screen. The agents are aimed at organizations that run customer interactions and want to design the experience themselves. Sierra emphasizes that your team designs and hosts the components used in the conversation, which gives you control over how they look, what they show, and when they change. Deployment is described as building the agent once and running it across all channels, with updates flowing everywhere without redeployment or platform-specific versions. The MCP UI integration is the specific integration named in the content for bringing interactive components such as product cards, comparison tables, calendars, and forms directly into the conversation. The takeaway is that Sierra's multimodal agents treat the conversation itself as the interface and let the medium change as the moment demands. Voice handles explanation, visuals handle comparison, and text handles referencing, all within one continuous interaction that customers never have to restart. Built once and deployable everywhere, with components your team owns and updates centrally, the agents aim to make multimodal customer experiences as straightforward to build as they are to use.
The archive
Quốc Đăng (quangcaoktd.com) is a professional signage company based in Hanoi, Vietnam, specializing in the design, manufacturing, and installation of storefront and commercial advertising signs (biển quảng cáo). Founded to serve the growing needs of small businesses, retail shops, and enterprises across Hanoi and the surrounding provinces, the company has built a reputation for combining durable materials, modern printing technology, and skilled craftsmanship to produce signs that stand out and last.The company offers a full range of signage solutions including aluminum composite signs (biển alu, biển quảng cáo alumi), 3D raised letter signs and LED channel letters (chữ nổi, chữ nổi đèn LED, bảng hiệu chữ nổi), illuminated acrylic light box signs (hộp đèn quảng cáo, hộp đèn mica), large-format vinyl banner and decal printing (in bạt, in decal, băng rôn quảng cáo), and mica awning or hood signs (biển vẫy mica hút nổi, biển hiệu vẫy). Each product line is designed to fit different budgets, storefront sizes, and branding goals, from compact shopfront nameplates to large illuminated signage for restaurants, showrooms, and office buildings.With an in-house production workshop located in Hoàng Mai, Hanoi, Quốc Đăng manages the entire signage process internally, from initial concept design and material consultation to CNC cutting, printing, LED assembly, painting, and final on-site installation. This end-to-end approach helps keep production times short, pricing transparent, and quality consistent across every project. The team has completed signage projects for a wide variety of industries, including retail stores, restaurants and cafes, car repair garages, gyms and fitness centers, clinics, schools, and corporate offices, giving them practical experience in matching sign type and materials to different business environments and local regulations.The website itself serves as both a company showcase and a practical resource hub. Visitors can browse a portfolio of completed sign installations, read detailed guides comparing different sign types and materials (such as when to choose LED raised letters over a standard light box, or how to select the right size and material for an aluminum storefront sign), and check general pricing references before requesting a custom quote. A dedicated contact page and hotline make it easy for business owners to reach the team directly for consultation, site measurement, and design proposals.Whether a business needs a durable outdoor aluminum storefront sign, an eye-catching illuminated light box, elegant 3D raised letters with LED backlighting, large-format banner printing for a promotional campaign, or a mica awning sign for a shopfront entrance, Quốc Đăng combines local industry experience with modern signage technology and design know-how to deliver advertising signs that are visible day and night, weather-resistant, and built to represent a brand professionally in a competitive Hanoi market.
OzBrain is a hosted knowledge base that acts as a shared brain every AI agent you use can read and write. Rather than letting each platform build its own separate, partial memory, OzBrain gives Claude, ChatGPT, Claude Code, Cursor, Gemini Spark and other connected clients one structured source of truth that agents and teammates both read from and write to. It is a place to hold your projects, decisions, research and the thinking you have already done, so a new chat can begin with what the task actually needs. It is aimed at founders, small teams and individuals whose work increasingly happens inside AI agents, and who want one brain instead of a scattered pile of chats, documents and stale file copies. The problem OzBrain addresses is fragmentation. Today the context of your work lives in your chats, your teammate's context lives in theirs, and the two never meet, so you share a doc, drop a message, and paste the same things over and over again. Meanwhile copies of the same plan sit in Drive, on laptops, in Downloads and in email, and no one is sure which one is current. Platform memory does not solve this: it keeps scraps and summaries, a few preferences and a thin summary of past chats, not the work itself. OzBrain is positioned as the layer underneath the tools you already use, holding the projects, decisions, research and prior thinking that platform memory cannot hold. The first core capability is structure. OzBrain breaks your knowledge into nested pieces, so an agent pulls the exact slice it needs rather than loading everything. The site illustrates this with a launch plan that nests into launch campaigns, which in turn nests into a single launch email: the agent can retrieve the 218-token, 0.87 KB email instead of the 11,842-token, 47.3 KB plan. Because the agent has less to load, it answers faster and more cheaply, and it is less likely to invent an answer out of context it never needed. In practice this means an agent can go straight to the email body it has to write without dragging the whole launch plan, the campaigns and the surrounding research into the conversation. The second capability is freshness. When newer thinking lands, OzBrain goes back through your knowledge on its own, marks the old material as replaced, and points to the latest version. You never have to hunt down every place an old decision lived, and no agent answers from a version you have already moved past. The site shows a company-details article being updated with a new domain, and the website-launch-plan article being updated to record that a new website URL was set and that the old domain is forwarded. Alongside this, OzBrain keeps every change on the record: which agent made it, what changed, and the reasoning behind it. Changes are proposed before they land, so several agents can work at once without writing over each other, and you can always see how the brain got to where it is. A recent-changes table on the site lists the time, the agent, the article and the reason for each edit. The third capability area is privacy and portability. Your brain is encrypted at rest and sealed to your account, so nothing leaks between tenants. OzBrain states that it never trains on your data and never sells it, describing the brain as a sovereign place for your data. On top of that, you can export everything as markdown whenever you want, including after you cancel, and deleting your account removes your content. The company frames this as a deliberate position: your knowledge is yours, you should be free to use the best tools for it, and OzBrain would rather earn your stay than lock you in. OzBrain works as a brain you connect rather than a service you code against. It is explicitly not another memory API: memory APIs sell add and search endpoints to developers building apps, while OzBrain is a hosted brain behind the connector menu that Claude and ChatGPT already show you. There is nothing to install and no coding required: you add OzBrain from the connector menu in Claude or ChatGPT, sign in, and approve it. The knowledge itself is stored as structured articles with links, provenance and freshness. Every write is staged, routed and checked against what the brain already holds, which is what separates it from a notes app: notes are written by you for you, while a brain is written by your agents for your agents. The site also describes it as one URL, so anything that speaks the protocol can hold the same brain. The benefits described follow from that approach. Agents pull only what they need, so they make fewer mistakes and answer faster and more cheaply. Your new and better ideas replace old notes automatically, so you stop chasing outdated versions scattered across drives, downloads, chats and email. Because every change is recorded with its reasoning and proposed before it lands, multiple agents can work simultaneously without overwriting each other, and you can audit how the brain arrived at its current state. Your data stays encrypted and private, and you retain the ability to take it with you as plain markdown at any time. Concrete scenarios in the content include teams where every member's agents work on the same knowledge: point everyone at one OzBrain, and what one person works out is already available to everyone's agents. A launch workflow shows an agent retrieving just the launch email slice instead of the full plan. A domain migration shows an update to company details propagating so agents no longer answer from an outdated domain. A solo founder's export shows seven brains and 503 articles being exported as markdown, and an enterprise scenario shows org-owned shared brains that every seat's agents share. OzBrain connects to Claude and ChatGPT through their native connector flows, plus Claude Code, Cursor, OpenClaw, Hermes Agent and Gemini Spark where Google makes it available (US, Spark eligibility), and any client that supports connectors. Pricing starts free: the Free plan is $0 forever with up to 50 articles, sharing on brains you own, unlimited brains, reads, writes and connections, write-time size discipline, and markdown export anytime. Pro is $20 per month with up to 500 articles for one venture plus personal knowledge, and Max is $99 per month with up to 5,000 articles for when agents run the operation from one brain. Both paid tiers include unlimited brains, reads, writes and connections plus markdown export anytime. Enterprise adds org-owned shared brains above the Max ceiling with per-seat pricing designed with you. The site also publishes comparisons against Mem0 and Supermemory, ChatGPT Memory, Claude Projects, ChatGPT Projects, Notion and Obsidian. The takeaway is straightforward: OzBrain is the shared, structured, portable knowledge layer beneath every AI agent you use, so your agents and your teammates stop working from separate partial memories and start working from one current, auditable source of truth that you can export and leave with whenever you choose.

Web Search Agents by Nimble are self-learning agents that become experts at your specific research task. They are described as expert web crawling and research agents built for a specific domain — company enrichment, regulations research, and similar areas — and they self-learn your use case in order to go deeper into the sources that matter most to you. The stated goal is to give your AI deeper and more relevant web context, and to automate web research with higher accuracy and less tokens. The product is aimed at agent builders and teams that need reliable web search and retrieval as part of an AI workflow; Nimble says you can get started by giving your AI an agent onboarding document, and the page offers both a free start-building path and a demo booking. The background problem is that ordinary web search and generic benchmarks do not reflect the queries agent builders actually run. Nimble explains that it evaluates web search by domain because that lets agent builders judge solutions against queries that resemble their own, not generic benchmarks. It also points to inefficiencies in common retrieval approaches: redundant searches and the need to parse raw pages with an LLM inflate token costs, and many tools cannot reach the subpages that hold the most useful detail. Nimble positions auditable search methodology and tight control as the answer, alongside accuracy that compounds over time instead of resetting with every query. Web Search Agents adapt to your use case and self-improve. Their first stated capability is compounding domain knowledge: the agent accumulates web context over time to master your domain. Because that context builds up rather than being discarded between runs, accuracy compounds over time through a Proprietary Index and Memory that gets smarter with every query. For teams running the same class of research repeatedly — company enrichment, regulatory lookups, market analysis, or product intelligence — this means the agent is not starting from zero each time, and the sources it favors reflect what has already proven relevant to the specific task. Because the memory gets smarter with every query, the value of the agent grows with usage rather than staying static, which is what Nimble means by compounding accuracy over time. Full governance and control is another core capability. Nimble provides auditable Search Plans that show exactly what was searched, where, and why, which gives teams a record of the retrieval methodology rather than an opaque answer. Users also get full control over search methodology, with data retrieved within the scope and guardrails defined for the search plan. On cost, Nimble says the agents cut token costs by retrieving exactly what is needed — no redundant searches and no parsing raw pages with an LLM. Combined with the Proprietary Index and Memory, the stated result is higher accuracy at a fraction of the token cost, which matters both for teams paying per-token and for teams that need repeatable, defensible research output. Web Search Agents also combine web search with domain crawling to provide deep web access for your sources, reaching subpages that other tools can't. Three workflow-level capabilities are highlighted on the site: executing hyper-specific research workflows, where the agents crawl the web with surgical accuracy; building and enriching datasets, where you define your schema to get consistent results every run; and monitoring for changes on the web in beta, which continuously tracks any data point on any webpage in real time. Domain-specific benchmark pages cover Market Analysis, Real Estate, Social Media Monitoring, Travel & Hospitality, Company Research, Finance, Product Intelligence, and GTM, and Nimble invites teams whose domain is not listed to contact the company to see how the agents adapt to their use case. How the product works is described as a self-learning loop. The agents adapt to your use case and self-improve, accumulating domain knowledge, applying a search plan with defined scope and guardrails, and returning results shaped to the schema you define. Nimble states that Web Search Agents can master any domain. The published benchmarks note that independent evaluations completed tasks such as reports, enrichment, and discovery, each graded fact-by-fact by an independent AI judge against a gold standard built without any contestant's input, with Web Search Agents, exa, parallel, and in several cases OpenAI and GPT-5.6 involved in the evaluation process. The stated benefits center on accuracy, cost, and control. Nimble says it delivers higher accuracy at a fraction of the token cost, and that accuracy compounds over time rather than staying flat. Teams gain full governance and control through auditable Search Plans that show what was searched, where, and why, plus the ability to keep retrieval inside the scope and guardrails of a defined plan. Retrieving exactly what is needed — instead of running redundant searches or sending raw pages through an LLM — reduces token spend. Deep access to subpages means the web context returned is deeper and more relevant to the specific research task, and dataset building with a defined schema means results stay consistent from run to run. Nimble lists concrete things you can build with Web Search Agents. Company research and due diligence, with a cookbook for audit-grade company diligence from one prompt. Researching case laws and regulations. Enriching your dependencies with health indicators. Finding assortment gaps on the digital shelf. Finding where products are sold in order to enforce MAP compliance, through monitoring MAP violations across sellers. Discovering businesses that match an ideal customer profile by mapping any market from an ICP prompt. Tracking analyst earnings predictions against actuals, including earnings guidance. And building a dataset of job candidates, described as building a targeted influencer list. The product targets agent builders and teams doing domain-specific web research and retrieval. Native integrations shown on the page include Anthropic, GPT, LangChain, and Vercel, and Nimble names Databricks, Qudo, Uber, LG, TripAdvisor, Semrush, Coca-Cola, L'Oréal, Microsoft, Rox, and Browserbase among the organizations displayed as trusted by the product. Security and compliance measures stated on the page include zero data retention, flexible PII masking, audit logs, data encryption in transit, and no training, with CCPA, GDPR, and AICPA SOC 2 badges displayed. On pricing, the page offers an option to start building for free alongside sign-up and demo booking, and describes talking through use cases to see how Nimble delivers higher accuracy at a fraction of the token cost. Overall, Web Search Agents by Nimble is positioned as a specialized web search layer for AI agents: self-learning, auditable, and cost-aware. It adapts to a specific domain, compounds knowledge over time, reaches the subpages other tools miss, and returns results that fit a schema you define. For teams whose AI depends on accurate, relevant web context, the primary value proposition is expert-level web search at lower token cost, with full visibility into how each search was run.
Naoma AI Demo Agent V2 is an AI video sales agent that gives every prospect a live, personalized product demo the moment they want one. Instead of asking visitors to fill in a book-a-demo form and wait for a rep, Naoma starts the demo instantly, walks the prospect through the live product, answers their questions, qualifies them and books the meeting. It is built for B2B SaaS teams that want to run more demos without hiring more reps, and it works on a website, inside an app, or in outbound emails. Naoma speaks 33 languages, runs 24/7, and writes every session back into the CRM so no conversation is lost. The problem Naoma targets is the gap between buyer interest and buyer access. A typical book-a-demo button converts only 1-2% of website visitors; everyone else leaves without ever seeing the product. Demos also tend to be constrained by business hours, time zones and the languages a sales team can realistically staff, which means a prospect researching at 11:42 PM, 3:15 AM or 5:07 AM may simply never get a demo at all. Long enterprise buying cycles make the gap worse, because a single opportunity often involves multiple decision-makers across marketing, operations, IT, procurement and management, each with different priorities, KPIs and questions. Naoma's premise is that a demo should be available immediately, in the buyer's language, whenever the buyer is ready - not whenever a rep happens to be free. Naoma's core capability is the automated demo itself. When a visitor requests a demonstration, there is no scheduling and no waiting: the demo starts immediately, and Naoma states that demos can start in 10 seconds. The AI agent handles discovery, tailors the session to the prospect's needs, industry and role, shows the features that matter to that person, and answers questions as they come up. After the session it qualifies the prospect and routes them onward: qualified leads go straight to the CRM, high-intent buyers can be sent to checkout, and Naoma can book a meeting with the sales team, all without a manual handoff. In practice each demo ends in one of three outcomes - meeting booked, qualified, or disqualified - so the sales team receives a pre-qualified list rather than raw traffic. Hyper-personalization is what makes each demo feel relevant rather than generic. Naoma learns the product from the material the company already has: sales scripts, demo recordings, the knowledge base, sales presentations and the demo environment itself. Because it is trained on those sources, it can handle complex technical questions and adapt the conversation to the context of the specific visitor. This is what allows the same agent to demo a deep, feature-rich platform credibly without a human rep driving the screen, and it is why teams describe the experience as doing discovery for them. Language coverage is a headline feature. Naoma speaks 33 languages, on the principle that buyers prefer to explore a product in their native language, which removes friction and helps every prospect understand the product and its value in the language they think in. The website illustrates this with named agent personas such as Alexandra Chen (VP of Sales) in English, Carlos Rodriguez (Head of Customer Success) in Spanish and Sophie Martin (Product Marketing Director) in French. Teams can also choose the face of their demos: the signature Naoma agent, a branded mascot, an animated avatar, or a static realistic avatar generated from a real photo, so the demo experience fits the brand and stays memorable. Beyond revenue, Naoma captures intelligence that buyers do not usually volunteer to a rep: competitors, objections, questions and feature requests. The company frames this as intel for sales, marketing and product teams, not just a source of pipeline. Because every session runs through the agent, the objections and questions raised during demos are recorded systematically, which gives marketing and product a view of what buyers actually ask and resist. Naoma also remembers returning visitors and picks up where they left off, so a prospect who starts exploring and comes back later continues the same thread instead of starting over. Naoma describes its workflow in four automated steps. First, a prospect on the website or in the app requests a demo - no scheduling and no waiting, the demo starts immediately. Second, the AI sales agent runs a live, personalized demo tailored to the prospect's needs, industry and role, handling discovery, showing relevant features and answering questions. Third, qualified leads are routed straight to the CRM, with the option to book a meeting with the sales team or send high-intent buyers to checkout, with no manual handoff. Fourth, the agent surfaces buyer insights, including competitors, objections, questions and feature requests, for sales, marketing and product. End-user feedback from live demos is used to benchmark quality: 89% of end users mention how human the experience feels, 77% praise how it handles interruptions, and fewer than 2% of sessions hit any technical issue. The stated outcome for customers is more demos from the same traffic and the same budget. Naoma reports that typical visitor-to-demo conversion is 1-2%, while visitor-to-AI-demo conversion with Naoma reaches 6-20%. The company also positions the product around running 5x more demos without hiring more reps. Because the agent operates 24/7 and in 33 languages, prospects get demos at peak buying moments across every time zone rather than waiting for a reply. Reviewers on G2 describe the practical effect: prospects learn about the platform whenever it is convenient for them, discovery is effectively done for the sales team, and reps can focus on higher-value conversations. Naoma holds a 4.9 rating on G2 and states that 50,000+ demos have been run for B2B SaaS teams. Concrete use cases come from published case studies. Hoteza, a web-based guest engagement platform for hotels, placed Naoma behind a "Get AI demo now" button so leads arriving across every time zone and language get an interactive demo immediately; the company reports that since April, 57 hotels explored the product this way and one regional partner signed after going through the AI demo. AiSDR uses Naoma to run personalized demos of its AI sales development platform for website visitors. UXPressia uses it to demo journey maps, personas and an AI persona builder for visitors who might not discover the platform's depth in a self-serve trial. App Radar uses it to qualify visitors and surface larger accounts worth routing into a sales-assisted funnel. Mellow uses it to reduce demos run with prospects who are not the right fit, and Hoteza and Mellow both cite that same qualification goal. Naoma is aimed at B2B SaaS teams - its customer logos include Yesim, Mellow, Runwayer, MarketOwl, Magify, UXPRESSIA, AiSDR, Hoteza and App Radar - and G2 reviewers span small businesses, mid-market companies and enterprise buyers. The product routes into a CRM, a calendar or checkout, and the site points to a knowledge base covering pricing, setup, security, CRM integrations and multilingual demos. On the security side, Naoma states that it is GDPR compliant and protects both customer data and their customers' information with enterprise-grade security. Naoma has also been recognized publicly, including Product Hunt daily and monthly top-post badges, Tekpon's Top Demo Automation Software Q1 2026 and a Global Startup Award from The Ventures, alongside press coverage of a $440k pre-seed round. Prospects can start a demo directly from the website, teams can build an agent in Naoma's app, and the company offers an ROI calculator. Naoma AI Demo Agent V2 is a purpose-built AI video sales agent for instant, personalized product demos. By replacing the book-a-demo form with an agent that demos, qualifies and routes in real time across 33 languages, it turns existing website traffic into booked, qualified meetings without adding sales headcount - and it feeds the objections, questions and competitor mentions back to the teams that need them.
OVO: Play Music Anywhere is the official OVO Music Player for iPhone, iPad and Apple Watch, built by Sharply Labs. It is a local-first music player: the files you already own stay at the center of the experience, while connected sources such as Apple Music, SoundCloud, synced folders and direct stream URLs sit alongside them in one library. Rather than asking listeners to choose between ownership and streaming, OVO places local files, cloud folders and live sources in a single place to browse, play and keep moving. The app is aimed at people who have collected music over years and want that collection treated as a real library rather than an edge case, and it is shaped so listening continues across iPhone, iPad and Apple Watch while the library stays in step between them. The motivation behind OVO is described plainly by its makers: a carefully collected music library should not feel like a second-class citizen on a modern device. Music that people have bought, ripped or gathered over the years often ends up scattered across a phone's storage, a computer, an external drive, a cloud folder and several streaming apps, each with its own rules and its own way of browsing. OVO's answer is to treat ownership as the starting point instead of an afterthought. Sharply Labs says OVO began with that familiar frustration and is building the player the team wants to use every day, one that respects the collection, the device and the act of listening, as focused software for people who care about the details. OVO's central idea is that a collection should have more than one way in, and that different sources do not have to look or behave the same. The Sources screen gathers connected streams and synced folders together above the Add Source options, with each source showing its own status. Beyond local files, OVO can connect Apple Music so that a subscription library sits beside your own tracks instead of living in a separate app, and SoundCloud so that mixes, edits and demos that never reach the big catalogues remain part of the same listening session. You can paste a direct stream or station URL and play it with the same controls as everything else, connect Files and iCloud Drive folders so albums arrive without rebuilding a collection by hand, and connect a secure WebDAV folder you maintain to reach the tracks inside it from the player. Local files come first in OVO. The app supports MP3, AAC and M4A, plus the lossless and uncompressed formats ALAC, FLAC, WAV and AIFF, and imported music is browsable by album, artist, song and playlist, with albums, artists and artwork kept intact. Files can be imported from the Files app or an iCloud Drive folder, and songs can be sent from a Mac or PC with Wi-Fi Transfer. Wi-Fi Transfer starts from Sources: OVO shows a temporary local transfer page and a one-time code, you open that page on a computer connected to the same Wi-Fi network, enter the code and send supported audio, with no cable, no cloud upload and no companion app, and the songs you send are added durably to your library. OVO recommends using it on a network you trust. Music kept on the device plays offline with no connection, while connected services and live streams still depend on their source and network availability. Sound shaping is built into the player rather than pushed out to another app. OVO includes a 10-band equalizer with faders from 32 Hz to 16 kHz and a Reset control, so you can shape the range you care about band by band. Bass Boost adds weight to the low end for headphones that need it, and Volume Boost lifts quiet transfers and old rips to a usable level. Together these controls let listeners start with the recording and then make the listening experience their own for headphones, speakers and the particular recordings in their library, without leaving the playback screen to do it. Party Mode is a visual layer in OVO, not an audio effect. Turn it on and supported local tracks come to life in Now Playing with colors drawn from the artwork, fluid motion and beat-reactive pulses that follow the beat, plus optional rhythm haptics that add a physical sense of the rhythm on supported iPhones. It is off by default, so you decide when a session should look like this, and visuals and haptics are controlled separately, so you can use each one independently or only one of them. Party Mode applies to supported tracks in your local library rather than to Apple Music, SoundCloud, direct streams or other provider content. OVO also includes music recognition: recognize a song around you, see what is playing, and bring that discovery back into your listening flow. OVO is shaped for the screen in front of you. On iPad it offers a spacious library designed for browsing, multitasking and touch, with Now Playing showing large artwork and transport controls alongside the Playing Next queue in landscape. On iPhone it is the complete everyday library and player. On Apple Watch, synced local files can play directly on the Watch, while Apple Music and stream sources play through the paired iPhone and remain controllable from the Watch. iCloud keeps your OVO library in sync between your Apple devices, so the library you build on one device is there on the next and what matters stays in step wherever you pick up listening. There is no native macOS app: OVO runs on iPhone, iPad and Apple Watch, and it does not present Apple Music tracks as downloads. The benefits follow from that structure. You keep one library instead of juggling separate apps for owned files and for subscriptions, and you can move between sources without changing apps. Your own music stays browsable by album, artist, song and playlist rather than being reduced to a file list, and it remains playable offline because files kept on the device need no connection. Sound controls let you tailor playback to the headphones or speakers you actually use, and Party Mode gives supported local tracks a visual, beat-aware presentation without touching the audio. For people with libraries accumulated over many years, the outcome is that ownership stops being an edge case and starts being the center of the listening experience. Concrete workflows follow from these pieces. A listener with a folder of ripped FLAC and ALAC albums can import them from Files or an iCloud Drive folder, browse them by album and artist, and play them on a plane with no connection. Someone with music on a Mac or PC can start Wi-Fi Transfer in Sources, open the temporary transfer page on the computer, enter the one-time code and send supported tracks over trusted Wi-Fi without a cable or cloud upload. A user who follows artists on SoundCloud can keep mixes and edits in the same session as their owned files. Anyone with a stream or station link can paste it and play it with the standard controls, as long as the network allows. And a listener who wants hands-free playback can play synced local files directly on Apple Watch while controlling Apple Music or stream sources through the paired iPhone. OVO is for iPhone, iPad and Apple Watch users who keep a personal music collection and want it alongside the sources they already stream from, including Apple Music and SoundCloud. It suits listeners who care about formats, since it plays MP3, AAC, M4A, ALAC, FLAC, WAV and AIFF, and who want to bring music in from the Files app, iCloud Drive folders, WebDAV folders or Wi-Fi Transfer from a Mac or PC. It also suits people who want sound controls in the player itself and privacy-minded listeners who value library sync between their own Apple devices through iCloud. It is not a macOS app, and connected sources still depend on their own availability and network. Put simply, OVO is a player that puts your music back at the center. It gathers the files and sources you care about into one library made for listening, keeps your own collection first with offline playback and full album, artist, song and playlist browsing, and carries that library across iPhone, iPad and Apple Watch with iCloud sync, all while giving you a 10-band equalizer, Bass Boost and Volume Boost to shape the sound.

LLMagnet is a WordPress plugin that makes a website visible and understandable to AI assistants such as ChatGPT, Claude, Perplexity, and Gemini. Its website describes the product simply as a way to track how AI models see your website. The plugin combines real-time analytics of AI bot activity with automatic generation of the llms.txt files that large language models read, and it also manages schema.org structured data on your pages. According to the site, it is the official WordPress plugin that tracks visits from AI bots and gives you real insights into how language models interpret your content. LLMagnet is positioned for web creators, agents and marketers who want their brand to have a measurable presence in the AI ecosystem, and it also offers a Shopify app alongside the WordPress plugin. The problem LLMagnet addresses is that AI assistants have become a real discovery channel, yet site owners have had almost no visibility into whether these models can actually read, rank and connect with their content. The website frames llms.txt as an emerging standard, comparable to robots.txt for search engines, that helps AI models understand a site's structure and content focus. Without such guidance, AI crawlers may struggle to read pages accurately or cite them at all. LLMagnet takes the position that businesses should prepare for AI-driven discovery rather than react to it later. The company also publishes content on related shifts, such as articles about content having a short half-life in AI search, about Shopify making millions of stores agent-ready, and about Google rankings no longer predicting AI citations, which reinforces its focus on measuring and improving AI visibility rather than traditional ranking alone. The first group of capabilities is AI visibility measurement and analytics. LLM Analytics tracks real AI bot traffic and provides detailed insights into visits, impressions, and clicks from major models including ChatGPT, Gemini, Claude, Perplexity, Grok, Bing AI, Mistral, DeepSeek, and Llama. The AI Visibility Score condenses this into a single metric that reflects how well large language models can access and understand your content across the web. Trends and Insights then track that visibility over time so you can spot rising opportunities and content drops instantly. Because these numbers come from the actual bots crawling your site, they show which pages are being read and engaged with rather than relying on estimates. The second group covers the files and markup that make a site readable to machines. The LLMs.txt Generator automatically builds and maintains your llms.txt file so AI crawlers can better understand your site structure and content focus, and higher plans also generate a full-llms.txt and .md files. LLMagnet manages your schema.org structured data and, on WordPress 6.9 and later, connects to the WordPress Abilities API so assistants such as Claude, ChatGPT, and Cursor can query your site's data natively. The product is described as agent ready, and an MCP Connector is included in plans. Together these pieces move a site from simply existing on the web to being structured in a way that language models and AI agents can parse and act on. The third group is reporting, prompt tracking, and store-focused features. Automated Reports and Insights deliver weekly and monthly reports that summarize your visibility and growth, backed by visual traffic breakdowns and actionable visibility tips. Prompt Tracking and Optimization shows where your brand appears in AI answers, tracking the prompts that mention your site and how your ranking evolves over time, including which prompts include your brand, how visibility shifts by LLM, and what to improve next. For stores, LLMagnet connects to your product data so AI can display accurate information in generative search, with auto product and price sync, AI-search visibility boost, and product mention tracking. On WooCommerce specifically, the Plus and Enterprise plans add product visibility scores and AI revenue funnel tracking. In terms of how it works overall, LLMagnet installs directly into WordPress and is described as lightweight and privacy-safe, with no setup or code required. You enter your WordPress site address and are redirected to the plugin installer to add it in one click, or you install it from the WordPress plugin directory. Compatibility is broad: the site lists Elementor, Gutenberg, Divi, WooCommerce and more, and states that LLMagnet runs alongside RankMath and Yoast SEO without conflicts while integrating into the Elementor editor with per-page AI visibility scores and schema management. Importantly for performance, file generation and analytics run in the background so there is no impact on your site's front-end performance or page load speed. Bot visit analytics are stored locally in your WordPress database and never sent externally, optional integrations are off by default, and the plugin is fully GDPR-compliant with built-in data export and erasure tools. The stated benefits center on understand, control, and automate. Under Key Benefits the site lists AI Visibility Control, so you know exactly how large models see your content; Smart Automation, which keeps llms.txt and data always updated automatically; and Deep Insights, which analyzes which pages drive the most AI engagement. It also lists Enhanced Collaboration for streamlining workflows with team-friendly features, Data Security to safeguard data with top-tier encryption, and Continuous Improvement so AI adapts and improves with evolving data. The overall promise is to turn AI data into clear, growth-driven actions rather than leaving site owners guessing about a channel they cannot see. Customer reviews on the page echo practical outcomes: seeing AI-related traffic, saving time with the llms.txt generator, and gaining visibility into AI crawlers, product exposure, and content gaps without added complexity. Concrete use cases emerge from the content itself. A WooCommerce store owner can use LLMagnet to prepare for AI-driven discovery ahead of time instead of reacting later, watching AI crawlers, product exposure, and content gaps. A merchant can rely on auto product and price sync plus product mention tracking so generative search surfaces accurate product information. A publisher or content site can track AI bot visits and impressions page by page and monitor how visibility trends change week to week through automated reports. A marketer can use prompt tracking to see which prompts mention the brand and how that position shifts across different LLMs. A solopreneur store owner, as one reviewer describes themselves, can follow incoming traffic from LLM agents without technical effort. Teams and agencies working across sites can rely on agent-ready output, llms.txt generation, and the MCP Connector to keep client sites consistent, while developers on WordPress 6.9+ can let AI assistants query site data natively through the Abilities API. LLMagnet targets WordPress site owners, web creators, marketers, and store operators, including WooCommerce merchants and solopreneur store owners, as well as teams that need collaborative visibility workflows. It is also designed for AI agents themselves: the product is described as built for agents and marketers, and it is agent ready. Integrations and compatibility explicitly named in the content include WordPress, WooCommerce, Elementor, Gutenberg, Divi, RankMath, Yoast SEO, the WordPress Abilities API, and an MCP Connector, with a companion Shopify app. Pricing is tiered with a free plan available and no credit card required. The Free plan offers analytics from ChatGPT, tracking visits and clicks, LLMs.txt generation, .md files, an MCP connector, page tracking, agent readiness, and support. Pro adds analytics from ChatGPT, Claude, and Perplexity plus full-llms.txt. Plus adds analytics from all bots, WooCommerce integration, product tracking, and support, and Ultra adds ten prompts tracking and chat support, with monthly and yearly options and different prices per site or per user. Taken together, LLMagnet is best understood as an AI visibility layer for WordPress. It answers a question that traditional analytics cannot: are AI models reading my site, what are they reading, and how do I improve my position in AI answers? By combining bot traffic analytics, an AI Visibility Score, llms.txt and .md generation, schema management, prompt tracking, and automated reporting in a single lightweight plugin, it gives site owners a measurable, continuously updated view of their presence in the AI ecosystem and the practical steps to improve it.
AppZapper 3000 is the most fun uninstaller for macOS, rebuilt for the 31st century. It exists to do one job completely: drag in any app and instantly find all of its extra files, then delete them with a real 3D zapper. The product is aimed at Mac users who want to remove applications thoroughly rather than leaving pieces behind, and who would rather enjoy the process than dig through folders by hand. Its entire pitch is captured in three words the website puts at the very top of the page: drag, drop, zap. The problem AppZapper 3000 solves is the gap that macOS leaves open. Deleting an application the usual way does not remove the rest of what that application installed, and the website positions AppZapper 3000 as "the uninstaller Apple forgot." That framing matters because the missing pieces — the caches, preferences, and support files that the product is built to locate — are exactly the items that accumulate quietly over time as software comes and goes on a Mac. The testimonials on the site repeat the same observation from twenty years of users: deleting an app without deleting all the extra files along with it is described by one long-time user as a "no-brainer." Others describe AppZapper as one of the first applications they install on a new machine, and as software they have kept in the dock for over fifteen years. One user states the app has never failed them, and another, a forty-year mainframe professional, appreciates the simplicity of the product and its accuracy. The message across those quotes is consistent: the value is in removing the entire footprint, not just the icon in the Applications folder. The core workflow is deliberately short. Step one is an empty AppZapper 3000 window, ready for an app to be dragged in. Step two is the search: the product instantly finds every extra file associated with that application. Step three is the zap, where the app and its leftovers are destroyed together. The site presents this as a numbered sequence of screens, with the first frame being simply an empty window waiting for a drop. The screenshots are labelled Step 1, Step 2, and Step 3, and the first one is described as AppZapper 3000's empty window, ready for an app to be dragged in — an explicit signal that the starting point is a drop target rather than a settings screen. This is the whole interaction model: no menus to hunt through, no manual scanning of library folders, and no leaving part of an app behind because you did not know where to look. The zapper itself is the centrepiece. AppZapper 3000 describes its "business end" as real laser bolts that blast away unwanted apps and the junk they install. Aiming is instant with the mouse, and the recoil is described as manageable, so the shooting stays under control while still feeling physical. You can fire one click, one shot at a time, or use Zap All to blast them all away automatically. The visual effects — explosions and smoke — are part of the experience rather than a hidden progress bar, which is why the product calls itself the most fun uninstaller for macOS. The "Ring in" behaviour supports the shooting: it instantly finds all caches, preferences, and support files, and reports the target as locked. Underneath the spectacle, the app has been "built to fly." The site says AppZapper 3000 was rebuilt with the fluidity, agility, and smoothness the team always dreamed of, making the new version feel fast and responsive to operate. There is also a cosmetic layer for people who want it: you can use the classic livery or apply one of the new blaster themes to zap in style. Combined with the scanning that instantly finds caches, preferences, and support files, the result is a tool that pairs a targeted technical job with a look and feel that is clearly meant to be enjoyed. The interface is described as fitting your hand, with manageable recoil and instant mouse aiming, so the physical framing of the zapper runs through both the visuals and the controls. AppZapper 3000's approach is to combine accurate file targeting with a physical, playful interface. When you drop an app in, the product identifies everything that app has spread across your Mac — caches, preferences, and support files — so the target is locked before you fire. The deletion step is then given a form: a three-dimensional zapper with laser bolts, recoil, and aiming, rather than a confirmation dialog. The rebuild framing means the familiar behaviour — drop an app, find everything, destroy it — is preserved while the interface and performance are new. The other half of the identity is longevity. AppZapper was first released in 2006, and the site marks a twenty-year legacy, thanking everyone who has been zapping apps over the past two decades. AppZapper 3000 is the same idea rebuilt for the 31st century. The stated benefit is completeness plus enjoyment. By finding all of an app's extra files and removing them in the same action, AppZapper 3000 leaves you with fewer stray caches, preferences, and support files than a simple drag to the Trash. Long-term users describe keeping their Macs the way they want them, and one user notes the app "just works." Because there is a Zap All option, the benefit scales to sessions where several apps need to go at once, and because the interface is fast and aimable, the work does not feel like maintenance. Users also describe it as one of the first apps they install on every new Mac, which suggests the benefit compounds over the life of a machine. Concrete uses described on the site start with removing a single unwanted application and everything it installed, using drag, drop, and a single shot. A second is a multi-app cleanup, where Zap All blasts them all away automatically instead of one at a time. A third is the ongoing habit long-time users describe: installing AppZapper early on a new Mac so that every future removal is complete, and keeping it in the dock so it is always at hand. Users also describe using it repeatedly over years on both desktops and laptops to keep machines configured the way they prefer, and one user notes it stays on the dock even when unused because of its icon. AppZapper 3000 is version 1.0 and requires macOS 15 or later. You can download it directly, try three free zaps, and then buy a licence from the site's buy page. The site links to a Try option, a Download for version 1.0, a Buy page, a Help page, a lost-licence resend tool, and an email support address, so the path from trial to purchase to support is laid out in one place. The product carries a twenty-year history behind it, with the new release presented as a rebuild rather than a brand-new idea. AppZapper 3000 takes a mundane Mac maintenance task and turns it into something people describe with affection. It finds all the files an app leaves behind, lets you target them precisely, and then removes them with a real 3D zapper — one shot at a time or all at once. For Mac users who want their machines kept clean and who would rather enjoy doing it, it is the uninstaller Apple forgot, back for another era.

Image to ASCII is a free browser-based converter that turns an image into a composition of characters. You can drop, paste or choose an image, adjust its width, character style, brightness, contrast and color, and then copy the result as plain text or Markdown, or export it as TXT, PNG, SVG, HTML or ANSI. The tool describes itself as an ASCII studio with three steps: upload, refine, export. It is built for people who want ASCII art they can actually use, such as a signature for a GitHub README, a mascot for a Discord server, a character-art cover for a blog post, or retro visuals for profiles, posters and landing accents. No signup is required, and images stay on your device. The underlying problem the product addresses is that ASCII art is easy to generate but surprisingly hard to place usefully. Spacing collapses in some destinations, fonts differ from the preview, and colored output does not survive as plain text. The converter handles this with a live preview, a before/after comparison, and explicit guidance that images may need a code block to preserve spaces or an image export when the destination changes the font. It also states clearly that GIF input produces a still result, not an animation, so output stays predictable. Detailed FAQ entries explain why ASCII art can look stretched, why colored ASCII does not work in TXT, and what width suits a GitHub README, giving users concrete ways to keep their text art readable after copying. Images can be uploaded by dropping, pasting or choosing a file, and the supported formats are JPG, PNG, WebP and GIF. Conversion happens locally in the browser using Canvas, so the source file never needs to leave the device. The site emphasizes this repeatedly: the image is read by your browser and converted locally with canvas, processed locally and never uploaded, and your file stays in this browser. GIF conversion uses the frame the browser provides. Alongside your own files, the tool ships with built-in sample images you can load to see real ASCII previews with their settings, including a prism portrait at 200 columns, silk in motion and a light portal at 220 columns, a glass bloom blog cover at 200 columns, an 80-column fox README mark, a 56-column Discord mascot, and a neon jellyfish demo. Output readability is controlled primarily by width and character style. The interface states that fewer columns give bolder characters while more columns give finer detail, and real examples run from 56 columns for chat code blocks to 80 columns for README marks and 200 to 220 columns for detailed editorial studies. Character styles include Detailed (a smooth photo ramp), Dense (@%#\*+=-:. ), Blocks (Unicode symbols), Simple (#*+=-. ) and Minimal (@. ), and an Invert option is available. Presets are split into two groups: visual styles such as Auto, Neon, Pixel, Gallery, Fine Art and Portrait, and presets for a destination such as Logo, README, Terminal, Social and Poster. Users can start from a preset and then fine-tune for the specific image in front of them. Under advanced tuning the tool groups light, texture and background controls. These include Tonal balance, described as recovering midtones without clipping the extremes, plus Brightness, Contrast, Sharpen, Saturation, Background Cleanup and Dither. The design intent is that the controls stay close to the preview, so you can see how every setting changes the final text art as you adjust it. A reset settings action returns you to a starting point, and the preview panel can be expanded while refining. Export options are separated into text formats and image formats. Text-side actions include Copy Plain, Copy Markdown, Copy README, Copy Comment and Copy ANSI, plus Download TXT and Download ANSI, along with a Copy Share Caption action. Image-side downloads include PNG, SVG and HTML. Color is preserved in PNG, SVG, HTML and ANSI export, while TXT, Markdown, README and comments stay plain for code blocks. The FAQ explains the distinction directly: TXT files store plain characters rather than per-character colors, so image exports should be used when the colored ASCII preview needs to travel with the artwork. Text exports keep editable characters; image exports preserve the look. Overall the product works by sampling your image in the browser, mapping brightness and detail to characters on a live canvas, and offering a comparison against the original. A compare slider lets you drag across artworks, Paper view and an expand preview option change how you inspect the result, and sample artworks can be reused with a "use this style" action. The converter compensates for tall text cells when sampling your image, which is why the documentation tells users to keep results in a monospace font and preserve line breaks, and notes that changing the column width changes detail rather than character proportions. A mobile-friendly workbench keeps upload, tuning, copy and export actions reachable on small screens. The practical benefit is ASCII art that survives its destination. For GitHub and code, the tool creates README banners, text signatures and code comment artwork. For terminals and forums it makes terminal welcome screens, Discord posts and forum text art. For retro visuals it turns a photo or picture to ASCII for profiles, posters and landing accents. Because conversion is local, users get this without uploading a personal photo or logo, and without creating an account. The site presents three purpose-built destinations with the settings and export choices that make them work. For a blog or editorial cover, a 200-column detailed color glass flower can be exported as PNG or SVG to preserve character texture and colors, while the headline stays in the blog editor so it remains readable and searchable. For a GitHub README, an 80-column simple monochrome geometric fox stays recognizable as a compact text mark, copied with Copy README for a fenced text block while project names and links stay outside the artwork. For Discord, a 56-column dense monochrome ghost mascot can be copied as Markdown and checked on a phone, or exported as PNG if the message wraps or clips. Dedicated guides cover the blog cover, GitHub README and Discord workflows. The tool also publishes preset recipes as starting points: Portrait uses a detailed ramp, dither on, mild sharpen and medium contrast; Logo uses Blocks style, a smaller width, high contrast and dither off; README uses a simple ramp around 80 columns and then Copy README or Copy Markdown; Terminal uses 80 columns with clean light backgrounds and exports ANSI or TXT; Social uses 56 columns for chat code blocks or PNG when spacing may collapse; and Poster uses a wider 200-column output exported as PNG, SVG or HTML. For GitHub READMEs the guidance is to start around 70 to 90 columns so the art fits code blocks on laptops and mobile screens, and for Discord or Slack it is to use Copy Markdown to wrap the output in triple backticks so spacing is preserved in a monospace code block. In short, Image to ASCII is a free, private, browser-based way to turn any picture into character art and then get it into the place it is meant to live. It keeps the source image on your device, gives you readable controls for width, character ramp, tone, color and dither, and offers both plain-text and color-preserving exports so the result works whether it lands in a README, a chat message, a terminal or a blog cover.

Juggler is a visual workbench for AI coding agents. It gives developers a desktop application, backed by a matching server, where conversations with a coding agent live as persistent trees rather than scrolling transcripts. Tool calls open into proper views, and every model transaction can be inspected to show exactly what the model received and returned. Juggler supports Claude Code, OpenAI Codex, GitHub Copilot, Gemini, Ollama and other providers through one interface. It is free to download, its core is open source, and it needs no account of its own. The product is aimed at developers who do hands-on work with coding agents and want to see and control what the model is doing to their codebase. Using a coding agent means reading and editing substantial amounts of text, and a conventional scrolling transcript is a poor interface for that work. Important detail — the arguments passed to a tool, the approval that was granted, the exact system prompt the model saw — tends to disappear into a log. Context behaves like a sealed container: once history has been assembled it is hard to see what is in it or to reshape it. At the same time, long-running agent sessions are fragile. A lost connection, a quit or a restart can end the work, and if the code lives on a dev box or a server, the session is stranded on that machine. Juggler exists to give that work a proper interface and to make the agent's behaviour inspectable rather than opaque. Conversations in Juggler are persistent trees rather than log files. You can branch at any point, recursively, and use a sub-thread for a tangent, a delegated task or a competing approach. When the sub-thread finishes, only its result returns to the parent instead of pouring its entire working history into the main context — delegated threads keep their intermediate work out of the parent context and return only the result requested. The Context Surgeon extends this idea: the agent's context is not treated as a sealed container. You can inspect the assembled system prompt and the available tools, fold selected history into a new thread, move or copy items between branches, expand a branch back into its parent, and undo structural changes. Everything important is inspectable. Tool calls open into proper views, and tool arguments, approvals and results can each be opened on their own. Any model transaction can be inspected to show its system prompt, messages, tool definitions, output, token use, timing and stop reason. Tool calls, item properties and nested sub-threads are laid out in a Finder-style Miller column view, with Miller-column navigation, focused views for tool calls and context, and controls designed for long sessions. Because the interface is built around inspection rather than a single stream of text, you can compare what is available now with what a past model turn actually received. Juggler can run where the code lives. For most work you launch the desktop app, which starts the local server itself and opens your project with no terminal required. When the project lives on a dev box or server, you run the headless juggler binary there instead and attach from a browser or the desktop app, locally or across the network. The server owns the session and does the work, and every connected client stays in sync, so you can keep a desktop view on your main screen, open another in a browser, or check the same session from your phone. Sessions also survive quits and reconnects because a session lives on disk, not just in memory: quit, relaunch or lose the connection and the conversation is still there, including an agent waiting for you to approve its next step. Juggler supports the usual LLM providers — Claude Code, Anthropic, OpenAI, Codex, GitHub Copilot, Gemini, Mistral, Z.AI, Ollama, OpenRouter, DeepSeek and other OpenAI-compatible providers — so you can bring a subscription you already pay for or your own API keys. Context limits are handled before they become your problem: Juggler sizes the complete request before each call, leaves room for the answer, and compacts older history when a conversation outgrows the model's window. MCP tools are fully inspectable as well: connect a local or remote MCP server and follow the whole handoff, including the schema offered to the model, generated arguments, approval, result and error. You can inspect server status and logs, filter individual tools, and compare what is available now with what a past model turn actually received. Under the hood, Juggler is Go, not Electron. It ships as a native desktop app and matching server; the backend is Go and the interface is type-checked JavaScript served directly, with no frontend compilation step. Conversations are Yjs documents synced live to every connected client. The application is built to be extended: context items, LLM loop strategies, slash commands, file viewers, info cards, Pinboard tabs and their UIs are JavaScript extensions you can inspect, fork or replace. Even tools such as read, write and bash use the public extension SDK, so the LLM-facing tools use the same SDK available to you. Writing an extension starts with a single scaffold command. The result is a workbench built for hands-on work that holds up over long sessions. Developers can see and control what their LLM is doing to the codebase, delegate work into sub-threads without flooding the main context, and inspect exactly what the model received and returned at any point. Sessions are durable and multi-client, so the work is not tied to one window or one machine. Because the main application is AGPLv3 and the extension SDK, bundled extensions and examples are Apache-2.0, extensions can remain closed source while the core stays open. Typical scenarios follow the product's design. A developer working through a large change opens a sub-thread for a tangent, delegated task or competing approach and returns only its result to the parent. Someone whose project lives on a dev box or server runs the terminal server there and attaches from a browser or the desktop app. Anyone connecting an MCP server can follow the schema, arguments, approval, result and error of each handoff. Long sessions benefit from tree navigation, focused tool-call views and context management, and an agent waiting for approval after a quit or reconnect can be picked up where it left off. Juggler is aimed at developers and other hands-on users who spend a substantial part of their working life inside a coding agent. It is free to download, its core is open source and it needs no Juggler account. It is available for macOS, Windows and Linux, either as the desktop app or as a headless terminal server, and it works with a wide range of LLM providers and OpenAI-compatible endpoints. The author behind it has spent more than 30 years building tools for developers and creators, including Tracktion, JUCE and Cmajor, and Juggler is in active development with frequent releases and a public changelog. Juggler's value proposition is control: a visual workbench that turns an AI coding agent's opaque transcript into inspectable trees, inspectable tool calls and editable context, running locally or on the machine where the code lives. It is free, open source and extensible — a foundation built to hold up for people who use coding agents every day.
Afterglow is a macOS application that runs classic After Dark screen saver modules — including Flying Toasters, Fish!, and Starry Skyline — natively on modern Macs, with no ROMs required. It is an emulator built specifically for After Dark modules, running the original 68k module code rather than offering a remake or a port. The project is created in the spirit of software preservation, with the stated goal of making After Dark easy to enjoy today and for years to come. Afterglow ships as version 1.0.1, a Universal binary that requires macOS 14 or later, and it includes a screen saver module for modern macOS so that the classic modules you import can run as your actual screen saver. In the 1990s, Berkeley Systems' After Dark screen savers brought Flying Toasters, Fish, and Starry Skylines to Macintosh screens everywhere. They served a practical purpose by preventing burn-in on CRT monitors, but they also entertained, with animations that could be funny, surreal, beautiful, and sometimes gross. Those modules are described on the Afterglow site as works of art worth preserving. Enjoying them in the present day has not been simple, however: running After Dark modules has involved fussy configuration of Mac OS emulators or vintage hardware. Even then, no single emulator or vintage computer can faithfully run every module — some animate too fast, and some animate too slowly. Afterglow exists to remove that friction and to run the modules faithfully on the Mac you already own. The core of Afterglow is its emulation approach. Afterglow is an emulator built specifically for running After Dark modules — the original 68k module code, not a remake or port — with no dependencies on ROMs or classic Mac OS. It is powered by the Musashi 68k CPU emulator, and Afterglow reimplements just enough of the Macintosh Toolbox and OS APIs to run After Dark modules. Because of that design, no Apple ROM or classic Mac OS installation is required. Every module runs inside the same purpose-built environment, which is why the project can aim to run modules faithfully rather than accepting the speed and compatibility problems that come with general-purpose Mac OS emulators or vintage machines. Modules are not included with Afterglow, but importing is designed to be easy. You drag and drop module files, disk images, or compressed archives into the app, and Afterglow extracts and imports them automatically. As the site puts it, whatever you have, if there are modules in there, you can probably drop it into Afterglow. That matters because After Dark material has survived in many different shapes over the decades — loose module files, disk images, and compressed archives. Rather than asking you to identify the correct format and extract it manually, Afterglow handles the extraction step for you so that getting a module running is a matter of dragging something in. Afterglow also lets you browse and install software releases directly from the Internet Archive without leaving the app. Inside the app there is an Internet Archive browser that displays cover art for releases spanning After Dark 1.0 through After Dark 4.5J. This gives you a way to find classic After Dark software from within Afterglow itself, instead of searching elsewhere and then working out how to bring the files into the application. The same preservation-minded browsing extends to packaging: Afterglow can display a rotatable 3D preview of retail boxes, and the site shows the More After Dark retail box as a 3D preview. Because Afterglow includes a screen saver module for modern macOS, you can run any of the classic modules you have imported as your Mac's screen saver. The site frames the appeal of screen savers as the surprise and delight of returning to your computer and seeing something unexpected: a psychedelic fractal, a procedurally generated mountain landscape, or a Bad Dog defiling your desktop. Afterglow's screen saver module ties the emulated classic modules back into the modern macOS experience, and the site notes that the Liquid Glass lock screen has never looked better with those modules running behind it. Beyond importing and the screen saver, Afterglow provides module controls and a full-screen mode. The module controls expose an individual module's settings; the site shows Starry Skyline's controls, which include Background, Buildings, Building Height, and a Flasher option, displayed alongside the module's original settings and notes. The app also lists a randomizer and a multimodule option among its capabilities. Together these options cover both deliberate use — dialing in a specific module and its settings — and looser, more casual use, where modules cycle or combine for variety. Afterglow rounds out its feature set with several extras aimed at presentation and preservation. It lists 3D box art, so original packaging can be viewed as a rotatable 3D object inside the app. It lists a CRT shader, which sits among the display options the app offers. It also lists a resource inspector, and a DrawMorph editor. These appear alongside the module controls, full-screen mode, randomizer, and multimodule in Afterglow's own summary of what the app can do, positioning it as more than a simple launcher: it is a viewing environment for classic After Dark modules and the material that surrounds them. The clearest benefit Afterglow claims is simplicity. Instead of fussy configuration of Mac OS emulators or vintage hardware, you get an emulator purpose-built for After Dark modules that runs the original 68k code with no ROMs and no classic Mac OS installation. Instead of hunting down software elsewhere, you can browse the Internet Archive inside the app. Instead of wrestling with archives, you can drag and drop module files, disk images, or compressed archives and let Afterglow extract and import them. And instead of the modules only living inside a separate emulator window, they can run as your actual macOS screen saver. Concrete ways Afterglow is used follow from those capabilities. You can bring an existing collection of After Dark material onto a modern Mac by dragging module files, disk images, or compressed archives into the app and letting it extract and import them automatically. You can set a classic module such as Flying Toasters, Fish!, Starry Skyline, Satori, or Bad Dog as your macOS screen saver and let it appear when your Mac is idle. You can browse the Internet Archive browser inside the app to find and install releases from After Dark 1.0 through After Dark 4.5J without leaving Afterglow. You can open a module's controls and adjust settings such as Starry Skyline's Background, Buildings, Building Height, and Flasher, with the module's original settings and notes visible beside them. You can view original packaging, such as a rotatable 3D preview of the More After Dark retail box. And you can run modules in full-screen mode, or use the randomizer and multimodule options the app lists. Afterglow is aimed at Mac users who want to run these classic modules natively on macOS 14 or later. It suits people with an interest in software preservation and retro Mac software, particularly those who remember Berkeley Systems' After Dark screen savers — Flying Toasters by J. Eastman & P. Beard, Starry Skyline by James J. Eastman (©1989, 90 Berkeley Systems Inc.) — and want to keep enjoying them without maintaining vintage hardware or a classic Mac OS installation. Distribution is a Universal binary macOS app, version 1.0.1, with a changelog and a help site available; the site provides an email contact and a Mastodon account for questions or feedback. Pricing is not stated on the page. The summary takeaway is straightforward: Afterglow turns a preservation problem into a download. It is an emulator built specifically for After Dark modules, running the original 68k module code on modern macOS with no ROMs or classic Mac OS required, and it wraps that emulation in practical conveniences — drag-and-drop importing, an in-app Internet Archive browser, module controls, full-screen mode, a randomizer, multimodule support, 3D box art, a CRT shader, a resource inspector, a DrawMorph editor, and a screen saver module for modern macOS. For anyone who loved Flying Toasters, Fish!, or Starry Skyline the first time around, Afterglow is a way to see them again on the Mac they use today.
Deplo is an open-source, self-hosted alternative to cloud deployment providers. It keeps the push-to-deploy workflow developers already know — connect a repository, push code, and the application goes live — but it runs on a machine you already pay for instead of on someone else's cloud infrastructure. Installation is a single command executed on your own server. The product's homepage states the value proposition plainly: same push-to-deploy you already know, running on a machine you already pay for, with no Docker, no SSH and no invoice. Deplo is built for developers, small teams and operators who want the convenience of a modern deployment platform without giving up control of their hardware, their network and their data. Its stated purpose is to be a ridiculously good alternative to the cloud, delivering the boring operational parts already handled so that you only have to pick what to deploy. The problem Deplo addresses is the cloud bill and everything attached to it. Cloud platforms bundle deployment, TLS, backups, logs and metrics into metered services, and teams end up paying per-seat, for bandwidth, and for every additional environment. The site is candid about the psychology involved: nobody moves off a cloud bill this happily without looking for one, and it lists the six questions such a move usually raises. Deplo's answer is that you get the same push-to-deploy experience on a machine that is yours. It argues the result is usually faster, because resources are dedicated instead of shared and metered; more flexible, because anything that runs in a container runs; and cheaper, because you pay the server and nobody in between. There is also nothing proprietary to unpick the day you move it somewhere else. Deplo says that what you get on day one is deploys, backups, logs, metrics and TLS, already switched on, with nothing to buy on top and nothing to hunt down. Those are the operational basics that normally require assembling a monitoring stack, a certificate renewal process and a backup routine by hand. Deplo puts them in place as part of the platform, so a freshly installed instance is immediately useful rather than a bare server waiting to be configured. The interface supports this approach: simple by design, with a clean, intuitive UI that helps you understand what is happening without wasting time. The company frames the question of whether Deplo is another tool you have to learn as exactly what it is trying to avoid, describing the product as built to be intuitive from the start so you can understand what is happening without spending hours on another complicated interface. Two of the core workflows are shipping on every push and hosting a web application. For shipping, you connect GitHub, GitLab, Bitbucket or Gitea once. Every push to your production branch goes live, every pull request gets its own preview URL that disappears when it closes, and a bad release rolls back to the exact image that worked. The claim is that there is no CI pipeline to own, which removes a whole category of configuration and maintenance work. For hosting, you connect the repository and get a live URL with HTTPS on it; Deplo works out the framework and builds it for you, so there is no Dockerfile to write, no SSH, and nothing to hand-edit. Postgres or Redis sits next to your application in two clicks. The site notes it is the same stack you ran on the cloud — only the bill changed. Deplo is AI ready in a specific, documented way: it ships a native MCP server. You point Claude, Cursor or any MCP client at your instance, and that agent can deploy, read logs and roll back in plain language, under a token you mint and revoke. Your coding agent gets the same access a teammate gets, and the same permission checks that apply in the dashboard apply to the agent, so an agent can never do what you cannot. The capability is off by default, so it is opt-in rather than something you have to switch off after the fact. Deplo is built for a team rather than for one operator with root. It defines 46 fine-grained Capabilities, which let you express rules such as can deploy, cannot delete, and per-folder grants let you hand a member exactly one corner of the fleet. The activity trail answers who did what and when, directly in the UI, so nobody has to look in a database to find out. The site's shorthand for this is the question who did that — Deplo knows. Every action carries a name and a time on it, and you decide who is allowed to do what in the first place. Underneath, Deplo runs Docker, and the platform handles the container part for you: you deploy from a repository or a template rather than writing container configuration. There is a terminal and a compose escape hatch if you want one, and it stays out of your way if you do not — so a user really can avoid touching Docker, as the FAQ confirms. Anything that ships as a Docker image runs on Deplo, and every one of the hundred-plus templates is deployed and checked first, on the principle that a hundred that work beat a thousand that might. Templates include WordPress, Supabase, OpenClaw, Home Assistant, GitLab, Gitea, Nextcloud, Forgejo and Grafana. Deplo is open source under AGPLv3 and brings your own server: your hardware, your network, your data, with no lock-in and no pricing page to keep an eye on. The outcomes Deplo claims are straightforward. Setup is fast — ten minutes from now it is deployed, since install takes one command on a server you already pay for. The bill collapses to a single line: you pay your server provider and that is the whole cost, with no per-seat pricing, no bandwidth surprises and no charge for the tenth environment. Performance is usually better because resources are dedicated rather than shared and metered. Flexibility comes from the fact that anything that runs in a container runs. And exits are clean: your apps are standard Docker containers on a server you own, so leaving means moving containers rather than rebuilding on someone else's proprietary primitives, and because Deplo is AGPLv3 nobody can take it away or reprice it. Deplo's own use-case pages demonstrate how it is used. One is letting AI interact with your infrastructure: pointing an MCP client at your instance so an agent can deploy, read logs and roll back under a revocable token with the same permission checks as the dashboard. Another is shipping on every push, where pushes to a production branch go live and pull requests get preview URLs that disappear when they close, without owning a CI pipeline. A third is controlling who can do what on a shared fleet, using capabilities, per-folder grants and the activity trail. A fourth is hosting a web application from a repo with a generated HTTPS URL and a Postgres or Redis instance alongside it. Deplo also documents taking over an existing VPS and migrating from Coolify or Dokploy, and its template library covers services such as WordPress, Supabase, Nextcloud or Grafana. The audience is developers, small teams and operators who run their own servers or want to, and who want team-grade deployment without cloud pricing: Deplo is built for a team, not for one operator with root. Integrations explicitly named include GitHub, GitLab, Bitbucket and Gitea for repository connections, Claude and Cursor as MCP clients, and Docker as the underlying container technology. Templates cover services such as WordPress, Supabase, GitLab, Gitea, Forgejo, Nextcloud, Grafana, Home Assistant and OpenClaw. Pricing is free and open source under AGPLv3, and the only bill is whatever you pay your server provider. The product is currently in beta, with a stable release targeted for Q4 2026, and people are already using it for real workloads today. Deplo's takeaway is a single trade: keep the push-to-deploy experience you already like, move it onto hardware you already own, and stop paying a metered bill in between. With deploys, backups, logs, metrics and TLS on from day one, an MCP server for agent-driven operations, per-push shipping with preview URLs, fine-grained team permissions and an AGPLv3 open-source core, it positions itself as a simple-to-use alternative to cloud deployment that leaves your apps as standard Docker containers on a server that stays yours.
Oats is a free, open-source meeting notetaker that records your meetings right on your Mac. Instead of sending a bot into the call, Oats listens to audio your Mac can already hear, and when the meeting ends it hands you a clean summary and a todo list you can actually work through. The product is designed to not get in the way of your meetings, and its stated premise is that notes are where a meeting's work starts, not where it ends. It is aimed at people who spend their days in calls and want those calls turned into structured, actionable notes without involving a third-party cloud. Most meeting note-takers follow the same model: a bot joins the call, or a browser extension captures the audio, and the recordings are stored in the vendor's cloud behind a subscription. Oats positions itself as the open alternative to that approach. The website states that most note-takers want your recordings in their cloud, while Oats records locally, runs AI locally, and never forces your audio off-device. It also removes the usual commercial friction — no seats, no trial timer, and no paywall waiting at meeting six — and it keeps bots out of the call entirely. That combination of privacy, price, and unobtrusiveness is the problem the product was built to solve, and it is what the tagline describes as an open, free, on-device meeting notetaker. The core capability is on-device recording. Oats records directly from your Mac's audio, which means there is no browser extension, no bot, and no third-party server touching the audio stream. Because it works with any audio the machine can hear, Oats is not limited to one conferencing platform: the site lists Zoom, Meet, Teams, a phone call, and even a hallway chat as situations where Oats can turn sound into notes. The workflow is deliberately simple — hit record when the meeting starts, let Oats listen, and get notes instantly when the meeting ends. This matters because it means the user does not have to change tools, invite a participant, or change how the meeting is run in order to capture it. After each meeting Oats writes the notes for you. It produces a quick digest, a full summary, action items per person, and a quality score derived from the conversation itself. The example shown on the site is a weekly sync where the quick digest reads that the roadmap is at risk of slipping and that the team aligned on a ship date and locked pricing, while the action items are listed per owner. The quality score, shown as a "Productive" rating alongside the meeting length, gives a signal about how the conversation went. Because the notes are generated from what was actually said, they reflect the conversation rather than someone's memory of it, and the per-person action items make ownership explicit instead of leaving follow-ups buried in a document. Oats does not stop at producing text. Action items from every meeting collect in a Todos tab, and ticking one off in the notes closes it, so follow-ups actually get followed up. On the local backend, notes are stored as plain Markdown and action items as Obsidian Tasks inside a vault you choose — you can open that vault in Obsidian, sync it, or move it anywhere. Recent releases added one-click download and export, so a meeting's recording and its notes can be saved wherever you want them. Version 0.23 also added sign in with Microsoft, so a work Microsoft account can be used alongside Google from onboarding, Settings, or the menu bar. The product ships every week, with the full changelog published on GitHub. Oats can run entirely on your machine or with extra cloud capability. With a local model, recording and AI notes run on-device and zero data leaves your Mac, which keeps audio fully private. Connecting an Ariso account unlocks richer AI features, including enhanced transcription, multi-language support, speaker recognition, assessment, and coaching, plus auto-tracking of follow-ups. Speaker tagging is one of those cloud-side features: it matches each voice in a recording to the person who said it, so notes attribute statements to a name rather than "Speaker 2." The distinction is presented as a choice — keep everything local and private, or opt into the cloud backend when you want more from the AI. Oats is truly open source. Every line is public on GitHub, and the project invites users to read it, fork it, self-host it, or ship their own features on top. The site frames this as "open by design" and "inspect every line," the point being that you can audit what the software does rather than trusting a marketing page. Combined with local Markdown notes, this also removes lock-in: export anything, owe nothing, and leave whenever you want. Free forever, with no seats, no trial timer, and no paywall, is the other half of the same promise, and it is reinforced by the fact that running locally requires no subscription at all. The outcomes Oats promises follow directly from those design choices. Because recording happens on the machine, users get privacy without extra work — no bot appears in the participant list and no audio goes to a third-party server. Because action items are extracted per person and collected in a Todos tab, what was agreed in a meeting is more likely to be done, and items can be closed from the notes or from Obsidian. Because notes are searchable, a user can ask questions across their whole history — the example given is asking what was decided about pricing. And because the app is free and open source, there is no cost barrier to trying it or to keeping it. Concrete scenarios appear throughout the site. A weekly sync is shown in detail, with a quick digest noting a slipping roadmap, a locked pricing decision, and action items owned by named teammates. Standups are represented by the #standup tag on that meeting. Beyond scheduled calls, Oats handles any audio the Mac can hear: Zoom, Meet and Teams meetings, a phone call, or a hallway chat. The searchable library turns past meetings into a knowledge base you can question, and the Obsidian integration fits meeting notes into an existing note-taking and task workflow rather than creating a separate silo. Oats ships as a desktop application: a download for macOS and a Windows beta, with the code available on GitHub. Pricing is free — the app is free forever, and the site notes that no subscription is needed when running locally with an on-device LLM. Accounts are optional and only relevant if you want the Ariso cloud backend; sign-in supports Google and Microsoft, the latter added in v0.23 for work accounts. The integration surface is deliberately flat: local Markdown files, Obsidian vaults and Obsidian Tasks, and one-click export and download. The product is published by Ariso and developed in public. Taken together, Oats is a meeting notetaker built around a simple reversal: instead of pulling your meetings into a vendor's cloud, it keeps the recording and, if you choose, the AI on your own machine. Free, open source, no bot in the call, notes in plain Markdown you own, and a todo list that closes when you tick it off. For Mac users who want their meetings summarized and their follow-ups tracked without a subscription or a third party listening in, that is the whole value proposition — and it is available today, recording on your Mac in a minute.
appdesigns is a free, browser-based editor for creating App Store and Google Play screenshots. As its homepage puts it, it makes 'Amazing app screenshots. Completely free.' You drop in your own app screens, frame them inside the latest iPhone, iPad, Mac or Watch devices, and add headlines, backgrounds and stickers before exporting at the exact sizes App Store Connect asks for. The tool is aimed at anyone who has to prepare a store listing - app developers, indie makers, designers and marketers - and its core purpose is to let them produce a polished, complete set of store screenshots directly in the browser, without an account and without installing design software. Store screenshots matter because they are the visuals shoppers see before they read a word of the description, and both the App Store and Google Play expect images at specific sizes and formats. Getting that right usually means either learning a full design tool, paying for a screenshot service, or settling for a free plan that caps how much you can export. appdesigns is positioned against exactly that friction: the site describes it as 'Truly free, not free to start', with unlimited exports, no watermark and no account required to start. In other words, the steps that normally sit between an idea for a screenshot and the finished file - sign-ups, paywalls, watermarks and manual resizing - are removed, and only the design work remains. The device framing system covers Mobile, iPad, Mac and Watch, so a single editor serves phone, tablet, desktop and watch listings. Within the mobile set you can pick from specific frames, including an iPhone Duo frame alongside iPhone 18 Pro, iPhone 18 Pro Max and iPhone 17 Pro Max models shown as the latest options, plus a further group of choices presented as '3 more'. Frame Type options such as Uniframe and iPhone appear next to the Device selector, there is an Orientation switch for Portrait and Landscape, and a Show Device toggle that lets you reveal or hide the frame itself. Framing screens in a recognisable device matters because store listings read more clearly when the mockup matches the hardware your app actually runs on, and the breadth of frames here means one workflow can cover a phone-only app or a product shipping on iPad, Mac and Watch at the same time. Once a screenshot is uploaded through the 'Upload a screenshot' control, the canvas becomes the working surface for the rest of the design. Backgrounds are handled with a Background Color picker that shows a hex value such as #FF512F, a Transparent option for screens that should sit on nothing at all, and an 'Apply to all' action that pushes the chosen background across the entire set rather than one image at a time. Text is added from an 'Add text' button, with the on-canvas hint telling you to 'Click or drag to the canvas. Press T to place.' - so a headline can be typed, positioned by dragging, or dropped in quickly with the T key. The editor also displays the working canvas dimensions, shown on the site as 1242 x 2688, which keeps the export size visible while you compose. Together these controls cover the three things most store screenshots need beyond the app screen itself: a background, a short headline, and the correct pixel dimensions. The editor goes beyond static framing with a Scale & Tilt panel, where values such as Scale 135% and Tilt 0 degrees can be dialled in to change how the device sits on the canvas - useful for angled, dynamic compositions rather than a straight-on shot. A Templates section presents a row of thumbnail previews to start from, matching the product description's note that you can 'start from a community template' instead of building every screen from scratch. And rather than treating each image as an isolated task, appdesigns is built for working across the whole set: the Product Hunt description states you can 'design the whole set side by side', which is how a coherent, consistent sequence of store screenshots gets produced. The homepage reduces the entire process to three steps: 'Upload your app screenshots', 'Choose a device frame', and 'Customise and export'. Everything runs in the browser, and the page is explicit that the editor needs a laptop-sized window, offering a 'Copy the link for your laptop' option - so the intended environment is a desktop or laptop browser rather than a phone. First-time visitors are given a choice of onboarding: 'Show me around' for a guided tour, or 'I'll explore on my own' for people who would rather go straight to the canvas. Because it is truly free rather than free to start, the practical benefits are straightforward: unlimited exports, no watermark on the finished images, and no account needed to begin. That means you can iterate on a headline, swap a device frame, or re-export a full set as many times as the listing needs, with nothing stamped across your artwork and no sign-up step in the way. Backgrounds can be standardised across every screen in one action, and community templates give a head start when you would rather not begin from an empty canvas. The site adds that 'Support is appreciated, never required', reinforcing that the core tool is not gated behind payment. The most concrete use case shown on the site is a reference set of three App Store screenshots for a health or habit app, laid out on the canvas with the headlines 'Plan your week', 'Never miss a habit', 'Share progress' and 'Widgets too'. That is the classic pattern: upload several screens from the app, give each one a short benefit-led headline, place them in a phone frame, and export them as an ordered set. The same flow applies when producing Google Play screenshots, when building iPad, Mac or Watch visuals using the matching frames, when assembling a full set side by side with a shared background applied to all, and when using Scale & Tilt to create angled device shots instead of flat, straight-on images. appdesigns runs on the web and is free to use. It is built for app developers, indie makers, designers and marketers who need store-ready screenshots, and it does not require an account to start. The device library covers Mobile, iPad, Mac and Watch frames, the canvas supports text, solid or transparent backgrounds and a working size displayed at dimensions such as 1242 x 2688, and exports are unlimited with no watermark. A guided tour is available for new users, and the editor is designed for a laptop-sized browser window. In short, appdesigns turns a job that normally involves paid tools, accounts and resizing work into a three-step browser workflow: upload your screens, choose a device frame, customise with backgrounds and headlines, and export at the sizes the stores expect. It is free rather than free to start, it leaves no watermark, and it lets you design the whole set side by side - which is why it is a practical choice for anyone preparing an App Store or Google Play listing.
Ghostwriter by MyHandler is an AI writing assistant for Windows 10 and 11 that drafts text directly at your cursor inside any application. Rather than asking you to describe what you want written, it reads the screen in front of you — the thread above your cursor, the question beside it, or the half-finished sentence inside it — works out what you would write next, and types that draft in your voice. The site describes the entire interaction as a double-tap: put your cursor in any text field, double-tap the hotkey, and the text appears. It is designed for people who write replies all day and want the first draft to arrive already written instead of having to prompt an AI for it. The problem Ghostwriter targets is stated plainly on its own site: every other AI writes what you tell it, while Ghostwriter writes what you already know. The friction it removes is not the writing itself but the prompting — describing what you want written was the work you were trying to avoid, and describing a reply in a live conversation is often more effort than typing it would have been. Ghostwriter replaces the prompt with the context already on your screen, so the screen content becomes the entire input. Because automatic writing carries the risk of sending something you did not intend, Ghostwriter also stops short of the final step: it types into the box and never sends anything itself. You edit it, you send it. The core feature is screen-context drafting. When you double-tap the hotkey, your Handler captures the screen around your cursor — the thread above it, the question beside it, the half-finished sentence in it, the form, or whatever is in front of you. That capture is the input. Before writing a single word, Ghostwriter works out what kind of writing this is: a reply owed in a thread, a sentence to continue from exactly where it stops, a blank box under a question that wants a real answer, or a message the context obviously calls for. The site states that getting this right is most of the job, so it decides on the kind of writing before it drafts anything. This matters because a continuation that restates your own sentence, or a reply that summarises the thread back at you, would be worse than useless. Ghostwriter also handles the social detail of a conversation. It maps each message to its sender, works out which handle is yours, and tracks who asked whom for what, so it answers the other party rather than replying to your own words. It matches how you write to that person, down to the sign-off. The result is a draft that reads like something you would have written to that specific person in that specific thread, not a generic assistant response that you then have to rewrite from scratch. Two further capabilities shape the draft. First, scheduling safety: if the reply proposes a time, it is checked against the next two weeks of your calendar first, and the product states that it will not double-book you. A connected calendar is required only for this scheduling cross-check — the site notes that everything else works without one. Second, rewriting: if you select text before double-tapping, Ghostwriter rewrites the selection instead of composing a new reply, so the same single gesture covers replying, continuing, filling in, and rewriting existing text. Ghostwriter is part of the MyHandler desktop app for Windows. The workflow the site describes has three steps. First, you put your cursor where the words go — no prompt, no dictation — and double-tap the hotkey so the Handler captures the screen around that cursor. Second, the Handler decides what kind of writing this is and, if the reply proposes a time, checks it against your calendar. Third, the text appears at your cursor exactly as written, with nothing sent. On privacy and data handling, the capture around your cursor happens on your machine, against the encrypted vault on your PC. The assembled context is then sent to the company's cloud model, which the site says operates with zero data retention, to write the draft. The stated benefits follow from that design. There is no prompt to write, because the whole interaction is a double-tap and you never have to describe what you want. It reads the situation, not just the words, identifying whether the moment calls for a reply, a continuation, a fill-in, or a composition from scratch before it writes. It gets who's who right, so it answers the other party rather than your own messages. And the last step stays with you: Ghostwriter types the draft and stops, so nothing leaves your machine without your decision. These benefits combine into a simple outcome — the first draft of a reply appears at your cursor in your voice, and you spend your time editing rather than composing. The use cases are anchored in the places people actually write. The site names a mail client, Slack, a browser form, and a comment box as examples of any app where a cursor in a text field is enough. In practice, that covers an email reply owed in a thread, a chat message that needs answering, a sentence you want continued from exactly where it stops, a blank box under a question that wants a real answer, a message the context obviously calls for, and a scheduling reply that has to respect your next two weeks of calendar. Because the input is whatever is on screen, the same double-tap works across all of them without switching tools or re-describing the task. Selecting text first turns the same gesture into a rewrite rather than a continuation. Ghostwriter runs on Windows 10 and 11 today and is free for those platforms. The site states that macOS and Linux are coming, and offers to email you the download link so it is waiting when you are at a Windows PC, with a direct download for Windows also provided. A connected calendar is optional and used only for the scheduling cross-check. MyHandler offers related capabilities built on the same local-vault foundation: Dictation, which lets you hold a key, talk, and release so your words appear at the cursor and which keeps working with Cloud AI switched off; AI Gatekeeper, which watches every channel you connect and screens the noise on your own PC; Contact Intelligence, which builds living contact profiles automatically on your machine from the messages, meetings, and activity already in your vault; and Daily Briefing, a morning briefing written from the data on your own PC. Ghostwriter's value proposition is that the draft is already there. You do not type a prompt, you do not dictate, and you do not describe the reply you want. You put your cursor in the text field, double-tap, and a reply written in your voice, grounded in the thread on your screen, appears where you were about to type — calendar-checked if it proposes a time, addressed to the right person, and never sent without you. Stop rewriting the same reply: it drafts, you decide.
Resurf is a personal context library for the things you like, care about, and work on. It is a fully local app for Mac, iPhone, and iPad where you save notes, links, images, PDFs, and documents into one place. Once your material is saved, Resurf lets you find what you need and hand off that context to AI through MCP or the CLI on Mac. The app is written entirely in native Swift, so it runs natively on every device it supports, and your library lives on your device. No Resurf account is required, the app works offline, and if you want your library on more than one device you can opt into private sync through your own iCloud. The core promise, in the words of the site, is a library that gets more useful every time you save — fully local, private by default, and designed to stay out of your way. Most people accumulate context constantly: articles worth reading, PDFs to revisit, images that inform design work, voice notes jotted down before an idea disappears, links saved for later. That material usually scatters across apps and rarely gets revisited. Resurf's answer is a save-first workflow. Its Inbox First model is built around saving now and organizing later, so capturing something never requires deciding where it belongs while you are in the middle of something else. Quick Capture is described as capturing without switching context, Voice Memos exist so you can record thoughts before they disappear, and AI Summaries are opt-in so you can revisit articles, links, and PDFs faster. The problem Resurf addresses is not a lack of tools for saving things, but the gap between saving and actually using what you saved. Capture is deliberately broad. Resurf accepts articles, PDFs, images, audio, video, code, tweets, GitHub links, YouTube links, and notes, and the product states that every format renders natively rather than landing in the library as an opaque attachment. Capture happens with the keyboard shortcut ⌘⇧C, so you can grab something without leaving what you are doing, and it works from Mac, Chrome, and iPhone into one library. A dedicated Chrome extension is available, and the site shows a Substack article being saved with a #reading tag. The result is a single destination for everything you collect, rather than separate bookmark lists, screenshot folders, and note files spread across services. Organization happens after capture, not during it. Inbox First means every new item lands in an inbox where you can sort it when convenient. Spaces and Tags organize around projects, research, and ideas — the site shows Research and Writing spaces alongside tags such as #ml, #philosophy, and #ideas — so related material can be grouped by project while lightweight tags cut across those groups. The Visual Library lets you browse what you saved the way you remember it, presenting captures in a browsable grid rather than a text list. Instant Search, triggered with ⌘K, finds notes, links, PDFs, images, and files fast; the site's example shows a search for typography notes returning 24 captures from the last six months. Reading and writing get their own surfaces. The View surface is an article reader with highlights and a properties panel, and Highlight & Annotate lets you keep your thoughts beside the source, so an article or PDF carries your own notes with it. The site's example shows a paper PDF marked as worth revisiting. The Notes surface is a rich-text editor with a formatting toolbar and highlights, so you can write alongside what you have collected. Voice Memos let you record thoughts before they disappear, and the recorded audio joins the same library as everything else, keeping spoken ideas inside the searchable collection instead of in a separate recording app. AI is opt-in throughout. AI Summaries help you revisit articles, links, and PDFs faster, with a TL;DR shown for a thirty-second read. Bring Your Own AI lets you use your own AI key — the site shows an OpenAI key field and a GPT-5 model reference — or hand off saved context to AI agents through MCP or the CLI on Mac. Ask Your Library lets you ask questions across the context you saved, with the example question of what was saved about typography. An Assistant pane can sit open beside a Space so you can work with the material you collected, and the site notes that Resurf connects to agents through MCP or the CLI. Overall, Resurf is organized around five surfaces that make up one library: capture, organize, view, write, and ask, exposed as Library, Inbox, View, Notes, and Assistant. These are described as the five places you will actually spend your time in Resurf. Architecturally, the library sits at ~/Library/Resurf, your data stays on your Mac, the app works offline, and no account is required. The app is 100% native Swift, built for Mac (Apple Silicon and Intel), iPhone, and iPad, and sync is optional and private through your own iCloud. The benefits follow directly from that design. Because everything lands in one searchable place, you spend less time hunting across apps. Because search is instant and the library is visual, you recognize saved items the way you remember them. Because everything is local and works offline, your library remains accessible and private by default. Because capture is a single shortcut and organization is deferred, saving something costs almost nothing in the moment — which is what allows the library to compound, getting more useful every time you save. Concrete workflows show how this plays out. A reader saves articles and Substack posts with a #reading tag as they browse, lets them pile up in the inbox, and later revisits them faster using opt-in AI Summaries or by asking their library what they previously saved about a topic. A researcher or writer opens a Space for a project, adds tags such as #ml or #philosophy, and keeps the Assistant pane open beside that Space while working. A designer captures typography references from Chrome, Mac, or iPhone into the same library and later searches for typography notes. Someone reading a PDF highlights passages and attaches notes so their thinking stays next to the source. A voice memo catches an idea mid-walk. And anyone using AI agents hands their saved context over through MCP or the CLI on Mac. Resurf is intended for people on Mac, iPhone, and iPad who collect context for their work and interests and want it to stay local. Downloading for Mac is free to try, and the app requires macOS 14.3 or later on Apple Silicon or Intel; it is free on iPhone and iPad, with a separate purchase license option. A Chrome extension is available for capture in the browser, and AI integrations include MCP and a CLI on Mac, plus support for your own AI key. Everything described here is opt-in or local by default, and no Resurf account is required to use the library. Taken together, Resurf's value proposition is a private, on-device library for everything you save, combined with instant search and an explicit path for handing that saved context to AI. It stays out of your way at capture time, organizes later, and gets more useful with every item you add.
Cue is an Awwwards-tier UI component library for anyone building to stand out. It collects best-in-class components from across the internet, curated by hand, so that designers, developers, agencies, solo makers, and product teams who refuse to ship generic-looking work can bring high-end web design closer to their next project. Every entry is a component reference sourced from an Awwwards Site of the Day, a Behance-featured interaction, or a production output the founder considered best-of-class. Cue does not host projects, deploy code, or run an AI model itself; it is the taste layer on top of the tools people already use. The problem Cue addresses is a familiar one for builders: a website can function perfectly and still look entirely forgettable. Bold hero sections, smooth interactions, unique layouts, and thoughtful micro-animations are the elements that make a site stand out, but finding genuinely best-in-class examples and then reproducing them takes time, taste, and a lot of searching. The strongest references are scattered across Awwwards, CollectUI, and X, presented as finished sites rather than as reusable, copyable pieces. Cue gathers those references in one place and pairs each one with the code and prompt needed to recreate it in your own project, shortening the distance between spotting a great interaction and shipping something that feels like it. The core of Cue is its growing collection of hand-picked components — 75+ and counting, with new drops arriving daily. Each entry is a component reference rather than a machine-generated filler item, sourced from an Awwwards-tier website or a best-in-class interaction. Cue explicitly states that nothing is machine-generated to fill the grid; every drop is hand-picked by the founder, and there is a dedicated editorial section highlighting the new drop of the day. The library covers bold hero sections, smooth interactions, unique layouts, and thoughtful micro-animations, organised so builders can browse sections and interactions separately and sort between new and old entries. Because the bar is taste rather than volume, if a user finds a better reference for the same component, the founder replaces it. Every Cue component ships with an AI prompt designed to be dropped directly into the AI builder or assistant you already use. The prompts are written for tools including Bolt, v0, Cursor, Framer AI, ChatGPT, and Claude, so a reference you like can be turned into working output inside your existing workflow rather than being rebuilt by hand. For builders working in AI-native environments, this reframes the component library as an input to their tools rather than a separate destination. Free members can copy two AI prompts per 24 hours, which allows anyone to test the format before committing to a paid plan. Alongside prompts, Cue is actively rolling out React source code and an MCP server for its components. The MCP server is described as native access from Cursor, Claude Desktop, and any MCP-aware AI tool, meaning components can be pulled into an AI-assisted development session without leaving the editor or assistant. React source code gives developers a concrete implementation to adapt rather than a description to interpret. Together these two channels cover builders who prefer to prompt, builders who prefer to code, and builders who work in a mix of both — while the website itself stays a reference layer rather than a hosting or deployment platform. Browsing is built for fast discovery. A ⌘K command search lets you jump straight to what you need, and the library can be filtered by tags covering sections and interactions, sorted between new and old entries, and filtered by price. A 'new drop today' area highlights what has just been added, and visitors can subscribe by email to be told when new components ship — described as no spam, unsubscribe anytime. There is also a Discord community where members help pick the next drop. The overall approach is deliberately lightweight: Cue is explicitly positioned as not a template pack, not a subscription, not a course, not an AI wrapper, and not a marketplace. For users, the outcome is a shorter path from inspiration to implementation. Instead of bookmarking a striking site and then reverse-engineering it, you get the reference, the prompt, and — as it rolls out — the React code and MCP access. The stated promise is simple: build less, create more. That means less time hunting for reference material, less time translating a visual idea into an implementation, and a result that does not look generic. For teams and freelancers whose work is judged on visual quality, Cue acts as an external taste layer that raises the baseline of what they ship. Typical scenarios revolve around building websites that stand out. A solo maker preparing a landing page can pull a hero section reference and drop its prompt into v0 or Bolt. A developer working in Cursor or Claude Desktop can reach the same components through the MCP server as it rolls out. A designer looking for a specific interaction can browse the interactions tag, find a reference sourced from an Awwwards Site of the Day, and use the attached prompt to recreate it. Agencies and product teams can use the curated set to raise the visual bar across client projects, and founders can subscribe to email drops to see each new component as it ships or join Discord to help choose the next one. Cue is explicitly not only for AI builders. It is aimed at designers, developers, agencies, solo makers, and product teams who refuse to ship generic-looking work, and the Product Hunt listing places it in Design Tools, Developer Tools, and Web Design. Pricing spans several options. A Free tier lets you browse the library with two AI-prompt copies per 24 hours. Cue+ Founding Lifetime is USD $99 one-time, capped at the first 50 members. Cue+ Lifetime standard is USD $249 one-time after the founding tier sells out. A time-limited offer shows $99 marked down to $79 lifetime with coupon code CUE49, and a custom pricing option lets builders pay only for the components they pick. The founder also offers a paid service to build a site that stands out. On the integration side, Cue names Cursor, v0, Bolt, Framer AI, ChatGPT, Claude, Claude Desktop, and any MCP-aware AI tool. In short, Cue is a hand-curated, Awwwards-tier component library paired with AI prompts, React source, and MCP access — a taste layer that helps builders move from a best-in-class reference to a shipped interface without settling for generic-looking work.
Kirokune is an iPhone app for logging work and personal incidents with notes, voice recordings and photos, and it is available on the App Store. It is built for people who have been told to document what happens to them and want a private place to do it, keeping every record on their own iPhone rather than behind an account somewhere online. You can write down what happened in your own words, save a voice note, or take a photo, and the app organizes what you save into a timeline. No account is required — you open the app and start. Kirokune requires an iPhone with iOS 17 or later, is free to download with in-app purchases, and is available in the United States and India. The premise behind the product is the phrase almost everyone has heard: everyone says document everything. Kirokune's own framing is that you do not have to let something go just to get through the day. The difficult part is rarely the intention to keep a record; it is finding a way to do it at the moment something happens, when you may be stressed, rushed, or simply unable to bring yourself to type out a long account. The details that matter later — the date, the time, where it happened, what was said and who was there — are easiest to capture while they are fresh, and much harder to rebuild from memory weeks afterwards. Kirokune gives that moment somewhere to land, so a record exists even before you have decided what, if anything, you want to do with it. The first capability in Kirokune is capturing a record quickly, in whatever form is easiest at the time. One tap starts a recording, which the app describes as useful even when you cannot bring yourself to type. A photo works too, and so does a quick note written in your own words — Kirokune notes that a short note is enough to begin. There is no setup first: you open the app and start a note, a recording, or a photo. Because an entry can take several different shapes, the tool does not force one particular workflow on you in the middle of a difficult moment. You can pick the format that fits the situation and sort out the rest afterwards. Once something has been saved, Kirokune puts it in order. Records appear in a timeline alongside your original notes, with dates, times and exact words, so you can see events in time order and review them against what you actually wrote. The app states that nothing you already wrote gets changed — the record stays exactly the way you wrote it, and the timeline supplies context rather than rewriting your account. Records are kept in a case, and the free plan allows unlimited records inside one case. The optional Kirokune Plus plan adds unlimited cases, so you can give separate situations their own collections instead of keeping everything in a single place. Kirokune can also import a chat export file as a record. You choose a supported export file from Apple Messages, Messenger or Instagram without connecting your chat accounts, and the app keeps the file's whole original text alongside the messages it can display; Kirokune advises choosing the conversation and date range before exporting where the service allows it. Recording incidents is only part of the point, because the app also helps you prepare for a conversation. When you are ready, you can look back at what you saved at your own pace and pull it into a summary you can walk someone through. Paid Kirokune Plus adds detailed reviews and PDF export for this stage. Kirokune describes its own approach in three steps. First, get it down: open the app and start a note, a recording, or a photo, with no setup first. Second, sort it later: when you have the energy, group what you saved into a private case. Third, look back: everything in order, exactly the way you wrote it. Separating capture from organization this way is what makes the app usable in the moment — you are not asked to decide on structure, titles or categories while something is happening, only to get the detail down. The structure comes later, when you have the time and the composure to put what you saved into a case and read it back in sequence. Privacy and honest limits are central to the product. Records stay on your iPhone, and nothing leaves the app unless you export it yourself; there is no account to create. The app currently provides no automatic sync or cloud backup, and Restore Purchases only checks access to your paid plan — it does not restore a backup of your records — so users are told to keep their own copies of needed records and original files before deleting the app. Kirokune also states plainly what it does not do: it does not diagnose, decide what happened, or give legal advice, and it keeps your own record organized and that is all. It cannot tell you whether a recording is lawful, noting that rules about recording and sharing a conversation vary by place and situation, and it suggests considering letting the other person know and checking the rules where you are. Naming the other person is not required either — initials or a nickname you would recognize later works fine. The outcome Kirokune aims for is that you will not have to go from memory. When you decide to talk it through — with someone you trust, HR, a lawyer or a support service — having it written down in your own words helps you explain what happened. Records you captured near the moment, kept in time order with the original wording intact, give a clearer account than a recollection assembled afterwards. Because multiple formats are accepted, a record can exist even when you could not type; because cases keep things together, related entries are not scattered; and because nothing you wrote is changed, the record you bring to a conversation is the record you made. Several concrete workflows follow from these features. In one, you document a workplace incident by noting the date, the time, where it happened, what was said and who was there as soon as you can, with Kirokune holding all of that together in one private place in time order. In another, you capture something in the moment when typing is not possible, starting a recording with one tap, or taking a photo, or writing a quick note, and group it into a case later when you have the energy. You might save a chat conversation with its context by exporting from Apple Messages, Messenger or Instagram and choosing the conversation and date range where the service allows it. Later, you prepare for a conversation: looking back at what you saved at your own pace and pulling it into a summary you can walk someone through, with detailed reviews and PDF export available in Plus. And if you are not ready for an app at all, the website offers a free workplace incident log template and example worksheet you can use in your own notes without installing anything or creating an account. Kirokune is intended for people who have been told to document what happens at work and want a private place to keep those records on their own iPhone, as well as for anyone recording personal incidents. It is available in the United States and India, with English, Japanese, Traditional Chinese, Korean and Spanish interfaces, and runs on an iPhone with iOS 17 or later. The free plan covers unlimited notes, recordings, photos and other records organized in one case, with no account or paid plan required. The optional Kirokune Plus plan adds unlimited cases, detailed reviews, PDF export and removal of ads, and is offered as a monthly, yearly or one-time lifetime purchase; the purchase screen shows your local price and renewal terms before you decide. There is no Android app, and the free worksheet on the website works without installing anything. Kirokune's value proposition is narrow and deliberate: a private, account-free place on your iPhone to write down, record or photograph what happened, to keep those records in time order without changing a word of them, and to read them back when you are ready to talk. It does not decide what happened, does not give legal advice, and does not move your records off your device on its own. What it provides is the thing everyone is told to do and few have a workable way to do: documenting the moment, in your own words, so that later you are not relying on memory.
Naverny Borshchu is a web application and interactive map devoted to Ukrainian borshch. It gathers bowls of borshch served in Ukraine into a single place so that anyone can find a spot, see how its borshch was rated, and contribute a discovery of their own. The project describes itself as 'the map of Ukraine's best borshch' and as 'a web app for borshch lovers', with the goal of helping people 'find your perfect Borshch'. According to its Product Hunt listing, the map holds 278 bowls across 31 cities, 103 of which are already rated by people who actually ate them, while the other 175 still carry no score. The website states that more than 100 bowls of borshch have been tasted and that over 800 borshch lovers are on board. Eating borshch is a deeply rooted Ukrainian tradition, and opinions about which bowl is best are as strong as they are personal. Traditionally, those opinions live in conversations, social posts and word of mouth, which makes them hard to compare or to use when choosing where to eat. Naverny Borshchu answers that by putting borshch on a shared map and giving every bowl the same set of criteria, so ratings from different people in different cities can sit side by side. The team states its mission as bringing people together around a love of borshch and keeping the culture of tasting it alive in places all over the world. It shares stories, flavors and discoveries - from well-known restaurants to hidden spots where great borshch turns up when you least expect it - and describes the project as building a place where borshch stirs a real feeling of being Ukrainian. The core of the product is an interactive map of borshch across Ukraine. From the 'Find borshch' button on the homepage, visitors open the map and look for bowls by location, including a 'Find borshch near me' call to action. Each entry is tied to a place where the borshch is served, so the map doubles as a discovery tool for a single city or for a trip across the country. Entries also carry a meat type: chicken, pork, veal, meat-free or other. That filter matters because borshch is cooked differently from kitchen to kitchen, and a guest who wants a meat-free bowl or a rich veal broth can narrow the map to the options that suit them. The interface shows a rating alongside each bowl, with scores such as 8.5 or 4.5 visible in the previews. Naverny Borshchu rates every bowl on seven criteria rather than a single vague star score. The first is meatiness - how much meat there is and how well it is cooked. The second is beetiness - how clearly the beet comes through in amount, color and aroma. The third is saltiness - how well the salt is balanced, neither bland nor oversalted. The fourth is thickness - how rich and hearty the borshch is, 'the spoon stands up', or thinner. The fifth is aftertaste - whether a pleasant and full-bodied taste lingers after the tasting. The sixth is presentation - whether it looks appetizing and neat, and what comes on the side. The seventh is overall - how much the taster liked the borshch as a whole. Because the same seven questions are asked about every bowl, the resulting ratings are comparable across cities and restaurants, and the overview shows values such as 7/10 for meatiness. Beyond finding and rating, Naverny Borshchu invites people to add borshch that is not on the map yet: 'Discover new borshch and put them on the map.' This is where the discoverer mechanic comes in. Of the 278 bowls listed, 103 already have a score and 175 still have no score, and the team explains that whoever tastes one of those unrated bowls first stays on it as its discoverer. That gives early tasters a visible role in building the map rather than only consuming it. A separate section, the Borshch Index, puts price into the picture. For Kyiv it shows 202 UAH per serving and 56.1 UAH per 100 g, expressed as x10.2 versus a homemade pot. The index gives a way to judge value alongside taste, comparing what a restaurant bowl costs with the cost of cooking borshch at home. The site sums the workflow up in three steps: Find, Add, Rate. Find means locating borshch across Ukraine on an interactive map. Add means discovering new borshch and putting those places on the map. Rate means scoring a bowl against the seven criteria and sharing what you found. Those three actions describe the whole loop the product is built around: a visitor opens the map, picks a spot, eats the borshch, and then returns a rating that helps the next person decide. Because unrated bowls outnumber rated ones, the loop is still open - every new tasting either adds a score to an existing place or introduces a place that was not on the map before. The practical benefit is a single, consistent source of answers to a common question: where should I eat borshch? Instead of collecting scattered opinions, a user sees scores built from the same seven criteria and can weigh meatiness, beetiness, saltiness, thickness, aftertaste, presentation and overall liking for themselves. Ratings come from people who actually ate the bowl, as the project states, which ties the score to first-hand experience. The map format makes the answer geographic as well as qualitative, so it works whether someone is choosing between two places in their own neighborhood or planning where to eat while traveling. Price information from the Borshch Index adds a second dimension, letting a diner balance taste against cost per serving or per 100 g. The discoverer mechanic gives contributors a reason to be early. Several concrete scenarios follow from how the product is described. A person in Kyiv can open the map, filter by meat type and pick a nearby place whose borshch scored well on the criteria they care about. A traveler moving between Ukrainian cities can use the map to see which of the 31 cities covered have bowls listed and what those bowls were rated. Someone who has just eaten a bowl can rate it on the seven criteria and share the result, adding a score where there was none. A taster who finds borshch in a place that is not yet listed can add it and become its discoverer. A cost-conscious diner can consult the Borshch Index for Kyiv, which shows 202 UAH per serving and 56.1 UAH per 100 g against the price of a homemade pot. Members of the community can also follow the project's Instagram account to see stories, flavors and discoveries from the team and other tasters. Naverny Borshchu is aimed at people who love borshch and at anyone looking for a good bowl in Ukraine, whether locals or visitors. It is free to use, and the team states plainly that it is open source, with no ads and no affiliate links, so listings are not paid placements. It runs as a web app reached through the website and its map subdomain, with a mobile-friendly interface. The project is run by a named team of stakeholders, project and compliance managers, backend and frontend developers, and designers, and it is reachable by email and through LinkedIn and Instagram. It launched on Product Hunt on 13 September, where it gathered 18 votes and 15 comments. Beyond the product itself, the site collects Instagram posts from the community, positioning the map as part of a wider conversation about borshch. In short, Naverny Borshchu turns a famously opinionated food into structured, comparable data on a map. It lets anyone find borshch across Ukraine, add places that were missing, and rate bowls on seven clearly defined criteria, while the Borshch Index adds price context and the discoverer rule rewards early tasters. Free, open source and free of ads or affiliate links, it is a community project with a cultural mission: to bring people together around a love of borshch and keep the culture of tasting it alive in places all over the world.
DemoTV is a 24/7, audience-ranked television channel for product demos, built for people who want to discover independent products by watching them in action. The station streams short demos continuously, and the audience decides which products occupy Channels 1, 2 and 3 by backing the demo they would actually try. Anyone with a product can submit a short demo for free, and founders can embed a demo on their own website, recruit testers and collect product feedback. As the site states, "Audience Elo decides the rank — airtime never buys rank," so the top of the board reflects viewer preference rather than advertising spend. Product discovery is crowded, and the usual signals — paid placements, sponsored slots and banner inventory — are hard for a viewer to separate from genuine popularity. DemoTV addresses that by splitting the two ideas apart completely. Ranking is produced only by viewers backing the demo they would try in head-to-head battles, while any commercial placement is clearly labelled and confined to exposure. In the site's own words, "money buys exposure, completed views and clicks, never the ranking." For viewers this means a leaderboard they can read at face value; for makers it means the path to Channels 1-3 runs through the quality of the demo itself rather than the size of a budget. Channel Battle is the central mechanic. Two products for the same job are shown side by side — for example an app builder versus another app builder — and viewers are asked simply to "Watch both. Back the one you'd try — no sign-up." The pick is cast without creating an account, and that pick feeds the audience rank. Because the battles are head to head and paired by category, the comparison is like for like. Wins and battles are counted per demo and shown alongside an audience score, so a listing might display an audience score with a running tally of wins and battles. The station explains that Channels 1-3 are the current top three, that Rank 1 is the demo viewers picked most, and that airtime never buys either. Filling the channel is deliberately simple for makers. Submitting a demo is free and needs no card: a YouTube link or an MP4 upload is enough, with an optional MP4 capped at 40MB, and every submission is reviewed before it goes live. The submission flow has four steps — website details, video, visitor action, then review — and after station approval the maker gets a private dashboard holding one embed code for their website. That widget is included with an approved listing and carries the video, an optional try link and a button the maker chooses, such as Visit website, Start free, Join waitlist, Book a demo or Claim offer. From the dashboard makers can also request testers, cap reveals and copy the embed, while details like video start automatically only when a viewer presses play. Discovery on the station runs through a demo directory that lists all broadcasts, paged ten at a time and sortable by audience rank or newest. Demos are filed under categories that also determine which battles they join, spanning groups such as AI agents, AI app builders, video generation, chat assistants, computer use, developer tools, design and no-code, data and analytics, marketing and sales, productivity, infra and APIs, games, crypto and web3, crypto wallets, crypto infra, robotics and hardware, fintech and payments, security and privacy, education, consumer and social, climate and energy, and other. Category leaderboards highlight positions such as first place in a given category, and the site displays aggregate station numbers — live demos, audience backings, views and visitors — only once live demos exist. Paid reach on DemoTV is explicitly separated from ranking. Makers who want more visibility can buy labelled airtime after claiming their listing; airtime units add promoted placements across the reel and the directory and never change a demo's audience score or channel. Advertisers can also become featured partners through labelled homepage cards, described as $39 for 30 days with labelled placement that never buys Channel rank, or take a Launch Week labelled 7-day sponsorship. There is also Demo Studio, priced at $79, where a maker pastes their site and receives automated production with station QA before air and maker approval, while rank stays audience-only. Optional viewer thank-yous let a maker offer a backer code, a time-boxed free week or a discount, shown with a one-line pitch; the site notes that this never moves Elo and that battle buttons will not show it. Makers are also told they pay only if they want extra reach, and that none of these options buy Channel rank. The wider methodology is consistent throughout: everything is audience-only until a maker chooses to pay, and payment is confined to exposure, completed views and clicks. Airtime is bought in units, with larger unit counts adding more promoted placements and the price shown at checkout. Advertising on the reel is clearly labelled, and the site repeats that paid airtime never touches the rank. Claiming a listing is free and does not by itself approve a claim, and signing in alone is not enough. Community safety is handled through a report flow listing reasons such as scam or misleading, spam, malware or unsafe link, adult or offensive content, impersonating another product, broken video or link, and something else, with reports going to the DemoTV team for review. Contact for takedowns and press is handled by email, and viewers are offered an optional first-party analytics choice that connects a visit with signup and purchase results, with no ad trackers or search terms and a statement that the choice does not affect the site. For viewers, the benefit is a ranked channel of product demos that can be watched and compared without signing up, where the ordering reflects what other people said they would try. For makers, the benefit is a free route to being seen, a free embeddable widget that puts the demo on their own site, and a dashboard for recruiting testers and collecting feedback. Because the ranking is audience-driven, smaller products can climb the board on the strength of the demo rather than the size of a media budget, and because paid placements are labelled, viewers can trust what the rank means. The station frames this as demo quality driving the possibility: what the board has counted grows only as live demos accumulate. Concrete workflows on DemoTV follow a few clear patterns. A viewer browses the directory or the TV view, presses play on a channel, then enters a Channel Battle, watches both demos and backs the one they would try, with no sign-up required. A founder pastes their project URL, submits a title and tagline, chooses the category whose battles the demo will join, adds a YouTube link or MP4, and waits for review. A maker without a video yet can commission one through Demo Studio. Once approved, the maker claims the company, takes the embed code and places the widget on their website with a chosen button and destination. From the dashboard the maker can request testers and cap reveals, and separately buy airtime units, a Featured partner card or a Launch Week sponsorship if they want extra reach. DemoTV runs on the web at demotv.lol and reaches makers and viewers through an embeddable widget, a submission form and a private dashboard. Its audience includes founders and small teams submitting demos, companies that already have a listing and want to claim it, advertisers buying labelled placements, and viewers looking for new products to try. Pricing is straightforward: submission and review are free with no card needed, claiming a listing is free, and paid options are optional — labelled airtime, Featured partners at $39 for 30 days, Demo Studio at $79, and Launch Week labelled seven-day sponsorship — none of which buy Channel rank. Maker contact, takedowns and press are handled through the station's contact address. The takeaway is that DemoTV turns product demos into a ranked channel where the audience, not the advertiser, decides what sits on Channels 1-3. Free submission, a free embeddable widget, tester recruitment and feedback tools give makers the means to be discovered, while clearly labelled airtime gives them a way to buy exposure without ever buying the rank.
Picreword helps you edit text in existing images with AI. Update a promotional headline, correct a typo on a poster, change an event date, or replace wording on a social media graphic without rebuilding the design from scratch.Upload your image, specify the text you want to change, and enter your replacement wording. Picreword generates an edited version while aiming to preserve the original font style, colors, layout, and background. Review the result, compare it with the original, and download your updated image.Built for content creators, marketers, small businesses, and everyday users, Picreword makes focused text changes possible even when you only have the exported image. No editable layers or original design files are required.
FrameSketch is a video annotation tool that lets animators sketch directly on top of their footage. You drop in a video, step through it frame by frame, and draw right on the canvas — arcs, breakdowns, poses, sticky notes — with every line fixed exactly where you left it. It is built for animators, VFX artists, and motion designers who need to mark up motion rather than describe it in words or rebuild stills in another application. FrameSketch runs in the browser and as a PWA, is free to use, and keeps your footage on your own device. Annotation is the whole point, and FrameSketch keeps that workflow short. Rather than opening a full animation suite, juggling plugins, or working through export settings, you open a file, draw, and get back to the shot. The site positions it as the opposite of animation-suite bloat: no plugins, no export roulette, and no timeline lag, and no project-browser rabbit holes when you want to get back into work in progress. Review is part of the problem it solves too — the tools you reach for mid-review are built in, so a shot review does not turn into a detour through several other applications. And because footage can be private or simply huge, FrameSketch never uploads it: local-first by default, with optional cloud sync that only ever carries annotations. The core of FrameSketch is frame-accurate annotation. You can walk footage frame by frame, scrub to a section, and see the frame number as you step through it. Lines land on the exact frame you drew them on, so the canvas never drifts away from the video beneath it, and stepping forward or back keeps each drawing locked to its frame. The frame-by-frame timeline lets you mark a stretch of footage and play just that range on a loop, which is useful for studying a cycle or a specific beat repeatedly. Onion skin completes the picture: you can peek at the frames before and after the current one and tune the ghosting until it feels right, which supports exactly the kind of spacing and breakdown judgement animators make when checking arcs. Drawing itself is designed to feel immediate. FrameSketch is pressure sensitive, so pen input translates into the stroke, and the editor offers four pens drawn from one palette. Strokes stay put: each line is fixed the moment you lift the pen, so your marks remain exactly as drawn, frame after frame, instead of shifting under the video. Annotations live on real layers — you can stack strokes, shapes, and notes, reorder them, hide them, and dial in each layer's opacity independently. That makes it possible to keep a rough pass separate from a corrected pass, or keep notes distinct from drawing, without flattening everything into a single image. FrameSketch also bundles the collaboration and alignment tools a shot review needs. Sticky notes and comment markers can be pinned right on the frame, then moved, resized, recolored, and edited at any time — so feedback sits on the exact moment it refers to instead of in a separate document. Grids, rulers, and guides help you line marks up by eye: grids can be rectangular or isometric and drawn as dots or lines, and you can drag guides out of the rulers to align your marks where you need them. Pan and zoom let you move into the detail of a shot and back out again while your annotations stay exactly where you left them. Scenes and backgrounds round this out: one project can hold many scenes, and every scene sits on a solid background layer, so you can hide or dim the video whenever you want to look at your lines on their own. FrameSketch works in three steps. First you drop in a video — any local file, read straight from your machine, with nothing leaving it and nothing re-encoded. The file picker lists what your platform can really play: MP4 with H.264, which is recommended and plays everywhere; MOV, a QuickTime container whose H.264 content plays everywhere; M4V, the same H.264 core as MP4; and WebM, the open VP8/VP9 codec that plays on Windows, Linux, and Chromium (on macOS, the site suggests using MP4 or MOV instead). Anything else can be converted once to H.264 MP4 and will then play anywhere. Second, you draw on the frames, with each line fixed the moment you lift the pen. Third, you share the project: a single small .fsk file holds every stroke, so you can email it, open it, and keep going. FrameSketch runs entirely on your machine, and cloud sync is optional — it only carries annotations, never footage. The result is a review loop that stays quick and private. Because each line is fixed to its frame and the canvas never drifts, you can trust what you see when you come back to a shot later. Because a whole project is only a few hundred kilobytes, projects are small enough to email, stash, or version rather than shipping heavy media around. Because your footage stays on your machine, you can annotate client material or unreleased shots without uploading them anywhere. And because cloud sync only carries annotations, you can let annotations follow you across devices — or turn the cloud off entirely and keep everything local. Concretely, animators use FrameSketch to mark up arcs and poses over reference footage: drawing the line of action, blocking breakdowns, and checking the spacing between keys with onion skin. VFX artists and motion designers can annotate a shot frame by frame, pinning notes and comment markers to the exact frames a review refers to, then loop a marked range to study the motion repeatedly. For shot review, sticky notes and comment markers on real layers keep feedback in the same place as the drawing, and the .fsk file makes it possible to hand the annotated project to someone else and let them continue from the same strokes. Alignment-heavy work benefits from the rectangular or isometric grids and guides dragged out of the rulers, and anyone working with confidential or unreleased footage can annotate locally without ever uploading the video. FrameSketch is aimed squarely at animators, and the site also names VFX artists and motion designers — the people who think frame by frame and reach for a pen mid-review. It is free to use, and the site says your first arc takes about ten seconds. It works in the browser and as a PWA via app.framesketch.xyz, and desktop apps for Windows and Linux are stated as coming soon. Cloud sync is an optional toggle that carries annotations only. FrameSketch's promise is simple: the motion is right there, so draw on it. It replaces describing a pose or compiling screenshots with direct annotation on the footage — frame-accurate, pressure sensitive, layered, and local-first. Free to use, with tiny .fsk project files that travel easily and footage that never leaves your device, it gives animators a fast, private way to mark up motion and pass the notes along.
QApilot MCP for Android is a Model Context Protocol (MCP) server and CLI that lets developers automate tests on real Android devices and emulators from inside an AI coding client such as Claude, Cursor, or any MCP-compatible AI client. Rather than writing Appium code, users describe a test flow in plain English, and the AI agent builds a structured plan that QApilot executes step by step on the connected device. It is intended for mobile QA engineers, Android developers, and release teams who want Android test automation to run from the tools they already work in. The guide positions QApilot MCP around a simple premise: Android UI automation should not require hand-written Appium code. Test authors describe what they want to verify in ordinary language, and the system handles the mechanics of driving the device. The documentation also points out that step titles are generated automatically with a maximum of 50 characters and no XPath, so reports and the dashboard always stay readable. Before installation, the guide stresses that five prerequisites must be in place: Node.js 18+ (from nodejs.org or nvm), Java JDK 11+ (required by Appium, with JAVA_HOME set in the shell profile), the Android SDK or Studio (which installs adb and platform-tools, with ANDROID_HOME pointing to the SDK path), a USB device with USB debugging enabled or an AVD emulator verified with adb devices, and Appium 2.19.0 installed globally with the UIAutomator2 driver. Installation follows a documented sequence. The CLI is installed globally from the distribution package with a single npm command, then verified by running the server in stdio mode, where the server starts and waits for input without errors. Appium setup is described as a one-time task using pinned versions: Appium 2.19.0 and the UiAutomator2 Android driver 4.2.6, followed by starting the Appium server with the flags shown for chromedriver autodownload, adb shell access, the /wd/hub base path, and CORS, and confirming the device is visible through adb devices. The guide warns that other Appium or driver versions may break the MCP server and recommends keeping Appium running in a separate terminal before starting any test session. Connecting an AI client is done by pasting an MCP configuration block for Claude Desktop, Cursor, or OpenAI Codex, after which QApilot Mobile MCP appears in the client's connected tools list. Restarting the AI client is required after saving the configuration. Once connected, users register and log in through conversation. An account can be created by asking the AI to sign up with an email address; an activation link arrives by email and the login credentials follow. If environment credentials are set in the configuration, the client logs in automatically on first use; otherwise credentials can be supplied in a prompt. Users then create a project to hold their tests and launch their app by giving the Android package ID, with the default project and device selected automatically. From there, test steps are recorded by describing them: the AI builds a structured plan and executes each step on the device in real time. The guide shows example prompts for search flows, login flows with screenshots, navigation and assertions, scrolling and filtering, and form submission. A live preview returns a URL on every app launch call so the device screen can be watched in the browser as steps execute. After a successful run, the recorded steps can be pushed to QApilot as a saved test case for future replay, and only happy-path steps are saved; failures are excluded, and a failed step should be fixed and a passed report generated first. Saved test cases can be replayed one by one, in batches of IDs, or from an Excel sheet such as regression_suite.xlsx, with execution status checked on demand. Every session should end with a report, generated even on failure because it clears execution state so the next test can start cleanly. Reports capture step results, screenshots, errors, and timing, and are written to a dated session folder containing output.json and report.yaml, plus a scenario.feature Gherkin file when the session passes. The server also exposes a cache for XPaths and skills learned per app, with tools to fetch cache context for the current app and summarize what is cached for a given package, along with usage reporting for tokens and API consumption. The overall workflow is agent-led. The AI client lays out the test steps, and QApilot runs them: it finds the elements, waits for the screen to settle, retries when something moves, and caches what it learns so repeat runs are faster. Every passing run saves a Gherkin feature file and becomes a replayable test case, tying prompt-driven testing to a durable regression asset. The MCP server communicates over the Model Context Protocol, exposing dedicated tools for every capability, including account signup and login, project listing and selection, device listing and selection, app listing and launching, session start and stop, plan submission and execution, single manual actions such as tap, type and swipe, execution state, session status and info, preview URLs, accepting steps, replaying test cases, running Excel suites, generating reports, cache inspection, and usage tracking. For users, the benefits described are practical: no Appium code to write, test flows expressed in plain English, execution on real devices and emulators, readable auto-generated step titles, and replayable test cases that accumulate over time. Because caching is retained between runs, repeated executions are faster, and because reports include screenshots, errors and timing, failures are easier to inspect. The preview URL lets teams watch a run from the beginning, and the Excel-driven execution path supports regression batches without rewriting anything by hand. The documented use cases are drawn from everyday mobile app testing. A search flow can be tested by tapping Search, typing a search term such as Honda City, selecting the first result, and verifying the car detail page loads. A login flow can enter an email and password and screenshot the home screen. Navigation and assertions can go to a comparison screen, add two cars, and confirm the compare button is visible. A scroll-and-filter scenario can scroll the filters page, select Petrol as the fuel type, and apply the filter. Form submission scenarios can fill an enquiry form with a name, phone number and city, then submit. Saved suites can then be replayed individually, in sequence, or in bulk from an Excel regression sheet, with status checks in between. QApilot MCP for Android is aimed at mobile QA engineers, Android developers, and teams that already work inside AI coding agents such as Claude, Cursor, or OpenAI Codex, as well as any MCP-compatible client. It integrates with Appium 2.19.0 and the UiAutomator2 driver, the Android SDK and adb, and runs on Node.js 18+ with Java JDK 11+. A Slack community is available for questions, prompts, and setup help. The guide does not state pricing or plan details. In short, QApilot MCP for Android turns an AI coding agent into an Android test automation driver: describe the flow in plain English, let the agent plan it, and let QApilot execute, preview, accept, replay and report on it, with caching that makes the next run faster.
Kabza is a real-time territory capture game played on the real maps of Noida, Gurugram, Delhi and Bengaluru. Rather than an invented fantasy world, it drops you onto city maps divided into wards, where rival fictional parties already hold ground and Independents sit in the middle of the fight. Your job is simple to describe and hard to master: drag from a ward you hold to any other ward to send half its supporters, take territory, and outgrow the rival parties until you control 75% of the map. It is made for people who want a competitive strategy match without setup friction. You can play solo against bots, or open a room of up to eight and battle friends. It runs free in your browser, with no download and no account needed. Most browser strategy games ask you to care about places that do not exist. Kabza's premise is that the map itself is the hook. The territory you are fighting over is recognisable: Noida, Gurugram, Delhi or Bengaluru, laid out as a real map divided into wards and coloured by the parties that hold them. That familiarity makes the game easier to read at a glance and more interesting to argue about afterwards, because the board looks like somewhere you have actually been. Two other frictions are removed at the same time. There is nothing to install and there is no sign-up: the product is described plainly as free in your browser, with no download or account needed. That combination of familiar geography and near-zero setup means a match can begin in moments, whether you are playing alone or bringing a group of friends into a room. The central mechanic in Kabza is drag-and-send. The on-map instruction reads: drag from a ward you hold to any ward to send half its supporters. Every action you take is therefore a trade-off. Sending supporters outward takes half of what a ward currently holds, which means a strong ward becomes weaker the moment it attacks, and a ward you strip too aggressively becomes an easy target for a rival party. Because the cost is always half, the maths scales with your own strength: large holdings can project serious force, but they also bleed proportionally whenever they move. This single rule gives the game its strategic texture. You are constantly deciding whether to press an advantage right now or hold supporters back to defend what you already own, and that decision repeats for every ward on the board. The map is divided into wards, and the interface keeps the state of the match in front of you. Kabza surfaces three things directly: Party, Wards and Supporters, alongside a count for Independents, the unaligned holders shown in the interface. Wards are the units of territory; supporters are the resource that flows between them; parties are the competing colours on the map. The published artwork for the game shows exactly this: a map of Noida's sectors coloured by rival fictional parties. Because everything is expressed in those three terms, there is very little to learn before you can read the board. You look at who holds what, how many supporters are stacked where, and which direction a push would leave you exposed. Kabza supports two ways to play. In solo mode you face bots, which lets you learn the drag-and-send rhythm and the 75% win condition without the pressure of other people. In multiplayer you join a room with up to eight players, so a single match can involve a full table of friends fighting over the same real city map. The game is described as real-time territory capture, meaning everyone is acting on the same live board rather than taking turns, and the interface displays a timer that runs during the match. That changes how you think about your moves. A decision you hesitate over is a decision someone else may already be making, and the map can shift while you are still working out where to send your next wave of supporters. Put together, the loop is straightforward. You begin on a real city map divided into wards, with rival fictional parties and Independents holding ground alongside you. You build supporters in the wards you control and then drag between wards to move them. Each send transfers half of a ward's supporters to the target, so attacking is always funded out of your existing position. Taking wards shifts the balance of the map; losing them shifts it back. The interface shows a growth state described as 'growth doubled until a ward changes hands', which tells you that supporter growth is affected by changes in ward ownership. The match ends when one side holds 75% of the map — a threshold high enough that you have to keep expanding, and high enough that a comeback remains possible while the board is still contested. The first benefit is access. Kabza is free in your browser, with no download and no account needed, so trying it costs nothing but time. The second is readability. Because the game is played on real maps of Noida, Gurugram, Delhi and Bengaluru and expressed through three simple concepts — party, wards and supporters — new players can understand the board almost immediately, while the half-of-your-supporters rule keeps every decision non-trivial. The third is flexibility: play solo against bots if you want a quiet match, or open a room of up to eight when you want company. And because matches are decided by a clear threshold of 75% of the map, every session has a definite target to push toward rather than an open-ended slog. There are several clear ways people use Kabza. A group of friends who all know a city can open a room of up to eight and settle an argument about which parts of the map matter, fighting over wards they recognise. Someone new to the game can play solo against bots to get comfortable with dragging supporters and reading the party, ward and supporter counters before joining other people. A quick browser match suits a short break, because there is nothing to install and no account to create — you open the page and play. And because the maps cover Noida, Gurugram, Delhi and Bengaluru, players from those cities can play on home ground, with a board that looks like somewhere they have actually been. Kabza is aimed at people who enjoy short, competitive strategy games and want to start one without friction, particularly those who know Noida, Gurugram, Delhi or Bengaluru and enjoy seeing a familiar city turned into a contest. It is listed under Indie Games, Strategy Games and Free Games, which fits its identity as a free, browser-based title. The product is delivered on the web: the game itself is described as free in your browser, so there is no store, installer or sign-up step standing between a player and a match. Pricing is free, and no account is required to start playing. Kabza's value proposition is narrow and clear. Take a real city map, divide it into wards, give each player a pile of supporters and one beautifully simple rule — dragging from a ward you hold sends half its supporters to another ward — then let rivals fight over the board until someone holds 75%. Wrap that in a browser game that is free, needs no download and no account, and supports both solo play against bots and rooms of up to eight friends, and you have a strategy game that is quick to start and immediately understandable. The real maps of Noida, Gurugram, Delhi and Bengaluru are what make it memorable.
Youkti is an outbound revenue system that turns account knowledge and relationship data into revenue. In its own words, it is "the outbound system of thinking and action": it keeps a memory of every account, conversation, and deal, then tells a sales team the exact next move — which deal is slipping, which dormant account just fired a signal, and what to prepare for tomorrow's meeting. It is built for account executives, RevOps teams, outbound reps, and sales leaders who want to win more new logos, move more pipeline, and reactivate dormant accounts. The stated promise is intelligent outbound, live signals, and a complete memory of every account, surfaced through command surfaces tuned to each role. The problem Youkti addresses is not a shortage of sales data but a shortage of attention and timing. Deals slip out of the pipeline before anyone notices they have stalled, dormant accounts quietly launch new initiatives, and buying committees change shape without the account team knowing. Sales teams are left doing manual updates, digging for context, guessing at next steps, and missing follow-ups. Battlecards go stale, competitive context arrives too late, and CRM records drift out of accuracy unless someone maintains them by hand. Youkti positions itself against that fragmentation, and even frames its automatic CRM sync as an alternative to spending $100K+ on Salesforce Data Cloud 360 and implementations. The first layer of the product is ARYA, described as a conversational GTM builder rather than a static workflow. You tell ARYA what you want in plain English and it builds the entire flow through conversation: signal triggers, persona matching, outreach rules, and cadence. The configuration updates live as you talk, with no drag-and-drop and no if-else logic — conversation in, config out. A visible flow runs Signal, Signal Filter, Persona Match, then Auto-Sequence. Signal triggers can include Funding Raised and Hiring Surge; target personas can be VP Sales, CRO, Head of Sales, VP Marketing, and CMO. Outreach rules can branch, for example: if Funding Raised AND Hiring Surge, use an aggressive tone, a cadence every 3–4 days, and 5 emails; if Funding Raised OR Hiring Surge, use a consultative tone, a weekly cadence, and 3 emails. The interface shows a live config review that updates as you chat with ARYA, and the product describes itself as a system that learns itself. The second layer is execution through a daily cockpit. Every morning reps open one screen where accounts are prioritized, signals are overlaid, personas are matched, and sequence hooks are written — one click pushes the sequence. A sample dashboard shows 15K accounts, 892 active signals, 609 plays for the day with 61 marked high priority, 165 live sequences, and meetings tracked for the day, with tabs for Queue, Insights, Alerts, Pipeline, and Cards. Each account row shows the account and domain, the signal and why it fired now, the matched personas, the sequence hook with its step count and duration, and a push button. Once an account is pushed, it enters an Account Journey. Youkti tracks status, engagement, replies, and meetings, and surfaces the next step automatically. There are no manual updates, no digging, no guessing, and no missed follow-ups. Journeys include auto-tracked engagement, health scoring, and AI-generated next steps, with account states such as Growing, Stable, Needs Attention, and At Risk. In a sample journey, Storylane is shown with 10 emails sent, 10 replies, and 3 meetings and a recommended next step of reaching out with a relevant case study; Intuit shows 5 emails with 5 replies and a suggestion to push for a meeting; WinSupply is shown with 16 emails, 16 replies, and 22 meetings. A deep dive view gives account intelligence with deal context and next actions. Clicking into any account reveals next actions with reasoning, the latest meeting brief with talking points, stakeholder maps, a full timeline, signals, and talk tracks. The system recommends and the user decides. In the Storylane example, the board shows emails sent, replies, meetings, and LinkedIn activity, plus seven next actions such as engaging on a product update, checking in after trial onboarding, re-engaging after 25 days of inactivity, and discussing tech stack changes, alongside a dated meeting brief and a timeline. Behind this sits an intelligence layer that scores every account on readiness, ICP fit, budget, timeline, and sales cycle, then generates deal actions, strategic approach, entry points, key messages, and email templates — described as a 6-step account-based campaign in 1 click. The scorecard example shows readiness 9/10, ICP fit 8/10, high budget backed by a $250M Series F, a 1–3 month timeline for pilot approval, a 3–5 month sales cycle, high ROI potential, a high effort level, and a best timing recommendation, along with concrete next steps. Signals are monitored across the entire TAM — funding, hiring, leadership changes, lawsuits, competitive moves, and tech stack swaps — and when one fires, the system provides analysis, reasoning, and a timing window rather than just an alert. It provides confidence scoring with reasoning, a "Why It Matters" explanation for every signal, and timing guidance such as "Next 2-4 weeks." Youkti then generates complete multi-step sequences with A/B variants, each tied to specific signals and account context. Campaign strategy, messaging angles, subject lines, and email bodies are grounded in account intelligence rather than templates. A sample sequence shows 6 total steps, 12 total emails, and a 16-day duration, where Variant A leverages a customer award and Variant B focuses on an ARR milestone and tech-stack consolidation. The selected variant can be pushed to Lemlist, Outreach, or any SEP with one click, with no copy-paste. The platform module list covers Prospects & Lists for building, distributing, and tracking prospect lists at scale; Account Intelligence for 100+ parameters of contextual company intelligence in under 60 seconds with a single click; Outreach Automation for messaging angles, follow-ups, and outreach guidance tied to real signals; Competitive Intelligence for tracking competitors, comparisons, and real-time changes affecting active deals; Sales Enablement for centralizing decks, case studies, and battlecards; CRM Enrichment for automatically updating accounts, contacts, and activity; ARYA, the AI GTM agent; Account Journey for personalized, adaptive multi-touch engagement; and Execution Analytics for tracking outbound execution across every rep, account, and play. Integrations span email and calendar (Gmail, Google Calendar, Outlook, Exchange, Office 365), data (Snowflake, AWS, OneDrive, SharePoint, Google Drive), CRM (Salesforce, HubSpot, Zoho CRM, Pipedrive, Freshsales), prospecting data providers (LinkedIn Sales Navigator, Apollo.io, Lusha, Cognism, Clearbit, People Data Labs, ZoomInfo, Full Enrich, Kipplo, Prospeo, BetterContact, Clay, Bitscale), sales engagement (Outreach, Salesloft, Apollo.io, HubSpot Sales), and signals (Google Analytics, rB2B, SEMrush, Ahrefs, Hotjar). Youkti states that other tools sync with your CRM while Youkti syncs automatically. Outcomes described on the site include NeoSOFT generating $50K+ pipeline growth, Samvidh increasing revenue 20% QoQ, and Deeploop increasing selling time by 3× with Youkti. The homepage says Youkti is trusted by high-performing teams including NeoSOFT, Samvidh Tech, Deeploop, and T-Hub, and that signal-based discovery spans 100M+ companies. Contact data, buying signals, and intent are described as free, with no card and no meter, and the product promises execution from day one rather than after weeks of setup, with a demo available. Concrete use cases shown in the product include protecting an at-risk deal such as Westbridge Industrial, an $180K ARR manufacturing account awaiting board approval for 16 days with a suggested meeting; prioritizing a high-intent account such as Northfield Systems, a Series B SaaS company with a new CRO, nine open sales leadership roles, new funding, and a 96/100 ICP score; reactivating a dormant account such as Crestview Health, last contacted 94 days ago, after a digital transformation initiative launched; opening an expansion opportunity such as Brookstone Manufacturing, with a renewal in 60 days and two business units engaged; and preparing for a strategic meeting such as Everline Retail, where a CIO joined tomorrow's meeting, triggering stakeholder map review, security question resolution, and talking point preparation. Youkti is aimed at leaders, AEs, and outbound reps, each getting a command surface tuned to their job: leaders and RevOps get intelligence on deals at risk, top competitors, and client objections; AEs and sales leaders get actions and preparation for strategic conversations; reps and GTM teams get outbound execution. The core takeaway is that Youkti turns account knowledge, relationship data, and live signals into specific revenue actions — telling each seller exactly what to do next, for every deal, every account, and every stage from first signal to last touch.

Marked Share is a free service for publishing, reviewing, and sharing Markdown and TextBundle documents on the web. It is a subproduct of Marked 3, the Markdown preview app, but it does not require Marked to be used — anyone can sign up free and publish Markdown either from Marked or straight from the web. Documents can be shared with images and attachments through short links on markedb.in. Beyond simple sharing, Marked Share lets other people highlight and comment on a document, gives you a library to manage what you have published, and lets you keep private drafts until you are ready to share. It also publishes "blog" feeds with RSS/Atom and Micro.blog integration, and offers either a built-in editor or a full API for integrating with your favorite editor or tool. Markdown and TextBundle documents are written in plain text, but they frequently carry images and attachments that have to travel with them for the document to make sense. That makes everyday sharing harder than it should be: you want readers to see the formatted result, keep the assets intact, and have a way to respond to what they read. Marked Share addresses this by publishing documents to the web as shareable, linkable pages rather than as loose files. It also solves the timing problem that writers face — material is often not ready to be public, so the service supports private drafts that stay unshared until the author decides otherwise. For authors who think in Markdown and write regularly, the service turns individual documents into something closer to a public stream. The core of Marked Share is publishing and sharing. A document is published from Marked or from the web, and the result is served under a short link on markedb.in that is easy to paste into a message, an email, or a chat. Because images and attachments travel with the document, the published page presents the full piece rather than a bare text file. Published documents are collected in a library that the author manages from the service, so there is a persistent place to track what has been shared. Private drafts sit alongside published items within that library, letting an author build a body of work incrementally and release each document only when it is ready to be seen. Marked Share is not only a publishing endpoint; it is also a place for review. Readers can highlight passages in a shared document and leave comments on them. This turns a published Markdown file into a two-way artifact: an author can send out a draft, receive specific feedback anchored to particular sentences rather than to vague general impressions, and revise accordingly. Because feedback lands on the document itself, there is no need to reconcile separate files, comment threads, or copies of the text. The highlight-and-comment model is what makes the service useful to anyone who wants a second pair of eyes on a document before it goes further — a reviewer, an editor, a colleague, or a client. For authors who publish regularly, Marked Share can go beyond individual documents and publish "blog" feeds. Each feed is served with RSS/Atom, so it can be subscribed to in any feed reader, and it integrates with Micro.blog as well. This means a set of Markdown documents can behave less like loose files and more like a running publication that interested readers can follow. Writers who already keep their material in Markdown — notes, essays, updates — can expose a stream of it without standing up a separate blogging platform or converting everything into a content management system. The feed is generated from the documents themselves, so the Markdown remains the source. Marked Share gives authors two ways to work. The first is a built-in editor on the service itself, sufficient for writing or editing a document and publishing it from the browser. The second is a full API, which allows Marked Share to be integrated with whatever editor or tool the author already prefers, so publishing can happen from within an existing workflow instead of requiring a switch to a new application. Either route produces the same result: a shared document with a short link, attached images and attachments, and the option of highlights and comments from readers. The service is free to use, with no subscription required, and access begins with a sign-in or a free sign-up, after which the library, drafts, published documents, and feeds are managed from one place. Because Marked Share is free and requires no subscription, the cost of sharing a document or trying the service out is effectively zero, and there is no commitment involved in using it. Authors get the benefit of a short, clean link instead of an unwieldy file attachment, and recipients get a page they can read and annotate. Private drafts give authors control over timing, so work in progress never has to be visible before it is meant to be. The library keeps published material organized rather than scattered. And the RSS/Atom and Micro.blog feeds give a body of Markdown writing a way to reach readers who want to follow it, without the author building and maintaining a separate publishing stack. Concrete uses of Marked Share follow directly from how it works. A writer can draft an essay in Markdown, keep it private until it is polished, then publish it to a short markedb.in link and send that link to a friend or an editor who highlights passages and leaves comments. A team member can publish a document that includes images and attachments so a reviewer sees the complete piece rather than a stripped-down text file. Someone who writes regularly can maintain a feed of published documents and share the RSS/Atom or Micro.blog subscription with readers who want to follow along. And anyone who prefers to write in their own editor can integrate through the API and publish from there, keeping the tool they like while still using Marked Share as the place documents live. Marked itself can also publish straight to the service. Marked Share is for people who write in Markdown and TextBundle: writers, note takers, and users of text editors, which are the topics under which the product is listed. It also suits Marked users who want a publishing and review layer for their documents, though Marked is not required. The integrations named in the product are Marked itself, markedb.in for short links, RSS/Atom feeds, and Micro.blog, along with a full API for connecting an editor or tool of choice. Pricing is straightforward: Marked Share is free, described as a free service with no subscription required, and is reached by signing in or signing up for a free account. Marked Share packages Markdown publishing into a single free service: publish a document from Marked or the web, share it with a short markedb.in link that carries its images and attachments, collect highlights and comments from readers, keep drafts private until the time is right, and optionally turn published documents into RSS/Atom and Micro.blog feeds. With a built-in editor for quick work and a full API for integrating existing tools, it makes sharing and reviewing Markdown and TextBundle documents as simple as sending a link.
ColdLine.ai is an AI tool that turns cold prospects into hot leads with AI-powered personalized pitches. It is built for anyone who sends outreach to people they have not spoken to before and needs each message to feel relevant rather than generic. The product works from information you already have about a prospect: you simply add your prospect's details, and ColdLine.ai creates a relevant, human-sounding pitch in seconds. Its stated purpose is to save time, personalize your outreach, and get more replies — without writing every message from scratch. The people it is positioned for are founders, sales teams, marketers, recruiters, and agencies. Cold outreach is difficult precisely because it is cold. A message that reads like a template is easy to ignore, while a message that speaks to the recipient's specific situation is far more likely to be read and answered. Producing that kind of message at any volume, however, is slow work: each prospect has to be considered individually, and each pitch has to be written from a blank page. ColdLine.ai addresses that tension head-on. Instead of forcing a choice between personalization and speed, the product is designed to deliver both, generating a relevant pitch for each prospect quickly enough that outreach can continue at volume. The stated outcome is more replies from prospects who were previously cold. The first step in the ColdLine.ai workflow is providing the details of the prospect you want to reach. You add your prospect's details, and that information becomes the basis for the pitch the tool generates. This input is what makes personalization possible: rather than a single generic message reused across a list of contacts, the pitch is built around the specific prospect in front of you. Because the only thing you have to supply is the prospect's details, the barrier to producing a tailored message is low, and the process fits naturally into an existing prospecting routine rather than replacing it. ColdLine.ai generates the pitch in seconds. That speed is at the core of the value proposition, because personalized outreach normally costs time — and time is what limits how many prospects a person or a team can realistically approach. By compressing the writing step to seconds per prospect, ColdLine.ai makes it practical to personalize outreach consistently instead of reserving personalization for the handful of prospects who seem most important. The stated benefit is tied directly to this speed: save time, personalize your outreach, and get more replies. The pitches ColdLine.ai creates are described as relevant and human-sounding. Relevance means the message is connected to the prospect's details rather than being a generic template; human-sounding means the result is intended to read like something a person would actually write, not like an obviously automated message. Together, these qualities are what allow a pitch to be sent to a cold prospect without immediately marking it as bulk outreach. A relevant, human-sounding message is more likely to be engaged with, which is how the product aims to turn cold prospects into hot leads. ColdLine.ai follows a deliberately short methodology. You bring the prospect details; ColdLine.ai handles the writing. No elaborate setup is described, and no writing is required from you — the product exists so that you do not have to compose every message from scratch. The workflow is simple: add your prospect's details, receive a personalized pitch created by AI in seconds, and send it. The AI's role is to turn the raw facts you have about a prospect into a pitch that is relevant and sounds human, at a speed that manual writing cannot match. The benefits stated for ColdLine.ai are threefold: saving time, personalizing outreach, and getting more replies. Saving time matters because outreach volume is usually limited by writing capacity. Personalization matters because relevant messages perform better than generic ones. More replies matter because a reply is the point at which a cold prospect starts to become a lead. Because the product removes the need to write every message from scratch, the time that would have gone into drafting can instead go into reaching more prospects or following up with the people who respond. ColdLine.ai is described as suitable for founders, sales teams, marketers, recruiters, and agencies. For a founder, it means reaching out to prospective customers or partners without spending the day writing introductions. For a sales team, it means personalized first-touch outreach across a pipeline of prospects. For a marketer, it supports outreach campaigns that need to feel individually written. For a recruiter, it means approaching candidates with messages tailored to each person. For an agency, it means producing personalized outreach for multiple clients without the writing overhead that would normally be involved. The target users named in the product's own description are founders, sales teams, marketers, recruiters, and agencies — people and teams whose work depends on starting conversations with prospects they do not yet know. ColdLine.ai is presented squarely as a tool for that outreach step. Beyond the fact that it is an AI-powered product reached through its website at coldlineai.xyz, the available content does not state specific integrations, a technical stack, or pricing plans. ColdLine.ai's value proposition is straightforward: cold prospects become hot leads when the pitch they receive is relevant and human-sounding, and producing that kind of pitch at scale is normally too slow to do consistently. ColdLine.ai automates the writing step so that you add your prospect's details and get a personalized pitch in seconds. The result is outreach that is faster to produce, personalized by default, and designed to earn more replies — without writing every message from scratch.
Captain Kill Switch is a free menu-bar utility that closes every running application on your computer with a single click. It installs quietly into the macOS menu bar or the Windows and Linux system tray, waits in the background, and fires only in the moment you need what the site calls a clean slate. The product is designed for anyone who wants a calm, decisive reset — before a presentation, a screen-share, a game, or simply to clear their head — and it delivers the same single-button experience on macOS, Windows, and Linux at no cost, with no account required. Most computer users know the small, recurring friction of a cluttered desktop. When many applications are open at once, closing them means either tabbing through windows one by one or running what the site calls a "Cmd-Q marathon" — a repetitive sequence of quitting each app in turn. That is slow, error-prone, and awkward when other people are watching your screen. Captain Kill Switch was built to replace that ritual with one action. As the copy puts it, there is "No Alt-Tab. No Cmd-Q marathon. Just one calm, decisive click." The whole point of the product is that it does one thing extremely well, with no bloat, no dashboards, and no upsell. The core feature is instant, one-click reset. Click the tray icon once and every open application closes in milliseconds, delivering an empty desktop ready for whatever comes next. The site positions this as perfect before a presentation, a screen-share, a game, or just to clear your head. Alongside the click, Captain Kill Switch offers a global hotkey: you can bind a shortcut and fire it from anywhere, so you never have to hunt for the menu bar. The documentation describes setting it through the menu-bar icon, then Preferences, then Shortcut, where you press the key combination you want — with the advice to pick something deliberate so you never trigger it by accident. Together these two controls mean the reset is always one click or one keystroke away. Captain Kill Switch lives in your menu bar or system tray as a discreet tray icon and nothing more. The site emphasizes that it uses minimal memory, adds no dock clutter, and consumes no background CPU, so you will forget it is there until you need it. This restraint is deliberate: the app keeps a low profile rather than competing for attention. That is matched by zero configuration. There is no setup wizard, no permissions maze, and no manual — you install it, and it just works. The getting-started flow is described as a single step: download for your OS and open it once, after which it tucks itself into your menu bar or system tray automatically. Closing "everything" could be dangerous, so Captain Kill Switch includes smart detection that closes your applications while leaving critical system processes untouched, so your Mac or PC stays stable rather than stranded. The other pillar is cross-platform consistency: the same calm, single-button experience is available on macOS, Windows, and Linux, so you learn it once and use it on every machine you own. The app is also described as running 100% locally with no account ever required, and the macOS builds are signed and notarised — signed with an Apple Developer ID and notarised by Apple, which means they open with a normal double-click with no right-click workarounds or security warnings. How it works is described in three steps, taking roughly three seconds to reach a clean desktop. Step 01, install and forget: download for your operating system and open it once, and the app tucks itself into your menu bar or system tray automatically. Step 02, hit the button: when you need a fresh start, click the tray icon or press your global hotkey — one action is the whole interface. Step 03, clean slate: every app closes at once, leaving a quiet, empty desktop ready for whatever is next, and you can repeat the process whenever the chaos returns. Under the hood, each app is asked to quit properly first, so your next launch is clean with no crash-recovery prompts. Anything still open a couple of seconds later is force-closed, unsaved work included, which is why the site advises saving what matters before you fire it. The benefits follow directly from that design. Users get speed — a full desk of applications closed in milliseconds instead of a manual quitting routine. They get predictability, because the proper-quit-first behaviour means apps reopen cleanly rather than showing crash-recovery prompts. They get a stable system, because critical processes are left alone. They get convenience, because the tool is reachable from the menu bar or a global hotkey and requires no configuration. And they get peace of mind on privacy: the app runs entirely on the machine, with no account and no ads, so nothing personal leaves the device. Concrete use cases are spelled out on the site. Before a presentation or a screen-share, a single click clears the screen so no stray windows, messages, or notifications appear to an audience. Before launching a game, it frees the machine of background applications. For anyone whose focus is scattered by a busy desktop, it works as a deliberate "clear your head" gesture that resets the workspace to zero. Because the same action is repeatable, it also suits anyone who regularly accumulates windows during the day and wants to return to a quiet, empty desktop whenever the chaos returns. Captain Kill Switch is free forever across macOS, Windows, and Linux. The current release stated on the site is v0.4.4, dated August 28, 2026, with builds for Windows 10/11, macOS 10.15+, and Linux distributions including Ubuntu, Debian, and Arch. Installation is offered through several official channels. On Windows there is an EXE installer (recommended) and an MSI installer, plus winget and Scoop packages. On macOS there is a DMG package (recommended), a PKG installer, and Homebrew options for both the app and the command-line tool. On Linux there is a DEB package (recommended), an APT repository, and a terminal install script. The app leaves nothing lingering behind when removed: quit it from the menu bar and drag it to the Trash on macOS, uninstall it from Apps & Features on Windows, or remove the package on Linux. Privacy is a stated priority. The app runs 100% locally, requires no account, and shows no ads. The only data collected is anonymous usage statistics and crash reports used solely to improve the app: which features are used (for example, how many apps a sweep closed), the app version, the operating system, and the language, plus a crash report if the app itself crashes. Those events carry a random install ID and never a name or anything about the apps, files, or windows on the machine. Nothing is sold or shared. The site answers the obvious question about cost directly — there is no catch; it is genuinely free, with anonymous statistics helping the team improve it. Captain Kill Switch takes a single, well-defined job — closing every open application on demand — and reduces it to one button, a hotkey, and a menu-bar icon. Free on macOS, Windows, and Linux, locally run, signed and notarised, and configurable in seconds, it turns the chore of quitting apps one by one into one calm, decisive action, leaving a clean slate exactly when you need it.
Stackness is a social platform where people in IT show the tools, workflows, and approaches they use to get things built. It is built for everyone in IT with opinions about their setup, from engineers and designers to data folks and everyone in between. The main purpose is to give your setup a social home: you build a stack profile that you share as one link, post the moves behind that stack, follow people whose taste you trust, and discover what works. Most people working in tech have strong opinions about the tools they use, but there is rarely a good place to put that knowledge. Tools are what you install, while moves are how you actually work — the habits, rituals and workflow tricks that make a stack yours. Stackness exists to capture both. Rather than leaving your setup buried in a forgotten README or a chat thread, it turns it into a public, living profile. The platform also tracks how tools rise and fall over time, so the community can see which choices are gaining traction and which are slipping, instead of relying on isolated opinions. The first thing Stackness gives you is a profile you can customize to make it unique. You drag tiles where they belong, size up the ones that matter, tuck the little utilities into a cluster, and colour each subspace to taste, so that one link ends up looking like you. Tools are grouped into logical buckets. In the example shown on the site, a profile has a "Daily drivers" group holding nine tools and one move, listing Visual Studio Code, Tailwind CSS and Claude Code, plus a "Toolbelt" group with Next.js and Docker and another Toolbelt cluster of five items including Warp, Raycast, Postman, HTTPie and jq. Each tool can carry a personal note — for instance, "My daily driver for years" or "The TypeScript support is unbeatable" — giving context to why a tool earned its place rather than just naming it. Alongside tools, Stackness lets you show your moves. Moves are the switches, setups, and workflow tricks behind your stack; they share how you actually work rather than just what you installed. A move is written up with a title, a description, and the tools it involves. The example on the site is a prompt-driven TDD workflow: "I write the test prompt first, then implement until it runs green." Its steps are laid out in order — write a failing Vitest spec for the bug first and do not touch src/ until it runs red, let Claude Code scaffold the specs, run the suite so it must fail first, then implement until green. Moves like this make a stack legible to other people and give them something concrete they can copy. Discovery is the other half of the product. You can see what everyone else is using through trending tools, trending moves, and rising stars. Following is central to the experience: follow people whose taste you trust and keep an eye on the rest. Stackness surfaces a Top members list, with profile cards showing a member's handle, how many moves and tools they have listed, and a follow button, so you can build a feed of setups you find credible. Because everything is public and comparable, the platform doubles as a way to benchmark your own choices against people doing similar work. Every tool has its own page. A tool page shows popularity over twelve weeks, who else is using it, and what they keep it next to. The Tailwind CSS page, for example, is labelled a utility-first CSS framework for rapid UI development, filed under Languages & Frameworks, and shows usage on Stackness by week — starting at 128 members, then 131 members (up 3 in the last 12 weeks), then 126 members (down 2 in the last 12 weeks). This makes it possible to watch a tool climb the ranks or slip down them, and to see the company a tool keeps in real stacks. Stackness also publishes a blog with updates, announcements, trends and explainers. Posts are tagged for browsing — product-hunt, stacks, moves, changelog, trends, workflows and getting-started — and include an announcement that Stackness is live on Product Hunt, a changelog covering public trending pages, category hubs, move cards for your README, tile quick look and a nicer blog, plus a knowledge post answering "What is a move, anyway?". The blog is where the platform explains its concepts and shares its changes in public. Overall, Stackness works by turning a personal setup into structured, shareable content. You register, add the tools you use, arrange them into tiles and clusters, and attach notes explaining each choice. You then write moves that describe the switches, setups and workflow tricks behind your stack, linking the tools involved. Everything rolls up into a single profile link you can share anywhere. From there, the platform aggregates that data across members into trending tools, rising stars, and per-tool pages with twelve-week popularity charts, while the follow graph lets you curate whose stacks you watch. The benefits follow directly from that structure. Your stack becomes one link instead of a scattered list, so it is easy to share in a bio, a README, or a conversation. Notes and moves explain the reasoning behind your choices, which turns a tool list into something other people can actually learn from. Following people whose taste you trust gives you a filtered signal on what works, while tool pages and trend charts show whether a tool is gaining or losing momentum before you commit to it. And because the product is free to use, the barrier to showing your stack is essentially zero. Concrete use cases appear throughout the site. A developer builds a stack profile and shares it as one link with their team or audience. Someone writes up a prompt-driven TDD workflow as a move so colleagues can reproduce it step by step. A person deciding between similar libraries checks the relevant tool page to see popularity over twelve weeks and which other tools it is kept next to. Someone follows a handful of members whose setups they admire and watches the trending pages for rising stars. A vibe coder or an engineer documents daily drivers such as Visual Studio Code, Tailwind CSS and Claude Code, with a note explaining why each one stays. Stackness is for everyone in IT who has opinions about their setup: engineers, designers, data folks, and everyone in between, including developers and vibe coders. Joining is free, and the platform also offers an MCP server. Beyond that, an optional supporter tier costs CHF 5 per month and adds a weekly trends newsletter, trend waves with historical popularity charts, subscribers-only stacks and moves, a supporter badge on your profile, and early access to new features. A separate team option lets you back Stackness together with your whole team, with team perks described as just getting started. Stackness takes the tools and habits that usually live in your head and turns them into a public, browsable profile: build your stack, post your moves, follow trusted people, and watch tools rise and fall. It is a social home for your dev tools, and it is free to join.

Work Life Panda is a task manager and a calendar combined into a single app, built so that everything you have to do and everywhere you have to be live in one calm place. Instead of starting with an empty list and asking you to rebuild your life inside it, it starts with the life you already have: you connect the calendar you already use and your week is simply there, and you capture the rest in a sentence with an AI that runs on your device rather than in the cloud. Tasks, events, calendars, notes, files and a chat on every item come together in one connected workspace, on iPhone, iPad, Android and the web, so your personal and family life, or the groups and small teams you plan with, can be coordinated from the same source of truth. Most task apps start empty and ask you to rebuild your life inside them. The reality of a normal week is more scattered than that: your week lives in a calendar, your to-dos live in a list, and your plans live in a group chat. That split means plans get duplicated, decisions get buried in messaging threads, and people end up asking where something was decided. Work Life Panda's answer is to start full rather than empty. It connects the calendar you already keep, brings the invitations already sitting in your email onto your schedule, and then gives each task and each event its own place to be discussed, planned and tracked. The result is described as one evolving operating layer for life rather than another isolated to-do app. Calendar connection is the foundation. Work Life Panda connects to the calendar you already use, with Google, Apple iCloud and Microsoft Outlook all syncing both ways, plus Fastmail and Zoho, and you can also follow any calendar published as a link. The important detail is that it stays your calendar rather than becoming a copy: change something in either place and both stay right. There is nothing to import and nothing to retype, because the week you already have simply appears inside the app. For anyone who has created a new tool only to abandon it during setup, or duplicated events between systems, this single connection removes the setup tax that usually kills a productivity app before it has a chance to help you. A related capability takes the effort out of getting plans out of your inbox. Invitations in your email become events: a booking lands in your inbox and the event lands on your calendar. Connect an iCloud or Outlook mailbox and the invitations already sitting in it become events on their own, with no forwarding and no copying. The marketing content notes that Gmail is waiting on Google's security review. This matters because confirmations, invitations and bookings are the raw material of a busy week, and they usually arrive somewhere other than the place you plan from. Pulling them into the calendar automatically means the thing you have to attend is already on your schedule when you go to plan around it. Panda AI handles capture. You turn a sentence or your voice into a task, and the AI that does the work runs on your device, not in the cloud, so your data stays with you. Because the processing is local, it also works with no internet, which means a thought captured on a plane, in a tunnel or anywhere else without a signal can still become structured around your schedule. The stated aim is to keep control while safe local AI automates the busy steps, smoothing the mechanical parts of planning without handing your life to an opaque cloud service. For people who are cautious about where their personal plans and family details are processed, running the AI on the device is the difference between trusting a tool with your life and not. Every task and every event carries its own chat. The conversation lives on the thing it is about, so you discuss and decide on the item itself, assign and hand off work, and see what moved, with files, people and tracked history attached to the item. Because the discussion is attached to the task or event rather than living in a separate messaging thread, nobody has to ask where it was decided. Shared spaces extend this to other people: share one with your partner, your family or your team, and connect a calendar into a shared space so everyone sees it. That turns a plan into something a group can actually operate from, rather than a chat thread that slowly loses the detail. Beyond tasks and events, the app is described as more than a task app, an evolving operating layer for life with several connected pieces. Notes stay connected, so you can capture ideas, lists, meeting notes or family context without losing the connection to what needs doing. People, roles, kids and rewards can be managed from the same core workflow, covering shared responsibilities, family routines, kids and reward systems. Birthdays, anniversaries and other important dates are kept in one place so the personal moments that matter do not slip through the cracks. Each of these is not a separate module you have to reconcile later, but a view onto the same connected workspace. The unifying methodology is a single connected workspace with one source of truth. Everything begins from the life you already have rather than a blank template; every item carries its own chat so context stays with the work; and the same product experience follows you across iOS, Android and web so your life does not split just because your devices change. On iPhone and iPad you capture, plan, collaborate and stay on top of life from the device already in your hand. On Android you keep the same connected workflow with the same shared model, collaboration and AI-assisted experience. In the browser you get a larger workspace for planning, reviewing and coordinating. Instead of scattering your life across separate tools, the app is where the calendar, the tasks, the notes, the people and the conversations about them meet. The benefits follow from that consolidation. Your to-dos and your whole schedule sit together, so you can see what you have to do in the context of everywhere you have to be. Invitations in your email become events, so attendance does not depend on manual copying. Capture in a sentence or by voice means the gap between having a thought and having it tracked is short enough that you actually do it. Private on-device AI means that convenience does not cost you control of your data, and offline operation means it works regardless of connectivity. A chat on every item means decisions stay attached to what they affect, and shared spaces mean the people you plan with see the same picture. The use cases described are grouped into two broad kinds of life. For personal and family life, Work Life Panda is a calmer home base covering chores, kids, plans, reminders, notes and birthdays, captured in a sentence and kept in one private place on every device you already own, with no shared wall tablet required. For teams and business, it is for trips, clubs, shared houses, side projects and small teams, giving the plan a real home where tasks, events, files and the conversation about them live together instead of being scattered across a chat thread and three tools. In both cases the mechanics are the same: connect a calendar, capture what needs doing, and discuss it on the item with the people involved. Work Life Panda works on iPhone, iPad, Android and the web, so it covers phone, tablet and desktop with the same source of truth. It syncs both ways with Google, Apple iCloud and Microsoft Outlook calendars, plus Fastmail and Zoho, and can follow any calendar published as a link. Email event import is available through iCloud and Outlook mailboxes, with Gmail pending Google's security review. The app is completely free during early access, including every Pro feature, and the content states that early members always get the best pricing later, with a direct line to shape what comes next from inside the app. The takeaway is simple: Work Life Panda does not ask you to rebuild your life in a new tool. It starts with the calendar and schedule you already have, adds a real task manager alongside it, keeps a chat on every task and event so decisions stay with the work, and runs its AI on your device so all of it stays private. Every task, every calendar, one app.
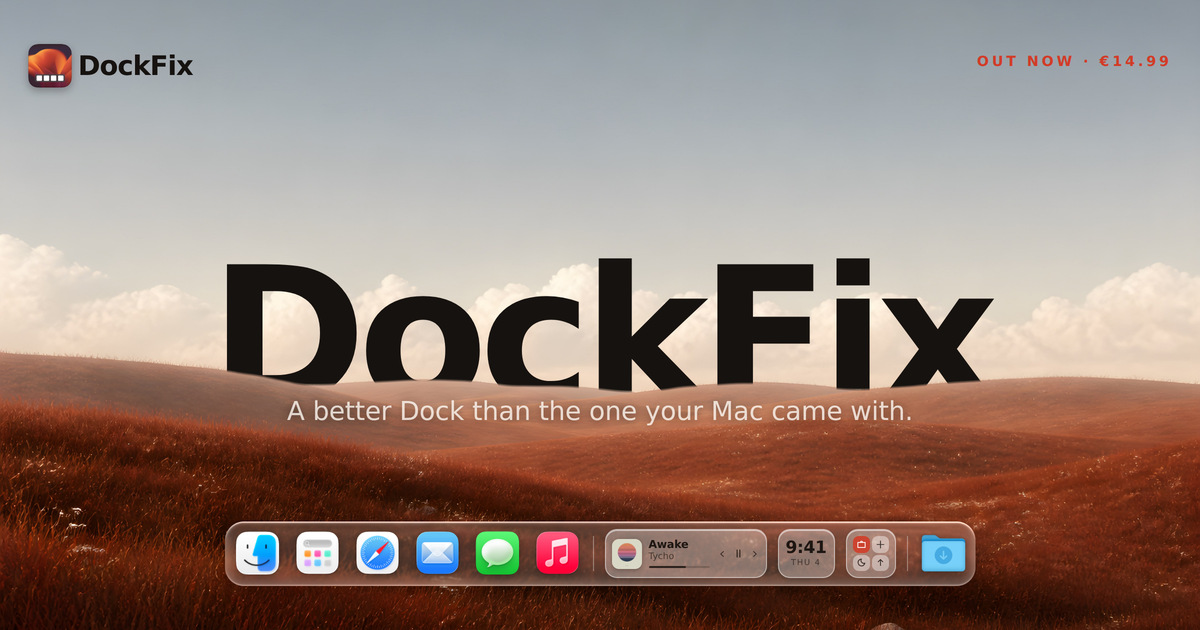
DockFix is a Dock replacement for macOS that swaps the Dock Apple ships with one you can control completely. It is built for Mac users who want their Dock to reflect their own taste and workflow rather than a fixed set of Apple defaults. With DockFix you can change colours, opacity, size, position, animations and icons, and you also gain features the system Dock does not offer, including widgets, window previews, folders, website shortcuts, presets and a file shelf. The dock keeps the same magnification, true liquid glass and overall feel as the system one, so the result reads as part of macOS rather than an add-on. DockFix runs on macOS 14 or later, on Apple silicon and Intel. The Dock that comes with a Mac is fast and reliable, but Apple closed it off. Users cannot personalise its colour, its icons, its animations, or much of what sits inside it. That limitation is the entire reason DockFix exists: as the founder puts it, the Dock that comes with your Mac is not yours. DockFix hands that control back, replacing the system Dock with one that does far more and lets you customise all of it. The trade-off most people expect from a replacement is that it will feel foreign or heavy. DockFix is built explicitly to avoid that: a dock you have made your own is only worth having if it still feels like part of macOS, right down to the weight of the magnification and the way a window folds toward the corner it came from. Complete customisation is the core of DockFix. Colours, opacity, size, position, animations and icons are all configured to your liking, so the dock can be tuned down to the detail rather than adjusted within the narrow limits of the system Dock. If you would rather not configure everything by hand, community presets let you instantly apply a theme with one click. Because those presets are shared, you can adopt a look someone else has already refined and then tweak it further. The dock keeps the same magnification and true liquid glass appearance as Apple's, so even a heavily customised dock still animates and behaves like the one that shipped with the Mac. Custom app icons let you apply your own artwork to any app on the system, including the native apps macOS will not otherwise let you touch. That means the dock can match a chosen theme or wallpaper instead of mixing stock icons with your own artwork. Folders and website shortcuts extend the dock beyond application launching, so groups of apps and frequently visited websites can sit alongside them. The file shelf provides somewhere to keep files you are working with, directly in the dock, rather than scattering them across the desktop or hunting through Finder. Together these additions turn the dock from a simple launcher into a small working surface that travels with you across every space on the Mac. Widgets bring useful information and quick controls into the dock itself, including media playback, the clock and shortcuts. Rather than opening an app or a separate panel, you can glance at or control these directly from the dock wherever you are. Window previews are described by the developer as the most requested feature: hovering an app shows its open windows, live, and you can jump straight to the one you want. This removes the guesswork of clicking through several windows belonging to the same application. Both features are additions Apple never made to the Dock, and both are integrated into the dock itself rather than bolted on. DockFix 5.0 was rebuilt from the ground up: a new engine, a new interface, and, according to the founder, not one line of the old code left in place. Nothing else shipped while the rewrite was happening, because, in the founder's words, a rewrite is not something you can do halfway. The goal of that work was a dock that looks and animates exactly like the system one straight out of the box, with the same magnification, true liquid glass, and the same feel throughout. The founder describes the finer points that had to be got right: the magnification has to carry the right weight, a window has to fold toward the corner it came from, and an icon has to appear the instant the app does. DockFix requires no special permissions and never asks you to disable System Integrity Protection. It hides the system Dock while it runs and restores it when you quit, so nothing is changed permanently. The practical benefit is a Dock that behaves exactly like the one macOS ships while doing considerably more. Performance is a stated priority: the new version uses under 1% CPU on average, so the customisation and the extra features do not come at the cost of a slower Mac. Because the system Dock is hidden rather than modified, quitting DockFix returns the Mac to its original state, which makes trying it low risk. Matching Apple's ordering and animation means there is no relearning period: the dock still feels native, just customised. And DockFix collects no data about you: there is no tracking and no usage collection of any kind. The developer states that it stores your email address to manage your licence and answer support, and nothing else. In day-to-day use, DockFix fits several concrete workflows. You can pick or build a theme, apply a community preset with one click, and have a dock that matches your desktop without hand-configuring every colour and animation. If you keep many windows of the same app open, such as a browser or an editor, you can hover the app icon and jump straight to the right window from the live preview. Media playback, the clock and shortcuts can be kept in the dock as widgets for quick control without leaving the current app. Files in progress can sit on the file shelf instead of cluttering the desktop, and folders plus website shortcuts keep frequently used apps and sites grouped in one place. Existing owners simply update as well: the new version is the one you get today, by downloading it or opening the copy you already have and choosing Check for Updates. DockFix is aimed at Mac users who want their Dock to be personal and more capable: people who already customise their desktop, wallpaper and icons, and who find the standard Dock too limited. It runs on macOS 14 or later, on both Apple silicon and Intel Macs. Pricing is a single payment of €14.99, paid once, with no subscription. A seven-day free trial unlocks every feature with no card required, and your settings carry straight over if you buy a licence during or after the trial. Enrolled students receive a 30% discount. If you already own DockFix, the new version is free: your licence carries over automatically, with nothing to move or reactivate, and a lost licence key can be recovered by pressing Recover inside the app. Questions are handled through the DockFix support page and a Discord community where, according to the site, most questions are answered within a day. DockFix also publishes a roadmap and a discover page for community docks, so users can see what is planned for the app and what other people have built with it. Taken together, DockFix 5.0 is a fully customisable Dock for macOS that keeps everything people like about Apple's Dock, the same magnification, liquid glass and native feel, while adding the colours, icons, animations, widgets, window previews, folders, presets and file shelf that Apple never provided. It costs €14.99 once, runs at under 1% CPU on average, and can be tried free for seven days.
Duos is an AI-powered job interview preparation app that lets candidates rehearse a realistic voice interview before the real thing. You paste a link to a real job posting — the site says it can analyze any public link, including LinkedIn — and Duos builds the company, the role, the questions and a personalized interview flow around it. From there you put on headphones and talk out loud to an AI interviewer in a live voice conversation, just as you would in an actual interview. The product is built for anyone preparing for a job interview, from a first internship through to a senior career switch, and its stated purpose is simple: stop guessing why you are not getting hired, fix your blind spots, and land the job offer. Why Duos exists: the site opens with the blunt premise 'Stop guessing why you're not getting hired' and lists three reasons job interviews suck. First, preparation feels fake — rehearsing answers feels nothing like the real thing. Second, total uncertainty — the stakes are high and you don't even know if you're doing well. Third, no feedback — you get rejected and never hear what went wrong. The Product Hunt description frames the same problem differently, describing interviewing as 'a social game with unwritten rules, scored by people who never explain the score.' Duos positions itself as the rehearsal, a place to practice until you know exactly what to fix, so that you build real skills without risking real interviews. As the closing line of the site puts it, 'Practice here. Win out there.' Rehearse the real interview. The core workflow starts with a real job. You paste a link to a job posting — the site shows a LinkedIn jobs URL as an example and states that it can analyze any public link, even LinkedIn. Duos then runs an extraction process: reading the job post, pulling out the role, building the company and shaping the questions. You review the recognized job details, which include the company name, the role, the requirements and a role description. From there you pick the difficulty and the interview stages and generate a personalized interview flow. Because the simulation is built from your actual job posting and your CV, the questions stop being generic — the site notes that uploading your CV means the questions get built from your actual experience rather than staying generic. Talk and read the room. The interview itself is a live, realistic voice conversation. The interface shows the interviewer speaking and then waiting for you, along with emotional state indicators such as 'Pleased', 'Concerned' or 'Impressed', and a personality tag for each interviewer. Sessions are structured in question blocks — the example shown is an all-in-one interview with Mike of roughly 28 minutes and five questions covering small talk, past experience, UX strategy, design thinking, JTBD and Figma, and a Q&A. In-interview tools let you stay in control when you get stuck: you can see what is behind every question ('What does Mike really want to know?'), get hints based on your CV, go back and retry a topic, skip questions you're not ready for, show an example answer, explain the meaning of a question, or restore energy. The site emphasises that you have to talk out loud — 'It's a voice app, because the hardest part of job interviews is talking' — and that all it takes is headphones and ten minutes alone, with the option to pause any time to gather your thoughts. Get your game plan: the debrief. After the interview Duos produces a structured interview analysis described as a recruiter's opinion, plus an outcome such as 'Strong Yes', a count of red flags and a set of patterns. The example shown includes a hiring manager's written assessment, red flags such as negative remarks about a current workplace and a candidate speech level below expectations, confidence indicators, and a problem score. It also surfaces concrete speech patterns — for instance flagging a frequent filler word, quoting the exact replies where it appeared, and explaining how it affects you ('Stutters interrupt flow and distract from content'). The site promises a full breakdown with practical advice and real examples, and states that interviewers take notes about you and here you get to read them. Duos also tracks your performance across sessions, which the feature comparison table lists as something ChatGPT does not do and other interview apps rarely do. Stages and interviewers. Duos can run the whole hiring process or you can laser-focus on a single stage: a recruiter screen of roughly 10 minutes covering your background and motivation, a skills round of roughly 20 minutes covering your skills in action, projects, decisions and hard calls, and a manager chat of roughly 15 minutes about working style and team fit. Alongside the stages sits a large roster of AI interviewers, each with a distinct personality, demeanor and difficulty level. Examples from the site include Mike the know-it-all (100% honest, easy), Justin the impatient one (driven, hard), Mirna the mission-oriented (opinionated, mid), Marcus the high-pressure (authoritative, hard) and many more ranging from unhinged to encouraging, from hostile to supportive. The site frames this as 'Every interviewer hits different — choose who you're ready for.' Privacy. Duos makes explicit commitments about how your data is handled: your data stays private, is never sold and is never used to train AI. Your CV is scrubbed before any AI reads it, no human ever hears you, you can delete everything at any time, and only enterprise-grade, audited AI providers are used. In the FAQ the company confirms that nobody hears your recordings — it is you and the simulator, no recruiter on the line, no audience — that your audio isn't stored, and that you can delete your data whenever you want. The site also states that Duos does not judge your accent: it responds to what you say, not how you pronounce it, although it will still flag a sentence that is hard to follow, because a real interviewer would too. Why not just use ChatGPT. Duos is positioned explicitly against using a general-purpose chatbot for practice. Its comparison notes that ChatGPT drifts out of character, is always agreeable and rarely honest, asks few questions and then loses track, produces dense forgettable notes, and leaves you on your own. Duos, by contrast, is listed as offering consistent interview roleplay that stays in character, pushing back for real practice, simulating the full hiring process, producing a structured report, and offering tools when you're stuck. The Product Hunt description adds that there is a proudly over-engineered multi-agent stack inside, and that you talk to interviewers who have read your CV and can change tactics mid-conversation. The outcomes for users are focused on clarity and confidence. Instead of wondering whether you did well, you get red flags, green flags and an explanation of how to fix the patterns behind them. Instead of a rejection with no explanation, you get worked examples of better answers, and you can redo the question or redo the whole interview — nobody is keeping score but you, and failing here is the point. The site says the app builds real skills without risking real interviews, and reviewer quotes on the page describe it helping a freelancer land a first full-time design role in a competitive market, helping candidates practice interview English, boosting confidence, and pushing candidates on technical details such as API security. Concrete scenarios described on the site and by reviewers include preparing for a specific interview by uploading your CV and the job posting to get a simulation with specific questions; last-minute interview preparation; continuously improving skills to stand out from the crowd on the way to a new adventure; practicing interview English and fixing weak points in conversation; keeping interview skills sharp between real calls while staying in the context of your own profile; and rehearsing for any role and any level, from a first internship to a senior switch. The site notes that Duos will still ask hard technical questions and push you on your projects and decisions, but it is not a whiteboard tool. It also can't predict how a real conversation will go — the point, it says, is that whatever they throw at you, you can answer. Duos is available as a website and as a mobile app, with 5.0 ratings listed for both the App Store and Google Play. Pricing is straightforward: you get one full interview free with no card needed, and after that plans start at €22.99 a month, less if you pay quarterly, and practice is unlimited. It supports any role and any level. The FAQ answers questions about privacy, about whether you have to talk out loud (yes, it's a voice app), about what happens if you fail (you get feedback and worked examples of better answers), about whether it judges your accent (no), and about whether it supports technical interviews (it runs recruiter screen, skills deep-dive and hiring manager rounds but is not a whiteboard tool). In short, Duos turns interview preparation from guesswork into a repeatable loop: paste a real job, rehearse out loud with an in-character AI interviewer who has read your CV, then read a structured debrief that tells you exactly what to fix. Interview, debrief, repeat until you're ready — practice here, win out there.

LinkFlick is a macOS menu bar app that switches your Apple Magic Mouse, Magic Keyboard, and Magic Trackpad between any two Macs in one click. It is built for people who move between multiple Macs during the day — a personal MacBook and a work MacBook, or a laptop and a desktop at home — and who want their Magic peripherals to come with them. LinkFlick flicks the devices over Bluetooth instead of asking you to re-pair them by hand, and it does so without iCloud, without an Apple ID, and without digging through menus. The app was built out of a specific frustration: re-pairing a Magic Keyboard and Mouse every time its maker moved between a MacBook and a work MacBook. Those two machines ran on different Apple IDs, so Universal Control was never going to work for that setup, and manual Bluetooth re-pairing was the only option left. That meant digging through menus and repeating the same tedious routine several times a day. LinkFlick replaces that routine with a single, explicit action that moves the physical hardware to the other Mac. LinkFlick lives in your menu bar, designed to stay out of your way and ready whenever you need to switch. It connects all your trusted Macs into a cluster that is instantly available for a switch, showing which machines are online and which devices are currently attached where. With one click you move your keyboard, mouse, and trackpad to the other Mac — no cables, no dongles, just a seamless hand-off of your controls. You can also trigger the switch with a customizable hotkey, or simply tell Siri to flick devices. Because control is explicit, there is no cursor drifting off the screen by accident, and the interaction feels like a native part of macOS. Unusually, LinkFlick moves the physical hardware rather than just the cursor. It re-pairs peripherals at the Bluetooth layer, so the destination Mac sees a real Magic device, not a bridged input stream. That native approach means there is no iCloud dependency, no network relay, and no limit imposed by a bridging layer. It also means no Apple ID is required: LinkFlick works between any two Macs on the same network, whether they are personal or work machines, and even when they are signed into completely different accounts. LinkFlick simply does not care which account each Mac uses. LinkFlick supports every Magic peripheral — Magic Keyboard, Magic Mouse, and Magic Trackpad — across both 1st and 2nd generation hardware, handling the hand-off so macOS does not have to. Support is intentionally limited to Apple's Magic peripherals, because those devices enter Bluetooth discovery mode automatically after unpairing. That behaviour is what allows LinkFlick to perform a silent re-pair on the other Mac without PIN codes or confirmation dialogs. Third-party devices such as Logitech or Razer are not supported. The menu bar interface also displays battery levels for your devices, and it nags you before your Magic Mouse battery dies. Under the hood, LinkFlick uses Bonjour to discover your Macs on the local subnet, so no cloud servers are involved and nothing is sent outside your home or office network. Both Macs must be on the same network — Wi-Fi and Ethernet both work — and LinkFlick must be running on each Mac you want to transfer devices between. The app runs as a lightweight menu bar extra and uses almost no resources when idle. It requires Bluetooth access to re-pair devices and Local Network access to discover other Macs via Bonjour; it does not need administrator privileges and does not read your keyboard input. Transfers typically take 5 to 15 seconds, depending on how quickly macOS processes the Bluetooth pairing request internally — by the time you turn to face the other screen, the device is usually ready. If the destination Mac is off or asleep, your devices simply stay connected to the current Mac, and as soon as the other Mac wakes and LinkFlick reconnects, it reappears in the Flick List ready for the next transfer. LinkFlick also senses your power and display status, so work starts the moment you plug in. When you connect power, LinkFlick wakes up and checks where your devices need to be. If your Magic Keyboard, Mouse, and Trackpad are still on another Mac, you get a gentle nudge that one tap resolves. The app then hands off each device silently in the background, with no pairing screens and no interruptions, so everything follows you. By the time you sit down and open your editor, your mouse is already where you left off. The outcome is that your workflow follows you between machines. Rather than stopping to reconnect hardware, you continue exactly where you left off, with your Magic devices simply present on whichever Mac you are using. Because switching happens in the background and takes only seconds, the interruption is minimal, and because the app sits in the menu bar with explicit controls, switching stays deliberate rather than accidental. There is also less battery anxiety, since device battery levels are visible and low battery warnings arrive before a mouse dies mid-task. Typical use cases include a personal MacBook paired with a work MacBook that use different Apple IDs, where Universal Control cannot help but LinkFlick can. Others use it to move a keyboard, mouse, and trackpad between a MacBook Pro and a Mac mini on the same desk, or between any two Macs on one local network. Power users with a full multi-Mac setup can connect up to five Macs under the Pro plan. The plug-in workflow suits people who dock or connect power and external displays when they sit down, since the devices follow automatically. And when the other Mac is asleep, devices remain usable on the current Mac until it returns. LinkFlick is available as a 14-day free trial with no credit card required, and pricing is a one-time purchase with free updates and no subscription. The Personal plan costs $14.99 and supports up to 3 Macs, which is described as perfect for working between a laptop and a desktop at home. The Pro plan costs $19.99 and supports up to 5 Macs for power users and full multi-Mac setups. Both plans include auto device discovery, instant switching, battery level display, trusted peers, and no cloud or account requirement. System requirements are macOS 14 Sonoma or later, with all Macs on the same local network. LinkFlick's core value proposition is simple: it removes the friction of sharing Magic peripherals between Macs. It does that natively at the Bluetooth layer, without iCloud, without an Apple ID, and without re-pairing, so switching Macs becomes a single click in the menu bar rather than a routine chore.
VoxelWall is a live wallpaper engine built natively for the Mac. It ships with 37 original scenes — among them Crystal Resonance, Spike Field, Infinite Tunnel, Storm Eye, City Descent, Liquid Starfold, Inner Echo, Ember Strata, Voxel City and Orbital Halo — that react in real time to whatever the Mac is playing. Rather than looping a recorded clip, VoxelWall analyzes the system audio on the machine and renders each scene live on the GPU using Metal. It follows Spotify, Apple Music, YouTube, browsers and local audio, and the same visual language is available in three states: Desktop, Lock Screen and Energy Saver. It is built for Mac users who want their screen to respond to the sound in the room instead of repeating a video. Most live wallpapers simply repeat a video. The motion loops, and the eye eventually learns the pattern. VoxelWall takes a different position, stated directly on its site: a wallpaper should do more than move — it should respond. Instead of playing back a fixed animation, VoxelWall reads rhythm, bass and space while the sound is still happening, so what appears on screen is derived from the audio being produced at that moment. That distinction matters because a wallpaper is something a Mac user looks past for hours at a time, and a scene that answers the music keeps that surface alive rather than turning it into a decorative loop. The company frames the product as one that listens to system audio rather than connecting to a music service. Every scene in VoxelWall is designed and built by the VoxelWall team, imagined, engineered and tuned inside the product — from its visual language to the way it responds to sound. The collection is grouped into named worlds, each with its own descriptive subtitle: City Descent is an architectural world, Spike Field a reactive lattice, Crystal Resonance a prismatic field, Storm Eye an electric vortex, Infinite Tunnel a spatial engine, Liquid Starfold a fluid system, Inner Echo a dream system, Ember Strata a terrain system, Voxel City a voxel system, and Orbital Halo a particle world. Because these worlds are original rather than licensed stock loops, the way each one moves and reacts can be authored alongside its look. VoxelWall currently offers 37 scenes, and the app describes future wallpaper releases as included with the lifetime license. VoxelWall presents one atmosphere in three states. Desktop is the mode for while you work: a living scene stays behind your windows, and VoxelWall reads the shape of your system audio and changes the visual in real time. Lock Screen carries the same visual language into the quiet moment before you unlock your Mac, and this system Lock Screen integration requires macOS 26 or later. Energy Saver is the mode for when you want less system work: VoxelWall switches to a silent prepared loop that keeps the same visual mood without live audio analysis. Having all three states means the same scene can follow a user from focused work to a locked machine to a low-effort ambient loop without changing the look of the desktop. Inside the app, VoxelWall is deliberately restrained: only the controls that matter — find a world, make it yours, and let VoxelWall stay quietly out of the way. Home provides daily control. The scenes you use are ready when you need them: return to recent scenes, build a daily rotation, and keep six quick-switch highlights close at hand. Library is where you browse the collection without leaving the atmosphere — search, filter and preview every installed world inside one focused, native Mac surface. Scene tuning lets you decide how each world listens and moves: choose a response character, adjust audio intensity and motion speed, or switch that scene to a silent Energy Saver loop. Together these three screens cover selection, management and per-scene behaviour. The engine itself works by listening locally. VoxelWall analyzes system audio on the Mac and renders each scene live with Metal through a native graphics pipeline — the product is explicit that the wallpaper is not a repeating video. Its stated audio route is local, with no raw audio upload, so the analysis happens on the machine rather than in the cloud. The same approach means VoxelWall does not need to be tied to a particular player: it works with Spotify, Apple Music, YouTube, browsers and local audio. The site's guides make the same point in practice — how to make a Mac desktop react to Apple Music using local system audio without connecting your Apple Account, library or playlists, and how to make a Mac wallpaper react to YouTube and YouTube Music through local system audio without a browser extension or account connection. Because the audio analysis is local and the rendering is a native Metal pipeline, VoxelWall positions itself as quiet in the system and loud on the screen. The Energy Saver state gives users a way to keep the visual mood of a scene when they would rather not spend system resources on live audio analysis, which addresses the most common hesitation about animated wallpapers. The license is a lifetime license that does not expire, sold as a one-time purchase rather than a subscription. That single purchase covers the one native engine, all 37 current scenes, and future wallpaper releases — so the collection a user starts with is not the collection they are limited to. Concrete uses follow from those modes. While working, a Desktop scene sits behind open windows and answers whatever is playing, so the desktop keeps moving with the music instead of going static. For music listening sessions, the guides describe using VoxelWall as an Apple Music visualizer or a YouTube visualizer on the Mac, driven by local system audio rather than an account connection. At the other end of the day, the same scene continues on the Lock Screen before unlock. When a user wants the atmosphere without the work, Energy Saver turns the live scene into a prepared silent loop. Audio-reactive visuals also proved interesting to the Mac community around the launch: commenters on the site described running a scene on a side monitor or an always-on Mac mini, and one suggested capturing the visuals with a screen recorder to create clips that could be shared online. VoxelWall is built as a Mac product. The minimum supported version is macOS 14.4, rendering runs on Metal through a native graphics pipeline, the audio route is local with no raw audio upload, and the license is lifetime. Pricing is a one-time purchase rather than a subscription, and the site directs buyers to a dedicated pricing page. On Product Hunt the product is listed under Mac, Music and Wallpaper, and it was launched with the tagline "music-reactive live wallpapers for Mac." VoxelWall's primary value proposition is straightforward: it turns the Mac desktop, Lock Screen and idle moments into a surface that answers the music already playing, using 37 original scenes rendered live on the GPU from locally analyzed system audio. For Mac users who want motion on their screen that is driven by sound rather than by a looping video, and who prefer a one-time purchase with a lifetime license, VoxelWall is the engine built for exactly that.
Take MySeasonColors' free 16-season color analysis quiz to find your natural palette in minutes. Upgrade to the full report for a complete color and makeup guide, wardrobe strategy, and AI-generated photos of your best look.
Devin Voice is a voice mode feature that allows you to talk naturally with Devin, Cognition's AI software engineer. It is designed for software developers and technical users who want to explore ideas, pressure-test approaches, and hand off work while away from their keyboard. Instead of typing, you can speak a task out loud, and Devin will plan, code, and deliver the work. The feature is accessed through the Devin web application, where you can start a voice call in Agent mode or within an existing session. This creates a hands-free way to interact with an AI software engineer, making it possible to continue development work even when you are not at your desk. The problem Devin Voice addresses is the friction of being tied to a keyboard when you need to delegate coding tasks or discuss technical ideas. Developers often have moments of inspiration or need to hand off work while away from their computer—whether commuting, walking, or simply taking a break. Typing is not always convenient or possible. Voice mode solves this by enabling natural spoken conversation with Devin. It matters because it removes the keyboard as a barrier to starting and managing development work. You can capture ideas as they come, verbally describe a task, and let Devin handle the implementation, all without sitting down to type. This makes the development process more fluid and accessible. One of the core features of Devin Voice is the ability to start a call easily. On the home page in Agent mode, or in an existing session, you click the voice call button beside the message box and allow microphone access. Any message you have already typed is sent when you start the call, so you do not lose your drafted context. This seamless transition from typing to talking ensures you can switch modes without interrupting your workflow. The voice call button is indicated by a waveform icon, and hovering over it shows the 'Start voice call' tooltip, making the entry point clear and discoverable. Once a call is active, you have several controls to manage the conversation. You can mute your microphone to pause your input, then unmute to speak again. If you are muted but need to say something quickly without toggling mute, you can hold the Space bar to talk, which is especially useful when you are not typing. You can also silence Devin, which turns off Devin's audio without muting your microphone, allowing you to continue speaking without hearing responses; clicking 'Unsilence Devin' restores the audio. To end the call, you simply click 'End voice call'. These controls give you fine-grained command over the voice interaction, making it adaptable to different situations. While a voice call is ongoing, you can navigate within Devin and the call stays connected. This means you can move between different views, check code, or review other parts of the application without ending the conversation. Your spoken conversation appears in the session history, so you can refer back to it later. The documentation also offers tips to make the most of voice mode. You are encouraged to interrupt Devin's work, ask questions, and clarify your thoughts as they occur. You can even interrupt Devin while it is talking, which keeps the conversation natural and dynamic. Additionally, if you have preferences for how Devin should speak—such as speaking faster or slower, or a particular communication style—you can simply ask, and Devin will adjust. The unique approach of Devin Voice lies in its integration with Devin's underlying AI capabilities. According to the product description, it is powered by GPT-Live for natural conversation, with Cognition's new SWE-2 coding model under the hood. This combination allows Devin to understand spoken tasks and translate them into planned, coded, and delivered work. The voice interface is not just a dictation tool; it is a full conversational interface with an AI software engineer that can act on your requests. This means you can speak a task and have Devin ship it, as the tagline says: 'You say it, Devin ships it.' The benefits for users are significant. You gain the ability to work hands-free, which is useful when you are away from your keyboard or occupied with other tasks. You can explore ideas and pressure-test approaches through natural conversation, which can be faster and more expressive than typing. Handing off work becomes as simple as speaking a task, and Devin takes care of the planning, coding, and delivery. The ability to interrupt and ask questions means you stay in control and can clarify details in real time. The session history provides a record of your conversations, and the speech preference adjustments let you customize the interaction to your liking. Overall, Devin Voice makes interacting with an AI software engineer more accessible and flexible. Concrete use cases for Devin Voice include exploring ideas when you are away from your desk, such as during a walk or commute. You can talk through a feature concept, and Devin can help refine it. Pressure-testing an approach is another scenario: you can verbally discuss trade-offs and edge cases, and Devin can respond with analysis or suggestions. Handing off work is a primary use case—speak a coding task out loud, and Devin will plan, code, and deliver it while you continue with other activities. You can also use voice mode to ask questions and clarify thoughts as they arise, interrupting Devin's work or speech to get immediate answers. Navigating within Devin during a call lets you review code or check other sessions without breaking the conversation. Finally, adjusting speech preferences allows you to tailor Devin's voice to your needs. Devin Voice is targeted at software developers, engineers, and technical teams who use Devin. It is particularly suited for those who want to hand off coding work or explore ideas while away from their keyboard. The feature is available within the Devin web application, and no additional integrations are mentioned in the documentation. The tech stack includes GPT-Live for conversation and SWE-2 for coding. Pricing and plan details are not specified in the provided content, but the product is part of the Devin platform, which can be tried at https://devin.ai. In summary, Devin Voice is a voice mode for Devin that lets you talk naturally with an AI software engineer to explore ideas, pressure-test approaches, and hand off work. With easy call initiation, flexible call controls, and the power of GPT-Live and SWE-2, it enables hands-free development and natural conversation. Whether you are away from your keyboard or simply prefer speaking over typing, Devin Voice makes it possible to ship work by speaking it out loud.

Spaces is a desktop app that gives a team one shared space per project, where the people on the team and their AI agents work side by side in the same place. Chats, files, and routines live in the space rather than in one person's private thread, so context survives from one day to the next and is visible to everyone who is in the space. It is aimed at teams that already pay for an AI model and want that model's work to end up somewhere shared instead of scattered across separate laptops. The app installs like any other desktop program, is free to start, and needs no account until you want to bring other people in. The problem Spaces is built around is described plainly on the site: five people, five private chat histories. Everyone on the team has their own AI thread and none of them can see each other's. The project's context is scattered across browser tabs on separate laptops, so every new question starts by re-explaining the job. The result, in the site's own words, is that each person gets faster while the team does not. That is the gap Spaces targets. Individual AI assistants are useful, but the reasoning, drafts, decisions, and files they produce tend to stay inside a single person's chat. By making the project — not the person — the thing that holds context, Spaces lets the standing knowledge of a project accumulate in one shared location instead of being rebuilt from scratch each time someone asks a question. The core of the product is the shared space itself: one project, one conversation. Chats and files live in the space, not in one person's thread, so a decision made on Monday is still there on Thursday for everyone. The site shows a Product Launch space as an example, managed by a Launch Lead, with a Copywriter and a Researcher also working in it. Its chat list includes "Press list for launch week" with the Launch Lead, "Waitlist copy" with the Launch Lead, and "Battery claims vs launch brief" with the Researcher, each showing when it was worked on. Alongside Chats, the space carries Files, so the documents a project depends on sit next to the conversations about them rather than in someone's downloads folder. Specialists are how Spaces replaces a single general assistant with a small team of agents. The site's instruction is to hire agents, not one assistant: a researcher, a copywriter, a launch lead. Each agent keeps its own notes, and anyone in the space can put any of them to work. Each specialist gets its own instructions, memory, and tools, which is what allows it to research, draft, work through your inbox, or run a report. In the interface, agents are added and managed from an Agents panel that distinguishes Agents, Skills, and Tools, and the space lists who is in it under a line such as "Managed by Launch Lead · Also Copywriter · Researcher." The practical effect is that a task goes to the specialist suited to it, and the specialist's own accumulated context stays attached to that agent rather than being lost between sessions. Routines are the part of Spaces that keeps working when nobody is watching. A routine is described as something that runs on a schedule — check-ins, follow-ups, reminders — and the space shows them in a Routines panel with their state and timing. The example space lists three routines: a "Launch morning brief" that runs daily at 9:00 AM, a "Friday recap" that runs Fridays at 4:00 PM, and a "Waitlist follow-up" that is currently paused. Each entry shows when it will next run or when it last ran. The point of routines, as the site frames it, is that the space does the standing work and pings someone only when it needs a decision, so recurring project chores like morning briefs, follow-ups, and weekly recaps stop depending on someone remembering to ask. Spaces does not sell AI usage. You connect the ChatGPT, Claude, or Gemini account you already pay for, and Spaces becomes the place those models do the work — you are buying the space, not another subscription for tokens. The Providers panel shows Anthropic's Claude and OpenAI's ChatGPT as connected, with Google's Gemini through Google AI Studio available to add, and Ollama available to run a model on the computer itself. Keys stay on the machine, and you can switch provider per agent at any time, so one specialist can run on one model and another on a different one. The site is explicit that Spaces is not a reseller: the AI account belongs to the user, and the app is the workspace that account operates in. The architecture is deliberately split between the local machine and the cloud. Each person's agents, API keys, and connected accounts stay on their own computer and never go to the cloud. What the cloud carries for a shared space is the space itself — the chats, files, and routines — and nothing else. Shared-space content is encrypted at rest with a per-space key held in Google Cloud KMS, and only members of the space receive that key. Anyone who uses Spaces alone can keep everything on their own machine, because a cloud space is only needed when other people have to work in the same project. The built-in browser lets agents use the real web rather than a cached or limited view of it. They can research, click through pages, and stay signed in, and because the browser lives inside the app, the agent sees the page the user sees. The site illustrates this with a research example: a Launch brief and a Supplier spec at example.com/solar-backpack, with the space's Files containing "Solar backpack — claims" listing a 65W peak panel, a 20,000 mAh pack, and a weatherproof shell, alongside an instruction not to claim the product "charges a laptop in an hour." The scenario shows an agent reading a live supplier page and checking its claims against the brief and the files already in the space. A space starts as yours. Inviting someone turns it into a shared space that both people work in: the same chats, the same files, the same routines, with their agents alongside yours. The site defines a cloud space as a project space that lives in the cloud instead of only on your machine, so other people can work in it — and notes that you do not need one to use Spaces by yourself. Pricing is split across three options. Spaces itself is free: the full desktop app, unlimited spaces on your computer, specialists, routines, and playbooks, and your own AI keys with no account needed. Spaces Cloud is the paid tier for teams, priced at $10.99 per year per person, described as $0.92 a month and, in the FAQ, as $1.49 a month, and it adds spaces that live in the cloud plus shared chats, files, and routines, and the ability to invite anyone who has a seat, while keys and agents stay local. Enterprise is a conversation rather than a checkout: Spaces inside your own cloud, data that never leaves it, and help with the whole setup. Everyone who works in a shared space needs their own seat, because each person runs their own agents, so a team of five is $55 a year in total; anyone who only works alone stays free, and cancelling leaves the desktop app free on your own computer. Getting started follows three steps the site lays out. First, download Spaces — it is free and no account is needed, and it installs like any other desktop app. Second, connect your AI by pasting the ChatGPT, Claude, or Gemini key you already have; one provider is enough to begin. Third, open a space: name the project, put a specialist to work, and the space starts holding the context. Spaces runs as a desktop app on Apple silicon Macs and Windows PCs. The examples on the site point to a few concrete ways teams use it. A product launch is run from a single Product Launch space, where a Launch Lead, Copywriter, and Researcher share a press list, waitlist copy, and checks of battery claims against the launch brief. Research work happens in the built-in browser, with agents reading live pages such as a supplier spec and comparing them against files in the space. Routine work is scheduled rather than requested: a morning brief at 9:00 AM, a Friday recap at 4:00 PM, and a waitlist follow-up that can be paused and resumed. Teams that need everything inside their own infrastructure can run Spaces inside their own cloud through the enterprise option. Taken together, Spaces is a place where a project's chats, files, and scheduled work live together, and where each person's AI agents contribute into that shared context instead of into private threads. It keeps the AI accounts and keys people already pay for, keeps their agents on their own machines, and charges only for bringing other people into the same space. The value proposition is simple: the team, not just the individual, gets to benefit from the AI work being done.
EasySpecs is a Spec Engineering Assistant and spec review platform built for teams practicing Spec-Driven Development. It documents undocumented codebases and turns them into trustworthy specifications, grounds AI agents in reality, and lets teams create Trust by Design Specs before code is written rather than after bugs pile up. The product is aimed at product owners, developers, technical product managers, and organization leaders who need product and engineering to share the same source of truth about an application. Its stated purpose is to close the gap between teams shipping at 1.5x and teams shipping at 100x — a gap EasySpecs describes as trust rather than speed. AI is accelerating how fast software changes. As EasySpecs frames it, AI agents generate code 100x faster than humans write it, but a team cannot review it all. The result is familiar to engineering leads and CTOs: “Agents generate faster than my team can review. We're drowning in AI PRs.” Developers describe the other side of the same problem: “I babysit the agent the whole run. If I look away, things go wrong.” Spec Driven Development is presented as the new standard, and with it come new consequences — a need for a tool for quality specs, new spec management requirements, documentation that lags, shared context that goes stale, overlap between product and engineering with no place to align together, and surging merge requests that create code review bottlenecks. EasySpecs positions itself as the response to each of those consequences. Step one of the EasySpecs workflow is understanding the code. EasySpecs produces functional documentation of your project with up to 98% LOC coverage assignment. That documentation is described as the first stone of Trust Engineering and as a foundation: functional documentation of the real system, so every later Spec starts from how the app actually behaves rather than from a guess. The stated benefit is that change requests start aware of real behavior and user intent, which lets teams make informed decisions instead of building on assumptions. Because the documentation reflects the actual application rather than someone's memory of it, it gives the rest of the workflow something concrete to build on — the factual baseline that intent and Specs are later grounded against. Without that baseline, every downstream step would inherit the same uncertainty the documentation exists to remove. Step two is polishing the intent and grounding it to the current codebase. When intent is fuzzy, EasySpecs helps you craft, clarify, and ground it to the current codebase before agents generate code, so that Spec-Driven Development has something trustworthy to drive. Intent is described as the ask behind the change — captured and grounded in how the app actually works, so product and engineering share one picture before Specs are written. The product surfaces this through a Specs accordion that shows Change, Intent, Diagram, and Spec steps. For technical product managers, the outcome is specs that developers can ship against, ready the moment engineering picks them up and integrated with Jira. This step matters because fuzzy stories burn engineering time: when the ask behind a change is unclear or divorced from the real system, developers end up interpreting rather than building. Step three is creating Trust by Design Specs. Once intent is clear, EasySpecs creates Trust by Design Specs with structured views and HTML-rendered views, so the change is visible and checkable before you write the code. Every Spec is sided by a Trust Spec. The Spec is the Spec-Driven Development Spec — what to build — presented in structured and HTML views the team can actually read. The Trust Spec holds validators, evals, and checks that sit beside the Spec, so you know how you will trust the change before agents generate code. The Product Hunt description also refers to reviewing specs including Oracles and Rubrics, and to developers working from Specs and Spec of Trust validators. The underlying principle is Trust by Design: define how you will trust the code before you write it, not after bugs pile up — and the sooner you set that bar, the less cost and fewer problems you carry. EasySpecs works in three steps and frames the whole loop as Trust Engineering: understand the code, polish the intent and ground it to the current codebase, then create Trust by Design Specs — before you ship, not after bugs pile up. Around that loop, EasySpecs acts as spec-driven change management. A dashboard shows change requests and linked Spec status across projects, so every change request and its Spec can be tracked. Documentation auto-syncs, addressing the problem of docs that lag and shared context that goes stale. EasySpecs also presents itself as one Spec-Driven operating system for tech and product, introducing Spec-Driven Development across a team so product and engineering share the same source of truth. The stated aim is that the gap between teams operating at 1.5x and teams operating at 100x is not speed but trust, and that grounding agents in reality lets you scale agentic development without babysitting, documenting the foundation once. EasySpecs states a set of outcomes tied to each consequence of faster shipping. Where a tool for quality specs is needed, EasySpecs creates quality specs easily. Where shipping faster demands new spec management, EasySpecs provides spec-driven change management. Where docs lag and shared context goes stale, EasySpecs auto-syncs documentation. Where product and engineering overlap with no place to align, EasySpecs offers one place to align together. Where merge requests surge and code review bottlenecks form, Trust Engineering eases merge requests, making spec review the new merge request review. For developers, the promise is concrete: stop babysitting the agent, and start generation from clear intent and checks rather than vibes. For product owners, change requests can be grounded in the real app and shaped into Trust by Design Specs the team can actually see. One testimonial sums it up: “My team finally speaks the same language about specs. The pace of change was so fast we could not align. Now with EasySpecs, all clear.” Concrete scenarios appear throughout the content. A team working with an undocumented codebase can have EasySpecs produce functional documentation first, so change requests start aware of real behavior. A developer struggling with AI-generated pull requests can move review upstream to Specs and Spec of Trust validators instead of reviewing an endless stream of code. A technical product manager can write a spec against the system that developers can ship against, ready the moment engineering picks it up through Jira. A product owner can ground a change request in the real application, polish the intent behind it, and shape Trust by Design Specs the team can see. An organization leader can introduce Spec-Driven Development across a team so product and engineering work from the same source of truth, with a dashboard tracking every change request and its linked Spec across projects. And a developer working in an editor can stay inside VS Code, Cursor, Antigravity, or any VS Code-compatible IDE while the workflow runs. EasySpecs is built for product owners and developers — two sides of the same Trust by Design loop — and also speaks directly to technical product managers and organization leaders. The workflow is integrated with Jira and Linear, and with VS Code, Cursor, Antigravity, and any VS Code-compatible IDE on the development side. The product is listed on Product Hunt under SaaS, Developer Tools, and Development, and the site includes a section on agentic coding noting Loop Engineering, Graph Engineering, Context Management, and more. No pricing or plan details are stated in the available content. EasySpecs positions Trust Engineering at the center of AI-accelerated software delivery: document the real system once, polish intent against that reality, then define how you will trust the change before agents generate code. By turning Specs — including their validators, evals, checks, and the review of Oracles and Rubrics — into something reviewable, it reframes spec review as the new merge request review and gives product and engineering one shared source of truth. The takeaway is straightforward: the gap between 1.5x and 100x is not speed, it is trust, and EasySpecs is built to supply it.
Loqua is context-aware voice typing and dictation software built for Mac and Windows. It converts natural speech into polished, ready-to-use writing, understands what is on your screen, offers read-aloud when you would rather listen than read, and lets you trigger everyday actions by voice. Its stated purpose is to help people move from thoughts to being done — less typing, less context switching, and more time in flow. Loqua is aimed at anyone who would rather think than type: professionals who write all day, developers and engineers, product managers, designers, marketers, founders, writers, researchers and students. The keyboard has long been the bottleneck between having an idea and getting it written down. Traditional keyboard typing runs at roughly 45 words per minute, while Loqua's dictation runs at 220 words per minute — a difference the company presents as saving up to 3 hours per day. Raw speech, however, is rarely usable as written text: it is full of filler words, repetition and half-finished sentences. Loqua removes filler words, cuts repetition and refines phrasing in real time so that what lands on screen is ready to send. A second problem Loqua targets is context switching: stopping work to open another app, look something up, translate it or rewrite it breaks concentration. Loqua aims to keep people inside the app they are already working in. The core of Loqua is dictation with real-time cleanup. When you speak, Loqua strips out filler words, trims repetition and refines your phrasing, so the sentence that appears on screen reads as if it had been carefully written rather than spoken. This happens in real time, which means you do not have to go back and re-read everything you just said. Loqua also recognises structure in speech and builds it automatically: if you think in bullets but speak in blocks, Loqua derives lists, headings and hierarchy on its own, so you do not have to dictate formatting out loud. For anyone who writes long documents, meeting notes or structured updates, this removes the tedious formatting pass that normally follows dictation. Capture to Ask addresses the moments when the answer is on your screen but you cannot figure it out. Using a shortcut, you select any part of the screen — a table, a chart or anything else — then speak your question. Loqua returns an answer, an analysis, a translation or a summary without you having to switch apps. It is a three-step flow the company describes as Capture, Ask, Know. Related to this is Ask and Edit: highlight anything, whether it is a product description, a draft or a note, speak your instruction, and Loqua rewrites it on the spot. There is also a simpler ask-anything path — hit a shortcut, ask a question out loud, and get an instant answer without leaving your current app, which is useful when you are stuck mid-task. Translation lets you speak in your own language and deliver in someone else's, with native phrasing in nearly 100 languages, returned instantly. That makes it practical for international teams, multilingual correspondence and anyone writing in a second language. Command to Go turns your voice into a hands-free command hub: with a shortcut you can set reminders, open apps, search routes, place calls and send texts, so you can manage small tasks without jumping between applications. AI Podcast read-aloud works in the opposite direction — select text and Loqua reads it aloud, which the company suggests for morning news and multitasking, effectively giving you a hands-free text-to-speech assistant. Loqua's approach is to sit globally on top of your existing workflow rather than replace it. You invoke it with one shortcut in any text field, so it works in tools like Terminal, Slack, Notion, email, Google Docs, Microsoft Word, VS Code, Teams, Figma, Obsidian, GitHub and many more, with your voice landing right where your cursor is. The company describes the experience as no switching and no waiting, with a zero-latency feel that makes the tool easy to forget about. Loqua is built by a dedicated voice AI team with full model iteration capabilities, and the roadmap includes meeting transcription, multimodal capabilities and a Skill Market. Users report that Loqua adapts tone automatically — shifting register between, for example, a message to a CEO and a Slack message to a team — by understanding the context it is typing into. The benefits the company and its users describe are time and flow. Because dictation runs at 220 words per minute rather than 45, and because cleanup and formatting happen automatically, people report writing that used to take an hour finishing in minutes — one user summarises 30-minute writing sessions becoming 5-minute speaking sessions, and another says PRDs written by voice save at least an hour a day. Beyond speed, Loqua reduces the proofreading burden: users report they have stopped going back to check output, even when dictating framework names, library names and acronyms. For people with repetitive strain injury, Loqua is described as making work possible again rather than merely faster. Non-native English speakers say it makes their writing sound native, and international users say translation is instant and natural. Concrete use cases appear throughout the site. Product managers write PRDs, standup notes, sprint recaps and stakeholder updates by speaking. Engineers dictate coding notes, documentation and terminal input, and use it in Slack, Notion and their IDE. Designers keep their hands on Figma and narrate case studies and design processes. Content strategists and marketers draft LinkedIn posts, email campaigns, blog outlines and ad copy by voice and then polish from there. Founders and executives who context-switch all day speak thoughts into whatever app is open, and heavy email users cut correspondence time. Consultants talk through client debriefs to get clean summaries, UX researchers dictate research notes between interviews, and PhD candidates use the cleanup and formatting for academic writing. Sales teams use translation to send emails in a different language from the one they speak. Loqua runs on Mac and Windows as a desktop application you download from the site, with a 14-day free trial. It advertises support for a very broad set of applications — among them Google Docs, Word, Notion, Slack, Gmail, Figma, VS Code, Teams, Obsidian, Google Sheets, Zoom, Excel, GitHub, Terminal, Discord, Outlook, IntelliJ IDEA, PowerPoint, GitLab, WhatsApp, Telegram, Stack Overflow, OneNote, Canva, Photoshop, LinkedIn, Google Slides, X, Sketch, Reddit, Illustrator, Confluence, Evernote, Facebook, Adobe XD and Google Keep. There is also a developer programme: maintainers of public open-source projects can apply for a Developer Grant giving free access. The site states that thousands of professionals use Loqua every day. Loqua's core promise is that your thoughts should not have to slow down for a keyboard. By combining high-speed context-aware dictation, automatic cleanup and structure, screen understanding, translation, voice editing and voice-triggered actions in one shortcut-driven tool, it turns rough ideas into ready-to-use writing and keeps work moving inside the apps you already use.
GLYPH Immersive is a free, browser-based tool for modular grid lettering. It lets you draw rounded-pixel letterforms and shapes on an adjustable grid, with dedicated controls for spacing, corners, and edges, and it runs in the browser with no signup required. The board supports grid-based drawing more broadly: you paint cells to build letterforms and shapes, insert a photo and save it as a soft reference overlay or as editable dot-grid art, and download the result in several formats. The site describes it as "a simple space that balances possibility with constraint, encouraging experimentation, play, and reflection about the systems that we inherit - no matter how basic they may seem." The tool's own guide places it in a long lineage of grid thinking. Long before the digital pixel, the site notes, humans used math to create precise guides for art, architecture, and the page; weaving, tiling, and writing were the foundation for humankind's earliest grids. Andean weavers encoded modular symbols across bands of textiles, Ibn Muqla proportioned Arabic script using rhombic dots, kolam artists built patterns across fields of points, and Hangul assembled circles, squares, and lines into 1:1 blocks. Later, the Bauhaus stripped design to those same elementary parts, with Anni Albers crediting Andean weavers as her teachers. The early digital age relied on the same foundation, using pixels to create efficient symbols on tiny screens, and that era inspired novel approaches to the grid such as Wim Crouwel's New Alphabet, Gego's Reticulareas, Lance Wyman's Huichol-inspired Mexico 68, and Cordeiro's computer art. Cordeiro, the site explains, was optimistic about electronic art, or arteonica, believing that computation belonged to artists. GLYPH Immersive sits in that tradition: a simple space that balances possibility with constraint, at a time when technology has continued to present new possibilities while at times numbing life's necessary friction - the constraints and discomfort that produce great art and ideas. Drawing happens directly on the board. You click or drag to paint, and Shift+click fills a line between two cells. Clicking through a cell cycles its joints: the first click fills and joins a cell, the second click removes joints, and the third click resets it. The board can be rendered as Grid, Dots, or Vertex, which changes how the underlying system of cells, points, and connections is displayed while you work. Corners and Edges settings shape how the letterforms and shapes resolve, and a Detail/Invert option is available for reviewing the artwork. A Preview Type control and a Clear board action sit alongside these tools, so a design can be checked and reset without leaving the page. Two menus organize the work. The control menu adjusts the artwork itself, while the guide menu controls the artboard. Width, Height, and Spacing controls determine the size of the grid and how much room sits between forms, and guides can be added to the board. The Type (beta) panel inside the guide menu exposes Font name, Columns with Gutter, and Rows with Gutter settings. Color, accessed in the guide menu, cycles fill and background modes. Wander plays a calm loop of designs, useful for watching a system unfold rather than drawing it by hand. Navigation is done by scrolling or two-finger dragging to pan, and by pinching or using the Zoom slider to zoom; the zoom level is shown as a percentage. The guide menu also presents the grid, dot, and vertex views along with Sound and a Language option shown as EN and ES. Reference imagery is a first-class part of the workflow. You insert a photo, place it on the board, and then choose to Save as reference, which lays it down as a soft overlay beneath your drawing, or Save as dots, which turns it into an editable grid artwork made of cells. A Cancel option lets you back out before committing. Once a design is finished, Download offers SVG, PNG, JPG, ASCII MAP, and TYPE formats, with TYPE available when Create type is switched on. That combination means the output can be a vector file, a raster image, a text-based map, or an installable font, depending on what the project needs. GLYPH includes a Type tool for building a font from scratch. The site calls it "a simple way to create your own font." When Create type is on, each labeled green box on the board represents one character, covering A-Z, digits, and punctuation. You adjust the guides to change width, height, and spacing, then paint inside the boxes to design each letter. When the glyphs are ready, downloading TYPE exports a basic OTF file that you can install and try out in other software. The overall approach is deliberately minimal. One menu controls the artwork, the other controls the artboard, so the settings that define the system stay separate from the marks you make inside it. Grid, Dots, and Vertex views let you look at the same construction through different lenses, while Color and Sound settings sit in the guide menu together with the grid and guide controls. Free export, no signup, and browser-only operation keep the barrier to entry at zero, and GLYPH Immersive is published as an open source resource by Kate Ander. Because it is free, requires no signup, and runs in the browser, GLYPH Immersive removes the usual setup friction from grid drawing and type design - there is no account, no install, and no export paywall. The constraint of the grid, paired with adjustable spacing, corners, and edges, keeps outcomes coherent while leaving room to experiment, which is exactly the balance the project sets out to hold. The export options mean the work is not trapped in the tool: vector and raster files can move into other design software, ASCII MAP offers a text-based representation, and TYPE produces a font that can be installed and tried. Concrete uses described on the site include drawing rounded-pixel letterforms and shapes on the grid, designing a full set of characters in the Type tool and exporting an OTF font to install and try, turning a photograph into editable dot grid art with Save as dots, and laying a photo down as a soft reference overlay to paint against. Wander mode supports a different, more passive use by letting a calm loop of designs play. The Clear board action, the guides, and the grid, dot, and vertex views make it practical to iterate through many variations of a single system. GLYPH Immersive is aimed at anyone working with letterforms, grids, and modular systems - designers and typographers building type and grid art, artists experimenting with pixel and dot constructions, and educators or students exploring grid systems and their history. The tool is web-based and free, with no signup required, and it is released as an open source resource. The site also offers occasional email updates about GLYPH and new work from Kate Ander, and questions, ideas, and bugs can be sent to glyph@kateander.com. GLYPH Immersive is a free, open source, browser-based space for modular grid lettering and grid art. It pairs a simple adjustable grid with corners, edges, spacing, reference-photo tools, and free export to SVG, PNG, JPG, ASCII MAP, or OTF - inviting experimentation and play with the systems we inherit.
Raycast 2.0 is the next generation of Raycast, described by its creators as a new foundation, redesigned from the inside out. It is a launcher for macOS that acts as your shortcut to everything, and this release adds AI that can take action across your apps, Automations for recurring tasks, and Projects to keep ongoing work together. It is built for Mac users who want to move quickly across their desktop, combining a command launcher, file search, dictation, and an AI chat experience in one place. Raycast 2.0 is available to download now, and it requires macOS Tahoe and Apple Silicon. The update exists because Raycast chose to rebuild its launcher on a new foundation rather than continue patching the previous one. Raycast V1 was already described as the best Launcher, so the bar for 2.0 was high: the goal was to keep what people relied on while modernizing the interface, the hotkey handling, and the AI experience. That scope comes with trade-offs the team states openly. Raycast calls this a major update and tells users to expect frequent updates and occasional rough edges. On installation, the new Raycast will replace Raycast V1; there are just a handful of missing features, and those will be added soon. The most concrete risk of any rebuild is losing a carefully tuned setup, so 2.0 is designed to bring your configuration with you instead of asking you to start over from scratch. The core of the new release is a reworked AI experience built around two surfaces. Quick AI keeps you in the same Tab while adding more power, so you do not have to leave what you are doing to get an answer. AI Chat collects skills, agents, and memory in one place, giving AI work a persistent home inside the launcher rather than a one-off query box. Beyond answering questions, the AI in Raycast 2.0 can take action across your apps, which means the assistant is not limited to conversation alone. You can also connect your own ChatGPT or Claude account and put AI to work alongside the commands and extensions you use every day. Connecting your own account lets the AI you already use become part of the same surface as your launcher commands and extensions. Several changes target the everyday speed of the launcher itself. File Search now sits in Root, described as one less step to find your files, so files are reachable from the top level of your search instead of requiring extra navigation. File search is also faster in v2, and the FAQ lists quicklinks and snippets tagging among the additions in this release. Because root search is where queries begin, moving File Search there shortens the path between thinking of a file and opening it. Quicklinks and snippet tagging build on the same idea: your own shortcuts, snippets, and saved searches stay close at hand rather than buried inside menus, which matters for people who run the same workflows dozens of times a day. The look and feel of Raycast has been updated to feel right at home on macOS Tahoe, giving the v2 interface a refreshed appearance. The release also adds built-in dictation under the banner Type with your voice, so text can be entered by speaking without leaving the launcher. Settings have been reorganized, making the growing set of options easier to navigate as the product adds capabilities. In addition, you can configure inline, meaning hotkeys and aliases can be assigned directly from root search. That combination matters because a launcher is only fast when it is configured the way you actually work, and v2 places configuration and voice input on the same surface as search. Raycast 2.0 also treats the upgrade itself as a migration rather than a fresh start. During onboarding you are prompted to import or migrate your data from Raycast v1, and if you skip the step or want to rerun it later, you can use the documented commands. The Migrate from Raycast v1 command automatically migrates your data, and importing settings at this step also imports and migrates all of your shortcuts to Raycast v2 and disables them from working in Raycast v1, ensuring that your hotkeys do not conflict. Raycast calls this the recommended approach because some extra data is not imported with the manual route, including Clipboard History, Wrapped, and the Emoji picker. The alternative, Import Settings and Data, is a manual import from a .rayconfig file that you must export from Raycast v1. For people who build their own tools, custom extensions also need attention: to import correctly you must be on the latest version of Raycast V1, or at least v1.104.16, and if they did not import automatically you can run npx @raycast/api@latest dev, which is designed to pick up the new version if it is running. The benefits of Raycast 2.0 come from combining a faster launcher with AI that can act. Files are reachable in fewer steps, AI answers arrive in the same Tab through Quick AI, and longer AI work has a dedicated place in AI Chat with skills, agents, and memory. Built-in dictation offers a different way to input text when typing is slower than speaking. Because hotkeys and aliases can be assigned from root search and your existing shortcuts migrate from v1, the muscle memory you have already built keeps working in the new version. The result is a launcher that feels familiar on day one while offering more capability than before, which is exactly the balance the team set out to strike with a major rebuild. In practice, that shows up in concrete workflows. You can type a file name and open the result directly from root search instead of navigating to a separate file search view. You can ask Quick AI a question in the same Tab while staying in the flow of your current task, or move into AI Chat when a task needs skills, agents, and memory to be sustained over time. Ongoing work can be kept together in Projects, while Automations handle recurring tasks so they do not have to be triggered by hand. When writing is faster by voice, built-in dictation takes over, and when you want a command at your fingertips you can assign a hotkey or alias to it straight from root search. Upgrading is itself a workflow: import during onboarding, or run the migration commands afterwards. Raycast 2.0 is aimed at Mac users, and specifically at anyone running macOS Tahoe on Apple Silicon, since those are the stated minimum requirements. People already using Raycast V1 are the primary audience for the upgrade, and that includes extension developers, who need to be on Raycast V1 v1.104.16 or later for custom extensions to import correctly, or run the Raycast API dev command if they did not. Alongside the free download, Raycast offers Pro, Teams, and Enterprise plans, with pricing published on the Raycast site, plus an iOS app, a Windows page, and a browser extension in the wider Raycast family of products. AI in v2 can be used with your own ChatGPT or Claude account, letting you bring an existing AI subscription into the launcher. Taken together, Raycast 2.0 is a rebuild of a launcher that many Mac users already depend on, and the site sums it up directly: the launcher, relaunched. A new foundation, redesigned from the inside out, with AI that can take action across your apps, Automations for recurring tasks, Projects that keep ongoing work together, AI Chat with skills, agents, and memory, built-in dictation, faster file search in root, and a migration path that carries your settings, shortcuts, and extensions forward. The value proposition is the combination: more capability in the same fast surface you already know, without asking you to rebuild your setup from zero.

Cadenya is a hosted agent runtime that layers tools, agents, and objectives on top of the APIs you already run. It is explicitly not a framework you bolt into your application stack; instead, Cadenya runs the agentic loop for you. You connect your MCP servers, OpenAPI specs, and existing endpoints through a single tool layer that agents can use, then define an agent, shape its abilities, and run objectives against it. The product is positioned for developers and teams who want to bring agentic possibilities to life in software they already operate, testing safely and improving quickly without rebuilding the stack that supports them. The problem Cadenya addresses is the cost of adopting agentic capabilities inside a system that already works. Building agents typically means invasive change: framework glue inside the application, wrapper layers around APIs, and hand-built machinery for streaming, approvals, retries, context limits, and visibility into what an agent actually did. Cadenya's answer is a hosted loop that handles those concerns out of the box. The product states that it handles context compaction, tool approvals, webhooks and SSE streaming, embeddable widgets, and SDKs in four languages. A frequently asked question on the site answers directly that you do not need to rewrite your APIs: connect MCP servers, OpenAPI specs, and existing endpoints through a single tool layer, and agents can use them as they are. That preserves existing infrastructure investment while new agentic behaviour is layered on top, which matters because teams can iterate on agent behaviour without destabilising the services their business already depends on. The first layer is the tool layer, and the product's guidance is to start with your stack. You connect MCP servers, OpenAPI specs, and existing endpoints through a single tool layer agents can use. Because connection is based on specifications developers already know, existing services become available to agents as they are. Tools can be assigned to an agent individually, organised as tool sets, and combined with sub-agents. In the interface example shown on the site, a shipment-exceptions agent carries assignments such as a reroute shipment tool, an update ETA tool, a Dispatch API tool set, and a Customs Broker sub-agent, alongside memory layers such as a Carrier Playbook covering SLA policies. This layer is what lets an agent reach into real systems rather than only producing text. Experimentation is handled through variations. The interface shows a Default variation and Canary variations, each tied to a specific model, such as Anthropic Claude Sonnet as the default and OpenAI GPT-5.5 or GPT-5.2 as canaries, with a creation timestamp. A variation also carries its own system prompt, its own assignments, and its own memory layers. The product's stated goal for this area is to let you iterate without uprooting: swap models, evolve behaviours, and expand capabilities while retaining infrastructure. It also frames the runtime as a way to evolve with what is next, so you can adopt frontier models fast, test behaviours and compare approaches, and add functionality rather than complexity. Practically, that means model and behaviour changes are configuration inside the runtime rather than a rewrite of the surrounding application. Cost and context are managed through the token usage layer. Cadenya provides live token metering so teams can stay on top of costs, and describes reducing waste through progressive discovery, with efficiency improving as agents adapt. Progressive tool discovery can be enabled, with a maximum number of tools per search set between 1 and 10 (5 shown in the example), search hints of up to 5 terms, and a rerank threshold between 0.0 and 10 that can be left blank to skip reranking. The mechanism is described precisely: tool schemas stay out of the context window until the agent asks for them, and only names ride along, so every request gets smaller. That matters for agents with many connected tools, where schema bloat would otherwise consume context and budget before the agent does any work. Cadenya is also built to power real-time services. Webhooks and SSE push live updates, and the product states it makes it easy to wire agent events into your applications. The webhook delivery view on the site lists event types including assistant message, tool_result, tool_approval_requested, sub_agent_spawned, context_window_compacted, and timed_out, each with an HTTP status and target URL. Around this, the product provides tool approvals: approval-gated tools pause the agent and deliver a tool_approval_requested event so a person or system can approve before anything runs. It also ships embeddable widgets, described as a feature called Widgets that can be dropped into any frontend to enable agentic features like conversations and, per the product, so much more. Observation closes the loop. Cadenya is designed to let you monitor outcomes and understand how behaviours take shape in the real world, with the stated goal that clear visibility means your agents show their worth. Every objective keeps its trail: tool calls, webhook deliveries, token usage, and the feedback people leave on the outcome. The feedback view shows comments scored by sentiment, attributed to a variation and an objective, such as a reroute completed before an SLA breach, a customs hold caught with a proactive ETA update, a reroute that notified the recipient twice, a hold that occurred when a reroute was available, and a correctly escalated frozen-goods lane. Those scored outcomes are what make comparison between variations meaningful. Overall the product works as a hosted agentic loop in three steps: define an agent, shape abilities, and run objectives. Inference is model-agnostic. You point Cadenya at OpenRouter or any OpenAI-compatible endpoint and it uses that for inference. Each new account comes with $5 in credits on OpenRouter pre-configured; after that you provide your own LLM provider credentials. Agents can dispatch sub-agents, and the model configuration for sub-agents can be changed to be best suited for the job, which the product describes as giving the most efficient token usage and outcome. The runtime itself is described as unified: you add functionality, not complexity. The benefits follow from that design. Because the loop is hosted rather than embedded, teams can experiment safely and improve quickly. Because APIs are not rewritten, capabilities expand while infrastructure is retained. Because variations, memory layers, and assignments sit in configuration, frontier models can be adopted fast and behaviours compared rather than guessed at. Because events flow through webhooks and SSE, downstream services react immediately instead of polling. Because token metering and progressive tool discovery are built in, spend is visible and requests stay smaller. And because every objective keeps a trail of tool calls, webhook deliveries, token usage, and human feedback, improvement is grounded in recorded outcomes rather than impressions. Concrete scenarios appear throughout the product's own material. The site's worked example is a freight and logistics agent named for Meridian, a shipment-exceptions agent instructed to reroute a stalled delivery via a dispatch API, with assignments covering rerouting, ETA updates, a Dispatch API tool set, and a Customs Broker sub-agent, and memory layers holding a Carrier Playbook and SLA policies. Feedback entries describe rerouting before an SLA breach, catching a customs hold and updating the ETA proactively, and escalating a frozen-goods lane. Other described workflows include dropping Widgets into a frontend for conversations, pushing agent events into applications via webhooks and SSE so downstream services react immediately, gating tool calls behind approvals, and dispatching sub-agents for parts of a job. On integrations, Cadenya connects MCP servers, OpenAPI specs, and existing endpoints through a single tool layer, uses OpenRouter or any OpenAI-compatible endpoint for inference, and delivers webhooks and SSE streams to endpoints you provide. It ships SDKs in four languages and embeddable widgets for frontends. The site notes that each new account includes $5 in credits on OpenRouter pre-configured, after which you supply your own LLM provider credentials, and states that you can email support@cadenya.com to get a free month. Getting started is described as a few steps, the first of which is signing up, with sign-up available at app.cadenya.com and API documentation linked from the site. Cadenya's core promise is that you can bring agentic possibilities to life on the stack you already run. It converts agent development from a rebuild project into a hosted runtime you configure, connect, observe, and improve, with the surrounding concerns of context, approvals, streaming, cost, and feedback handled as part of the loop.

Moji is a desktop application that opens Markdown files the way you would open a PDF. The project describes itself simply: double-click a Markdown file and start reading. Moji displays your document with clear typography, tables and diagrams, and keeps editing and export ready for when you need them. It runs on Windows, macOS and Linux, is free and open source, and requires no account. The product positions itself as a fast, clean and distraction-free way to read Markdown, with the stated purpose of making a Markdown file open the way a PDF does: with a double-click, instantly readable and with no setup required. On the project's site, the creator explains the motivation directly under the heading "why I built Moji": the goal was for a Markdown file to open the way a PDF does, with a double-click, instantly readable, with clean typography and no setup. The site adds that usability came first from day one, that Moji is lightweight and comfortable for long-form reading, and that it is simple enough to disappear while you read. Editing and export were added without losing that focus. The entire design intent is captured in the line "Less interface. More document." The problem being addressed is the friction between raw Markdown text and a comfortable reading experience: instead of configuring a toolchain or an authoring environment simply to look at a document, the user opens the file and reads it, and the more advanced capabilities only appear when they are actually needed. Opening and reading a document in Moji is deliberately flexible. The site lists four ways to open a file: a standard file dialog, drag and drop, file associations, and a multi-tab workspace. File associations mean a Markdown file can be opened by double-clicking it in the operating system, which is the behaviour the product is built around. The multi-tab workspace lets several documents stay open at once, so readers can move between files without returning to a file picker each time. Once a document is open, Moji renders a rich, secure preview that includes tables, task lists, footnotes, LaTeX, code highlighting, emoji and outline navigation. A synced outline keeps the document structure visible alongside the content, and a dark theme is available for focused reading. The interface uses subtle chrome and compact controls so that the content itself stays in the foreground. Editing is available but stays secondary to reading. Moji's editor is built on CodeMirror 6 and adds Markdown shortcuts, line numbers, history, and search and replace. The site describes this as precise editing covering code, shortcuts and search. The intent is that a user who opened a file to read it can switch into editing without leaving the reader or losing the distraction-free layout, then return to reading. Markdown shortcuts speed up common formatting tasks, line numbers help when working with code-heavy documents, history provides a record of changes within the session, and search and replace supports navigating and updating longer documents. Moji renders Mermaid diagrams without leaving the document. Valid Mermaid blocks in a file become responsive diagrams inline, and the site states that flowcharts, sequence diagrams, Gantt charts, class diagrams, ER diagrams and more are supported. Diagrams can be zoomed from 10% to 1000%, panned freely, or fit to view, and a minimap plus a dedicated diagram viewer help navigate larger charts. Each image can be exported individually as PNG. The rendered diagrams are described as self-contained SVG in HTML, PDF and PNG output. The site summarises this as turning code into diagrams instantly, which means a document that describes a system in Mermaid syntax can be read and understood visually in the same window. Exports are described as predictable. Moji can export to PDF for precise layouts, to HTML for web-ready output, and to PNG, which the site presents as suited to long documents. Exports preserve typography, diagrams and very long documents. The export dialog is intentionally simple: the user chooses a format and a layout. Because Mermaid output is embedded as self-contained SVG, diagrams that appear in the reader also appear correctly in the exported PDF, HTML or PNG file. Moji is a desktop application rather than a web service. Official installers for Windows, macOS and Linux are published directly through GitHub Releases. For Windows, an NSIS installer is provided for Windows x64 with automatic updates. For macOS, a universal DMG supports both Apple Silicon and Intel, with manual updates. For Linux, users can choose an AppImage with automatic updates or a DEB package for manual installation. The version referenced on the site is 1.0.7. Moji is free, distributed under the MIT license, and requires no account, so no sign-in or subscription stands between the user and their document. The stated benefits follow from that design. Because Markdown files open with a double-click, the tool fits into the same habit as opening a PDF. Because the interface is lightweight and uses subtle chrome, it is described as comfortable for long-form reading and simple enough to disappear while you read. Because the preview supports tables, tasks, footnotes, LaTeX, code highlighting, emoji and diagrams, technical and structured documents render correctly rather than as raw text. Because editing and export are built in, a single application covers reading, light authoring and sharing. And because the interface is available in Portuguese, English, Spanish, Japanese, Chinese and Russian, readers can use the product in their own language. Several concrete scenarios follow from the features the site describes. A developer who receives a README or technical document can double-click the file and read it immediately with code highlighting and correctly rendered tables. A writer or note-taker can open a long Markdown document in the multi-tab workspace, follow the synced outline, and use the dark theme for extended reading sessions. Anyone working with technical documentation can embed Mermaid blocks and view flowcharts, sequence diagrams, Gantt charts, class diagrams or ER diagrams inline, zoom into a detail and export a single diagram as PNG. A user who needs to distribute a document can export it to PDF with precise layouts, to HTML for the web, or to PNG for long documents, with typography and diagrams preserved. Someone who needs to make a small correction can switch into the CodeMirror-based editor, use Markdown shortcuts and search and replace, then return to reading. And because Windows, macOS and Linux builds are all available, the same reader can be used across different machines. Moji is aimed at people who read Markdown on a desktop and want it to behave like a document rather than source code: developers reading repository documentation, writers and note-takers working in Markdown, and anyone who deals with technical documentation that contains diagrams. It is explicitly free, open source under the MIT license, and requires no account. The site states that the source can be explored, development followed, issues reported, and the project's next chapter shaped through the public repository. Technically, the site names CodeMirror 6 as the editor foundation and Mermaid for diagram rendering. Moji runs on Windows, macOS and Linux, with distribution handled through GitHub Releases, and the interface is localised into six languages. Moji's primary value proposition is stated on its own homepage: opening Markdown should be as simple as opening a PDF. It delivers that by pairing a focused, lightweight desktop reader with the editing, diagram rendering and export tools needed when reading is not enough, and it does so free of charge, as open source, across Windows, macOS and Linux.

sizeless is an AI-powered workflow for civil engineering that delivers precise 3D digital twins of open trenches and house connections, directly for GIS and CAD. The company describes its core promise simply: it turns a smartphone video of an open trench into the documentation utilities and contractors are legally required to produce — a 3D model, CAD/BIM plans, and the quantities they bill from. The product is aimed at network operators, civil engineering teams, district heating projects, and pipeline construction work, and it replaces a process that today takes months and a surveyor with one that the company says is completed in hours, from a video the crew films themselves. Underground infrastructure work has a documentation problem that is both expensive and time-sensitive. Once a trench is backfilled, the evidence of what was actually installed — pipe routes, couplings, house entries, third-party utilities crossing the excavation — is gone. Historically, capturing that evidence required waiting for separate surveying appointments before the trench could be closed, which delayed backfill, delayed billing, and delayed cash flow. Where documentation was handled manually, teams relied on manual sketches and created data silos that were hard to audit. Basement areas and other below-grade spaces made matters worse because GPS is not available there, so conventional positioning-based capture methods struggle. sizeless targets exactly these pain points by making documentation a by-product of work the crew already performs on site. The capture side of the workflow centres on SiteScan, the sizeless iPhone app. Field teams use a guided iPhone Pro workflow to capture properties, trenches, and technical rooms in minutes. The company emphasises that this requires no special hardware and no specialist training: the existing project team carries out the capture as part of the job. Because capture happens directly at the excavation, technicians can document house connections independently via smartphone, and trenches are backfilled immediately after the video is taken rather than waiting for a separate surveying appointment. SiteScan is distributed through the App Store, where it is listed as the Sizeless iPhone app. A single smartphone scan produces every deliverable the team already works with, described on the site as "one capture, every output". Those outputs fall into three families: 3D point cloud, 2D CAD, and BIM/GIS. The centimeter-accurate point cloud is a high-resolution 3D reconstruction of the scanned space and serves as the objective basis for earthwork volumes, dimensions, and audit trails. From it, sizeless generates industry-standard 2D CAD as-built plans in DWG and DXF for revision documentation, with the company noting that couplings and pipes are quickly identified and that measurement extraction is simplified. On the 3D side, sizeless produces digital twins of the pipe route including house entries, with seamless integration into GIS systems for future-proof planning and maintenance. Beyond the deliverables themselves, sizeless positions three core benefits for network operators. Quality and audit-proof documentation is provided as continuous 3D evidence that includes third-party utilities and house entries, and that works without GPS in basement areas. This eliminates manual sketches and data silos, and means construction errors can be identified before backfilling rather than after. Process autonomy means technicians document house connections independently via smartphone, so existing internal or external teams can handle a higher project volume through efficient workflows. Accelerated construction and billing follows from immediate backfill after the video: complete documentation is available weeks earlier, described by the company as "72h docs", enabling faster billing and cash flow. The workflow is presented as four steps. Step 01, trench capture, is standardized capture via iPhone Pro directly at the excavation — no special hardware and no extra appointments, carried out by the existing project team. Step 02, 3D point cloud, uses algorithms developed at ETH Zurich to generate a high-resolution 3D point cloud of the open trench, which the company describes as centimeter-accurate. Step 03, 2D CAD as-built plan, produces industry-standard as-built plans in DWG/DXF for revision documentation. Step 04, 3D model and GIS, creates digital twins of the pipe route including house entries and integrates them into GIS systems. The differentiator is therefore spatial AI for underground infrastructure: reconstruction algorithms combined with a capture method that needs nothing more than a phone the crew already carries. For the people doing the work, the outcomes stated on the site are concrete. Trenches can be backfilled immediately because no separate surveying appointment is needed, and complete documentation is available weeks earlier than the traditional route, which supports faster billing and cash flow. Documentation becomes audit-proof and GIS-ready, with continuous 3D evidence replacing manual sketches and disconnected data silos. Errors surfaced in the record can be addressed before backfilling. Because no specialists are required, technicians can work independently and teams can take on higher project volume. The site summarises the outcome as 72h docs, DWG/DXF output, and instant backfill. Several concrete scenarios appear in the material. Trench documentation during civil engineering works: a crew films an open trench with an iPhone Pro and the trench is backfilled immediately afterwards. House connection documentation: technicians document house connections independently via smartphone, including house entries, and those entries are captured in the 3D twin. District heating projects: the workflow is explicitly named for civil engineering, district heating, and house connections. Pipeline construction: automated as-built documentation is described for pipeline construction, where pipes and couplings must be identified for revision documentation. Network operation and maintenance: the resulting digital twins integrate into GIS systems for future-proof planning and maintenance of the pipe network. Property and technical room scanning is also mentioned as something the SiteScan app captures. sizeless is built for network operators and for the civil engineering, district heating, and pipeline construction teams that build and maintain underground infrastructure. The company states that it was founded by engineers from ETH Zurich and UC Berkeley and that it is backed by Y Combinator, ETH Zurich, UC Berkeley, Cambridge, and MIT. Integration points named in the content are GIS systems, CAD and BIM workflows, and industry-standard DWG/DXF file formats, alongside the SiteScan iOS app. The site's primary calls to action are booking a demo, seeing it in action, and requesting an in-person demo with a full name, email address, company name, and preferred demo date. Taken together, sizeless reframes as-built documentation as something a construction crew produces as it works rather than something a surveyor delivers afterwards. The combination of a guided iPhone Pro capture workflow, ETH Zurich-developed reconstruction algorithms, and outputs that drop into existing CAD, BIM, and GIS tools means the trench can be closed immediately, the documentation arrives in hours instead of months, and the resulting record is a continuous, audit-proof 3D twin that supports both billing today and planning tomorrow.

TIM PG is a Windows utility designed to make the use of artificial intelligence safer by protecting sensitive information before it ever leaves your computer's local environment. Presented on timsoft365.com under the heading Privacy Guard, it is described as providing intelligent data protection and security for the safe use of artificial intelligence. The product is built for anyone who wants to use large language models and other AI tools in their daily work but cannot risk exposing personal or confidential data to those tools. Its core promise is simple: you keep working the way you already work, while TIM PG handles the protection of sensitive text and documents in the background. The rapid adoption of AI assistants and large language models has created a new kind of privacy problem. To get useful answers, people routinely paste emails, contracts, reports and other documents into AI tools. Much of that content contains personal data and confidential business information, and once it is submitted to a service it is out of the user's control. TIM PG addresses this problem directly. Instead of asking users to stop using AI, or to manually rewrite every prompt, it removes the sensitive parts automatically before the text is pasted, and puts them back afterwards. The result, according to the product, is secure local data privacy for your workflows — without giving up the productivity gains of AI. The central capability of TIM PG is automatic masking of personal data from your clipboard. As you copy text, the utility detects the sensitive elements and replaces them with masked equivalents before you paste that text into a large language model. The AI then works with the anonymized version of the content, so the model never receives the original personal data. When the AI returns its response, TIM PG seamlessly restores the sensitive data back into it, so the answer you read looks exactly as it would have if you had pasted the original text. This round trip happens without the user having to learn a new workflow or remember to anonymize anything manually, which is what makes it practical for everyday use. Beyond the clipboard, TIM PG includes document anonymization for PDF and Office files. Documents are among the most common carriers of sensitive information — contracts, invoices, reports, spreadsheets and presentations regularly contain names, addresses, identifiers and other personal data. By anonymizing these files, TIM PG allows users to work with their real documents in AI-assisted processes while keeping the underlying personal data protected. The feature extends the same protection model that applies to clipboard text to the files people handle most often in business settings, so users are not limited to protecting only short snippets of text. The product also introduces Smart Bubble technology, which protects text segments locally on your PC. Rather than sending content to a remote service for processing, the protection is carried out on the machine itself. This is consistent with the product's overall design: TIM PG is described as strictly offline and 100% AI-free. It does not rely on cloud processing to decide what is sensitive or to perform the masking. For users in regulated industries or in organizations with strict data-handling policies, that local-only approach is a significant distinction, because it means the sensitive data never travels to a third party as part of the protection process itself. What makes TIM PG distinctive is its architecture rather than any single feature. It is a strictly offline utility that runs on Windows and is explicitly described as 100% AI-free. The anonymization and restoration logic runs locally, with no cloud component, which the product summarizes as no cloud, no leaked data. This stands in contrast to approaches that ask users to trust a remote anonymization service, or that depend on a hosted model to redact text. TIM PG instead sits between the user and the AI tool, intercepting the content on the way out, masking it, and then reversing the process on the way back. The user continues to interact with their chosen LLM as usual; the protection layer is simply present in the middle. The benefits follow from that design. Users can continue using AI tools for drafting, summarizing, analysis and research without manually stripping out names, contact details or other sensitive content first. Because the original data is restored into the AI's response, the output remains directly useful rather than being filled with placeholders that have to be re-matched by hand. And because everything runs offline with no cloud dependency, organizations gain a way to adopt AI assistance that is compatible with data privacy expectations. The stated outcome is straightforward: secure local data privacy for your workflows, with no leaked data. Typical scenarios center on the everyday task of pasting text into an AI tool. A user might copy a customer email or a case note into a large language model to get a summary or a drafted reply; TIM PG masks the personal data first and restores it in the returned draft. The same pattern applies to document anonymization: a PDF or Office file containing sensitive material can be prepared for AI-assisted review while the personal data stays protected. More broadly, the product fits any workflow where a person or team wants the assistance of an AI model but needs to keep the underlying information private — a common situation in business operations, administration and any role that handles personal data. TIM PG is a Windows utility, so it is aimed at desktop users rather than mobile or browser-based users. The site presents it as the Privacy Guard component of a wider product family: TIM, described as a next-generation business platform for business operations, and TIM TL, a set of smart helper tools for daily business processes. The company behind these products emphasizes its expertise and trust, stating that its expert team provides decades of development and IT security background to guarantee business stability. The timsoft365.com site also offers a way to watch a demo of TIM PG and to request a consultation. No pricing or technology stack details are stated in the available content. TIM PG is best understood as a privacy layer for AI adoption. It does not try to stop people from using large language models; it makes that use safer by masking sensitive data before it is pasted and restoring it afterwards, entirely on the local machine. With clipboard protection, PDF and Office document anonymization, Smart Bubble segment protection, and a strictly offline, 100% AI-free design, it offers a practical route to the productivity of AI without the exposure of cloud-based data handling.

Wisry is an agentic ad-cloning platform built for ecommerce brands, described on its website as an 'Agentic AdClone for ecommerce.' Its core promise is simple to state and ambitious to deliver: AI agents run the whole play. They scan the Meta and TikTok ad libraries for the ads already winning in your market, clone them into your brand as static and video ads, and launch them to Meta and Google, optimized for ROAS. Wisry presents itself as a way to get 'Winning ads, without the guesswork,' and headlines its home page with the claim 'Launch high-ROAS ads, 10x faster.' The platform says it is trained on over $1B of ad spend, and that the strategist agent is backed by $1B+ in ad spend used to train it. The intended audience is ecommerce brands and the marketers, agencies and growth teams that run paid social for them. Onboarding begins with a single input: paste your store URL, and Wisry builds brand memory covering products, voice, visual identity and audience, so that every agent stays on-brand. From there the platform is meant to act as an autonomous ecommerce growth team. Paid social for ecommerce is a research-and-iteration problem as much as a creative problem. The Wisry site frames the status quo as slow and uncertain: marketers spend weeks on research, creative production and launch, and much of that effort is guesswork about which hooks, angles and formats will actually convert. Wisry's own customers describe the pain directly. One supplement brand says that in its category 'speed is everything' - it does not need more creative ideas, it needs to spot what is winning and replicate it before the window closes. An agency customer says the bottleneck 'was always research and iteration,' and that agentic research finds what is working across a market and turns it into output at a pace a manual team could not touch. Another customer, selling hardware to Tesla owners, notes that it operates in a niche audience 'where every ad dollar counts' and that it is no longer 'testing blindly' but scaling what is proven. Wisry's answer to this is to replace open-ended guessing with evidence pulled from ads that are already spending and converting in the market. The first group of capabilities is research and strategy. Wisry's flagship feature is agentic ad research: research agents read the ads already running in your market, cite what they found, and turn the winners into angles you can brief. The site shows this working against the Meta ad library and TikTok top ads, ranking the ads it finds - for example, a ranked set where the top three of nineteen are surfaced with details such as how long each ad has been live (64 days, 35 days, 23 days), how many variants sit behind the concept (17, 10 and 6), and impression counts in the millions. The reasoning shown is explicitly performance-based: the longest unbroken spend in the run, a format that survived a full test cycle, and the fastest variant ramp in the category. A strategist agent then turns that research into campaign concepts covering audience, hooks and messages, and attaches source citations behind every angle. Because Wisry builds brand memory from your store URL - products, voice, visual identity and audience - every agent in this chain stays on-brand rather than producing generic output. The second group is creative production. Wisry clones video ads: point it at a video ad that works and get your own version of it, matching the same structure and pacing while swapping in your product and your brand; the site illustrates this as 'Structure matched' across hook, proof and close. Static ad cloning follows the same logic: Wisry rebuilds a winning static in your palette, your type and your product shots, then fans it out into every placement you need. The site is explicit about what is kept and what is swapped - layout, headline structure and type are kept, while palette, product and type are swapped for your brand. On top of cloning, Wisry ships ad templates so campaigns start from formats with a track record instead of a blank canvas; templates include listicle, problem-solution, quiz, portrait, us-vs-them, seasonal, feature-benefit and how-to, arriving in feed (1:1 and 4:5), portrait (2:3), landscape (16:9) and story (9:16) sizes, and each one is sized and safe-area-checked for its placement, including Reels, Story and Feed. Finally, every generated cut opens in a real video editor inside Wisry, where you can retime scenes, restyle captions, swap a shot and re-render without leaving the platform. The third group is launch and optimization. Once creatives exist, an ads agent ships them to Meta and Google, watches performance, moves budget to winners, and keeps new creatives coming - a loop the site summarizes as 'launches, optimizes, repeats. 24/7.' This is what makes the system agentic rather than a one-off generator: the same platform that produced the ads from market evidence also handles distribution and budget allocation based on how those ads perform. Wisry describes its studio as shipping nine capabilities, all pointed at selling more of your products, with the two flagship features being the ones everything else is downstream of. The end-to-end loop is presented as a continuous cycle rather than a campaign: research feeds strategy, strategy feeds creative, creative feeds launch, and launch performance feeds the next round of iteration. Wisry's overall approach is deliberately end-to-end and evidence-first. The workflow is described in five steps: first, Wisry pulls your brand and products after you paste your store URL, building brand memory across products, voice, visual identity and audience; second, a research agent deep-analyzes your Meta and TikTok competitors' ads and content to find what is already converting; third, the strategist agent generates evidence-backed angles for your campaigns, including audience, hooks and messages with source citations; fourth, the agents copy winning creatives for your products, generating video and static ads from the best-performing ads and your chosen angles; and fifth, the ads agent launches, optimizes and repeats around the clock. The site summarizes the whole flow as 'Your store in. Winning ads out.' Under the hood, Wisry says it is orchestrated using leading models, listing Grok, Gemini, OpenAI, Claude, KlingAI and Nano Banana as the models involved. The distinguishing idea is that every angle is traceable to a real ad that is already winning, and every output stays inside the brand memory built at onboarding. The benefits Wisry claims are framed in performance and speed terms. The site advertises a +200% average boost in ad performance, $1B+ in ad spend used to train the strategist, a 10x faster path to launching a high-ROAS campaign, and a shift from weeks to minutes for research, creative and launch handled end to end. Customer quotes add concrete outcomes: a hardware brand selling to Tesla owners reports ROAS up 300% since starting and describes scaling what is proven instead of testing blindly; a supplement brand reports shipping winning variations 2x faster and describes the difference as reacting to trends versus riding them; and an agency says it has scaled client accounts much faster because agentic research finds what works across a market and turns it into output at a pace its team could not match manually. Concrete scenarios described in the content include a niche hardware brand that sells to Tesla owners and needs every ad dollar to count, scaling what already works in its account; a supplements brand operating in a fast-moving category that needs to spot winning creative and replicate it before the window closes; and an agency running ads for many clients, where research and iteration were the bottleneck and agentic cloning lets it scale client accounts faster. More generally, the product is built around the ecommerce advertising workflow of importing a store, researching a market's Meta and TikTok ads, generating evidence-backed angles, cloning winning static and video creatives into a brand's own palette, product shots and type, fanning them out across placements using templates, launching to Meta and Google, and then continuously moving budget toward the winners while new creatives are produced. Wisry is a paid product. The pricing section offers three commitment lengths with one payment up front, after which the plan continues month to month: 2 weeks at $49.50 (discounted to $34.65, saving 30%), 4 weeks at $99 (discounted to $49.50, saving 50%, marked Most Popular), and 8 weeks at $198 (discounted to $89.10, saving 55%). The site highlights a per-day cost of $3.53 at full price, reduced to $2.48, $1.77 and $1.60 per day at the three tiers, and the entry call to action is 'Get started for $49.50' with the note that this is one payment of $49.50 for 4 weeks, then $99/month, cancel anytime, secured by Stripe. Wisry runs in the browser as a web app. The site also notes a Product Hunt launch promotion offering up to 55% off. In short, Wisry's primary value proposition is that ecommerce advertisers no longer have to guess what creative will work. By researching the Meta and TikTok ads already winning in a market, converting that evidence into cited angles, cloning the strongest static and video creatives into a brand's own identity, launching them to Meta and Google, and then optimizing budget around performance around the clock, Wisry turns paid social from a slow, speculative process into a faster, evidence-driven loop - 'Winning ads, without the guesswork.'
Accordio is an AI back office built for people who run a business alone. It tracks your time, drafts contracts, proposals and invoices, gets them signed and collects the money, and it does all of it from a chat message rather than a dashboard. You connect it to Claude with a single URL, or text it on WhatsApp, Telegram or Slack. The product is aimed at consultants, designers, developers, coaches, founders, fractional CXOs and agencies of one who need the admin handled without hiring anyone. Most solo operators do not lose money because of their craft; they lose it to the paperwork around it. Hours go untracked, contracts are sent late, invoices sit unpaid and receipts pile up until tax season. Roma Bors, Founder at Deduxer, states the problem directly: he lost 50 thousand dollars to clients who never paid, so he built the app that makes sure it never happens again. Accordio exists to close that gap. Instead of subscribing to an e-signature tool, an invoicing app, a time tracker and a contract template library, the whole office ships inside one product that already knows your hours, your clients and what you are owed, so it never has to ask you for context before it acts. Time tracking is the foundation of the product. A Mac app tracks the day on its own, so you can ask what you worked on today and see what is still unbilled without ever starting a timer, while manual timers remain available when you want them. The tracker keeps a full history and produces client-ready timesheets, and it breaks the work day down into focus, meetings and breaks so you can see where the hours actually went. The tracker is open source on GitHub and free forever, and Claude and ChatGPT can both read and log your time. Billable hours convert into an invoice in one click, which is the real point: hours captured at the moment they happen do not get lost or forgotten at the end of the month. Documents are the second pillar. Describe a project and Accordio returns a complete contract with the right clauses and payment terms; an AI advisor flags gaps before you send it, and clients sign without creating an account. Those e-signatures are legally binding and meet the US ESIGN Act and EU eIDAS rules, with a timestamp, IP address and a full audit trail behind every signature. Proposals follow the same flow: Accordio drafts the scope and price, sends the proposal and tracks opens, and when the client says yes the proposal turns into a contract and an invoice without retyping anything. Forms and questionnaires capture leads and intake, and an estimate widget can be embedded on your website. Pitch decks round out the document set, and 12 themes, your own logo and colours and editable clauses mean clients see your brand rather than Accordio's. Existing contracts can be imported from Google Docs and elsewhere and become editable, signable documents. Invoicing and payments are where Accordio is most differentiated. An invoice can be generated from a project, from tracked time or from a contract milestone, and every invoice carries a pay page with your bank details configured for the US, EU and UK. Bank transfer payments carry no fees and no commission, and if you want to accept cards you add your own payment link and it appears on every invoice. Connect your bank through Plaid and incoming deposits are matched to open invoices on their own; when a match is unclear, Accordio asks you rather than guessing. Overdue invoices are chased automatically with payment reminders, and the accounting layer keeps expenses, a profit and loss report and a tax report ready so your books never need a bookkeeper. Snap a receipt and it is categorised, marked deductible and filed to the right report, with bank reconciliation happening continuously in the background. Around the paperwork sit the meeting, inbox and notification features. Booking links let clients find a slot on your calendar without back-and-forth email, and a meeting recorder auto-joins calls, transcribes everything and extracts action items so you can stay present instead of taking notes. Meeting briefs arrive before calls, and follow-ups are drafted afterwards. Accordio also manages your inbox: it reads new mail, drafts replies in your voice and flags the messages that need you. Proactive alerts push morning briefings, overdue reminders and deadline warnings before you even ask for them, and each client gets a branded portal with their contracts, invoices and files behind a magic link, so there is no password and no signup for them. The delivery mechanism for all of this is the MCP connector. Accordio speaks MCP, so pasting a single URL into Claude, through Settings, then Connectors, then add custom connector, gives Claude 30 tools covering your hours, clients, unbilled totals, invoices, contracts, calendar and tasks. Claude can see your business and act on it: ask what you promised a client on Tuesday's call and it answers from the recording. It can draft the contract, log the hours and prepare the invoice, while sending, signing and payments stay in the app, so Claude proposes and you approve. The connector is free forever and also works in Claude Code, Codex and ChatGPT, and the same assistant is reachable by plain text on WhatsApp, Telegram and Slack. Setup is described as a two-minute job with nothing to migrate, and the product is also available in the browser and as a Mac menubar app. The benefit is that the admin stops being a separate job. Because Accordio already holds the invoice, the contract and the hours, it does not ask you for context when you give it an instruction; it just does the work. You open one product instead of four subscriptions, and it replaces an e-signature tool, an invoicing app, a time tracker and contract templates with a single place. Payments arrive without chasing, receipts file themselves, calls are followed up and mornings start with a briefing rather than a backlog. The tracker stays free forever, so time tracking and asking an AI about your hours never carries a cost, and the paid tier adds the money documents and the agent that sends and chases them. Concrete workflows show how this plays out. A consultant asks who still owes them and Accordio reports that a client is 12 days late on a 2,400 dollar invoice and offers to send the reminder. A designer describes a retainer and gets a draft on their usual terms, sent to the client for signature. A solo operator asks Accordio to bill the hours for last week and it invoices 14.5 tracked hours, sends the invoice and attaches bank details. Someone asks for 30 minutes with a contact next week, Accordio sends the booking link, and the accepted slot lands on the calendar. A receipt for a software subscription is messaged in and filed under expenses, matched to the card charge. For founders, the pattern is broader: customer contracts described and signed, each customer billed on their own cadence with deposits matching themselves, books kept without a bookkeeper, and every call recorded with action items filed and follow-ups drafted. Accordio is built for people who run a business alone: consultants, designers, developers, coaches, founders, fractional CXOs and agencies of one, with dedicated solutions for software companies. It integrates with Google Workspace, Slack, Notion, Asana, Trello, Linear, GitHub, Figma, Zoom and more, and the site references Gmail, Google Calendar, Google Drive and 160+ apps, with bank connections handled through Plaid. Pricing is simple: the Mac time tracker, timers, time entries, clients, projects and the Claude and ChatGPT connector are free forever with unlimited clients and projects, while the Legend plan costs 39 dollars a month, or 29 dollars a month billed yearly at 348 dollars a year, and includes every feature, unlimited e-signatures, zero commission and 10,000 AI credits a month. There is a 14-day free trial with no credit card, and if it ends, nothing is deleted. Accordio's core proposition is that the assistant you already talk to should be able to run the admin around your work. Track time, create and sign contracts, send invoices, get paid, and let one message do the rest.

chat-recall is a tool that turns the conversation history your team has built up with AI coding assistants into a single searchable archive. It reads what your assistants have already written down — the chats, the plans, the task lists and the notes — and consolidates them into one searchable history. As the product puts it, Ctrl+F doesn't work on your brain, but now it works on your chat history: your team has done months of work with AI assistants, and none of it is searchable until chat-recall is installed. It is aimed at developers and teams who use several AI coding tools at once and want the record of that work to be findable rather than scattered. The problem chat-recall addresses is fragmentation. Claude Code, Codex, Cursor and OpenCode each keep a full record of the work you do with them, in its own format, and none of them can read the others. Across five AI coding tools that means months of chats, plans, task lists and notes sit in separate silos that no single search can reach. The result is work that gets redone because nobody can find the original decision, plus a quieter risk: passwords and API keys that were pasted into old conversations and never noticed again. Without a way to search across tools, both the value and the risk hidden in that history stay invisible to the team that created it. You start with a single command: npx chat-recall init. One command reads what your assistants already wrote and turns it into one searchable history. The steps the product describes are straightforward. First, your conversations: everything your assistants have written down, the chats, the plans, the task lists and the notes, across five AI coding tools. Second, passwords are removed on your own computer. Third, everything lands in one searchable history, available the moment it arrives. There is nothing to restructure by hand and no export to perform, because chat-recall reads the records the assistants have already created and assembles them into a single index. Privacy is handled locally rather than in the cloud. Passwords and secrets are removed before anything leaves your computer, and the vendor states that it only ever sees the last few characters of a removed value; the interface shows a masked preview such as the start of a token, a run of asterisks, and a short tail. Steps one through three of the pipeline happen on your own machine. That local-first design matters because the content being indexed is often the most sensitive material a team produces: live credentials, internal plans and unfinished work that nobody wants uploaded to a third-party search index just to make it findable later. Beyond organising history, chat-recall actively looks for secrets that leaked into old chats. Its security view groups every leaked credential by rule, and each row shows a masked preview of the value, a live-or-dead verdict on whether the key still works, the detectors that matched it, and how many sessions it appeared in, so you can see whether a key is still live and how widely it was exposed on one screen. The detectors know the key formats that the big services publish. If your company has invented its own format, you can tell chat-recall the pattern and it gets checked too, which is how custom internal credentials end up covered as well. chat-recall also gives your assistant access to the history itself. Your assistant searches it directly, so it stops asking what you decided last month, and one shared memory means decisions, findings and tasks live in one place rather than in a single tool's silo. The product lists tasks with proof, and what to fix next, among its outputs, and bugs turn into tasks on their own: each one shows up with the fix already sketched out, and closes itself once the problem is actually gone. Rules can be set once per project — mark a project a prototype or a live product, and every assistant that opens it plays by the right rules. Because teams rarely use one assistant on one machine, chat-recall includes a toolkit coverage matrix: six skills down the left and a column for each AI tool on each of two machines. A filled cell means the skill is installed there; an empty ring means it is missing, and clicking it copies the skill across with a sync-to-all action. Each row carries a coverage count so you can see at a glance which of your assistants has which add-on. The payoff is portability. A new laptop already knows everything once you sign in, with nothing to copy over by hand, and every add-on you have built up follows you to whichever assistant you pick up next, so trying a new assistant does not mean starting over. Overall, chat-recall works as a local assembly line rather than a cloud service. A single command reads the records that five AI coding tools have already written, strips passwords on your own machine, and produces one searchable history that is ready immediately. The same history, the same tools and the same rules are then available everywhere you work, across assistants and across computers. Three of the steps happen on your computer, and the product describes the flow as an assembly of your conversations, the removal of passwords, and one searchable history — with leaked passwords, what to fix next, tasks with proof and one shared memory all downstream of that assembly. The benefits follow from that design. Work stops being redone because the original decision is searchable, and your assistant stops asking about things you already decided. A new laptop is useful the moment you sign in, and a new assistant arrives with your accumulated add-ons already in place. Secrets stop being invisible, because leaked keys are surfaced with a verdict on whether they still work and how many conversations they turned up in. Bugs become tasks with a sketch of the fix and disappear on their own once resolved. And rules can be applied consistently, so a prototype and a live product are treated differently wherever they happen to be opened. Concrete uses follow the same pattern. A developer wants to find a decision the team made weeks ago and searches the shared history instead of scrolling through one tool's transcripts. A security-minded team runs the leaked-key check to catch credentials pasted into old chats and to see which of them are still live. Someone setting up a new laptop signs in and finds the whole history already there. A developer trying a new assistant keeps the add-ons built up over time. A bug found in a chat becomes a task with a sketched fix that closes when the problem is gone. And a project marked as a prototype is opened under the right rules by every assistant. chat-recall is built for developers and teams who work across multiple AI coding assistants and want a searchable record of that work. The named integrations are Claude Code, Codex, Cursor and OpenCode, with the site referring to five AI coding tools in total, and to add-ons or skills that can be installed per tool and per machine. Installation runs through npx chat-recall init, which places it in the Node.js command-line ecosystem, and the product links to documentation on how it works and on what your assistant can ask. The takeaway is that chat-recall gives a team back the searchability of its AI work. One command reads what Claude Code, Codex, Cursor and OpenCode already wrote, removes passwords before anything leaves your computer, and produces one searchable history that your assistant can search itself — while also catching keys that leaked into old chats and checking which of them still work.
Viral Sonar scans Instagram every morning and surfaces the Reels that are blowing up in your niche right now. Not the ones with the biggest view counts — our own algorithm detects the ones that are actually taking off, before everyone else piles in. Each reel comes with a breakdown of its format: hook, structure, pacing and why it works, so you can replicate it the same day. It also tracks the audio waves moving between accounts in your niche before they saturate. One scan every morning. No agency, no guessing.

Drive is a vehicle telemetry app that turns the phone already in your car into a telemetry rig. Its maker describes it as capturing g-force, braking and cornering data — "the whole trace" of a drive — and as flagging license plate reader cameras as you approach them. The product is aimed at people who want driving data from an old weekend car rather than through professional motorsport equipment, and it is delivered as an iOS app available on the App Store. There is no wiring loom, no dongle and no laptop involved, and no sign up is required to use it. The maker summarises the intent simply as "Just driving fun." Drive came out of a personal gap described by its maker, Andy Kim, who says he spent a few years as a design lead on autonomous driving for Android Auto — "the work of making a car drive itself well" — and then spent his weekends in a 27-year-old car doing precisely the opposite, badly, for fun. Drive is what came out of that gap. The problem the product targets is stated explicitly in the maker's own framing: the category it competes against costs $800 to $3,000 and involves a wiring loom, while the phone in a driver's pocket has had an accelerometer, a gyroscope and GPS built into it for a decade. The maker calls that gap "most of the product." In other words, much of what a basic vehicle telemetry setup needs already exists in the device most drivers carry with them every day, which is the observation the entire product is built around. The core of Drive is telemetry capture. According to the product description, Drive records g-force, braking and cornering, described as "the whole trace." These are the elements the maker calls out consistently: what the car is doing under load through corners, what is happening under braking, and the g-forces involved. Rather than requiring a wiring loom or a dongle to read data from the vehicle's own systems, Drive uses the sensors already present in the phone that is in the car. For a driver running a weekend car on a favourite road, that means the trace information associated with a dedicated logger, captured without installing anything in the vehicle. The maker frames the product around exactly this idea: the instrumented drive without the instrumented car. Drive also flags license plate reader cameras as you come up on them. The maker explains that this feature started as a personal itch, having noticed Flock cameras everywhere. Within the app, the result is an alert as the driver approaches a license plate reader (LPR) location. This is a privacy-oriented capability rather than a performance one, and it sits alongside the telemetry features rather than replacing them, which makes it an unusual combination: a driving and telemetry product that also provides awareness of automated plate reading within the same experience. In the Product Hunt discussion, one commenter called the LPR flagging "the surprise here" and asked where the camera locations come from — whether from a source such as DeFlock's OpenStreetMap layer or the maker's own dataset — but the maker's published description does not state where that data comes from. The setup described is deliberately minimal: no wiring loom, no dongle, no laptop, and no sign up. Each omission corresponds to something the maker identifies as friction in the existing telemetry category. A wiring loom is part of what makes dedicated systems expensive and permanently installed; a dongle is extra hardware to buy, carry and pair; a laptop is part of many data logging workflows; and a sign-up wall adds account creation before the driver can do anything. Drive's stated approach removes all four. The maker's summary — "Just driving fun" — makes the intended experience clear: get in the car, use the phone that is already there, and drive. The overall approach is to treat the phone as the telemetry device. The maker points out that the phone in your pocket has had an accelerometer, a gyroscope and GPS in it for a decade, and positions that existing hardware as the basis for the product, saying "That gap is most of the product." Drive therefore derives its driving data from the phone's own sensors rather than from dedicated hardware reading the vehicle's systems. The maker, who worked on autonomous driving interfaces for Android Auto, describes the product as coming out of the contrast between that professional work and weekend driving in an old car for fun. Drive is distributed as an iOS app, listed on the App Store under the name Drive: G-Force Telemetry. The stated benefit is access to vehicle telemetry without the cost and installation burden of the existing category, which the maker says runs from $800 to $3,000 and involves a wiring loom. Because Drive uses the phone already in the car, there is nothing to wire in, no dongle to plug in, and no laptop required at any point in the described workflow. A second benefit is privacy awareness: the LPR alert gives the driver notice as they approach license plate reader cameras, a feature the maker created after noticing Flock cameras everywhere. The maker also frames Drive as being about enjoyment — "Just driving fun" — rather than a professional engineering workflow, which suggests the intended benefit is quick, low-friction access to driving data. The primary scenario named in the product is the weekend drive. The maker's own story is of spending weekends in a 27-year-old car, and Drive is described as turning the phone already in that car into a telemetry rig capturing g-force, braking and cornering. A second scenario is the driver who is curious about professional-grade data logging: the maker explicitly addresses people who have run a real data logger — AiM, VBOX or Racelogic — and asks what they would miss most going to a phone, saying that list is what he is building from. A third scenario is privacy-oriented driving, where a driver approaching a license plate reader camera gets flagged as they come up on it. All three scenarios share the same setup: a phone, a car, and no additional hardware. Drive is aimed at driving enthusiasts — the maker's own reference point is a 27-year-old car driven for fun on weekends — and at drivers who want telemetry data without the $800–$3,000 spend and wiring loom associated with the existing category. It also speaks to people already familiar with data loggers such as AiM, VBOX and Racelogic, whom the maker invites to describe what they would miss moving to a phone. Privacy-conscious drivers are a further audience, given the license plate reader alerting built in after the maker noticed Flock cameras everywhere. Pricing is free to start, and the product is an iOS app available on the App Store. On Product Hunt it is tagged iOS, Cars and Privacy, and sits in the Maps and GPS category. Drive's proposition is straightforward: the phone already in your car has the accelerometer, gyroscope and GPS needed to record g-force, braking and cornering, so it can serve as a telemetry rig without a wiring loom, a dongle, a laptop or a sign up — while also flagging license plate reader cameras as you approach them. The maker, who designed autonomous driving interfaces for Android Auto, built it out of the contrast between that work and weekend driving in an old car. Free to start and available on iOS, Drive targets the gap between expensive professional data logging and simply enjoying a drive.

Viso Now is a self-building AI vision platform that turns images, video, and camera feeds into working computer vision applications. Rather than assembling a machine learning pipeline from scratch, users describe in plain language what they want to understand in their footage, and Viso Now builds the agentic vision logic and the custom live dashboards to go with it. The website positions the product around a single promise: bring a new AI vision application to life. It is designed for anyone who can describe a problem, from individuals who want a vision agent running in minutes to enterprises that need governed vision intelligence across many sites and cameras. The problem Viso Now addresses is the cost and complexity that traditionally surrounds computer vision. Building a vision application normally means model training, image annotation, ML engineering and ongoing model maintenance, which puts bespoke vision projects out of reach for most operational teams. Viso's own messaging states that isolated solutions are no longer enough and that not all computer vision is equal: single-purpose tools lease one outcome for one use case, while Viso positions its platform around multiple use cases across multiple locations. The site argues for flexible solutions with a lower total cost of ownership, complete control of your data, and the ability to customise outcomes and hit KPIs, and for handling today's challenges while preparing for tomorrow's opportunities. The core of Viso Now is prompt-driven building. A user describes the real-world situation they want AI to solve in plain language, with no model training and no annotation needed, and watches as Viso builds the application with them in real time. The site describes this as starting from a prompt, testing instantly, and turning ideas into vision agents. An 'Ask Viso to create a camera agent' flow sits directly in the product interface, where users work alongside the builder and refine the application until they are happy with the finished solution. Viso describes the underlying capability as visual general intelligence that applies to any use case, which is why the same engine can be pointed at very different operational questions without rebuilding anything from the ground up. Supporting that building process is a template gallery. Viso Now shows ready-made templates including Task-Aware PPE Check, Excavator Near-Miss Monitor, Hot Work Safety Check, Work-at-Height Safety Check, Clinical PPE Protocol Check, GMP Hygiene Check, Loading Dock Exclusion Zone, Front Desk Wait Tracking, Restricted Site Vehicle Alert, Hazardous Area PPE Check, Pipeline Integrity Scout, Visible Release Detection, Robot Cell Intrusion Detection, Production Area Access Check, 5S Shop Floor Audit, Emergency Exit Clearance, Reversing Vehicle Danger Zone and MEWP Fall Protection Check. Further templates cover Dock Turnaround Intelligence, Check-in Queue Orchestrator, HSE Workplace Audit, Commercial Vehicle Safety Screening, Dump Zone Safety Inspector, Abandoned Luggage Response, Handling Risk Assessment and Service Queue Pressure Analysis. Users can also feed the system their own media by clicking to upload or dragging a video in, with MP4, MOV, MKV, PNG and JPG supported, by capturing a photo, or by recording video, and they can choose between Fast, Balanced and In-Depth analysis modes depending on how much detail the task needs. Once an application behaves as intended, the workflow moves to deployment. Users iterate on the app until they are satisfied with the finished solution, then connect cameras or upload connectors to start using it immediately. Viso handles the end-to-end infrastructure behind the scenes, covering compute, visual analysis, governance, authentication and integrations, so teams do not have to stitch those layers together themselves. The platform produces custom live dashboards as part of the build, which turn what the camera agent observes into something an operator can actually monitor and act on rather than raw detections. Viso Now's distinctive approach is that the application builds itself. The website frames this as 'Your idea, the vision app builds itself' and 'If you can describe it, you can build it.' Instead of choosing from a fixed catalogue of detection types, users state the outcome they want and the platform constructs the agentic vision logic around that outcome. Build, refine, go live is the entire loop, and the security and infrastructure concerns are handled by the platform rather than by the user. The site summarises the free tier as dropping any video, describing what to build, and getting a working vision application in minutes, with no labelling, no training and no big team required. Viso reports concrete outcomes on its website. A customer story from a global manufacturer states that the company replaced four point solutions with one Viso deployment and that, by month three, near-miss incidents were down 54%, with the safety team spending zero hours rebuilding models. The same page cites 24/7 eyes on every camera that never blink and never tire, 10x faster AI vision versus other methods, and 90% less ML engineering effort with no labelling and maintenance. Elsewhere the site claims a 10x faster understanding of visual data to drive efficiency, automation and innovation, and an 85% reduction in time-to-value of computer vision applications. For teams, the practical benefit is speed: ideas become running vision agents without a dedicated ML function, and the same deployment keeps working as requirements change. The template library also shows the concrete scenarios the product is used for. In construction, Task-Aware PPE Check, Excavator Near-Miss Monitor, Hot Work Safety Check, Work-at-Height Safety Check and MEWP Fall Protection Check address worker safety and site hazards. In oil, gas and energy, Pipeline Integrity Scout, Visible Release Detection, Restricted Site Vehicle Alert and Hazardous Area PPE Check cover asset inspection and restricted zones. In manufacturing, Robot Cell Intrusion Detection, Production Area Access Check and 5S Shop Floor Audit support safety, access control and lean audits. In logistics and warehousing, Loading Dock Exclusion Zone, Dock Turnaround Intelligence, Dump Zone Safety Inspector and HSE Workplace Audit assess dock performance and workplace safety. Healthcare, food and beverage templates such as Clinical PPE Protocol Check and GMP Hygiene Check cover protocol and hygiene compliance, while Front Desk Wait Tracking, Service Queue Pressure Analysis, Check-in Queue Orchestrator, Abandoned Luggage Response and Commercial Vehicle Safety Screening serve hospitality, public venues and transport environments. Two products sit on one platform. Viso Now is the free entry point, marked 'Free · No Credit Card', offering a free forever tier with the ability to invite your team, prompt-to-agent building in minutes, visual general intelligence for any use case, and seamless connection to other systems. Viso Suite is the enterprise option, described as the complete operating system for enterprise vision intelligence: connect every camera across every site, build governed applications, and operate agentic workflows at scale, with support for 10,000+ cameras and hundreds of sites, full lifecycle from build to deploy to govern to scale, edge AI with on-prem or cloud support, and compliance with SOC 2, ISO 27001, GDPR and CCPA. Viso also states it is trusted by Fortune 500 companies and lists 136+ applications tuned for every industry. Viso Now's value proposition is straightforward: describe the real-world situation you want AI to solve, and the platform builds, refines and runs the vision application for you. No model training, no annotation, no code writing, and no large team, but with the same platform able to scale into governed enterprise deployments across thousands of cameras. It turns any camera into an analyst that can detect, inspect, alert and understand what is happening in the physical world.
