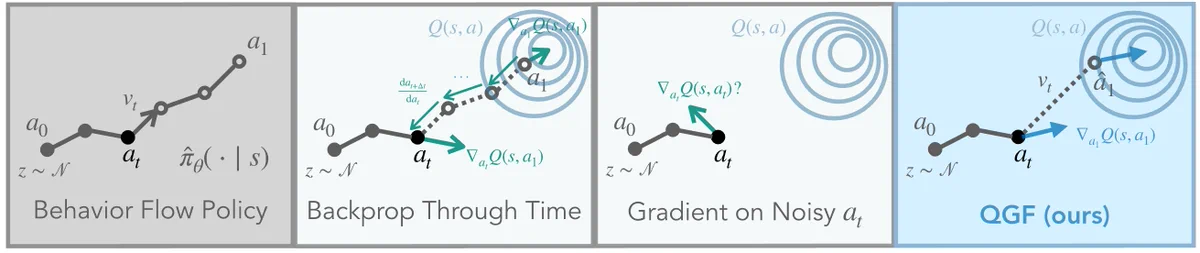
A surprisingly simple way to turn Q functions into test time RL guidance for flow policies. I had a small part in advising this while the Berkeley team churned out a lot of experiments to really understand what methods work when. Great work!

Training diffusion & flow policies with RL is hard, but training them with behavioral cloning is easy. So what if we just train flow policies with BC, and only "do RL" at test time?
We found an easy way to do this (called Q-Guided Flow), and some surprising findings👇🧵