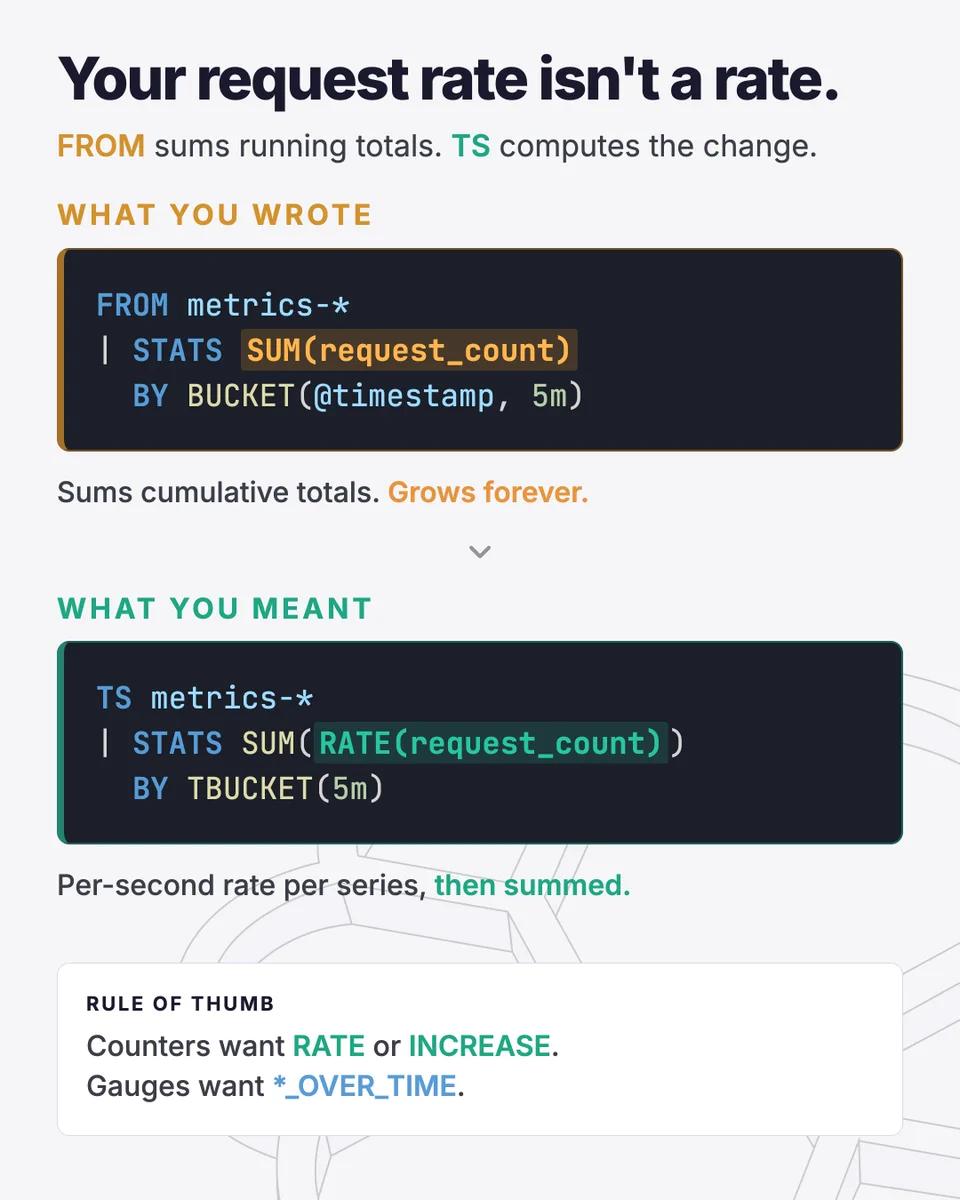
SUM(request_count) in a FROM query is not your request rate.
request_count is a cumulative counter: each sample is the running total since the process started. FROM treats every document as an independent row, so SUM adds each host's running total once per sample. The result
Elasticsearch 9.5's columnar index mode stops indexing most fields by default.
So what keeps a range query fast without an inverted index or BKD tree?
2 changes underneath made it possible. Tech preview, read before you switch.
The hard parts of hybrid retrieval, already done.
Elasticsearch Vector Database is a new serverless offering where expert-level tuning is the default:
- bfloat16 storage: half the disk footprint before quantization even starts
- BBQ: up to 32x vector compression, 95% less
BM25 has been the default similarity on every Elasticsearch text field since version 5.0. Every lexical query
you have ever run was scored with it (unless you defined otherwise).
That default still does work, vectors can't. Exact tokens are the clearest case: SKUs, error codes,