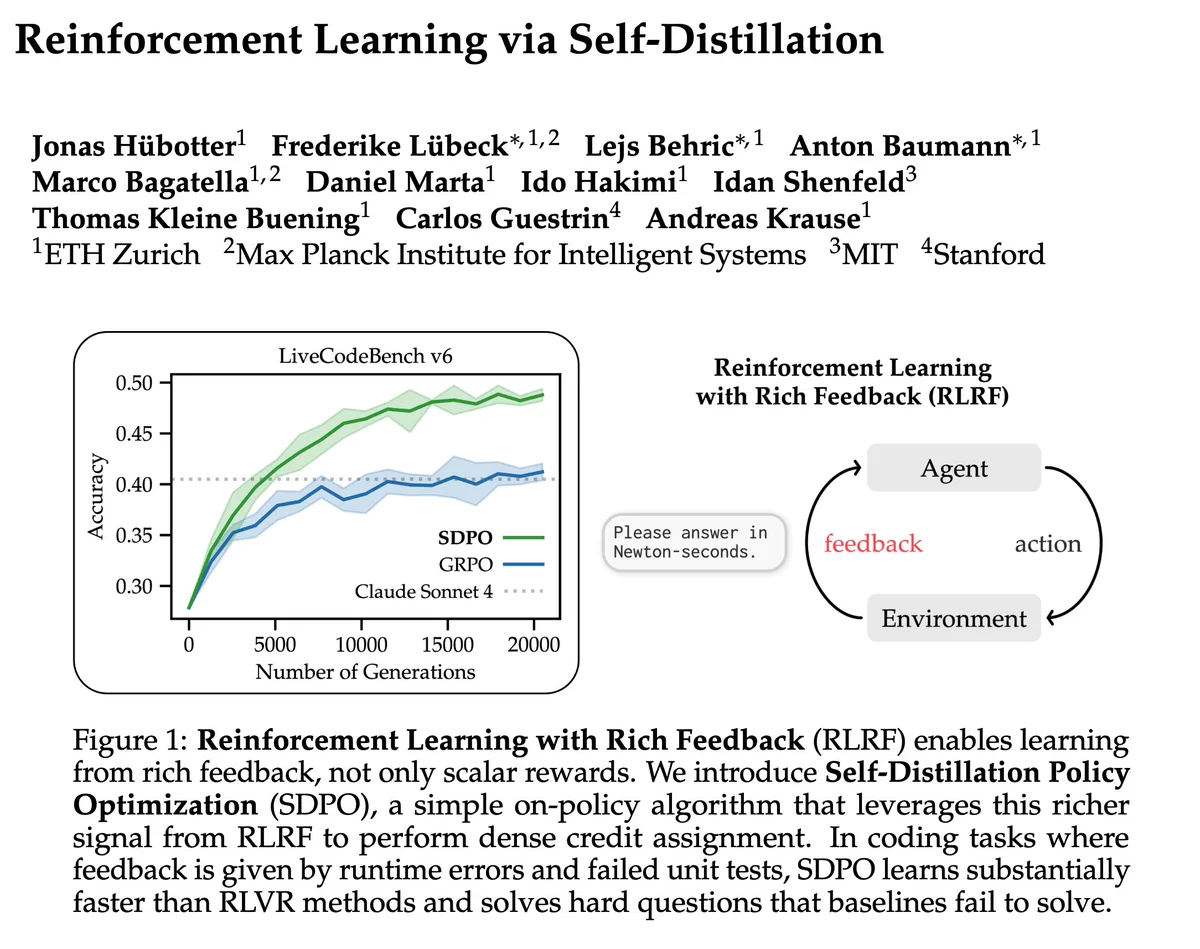
With SDPO, you can now do RL with natural language feedback, like error messages from coding environments or LLMs as judges. You can achieve huge gains over GRPO with scalar rewards!

Training LLMs with verifiable rewards uses 1bit signal per generated response. This hides why the model failed.
Today, we introduce a simple algorithm that enables the model to learn from any rich feedback!
And then turns it into dense supervision.
(1/n)