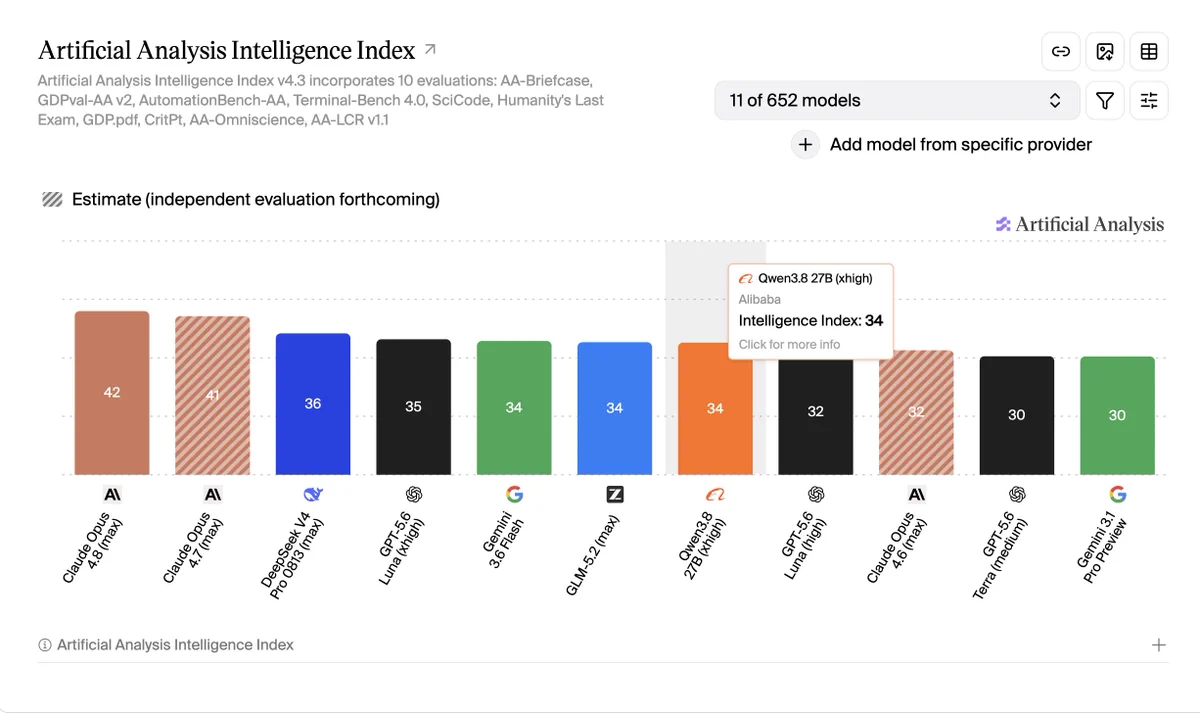
I am 99% certain that in the coming few years, the majority of daily work stuff will be managed using local LLMs, leaving the cloud frontier models to tackle the challenging stuff
Qwen3.8-27B now runs on 8GB of VRAM!
That's less than 500$ to run a model smarter and more capable than:
1. GPT-5.6-Luna High
2. Opus-4.6-Max
3. Gemini-3.1-Pro
And ties with:
1. GLM-5.2 Max
2. Gemini-3.6-Flash
PrismML has the mandate
Readers added context
The cited rankings reference Artificial Analysis benchmarks for full-precision Qwen3.8 27B (score 34), not PrismML's quantized ternary version which retains 98.2% of the base per its own benchmarks with no independent eval on this index.
artificialanalysis.ai/models/qwen3-8…prismml.com/news/bonsai-2-…
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
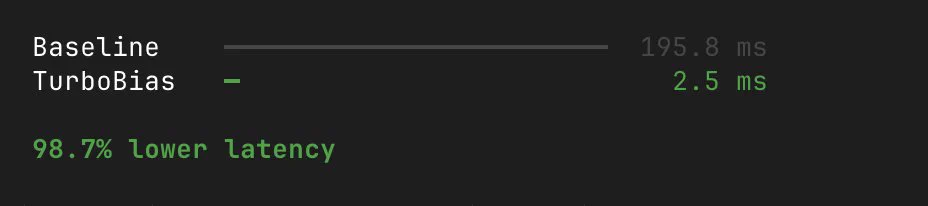
• 20-200x faster
• 40-400x
with astra and fable, it's actually the best time to make crazy advances in computer science stuff. you can just point astra at a paper and implement things