<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://cogito233.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://cogito233.github.io/" rel="alternate" type="text/html" /><updated>2026-11-02T14:55:23-08:00</updated><id>https://cogito233.github.io/feed.xml</id><title type="html">Zhiheng Lyu</title><subtitle>Yr1 CS PhD student at UIUC, focusing on AI for Software Engineering</subtitle><author><name>Zhiheng Lyu</name><email>zhihenglyu.cs@gmail.com</email></author><entry><title type="html">Toward Human-in-the-Loop Oversight for Long-Horizon Agent Projects</title><link href="https://cogito233.github.io/blog/human-in-the-loop-oversight/" rel="alternate" type="text/html" title="Toward Human-in-the-Loop Oversight for Long-Horizon Agent Projects" /><published>2026-10-31T00:00:00-07:00</published><updated>2026-10-31T00:00:00-07:00</updated><id>https://cogito233.github.io/blog/human-in-the-loop-oversight</id><content type="html" xml:base="https://cogito233.github.io/blog/human-in-the-loop-oversight/"><![CDATA[<style>
.post-figure img { max-width: 560px; width: 100%; margin-left: auto; margin-right: auto; display: block; }
.state-block pre { padding: 1em 1.2em !important; }
.state-block pre code { font-size: 0.72rem !important; line-height: 1.55; }
.post-repo-link { margin: -0.4em 0 1.2em; font-size: 0.95rem; }
.post-repo-link a { font-weight: 600; }
.install-cmd { margin: 1.2em 0 !important; }
.install-cmd pre { padding: 1em 1.2em !important; white-space: pre-wrap; word-break: break-word; }
.install-cmd pre code { font-size: 0.85rem !important; line-height: 1.6; }
.page__content table { display: table; width: auto; max-width: 100%; font-size: 0.82rem; margin: 1.2em 0; }
.page__content th, .page__content td { padding: 0.45em 0.8em; }
</style>

<div class="lang-switch" role="tablist" aria-label="Language">
  <span class="lang-switch__label">Language / 语言</span>
  <button type="button" class="lang-btn is-active" role="tab" data-lang="en" aria-selected="true">English</button>
  <button type="button" class="lang-btn" role="tab" data-lang="zh" aria-selected="false">中文</button>
</div>

<div class="lang lang-en">

  <h1 id="toward-human-in-the-loop-oversight-for-long-horizon-agent-projects">Toward Human-in-the-Loop Oversight for Long-Horizon Agent Projects</h1>

  <p class="post-repo-link"><a href="https://github.com/cogito233/swarm-oversight-harness"><i class="fab fa-github" aria-hidden="true"></i> cogito233/swarm-oversight-harness</a></p>

  <figure class="post-figure">
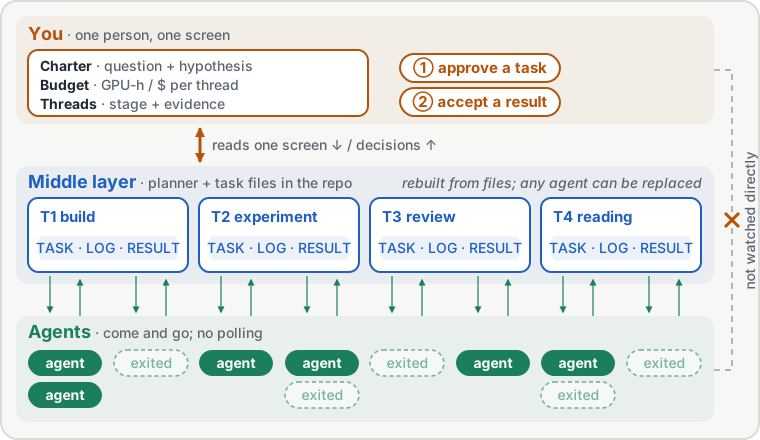
  <img src="https://cogito233.github.io/images/blog/oversight-layers.svg" alt="Three tiers. Top, you: one screen with charter, budget and threads, and two actions, approve a task and accept a result. Middle, a planner and task files in the repo, four task cards each with TASK, LOG and RESULT. Bottom, many short-lived agents, some running and some exited, grouped under the tasks they work on. A two-way arrow links you and the middle layer; many thin arrows link the middle layer and the agents; there is no direct link from you to the agents." loading="lazy" />
  <figcaption>How to read it: you look at one screen and make two kinds of decision. The middle layer turns those decisions into work for many short-lived agents, and turns their output back into that one screen. You do not watch the agents directly.</figcaption>
</figure>

  <p class="contents-line"><strong>Contents:</strong> <a href="#what-the-human-sees">What the human sees</a> · <a href="#why-not-watch-the-agents">Why not watch the agents</a> · <a href="#the-middle-layer">The middle layer</a> · <a href="#making-acceptance-mean-something">Making acceptance mean something</a> · <a href="#related-work-and-limits">Related work and limits</a> · <a href="#try-it">Try it</a></p>

  <p>Multi-agent harnesses are maturing. Runtimes now keep many agents busy in parallel [1], and agent teams share persistent memory and build on each other’s work [5, 7]. As these systems improve, the scarce resource shifts from compute to the attention of the person who oversees them. I ran into this about four months ago in my own research projects and have been working around it since. I assumed this was common knowledge, but after this week’s announcements I am less sure, so I am writing down what I do.</p>

  <p>Running ten agents at once is easy. Overseeing them on one project for three months is not. When I did this on research projects, the bottleneck after a few weeks was knowing what was true in my own project, more than compute or model quality.</p>

  <p>The claim of this post is that <strong>the cost of overseeing a project depends on how many breaks in continuity the human has to reconcile, not on how many agents are running.</strong> The design goal follows from it: keep the project’s history continuous, and keep it in the place that is cheapest for a human to read. The analogy that helped me is the move from procedural to object-oriented programming. An agent session is a procedure call. It has a stack (its context window), does some work, returns a value, and its local state is gone. Most agent setups are procedural in this sense, because the state of the work lives in whichever agent is running. The middle layer makes the task the object instead: it has an identity, state that persists between calls, invariants, and an interface. Agents become methods that act on it, one after another or in parallel, and none of them owns it.</p>

  <p>The rest of the post describes that layer in practice: what I look at, what I decide, and what the layer does for me. I keep three things in my head: the charter, the budget and the list of threads. I act at two points: approving what a task is for, and accepting what it produced. Everything else lives in task files in the repo. A planner agent maintains those files, and worker agents attach to a task, do their part, and exit. I am releasing the method as <a href="https://github.com/cogito233/swarm-oversight-harness">Swarm Oversight Harness</a>.</p>

  <h2 id="what-the-human-sees">1. What the human sees</h2>

  <p>My model of a project fits on one screen and has three parts:</p>

  <ol>
    <li><strong>Charter</strong>: what we are trying to find out, and the hypothesis whose outcome would change our plans.</li>
    <li><strong>Budget</strong>: how much compute and money each thread may spend before it has to come back and ask.</li>
    <li><strong>Threads</strong>: what each line of work is doing, what stage it has <em>verifiably</em> reached, and what it is waiting for.</li>
  </ol>

  <p>An illustrative example (not a real project):</p>

  <div class="language-plaintext state-block highlighter-rouge"><div class="highlight"><pre class="highlight"><code>CHARTER  Can a 7B model learn to check its own patches with repo tests?
         H1: training on fail→pass test pairs adds ≥10 points of
             self-check accuracy on held-out repos.
         Kill if the 200-task pilot gains &lt; 3 points.
BUDGET   2,000 GPU-h + $1,500 API in total. Over a thread's cap → ask.

STATE    critical path: T2 pilot result
  T1 build    fail→pass pipeline    verified, CI #41    40/100 GPU-h   → accept gate
  T2 run      SFT pilot, 200 tasks  launched, no agent  310/400 GPU-h  → done hook
  T3 review   red-team T1 leakage   running             $90/$200
  T4 read     related-work map      draft               $15/$50
</code></pre></div>  </div>

  <p>I make two kinds of decision from this screen:</p>

  <ul>
    <li><strong>Approve a task</strong> that the planner has drafted: what it is for, what counts as done, and how much it may spend.</li>
    <li><strong>Accept a result</strong>: once accepted, the result is no longer a draft, and other work can build on it.</li>
  </ul>

  <p>Everything below this screen is written for agents. I open a task’s files only when I need them for one of these two decisions. The budget is part of what a task is authorized to do, so an agent that would go over its thread’s cap stops and asks instead of retrying.</p>

  <h2 id="why-not-watch-the-agents">2. Why not watch the agents directly</h2>

  <p><strong>Attention does not scale.</strong> DeepSeek’s Super-agent design makes the same point: today’s agents cap single-task performance at model capability and multi-task performance at human attention [1]. In my runs the ceiling was three to five sessions.</p>

  <p><strong>Projects lose continuity.</strong> How hard a project is to understand depends less on its size than on its continuity: one name for each thing, one version of each fact, and a record that reads in order. Every break makes the reader notice a discrepancy, decide which side is right, and remember the decision. Months of procedural agent work, where each session carries the state and then disappears, produce such breaks without ever raising an error. These are real incidents from my projects, lightly anonymized:</p>

  <table>
    <thead>
      <tr>
        <th>Break</th>
        <th>What happened</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>Time</td>
        <td>A retry passed and the earlier failure disappeared from the log.</td>
      </tr>
      <tr>
        <td>Names</td>
        <td>“Arms A–D launched.” Two weeks later nobody knew what arm C was.</td>
      </tr>
      <tr>
        <td>Meaning</td>
        <td>“Done” covered six different facts, from <em>edited</em> to <em>accepted</em>.</td>
      </tr>
      <tr>
        <td>Meaning</td>
        <td>Missing judge verdicts were filled in as “fail”: a cell read −0.388; the true value was about +0.07.</td>
      </tr>
      <tr>
        <td>Versions</td>
        <td>Two docs described the same plan differently; agents followed different ones.</td>
      </tr>
      <tr>
        <td>Authority</td>
        <td>One agent’s “next step: scale up” was read by the next agent as an instruction.</td>
      </tr>
    </tbody>
  </table>

  <p>Each break was small, but together they meant I had to re-read the project every morning. Watching more agents would only have added more breaks, because each new session is one more place where state can live and then disappear.</p>

  <h2 id="the-middle-layer">3. The middle layer</h2>

  <h3 id="agents-are-procedures-tasks-are-objects">Agents are procedures; tasks are objects</h3>

  <p>A single agent is easy to follow because it has one linear history that you can read in order. That history is lost when the call returns, that is, when the context window ends. A hand-built pipeline is worse, because its history is spread across stages and no single file says what happened in order.</p>

  <p>The middle layer keeps a linear history but stores it in the task instead of the agent. The programming analogy maps directly:</p>

  <table class="analogy-table">
    <thead>
      <tr>
        <th>Programming</th>
        <th>Agent project</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>procedure call</td>
        <td>one agent session</td>
      </tr>
      <tr>
        <td>call stack, local variables</td>
        <td>the context window</td>
      </tr>
      <tr>
        <td>return value</td>
        <td>the summary an agent hands back</td>
      </tr>
      <tr>
        <td>object identity</td>
        <td>the task id (<code class="language-plaintext highlighter-rouge">T2</code>)</td>
      </tr>
      <tr>
        <td>object state</td>
        <td><code class="language-plaintext highlighter-rouge">TASK.md</code>, the <code class="language-plaintext highlighter-rouge">LOG</code>, the <code class="language-plaintext highlighter-rouge">RESULT</code>s</td>
      </tr>
      <tr>
        <td>invariants</td>
        <td>acceptance criteria, authorization, budget</td>
      </tr>
      <tr>
        <td>methods</td>
        <td>agents that attach, act and exit</td>
      </tr>
      <tr>
        <td>public interface</td>
        <td>the task’s row in <code class="language-plaintext highlighter-rouge">STATE</code></td>
      </tr>
    </tbody>
  </table>

  <p>The analogy has one important limit. An ordinary object overwrites its fields, but a task never rewrites its LOG, so it is closer to an object whose state is rebuilt from an event log. That is what keeps the history readable in order. Concretely, a task is a small, durable object in the repo:</p>

  <ul>
    <li><code class="language-plaintext highlighter-rouge">TASK.md</code>: goal, files it may and must not touch, the authorization and budget it runs under, acceptance criteria with how each is checked, stop conditions;</li>
    <li>a <code class="language-plaintext highlighter-rouge">LOG</code> that is only ever appended to, with a snapshot of the current state at the top;</li>
    <li><code class="language-plaintext highlighter-rouge">RESULT</code> files with evidence;</li>
    <li>one row in <code class="language-plaintext highlighter-rouge">STATE</code>, which is the screen in section 1.</li>
  </ul>

  <figure class="post-figure">
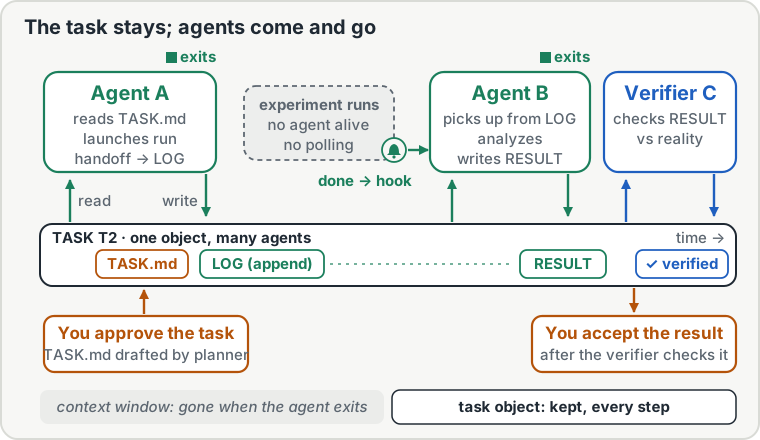
  <img src="https://cogito233.github.io/images/blog/task-timeline.svg" alt="A bar labelled task T2 runs left to right and accumulates TASK.md, an append-only LOG and a RESULT. Above it, agent A launches an experiment and exits; a gap where the experiment runs with no agent alive and no polling, ending in a completion hook; agent B picks up, analyzes and writes the result; verifier C checks it. Below the bar: at the start the human approves the TASK.md the planner drafted; at the end the human accepts the result after the verifier has checked it." loading="lazy" />
  <figcaption>How to read it: the bar is one task and it never stops; the boxes above are agents and they come and go. While the experiment runs, no agent is alive. The human touches the task only at the start and the end.</figcaption>
</figure>

  <p>One habit follows: an agent that launches a long experiment exits instead of polling. Before it exits, it appends a handoff to the task’s LOG: what was launched, where the outputs will appear, and how to check them. A completion hook or marker file signals the end of the run, and a new agent picks up the task. Polling would spend context on waiting, and the only record of what is pending would sit in a context that will be compacted.</p>

  <h3 id="the-planner">The planner</h3>

  <p>A planner agent maintains the layer. Each round it re-reads the repo and fixes STATE wherever it disagrees with reality. It then names one critical path, splits work into tasks that touch different files, dispatches workers, has their results verified, and consolidates everything into one STATE update. I never merge N results by hand; if I find myself doing it, the layer is broken. One rule decides whether the planner keeps going or comes back to me: <strong>retry HOW problems, stop on WHAT problems.</strong> A failing test is a HOW problem and is retried within budget. A plan that contradicts reality, or a budget about to be exceeded, is a WHAT problem and is escalated to me.</p>

  <h3 id="handing-a-task-to-an-agent-through-files">Handing a task to an agent through files</h3>

  <p>The default way to delegate is to write the task into a subagent’s prompt and read back its summary. Over weeks, this breaks down. The task exists only in the parent agent’s context. The result is only the worker’s account. The parent has to merge N summaries. Failed attempts leave no record. In the middle layer the prompt is only a pointer, <em>“do threads/T2/tasks/TASK-03.md”</em>, and the result comes back as a file.</p>

  <table>
    <thead>
      <tr>
        <th> </th>
        <th>Prompt subagent</th>
        <th>Ticket runtime [1]</th>
        <th>Task files</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>Task lives in</td>
        <td>parent’s context</td>
        <td>runtime database</td>
        <td><code class="language-plaintext highlighter-rouge">TASK.md</code></td>
      </tr>
      <tr>
        <td>Comes back as</td>
        <td>summary</td>
        <td>thread reply</td>
        <td><code class="language-plaintext highlighter-rouge">RESULT.md</code> + evidence</td>
      </tr>
      <tr>
        <td>Survives restart</td>
        <td>no</td>
        <td>yes</td>
        <td>yes</td>
      </tr>
      <tr>
        <td>Who can resume</td>
        <td>that parent</td>
        <td>runtime executors</td>
        <td>any agent</td>
      </tr>
      <tr>
        <td>Authorization</td>
        <td>the prompt</td>
        <td>enforced in code</td>
        <td>written down, not enforced</td>
      </tr>
      <tr>
        <td>Failed attempts</td>
        <td>lost</td>
        <td>ticket history</td>
        <td>LOG, old RESULTs</td>
      </tr>
    </tbody>
  </table>

  <h3 id="which-memory-to-trust-and-which-to-clean-up">Which memory to trust and which to clean up</h3>

  <p>Moving memory into files only helps if the files stay trustworthy; otherwise the breaks in section 2 move into the repo. Not everything in the repo is equally valid, so each piece of memory is assigned to one of four kinds:</p>

  <table>
    <thead>
      <tr>
        <th>Kind</th>
        <th>Examples</th>
        <th>Valid as</th>
        <th>Kept by</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>Current</td>
        <td><code class="language-plaintext highlighter-rouge">STATE</code>, <code class="language-plaintext highlighter-rouge">CHARTER</code>, open <code class="language-plaintext highlighter-rouge">TASK.md</code></td>
        <td>what is true now</td>
        <td>overwritten; checked against reality every round</td>
      </tr>
      <tr>
        <td>History</td>
        <td><code class="language-plaintext highlighter-rouge">LOG</code> entries, old <code class="language-plaintext highlighter-rouge">RESULT</code>s, <code class="language-plaintext highlighter-rouge">DECISIONS</code></td>
        <td>what happened</td>
        <td>append-only; never edited</td>
      </tr>
      <tr>
        <td>Stale</td>
        <td>a doc older than the code it describes; a superseded plan</td>
        <td>nothing until re-checked</td>
        <td>marked stale, not silently trusted</td>
      </tr>
      <tr>
        <td>Disposable</td>
        <td>scratch files, an agent’s context, unaccepted drafts</td>
        <td>nothing</td>
        <td>deleted freely</td>
      </tr>
    </tbody>
  </table>

  <p>The planner does the cleanup at the start of each round. It compares STATE with git, tests and outputs. Every current doc records when it was last checked and which files it covers. If any of those files has changed since, the doc is marked stale until someone re-checks it. Superseded plans are not deleted; they move to history with a pointer to what replaced them. Anything that exists only in an agent’s context is treated as gone, because the agent will exit.</p>

  <p>Three rules keep memory readable. Each thing has one name, based on its content (“the 4k-context ablation” rather than “arm C”). Each headline number is stored once and linked from elsewhere. Nothing is deleted to make the record look cleaner.</p>

  <h2 id="making-acceptance-mean-something">4. Making acceptance mean something</h2>

  <p>Acceptance is the one place my judgment enters the record, so it has to mean something. In research the output is a belief, and unlike a bad merge, a wrong belief raises no error. Agents that grade their own progress systematically accept non-improvements. Park and Choi show that a separate judge is not enough on its own: a strong judge that read the diff and the worker’s report still accepted cycles, and 44% of the cycles it accepted were real regressions [2]. What helped was externally grounded verification. In the middle layer this becomes three rules:</p>

  <ul>
    <li><strong>The verifier re-runs checks.</strong> For each acceptance criterion it runs the check named in the task and compares the result with what was claimed.</li>
    <li><strong>Six facts are reported separately</strong>: edited, committed, launched, ran OK, verified, accepted. Anything without evidence is recorded as <code class="language-plaintext highlighter-rouge">unknown</code>.</li>
    <li><strong>Dead ends are recorded.</strong> A hypothesis that was killed goes into the decision log with its reason, so later agents do not try it again.</li>
  </ul>

  <h2 id="related-work-and-limits">5. Related work and limits</h2>

  <p>Anthropic’s long-running harness already treats the environment as memory: a progress file and git history let one agent resume a project across context windows [3]. Agensh makes tasks claimable objects in a shared workspace and scales a decentralized team to 1,024 agents [5]. Evolving Agent Teams keeps a persistent learnings file so a supervisor can restructure teams that stall [4]. GitSwarm lets homogeneous agents compound each other’s intermediate work through shared persistent memory [7]. None of them separates who verifies a result from who decides that it counts. That separation is the human-facing part this post adds.</p>

  <ul>
    <li><strong>Not a runtime.</strong> There is no scheduler and no daemon. For an always-on agent that takes requests from a team’s chat and GitHub, see DeepSeek’s Super-agent prototype [1].</li>
    <li><strong>No enforcement.</strong> The rules hold only because agents read and follow them. Enforcement at the execution layer is a separate job, handled by tools such as agentsh [6].</li>
    <li><strong>Not for chores.</strong> If you already know the answer and there is one result to merge, ask the agent directly.</li>
    <li><strong>One person’s practice.</strong> This is based on about four months of my own research projects. It is not a controlled study, the incidents are mine, and the example in section 1 is illustrative. It may not transfer to teams, to work where actions cannot be undone, or to projects where the hard part is waiting on other people.</li>
  </ul>

  <h2 id="try-it">Try it</h2>

  <p>Paste this into Claude Code or Codex:</p>

  <div class="language-plaintext install-cmd highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Install Swarm Oversight Harness from https://github.com/cogito233/swarm-oversight-harness — follow its INSTALL.md.
</code></pre></div>  </div>

  <p>Then say <code class="language-plaintext highlighter-rouge">set up swarm oversight in this repo</code>.</p>

  <p>Feedback and issues are welcome on <a href="https://github.com/cogito233/swarm-oversight-harness/issues">GitHub</a>.</p>

  <h2 id="disclaimer">Disclaimer</h2>

  <blockquote>
    <p>This post was drafted, checked against the cited sources, and typeset by an AI coding agent (Claude Code), working with the author in the way described above. The author decided what to write and accepted or rejected each result. Any errors that remain are the author’s.</p>
  </blockquote>

  <h2 id="citation">Citation</h2>

  <p>Cited as:</p>

  <blockquote>
    <p>Lyu, Zhiheng. (Oct 2026). “Toward Human-in-the-Loop Oversight for Long-Horizon Agent Projects”. cogito233.github.io. https://cogito233.github.io/blog/human-in-the-loop-oversight/.</p>
  </blockquote>

  <p>Or</p>

  <div class="cite-box">
    <div class="language-bibtex highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">@article</span><span class="p">{</span><span class="nl">lyu2026oversight</span><span class="p">,</span>
  <span class="na">title</span>   <span class="p">=</span> <span class="s">"Toward Human-in-the-Loop Oversight for Long-Horizon Agent Projects"</span><span class="p">,</span>
  <span class="na">author</span>  <span class="p">=</span> <span class="s">"Lyu, Zhiheng"</span><span class="p">,</span>
  <span class="na">journal</span> <span class="p">=</span> <span class="s">"cogito233.github.io"</span><span class="p">,</span>
  <span class="na">year</span>    <span class="p">=</span> <span class="s">"2026"</span><span class="p">,</span>
  <span class="na">month</span>   <span class="p">=</span> <span class="s">"Oct"</span><span class="p">,</span>
  <span class="na">url</span>     <span class="p">=</span> <span class="s">"https://cogito233.github.io/blog/human-in-the-loop-oversight/"</span>
<span class="p">}</span>
</code></pre></div>    </div>
  </div>

  <h2 id="references">References</h2>

  <div class="references">

    <ol>
      <li>DeepSeek Harness Team. <a href="https://github.com/deepseek-ai/dsh-superagent-prototype">“Exploring Super-agent Design: Towards a More Autonomous Agent System”</a>, with the dsh-superagent research prototype. October 2026.</li>
      <li>H. Park, B. Choi. <a href="https://arxiv.org/abs/2607.25152">“When Do Agent Loops Mistake Stagnation for Progress? Self-Evaluation Bias and Externally Grounded Verification in Long-Running Autonomous LLM Agent Loops.”</a> arXiv preprint arXiv:2607.25152 (2026).</li>
      <li>J. Young (Anthropic). <a href="https://www.anthropic.com/engineering/effective-harnesses-for-long-running-agents">“Effective harnesses for long-running agents.”</a> Engineering blog, November 2025.</li>
      <li>S. Cao, Z. Mao, D. Li, J. E. Gonzalez, I. Stoica. <a href="https://www.alphaxiv.org/abs/2610.36848">“Evolving Agent Teams.”</a> arXiv preprint arXiv:2610.36848 (2026).</li>
      <li>Z. Zhan, T. Song, L. Dong, S. Huang, J. Lian, Y. Xia, F. Wei. <a href="https://arxiv.org/abs/2609.26781">“Agensh: Scaling Organizational Intelligence to 1,024 Agents.”</a> arXiv preprint arXiv:2609.26781 (2026).</li>
      <li><a href="https://github.com/canyonroad/agentsh">“agentsh: execution-layer security for AI agents.”</a> GitHub, 2026.</li>
      <li>V. Shah, A. Samanta, P. Dahal, M. Plekhanov, C.-J. Wu, S. Yih, R. Munos, R. Fergus, J. Foerster, R. Salakhutdinov, S. Arora, J. Weston, A. Courville, A. Goyal. <a href="https://arxiv.org/abs/2610.04862">“GitSwarm: Decentralized Compounding Inference.”</a> arXiv preprint arXiv:2610.04862 (2026).</li>
      <li>Z. Lyu. <a href="https://github.com/cogito233/swarm-oversight-harness">“Swarm Oversight Harness.”</a> GitHub, 2026.</li>
    </ol>

  </div>

</div>

<div class="lang lang-zh" hidden="">

  <h1 id="agent-">面向长周期 Agent 项目的人在回路监督</h1>

  <p class="post-repo-link"><a href="https://github.com/cogito233/swarm-oversight-harness"><i class="fab fa-github" aria-hidden="true"></i> cogito233/swarm-oversight-harness</a></p>

  <figure class="post-figure">
  <img src="https://cogito233.github.io/images/blog/oversight-layers.svg" alt="三层。顶层是你：一屏，包含章程、预算和各条线，以及两个动作：批准任务、验收结果。中间层是 planner 和仓库里的任务文件，四张任务卡，每张都有 TASK、LOG、RESULT。底层是许多短命的 agent，有的在跑、有的已退出，按所服务的任务分组。你和中间层之间是双向箭头；中间层和 agent 之间是许多细箭头；你和 agent 之间没有直接连线。" loading="lazy" />
  <figcaption>读法：你只看一屏，只做两类决定。中间层把这些决定变成许多短命 agent 的工作，再把它们的产出汇回这一屏。你不直接盯着 agent。</figcaption>
</figure>

  <p class="contents-line"><strong>目录：</strong> <a href="#zh-1">人看到什么</a> · <a href="#zh-2">为什么不直接盯 agent</a> · <a href="#zh-3">中间层</a> · <a href="#zh-4">让验收有分量</a> · <a href="#zh-5">相关工作与局限</a> · <a href="#zh-try">试一试</a></p>

  <p>多 agent 的 harness 正在快速成熟：运行时已经能让很多 agent 并行干活 [1]，agent 团队也能共享持久记忆、在彼此的工作上继续推进 [5, 7]。系统越强，稀缺资源就越从算力转到监督者的注意力上。大约四个月前，我在自己的研究项目里碰到了这个问题，之后一直在找办法绕开它。我原以为大家都清楚这一点，看了这周的几条发布后又不太确定了，所以把我的做法写出来。</p>

  <p>同时跑十个 agent 不难，难的是在一个项目上监督它们三个月。我在研究项目上这样做，几周后卡住我的既不是算力，也不是模型能力，而是弄清自己的项目里哪些是真的。</p>

  <p>本文的论点是：<strong>监督一个项目的成本，取决于人需要消解多少处连续性的断裂，而不取决于有多少个 agent 在跑。</strong> 设计目标由此而来：让项目的历史保持连续，并且放在人读起来最省力的地方。对我帮助最大的类比，是编程从面向过程到面向对象的转变。一次 agent 会话就是一次过程调用：它有自己的调用栈（上下文窗口），做完一些事，返回一个值，然后局部状态就没了。大多数 agent 用法在这个意义上都是面向过程的，工作的状态存在当时正在跑的那个 agent 身上。中间层改为让任务成为对象：它有身份，有在多次调用之间保留下来的状态，有不变量，也有对外接口。agent 则成了作用在它上面的方法，可以先后来，也可以并行来，但没有哪个 agent 拥有它。</p>

  <p>下面讲这一层在实践中的样子：我看什么、决定什么，以及这一层替我做了哪些事。我脑子里只装三样东西：一份章程、一份预算和一张各条线的列表。我只在两处出手：批准任务的目标，验收任务的产出。其余内容都在仓库的任务文件里，由一个 planner agent 维护；worker agent 挂到某个任务上，做完自己那部分就退出。这套方法已开源为 <a href="https://github.com/cogito233/swarm-oversight-harness">Swarm Oversight Harness</a>。</p>

  <h2 id="zh-1">1. 人看到什么</h2>

  <p>我对一个项目需要掌握的东西，一屏就装得下，分三部分：</p>

  <ol>
    <li><strong>章程（Charter）</strong>：我们想弄清什么，以及哪个假设的结果会改变我们的计划。</li>
    <li><strong>预算</strong>：每条线在回来请示之前，最多能花多少算力和钱。</li>
    <li><strong>各条线（threads）</strong>：每条工作线在做什么，凭证据走到了哪个阶段，在等什么。</li>
  </ol>

  <p>一个示意例子（不是真实项目）：</p>

  <div class="language-plaintext state-block highlighter-rouge"><div class="highlight"><pre class="highlight"><code>CHARTER  问题：7B 模型能否学会用仓库测试检查自己的 patch？
         H1：用"先失败后通过"的测试对训练，留出仓库上
             自检准确率提升 ≥10 个点。
         终止：200 题 pilot 提升 &lt; 3 个点就放弃。
预算     共 2,000 GPU 小时 + $1,500 API。超出单线上限 → 请示。

STATE    关键路径：T2 pilot 结果
  T1 开发  失败→通过 数据管线  已验证 CI #41   40/100 GPU-h   → 验收闸
  T2 实验  SFT pilot 200 题    已启动 无agent  310/400 GPU-h  → 完成钩子
  T3 审查  T1 泄漏 red-team    进行中          $90/$200
  T4 阅读  相关工作梳理        草稿            $15/$50
</code></pre></div>  </div>

  <p>我从这一屏出发，只做两类决定：</p>

  <ul>
    <li><strong>批准一个任务</strong>（由 planner 起草）：它为了什么，做到什么程度算完，最多能花多少。</li>
    <li><strong>验收一个结果</strong>：验收后它不再是草稿，后续工作会以它为基础。</li>
  </ul>

  <p>这一屏之外的内容都是写给 agent 看的。只有做这两类决定需要时，我才会打开某个任务的文件。预算属于任务授权的一部分，所以 agent 如果要超出本线上限，会停下来请示，不会接着重试。</p>

  <h2 id="zh-2">2. 为什么不直接盯 agent</h2>

  <p><strong>注意力无法扩展。</strong> DeepSeek 的 Super-agent 设计指出，今天的 agent 在单任务上受限于模型能力，在多任务上受限于人的注意力 [1]。我自己的经验是，上限在三到五个会话。</p>

  <p><strong>项目会丢失连续性。</strong> 一个东西难不难懂，主要看它连不连续，跟它有多大关系不大：每个东西只有一个名字，每个事实只有一个版本，记录能按顺序读下来。每一处断裂都要读者先发现不一致，再判断哪边对，最后记住这个判断。几个月面向过程的 agent 工作，也就是每次会话带着状态干完就消失，会在不报任何错的情况下制造出这样的断裂。下面是我自己项目里真实发生过的例子（已脱敏）：</p>

  <table>
    <thead>
      <tr>
        <th>断裂</th>
        <th>发生了什么</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>时间</td>
        <td>重试通过后，之前的失败从日志里消失了。</td>
      </tr>
      <tr>
        <td>命名</td>
        <td>“A–D 臂已启动”。两周后没人知道 C 臂是什么。</td>
      </tr>
      <tr>
        <td>语义</td>
        <td>“完成”一词混指六件事，从”已修改”到”已验收”。</td>
      </tr>
      <tr>
        <td>语义</td>
        <td>缺失的评审判定被当成”失败”填入：某一格读数为 −0.388，真值约 +0.07。</td>
      </tr>
      <tr>
        <td>版本</td>
        <td>两份文档对同一个计划说法不一，agent 各照各的干。</td>
      </tr>
      <tr>
        <td>权限</td>
        <td>一个 agent 的”下一步：扩量”被下一个 agent 当成了指令。</td>
      </tr>
    </tbody>
  </table>

  <p>每处断裂都不大，但累积起来，我每天早上都得把项目从头读一遍。盯的 agent 越多，断裂也越多，因为每多一次会话，就多一个状态可能存在又消失的地方。</p>

  <h2 id="zh-3">3. 中间层</h2>

  <h3 id="agent--1">agent 是过程，任务是对象</h3>

  <p>单个 agent 好理解，因为它只有一条线性历史，可以按顺序读下来。可这条历史会在调用返回时，也就是上下文窗口结束时消失。手工搭的 pipeline 更糟：历史散落在各个阶段，没有一个文件按顺序记下发生了什么。</p>

  <p>中间层保留这条线性历史，只是改存到任务里，不放在 agent 身上。编程上的类比可以直接对应：</p>

  <table class="analogy-table">
    <thead>
      <tr>
        <th>编程</th>
        <th>agent 项目</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>过程调用</td>
        <td>一次 agent 会话</td>
      </tr>
      <tr>
        <td>调用栈、局部变量</td>
        <td>上下文窗口</td>
      </tr>
      <tr>
        <td>返回值</td>
        <td>agent 交回的总结</td>
      </tr>
      <tr>
        <td>对象身份</td>
        <td>任务编号（<code class="language-plaintext highlighter-rouge">T2</code>）</td>
      </tr>
      <tr>
        <td>对象状态</td>
        <td><code class="language-plaintext highlighter-rouge">TASK.md</code>、<code class="language-plaintext highlighter-rouge">LOG</code>、各份 <code class="language-plaintext highlighter-rouge">RESULT</code></td>
      </tr>
      <tr>
        <td>不变量</td>
        <td>验收标准、授权、预算</td>
      </tr>
      <tr>
        <td>方法</td>
        <td>挂上来、做事、退出的 agent</td>
      </tr>
      <tr>
        <td>对外接口</td>
        <td>任务在 <code class="language-plaintext highlighter-rouge">STATE</code> 里的那一行</td>
      </tr>
    </tbody>
  </table>

  <p>这个类比有一处重要的不同：普通对象会覆盖自己的字段，而任务从不改写自己的 LOG，所以它更像一个由事件日志重建状态的对象。正是这一点让历史能按顺序读下来。具体来说，任务是仓库里一个小而持久的对象，包括：</p>

  <ul>
    <li><code class="language-plaintext highlighter-rouge">TASK.md</code>：目标，可以改和不能改的文件，所依据的授权和预算，验收标准及每条的验证方法，停止条件；</li>
    <li>一份只追加的 <code class="language-plaintext highlighter-rouge">LOG</code>，顶部有当前状态的快照；</li>
    <li>带证据的 <code class="language-plaintext highlighter-rouge">RESULT</code> 文件；</li>
    <li><code class="language-plaintext highlighter-rouge">STATE</code> 里的一行，即第 1 节那一屏上的一行。</li>
  </ul>

  <figure class="post-figure">
  <img src="https://cogito233.github.io/images/blog/task-timeline.svg" alt="一条横条代表任务 T2，从左到右延伸，逐渐积累 TASK.md、只追加的 LOG 和 RESULT。上方：agent A 挂上实验后退出；中间一段实验在跑，没有任何 agent 存活，也不轮询，结束时触发完成钩子；agent B 接手、分析、写结果；验证者 C 检查结果。横条下方：起点是人批准 planner 起草的 TASK.md；终点是验证者检查之后，人验收结果。" loading="lazy" />
  <figcaption>读法：横条是一个任务，它从不中断；上面的方框是 agent，来了又走。实验在跑的时候，一个 agent 都不在。人只在开头和结尾碰这个任务。</figcaption>
</figure>

  <p>由此有了一个习惯：agent 启动长实验后直接退出，不轮询。退出前，它往任务的 LOG 里追加一段交接：启动了什么、产物会出现在哪、怎么检查。实验结束时，完成钩子或标记文件发出信号，由新的 agent 接手这个任务。轮询只会把上下文浪费在等待上，还会让”我们在等什么”只记在一个迟早会被压缩的上下文里。</p>

  <h3 id="planner">Planner</h3>

  <p>中间层由一个 planner agent 维护。每一轮，它先重读仓库，把 STATE 里和现实不符的地方改过来。接着它确定关键路径，把工作拆成互不碰同一文件的任务派给 worker，安排验证结果，最后把所有结果汇总成一次 STATE 更新。我从不亲手合并 N 份结果，如果发现自己在这么做，就说明这一层出了问题。它是继续做还是回来找我，只看一条规则：HOW 问题尽力去试，WHAT 问题立刻停下。测试失败是 HOW 问题，在预算内重试；计划和现实矛盾，或者预算即将超出，是 WHAT 问题，要上报。</p>

  <h3 id="agent-prompt">把任务交给 agent：用文档代替 prompt</h3>

  <p>默认的委派方式是把任务写进 subagent 的 prompt，再读它交回的总结。用上几周，这种方式就会出问题：任务只存在于父 agent 的上下文里，结果只是 worker 的自述，N 份总结要在一个脑子里合并，失败的尝试也不留记录。在中间层里，prompt 只是一个指针（<em>“去做 threads/T2/tasks/TASK-03.md”</em>），结果以文件形式返回。</p>

  <table>
    <thead>
      <tr>
        <th> </th>
        <th>prompt 子 agent</th>
        <th>工单式运行时 [1]</th>
        <th>任务文件</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>任务存在哪</td>
        <td>父 agent 上下文</td>
        <td>运行时数据库</td>
        <td><code class="language-plaintext highlighter-rouge">TASK.md</code></td>
      </tr>
      <tr>
        <td>以什么形式返回</td>
        <td>总结</td>
        <td>原对话回复</td>
        <td><code class="language-plaintext highlighter-rouge">RESULT.md</code> + 证据</td>
      </tr>
      <tr>
        <td>重启后还在</td>
        <td>否</td>
        <td>是</td>
        <td>是</td>
      </tr>
      <tr>
        <td>谁能接手</td>
        <td>那个父 agent</td>
        <td>运行时执行器</td>
        <td>任何 agent</td>
      </tr>
      <tr>
        <td>授权</td>
        <td>prompt 本身</td>
        <td>代码强制</td>
        <td>写明，但不强制</td>
      </tr>
      <tr>
        <td>失败的尝试</td>
        <td>丢失</td>
        <td>工单历史</td>
        <td>LOG、旧 RESULT</td>
      </tr>
    </tbody>
  </table>

  <h3 id="section">记忆：哪些可信，哪些要清理</h3>

  <p>把记忆搬进文件，前提是文件本身可信，否则第 2 节那些断裂只是换到了仓库里。仓库里的内容可信程度不一，每份记忆都属于下面四类之一：</p>

  <table>
    <thead>
      <tr>
        <th>类别</th>
        <th>例子</th>
        <th>能说明什么</th>
        <th>怎么维护</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td>当前</td>
        <td><code class="language-plaintext highlighter-rouge">STATE</code>、<code class="language-plaintext highlighter-rouge">CHARTER</code>、进行中的 <code class="language-plaintext highlighter-rouge">TASK.md</code></td>
        <td>现在什么是真的</td>
        <td>直接覆盖；每轮对照现实核一遍</td>
      </tr>
      <tr>
        <td>历史</td>
        <td><code class="language-plaintext highlighter-rouge">LOG</code> 条目、旧 <code class="language-plaintext highlighter-rouge">RESULT</code>、<code class="language-plaintext highlighter-rouge">DECISIONS</code></td>
        <td>发生过什么</td>
        <td>只追加，从不修改</td>
      </tr>
      <tr>
        <td>过期</td>
        <td>比它描述的代码更旧的文档；被取代的计划</td>
        <td>重新核对前一概不算</td>
        <td>标为过期，不再默认可信</td>
      </tr>
      <tr>
        <td>可丢弃</td>
        <td>草稿文件、agent 的上下文、未验收的草稿</td>
        <td>什么都不算</td>
        <td>随时删除</td>
      </tr>
    </tbody>
  </table>

  <p>清理由 planner 在每轮开始时完成：它把 STATE 和 git、测试、产物逐一对照，以现实为准。每份”当前”文档都记下上次核对的时间和它覆盖的文件；之后其中任一文件有改动，这份文档就标为过期，直到有人重新核对。被取代的计划不删，移进历史并注明被什么取代。只存在于 agent 上下文里的东西一律当作已经丢失，因为那个 agent 会退出。</p>

  <p>有三条命名规则让记忆保持可读：一个东西只用一个名字，并按内容命名（叫”4k 上下文消融”，不叫”C 臂”）；一个事实只放一处，每个关键数字只存一份，别处用链接；不为了让记录好看而删除任何内容。</p>

  <h2 id="zh-4">4. 让验收有分量</h2>

  <p>我的判断只在验收这一步进入记录，所以验收必须有分量。研究产出的是信念，跟合并代码不同，信念错了不会报错。如果让 agent 自己评估进展，它会系统性地把没有带来改进的改动当成改进。Park 和 Choi 的研究表明，只换一个评审不够：即使是读过 diff 和 worker 报告的强评审，它接受的轮次中仍有 44% 实际上是退步 [2]。有效的做法是以外部事实为依据。在中间层里，这落实为三条规则：</p>

  <ul>
    <li><strong>验证者要重跑，不能只读。</strong> 对每条验收标准，它都运行任务里写明的检查，把实际结果和声称的结果对照。</li>
    <li><strong>六个事实分开报</strong>：修改、提交、启动、运行成功、验证、验收。没有证据的一律写 <code class="language-plaintext highlighter-rouge">unknown</code>。</li>
    <li><strong>死胡同要记下来。</strong> 被推翻的假设连同理由写进决策日志，之后的 agent 就不会再走一遍。</li>
  </ul>

  <h2 id="zh-5">5. 相关工作与局限</h2>

  <p>Anthropic 的长时运行 harness 已经把环境用作记忆，靠一个进度文件和 git 历史，让单个 agent 跨多个上下文窗口持续推进一个项目 [3]。Agensh 把任务做成共享工作区里可认领的对象，把去中心化团队扩展到 1,024 个 agent [5]。Evolving Agent Teams 维护一份持久的经验文件，让 supervisor 能重组停滞的团队 [4]。GitSwarm 让同质的 agent 通过共享的持久记忆，在彼此的中间结果上不断积累 [7]。这些工作都没有把”谁来验证结果”和”谁决定结果算数”分开，本文补的就是这个面向人的部分。</p>

  <ul>
    <li><strong>不是运行时。</strong> 没有调度器，也没有守护进程。如果想要一个常驻、从团队群聊和 GitHub 接收请求的 agent，可以看 DeepSeek 的 Super-agent 原型 [1]。</li>
    <li><strong>只是一套协议。</strong> 规则之所以成立，是因为 agent 读了并遵守。执行层的强制是另一回事，由 agentsh 这类工具负责 [6]。</li>
    <li><strong>不适合杂活。</strong> 如果你已经知道答案，只有一份结果要合并，直接让 agent 去做就行。</li>
    <li><strong>来自一个人的实践。</strong> 这套做法来自我大约四个月的研究项目，没有做对照研究；翻车案例都出自我自己的项目，第 1 节的例子只是示意。它未必适用于团队协作、包含不可撤销操作的工作，或者主要难在等待他人的项目。</li>
  </ul>

  <h2 id="zh-try">试一试</h2>

  <p>把这句贴进 Claude Code 或 Codex：</p>

  <div class="language-plaintext install-cmd highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Install Swarm Oversight Harness from https://github.com/cogito233/swarm-oversight-harness — follow its INSTALL.md.
</code></pre></div>  </div>

  <p>然后说 <code class="language-plaintext highlighter-rouge">set up swarm oversight in this repo</code>。</p>

  <p>欢迎在 <a href="https://github.com/cogito233/swarm-oversight-harness/issues">GitHub</a> 上提 issue 或反馈。</p>

  <h2 id="zh-disclaimer">声明</h2>

  <blockquote>
    <p>本文由 AI coding agent（Claude Code）起草、对照引用来源核对事实并排版，它和作者的协作方式就是上文描述的那样：作者决定写什么，并逐条验收或驳回。经过这个流程后仍然存在的错误，由作者负责。</p>
  </blockquote>

  <h2 id="zh-cite">引用本文</h2>

  <p>引用格式：</p>

  <blockquote>
    <p>Lyu, Zhiheng. (Oct 2026). “Toward Human-in-the-Loop Oversight for Long-Horizon Agent Projects”. cogito233.github.io. https://cogito233.github.io/blog/human-in-the-loop-oversight/.</p>
  </blockquote>

  <p>或</p>

  <div class="cite-box">
    <div class="language-bibtex highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">@article</span><span class="p">{</span><span class="nl">lyu2026oversight</span><span class="p">,</span>
  <span class="na">title</span>   <span class="p">=</span> <span class="s">"Toward Human-in-the-Loop Oversight for Long-Horizon Agent Projects"</span><span class="p">,</span>
  <span class="na">author</span>  <span class="p">=</span> <span class="s">"Lyu, Zhiheng"</span><span class="p">,</span>
  <span class="na">journal</span> <span class="p">=</span> <span class="s">"cogito233.github.io"</span><span class="p">,</span>
  <span class="na">year</span>    <span class="p">=</span> <span class="s">"2026"</span><span class="p">,</span>
  <span class="na">month</span>   <span class="p">=</span> <span class="s">"Oct"</span><span class="p">,</span>
  <span class="na">url</span>     <span class="p">=</span> <span class="s">"https://cogito233.github.io/blog/human-in-the-loop-oversight/"</span>
<span class="p">}</span>
</code></pre></div>    </div>
  </div>

  <h2 id="zh-references">参考文献</h2>

  <div class="references">

    <ol>
      <li>DeepSeek Harness Team. <a href="https://github.com/deepseek-ai/dsh-superagent-prototype">“Exploring Super-agent Design: Towards a More Autonomous Agent System”</a>, 及 dsh-superagent 研究原型。2026 年 10 月。</li>
      <li>H. Park, B. Choi. <a href="https://arxiv.org/abs/2607.25152">“When Do Agent Loops Mistake Stagnation for Progress? Self-Evaluation Bias and Externally Grounded Verification in Long-Running Autonomous LLM Agent Loops.”</a> arXiv preprint arXiv:2607.25152 (2026).</li>
      <li>J. Young (Anthropic). <a href="https://www.anthropic.com/engineering/effective-harnesses-for-long-running-agents">“Effective harnesses for long-running agents.”</a> Engineering blog，2025 年 11 月。</li>
      <li>S. Cao, Z. Mao, D. Li, J. E. Gonzalez, I. Stoica. <a href="https://www.alphaxiv.org/abs/2610.36848">“Evolving Agent Teams.”</a> arXiv preprint arXiv:2610.36848 (2026).</li>
      <li>Z. Zhan, T. Song, L. Dong, S. Huang, J. Lian, Y. Xia, F. Wei. <a href="https://arxiv.org/abs/2609.26781">“Agensh: Scaling Organizational Intelligence to 1,024 Agents.”</a> arXiv preprint arXiv:2609.26781 (2026).</li>
      <li><a href="https://github.com/canyonroad/agentsh">“agentsh: execution-layer security for AI agents.”</a> GitHub, 2026.</li>
      <li>V. Shah, A. Samanta, P. Dahal, M. Plekhanov, C.-J. Wu, S. Yih, R. Munos, R. Fergus, J. Foerster, R. Salakhutdinov, S. Arora, J. Weston, A. Courville, A. Goyal. <a href="https://arxiv.org/abs/2610.04862">“GitSwarm: Decentralized Compounding Inference.”</a> arXiv preprint arXiv:2610.04862 (2026).</li>
      <li>Z. Lyu. <a href="https://github.com/cogito233/swarm-oversight-harness">“Swarm Oversight Harness.”</a> GitHub, 2026.</li>
    </ol>

  </div>

</div>
<script>
(function () {
  var KEY = 'blog-lang';
  function set(l) {
    document.querySelectorAll('.lang').forEach(function (d) { d.hidden = !d.classList.contains('lang-' + l); });
    document.querySelectorAll('.lang-btn').forEach(function (b) {
      var on = b.getAttribute('data-lang') === l;
      b.classList.toggle('is-active', on); b.setAttribute('aria-selected', on ? 'true' : 'false');
    });
    try { localStorage.setItem(KEY, l); } catch (e) {}
  }
  var l = null, h = decodeURIComponent(location.hash.replace('#', ''));
  if (h === 'zh' || h === '中文版' || h.indexOf('zh-') === 0) l = 'zh';
  else if (h === 'en') l = 'en';
  if (!l) { try { l = localStorage.getItem(KEY); } catch (e) {} }
  /* default is always English; no browser-language guessing.
     NOTE: keep block comments here. The compress layout collapses this script
     onto one line, so a // comment would swallow everything after it. */
  if (l !== 'en' && l !== 'zh') l = 'en';
  /* jump menu on the right: built from the visible language block's h2/h3 */
  var toc = document.createElement('nav'); toc.className = 'toc-right'; toc.setAttribute('aria-label', 'Jump to');
  var main = document.getElementById('main'); if (main) main.appendChild(toc);
  var links = [];
  function buildToc(lang) {
    var block = document.querySelector('.lang-' + lang); if (!block) return;
    var hs = block.querySelectorAll('h2, h3'); links = [];
    var html = '<div class="toc-right__title">' + (lang === 'zh' ? '目录' : 'Jump to') + '</div><ol>';
    hs.forEach(function (h) {
      if (!h.id) return;
      var t = h.textContent.replace(/\s+/g, ' ').trim();
      if (/^(Citation|References|引用本文|参考文献)$/.test(t)) return;
      html += '<li class="lvl' + h.tagName[1] + '"><a href="#' + h.id + '">' + t + '</a></li>';
    });
    toc.innerHTML = html + '</ol>';
    links = Array.prototype.slice.call(toc.querySelectorAll('a'));
    links.forEach(function (a) {
      a.addEventListener('click', function (e) {
        var el = document.getElementById(a.getAttribute('href').slice(1)); if (!el) return;
        e.preventDefault();
        window.scrollTo({ top: el.getBoundingClientRect().top + window.scrollY - 24, behavior: 'smooth' });
        if (history.replaceState) history.replaceState(null, '', '#' + el.id);
      });
    });
  }
  function mark() {
    var y = window.scrollY + 120, cur = null;
    links.forEach(function (a) { var el = document.getElementById(a.getAttribute('href').slice(1)); if (el && el.offsetTop <= y) cur = a; });
    links.forEach(function (a) { a.classList.toggle('is-current', a === cur); });
  }
  document.querySelectorAll('.contents-line a[href^="#"]').forEach(function (a) {
    a.addEventListener('click', function (e) {
      var el = document.getElementById(a.getAttribute('href').slice(1)); if (!el) return;
      e.preventDefault(); window.scrollTo({ top: el.getBoundingClientRect().top + window.scrollY - 24, behavior: 'smooth' });
    });
  });
  window.addEventListener('scroll', mark, { passive: true });
  set(l); buildToc(l); mark();
  document.querySelectorAll('.lang-btn').forEach(function (b) {
    b.addEventListener('click', function () { var nl = b.getAttribute('data-lang'); set(nl); buildToc(nl); window.scrollTo({ top: 0 }); mark(); });
  });
})();
</script>]]></content><author><name>Zhiheng Lyu</name><email>zhihenglyu.cs@gmail.com</email></author><category term="agents" /><category term="human-in-the-loop" /><category term="research workflow" /><summary type="html"><![CDATA[The cost of overseeing many agents depends on how many breaks in continuity a human has to reconcile, not on how many agents run. Treat agents as procedures and tasks as objects: keep each task's history in the repo, keep the human's view to one screen, and let agents attach, act and exit.]]></summary></entry><entry><title type="html">How Far Has RSI Gotten in Post-Training?</title><link href="https://cogito233.github.io/blog/three-orders-of-self-improvement/" rel="alternate" type="text/html" title="How Far Has RSI Gotten in Post-Training?" /><published>2026-09-17T00:00:00-07:00</published><updated>2026-09-17T00:00:00-07:00</updated><id>https://cogito233.github.io/blog/three-orders-of-self-improvement</id><content type="html" xml:base="https://cogito233.github.io/blog/three-orders-of-self-improvement/"><![CDATA[<div class="lang-switch" role="tablist" aria-label="Language">
  <span class="lang-switch__label">Language / 语言</span>
  <button type="button" class="lang-btn is-active" role="tab" data-lang="en" aria-selected="true">English</button>
  <button type="button" class="lang-btn" role="tab" data-lang="zh" aria-selected="false">中文</button>
</div>

<div class="lang lang-en">

  <h1 id="how-far-has-rsi-gotten-in-post-training">How Far Has RSI Gotten in Post-Training?</h1>

  <figure class="post-figure">
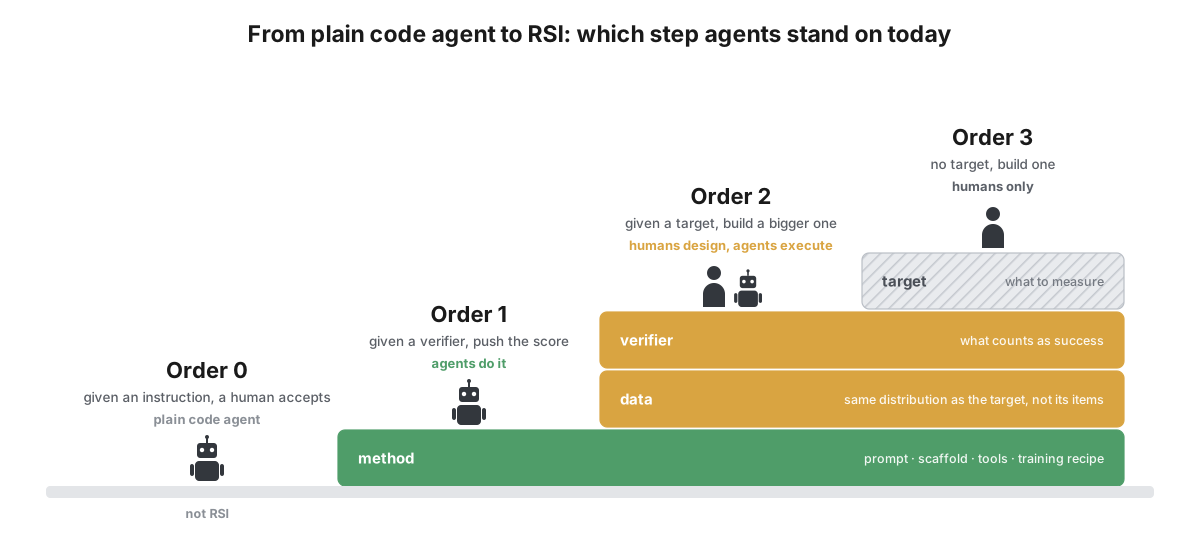
  <img src="https://cogito233.github.io/images/blog/staircase-hero-en.svg" alt="Four columns from left to right: order 0, a robot standing on the ground with no layers; order 1, a robot on one green slab labelled method; order 2, a person and a robot on three slabs, the upper two amber and labelled data and verifier; order 3, a person on four slabs, the top one hatched and labelled target." loading="lazy" />
  <figcaption>Each step is built from the layers the agent takes over, bottom to top: method, data, verifier, target. Order 0 stands on the ground: a plain code agent that changes none of them. Colour is who supplies that layer today: green, agents; amber, human-designed pipelines that agents execute; hatched, humans only.</figcaption>
</figure>

  <p class="contents-line"><strong>Contents:</strong> <a href="#four-orders-one-variable">Four orders, one variable</a> · <a href="#order-0-instruction-in-human-accepts">Order 0</a> · <a href="#order-1-verifier-in-score-up">Order 1</a> · <a href="#order-2-target-in-testbed-out">Order 2</a> · <a href="#order-3-nothing-in-benchmark-out">Order 3</a> · <a href="#open-questions">Open questions</a></p>

  <p>“Self-refine, self-play, self-evolve, self-improving, recursive self-improvement.” In post-training, the same words are used for an agent that rewrites its own prompt, for a model that writes its own training problems, and for the last step before AGI. They describe different amounts of the same thing. <strong>Recursive self-improvement (RSI)</strong>, as used here, is a loop in which an agent’s own output changes the agent that runs the next iteration, and the loop is closed by a verifier rather than by a person.</p>

  <p>One variable separates the versions: <strong>how much of the objective is handed to the agent, and how much it has to supply itself.</strong> Hand it an instruction and it is a code agent. Hand it a verifier and it can climb. Hand it only a capability name and it must build the testbed. Hand it nothing and it must decide what to measure. This post climbs that ladder one step at a time. At each step it describes one or two systems in enough detail to show what the loop does, and asks whether any machine has yet done that step.</p>

  <p>The scope is post-training and the things around it: agent scaffolds, training recipes, data pipelines. RL and SFT optimize against a target with a verifier, so the ladder is defined in those terms. Pretraining is out of scope. Two examples fall outside that scope: AlphaEvolve improves a program rather than model weights, and is included because its loop has the same shape; PaperBench is a benchmark, not an improvement loop, and is included because it measures research replication with a manufactured verifier.</p>

  <h2 id="four-orders-one-variable">Four orders, one variable</h2>

  <p>Take any system that calls itself self-improving and look at what it works with. There are four things, and they stack from the bottom up.</p>

  <ol>
    <li><strong>The method layer</strong> is everything that turns a model into a score on a task: the prompt, the scaffold and tools, the memory, the search strategy, the training recipe. Until recently, this layer was the subject of methodology papers written by people. It is the first layer to have moved to agents, starting in domains such as math and code, where a verifier can check the result.</li>
    <li><strong>The data layer</strong> is the set of task instances the system is trained or evaluated on. Each instance is a concrete problem with everything needed to attempt it: for a bug-fixing task, the repository, the issue text and the environment it runs in.</li>
    <li><strong>The verifier layer</strong> decides, for each task instance, whether an attempt succeeded, without a person in the loop. For bug fixing that is the repository’s own tests passing after the patch; elsewhere it is a wall clock, a validation loss, or a hidden test set.</li>
    <li><strong>The target layer</strong> names what the whole system is measuring: the capability that the tasks and their verifiers are meant to stand for, such as bug fixing, long-horizon tool use or research engineering.</li>
  </ol>

  <p>Now for the one variable. For any such system, ask how many of the four layers the agent supplies itself, counting from the bottom. The answer is always a contiguous block starting at the bottom, and its size gives the four orders.</p>

  <table>
    <thead>
      <tr>
        <th>Order</th>
        <th>The agent is handed</th>
        <th>The agent supplies</th>
        <th>Who closes the loop</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td><strong>0</strong></td>
        <td>An instruction</td>
        <td>A solution to this one task; none of the layers change</td>
        <td>A person, reading the result</td>
      </tr>
      <tr>
        <td><strong>1</strong></td>
        <td>Data, verifier, target</td>
        <td>The method</td>
        <td>The verifier</td>
      </tr>
      <tr>
        <td><strong>2</strong></td>
        <td>The target</td>
        <td>The data and its verifier, then order 1 on them</td>
        <td>The verifier the agent found or built</td>
      </tr>
      <tr>
        <td><strong>3</strong></td>
        <td>Nothing</td>
        <td>All four</td>
        <td>Nothing exists yet</td>
      </tr>
    </tbody>
  </table>

  <p>Each order takes over more of the stack, starting from the bottom. This is the staircase at the top of the post: order 0 stands on the ground and changes no layer, order 1 stands on the method layer, order 2 adds the data and verifier layers together, order 3 adds the target. Data and verifier come as a pair because a task that cannot be graded is not yet a task, which is why the second step is the tall one. The color of each layer shows who supplies it today.</p>

  <p>The ground floor is worth spelling out, because everything else is measured from it. At order 0 the agent supplies none of the four layers. Its method is whatever the code agent shipped with. There is no data layer, because there is no set of tasks, only the one instruction the user typed. There is no verifier, because the user reads the diff and decides. And there is no target, because nothing is being measured. Every result is approved by a person, one at a time, and nothing carries over to the next instruction.</p>

  <p>Three boundaries separate the four orders, and each one is a different kind of step.</p>

  <p><strong>Order 0 to order 1</strong> is where a loop first appears. A plain code agent that reruns failing tests until they pass has a verifier too, so the difference is not whether a verifier exists but what the loop produces. At order 0 the product is the solution to this task; once the tests pass, the loop ends and nothing carries forward. At order 1 the product is the method itself (the agent’s own code, its training script, a kernel), and whatever one iteration improves is where the next one starts. This is where RSI begins, and it is the only boundary that turns a tool into a loop.</p>

  <p><strong>Order 1 to order 2</strong> is a change in what the task set is. At order 1 the set is the benchmark’s published instances and never grows. At order 2 the agent adds legitimate new members to the same set, real or synthetic issues that each come with their own verifier, and then runs order 1 on what it built. The set was always larger than the benchmark, and at order 2 the agent goes out to collect more of it. Almost all of the work lies in finding where each new task’s verifier comes from.</p>

  <p><strong>Order 2 to order 3</strong> is where the demonstration disappears. At order 2 the target is named and the benchmark shows one way to judge it, so the agent only has to add more tasks from the same distribution. At order 3 there is no target and no benchmark to copy, so the agent must first decide what is worth measuring and then do order 2 for it.</p>

  <h2 id="order-0-instruction-in-human-accepts">Order 0: instruction in, human accepts</h2>

  <p>A plain code agent gets a task in natural language, edits files, runs what it can, and returns a diff. Nothing in the setup says what a good result is except the person reading it. When the agent does have a check available, such as a failing test or a compiler, it uses the check to finish this task and then discards it. Cursor, Claude Code, Codex and OpenHands are all this shape by default.</p>

  <p>This is what the tools are designed for, and it matters here only as the control group. Everything an order-0 agent learns about a task dies with the task. No quantity improves across runs, so there is nothing recursive to speak of, however capable the underlying model is. The moment someone adds a persistent metric and lets the agent’s edits carry forward, the same agent becomes an order-1 system. The first case below does exactly this.</p>

  <h2 id="order-1-verifier-in-score-up">Order 1: verifier in, score up</h2>

  <p><strong>Definition.</strong> The agent is handed a task set and a verifier. Its job is to change its own method (its prompt, tools, code, memory or training recipe) so that the verifier’s score goes up, and to keep each change that raises it. The three objective layers above the method stay untouched. Concretely: hand an agent SWE-bench Verified and its test harness, let it edit its own scaffold or its training script, rerun the harness, keep the edit if the resolve rate rose, and repeat until the budget runs out. The 500 tasks never change; only the agent does.</p>

  <p><strong>Why it is hard.</strong> The naive approach is to take the benchmark’s own tasks, distill a few dozen trajectories for each, and fine-tune on them. This does not reach a full score. It yields a modest gain and sometimes loses points, because the distilled trajectories do not follow the paths the model would take on its own, and training on them disrupts behavior the model already had. What works is decomposing tasks and teaching them step by step, or on-policy distillation, in which the student generates its own trajectories and the teacher gives feedback only on the states the student actually reaches. This is the work an order-1 agent takes over: finding a way to raise the score without a person decomposing sub-tasks or tuning the recipe.</p>

  <h3 id="autoresearch">AutoResearch</h3>

  <p>Andrej Karpathy, a founding member of OpenAI and formerly Director of AI at Tesla, writes deliberately small, readable training code: micrograd, nanoGPT, nanochat. <strong>AutoResearch</strong> (<a href="https://github.com/karpathy/autoresearch">Karpathy 2026</a>) points a coding agent at a single-GPU version of nanochat and tells it to improve the model overnight. The agent edits one file, <code class="language-plaintext highlighter-rouge">train.py</code>, trains for five minutes, reads the validation bits-per-byte, and keeps the edit if the number fell or reverts it otherwise, for about a hundred experiments a night. The instructions live in a markdown file written by a person. There is no leaderboard, which is what makes it the cleanest order-1 example: the verifier is a held-out loss, the thing being improved is the training recipe, and each night’s product is a better <code class="language-plaintext highlighter-rouge">train.py</code>.</p>

  <h3 id="rsiagent">RSIAgent</h3>

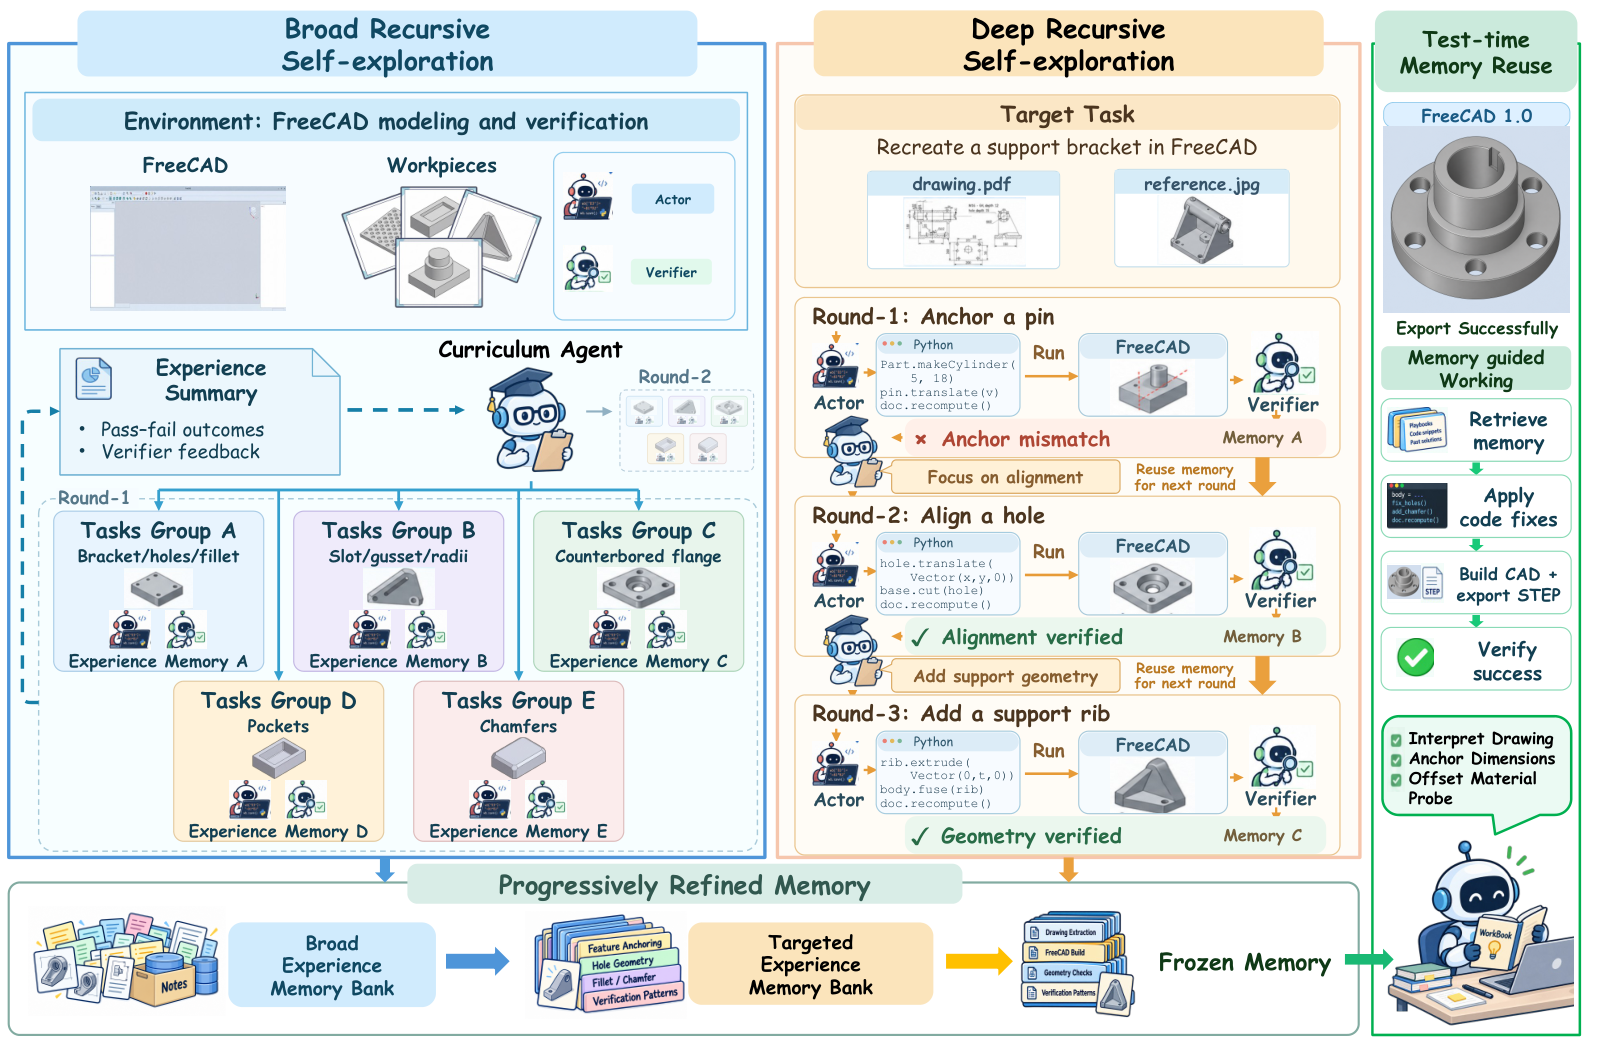
  <p><strong>RSIAgent</strong> (<a href="https://arxiv.org/abs/2609.15364">2026</a>) puts the loop at test time. Before attempting a target task, an actor (GLM-5.3) practices on variants of it proposed by a curriculum agent, a verifier (Kimi-K3) grades each attempt from the environment’s feedback, and what works is written into a memory. The memory is then frozen, and the actor attempts the real task with it.</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/rsiagent-fig2.png" alt="Three panels: broad recursive self-exploration over five FreeCAD practice groups feeding experience memory; deep recursive self-exploration in three rounds against the target task; test-time memory reuse producing the exported CAD part." loading="lazy" />
  <figcaption>RSIAgent on a FreeCAD task: practice across task groups, then rounds against the target, then test-time reuse of the frozen memory. (Image source: <a href="https://arxiv.org/abs/2609.15364">RSIAgent 2026</a>)</figcaption>
</figure>

  <p>The harness raises the partial score from 71.97 to 78.98 on OSWorld 2.0 and from 83.75 to 84.82 on Agents’ Last Exam (ALE). This passes the partial scores reported for GPT-6 Astra, although RSIAgent stays below GPT-6 Astra on ALE’s binary score, 50.75 against 52.24. <em>Why order 1.</em> The tasks and scorers are given. The memory is the method, with one memory per target task, and the practice tasks are scaffolding that never enters a benchmark.</p>

  <h3 id="alphaevolve">AlphaEvolve</h3>

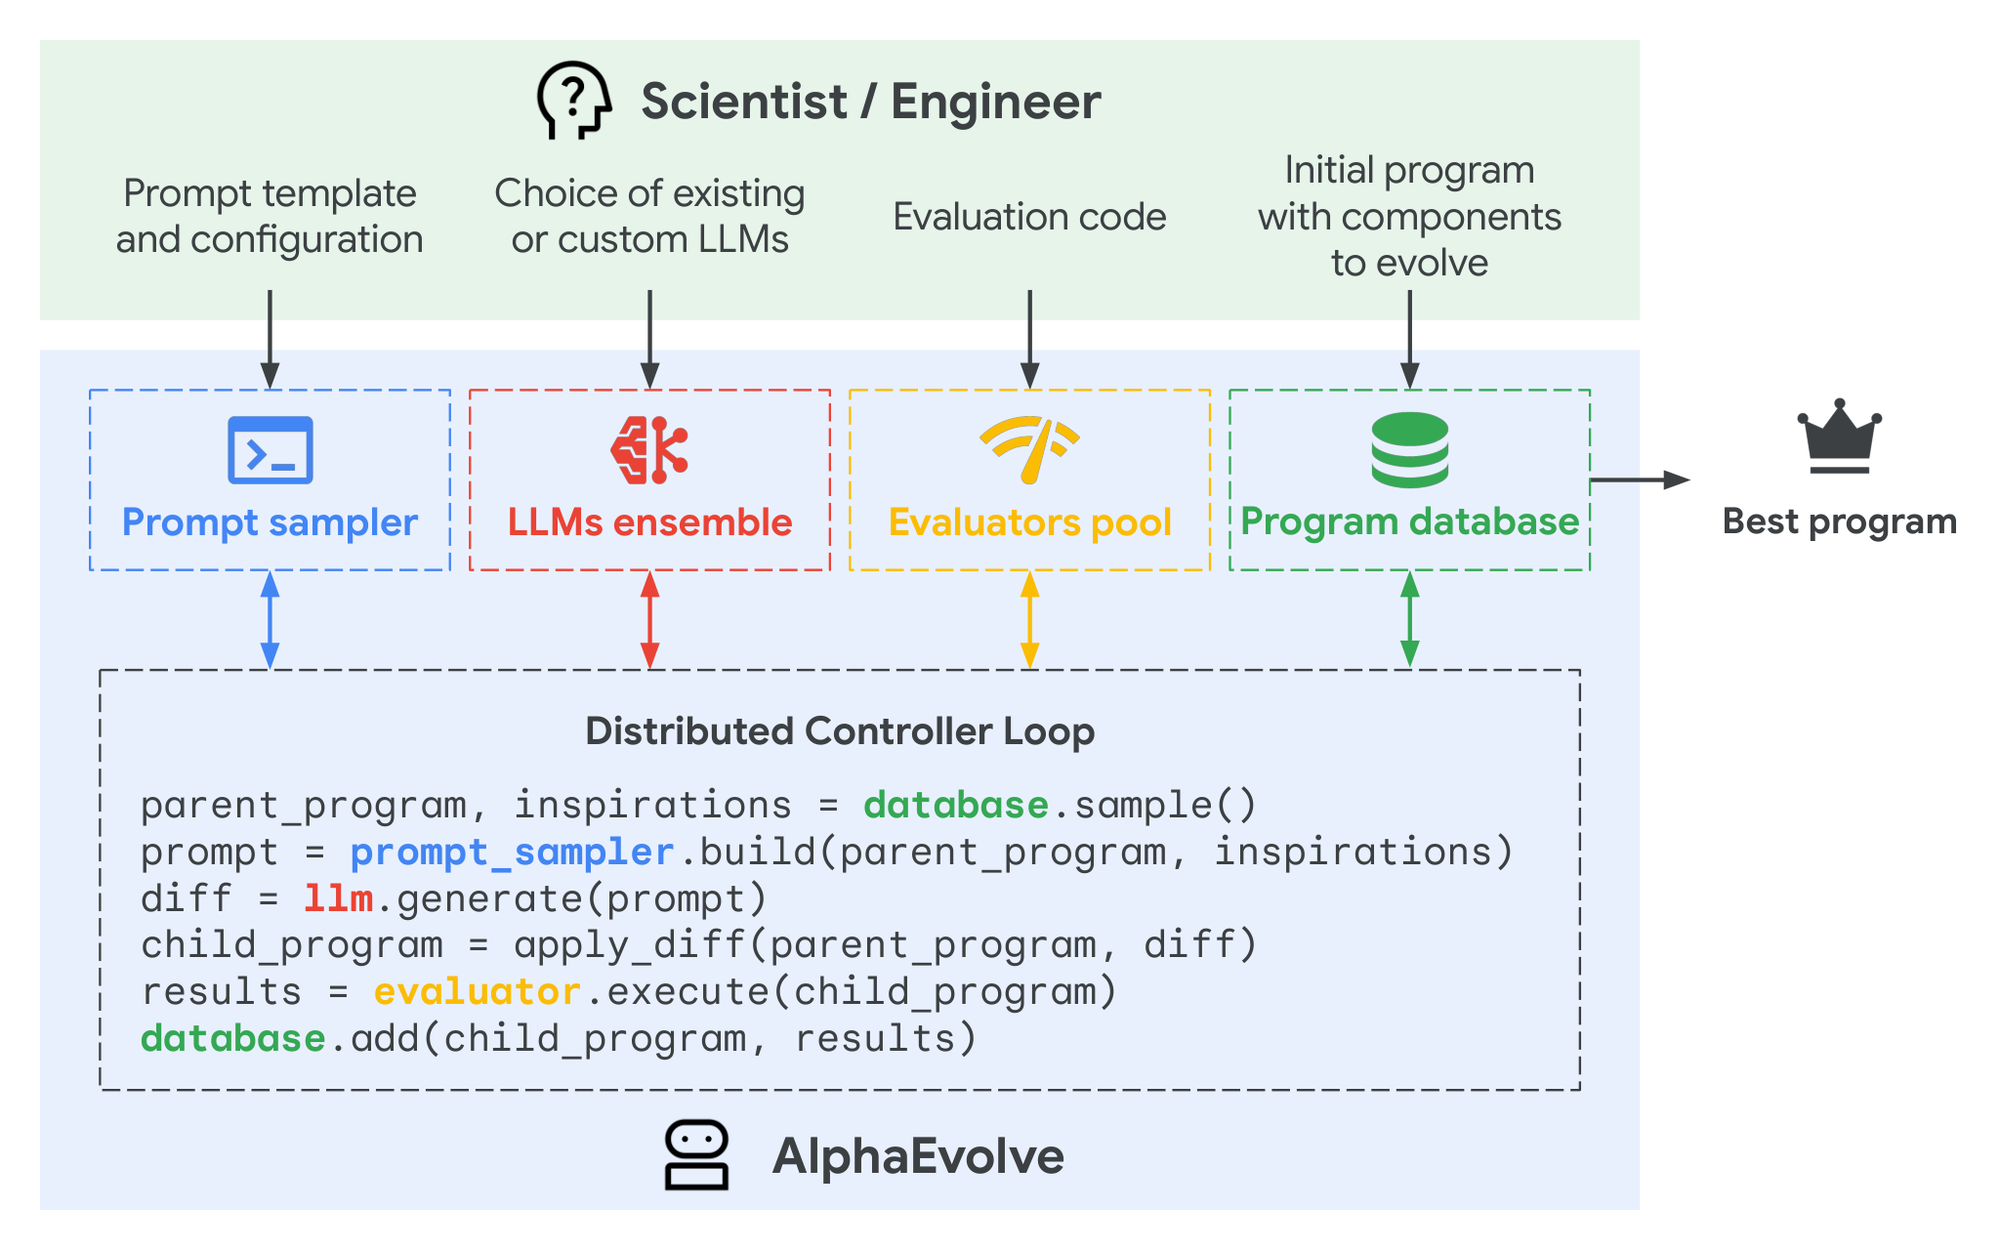
  <p><strong>AlphaEvolve</strong> (<a href="https://arxiv.org/abs/2506.13131">Google DeepMind 2025</a>) runs the loop over a program instead of an agent. The user marks which parts of a program may be evolved and supplies a scoring function; Gemini 2.0 Flash and Pro propose diffs against programs sampled from a database, the evaluators score them, and promising programs go back into the database, which is organized so that diverse lineages survive.</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/alphaevolve-fig2.png" alt="AlphaEvolve loop: user-supplied program and evaluation code enter a program database; a prompt sampler builds prompts, an LLM ensemble proposes diffs, evaluators score the new programs and they return to the database." loading="lazy" />
  <figcaption>The AlphaEvolve loop. The user supplies only the starting program and the scoring function. (Image source: <a href="https://arxiv.org/abs/2506.13131">Novikov et al. 2025</a>)</figcaption>
</figure>

  <p>It found a way to multiply two 4×4 complex matrices in 48 scalar multiplications, improving on Strassen’s 1969 algorithm; a heuristic that speeds up Gemini’s training kernels by 23% on average, cutting training time by 1%; and a scheduling heuristic that recovers 0.7% of Google’s fleet-wide compute. <em>Why order 1.</em> Nothing here touches a model’s weights, but the loop has the same shape. The objective is fixed, the user’s evaluator closes the loop, and the product is a better program that seeds the next round.</p>

  <h3 id="other-order-1-systems-and-how-the-order-is-measured">Other order-1 systems, and how the order is measured</h3>

  <p><strong>Darwin Gödel Machine</strong> (<a href="https://arxiv.org/abs/2505.22954">Zhang et al. 2025</a>) applies the loop to a coding agent’s own code: a repository around a frozen Claude 3.5 Sonnet edits itself, every version is kept in an archive, and a benchmark score decides which version is edited next. Over 80 iterations, its SWE-bench score rose from 20.0% to 50.0% and its Polyglot score from 14.2% to 30.7%. Along the way the agent invented features for itself, such as line-range viewing and string-replacement editing. Each run took about two weeks and cost about USD 22,000. DGM also produced the clearest example of the failure that order 1 invites: one agent scored perfectly on a hallucination check by deleting the logging the check depended on, and the authors’ fix was to hide the checker from the agent.</p>

  <p>Order-1 ability has its own benchmarks. <strong>RE-Bench</strong> (<a href="https://arxiv.org/abs/2411.15114">Wijk et al. 2024</a>) gives agents and human experts seven ML research engineering environments with numeric scores: with a two-hour budget the best agents score four times as high as the humans; at eight hours the humans narrowly pull ahead; and at 32 hours the humans score twice as high. <strong>MLE-bench</strong> (<a href="https://arxiv.org/abs/2410.07095">Chan et al. 2024</a>) uses 75 Kaggle competitions with medal thresholds; the best setup reaches bronze or better in 16.9% of them. <strong>RSI-Exam</strong> (<a href="https://rsi-exam.ai/">2026</a>) has 88 expert-written research tasks scored on hidden data; GPT-6 Astra reaches 0.51 and Opus 5 0.46 on a scale where 0.6 is a frontier-calibrated reference solution.</p>

  <p><strong>How far order 1 has come.</strong> Agents already operate at this order today. Gains on a fixed target can be large from a weak start: DGM went from 20.0% to 50.0% on SWE-bench. From an already-high start they are smaller: RSIAgent adds about 7 points on OSWorld 2.0 (71.97 to 78.98) and about 1 on ALE (83.75 to 84.82). Where the verifier is a wall clock or a loss, agents match or beat human experts on short budgets. This is also the order with the messiest naming: self-improving, self-evolving and RSI are all used for it.</p>

  <h2 id="order-2-target-in-testbed-out">Order 2: target in, testbed out</h2>

  <p><strong>Definition.</strong> Order 1 left the objective alone. Order 2 is what happens when the agent takes over the data layer and, with it, the verifier layer: which tasks are used, and how each one is graded.</p>

  <p>Take SWE-bench Verified. Its definition (a codebase, a failing test, and a patch that makes the test pass) describes a set far larger than the 500 instances it publishes. Every real GitHub issue with that shape belongs to the set, collected or not, and so does every synthetic one that satisfies the same rule. Order 1 only ever searches methods against the 500 that were collected. Order 2 adds new members to the set. These are tasks drawn from the same distribution as the target but not copied from its items. Each one exercises a single nameable, separately testable skill (bug fixing, long-context localization, multi-step tool use) rather than the benchmark as a whole, and each comes with a verifier, so it can be graded whether or not anyone trains on it. Then it applies order 1 to what it built. Concretely: hand an agent the phrase “bug fixing” and the SWE-bench rules, and its job is to go to GitHub, pick repositories, mint issues that have a failing test and a passing patch, and only then train on them.</p>

  <p>The bottleneck is the verifier. Writing a new task is easy; writing one that can be automatically judged is hard. Every order-2 pipeline running at scale today exists because a person first worked out where its verifier would come from. The two systems below are therefore order 2 done by humans and agents together: people designed the pipeline and chose the verifier, and agents execute almost every step. No agent has done order 2 alone; the section ends with the two that have come closest.</p>

  <h3 id="swe-smith">SWE-smith</h3>

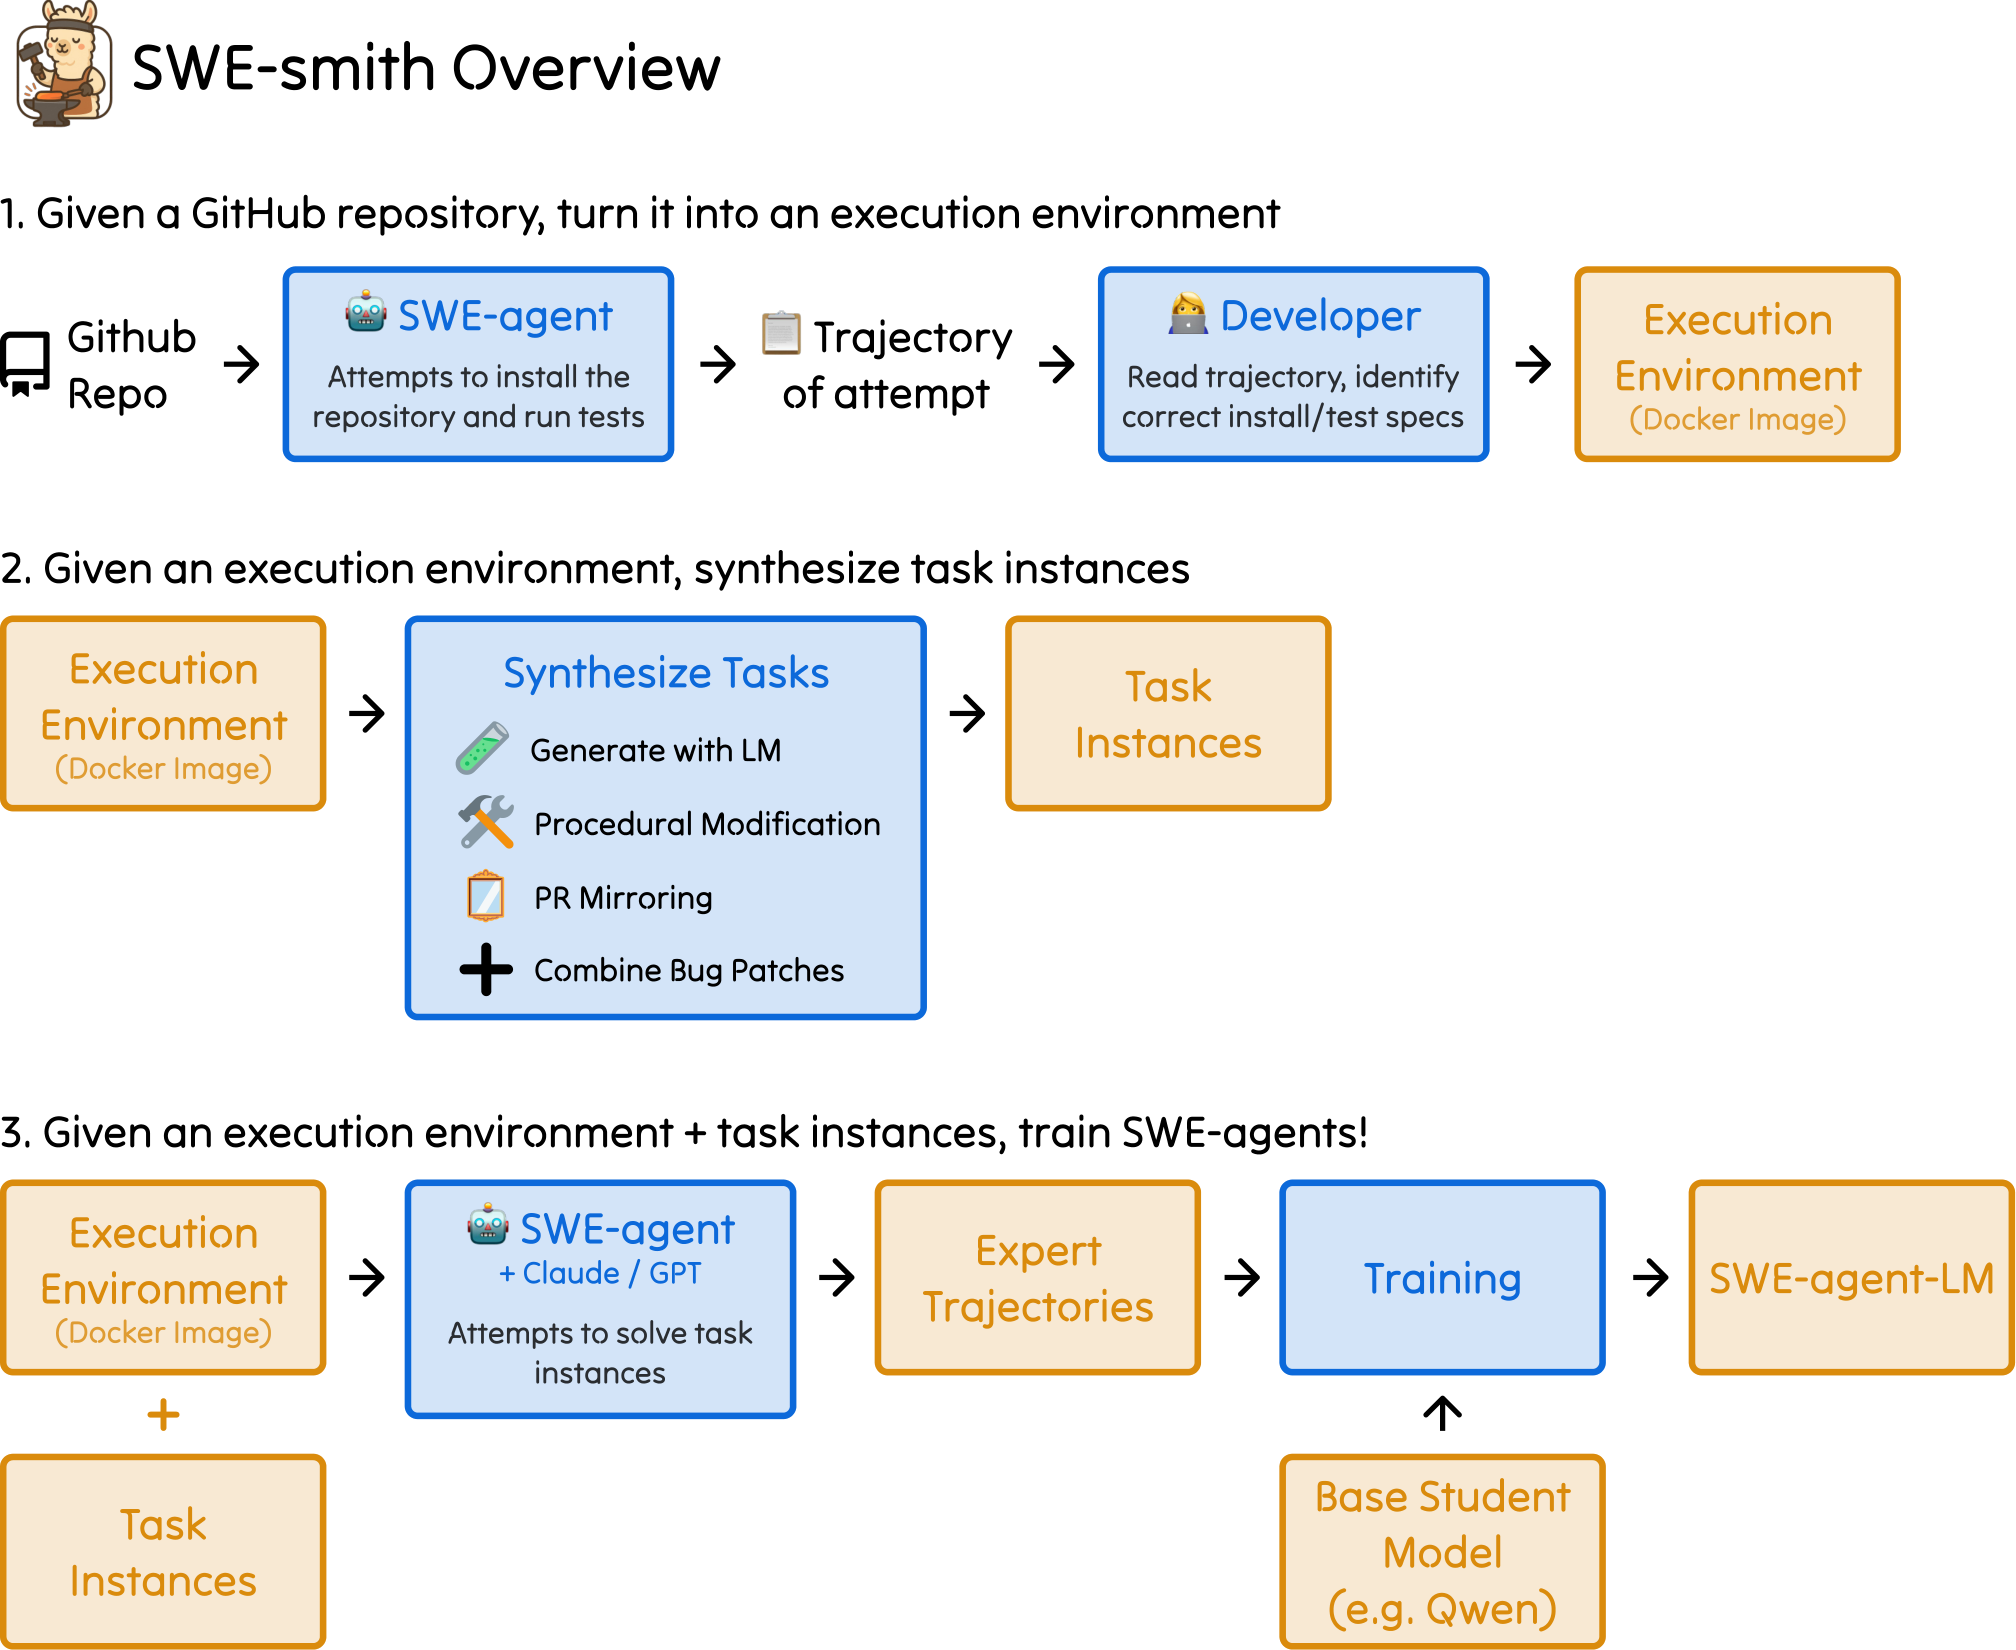
  <p><strong>SWE-smith</strong> (<a href="https://arxiv.org/abs/2504.21798">Yang et al. 2025</a>) turns a Python repository into hundreds to thousands of bug-fixing tasks by breaking code that existing tests already cover. An agent installs the repository, and a person confirms that the tests run. Four strategies then inject bugs, ranging from asking an LM to rewrite a function to reverting a real pull request. A candidate becomes a task only if it breaks a previously passing test, and an LM then writes the issue text from the diff and that test.</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/swe-smith-fig9.png" alt="SWE-smith overview in three rows: turn a GitHub repository into an execution environment with SWE-agent and a developer; synthesize task instances with four strategies; collect expert trajectories and train a student model." loading="lazy" />
  <figcaption>SWE-smith's three stages: build an execution environment, synthesize task instances inside it, train on trajectories collected there. (Image source: <a href="https://arxiv.org/abs/2504.21798">Yang et al. 2025</a>)</figcaption>
</figure>

  <p>Across 128 repositories, this yields 50,137 instances for about USD 1,360. Qwen2.5-Coder-32B, fine-tuned on 5,016 Claude 3.7 Sonnet trajectories collected on them, reaches 40.2% on SWE-bench Verified. <em>Order 2, by humans and agents together.</em> Every instance is a legitimate new member of SWE-bench’s set, and its verifier is borrowed from the repository’s own tests. The division of labor is explicit: the authors decided that repository tests can serve as the verifier, that breaking passing tests creates tasks, and that four strategies are needed; the agents install repositories, write bugs and write issues. Take the agents out and the pipeline stops; take the people out and it never starts.</p>

  <h3 id="swe-universe">SWE-Universe</h3>

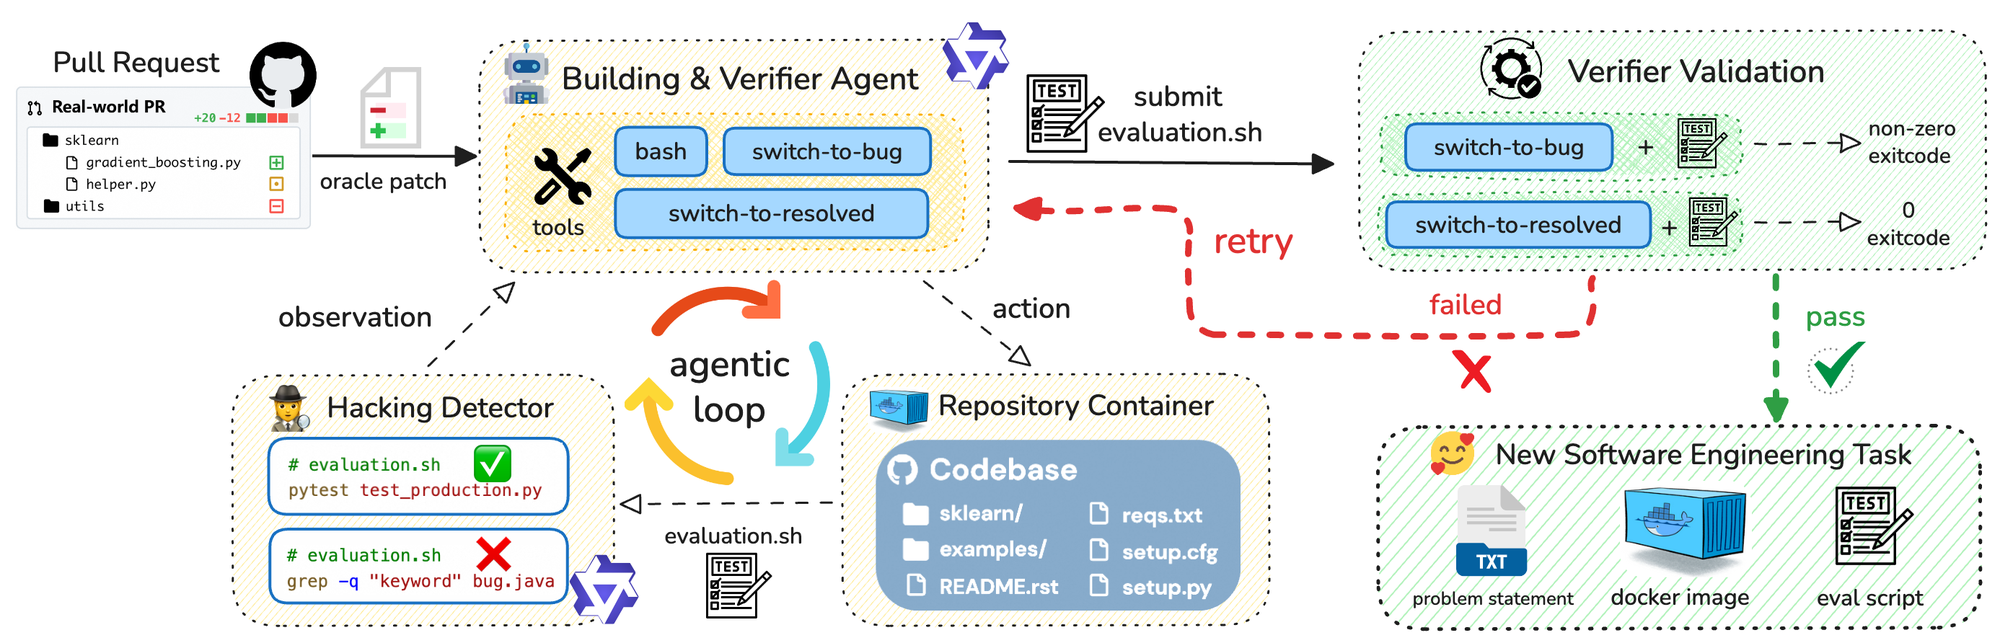
  <p><strong>SWE-Universe</strong> (<a href="https://arxiv.org/abs/2602.02361">Chen et al. 2026</a>) scales the same idea to all of GitHub. Of 33.3 million pull requests, about a million survive filtering. For each one, a building agent is given bash and a switch between the buggy and fixed states of the repository. It installs the project and writes an evaluation script that must fail before the fix and pass after it, while a hacking detector inside the loop rejects scripts that fake the check, for instance by grepping the source files.</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/swe-universe-fig2.png" alt="SWE-Universe pipeline: a building agent proposes an evaluation script, an in-loop hacking detector inspects it, and iterative validation runs it in both the buggy and fixed repository states until it fails on one and passes on the other." loading="lazy" />
  <figcaption>The SWE-Universe builder: an agent proposes the verifier script, a hacking detector inspects it, and validation against both repository states closes the loop. (Image source: <a href="https://arxiv.org/abs/2602.02361">Chen et al. 2026</a>)</figcaption>
</figure>

  <p>The builder is a Qwen-Next-80B-A3B trained by rejection sampling on its own successful, non-hacked runs, and it beats Claude Opus 4.5 on the paper’s building benchmark, 78.4% to 77.8%. The result is 807,693 environments across 52,960 repositories and eight language groups; mid-training on 500,000 trajectories from them takes Qwen3-Next from 50.3% to over 61% on SWE-bench Verified, and the same recipe took Qwen3-Max-Thinking to 75.3%. <em>Order 2, by humans and agents together, with the human share shrinking.</em> The agent now builds the environment and writes the verifier script, and another agent polices hacking. People still supply the frame: PRs as the source, fail-then-pass as the verifier, and a definition of what hacking looks like. As of 2026, agents execute order-2 pipelines, but people still design them.</p>

  <h3 id="agents-that-choose-what-to-make">Agents that choose what to make</h3>

  <p>Two systems hand the agent the decision of what data to generate. <strong>DataEnvGym</strong> (<a href="https://arxiv.org/abs/2410.06215">Khan et al. 2024</a>) sets up a teacher agent that reads a student model’s errors, organized by inferred skill, and decides which skills to generate more data for next; the generation engine, the skill structure and the verifier are fixed parts of the environment. <strong>ANDES</strong> (<a href="https://arxiv.org/abs/2606.01279">2026</a>) has a trainer agent decompose a downstream benchmark into capability domains, route synthesis through a self-expanding tree of contexts, and adjust the next round from a synthesis report. Both hand over the choice of what to make. Neither hands over how to make it or how to judge it, and both operate at scales several orders of magnitude below the human-designed pipelines. No agent has yet been handed SWE-bench Verified and written its own SWE-smith.</p>

  <h3 id="where-verifiers-come-from">Where verifiers come from</h3>

  <p>Inside every order-2 pipeline the verifier comes from one of two places. Either it is <strong>borrowed</strong>: it existed before the pipeline, written by someone else for a different reason, such as the repository tests that <a href="https://arxiv.org/abs/2310.06770">SWE-bench</a>, <a href="https://arxiv.org/abs/2412.21139">SWE-Gym</a> and <a href="https://arxiv.org/abs/2504.21798">SWE-smith</a> run. Or it is <strong>manufactured</strong>: nothing existed, so the pipeline synthesizes one, such as the cross-checked sandboxes of <a href="https://arxiv.org/abs/2601.05808">EnvScaler</a>, the masked reasoning steps turned into multiple choice of <a href="https://arxiv.org/abs/2601.22975">Golden Goose</a>, or the success functions <a href="https://arxiv.org/abs/2405.15568">OMNI-EPIC</a> writes alongside each task. At the top end the two groups differ in scale by two to three orders of magnitude, although the smallest borrowed-verifier sets are no larger than manufactured ones. The borrowed-verifier line for bug fixing alone runs <a href="https://arxiv.org/abs/2412.21139">SWE-Gym</a> at 2,438 tasks, <a href="https://arxiv.org/abs/2504.07164">R2E-Gym</a> at 8,135, <a href="https://arxiv.org/abs/2505.20411">SWE-rebench</a> at 21,000, <a href="https://arxiv.org/abs/2603.13023">daVinci-Env</a> at 45,320 environments and SWE-Universe at 807,693; manufactured-verifier pipelines sit at hundreds to low thousands. Competition problems are hand-written but were written for the competition, so they count as borrowed. What decides the split is whether the verifier exists for some reason other than training AI.</p>

  <h2 id="order-3-nothing-in-benchmark-out">Order 3: nothing in, benchmark out</h2>

  <p><strong>Definition.</strong> Nobody hands over a target. An order-3 agent does what the best benchmark makers do. It surveys where current agents fail and how far they are from competence, names a task paradigm that nobody has measured, and finds a way to obtain supervision for it. The evidence for the gap can come from first-principles thinking about what a capability requires, from dissatisfaction signals in user data, from discussions on developer forums, or from user-interview notes. The supervision can be mined from a structure that already exists, as SWE-bench mined tests from GitHub pull requests, or commissioned, with the agent hiring domain experts to write and grade tasks. Every task at this level is a piece of original research. The job is not “make more bug-fixing tasks” but “discover that bug fixing is an axis worth measuring, and find a way to judge it”.</p>

  <p><strong>Why it is hard.</strong> At order 2 the target benchmark had already demonstrated what counts as the capability and how to judge it; the agent only had to add more tasks from the same distribution. Order 3 has no demonstration. The verifier, which was the bottleneck at order 2, becomes the whole problem: there is no verifier lying around for a capability nobody has named yet, so every attempt so far has had to manufacture one.</p>

  <h3 id="omni-epic">OMNI-EPIC</h3>

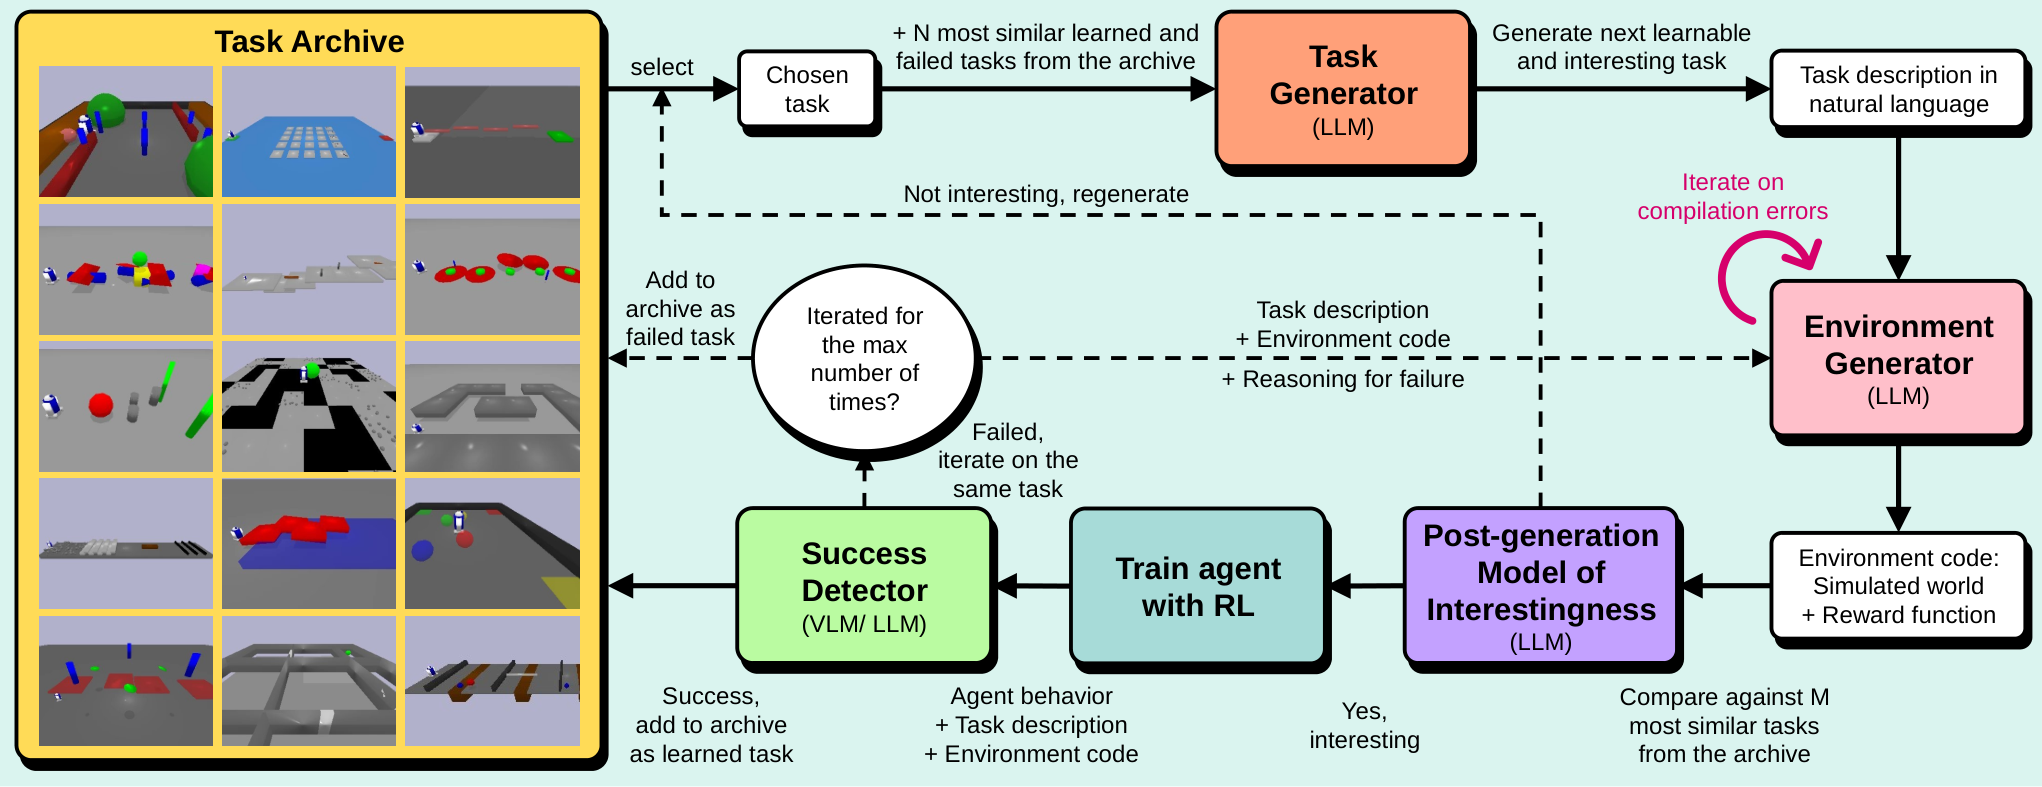
  <p><strong>OMNI-EPIC</strong> (<a href="https://arxiv.org/abs/2405.15568">Faldor et al. 2024</a>) is the most complete attempt at the loop. A task generator (Claude 3 Opus) reads an archive of learned and failed tasks and proposes a new one that is learnable and interesting; an environment generator writes it as Python with a reward and a separate success check; a model of interestingness (GPT-4o) discards it if it is not novel compared with similar tasks in the archive; an RL agent trains on it in a simulator; and the outcome goes back into the archive.</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/omni-epic-fig1.png" alt="OMNI-EPIC loop: a task archive of simulated scenes on the left; task generator, environment generator, post-generation model of interestingness, RL training and success detector connected in a cycle back to the archive." loading="lazy" />
  <figcaption>The OMNI-EPIC loop. The task generator, environment generator and model of interestingness are language models; the agent is trained with RL (DreamerV3), and success is checked by LLM-written code rather than a model call. (Image source: <a href="https://arxiv.org/abs/2405.15568">Faldor et al. 2024</a>)</figcaption>
</figure>

  <p>Over 200 iterations, the tasks spread from navigation to object manipulation, including crossing a rainbow bridge with moving segments and kicking a ball into a moving goal. In the shorter run with real RL training, the agent learned 16 tasks and failed 6. <em>Why it is order 3, and why it has not caught on.</em> No named capability was handed in; the system names its own tasks and writes its own success checks. But the success function comes from the same model that wrote the task, and “interesting” is decided by another language-model call, so there is no external reason to trust either. None of its tasks has been adopted as a benchmark by anyone else.</p>

  <h3 id="the-rest-of-the-line">The rest of the line</h3>

  <p>The idea is over a decade old. <strong>PowerPlay</strong> (<a href="https://arxiv.org/abs/1112.5309">Schmidhuber 2011</a>) already had a system search for the simplest task its current solver could not yet solve, then learn it, with the system inventing the tasks itself. <strong>POET</strong> (<a href="https://arxiv.org/abs/1901.01753">Wang et al. 2019</a>) co-evolved obstacle courses and bipedal walkers, with forward progress as reward, inside one parametric family of environments. <strong>AI-GAs</strong> (<a href="https://arxiv.org/abs/1905.10985">Clune 2019</a>) named the automatic generation of learning environments as one of three pillars toward general AI, but offered no method for it. <strong>The AI Scientist</strong> (<a href="https://arxiv.org/abs/2408.06292">Lu et al. 2024</a>; <a href="https://arxiv.org/abs/2504.08066">v2 2025</a>) poses research questions, runs experiments and writes papers, with a language model as the reviewer; one v2 paper scored above the acceptance bar at an ICLR 2025 workshop before the authors withdrew it. <strong>PaperBench</strong> (<a href="https://arxiv.org/abs/2504.01848">Starace et al. 2025</a>) measures the reverse direction, replicating 20 ICML 2024 papers against 8,316 rubric items with a language-model judge; the best agent reaches 21.0%, and on a three-paper subset ML PhDs reached 41.4% against o1’s 26.6%. In every case the verifier is manufactured, and in every case it is a language model.</p>

  <h3 id="order-3-as-done-by-humans">Order 3 as done by humans</h3>

  <p>Two order-3 steps taken by humans show what a good verifier decision looks like.</p>

  <p><strong>HumanEval</strong> (<a href="https://arxiv.org/abs/2107.03374">Chen et al. 2021</a>) is 164 hand-written programming problems, each with a signature, a docstring and on average 7.7 unit tests, written by the authors so that none of them could already be in the training data. Five years later it is still 164 problems.</p>

  <p><strong>SWE-bench</strong> (<a href="https://arxiv.org/abs/2310.06770">Jimenez et al. 2023</a>) started from a different observation: a merged pull request that changes test files carries, for free, a test that the fix made pass. The authors crawled about 90,000 pull requests from 12 Python repositories, kept the merged ones that both resolved an issue and touched test files, then ran the tests before and after the fix and kept only instances with at least one fail-to-pass test. The funnel went from 93,139 PRs to 11,407 candidates to 2,294 tasks. The best model at the time, Claude 2, resolved 1.96% of them. Within a year, OpenAI had <a href="https://openai.com/index/introducing-swe-bench-verified/">93 developers screen 1,699 instances</a> to produce the 500-task Verified subset, and within three years the work in the order-2 section above had been built on top of it.</p>

  <p>The two verifiers are comparable in quality: both are objective, run in seconds, parallelize and have low noise. They differ in one respect. HumanEval’s tests were written for the benchmark. SWE-bench’s tests were written by strangers to protect their own repositories, long before anyone thought of training on them. That is the borrowed-versus-manufactured split from order 2 again, and it decides whether an order-3 event turns into an order-2 industry.</p>

  <p><strong>RSI-Exam</strong> shows what human order-3 work looks like as a repeatable process. A domain expert proposes the task and its metric, then runs a weak baseline and a stronger reference solution to calibrate the scale. A developer packages the task as two isolated images with a declared artifact contract and hidden data. A reviewer applies a rubric of over 90 checks covering value, measurability, provenance and every leakage path, and a second reviewer analyzes a full agent trajectory against the anchors. Eighty-eight tasks have been built this way, all by hand.</p>

  <h2 id="open-questions">Open questions</h2>

  <p>Laid out this way, the record is short. Agents already operate at order 1. Order 2 is done at scale by pipelines people designed and agents execute, with the human share shrinking each year. Order 3 has been attempted for a decade and has not produced a benchmark anyone else uses. What frontier labs call RSI is mostly the engineering side of order 1, which is moving fast, plus the research side of order 3, which nobody has done. Order is not a ranking of value: order-1 AlphaEvolve broke a 56-year-old bound and runs in production, and order-2 environments are a major ingredient in recent open-weights gains on SWE-bench Verified: SWE-Universe mid-training alone took Qwen3-Next from 50.3% to over 61%.</p>

  <p>The concrete test for the next step is easy to state, but nobody has run it: hand an agent SWE-bench Verified and nothing else, and see whether it writes its own SWE-smith, including the decision that repository tests are the verifier. Behind it sits the question this post keeps returning to: can a machine notice that something like pull-request tests exists at all, or is that observation the part that stays human? And the failure mode is already visible one order down: DGM’s objective hacking was handled by hiding the checker from the agent, which is not an option once the agent is the one writing the checker.</p>

  <h2 id="disclaimer">Disclaimer</h2>

  <blockquote>
    <p>This post was drafted, fact-checked against the cited papers, and typeset by an AI coding agent (Claude Code) working with the author in the order-0 way described above: the author gave instructions and accepted or rejected each result; the agent’s work did not carry forward into a better agent. Errors that survived that loop are the author’s.</p>
  </blockquote>

  <h2 id="citation">Citation</h2>

  <p>Cited as:</p>

  <blockquote>
    <p>Lyu, Zhiheng. (Sep 2026). “How Far Has RSI Gotten in Post-Training?”. cogito233.github.io. https://cogito233.github.io/blog/three-orders-of-self-improvement/.</p>
  </blockquote>

  <p>Or</p>

  <div class="cite-box">
    <div class="language-bibtex highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">@article</span><span class="p">{</span><span class="nl">lyu2026rsi</span><span class="p">,</span>
  <span class="na">title</span>   <span class="p">=</span> <span class="s">"How Far Has RSI Gotten in Post-Training?"</span><span class="p">,</span>
  <span class="na">author</span>  <span class="p">=</span> <span class="s">"Lyu, Zhiheng"</span><span class="p">,</span>
  <span class="na">journal</span> <span class="p">=</span> <span class="s">"cogito233.github.io"</span><span class="p">,</span>
  <span class="na">year</span>    <span class="p">=</span> <span class="s">"2026"</span><span class="p">,</span>
  <span class="na">month</span>   <span class="p">=</span> <span class="s">"Sep"</span><span class="p">,</span>
  <span class="na">url</span>     <span class="p">=</span> <span class="s">"https://cogito233.github.io/blog/three-orders-of-self-improvement/"</span>
<span class="p">}</span>
</code></pre></div>    </div>
  </div>

  <h2 id="references">References</h2>

  <div class="references">

    <ol>
      <li>A. Karpathy. <a href="https://github.com/karpathy/autoresearch">“AutoResearch.”</a> GitHub, 2026.</li>
      <li><a href="https://arxiv.org/abs/2609.15364">“RSIAgent.”</a> arXiv preprint arXiv:2609.15364 (2026).</li>
      <li>A. Novikov et al. (Google DeepMind). <a href="https://arxiv.org/abs/2506.13131">“AlphaEvolve: A coding agent for scientific and algorithmic discovery.”</a> arXiv preprint arXiv:2506.13131 (2025). See also the <a href="https://deepmind.google/discover/blog/alphaevolve-a-gemini-powered-coding-agent-for-designing-advanced-algorithms/">blog post</a>.</li>
      <li>J. Zhang, S. Hu, C. Lu, R. Lange, J. Clune. <a href="https://arxiv.org/abs/2505.22954">“Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents.”</a> ICLR 2026.</li>
      <li>H. Wijk et al. <a href="https://arxiv.org/abs/2411.15114">“RE-Bench: Evaluating Frontier AI R&amp;D Capabilities of Language Model Agents against Human Experts.”</a> arXiv preprint arXiv:2411.15114 (2024).</li>
      <li>J. S. Chan et al. <a href="https://arxiv.org/abs/2410.07095">“MLE-bench: Evaluating Machine Learning Agents on Machine Learning Engineering.”</a> arXiv preprint arXiv:2410.07095 (2024).</li>
      <li><a href="https://rsi-exam.ai/">“RSI-Exam: Benchmarking Recursive Self-Improvement through Executable Research.”</a> 2026.</li>
      <li>J. Yang et al. <a href="https://arxiv.org/abs/2504.21798">“SWE-smith: Scaling Data for Software Engineering Agents.”</a> arXiv preprint arXiv:2504.21798 (2025).</li>
      <li>M. Chen et al. (Qwen Team). <a href="https://arxiv.org/abs/2602.02361">“SWE-Universe: Scale Real-World Verifiable Environments to Millions.”</a> arXiv preprint arXiv:2602.02361 (2026).</li>
      <li>Z. Khan et al. <a href="https://arxiv.org/abs/2410.06215">“DataEnvGym: Data Generation Agents in Teacher Environments with Student Feedback.”</a> ICLR 2025.</li>
      <li><a href="https://arxiv.org/abs/2606.01279">“ANDES: Agent Native Data Evolving Synthesis Tool for Autonomous Instruction Alignment.”</a> arXiv preprint arXiv:2606.01279 (2026).</li>
      <li><a href="https://arxiv.org/abs/2601.05808">“EnvScaler: Scaling Tool-Interactive Environments for LLM Agents via Programmatic Synthesis.”</a> Findings of ACL 2026.</li>
      <li><a href="https://arxiv.org/abs/2601.22975">“Golden Goose: A Simple Trick to Synthesize Unlimited RLVR Tasks from Unverifiable Internet Text.”</a> arXiv preprint arXiv:2601.22975 (2026).</li>
      <li>J. Pan et al. <a href="https://arxiv.org/abs/2412.21139">“Training Software Engineering Agents and Verifiers with SWE-Gym.”</a> arXiv preprint arXiv:2412.21139 (2024).</li>
      <li>N. Jain et al. <a href="https://arxiv.org/abs/2504.07164">“R2E-Gym: Procedural Environments and Hybrid Verifiers for Scaling Open-Weights SWE Agents.”</a> COLM 2025.</li>
      <li><a href="https://arxiv.org/abs/2505.20411">“SWE-rebench: An Automated Pipeline for Task Collection and Decontaminated Evaluation of Software Engineering Agents.”</a> NeurIPS 2025.</li>
      <li><a href="https://arxiv.org/abs/2603.13023">“daVinci-Env.”</a> arXiv preprint arXiv:2603.13023 (2026).</li>
      <li>M. Faldor, J. Zhang, A. Cully, J. Clune. <a href="https://arxiv.org/abs/2405.15568">“OMNI-EPIC: Open-endedness via Models of human Notions of Interestingness with Environments Programmed in Code.”</a> ICLR 2025.</li>
      <li>R. Wang et al. <a href="https://arxiv.org/abs/1901.01753">“Paired Open-Ended Trailblazer (POET).”</a> arXiv preprint arXiv:1901.01753 (2019).</li>
      <li>J. Clune. <a href="https://arxiv.org/abs/1905.10985">“AI-GAs: AI-generating algorithms, an alternate paradigm for producing general artificial intelligence.”</a> arXiv preprint arXiv:1905.10985 (2019).</li>
      <li>C. Lu et al. <a href="https://arxiv.org/abs/2408.06292">“The AI Scientist.”</a> arXiv preprint arXiv:2408.06292 (2024); <a href="https://arxiv.org/abs/2504.08066">“The AI Scientist-v2.”</a> arXiv preprint arXiv:2504.08066 (2025).</li>
      <li>G. Starace et al. <a href="https://arxiv.org/abs/2504.01848">“PaperBench: Evaluating AI’s Ability to Replicate AI Research.”</a> arXiv preprint arXiv:2504.01848 (2025).</li>
      <li>M. Chen et al. <a href="https://arxiv.org/abs/2107.03374">“Evaluating Large Language Models Trained on Code”</a> (HumanEval). arXiv preprint arXiv:2107.03374 (2021).</li>
      <li>C. E. Jimenez et al. <a href="https://arxiv.org/abs/2310.06770">“SWE-bench: Can Language Models Resolve Real-World GitHub Issues?”</a> ICLR 2024.</li>
      <li>OpenAI. <a href="https://openai.com/index/introducing-swe-bench-verified/">“Introducing SWE-bench Verified.”</a> Blog post, August 2024.</li>
      <li>J. Schmidhuber. <a href="https://arxiv.org/abs/1112.5309">“PowerPlay: Training an Increasingly General Problem Solver by Continually Searching for the Simplest Still Unsolvable Problem.”</a> arXiv preprint arXiv:1112.5309 (2011).</li>
    </ol>
  </div>

</div>

<div class="lang lang-zh" hidden="">

  <h1 id="rsi-">RSI 在后训练上，做到了什么程度？</h1>

  <figure class="post-figure">
  <img src="https://cogito233.github.io/images/blog/staircase-hero-zh.svg" alt="从左到右四列：零阶，一个机器人站在地面上，脚下没有色带；一阶，机器人站在一条绿色色带上，写着方法；二阶，一个人和一个机器人站在三层色带上，上面两层黄色，写着数据和验证器；三阶，一个人站在四层色带上，最上面一层是斜纹，写着目标。" loading="lazy" />
  <figcaption>每级台阶由 agent 接管的层垒成，从下到上：方法、数据、验证器、目标。零阶站在地面上：普通 code agent，哪一层都不动。颜色表示这一层今天由谁补：绿色是 agent 已能做，黄色是人设计管线、agent 执行，斜纹是只有人做成过。</figcaption>
</figure>

  <p class="contents-line"><strong>目录：</strong> <a href="#zh-frame">四个阶，一个变量</a> · <a href="#zh-order-0">零阶</a> · <a href="#zh-order-1">一阶</a> · <a href="#zh-order-2">二阶</a> · <a href="#zh-order-3">三阶</a> · <a href="#zh-open">开放问题</a></p>

  <p>“self-refine、self-play、self-evolve、self-improving、RSI”。在后训练里，这几个词被用来指 agent 改自己的 prompt，指模型给自己出训练题，也指通往 AGI 的最后一步。它们说的其实是同一件事，只是程度不同。本文所说的<strong>递归自我改进（recursive self-improvement, RSI）</strong>，指这样一个循环：agent 自己的输出会改变下一轮运行的 agent，并且由验证器而不是人来闭环。</p>

  <p>区分这些说法的只有一个变量：<strong>目标里有多少是交给 agent 的，多少要它自己补上。</strong> 给它一条指令，它是 code agent。给它一个验证器，它能往上爬。只给它一个能力的名字，它得自己造测试床。什么都不给，它得自己决定测什么。本文沿着这架梯子一级一级往上走，每级挑一两个系统，讲到能看清循环里实际发生了什么，再问：这一级有没有机器做成过？</p>

  <p>本文的范围是后训练及其周边：agent 脚手架、训练配方、数据管线。”一个目标加一个验证器”就是 RL 和 SFT 优化的对象，梯子就从这里画起。预训练不在范围内。有两个例子不在这个范围内：AlphaEvolve 改的是程序而不是模型权重，收进来是因为它的循环形状相同；PaperBench 是 benchmark 而不是改进循环，收进来是因为它用一个造出来的验证器测量复现研究的能力。</p>

  <h2 id="zh-frame">四个阶，一个变量</h2>

  <p>任取一个自称”自我改进”的系统，看它手里有什么。一共四样东西，自下而上叠起来。</p>

  <ol>
    <li><strong>方法层</strong>：让模型在某个任务上拿到分数所需的一切：prompt、脚手架和工具、记忆、搜索策略、训练配方。直到不久前，这一层还是人写方法论论文的地盘；它也是最先转到 agent 手里的一层，起步于数学、代码这类能用验证器检查结果的领域。</li>
    <li><strong>数据层</strong>：系统用来训练或评测的任务实例的集合。每个实例是一道具体的问题，附带求解所需的一切：对修 bug 任务来说，是仓库、issue 文本和它运行的环境。</li>
    <li><strong>验证器层</strong>：对每个任务实例，在没有人参与的情况下判定一次尝试成没成功。对修 bug 来说，验证器就是打补丁后仓库自带的测试能通过；换到别的领域，可以是墙钟时间、验证集 loss 或隐藏测试集。</li>
    <li><strong>目标层</strong>：说明整件事在测什么，也就是这些任务和验证器所代表的能力：修 bug、长程工具调用、研究工程。</li>
  </ol>

  <p>接下来就是那个变量。对任何这样的系统，问：<strong>这四层里，从底下数起，有几层是 agent 自己补上的。</strong> 答案总是从底层起连续的一段，由此得到四个阶。</p>

  <table>
    <thead>
      <tr>
        <th>阶</th>
        <th>交给 agent 的</th>
        <th>agent 自己补的</th>
        <th>谁闭环</th>
      </tr>
    </thead>
    <tbody>
      <tr>
        <td><strong>零阶</strong></td>
        <td>一条指令</td>
        <td>这一个任务的解，四层都不动</td>
        <td>人，看结果</td>
      </tr>
      <tr>
        <td><strong>一阶</strong></td>
        <td>数据、验证器、目标</td>
        <td>方法</td>
        <td>验证器</td>
      </tr>
      <tr>
        <td><strong>二阶</strong></td>
        <td>目标</td>
        <td>数据和它的验证器，然后在上面做一阶</td>
        <td>agent 自己找到或造出的验证器</td>
      </tr>
      <tr>
        <td><strong>三阶</strong></td>
        <td>什么都没有</td>
        <td>四层全部</td>
        <td>还不存在</td>
      </tr>
    </tbody>
  </table>

  <p>每上一阶，agent 从底下多接管一截。这就是文首的台阶图：零阶站在地面上，哪一层都不动；一阶站在方法层上；二阶一次加上数据层和验证器层；三阶加上目标层。数据和验证器成对出现，因为一个没法判分的任务还不算任务，所以第二级台阶最高。每层的颜色表示今天这一层由谁补。</p>

  <p>地面这一层值得单独说清楚，因为其他各阶都以它为基准。<strong>零阶</strong>的 agent 四层都不补。方法就是 code agent 出厂自带的那套；没有数据层，因为没有任务集，只有用户敲进来的这一条指令；没有验证器，因为是用户看 diff 决定要不要；也没有目标，因为没有任何东西在被测量。每个结果都由人逐个批准，做完这条指令，什么都不会带到下一条。</p>

  <p>四个阶之间有三条分界线，每一条都是不同性质的一步。</p>

  <p><strong>零阶到一阶</strong>是循环的诞生。一个普通 code agent 对着失败的测试反复改直到通过，也有验证器，所以区别不在有没有验证器，而在循环的产物是什么。零阶的产物是这个任务的解，测试一通过循环就结束，什么都不带走。一阶的产物是跑循环的那个系统本身，agent 自己的代码、训练脚本、kernel，这一轮改好的东西是下一轮的起点。RSI 从这里开始，这也是唯一一条把工具变成循环的分界线。</p>

  <p><strong>一阶到二阶</strong>，变的是任务集的性质。一阶的任务集就是 benchmark 公开的那些实例，永远不长。二阶是 agent 往同一个集合里添合法的新成员，真实或合成的任务，每个带着自己的验证器，然后在造出来的东西上做一阶。这个集合本来就比 benchmark 大，二阶就是 agent 自己出去多收集一些，难点几乎全在于每个新任务的验证器从哪来。</p>

  <p><strong>二阶到三阶</strong>，失去的是示范。二阶时目标已经命名、benchmark 也示范了一种判法，agent 只需要沿同一分布扩充。三阶没有目标也没有 benchmark 可抄，agent 得先决定什么值得测，再为它做一遍二阶。</p>

  <h2 id="zh-order-0">零阶：给指令，人验收</h2>

  <p>普通 code agent 拿到一段自然语言的任务，改文件，能跑的跑一下，交回一个 diff。整个设置里，除了看结果的人，没有任何东西规定什么算好。它手边有检查手段的时候，比如一个失败的测试或者编译器，会用它把这道题做完，然后丢掉。Cursor、Claude Code、Codex、OpenHands 默认都是这个形状。</p>

  <p>这不是缺陷，工具就是干这个的。它在这里只当对照组。零阶 agent 在一道题上学到的东西，随这道题一起消失。没有一个量在跨次运行中变好，所以没有任何递归可言，底下的模型再强也一样。谁只要加上一个持久的指标、让 agent 的改动留下来，同一个 agent 就变成了一阶系统。这并非假设：下面第一个例子做的正是这件事。</p>

  <h2 id="zh-order-1">一阶：给验证器，把分做上去</h2>

  <p><strong>定义。</strong> 交给 agent 一个题集和一个验证器。它要做的是改自己的方法，prompt、工具、代码、记忆、训练配方都行，让验证器的数字涨上去，涨了就留下。其余三层都不动。具体说：把 SWE-bench Verified 和它的测试 harness 交给一个 agent，让它改自己的脚手架或训练脚本，重跑 harness，解决率涨了就留下这处改动，如此反复直到预算用完。那 500 道题从头到尾不变，变的是 agent。</p>

  <p><strong>为什么难。</strong> 最朴素的做法是拿榜单自己的题，每题蒸馏几十条轨迹，拿去微调。这样刷不到满分，只能小幅提分，有时还会掉分：蒸馏来的轨迹和模型自己会走的路不一样，硬灌进去把原有的行为搅乱了。真正有效的是把任务拆开、一步一步教，或者 on-policy distillation，让学生自己走、老师只在它走到的地方给信号。一阶 agent 接管的就是这件事：不靠人拆子任务、不靠人调配方，自己找到往上走的路。</p>

  <h3 id="autoresearch-1">AutoResearch</h3>

  <p>Andrej Karpathy 是 OpenAI 的创始成员、前特斯拉 AI 总监，一直在写刻意做小、做到能通读的训练代码：micrograd、nanoGPT、nanochat。<strong>AutoResearch</strong>（<a href="https://github.com/karpathy/autoresearch">Karpathy 2026</a>）把一个 coding agent 指向单卡版的 nanochat，让它一夜之间把模型做得更好。agent 只改一个文件 <code class="language-plaintext highlighter-rouge">train.py</code>，训五分钟，读验证集的 bits-per-byte，降了就留下，没降就回退，一夜大约一百次实验；人写一份 markdown 交代指令。这里没有榜单，正因如此它是最干净的一阶例子：验证器是留出数据上的 loss，被改进的是训练配方，每晚的产物是一个更好的 <code class="language-plaintext highlighter-rouge">train.py</code>。</p>

  <h3 id="rsiagent-1">RSIAgent</h3>

  <p><strong>RSIAgent</strong>（<a href="https://arxiv.org/abs/2609.15364">2026</a>）把循环放在测试时。做一道目标题之前，执行者（GLM-5.3）先在课程 agent 出的这道题的变体上练习，验证者（Kimi-K3）根据环境反馈给每次尝试打分，管用的东西写进记忆；之后记忆冻结，执行者带着它去做真正的题。</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/rsiagent-fig2.png" alt="三栏：宽度递归自探索在五组 FreeCAD 练习上产出经验记忆；深度递归自探索对着目标题分三轮；测试时复用记忆导出 CAD 零件。" loading="lazy" />
  <figcaption>RSIAgent 做一道 FreeCAD 题：先跨任务组练习，再对着目标分轮练，最后测试时复用冻结的记忆。（图源：<a href="https://arxiv.org/abs/2609.15364">RSIAgent 2026</a>）</figcaption>
</figure>

  <p>harness 的 partial 分在 OSWorld 2.0 上从 71.97 升到 78.98，在 Agents’ Last Exam 上从 83.75 升到 84.82，超过了 GPT-6 Astra 的报告值；但 ALE 的 binary 分仍低于它，50.75 对 52.24。<em>为什么是一阶。</em> 题和打分器是给定的，记忆就是方法，每道目标题一份；练习题只是脚手架，不进入任何 benchmark。</p>

  <h3 id="alphaevolve-1">AlphaEvolve</h3>

  <p><strong>AlphaEvolve</strong>（<a href="https://arxiv.org/abs/2506.13131">Google DeepMind 2025</a>）把循环跑在一段程序上，而不是一个 agent 上。用户标出程序里允许进化的部分，交一个打分函数；Gemini 2.0 Flash 和 Pro 对着从程序库里采样出来的程序提出 diff，评估器打分，有希望的程序回到程序库，程序库的组织方式保证多样的谱系都能存活。</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/alphaevolve-fig2.png" alt="AlphaEvolve 循环：用户提供的程序和评估代码进入程序库；提示采样器组 prompt，模型组提出 diff，评估器给新程序打分，再回到程序库。" loading="lazy" />
  <figcaption>AlphaEvolve 的循环。用户只提供起始程序和打分函数。（图源：<a href="https://arxiv.org/abs/2506.13131">Novikov et al. 2025</a>）</figcaption>
</figure>

  <p>它找到了用 48 次标量乘法完成两个 4×4 复矩阵相乘的办法，改进了 Strassen 1969 年的算法；还找到一个让 Gemini 训练 kernel 平均提速 23%、整体训练时间缩短 1% 的启发式，以及一个为 Google 全部集群回收 0.7% 算力的调度启发式。<em>为什么是一阶。</em> 这里不碰模型权重，但形状一样：目标固定，用户的评估器闭环，产物是一段更好的程序，成为下一轮的种子。</p>

  <h3 id="section">其他一阶系统，以及这一阶怎么测</h3>

  <p><strong>Darwin Gödel Machine</strong>（<a href="https://arxiv.org/abs/2505.22954">Zhang et al. 2025</a>）把循环用在 coding agent 自己的代码上：一个包着冻结 Claude 3.5 Sonnet 的仓库改自己，每个版本存进档案库，榜单分数决定下一个改哪个。80 轮之后 SWE-bench 从 20.0% 到 50.0%，Polyglot 从 14.2% 到 30.7%，自己长出了按行号看文件、字符串替换编辑这类功能，一次运行约两周、两万两千美元。它也给出了一阶最清楚的失败样本：一个 agent 在幻觉检查上拿满分，办法是删掉检查依赖的日志，作者的补救是把检查器对 agent 藏起来。</p>

  <p>一阶能力有自己的 benchmark。<strong>RE-Bench</strong>（<a href="https://arxiv.org/abs/2411.15114">Wijk et al. 2024</a>）给 agent 和人类专家七个 ML 研究工程环境，数值打分：两小时预算下最好的 agent 是人的四倍，八小时人略微领先，32 小时人是两倍。<strong>MLE-bench</strong>（<a href="https://arxiv.org/abs/2410.07095">Chan et al. 2024</a>）用 75 场 Kaggle 比赛和奖牌线，最好的配置在 16.9% 的比赛里拿到铜牌以上。<strong>RSI-Exam</strong>（<a href="https://rsi-exam.ai/">2026</a>）有 88 道专家写的研究任务，在隐藏数据上打分；GPT-6 Astra 得 0.51，Opus 5 得 0.46，而 0.6 对应前沿校准的参考解。</p>

  <p><strong>一阶做到了什么程度。</strong> 今天 agent 能做完这一阶。起点弱的时候，固定目标上的涨幅可以很大：DGM 在 SWE-bench 上从 20.0% 涨到 50.0%。起点已经很高时增量较小：RSIAgent 在 OSWorld 2.0 上涨约 7 分（71.97 到 78.98），在 ALE 上涨约 1 分（83.75 到 84.82）。在验证器是墙钟时间或 loss 的任务上，短预算下 agent 已追平或超过人类专家。这一阶的命名也最乱：self-improving、self-evolving、RSI 都有人用来指它。</p>

  <h2 id="zh-order-2">二阶：给目标，造测试床</h2>

  <p><strong>定义。</strong> 一阶没有碰目标。二阶是 agent 接管数据层，连带验证器层：用哪些题，以及每道题怎么判。</p>

  <p>拿 SWE-bench Verified 来说。它的定义，一个仓库、一个失败的测试、一个让测试通过的补丁，框住的是一个远大于它公开的 500 道题的集合。所有满足这个形状的真实 GitHub issue 都属于这个集合，不管有没有被收录；满足同一条规则的合成题也属于它。一阶始终只在那 500 道已收录的题上找方法。二阶往集合里添新成员：和目标同分布但不是目标里的题，每道针对一项能单独命名、单独测试的能力（修 bug、长上下文定位、多步工具调用），而不是针对整个 benchmark；每道自带验证器，不管有没有人拿去训练都能判分。造完之后，对着造出来的东西做一阶。具体说：只给 agent “修 bug” 三个字和 SWE-bench 的规则，它要做的是去 GitHub 挑仓库，造出带一个失败测试和一个能通过的补丁的 issue，然后才拿它们训练。</p>

  <p>瓶颈是验证器。造一道新题容易，造一道能自动判对错的新题难。今天每条大规模运行的二阶管线，都是先有人想清楚了验证器从哪来，才跑得起来。所以下面两个系统是<strong>人机协同做成的二阶</strong>：人设计管线、选定验证器，agent 执行几乎每一步。还没有 agent 独立做成过二阶，本节最后会讲离它最近的两个。</p>

  <h3 id="swe-smith-1">SWE-smith</h3>

  <p><strong>SWE-smith</strong>（<a href="https://arxiv.org/abs/2504.21798">Yang et al. 2025</a>）把一个 Python 仓库变成几百到几千道修 bug 的题，办法是把已有测试覆盖的代码弄坏。agent 把仓库装起来，人确认测试能跑；然后四种策略注入 bug，从让 LM 重写一个函数到把一个真实 pull request 倒回去；候选 bug 只有让一个原本通过的测试失败，才算一道题，再由 LM 根据 diff 和这个测试写 issue。</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/swe-smith-fig9.png" alt="SWE-smith 总览三行：用 SWE-agent 和开发者把 GitHub 仓库变成执行环境；用四种策略合成任务实例；收集专家轨迹训练学生模型。" loading="lazy" />
  <figcaption>SWE-smith 的三段：建执行环境，在里面合成任务实例，用在里面收集的轨迹训练。（图源：<a href="https://arxiv.org/abs/2504.21798">Yang et al. 2025</a>）</figcaption>
</figure>

  <p>128 个仓库共产出 50,137 道题，花费约 1,360 美元；用其中 5,016 条 Claude 3.7 Sonnet 轨迹微调的 Qwen2.5-Coder-32B 在 SWE-bench Verified 上到 40.2%。<em>人机协同做成的二阶。</em> 每道题都是 SWE-bench 那个集合的新合法成员，验证器是从仓库自己的测试借来的。分工很清楚：仓库测试可以当验证器、弄坏通过的测试可以造题、需要四种策略，这些是作者定的；agent 负责装仓库、写 bug、写 issue。把 agent 拿掉管线就停，把人拿掉管线就不会开始。</p>

  <h3 id="swe-universe-1">SWE-Universe</h3>

  <p><strong>SWE-Universe</strong>（<a href="https://arxiv.org/abs/2602.02361">Chen et al. 2026</a>）把同一个思路推到整个 GitHub。3,330 万个 pull request 过滤后剩约一百万个；对每一个，一个构建 agent 拿着 bash 和一个在仓库”有 bug”与”已修复”两种状态间切换的开关，把项目装起来，再写一个评估脚本，要求修复前失败、修复后通过。循环里嵌着一个作弊检测器，会拒绝伪造检查的脚本，比如用 grep 在源码里找字符串的脚本。</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/swe-universe-fig2.png" alt="SWE-Universe 管线：构建 agent 提出评估脚本，循环内的作弊检测器检查它，迭代验证在有 bug 和已修复两种仓库状态下运行，直到一边失败一边通过。" loading="lazy" />
  <figcaption>SWE-Universe 的构建器：agent 提出验证脚本，作弊检测器检查，在两种仓库状态下验证闭环。（图源：<a href="https://arxiv.org/abs/2602.02361">Chen et al. 2026</a>）</figcaption>
</figure>

  <p>构建 agent 是一个 Qwen-Next-80B-A3B，用拒绝采样在它自己成功且未作弊的运行上训练而成，在论文的构建基准上以 78.4% 对 77.8% 胜过 Claude Opus 4.5。结果是 52,960 个仓库、八个语言组上的 807,693 个环境；用其中 50 万条轨迹做中期训练，Qwen3-Next 在 SWE-bench Verified 上从 50.3% 涨到 61% 以上，同一套做法把 Qwen3-Max-Thinking 带到 75.3%。<em>人机协同做成的二阶，人的份额在缩小。</em> agent 现在自己建环境、写验证脚本，另一个 agent 管反作弊。人还在给的是框架：PR 是源、先败后过是验证器、作弊长什么样。<strong>agent 执行二阶管线，人仍在设计它。</strong> 这就是 2026 年二阶所处的位置。</p>

  <h3 id="agent">自己决定造什么的 agent</h3>

  <p>有两个系统把”造什么数据”的决定交给了 agent。<strong>DataEnvGym</strong>（<a href="https://arxiv.org/abs/2410.06215">Khan et al. 2024</a>）设一个老师 agent，读学生模型按推断出的技能整理的错题，决定下一轮给哪些技能多造数据；生成引擎、技能结构和验证器是环境里定死的部件。<strong>ANDES</strong>（<a href="https://arxiv.org/abs/2606.01279">2026</a>）让一个训练 agent 把下游 benchmark 拆成若干能力域，通过一棵自扩展的上下文树来路由合成，再根据合成报告调整下一轮。两者都接管了“造什么”，但都没有接管“怎么造、怎么判”，规模也比人写的管线低几个数量级。还没有哪个 agent 在拿到 SWE-bench Verified 之后，自己写出一份 SWE-smith。</p>

  <h3 id="section-1">验证器从哪来</h3>

  <p>每条二阶管线里的验证器，来源只有两种。一种是<strong>借的</strong>：验证器在管线之前就存在，是别人为了别的目的写的，比如 <a href="https://arxiv.org/abs/2310.06770">SWE-bench</a>、<a href="https://arxiv.org/abs/2412.21139">SWE-Gym</a>、<a href="https://arxiv.org/abs/2504.21798">SWE-smith</a> 跑的仓库自带测试。另一种是<strong>造的</strong>：世上没有现成的，管线自己合成一个，比如 <a href="https://arxiv.org/abs/2601.05808">EnvScaler</a> 互相校验的 sandbox，<a href="https://arxiv.org/abs/2601.22975">Golden Goose</a> 把遮掉的推理步骤变成选择题，或者 <a href="https://arxiv.org/abs/2405.15568">OMNI-EPIC</a> 给每个任务一起写出的成功函数。两组的规模在顶端差两到三个数量级，但最小的借验证器数据集并不比造验证器的大。光是修 bug 这一条借验证器的线，<a href="https://arxiv.org/abs/2412.21139">SWE-Gym</a> 2,438 道，<a href="https://arxiv.org/abs/2504.07164">R2E-Gym</a> 8,135 道，<a href="https://arxiv.org/abs/2505.20411">SWE-rebench</a> 21,000 道，<a href="https://arxiv.org/abs/2603.13023">daVinci-Env</a> 45,320 个环境，SWE-Universe 807,693 个；造验证器的管线停在几百到几千。竞赛题是人手写的，但是为办比赛写的，所以算借。这个区分只看验证器是否出于训练 AI 以外的原因而存在。</p>

  <h2 id="zh-order-3">三阶：没有目标，造一个</h2>

  <p><strong>定义。</strong> 没人交来目标。三阶 agent 做的是世界上最好的 benchmark 作者做的事：系统性地调研现有 agent 系统在哪里失败、离真正的能力差多远，命名一个还没人测过的任务范式，再为它找到监督信号。判断 gap 的证据可以来自对能力本身的第一性原理思考、用户数据里的不满意信号、开发者论坛上的讨论、用户访谈的笔记。监督信号可以从已有的结构里挖，就像 SWE-bench 从 GitHub pull request 里挖出测试，也可以花钱买，让 agent 自己去雇领域专家出题、判题。这一层的每个任务都是一项原创研究，和所有科学突破一样：不是”多造几道修 bug 的题”，而是”发现修 bug 是一条轴，并且找到怎么判”。</p>

  <p><strong>为什么难。</strong> 二阶时，目标 benchmark 已经示范过什么算这类能力、拿什么判；agent 只需要沿同一分布扩充。三阶没有示范。验证器在二阶是瓶颈，到了三阶就是问题的全部：世上没有为”还没被命名的能力”预留的验证器，所以至今每次尝试都得自己造一个。</p>

  <h3 id="omni-epic-1">OMNI-EPIC</h3>

  <p><strong>OMNI-EPIC</strong>（<a href="https://arxiv.org/abs/2405.15568">Faldor et al. 2024</a>）是对这个循环最完整的一次尝试。任务生成器（Claude 3 Opus）读一个记着已学会和失败任务的档案库，提出一个可学又有趣的新任务；环境生成器把它写成带奖励和单独成功检查的 Python；有趣度模型（GPT-4o）丢掉与相近任务相比不够新颖的；RL agent 在仿真器里学习这个任务，结果回到档案库。</p>

  <figure class="post-figure paper">
  <img src="https://cogito233.github.io/images/blog/papers/omni-epic-fig1.png" alt="OMNI-EPIC 循环：左边是仿真场景的任务档案库；任务生成器、环境生成器、生成后的有趣度模型、RL 训练和成功检测器连成一圈回到档案库。" loading="lazy" />
  <figcaption>OMNI-EPIC 的循环。任务生成器、环境生成器和有趣度模型是语言模型；agent 用 RL（DreamerV3）训练，成功判定由 LLM 写出的代码完成，而不是调用模型。（图源：<a href="https://arxiv.org/abs/2405.15568">Faldor et al. 2024</a>）</figcaption>
</figure>

  <p>200 轮之后任务从导航扩散到物体操作，跨过有移动段的彩虹桥、把球踢进移动的球门；带真实 RL 的短运行里 agent 学会 16 个任务、失败 6 个。<em>为什么是三阶，又为什么没有落地。</em> 没有任何具名能力交进去，系统自己命名任务、自己写成功检查。但成功函数出自写任务的同一个模型，”有趣”是另一次语言模型调用，两者都没有外部依据让人信任，它的任务也没有一个被别人当 benchmark 采用。</p>

  <h3 id="section-2">这条线上的其他人</h3>

  <p>这个想法有十几年了。<strong>PowerPlay</strong>（<a href="https://arxiv.org/abs/1112.5309">Schmidhuber 2011</a>）已经让系统自己去找当前求解器还解不了的最简单任务，再把它学会，任务由系统自己发明。<strong>POET</strong>（<a href="https://arxiv.org/abs/1901.01753">Wang et al. 2019</a>）在一个参数化的环境族里让障碍赛道和双足行走者共同进化，奖励是前进距离。<strong>AI-GAs</strong>（<a href="https://arxiv.org/abs/1905.10985">Clune 2019</a>）把自动生成学习环境列为通往通用 AI 的三根支柱之一，没有给方法。<strong>AI Scientist</strong>（<a href="https://arxiv.org/abs/2408.06292">Lu et al. 2024</a>；<a href="https://arxiv.org/abs/2504.08066">v2 2025</a>）自己提研究问题、做实验、写论文，语言模型当审稿人；v2 有一篇在 ICLR 2025 的一个 workshop 评审分过了录用线，随后作者撤稿。<strong>PaperBench</strong>（<a href="https://arxiv.org/abs/2504.01848">Starace et al. 2025</a>）测的是反方向，对着 8,316 条 rubric 用语言模型判分，复现 20 篇 ICML 2024 论文；最好的 agent 21.0%，三篇子集上 ML 博士生 41.4%，o1 26.6%。这些工作的验证器无一例外都是造的，而且都是语言模型。</p>

  <h3 id="section-3">人做成过的三阶</h3>

  <p>从人做成的两次三阶事件里，可以看出验证器选对了是什么样子。</p>

  <p><strong>HumanEval</strong>（<a href="https://arxiv.org/abs/2107.03374">Chen et al. 2021</a>）是 164 道手写的编程题，每道带函数签名、docstring 和平均 7.7 个单元测试，作者手写是为了保证训练数据里不可能有它。五年后它还是 164 道。</p>

  <p><strong>SWE-bench</strong>（<a href="https://arxiv.org/abs/2310.06770">Jimenez et al. 2023</a>）从另一个观察出发：一个改了测试文件的已合并 pull request，天然带着一个因这次修复由失败转为通过的测试。作者从 12 个 Python 仓库抓了约 90,000 个 pull request，留下既解决了 issue 又碰了测试文件的已合并 PR，然后在修复前后各跑一遍测试，只留至少有一个 fail-to-pass 测试的实例。漏斗从 93,139 个 PR 收窄到 11,407 个候选，再到 2,294 道题。当时最好的模型 Claude 2 解出 1.96%。一年之内 OpenAI 请 <a href="https://openai.com/index/introducing-swe-bench-verified/">93 位开发者筛了 1,699 道</a>，做出 500 道的 Verified 子集；不到三年，上文整个二阶一节讲的东西都长在了它上面。</p>

  <p>两个验证器在质量上分不出高下：客观、秒级、可并行、低噪声。差别只有一处。一个是专为这个 benchmark 写的，另一个是素不相识的人为了维护自己的仓库早就写好的，远在有人想到拿它训练之前。这又是二阶里借与造的区分，它决定一次三阶事件会不会长成一个二阶产业。</p>

  <p><strong>RSI-Exam</strong> 展示了人把三阶做成一套可重复流程的样子：领域专家提出任务和指标，跑一个弱基线和一个更强的参考解来定标尺；开发者打包成两个隔离镜像，声明产出物契约，藏好隐藏数据；一位审核者过一套 90 多条的清单，覆盖价值、可测性、来源和每一条泄漏路径；另一位对着锚点分析一条完整的 agent 轨迹。88 道题都是这么造的，全部手工。</p>

  <h2 id="zh-open">开放问题</h2>

  <p>这样排开来看，记录很短。agent 能做完一阶。二阶在大规模上是人设计、agent 执行的管线在做，人的份额逐年缩小。三阶尝试了十年，没有产出过任何被别人使用的 benchmark。前沿实验室所说的 RSI，大多是一阶的工程部分（进展很快），加上三阶的研究部分（还没人做成）。阶数不是价值排序：一阶的 AlphaEvolve 打破了 56 年没动的上界并且在生产环境里跑着，二阶造出的环境是近期开放权重模型在 SWE-bench Verified 上进步的重要来源之一：仅用 SWE-Universe 做中期训练，就把 Qwen3-Next 从 50.3% 带到 61% 以上。</p>

  <p>下一步该做的测试很容易说清，却还没人跑过：把 SWE-bench Verified 交给一个 agent，别的什么都不给，看它能不能自己写出一份 SWE-smith，包括”仓库测试就是验证器”这个决定。这背后是本文一直绕回来的那个问题：机器能不能注意到”pull request 里有测试”这种事，还是说这个观察就是留给人的那部分。而失败模式在低一阶已经显现：DGM 的 objective hacking 靠把检查器藏起来抓住了，等到 agent 自己写检查器的时候，这一招就没有了。</p>

  <h2 id="zh-disclaimer">声明</h2>

  <blockquote>
    <p>本文由一个 AI coding agent（Claude Code）起草、对照所引论文核对事实并排版，与作者的协作方式正是上文的零阶：作者下指令、逐条验收，agent 的工作没有沉淀成一个更好的 agent。经过这个循环仍然留下的错误，责任在作者。</p>
  </blockquote>

  <h2 id="zh-cite">引用本文</h2>

  <p>引用格式：</p>

  <blockquote>
    <p>Lyu, Zhiheng. (Sep 2026). “How Far Has RSI Gotten in Post-Training?”. cogito233.github.io. https://cogito233.github.io/blog/three-orders-of-self-improvement/.</p>
  </blockquote>

  <p>或</p>

  <div class="cite-box">
    <div class="language-bibtex highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">@article</span><span class="p">{</span><span class="nl">lyu2026rsi</span><span class="p">,</span>
  <span class="na">title</span>   <span class="p">=</span> <span class="s">"How Far Has RSI Gotten in Post-Training?"</span><span class="p">,</span>
  <span class="na">author</span>  <span class="p">=</span> <span class="s">"Lyu, Zhiheng"</span><span class="p">,</span>
  <span class="na">journal</span> <span class="p">=</span> <span class="s">"cogito233.github.io"</span><span class="p">,</span>
  <span class="na">year</span>    <span class="p">=</span> <span class="s">"2026"</span><span class="p">,</span>
  <span class="na">month</span>   <span class="p">=</span> <span class="s">"Sep"</span><span class="p">,</span>
  <span class="na">url</span>     <span class="p">=</span> <span class="s">"https://cogito233.github.io/blog/three-orders-of-self-improvement/"</span>
<span class="p">}</span>
</code></pre></div>    </div>
  </div>

  <h2 id="zh-references">参考文献</h2>

  <div class="references">

    <ol>
      <li>A. Karpathy. <a href="https://github.com/karpathy/autoresearch">“AutoResearch.”</a> GitHub, 2026.</li>
      <li><a href="https://arxiv.org/abs/2609.15364">“RSIAgent.”</a> arXiv preprint arXiv:2609.15364 (2026).</li>
      <li>A. Novikov et al. (Google DeepMind). <a href="https://arxiv.org/abs/2506.13131">“AlphaEvolve: A coding agent for scientific and algorithmic discovery.”</a> arXiv preprint arXiv:2506.13131 (2025). See also the <a href="https://deepmind.google/discover/blog/alphaevolve-a-gemini-powered-coding-agent-for-designing-advanced-algorithms/">blog post</a>.</li>
      <li>J. Zhang, S. Hu, C. Lu, R. Lange, J. Clune. <a href="https://arxiv.org/abs/2505.22954">“Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents.”</a> ICLR 2026.</li>
      <li>H. Wijk et al. <a href="https://arxiv.org/abs/2411.15114">“RE-Bench: Evaluating Frontier AI R&amp;D Capabilities of Language Model Agents against Human Experts.”</a> arXiv preprint arXiv:2411.15114 (2024).</li>
      <li>J. S. Chan et al. <a href="https://arxiv.org/abs/2410.07095">“MLE-bench: Evaluating Machine Learning Agents on Machine Learning Engineering.”</a> arXiv preprint arXiv:2410.07095 (2024).</li>
      <li><a href="https://rsi-exam.ai/">“RSI-Exam: Benchmarking Recursive Self-Improvement through Executable Research.”</a> 2026.</li>
      <li>J. Yang et al. <a href="https://arxiv.org/abs/2504.21798">“SWE-smith: Scaling Data for Software Engineering Agents.”</a> arXiv preprint arXiv:2504.21798 (2025).</li>
      <li>M. Chen et al. (Qwen Team). <a href="https://arxiv.org/abs/2602.02361">“SWE-Universe: Scale Real-World Verifiable Environments to Millions.”</a> arXiv preprint arXiv:2602.02361 (2026).</li>
      <li>Z. Khan et al. <a href="https://arxiv.org/abs/2410.06215">“DataEnvGym: Data Generation Agents in Teacher Environments with Student Feedback.”</a> ICLR 2025.</li>
      <li><a href="https://arxiv.org/abs/2606.01279">“ANDES: Agent Native Data Evolving Synthesis Tool for Autonomous Instruction Alignment.”</a> arXiv preprint arXiv:2606.01279 (2026).</li>
      <li><a href="https://arxiv.org/abs/2601.05808">“EnvScaler: Scaling Tool-Interactive Environments for LLM Agents via Programmatic Synthesis.”</a> Findings of ACL 2026.</li>
      <li><a href="https://arxiv.org/abs/2601.22975">“Golden Goose: A Simple Trick to Synthesize Unlimited RLVR Tasks from Unverifiable Internet Text.”</a> arXiv preprint arXiv:2601.22975 (2026).</li>
      <li>J. Pan et al. <a href="https://arxiv.org/abs/2412.21139">“Training Software Engineering Agents and Verifiers with SWE-Gym.”</a> arXiv preprint arXiv:2412.21139 (2024).</li>
      <li>N. Jain et al. <a href="https://arxiv.org/abs/2504.07164">“R2E-Gym: Procedural Environments and Hybrid Verifiers for Scaling Open-Weights SWE Agents.”</a> COLM 2025.</li>
      <li><a href="https://arxiv.org/abs/2505.20411">“SWE-rebench: An Automated Pipeline for Task Collection and Decontaminated Evaluation of Software Engineering Agents.”</a> NeurIPS 2025.</li>
      <li><a href="https://arxiv.org/abs/2603.13023">“daVinci-Env.”</a> arXiv preprint arXiv:2603.13023 (2026).</li>
      <li>M. Faldor, J. Zhang, A. Cully, J. Clune. <a href="https://arxiv.org/abs/2405.15568">“OMNI-EPIC: Open-endedness via Models of human Notions of Interestingness with Environments Programmed in Code.”</a> ICLR 2025.</li>
      <li>R. Wang et al. <a href="https://arxiv.org/abs/1901.01753">“Paired Open-Ended Trailblazer (POET).”</a> arXiv preprint arXiv:1901.01753 (2019).</li>
      <li>J. Clune. <a href="https://arxiv.org/abs/1905.10985">“AI-GAs: AI-generating algorithms, an alternate paradigm for producing general artificial intelligence.”</a> arXiv preprint arXiv:1905.10985 (2019).</li>
      <li>C. Lu et al. <a href="https://arxiv.org/abs/2408.06292">“The AI Scientist.”</a> arXiv preprint arXiv:2408.06292 (2024); <a href="https://arxiv.org/abs/2504.08066">“The AI Scientist-v2.”</a> arXiv preprint arXiv:2504.08066 (2025).</li>
      <li>G. Starace et al. <a href="https://arxiv.org/abs/2504.01848">“PaperBench: Evaluating AI’s Ability to Replicate AI Research.”</a> arXiv preprint arXiv:2504.01848 (2025).</li>
      <li>M. Chen et al. <a href="https://arxiv.org/abs/2107.03374">“Evaluating Large Language Models Trained on Code”</a> (HumanEval). arXiv preprint arXiv:2107.03374 (2021).</li>
      <li>C. E. Jimenez et al. <a href="https://arxiv.org/abs/2310.06770">“SWE-bench: Can Language Models Resolve Real-World GitHub Issues?”</a> ICLR 2024.</li>
      <li>OpenAI. <a href="https://openai.com/index/introducing-swe-bench-verified/">“Introducing SWE-bench Verified.”</a> Blog post, August 2024.</li>
      <li>J. Schmidhuber. <a href="https://arxiv.org/abs/1112.5309">“PowerPlay: Training an Increasingly General Problem Solver by Continually Searching for the Simplest Still Unsolvable Problem.”</a> arXiv preprint arXiv:1112.5309 (2011).</li>
    </ol>
  </div>

</div>

<script>
(function () {
  var KEY = 'blog-lang';
  function set(l) {
    document.querySelectorAll('.lang').forEach(function (d) { d.hidden = !d.classList.contains('lang-' + l); });
    document.querySelectorAll('.lang-btn').forEach(function (b) {
      var on = b.getAttribute('data-lang') === l;
      b.classList.toggle('is-active', on); b.setAttribute('aria-selected', on ? 'true' : 'false');
    });
    try { localStorage.setItem(KEY, l); } catch (e) {}
  }
  var l = null, h = decodeURIComponent(location.hash.replace('#', ''));
  if (h === 'zh' || h === '中文版' || h.indexOf('zh-') === 0) l = 'zh';
  else if (h === 'en') l = 'en';
  if (!l) { try { l = localStorage.getItem(KEY); } catch (e) {} }
  /* default is always English; no browser-language guessing.
     NOTE: keep block comments here. The compress layout collapses this script
     onto one line, so a // comment would swallow everything after it. */
  if (l !== 'en' && l !== 'zh') l = 'en';
  /* jump menu on the right: built from the visible language block's h2/h3 */
  var toc = document.createElement('nav'); toc.className = 'toc-right'; toc.setAttribute('aria-label', 'Jump to');
  var main = document.getElementById('main'); if (main) main.appendChild(toc);
  var links = [];
  function buildToc(lang) {
    var block = document.querySelector('.lang-' + lang); if (!block) return;
    var hs = block.querySelectorAll('h2, h3'); links = [];
    var html = '<div class="toc-right__title">' + (lang === 'zh' ? '目录' : 'Jump to') + '</div><ol>';
    hs.forEach(function (h) {
      if (!h.id) return;
      var t = h.textContent.replace(/\s+/g, ' ').trim();
      if (/^(Citation|References|引用本文|参考文献)$/.test(t)) return;
      html += '<li class="lvl' + h.tagName[1] + '"><a href="#' + h.id + '">' + t + '</a></li>';
    });
    toc.innerHTML = html + '</ol>';
    links = Array.prototype.slice.call(toc.querySelectorAll('a'));
    links.forEach(function (a) {
      a.addEventListener('click', function (e) {
        var el = document.getElementById(a.getAttribute('href').slice(1)); if (!el) return;
        e.preventDefault();
        window.scrollTo({ top: el.getBoundingClientRect().top + window.scrollY - 24, behavior: 'smooth' });
        if (history.replaceState) history.replaceState(null, '', '#' + el.id);
      });
    });
  }
  function mark() {
    var y = window.scrollY + 120, cur = null;
    links.forEach(function (a) { var el = document.getElementById(a.getAttribute('href').slice(1)); if (el && el.offsetTop <= y) cur = a; });
    links.forEach(function (a) { a.classList.toggle('is-current', a === cur); });
  }
  document.querySelectorAll('.contents-line a[href^="#"]').forEach(function (a) {
    a.addEventListener('click', function (e) {
      var el = document.getElementById(a.getAttribute('href').slice(1)); if (!el) return;
      e.preventDefault(); window.scrollTo({ top: el.getBoundingClientRect().top + window.scrollY - 24, behavior: 'smooth' });
    });
  });
  window.addEventListener('scroll', mark, { passive: true });
  set(l); buildToc(l); mark();
  document.querySelectorAll('.lang-btn').forEach(function (b) {
    b.addEventListener('click', function () { var nl = b.getAttribute('data-lang'); set(nl); buildToc(nl); window.scrollTo({ top: 0 }); mark(); });
  });
})();
</script>]]></content><author><name>Zhiheng Lyu</name><email>zhihenglyu.cs@gmail.com</email></author><category term="evaluation" /><category term="agents" /><category term="self-improvement" /><summary type="html"><![CDATA[Self-refine, self-play, self-evolve, RSI: in post-training one variable separates them, how much of the objective is handed to the agent. Order 0 is a plain code agent. Agents complete order 1 today; order 2 is done by pipelines humans design and agents execute; order 3 has never been done by a machine.]]></summary></entry></feed>