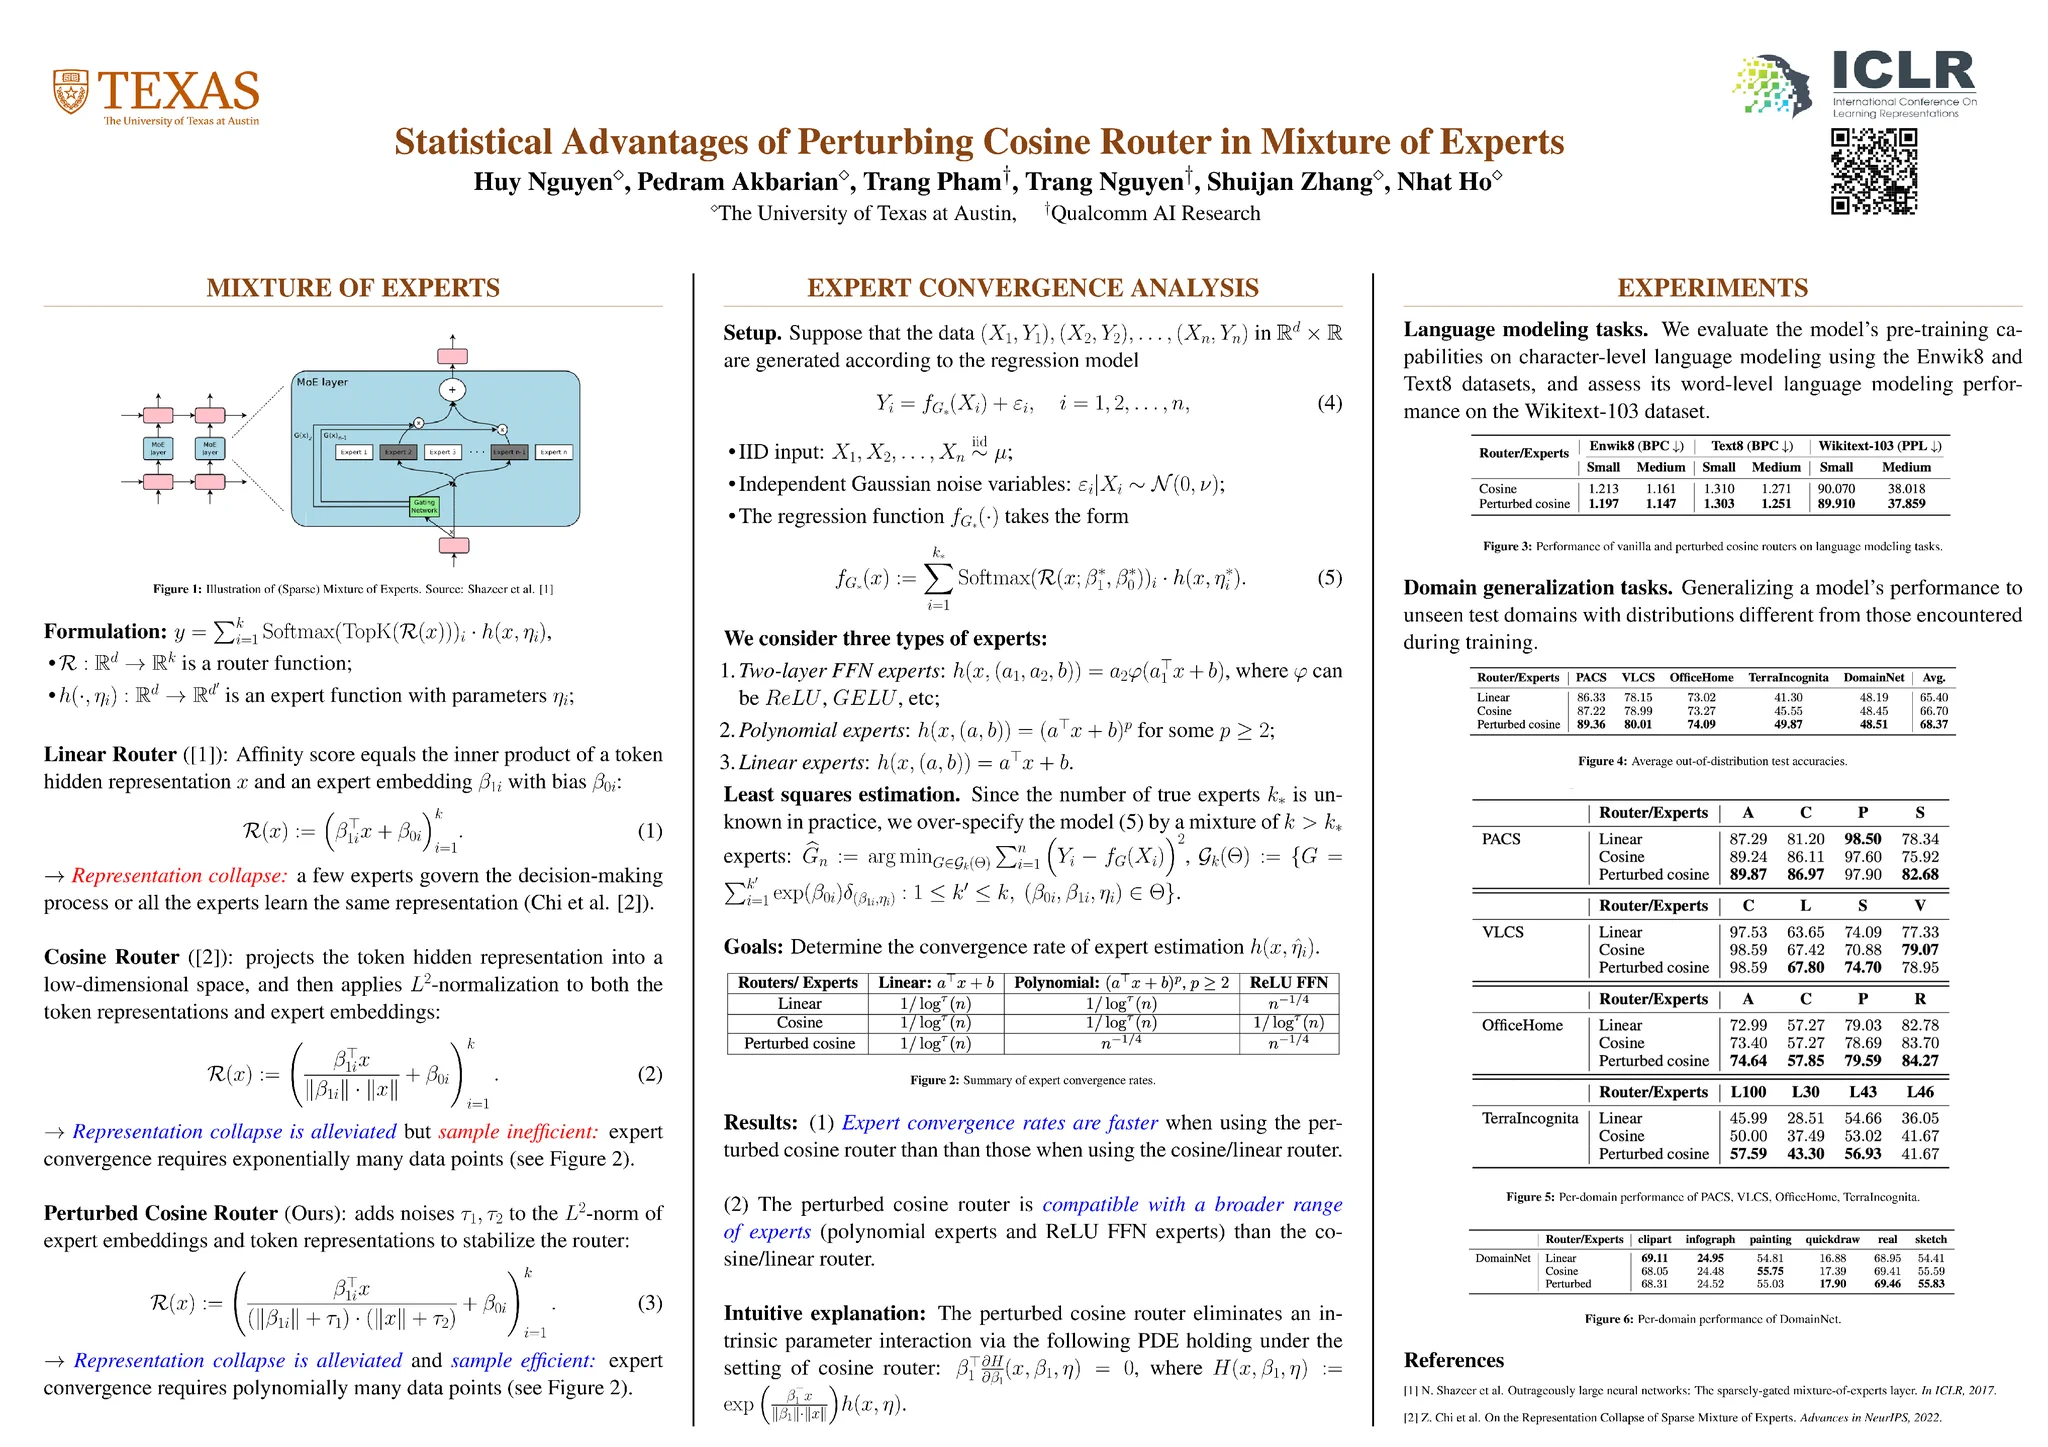
I'm glad to share our #ICLR2025 paper "Statistical Advantages of Perturbing Cosine Router in Mixture of Experts", introducing a novel perturbed cosine router for Mixture of Experts (#MoE) to address the representation collapse and enhance the sample efficiency. [1/n]
Hi everyone, I’ll be at #NeurIPS this year in San Diego. I’d love to chat about efficient design for Mixture of Experts (#MoE), attention mechanism, and their applications in #LLMs and multimodal learning. Let’s have a coffee if you’re interested in these topics 😃.
I’ll present our @NeurIPSConf paper “Sigmoid gating is more sample efficient than Softmax gating in Mixture of Experts” with Prof. Nhat Ho and Prof. Alessandro Rinaldo at
⏰ Dec 11, 11 a.m. - 2 p.m. PST
📍East Exhibit Hall A-C #4921
Please come by to say hi, and chat about MoE.
Toward the end of #ICML2024, I'd like to share another @icmlconf paper of our group, "A General Theory for Softmax Gating Multinomial Logistic Mixture of Experts", where we explore the impacts of the softmax gating on the convergence of MoE under a classification setting. [1/n]
I'm glad to share our #ICML2024 paper "Is Temperature Sample Efficient for Softmax Gaussian Mixture of Experts?". In this work, we study the effects of the dense-to-sparse (Gumble softmax) gate on the convergence of MoE and propose a novel gate to improve the performance. [1/n]