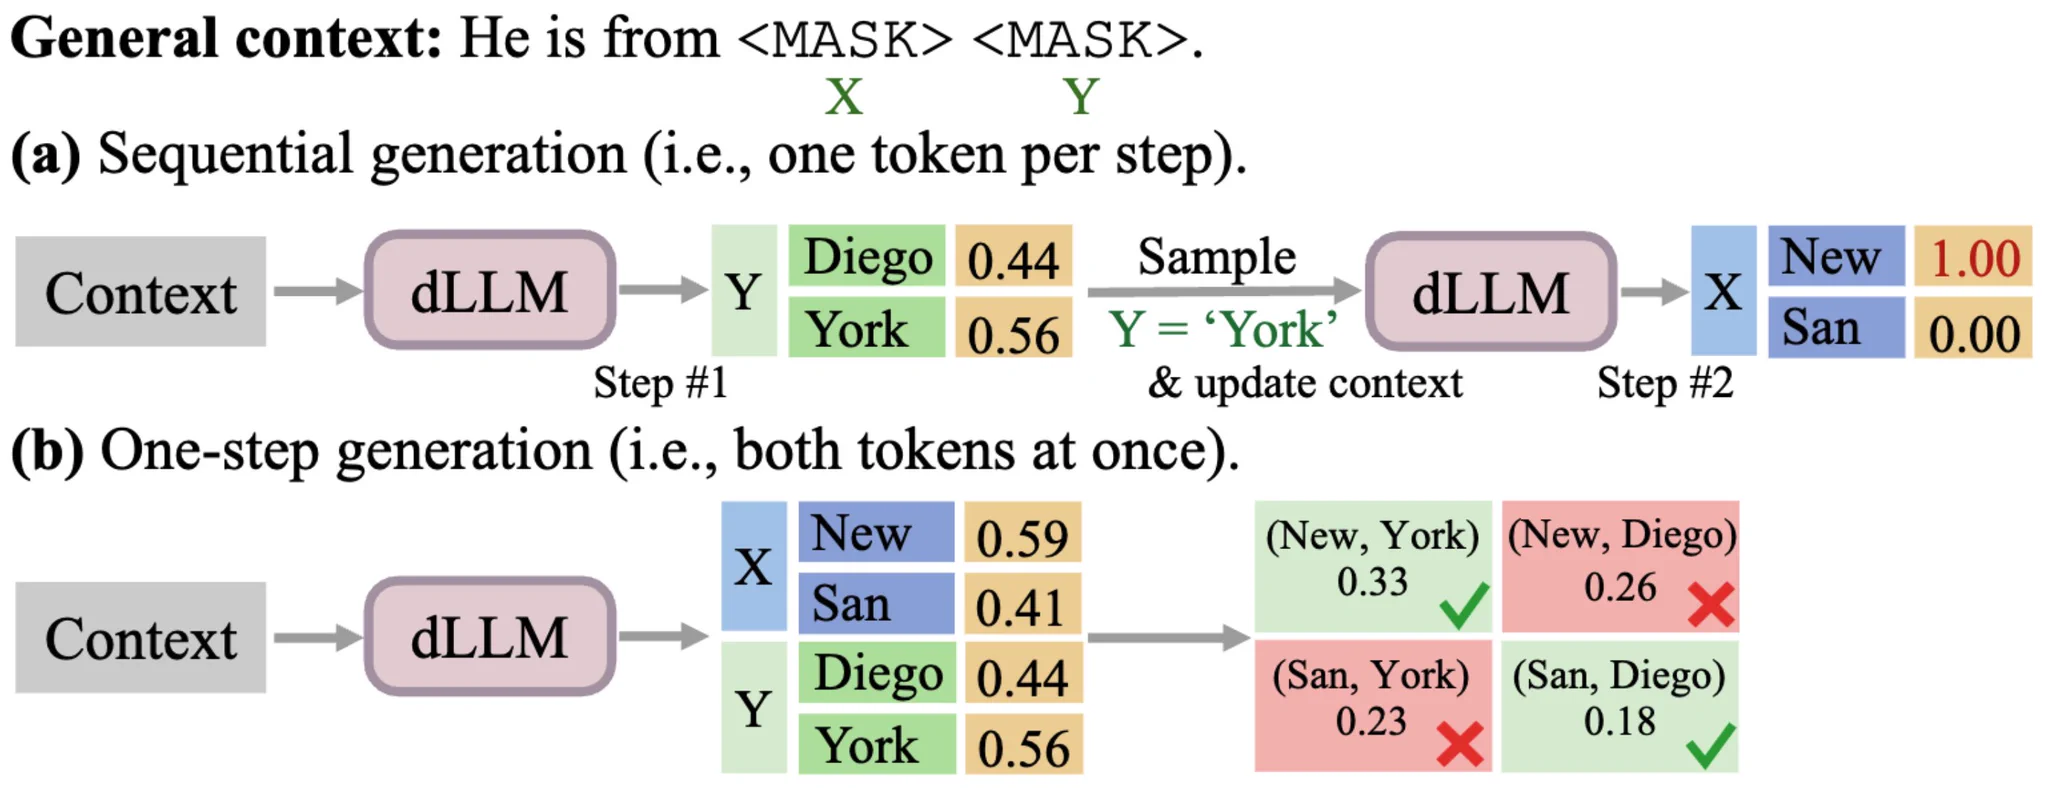
One of the biggest promises of Diffusion LLMs is parallel generation: predicting multiple tokens at once to bypass the sequential bottleneck of autoregressive models.
However, parallel generation comes with a price. For example:
Should the sentence “He is from [MASK] [MASK]” be