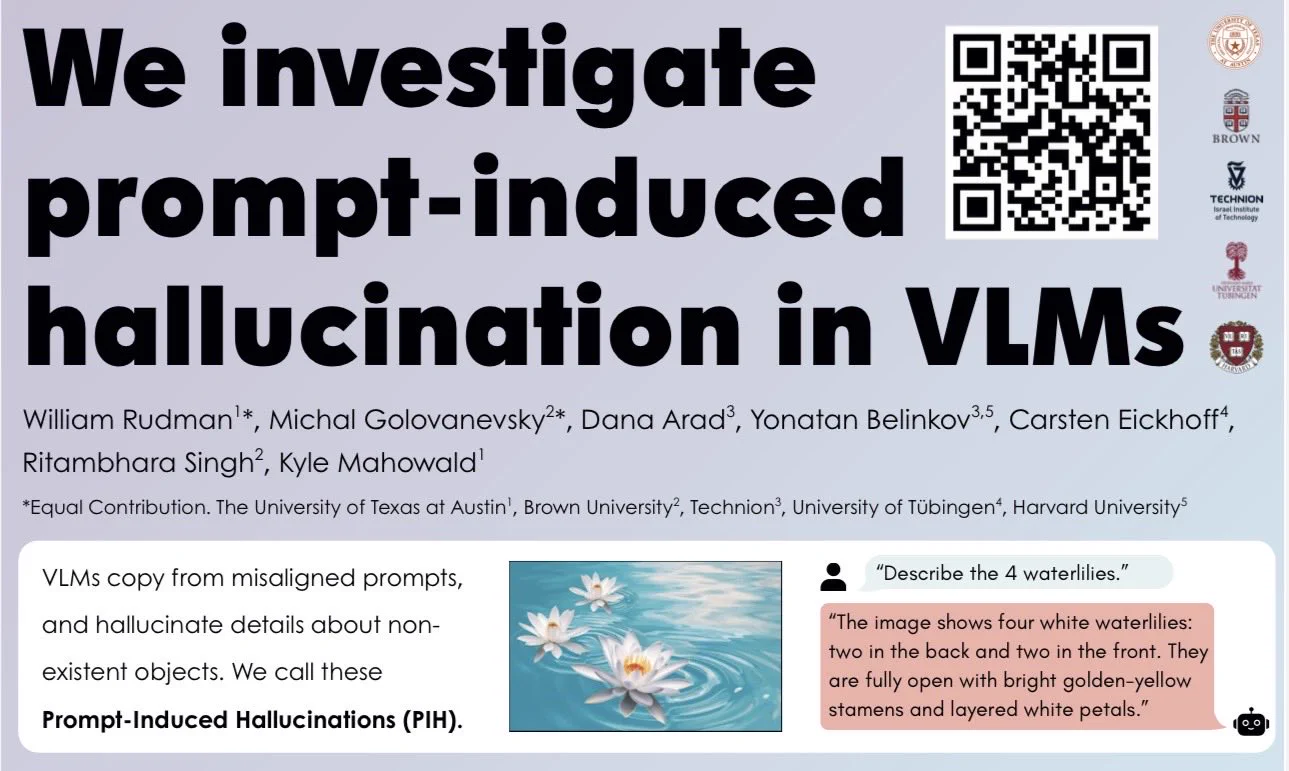
Why do vision–language models follow incorrect prompts even when the image clearly disagrees? We study this behavior as prompt-induced hallucination (PIH) in object counting. [1/6]
Can models predict their own behavior? Check out our #COLM2026 paper (poster presentation today at 4:30pm) showing that even SOTA VLMs contradict their stated introspective rules for “when to call an apple red.”
@MichalGolov and I will be presenting our work locating causal mechanisms of “prompt induced hallucinations” in VLMs at #ACL2026 tomorrow at 11am in the Grand Hall!
📖: arxiv.org/pdf/2601.05201
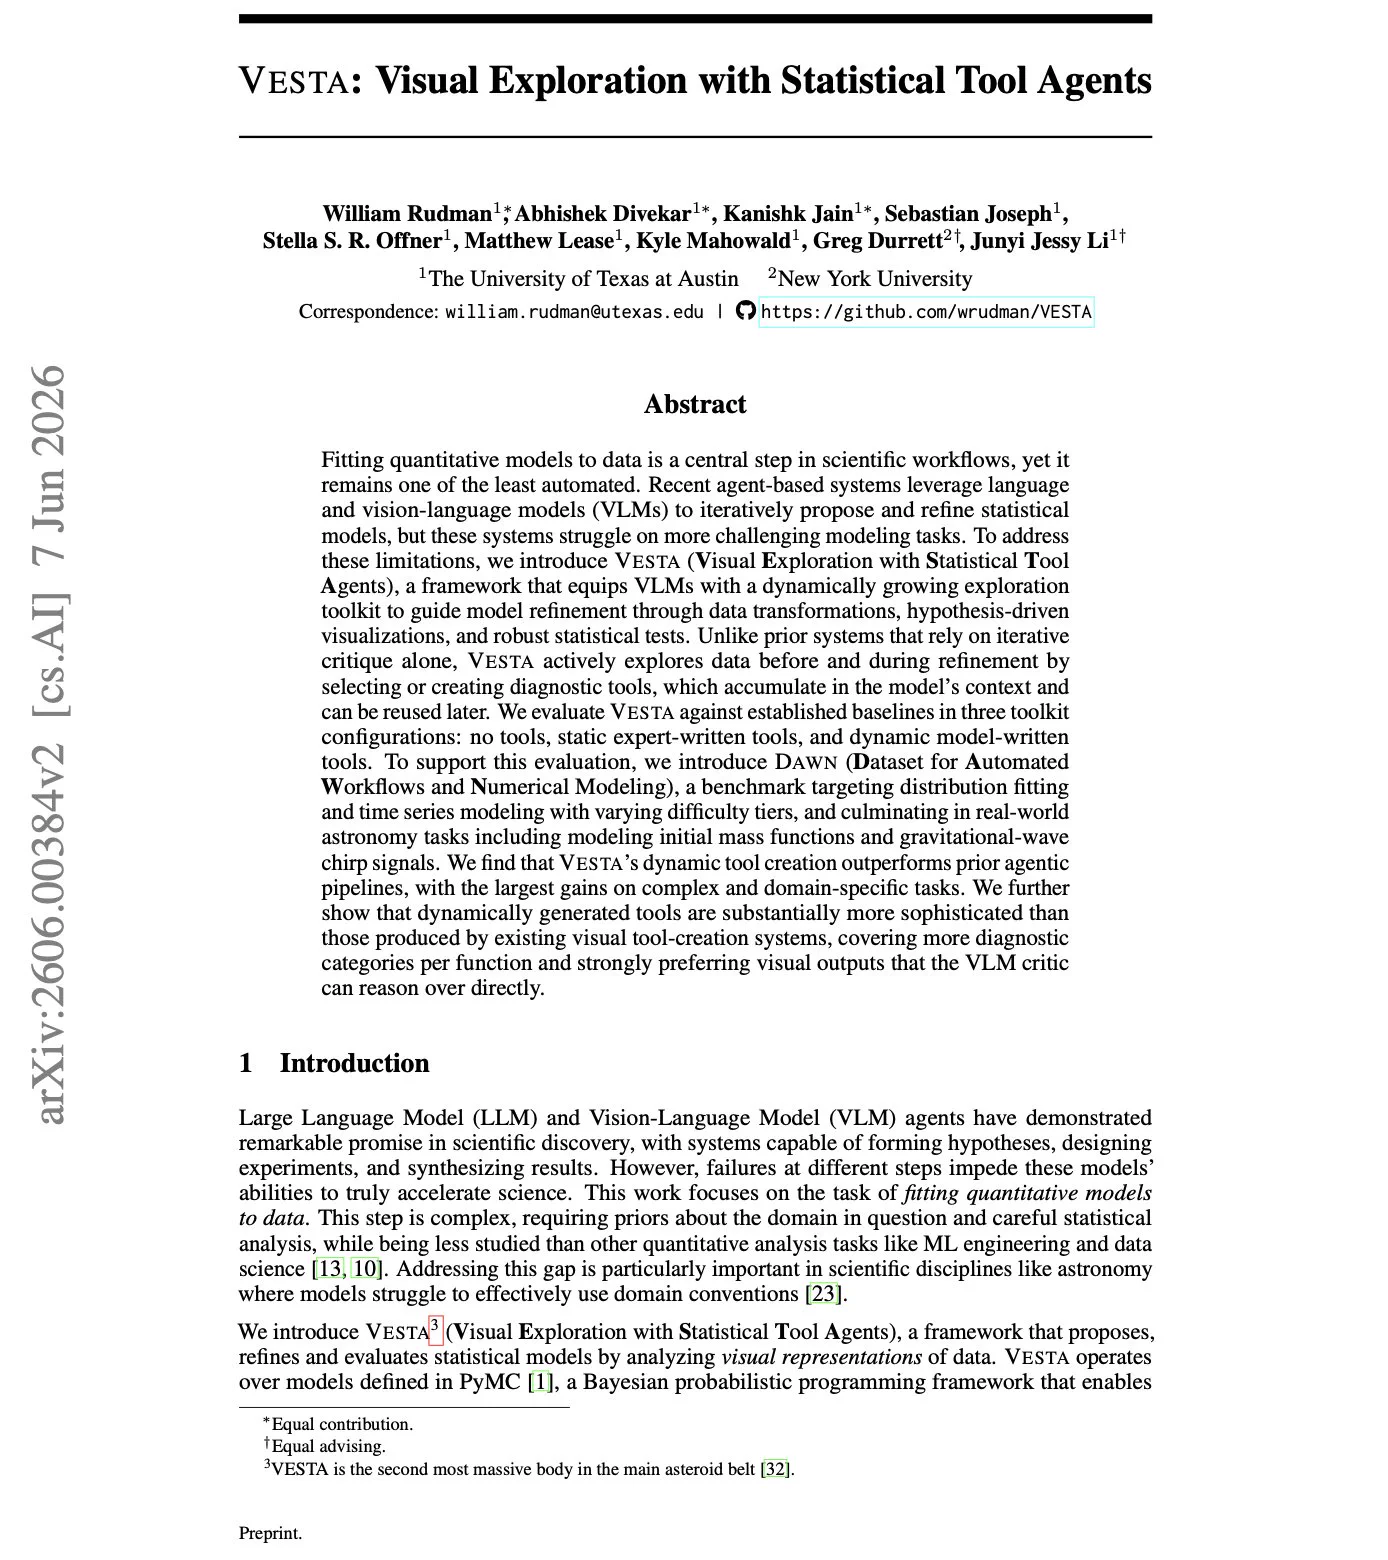
Hypothesis -> experiments -> analysis -> conclusions. LLMs are great at writing code and conducting experiments.
But there’s a weakness in their ability to propose statistical models and evaluate their fit.
Enter VESTA: Visual Exploration with Statistical Tool Agents.
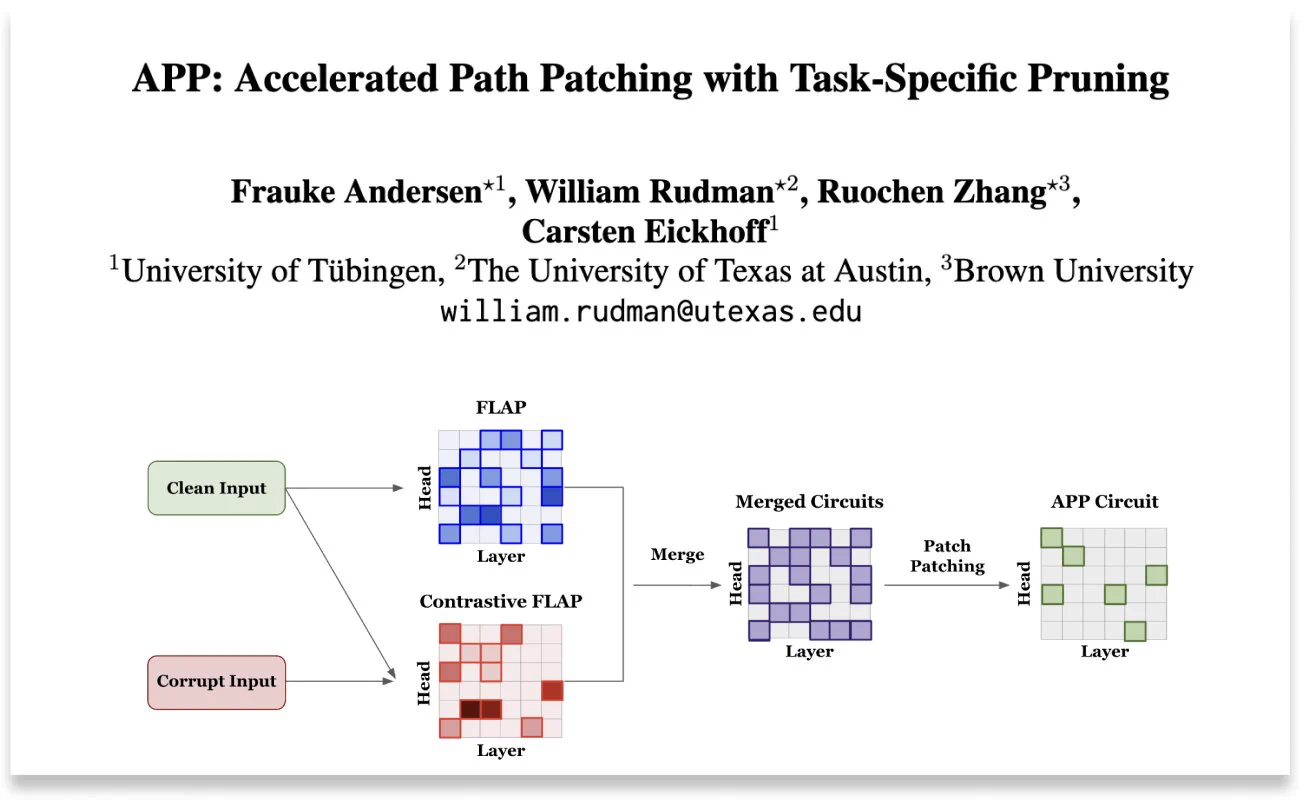
Do you hate running Path Patching on larger models? Accelerated Path Patching can save days of compute time.
APP produces faithful circuits by using contrastive pruning to reduce the search space of circuit discovery methods.
Go save some trees 🌳by using APP to speed up PP.
⚠️Circuit-finding too slow?
We introduce Accelerated Path Patching (APP), a method that uses task-specific pruning to cut down the search space before patching.
🚀APP finds faithful circuits with up to ~93% faster runtime.