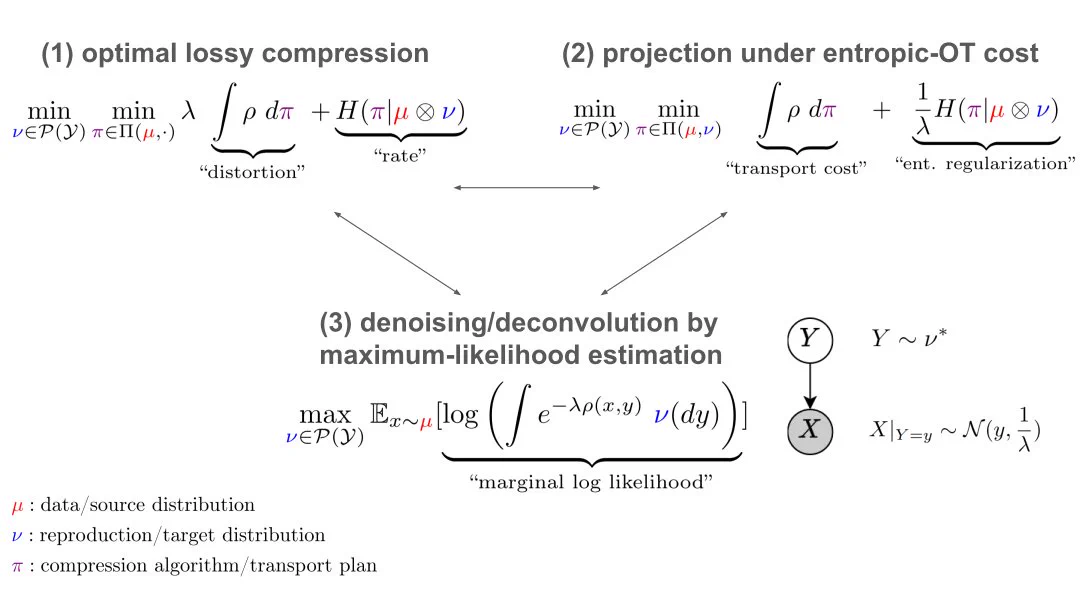
We've known that diffusion models are theoretically very good lossy data compressors , but how can we actually implement this idea in practice? I discuss this and related topics in a new review article on diffusion-based generative compression arxiv.org/abs/2601.18932