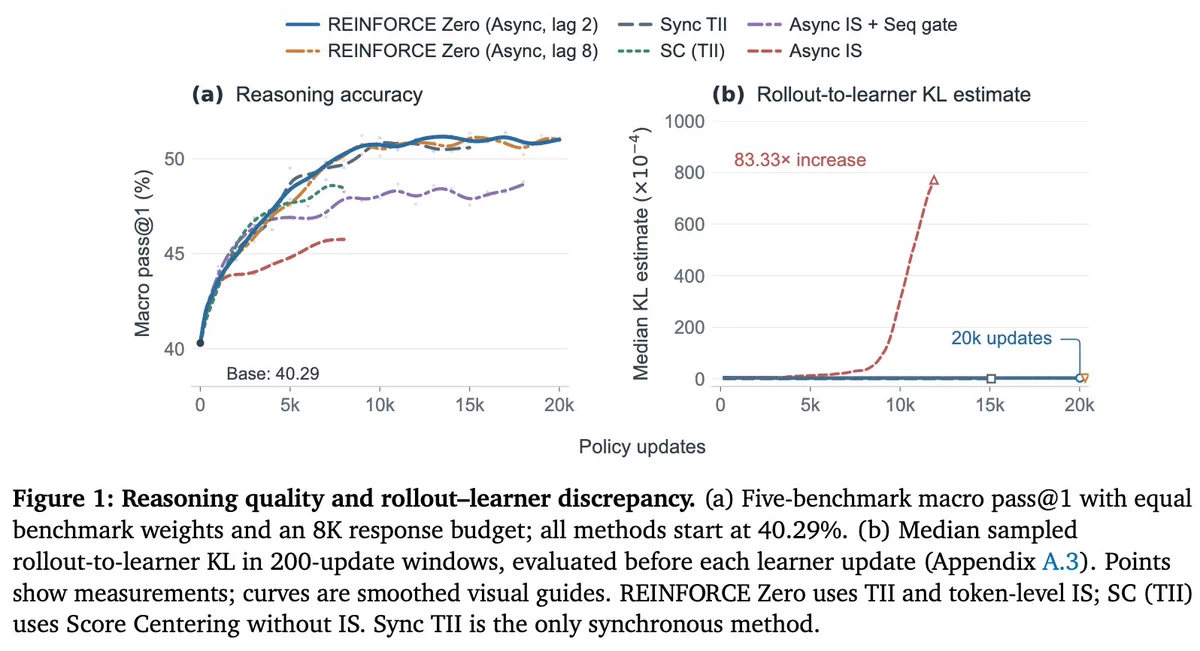
REINFORCE Zero: Trainer–Inference Invariance (TII) + the simplest IS ratio keeps async LLM RL stable for 20,000 updates.
To our knowledge, the first open-source 20K demo of this recipe: unclipped token IS, no rejection gates, a minimal loss.
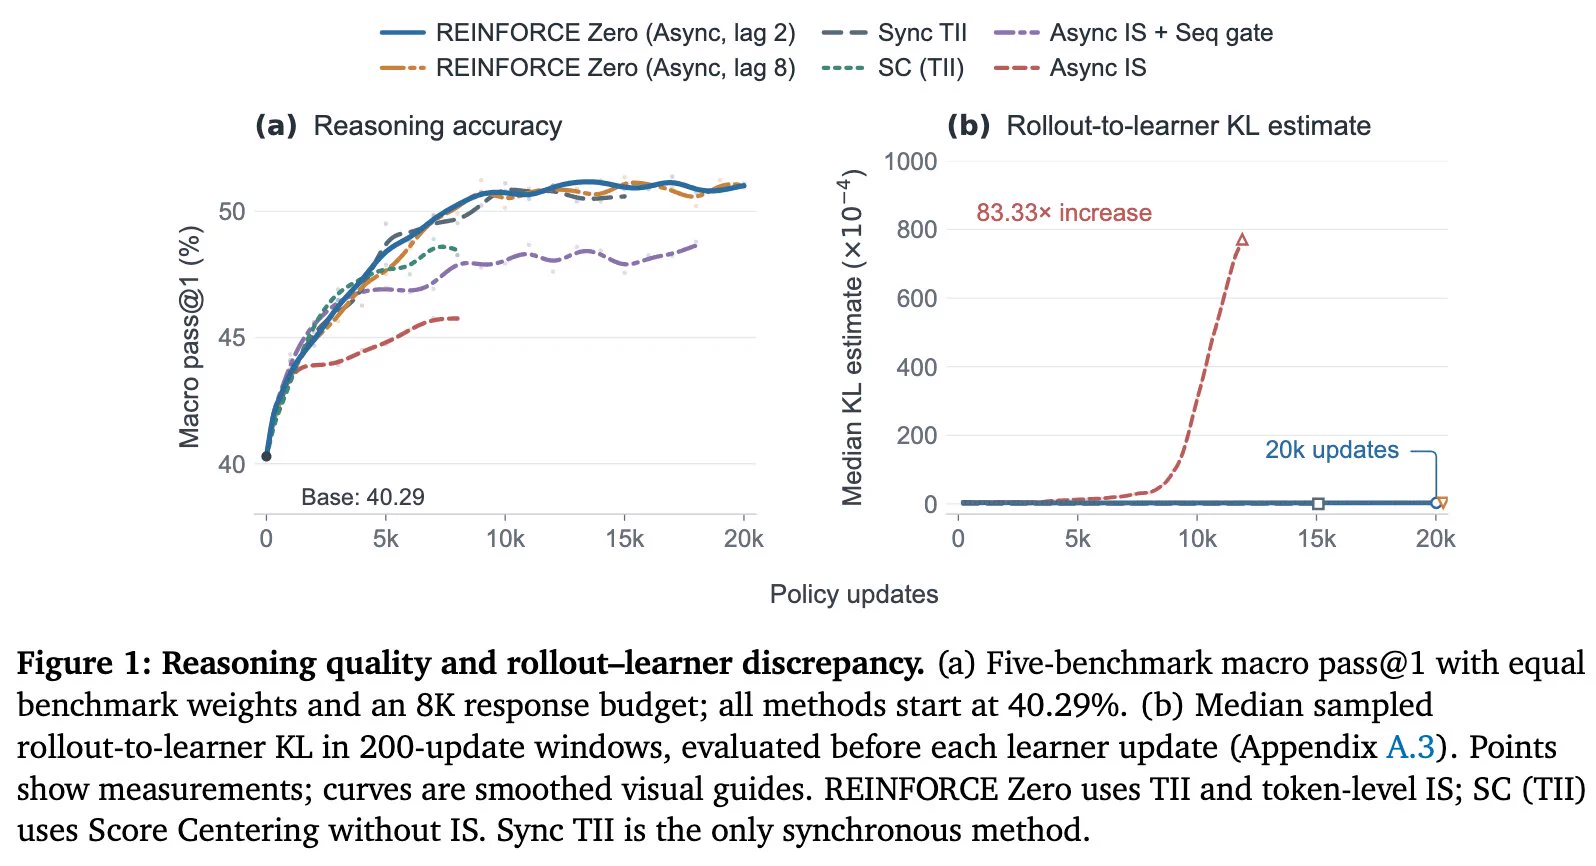
REINFORCE Zero: Trainer–Inference Invariance (TII) + the simplest IS ratio keeps async LLM RL stable for 20,000 updates.
To our knowledge, the first open-source 20K demo of this recipe: unclipped token IS, no rejection gates, a minimal loss.
Very cool, and not just for edge inference.
Light & clean architecture + native multi-harness agentic + multimodal. I think LFMs are the new go-to for quick-iter post-training experiments, especially with Qwen stepping off the sub-10B space.
“Judgement becomes the job.” 👍
Fundamentally, models optimize against past judgements — a collection of existing corpora, programs, and reward models.
We make judgements in a future point, rooted in human nature, situational adaptation and differed by individual tastes, none
Yesterday a junior researcher messaged me, frustrated and a little scared. They had just read that a company pretrained its model with a single researcher. One person for the entire pretraining. no R&D team, no nothing.
If one person and a cluster can do what used to take a
Pretraining a frontier-class model no longer requires a massive team! Mirendil just trained a model with 100B–500B parameters from scratch in 3.5 months, with a single researcher leading the effort. Very excited to see how this work will push the AI boundaries!