Pinned

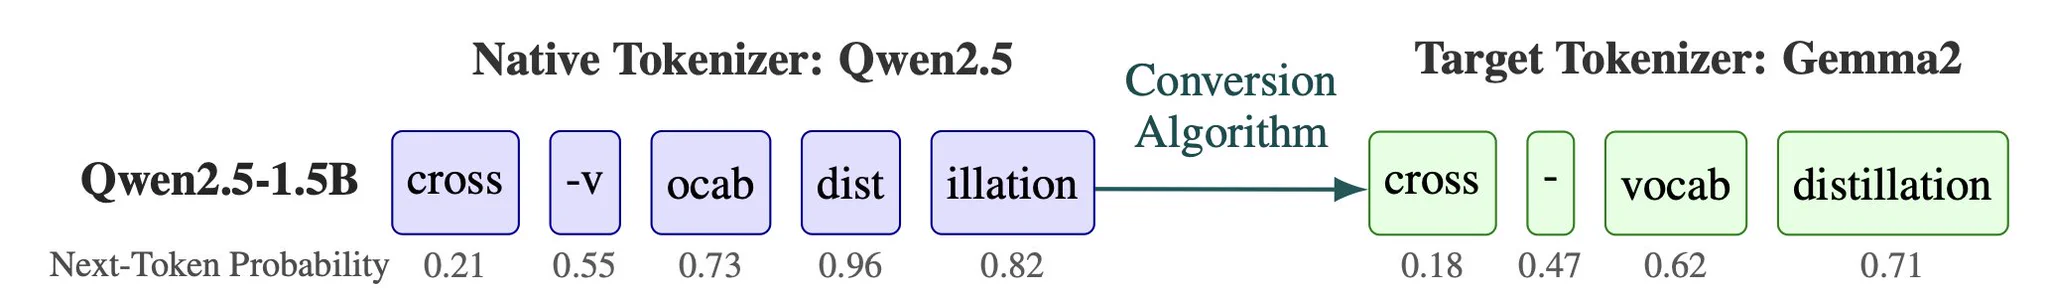
🤔Tokenization (1) makes your LLMs produce odd text when prompts are cut off mid-token? (2) gives you problems when ensembling different LLMs?
💡We solve both by converting tokenized LLMs into equivalent byte-level LLMs! No training required!
📎Paper: arxiv.org/abs/2410.09303