Some personal news: I am starting a new research project at Anthropic. Very excited about this!
Many things are needed to make AGI go well, and alignment is only one of them. More on this soon…
Now is a good time to build institutional mechanisms to pace the frontier of AI development.
The industry is locked into an all-out scaling race to build superintelligence as quickly as possible, and we may need to give everyone more time for safety and alignment mitigations.
In a new paper, we present NLAs, an unsupervised method for converting an LLM's internal state into human-readable text.
I've personally been astonished by our results. I think NLAs substantively advance our ability to understand what LLMs are thinking and audit them for safety
New Anthropic research: Natural Language Autoencoders.
Models like Claude talk in words but think in numbers. The numbers—called activations—encode Claude’s thoughts, but not in a language we can read.
Here, we train Claude to translate its activations into human-readable text.
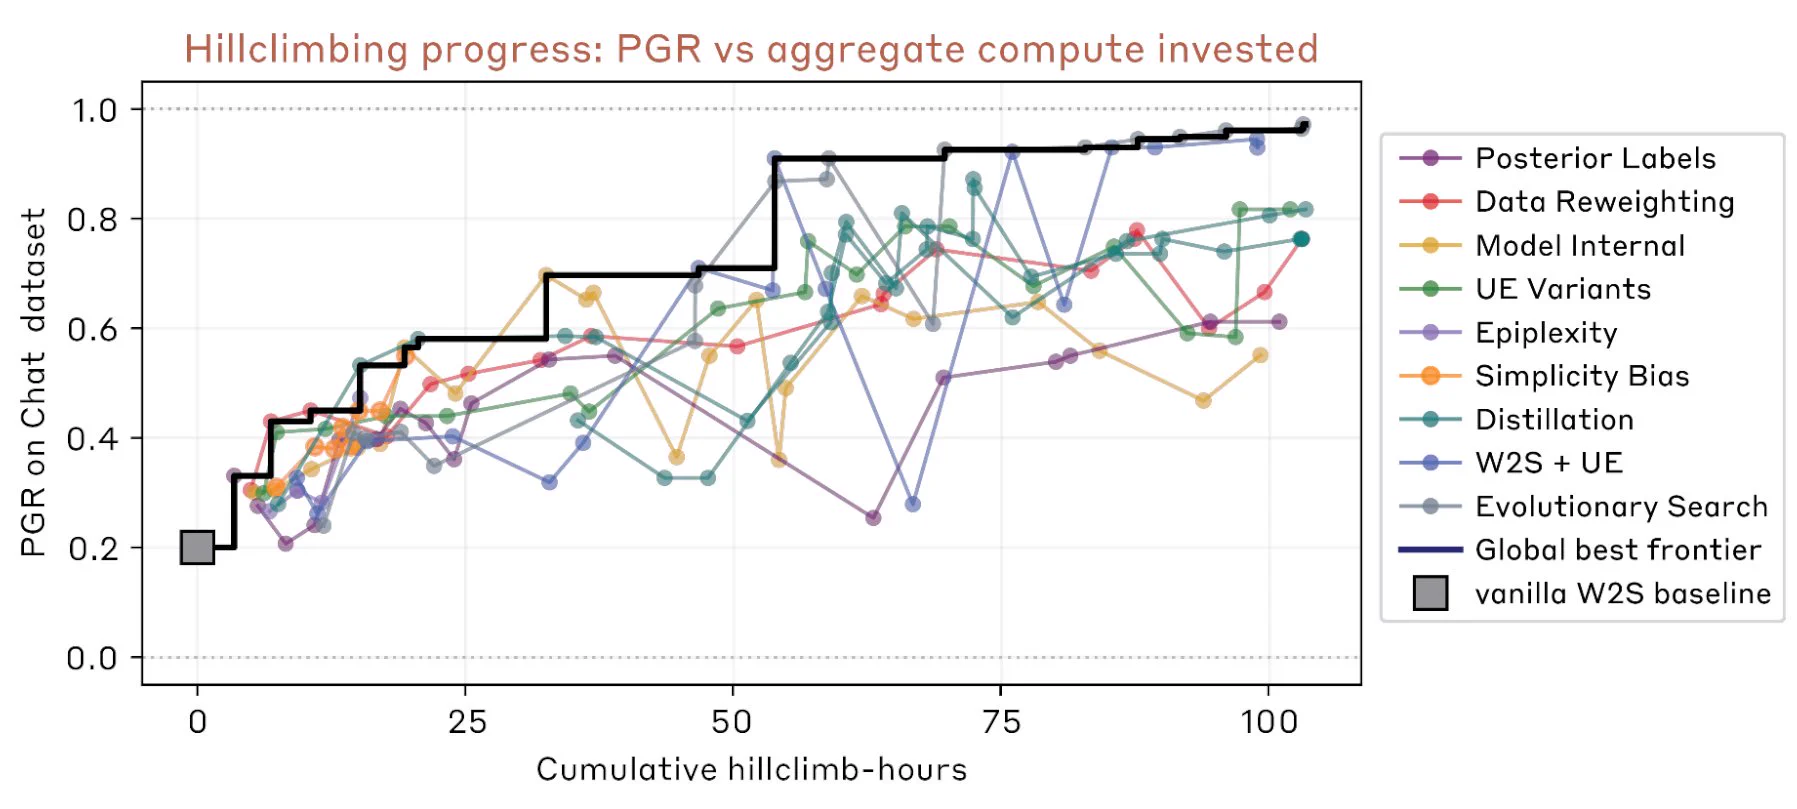
New research result: we use Claude to make fully autonomous progress on scalable oversight research, as measured by performance gap recovered (PGR).
Claude iterates on a number of different techniques and ends up significantly outperforming human researchers for $18k in credits.