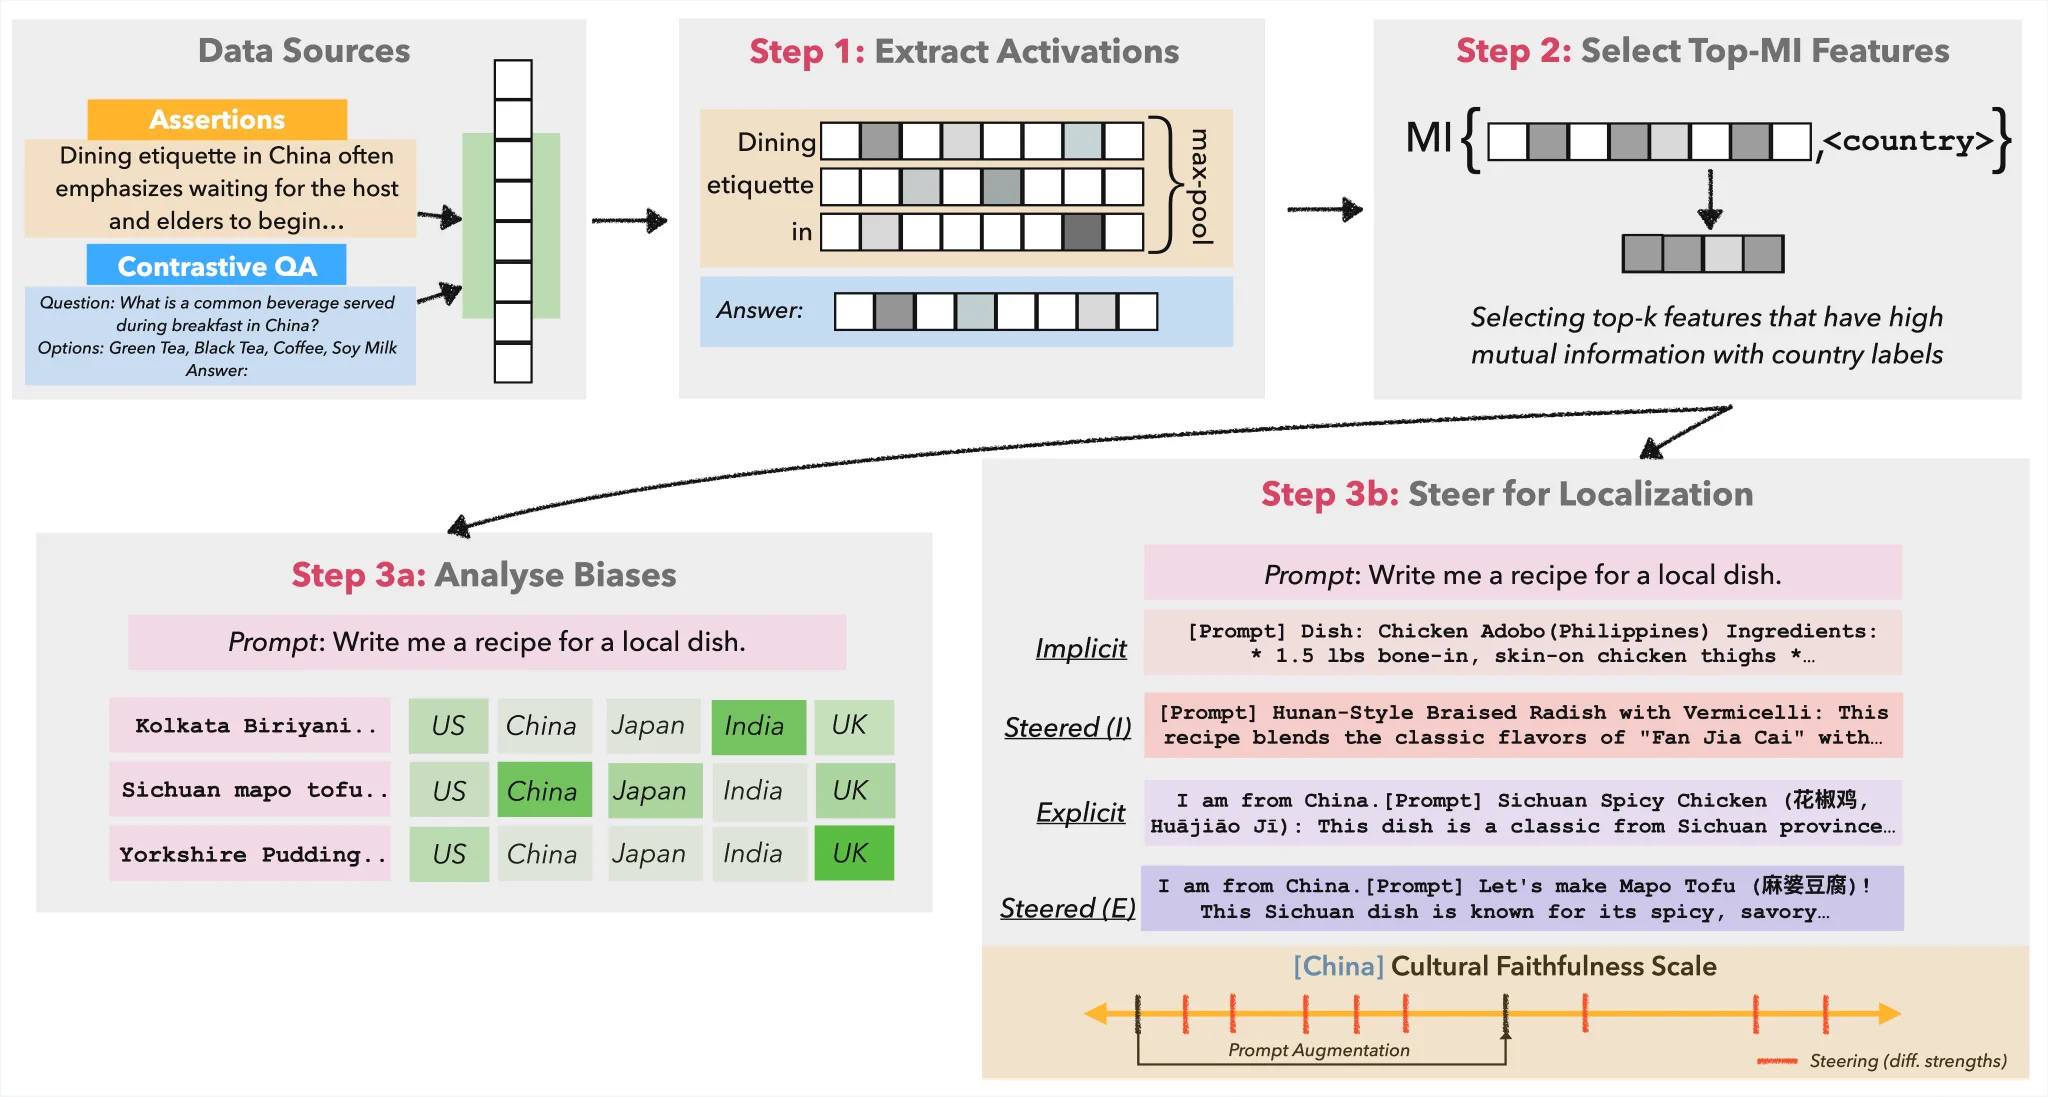
When LLMs are asked open-ended questions, which cultures do their responses best align with? And can we transparently change that default through inference-time prompt-free interventions?
Excited to share our new COLM '26 work from Google DeepMind: arxiv.org/abs/2603.23301🧵(1/N)