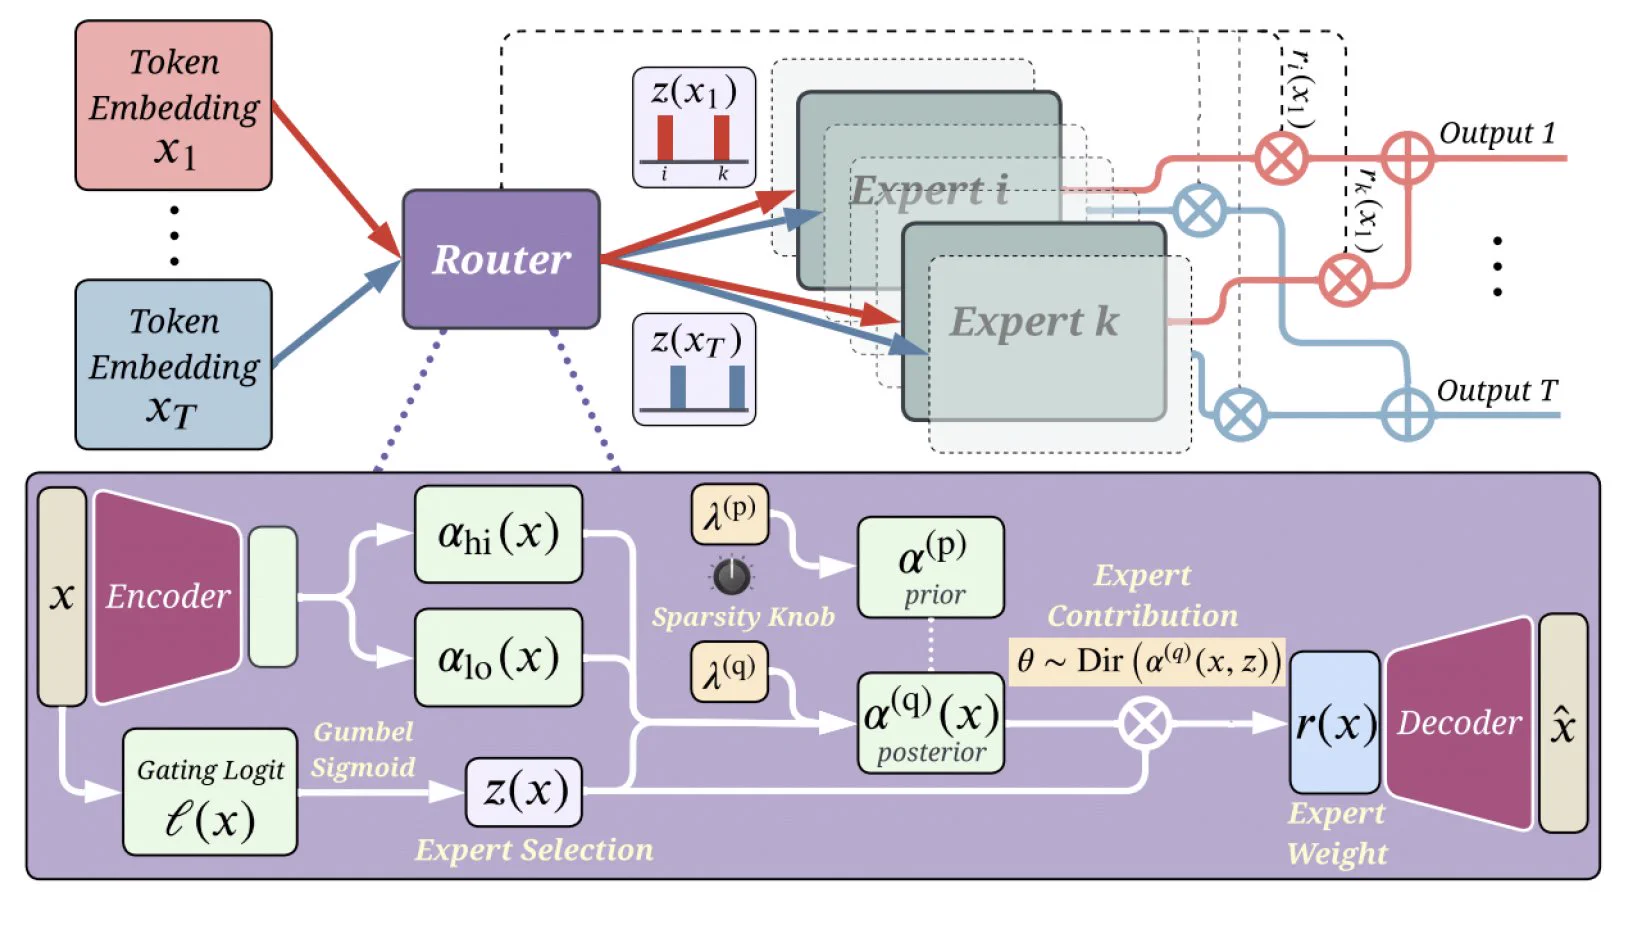
Mixture-of-Experts (MoE) is a powerful way to scale large language models (LLMs): instead of running the full model for every token, a router activates only a few “experts,” giving more capacity at roughly the same compute.
But routing is still a sore spot. Most MoE systems use