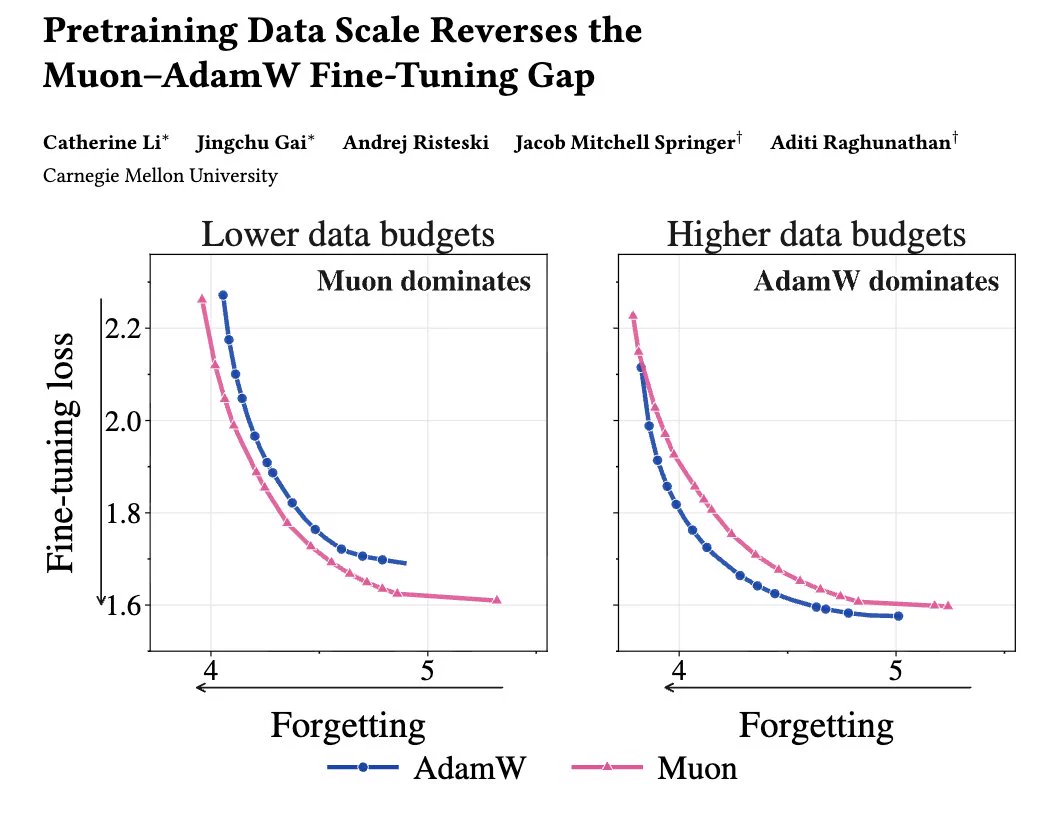
Check our new paper on Post-Train of Muon vs Adam. We show that although Muon is better at Pretrain, Adam is better at Fine-tune

Muon achieves lower loss than AdamW after pretraining, but does its advantage persist after fine-tuning?
Surprisingly, the answer depends on pretraining data scale: beyond a sufficiently large pretraining data budget, AdamW outperforms Muon after fine-tuning!