Pinned

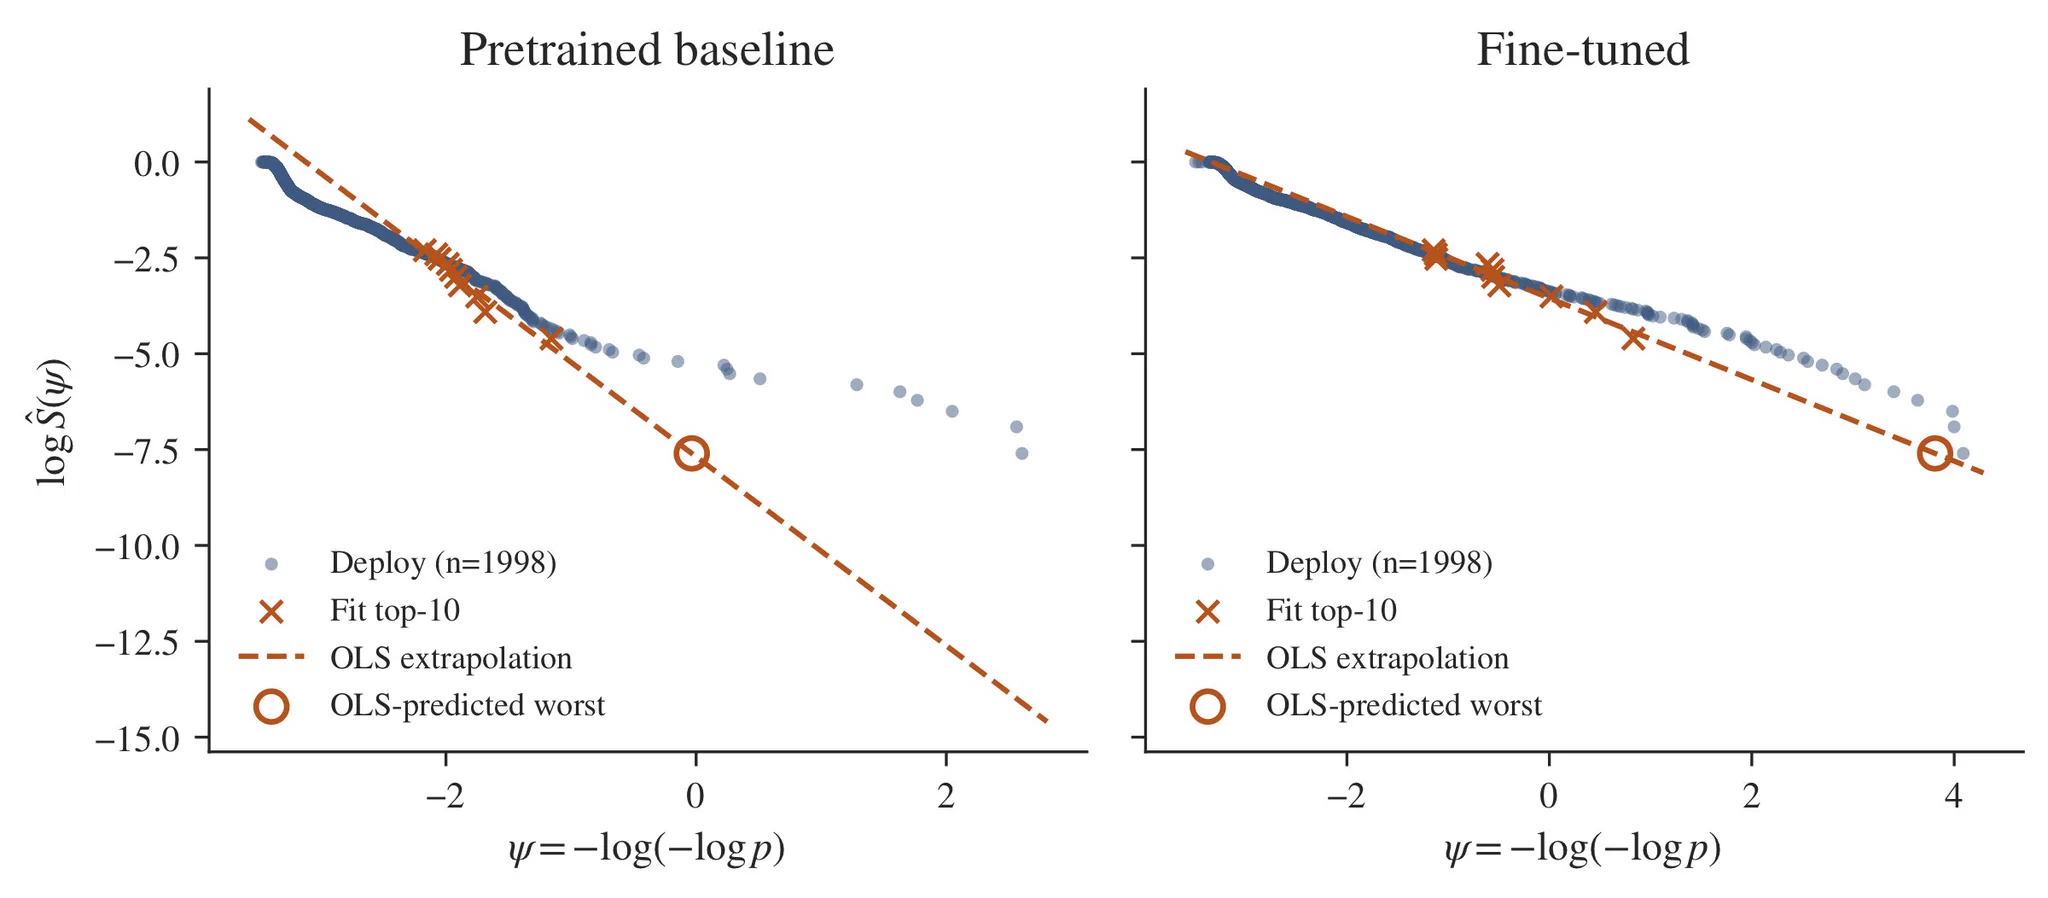
The failures that make an ML model unsafe to deploy are often too rare to appear in any eval. You can forecast them by extrapolating the tail of eval scores, but only if the tail is well-behaved. Our fix: fine-tune the model so its tail is forecastable. 🧵