Maybe a silly question, but why is this considered “reward hacking” instead of something like “the goal state was ambiguous”? Ambiguous as in there is more than one “meaning,” or path to the goal image, and the actual path isn’t specified.
(Maybe it was specified in some other
models grow up so fast :') pan-1 is already reward hacking. here we commanded it with a goal image where it's supposed to be riding a horse but it slips through the fences on foot and then hops up and down to be as high as the horse
Who are the linguists that take LLMs seriously? As in they acknowledge that llms have great implications for the field of linguistics, and are actively curious and studying them.
Where can I find these people? Anyone have any pointers?
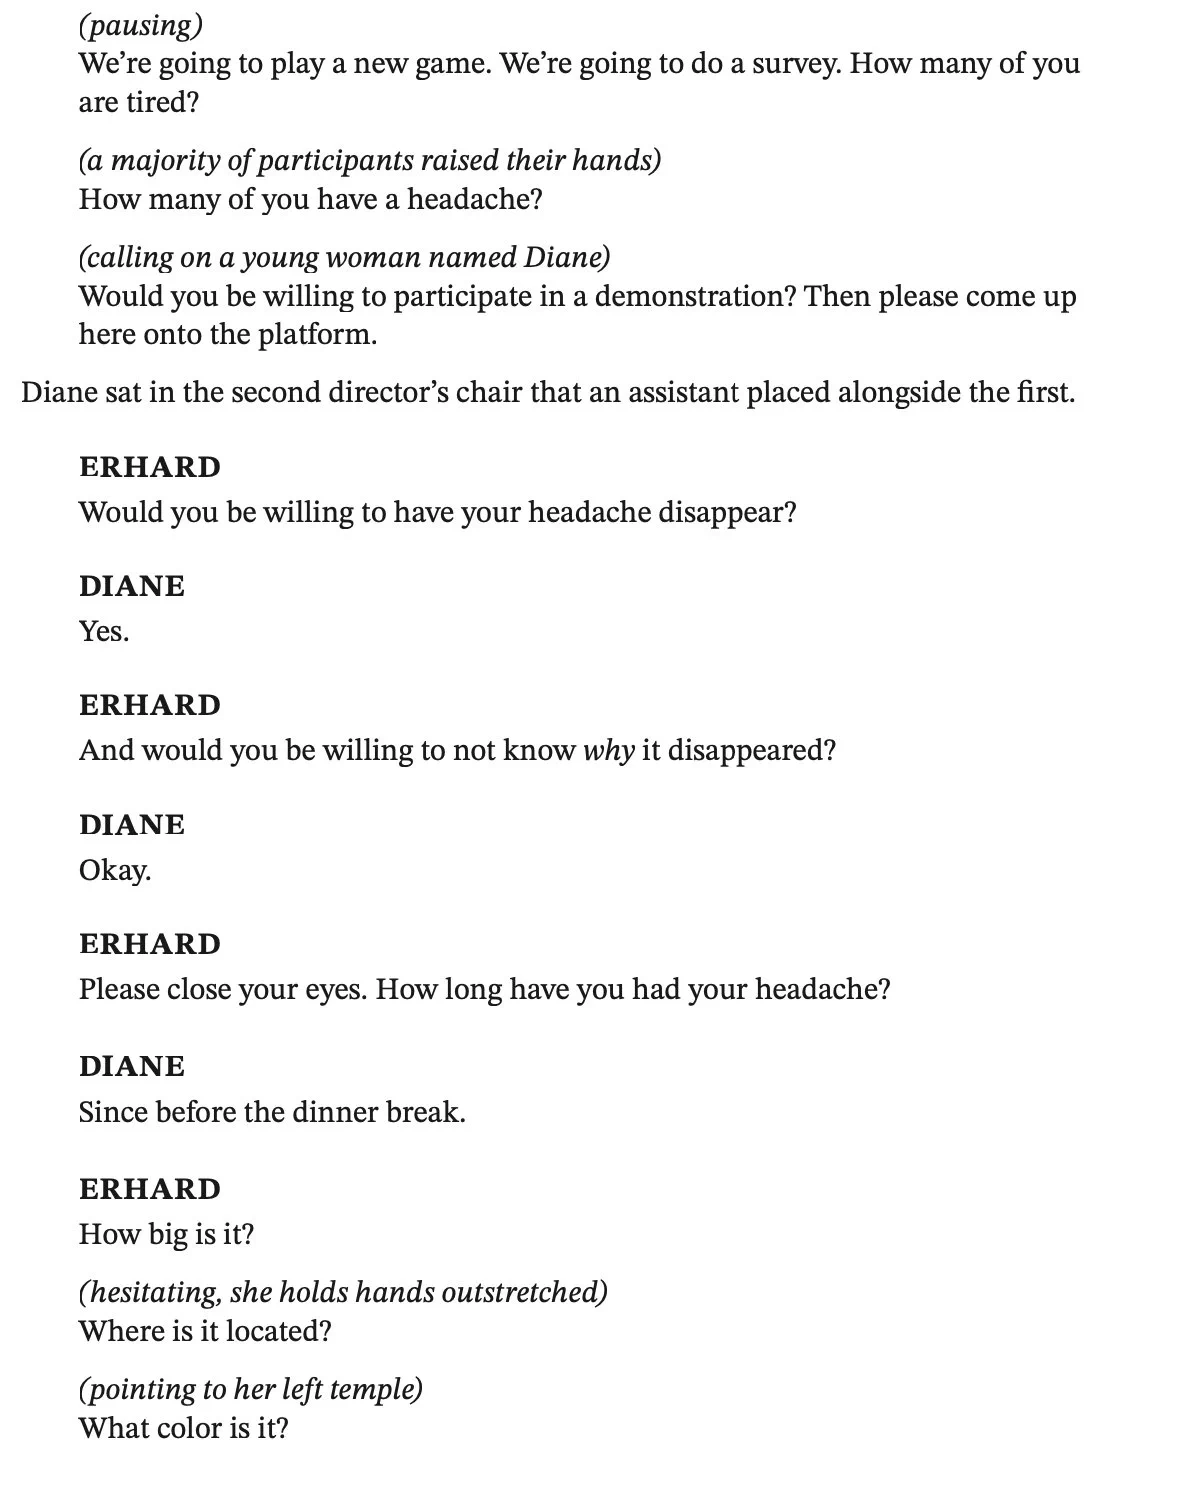
I like this bit of dialogue from Speaking Being, where a participant is asked to observe and describe the properties of her headache (like Focusing in the manner of Gendlin)--