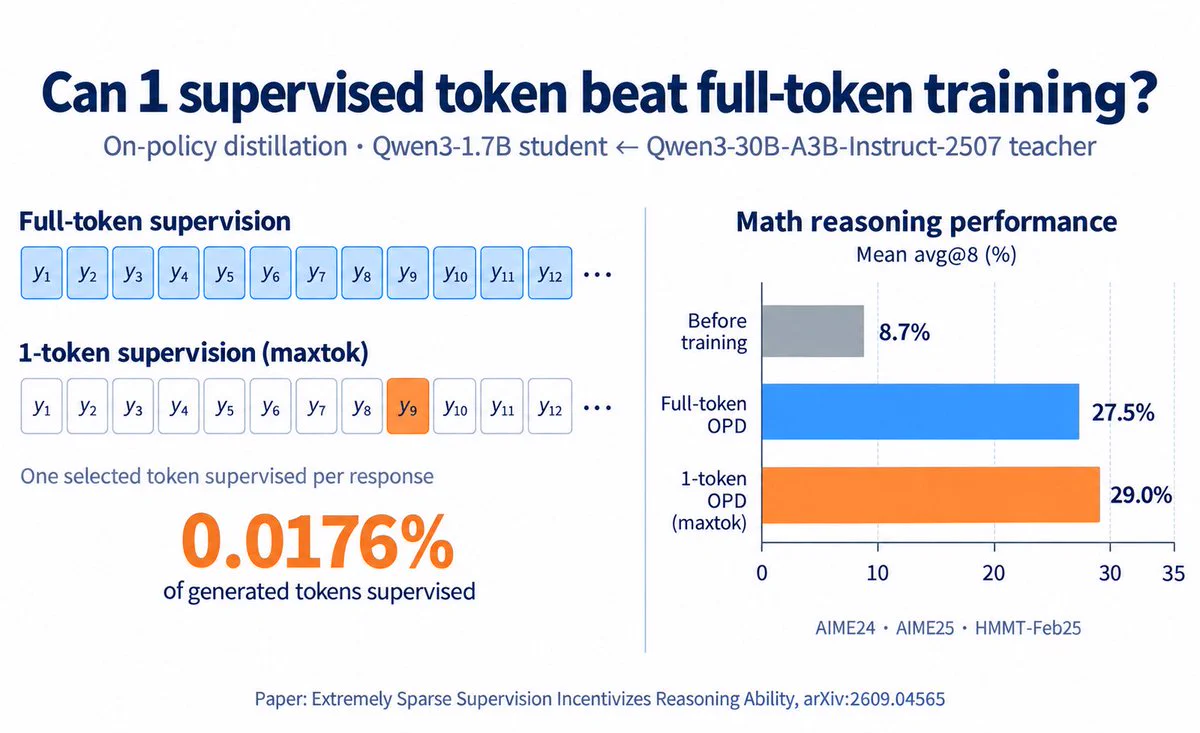
𝗖𝗮𝗻 𝘄𝗲 𝗺𝗮𝘀𝗸 𝟵𝟵.𝟵% 𝗼𝗳 𝘁𝗼𝗸𝗲𝗻-𝗹𝗲𝘃𝗲𝗹 𝘀𝘂𝗽𝗲𝗿𝘃𝗶𝘀𝗶𝗼𝗻 𝗮𝗻𝗱 𝘀𝘁𝗶𝗹𝗹 𝗺𝗮𝘁𝗰𝗵 𝗼𝗿 𝗯𝗲𝗮𝘁 𝗳𝘂𝗹𝗹-𝘁𝗼𝗸𝗲𝗻 #𝗟𝗟𝗠 𝗽𝗼𝘀𝘁-𝘁𝗿𝗮𝗶𝗻𝗶𝗻𝗴?
Yes: supervising just 𝙊𝙉𝙀 selected token per response can be enough.
How is it possible? (1/5) 🧵
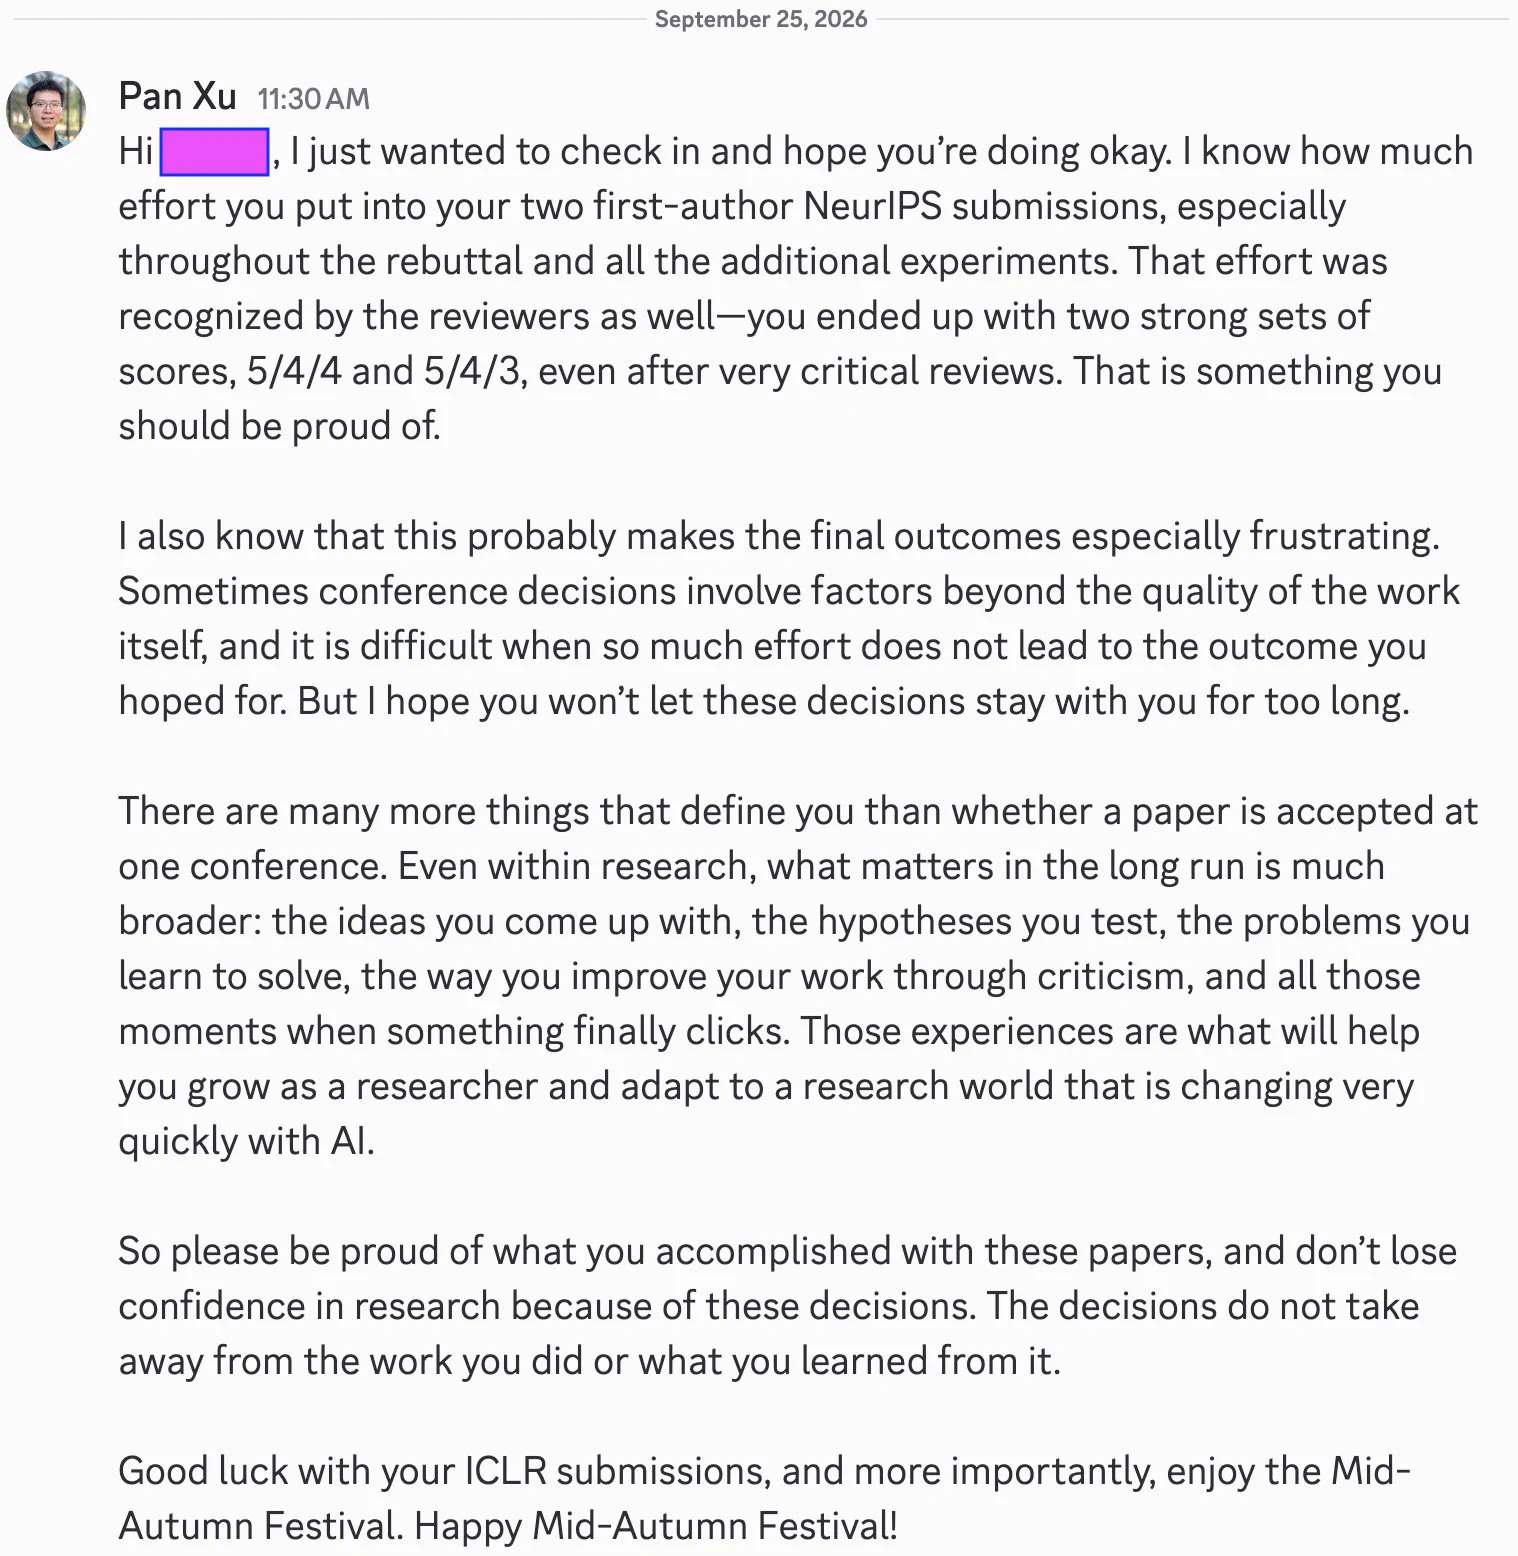
I sent this message to my student, whose two papers received scores of 5/4/4 and 5/4/3 at #NeurIPS2026 but were rejected.
It’s also what I want to say to all junior students going through the same process: please be proud of what you accomplished with these papers, and don’t let
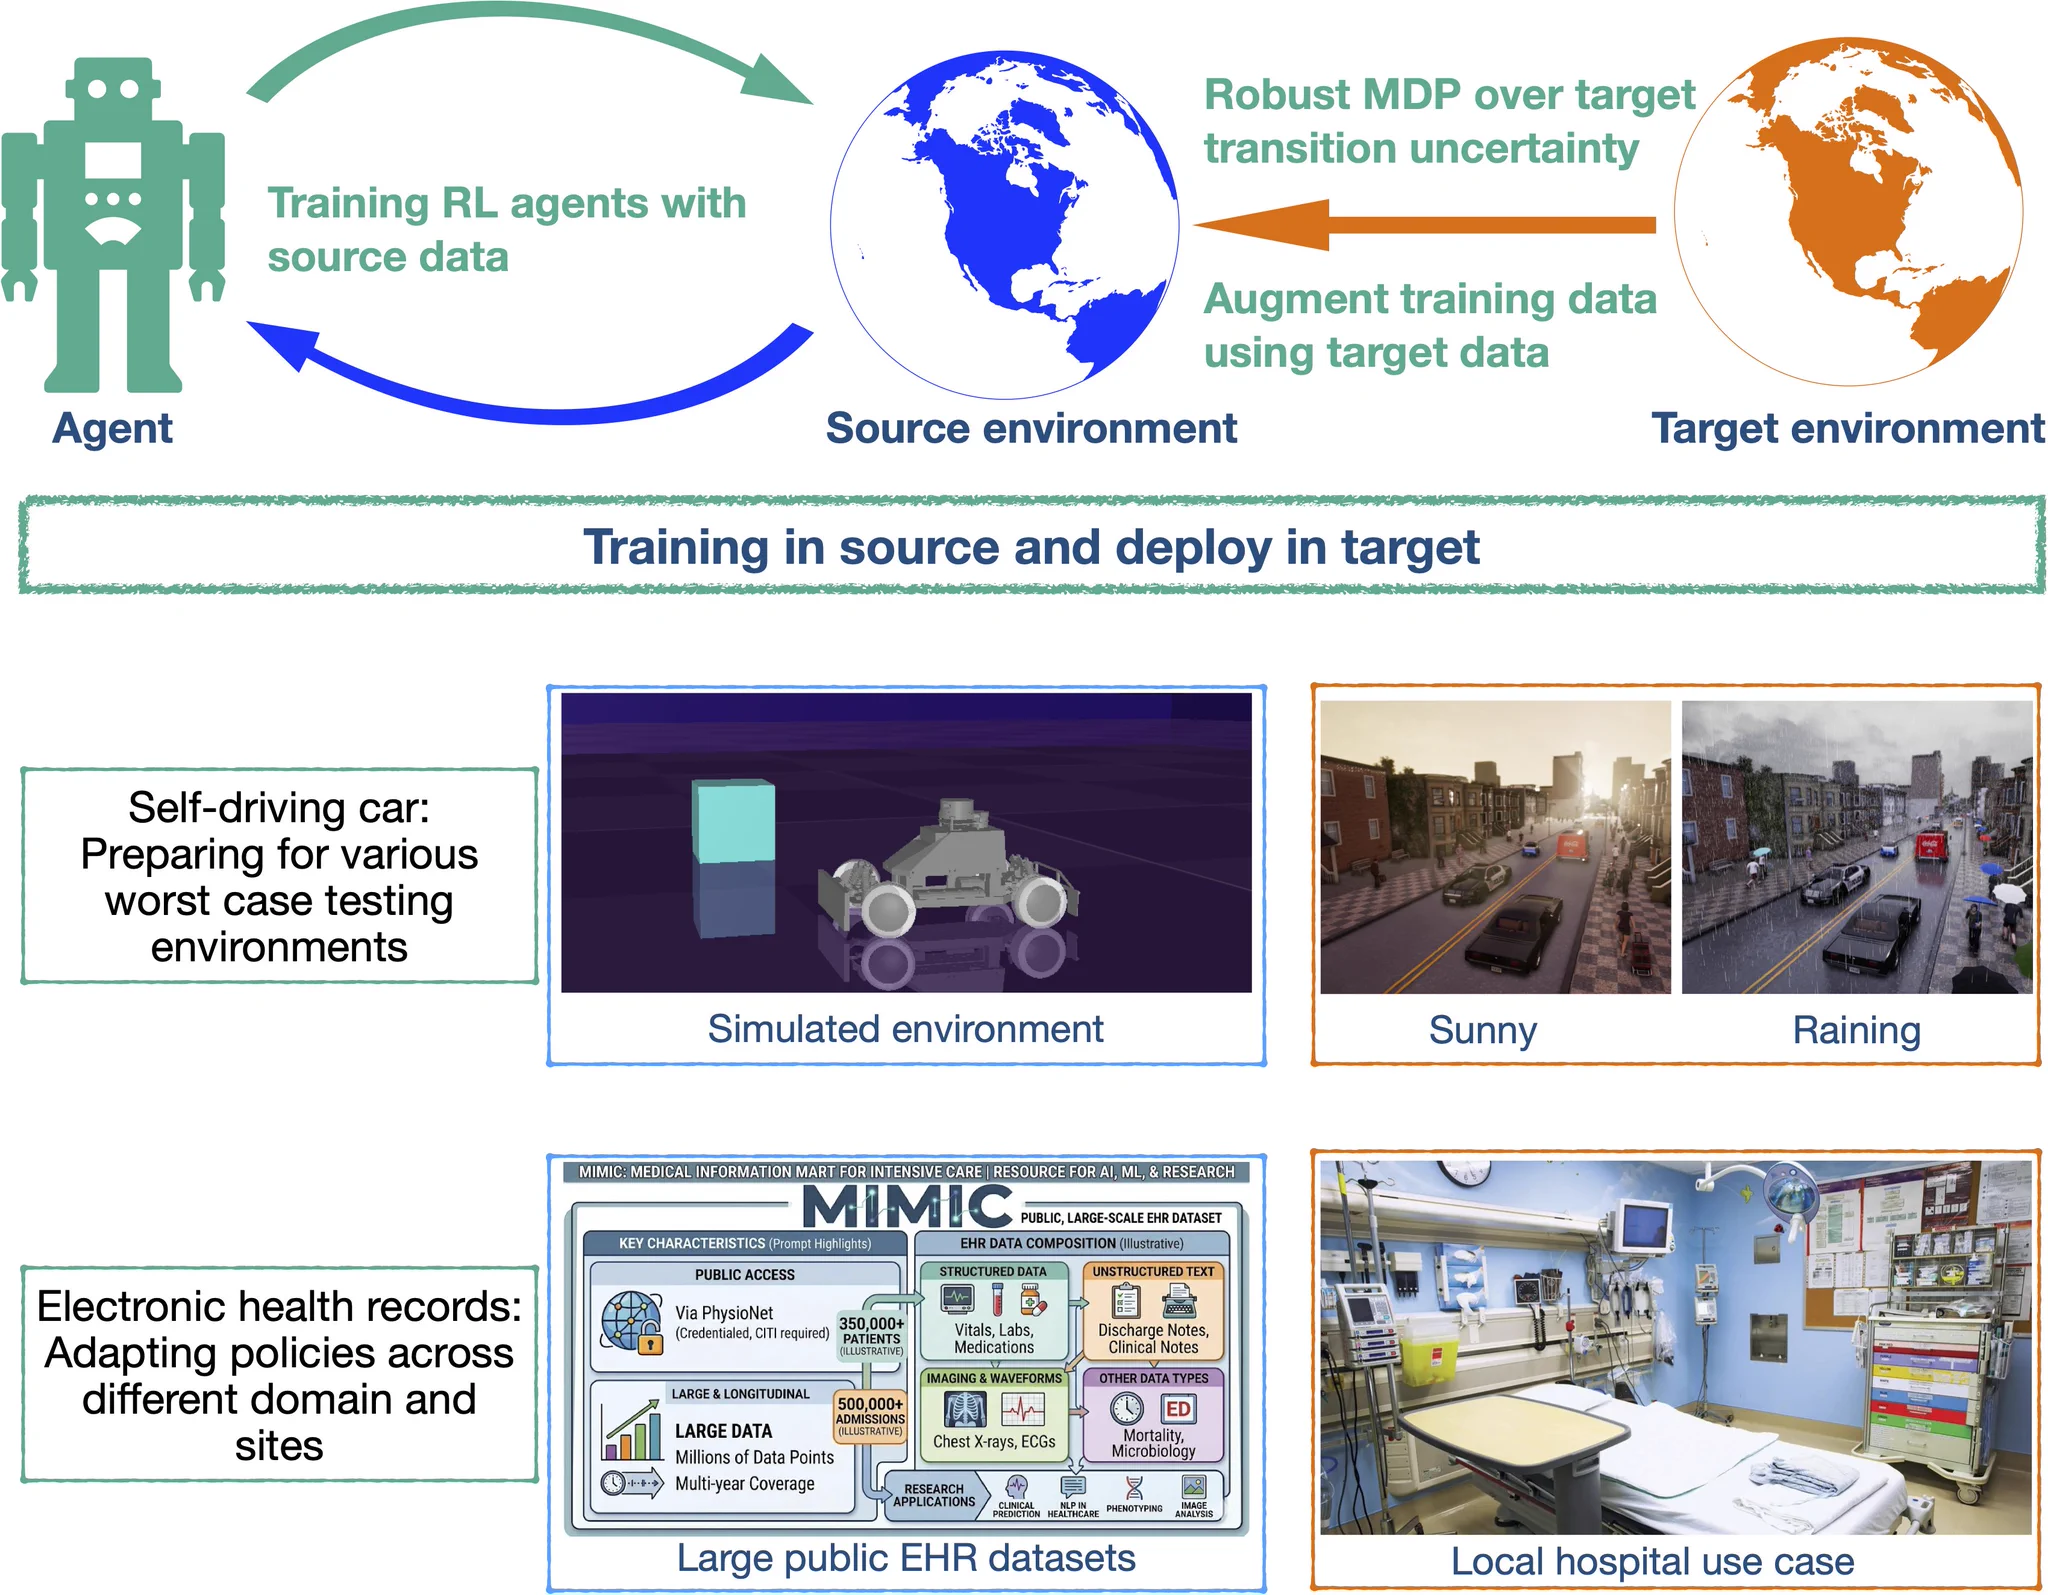
🎉I'm excited and deeply grateful to share that I have received a 𝐍𝐚𝐭𝐢𝐨𝐧𝐚𝐥 𝐒𝐜𝐢𝐞𝐧𝐜𝐞 𝐅𝐨𝐮𝐧𝐝𝐚𝐭𝐢𝐨𝐧 (𝐍𝐒𝐅) 𝐂𝐀𝐑𝐄𝐄𝐑 𝐀𝐰𝐚𝐫𝐝 for my project: "Harnessing the Power of Off-Dynamics Reinforcement Learning: Foundations, Algorithms, and Applications"
Excited to share our #ICML2026 paper:
📋Clipped Q-Learning: Your Value Clipping Is Secretly A Robust Operator
🤔A common trick in RL is to clip value estimates during Bellman updates. This is often used as a heuristic for stabilization, but what does it actually optimize?
1/5
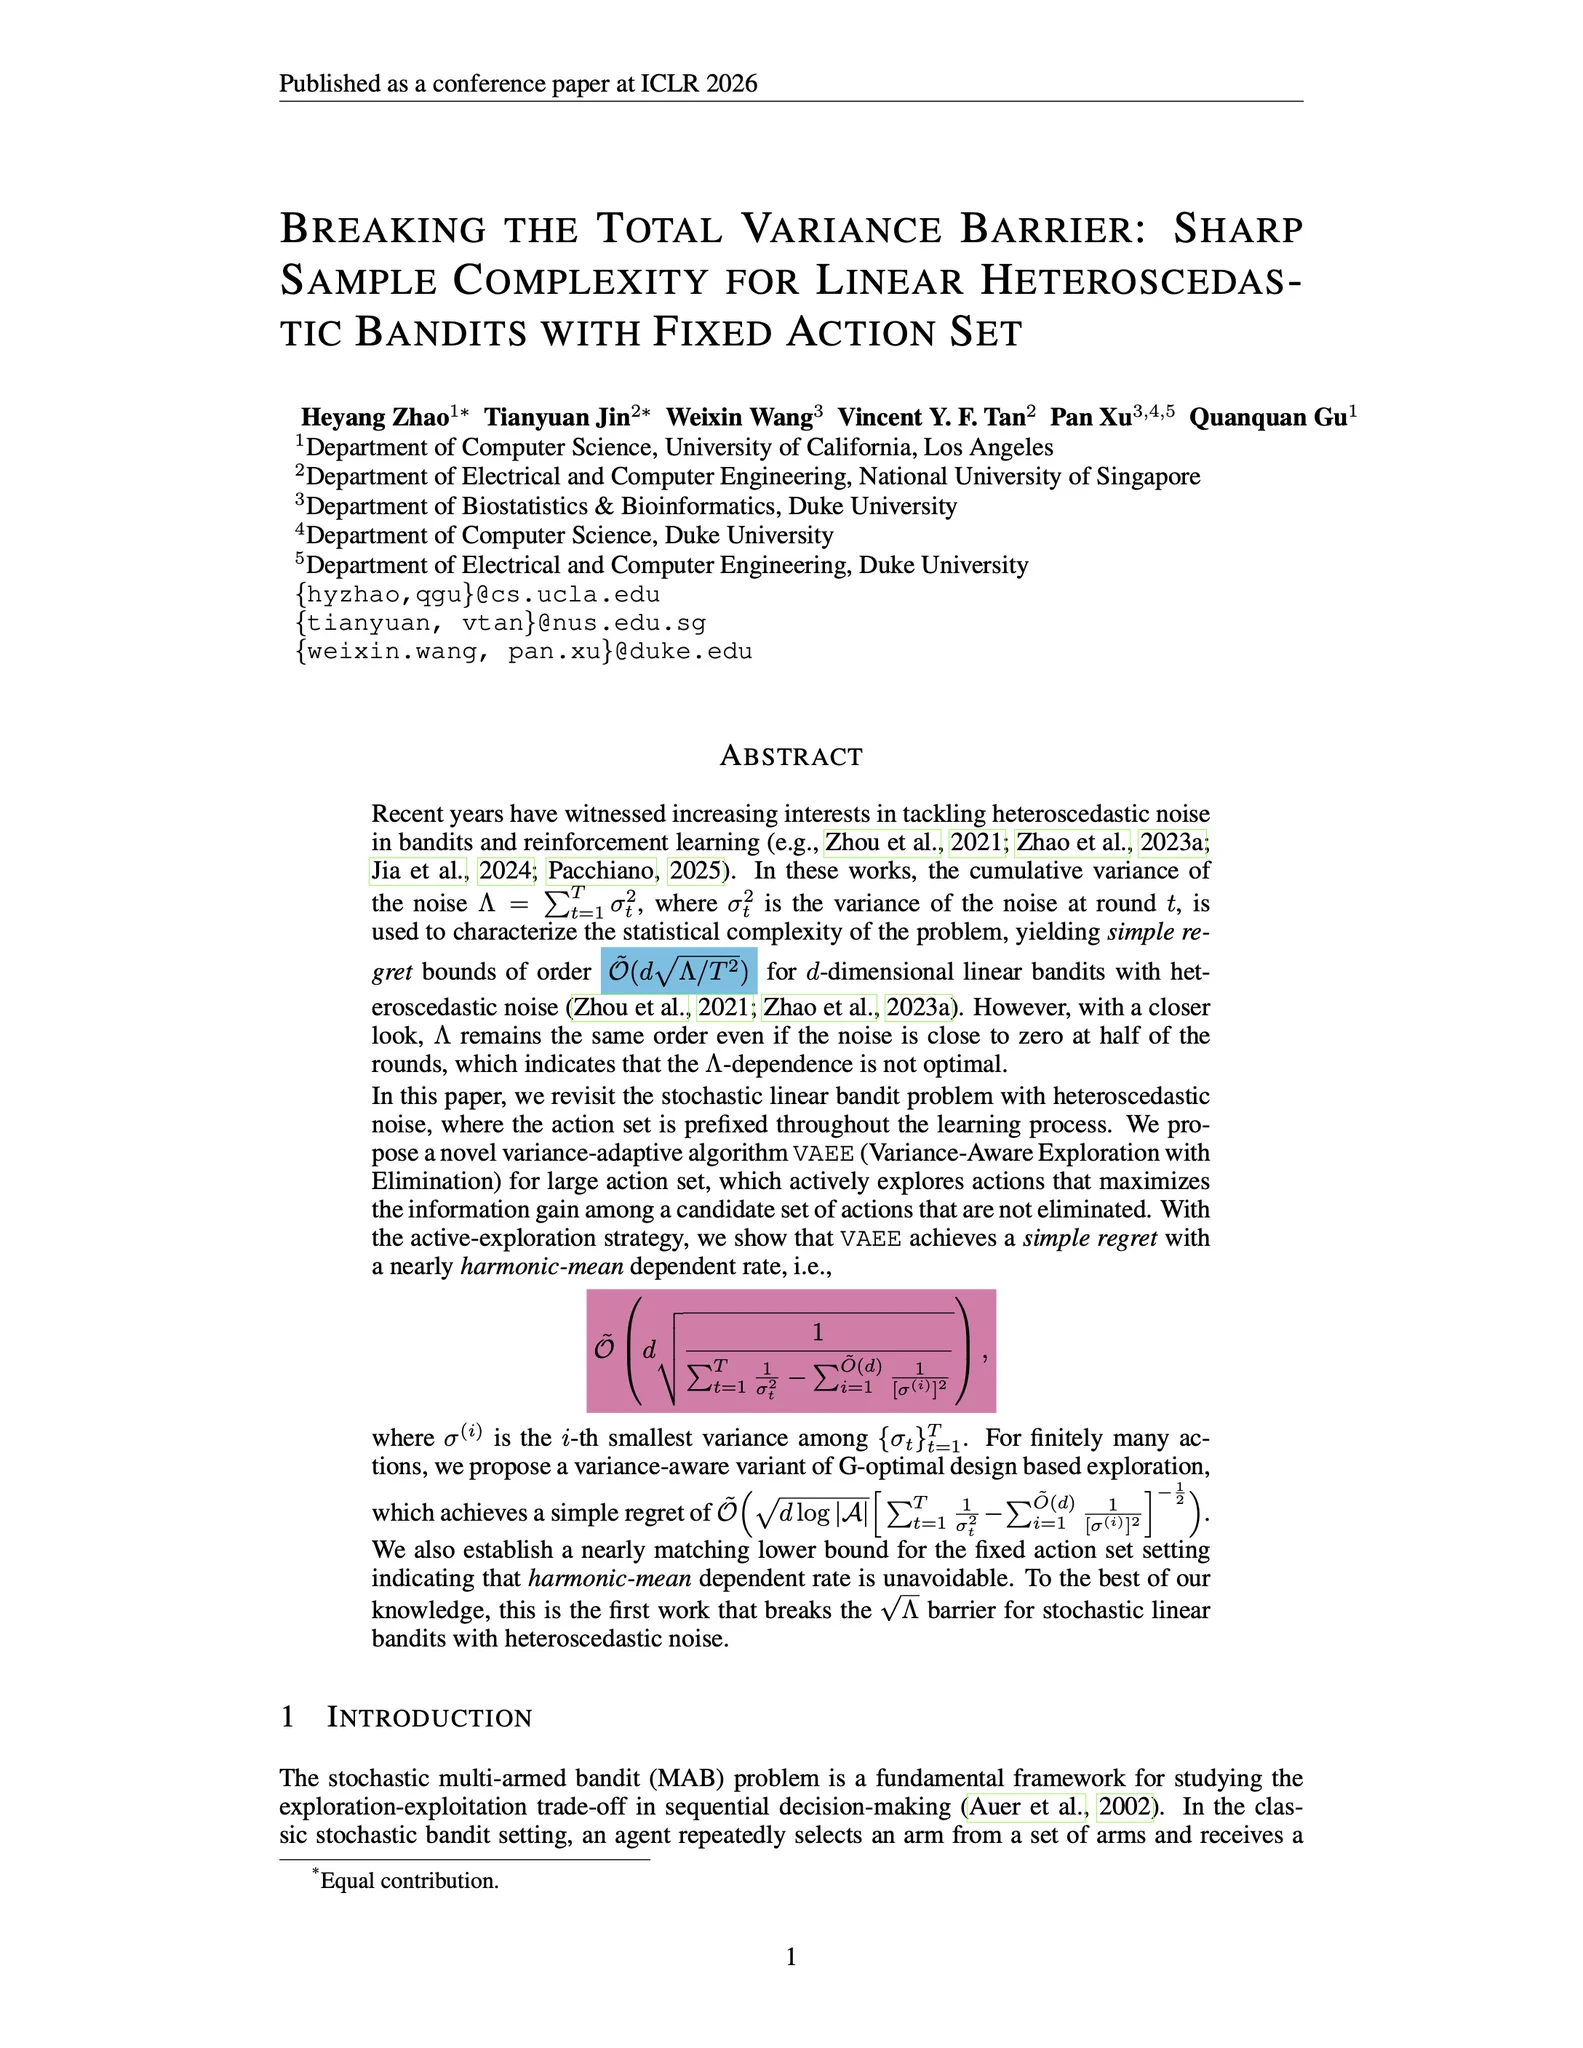
#ICLR2026 We revisited stochastic linear bandits under heteroscedastic noise and find that the “total variance” isn’t the right complexity measure for variance-aware regret.
We show a bound that is strictly sharper than previous results using the harmonic mean of the variances.