.@mirendil is building self-accelerating AI R&D to solve humanity's most pressing problems. To scale RL training across a global fleet of thousands of GPUs, it runs frontier RL on Baseten.
We power their rollout fleet with new policies served in ~40 seconds, and sampling
Meet Lor.
We’re building Lor to do the work of an entire AI lab. Today, its agents write our code, run experiments, and iterate on the results for days, on any machine, hundreds at a time.
Now in private beta ↓
Introducing Fern, Mirendil’s first model: pretrained from scratch, with up to 10 million tokens of context.
That’s ~0.5M lines of code or days of an agent’s work - all in context at once.
Built for high-volume agentic work in AI R&D: auditing training data, debugging training
Today, we're sharing a major milestone in our mission to democratize frontier AI development:
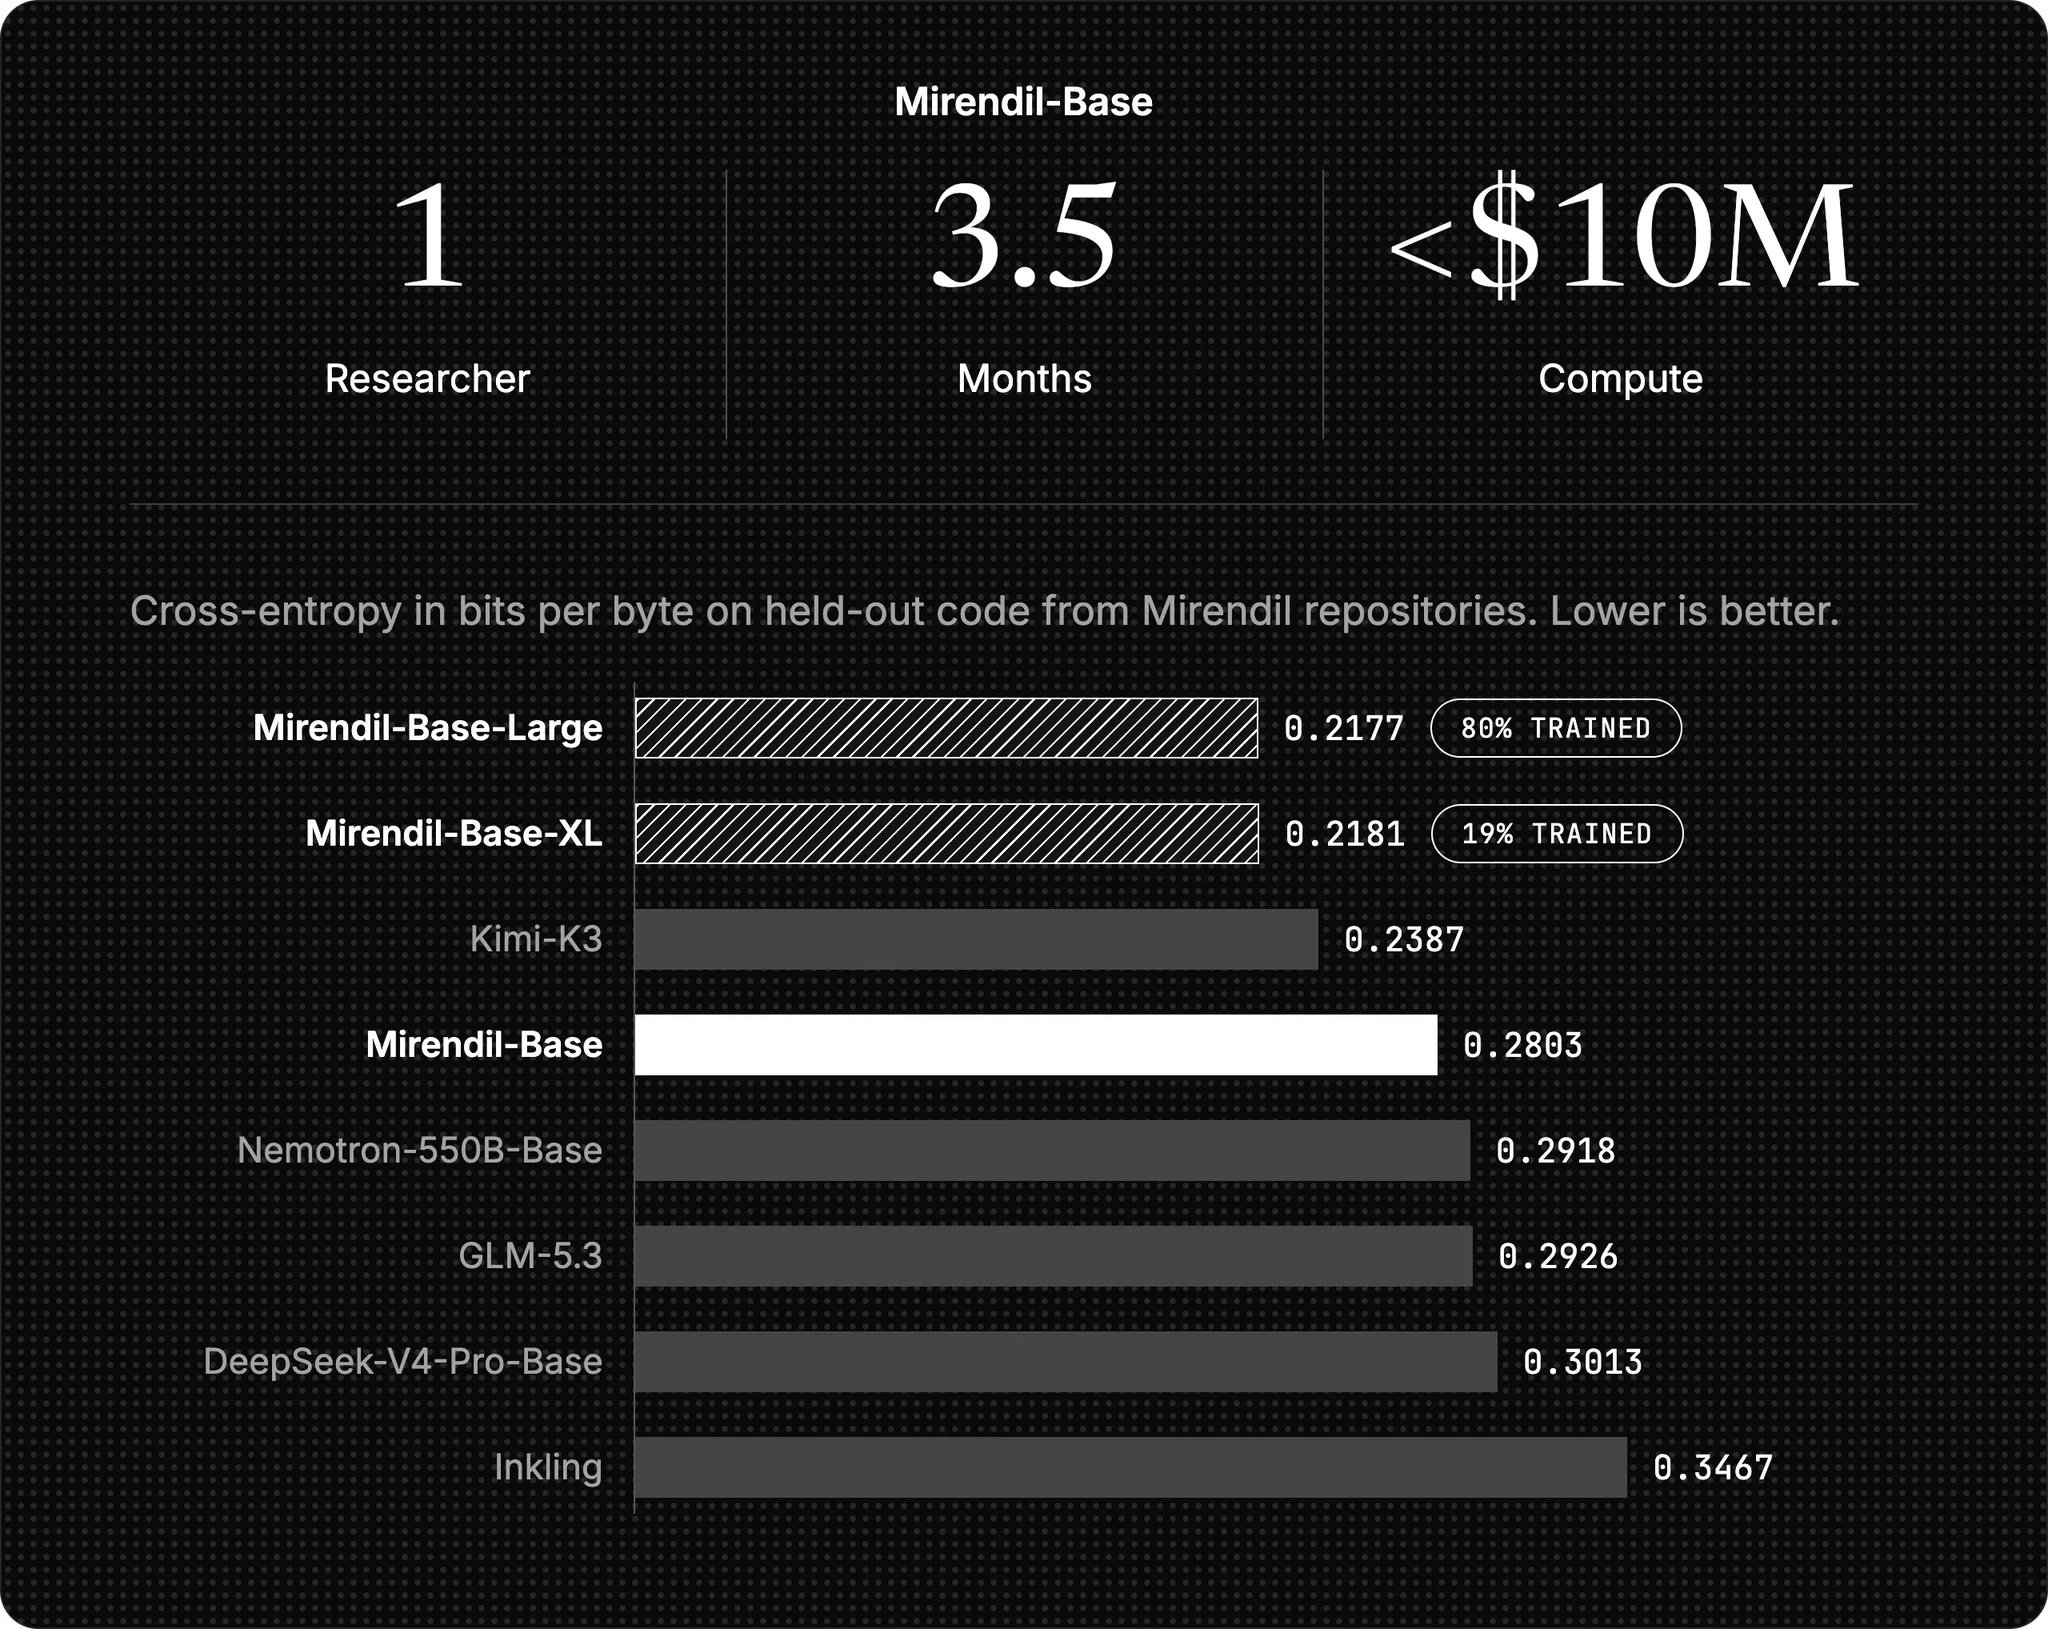
Pretraining at scale without a pretraining team.
We set out to answer an ambitious question: Can we significantly reduce the time, human expertise, and compute needed to pretrain a
Today, we're announcing a multi-year partnership with @Google to power the next generation of self-accelerating AI!
Mirendil will scale its training, inference, and AI research workloads on @googlecloud 's AI Hypercomputer — drawing on both TPUs and full-stack NVIDIA AI Infra.