We just released "German Commons", the largest openly-licensed German text dataset for LLM training: 154B tokens with clear usage rights for research and commercial use.
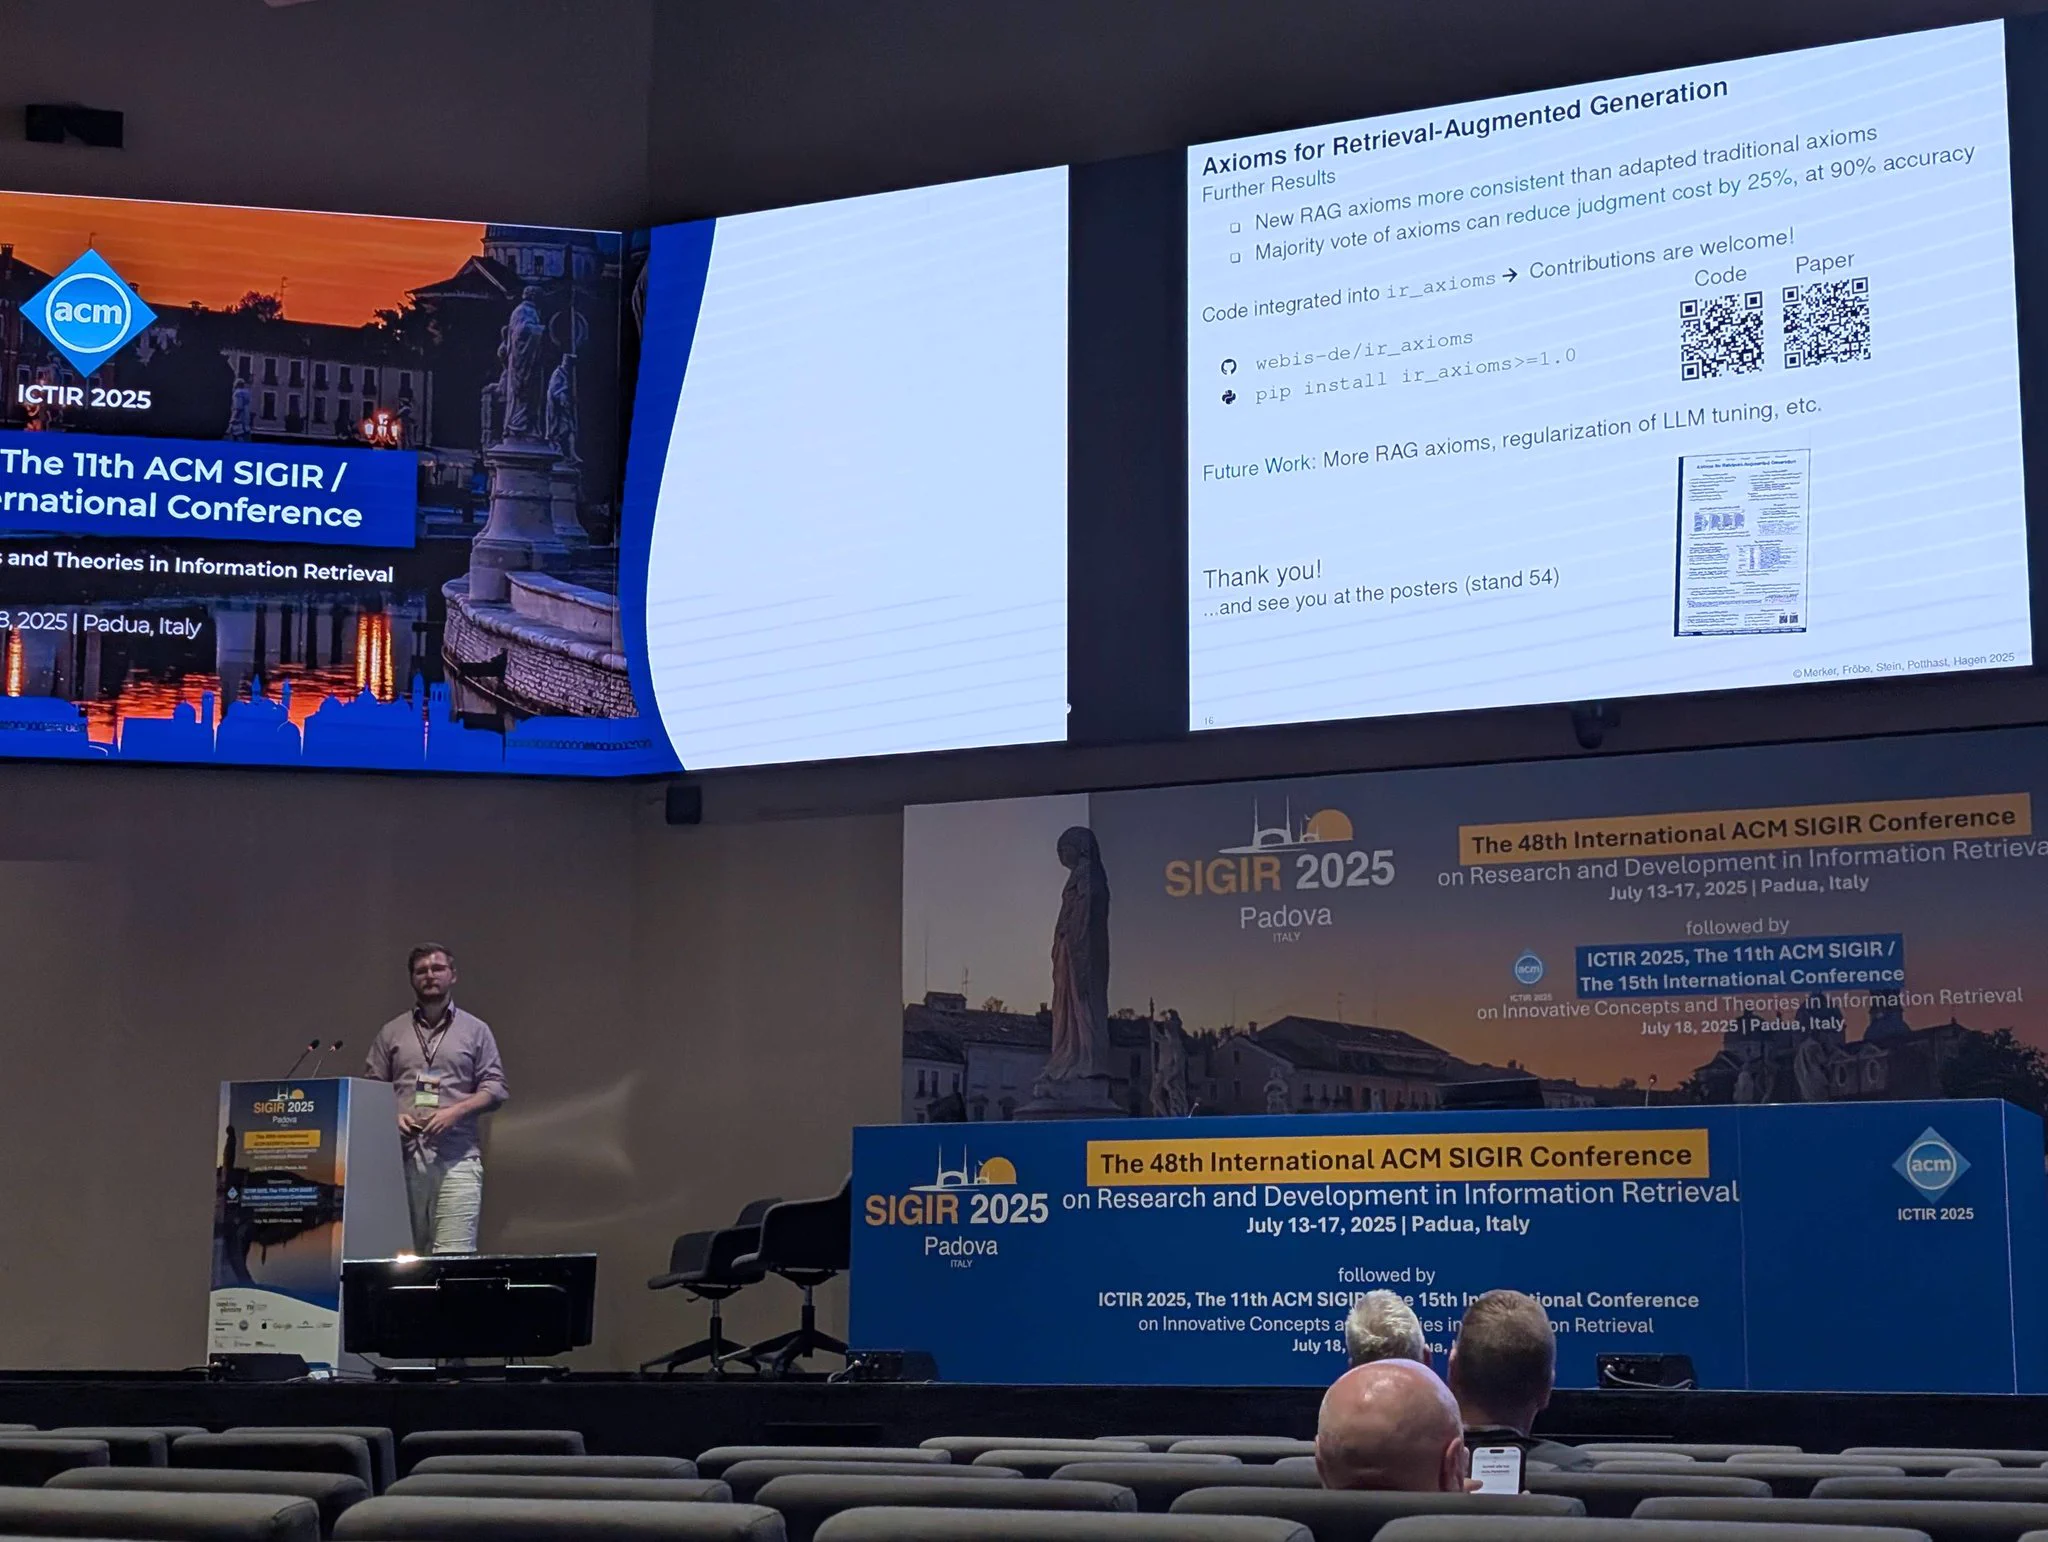
Come join us at the poster session at ICTIR 2025 to discuss:
- Axioms for Retrieval-Augmented Generation webis.de/publications.h…
- Learning Effective Representations for Retrieval Using Self-Distillation with Adaptive Relevance Margins webis.de/publications.h…
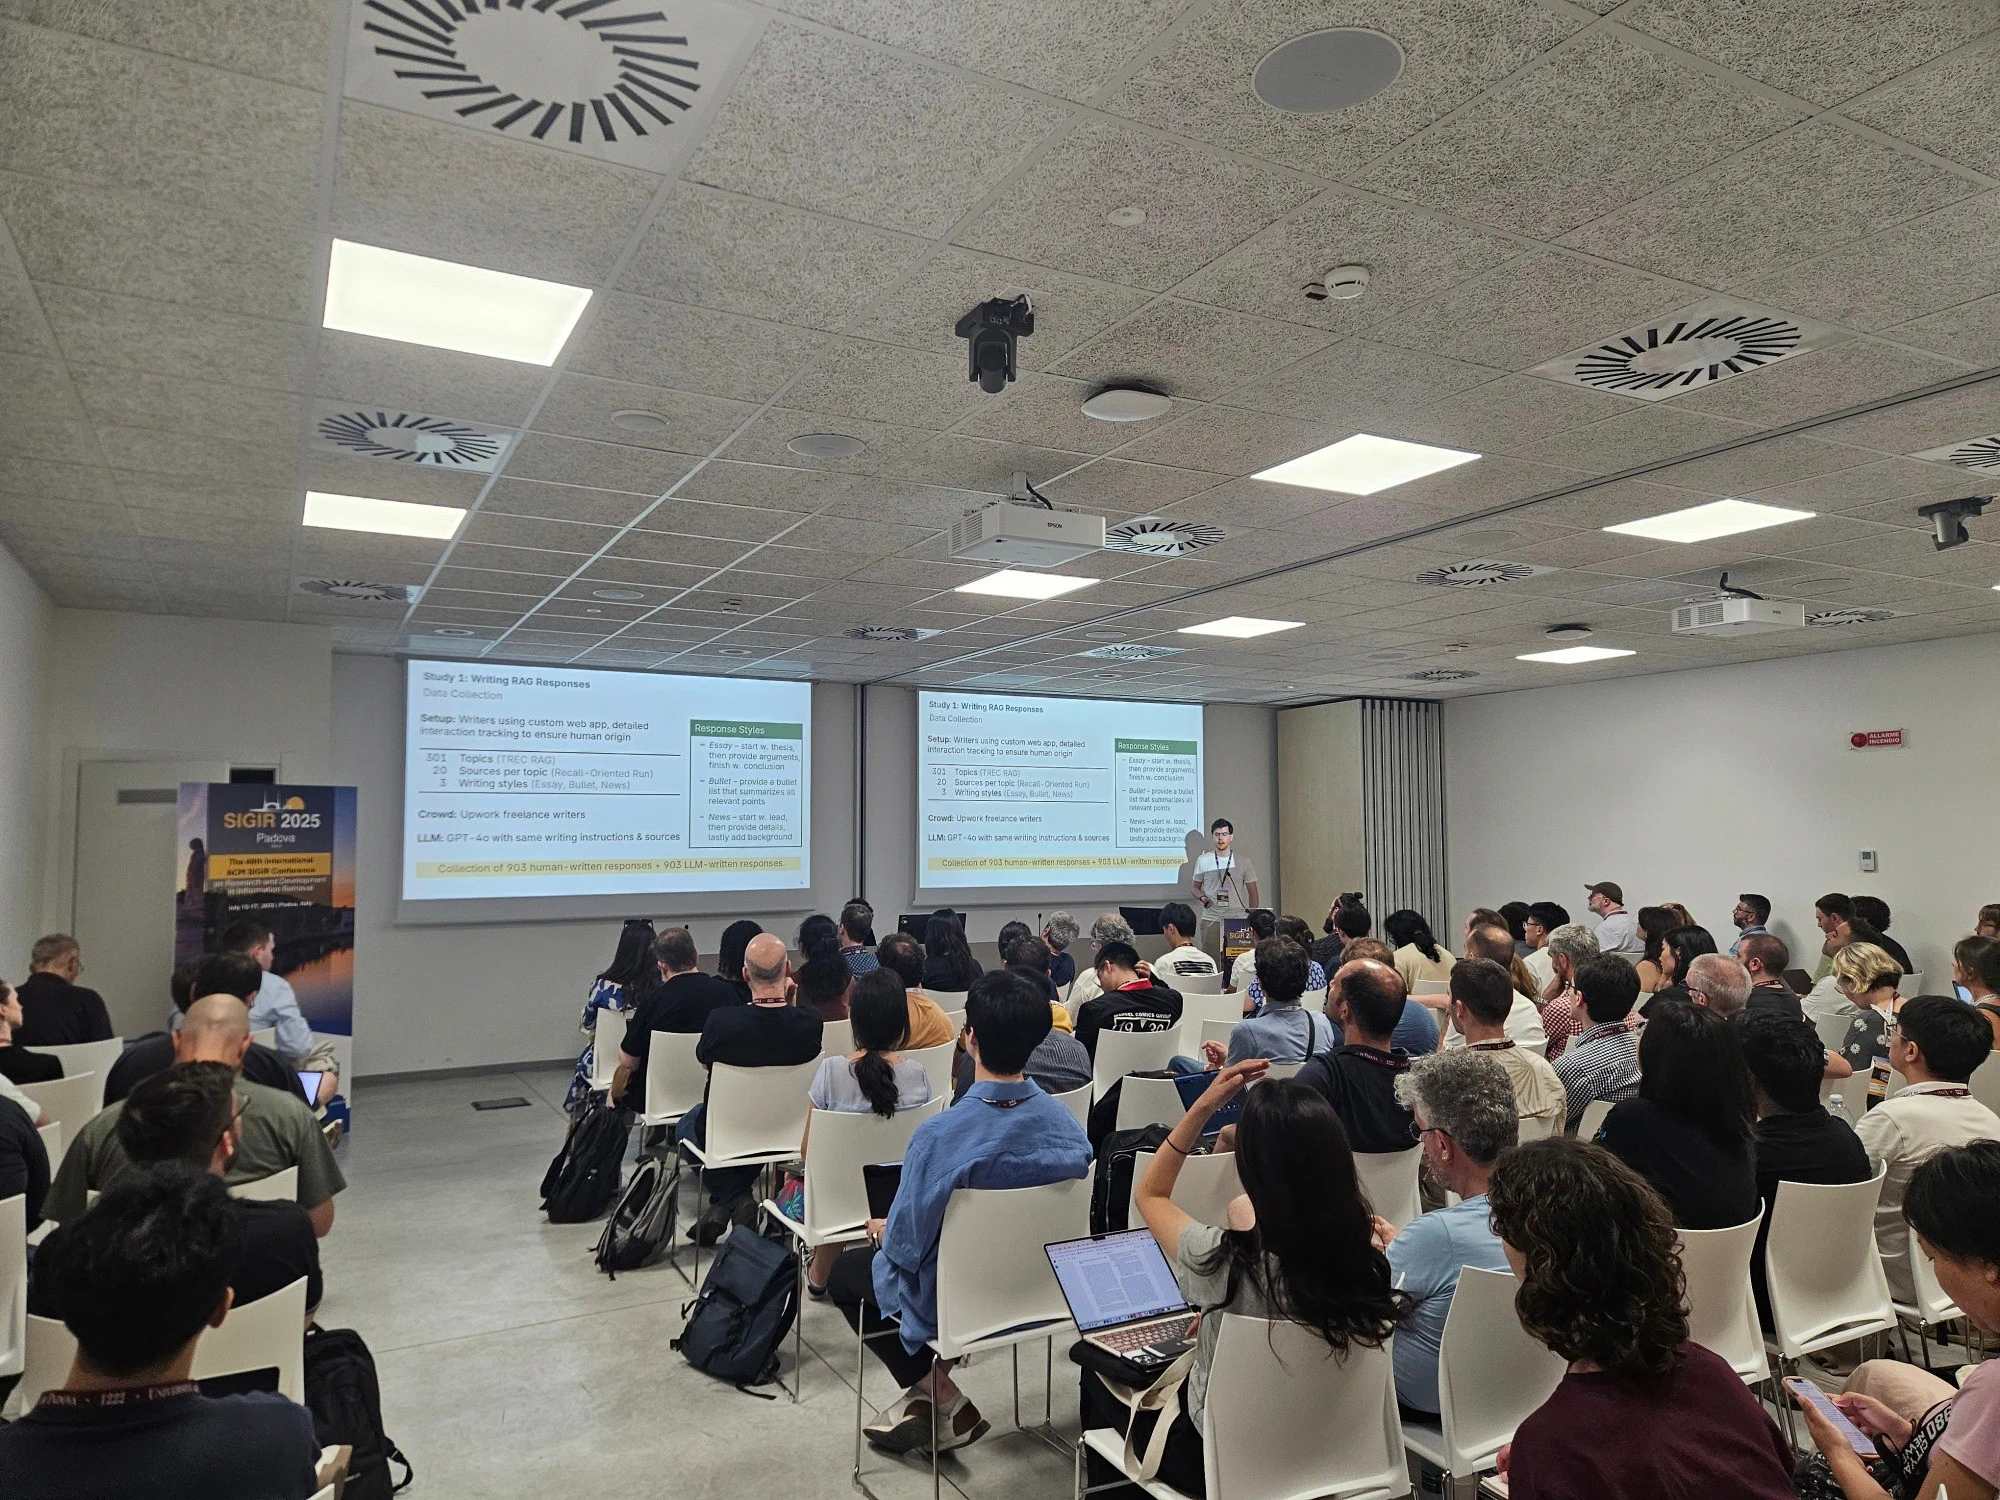
Happy to share that our paper "The Viability of Crowdsourcing for RAG Evaluation" received the Best Paper Honourable Mention at #SIGIR2025! Very grateful to the community for recognizing our work on improving RAG evaluation.
📄 webis.de/publications.h…