Introducing our Browser Agent Evals.
We benchmark frontier and open models using various harnesses on computer-use tasks.
Our evals are fully open source and reproducible via our Evals CLI.
Gemini 4 Argon is live in Stagehand.
It outperforms Fable 5.1 on computer use tasks with @eve and @pidotdev harnesses, while being roughly around the same cost/speed.
You can try the model in our playground at gemini.browserbase.com.
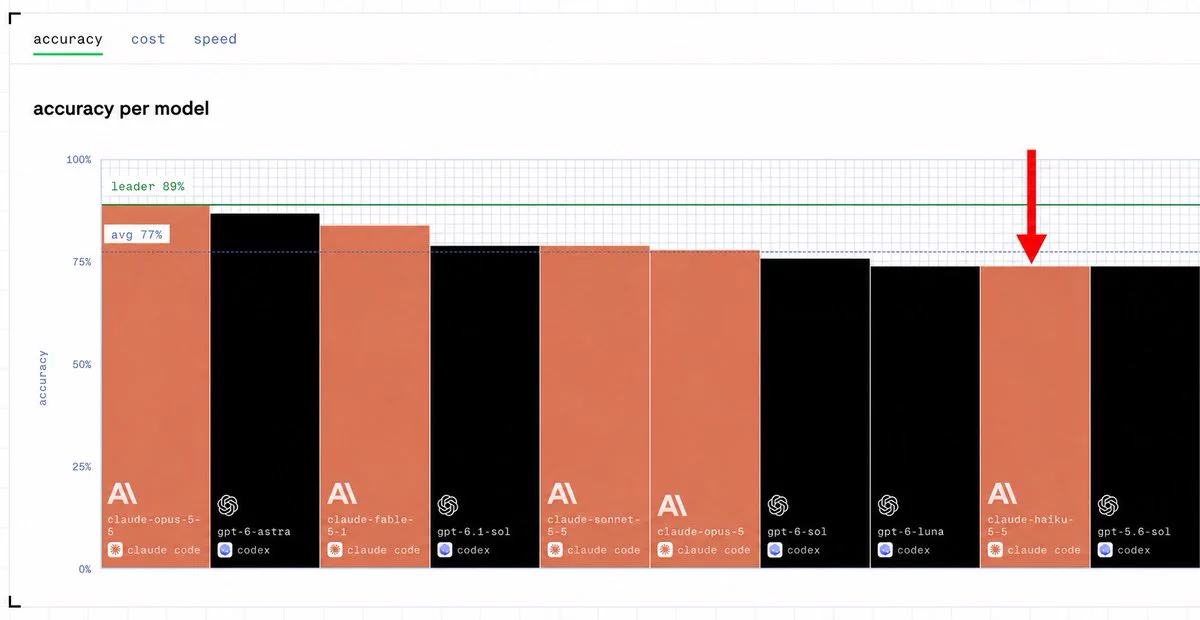
Claude 5.5 Haiku is on par with GPT 6 Luna from OpenAI on accuracy and speed, but is 3x the cost per task.
As computer use improves, most gains will show up on the Pareto frontier: maintaining high accuracy while also being faster and cheaper.