Introducing brae: GPU-native computational fluid dynamics. 🌊
The entire simulation runs on one GPU, no matrix shuffled back to the CPU every iteration.
~5× faster than GPU-accelerated OpenFOAM, on the same GPU. Validated to <1%.
🌐 brae.sh
Your GPU, earning while you sleep.
Brae turns your NVIDIA GPU into income. One command to join. Renters pay by the minute, you keep 80%. Paid to your bank or in USDC.
Early access is open → app.brae.sh
Settlement in SIMD comes after our smart contract audit.
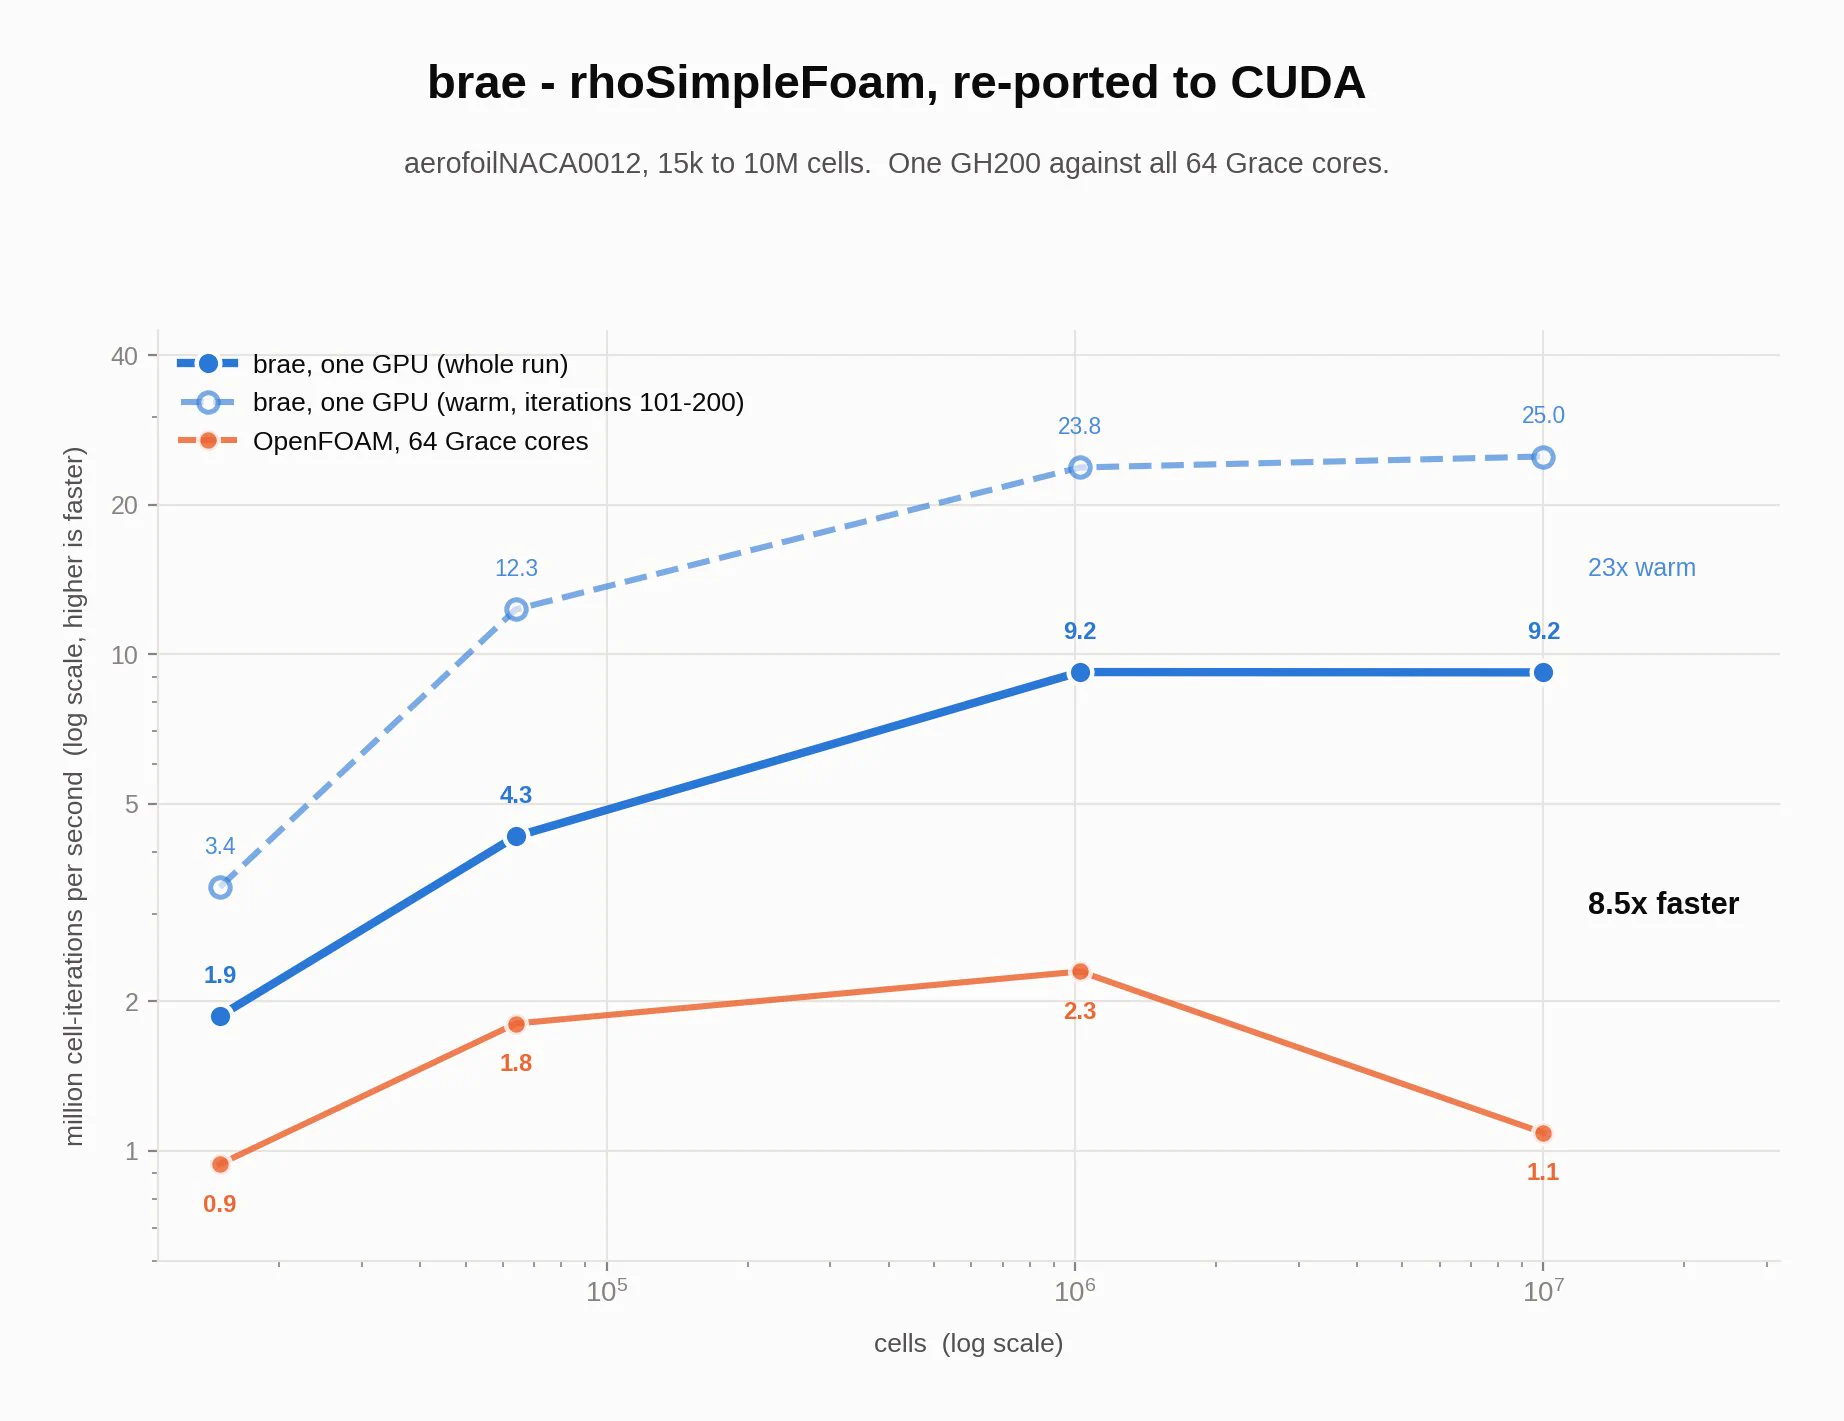
Brae now runs OpenFOAM’s rhoSimpleFoam fully on CUDA 🚀
Across cases from 15k to 24M cells on one GH200 outperforms all 64 Grace CPU cores.
At 10M cells / 100 SIMPLE iterations:
- GH200 GPU: 109s
- 64 Grace CPU cores: 921s
Matches OpenFOAM to 7e-08.
A port, not a
A transonic 180° U-bend
Mach 0.999 on the inner radius, 960K. converged in 3.4 seconds.
112,000 cells. Brae: OpenFOAM’s rhoSimpleFoam, ported to CUDA. The run stopped on the tutorial’s own residualControl at iteration 154 - not a hand-picked iteration count.
Brae now runs OpenFOAM’s rhoSimpleFoam fully on CUDA 🚀
Across cases from 15k to 24M cells on one GH200 outperforms all 64 Grace CPU cores.
At 10M cells / 100 SIMPLE iterations:
- GH200 GPU: 109s
- 64 Grace CPU cores: 921s
Matches OpenFOAM to 7e-08.
A port, not a
Brae now runs OpenFOAM’s rhoSimpleFoam fully on CUDA 🚀
Across cases from 15k to 24M cells on one GH200 outperforms all 64 Grace CPU cores.
At 10M cells / 100 SIMPLE iterations:
- GH200 GPU: 109s
- 64 Grace CPU cores: 921s
Matches OpenFOAM to 7e-08.
A port, not a