Discover next-gen
AI tools & startups.
Curated directory of the best AI tools. Submit your project to get high-quality backlinks and traffic.
Why Choose thistools?
thistools is your go-to platform for discovering cutting-edge AI tools and innovative tech products. We curate the best tools from around the world, helping you find the perfect solutions for your productivity, automation, and creative needs.
Daily Curated Picks
Every day, we feature fresh AI tools and startups selected for quality and launch momentum.
Quality-First Curation
We prioritize tools that solve genuine problems and offer exceptional user experiences.
Community-Driven Rankings
Trending lists are driven by real user feedback so the most valuable tools rise.
>> LAUNCHING_TODAY
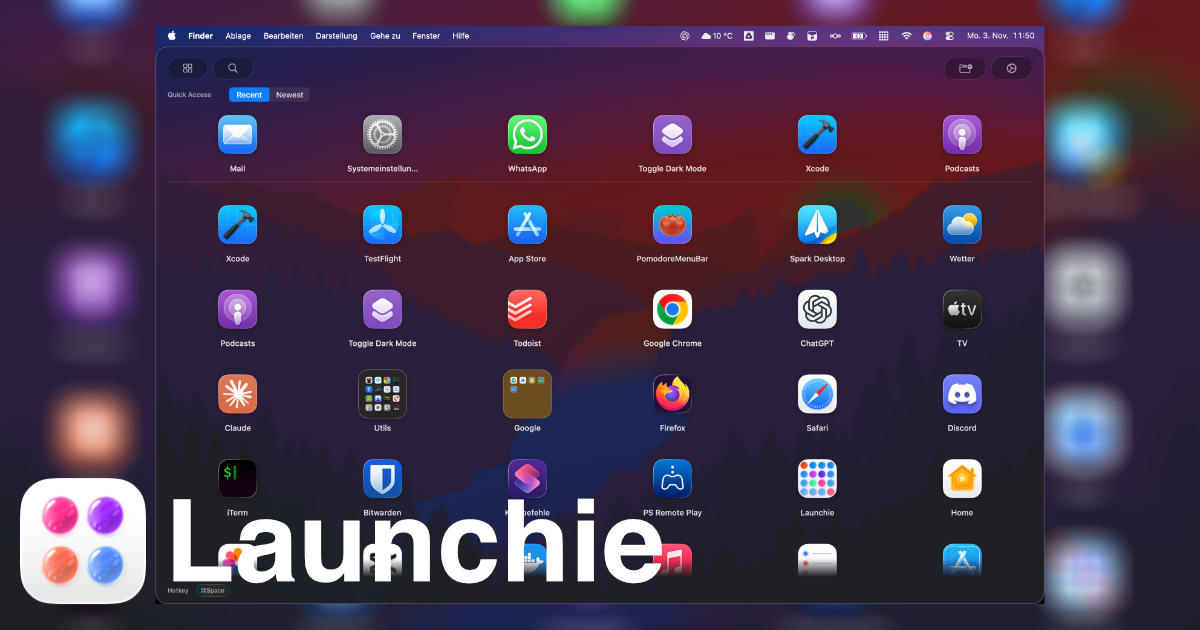
Launchie is a macOS application that brings a fullscreen, visual app launcher back to Macs running macOS 26 Tahoe and macOS 27 Golden Gate. It displays installed applications as a grid of icons that the user arranges themselves, with drag-and-drop ordering that sticks, unlimited folders, separate Spaces for different groups of apps, and instant search. Launchie is a replacement for people who browse their apps by eye instead of typing a name into a keyboard launcher, and it is positioned as the visual launcher macOS 26 removed: your app grid, your folders, your layout. It is available on the Mac App Store and can also be installed through Homebrew. Launchie is free to use, with a Pro tier offered as a one-time purchase. The product exists because Apple removed Launchpad in macOS 26 and kept it out of macOS 27. As the site puts it, macOS 26 broke the classic Launchpad. According to the feature comparison on the site, macOS 26's Launchpad offered no icon rearranging, so apps were stuck in alphabetical order; no custom folders, so users could not organize their workflow; a fixed grid layout that fits nobody; no customization at all; no backup options, so a setup was lost on new devices; and no smart features beyond a basic grid. Launchie is presented as the recommended alternative, offering drag-and-drop reordering, custom folders, flexible layouts, full customization of hotkeys, themes and icons, backup and restore, and Smart Lists. User reviews on the site echo the same story: reviewers describe losing a curated launcher when upgrading to Tahoe, and then finding that Launchie did everything the old Launcher did, and more, with one calling it the perfect un-Sherlock'ing of Launchpad. Launchie's core is the grid. Every app appears in a fullscreen grid that the user arranges themselves, and because drag-and-drop ordering sticks, the layout stays where it is put rather than snapping back to an alphabetical list. Spaces extend this by splitting the launcher into separate sections, each holding its own apps and folders, so a large library stops being one long wall of icons; users can keep work apps in one Space and everything else in another. The site notes that the old Launchpad never had Spaces. Screenshots on the site show the app grid, Spaces, search, organizing apps, quick access and appearance settings, alongside a live demo video of Launchie 1.6.1 running on macOS 27 and macOS 26. Folders and search handle organization and retrieval. Users can make as many folders as they like and drop apps into them to group what belongs together, and search finds and launches any app in seconds. Apps that are never opened can be hidden to keep the launcher clean. A backup and restore feature saves the whole Launchie setup so that a new Mac starts where the last one left off. Launchie is also designed to be opened and closed quickly. It can be opened with Command-K or with a custom keyboard shortcut chosen by the user, and it can also be launched through Hot Corner activation. Pressing Esc instantly returns the user to what they were doing, and clicking outside the launcher closes it as well. A quick access section uses Smart Lists to surface recently used, most used or newest apps at the top. Customization is a major part of the app: the look can be adjusted to the user's needs, and there is a choice between a modern Liquid Glass UI or a traditional sheet look. All of this is framed as everything that was loved about the classic Launchpad, plus modern enhancements. The overall approach is deliberately visual and spatial rather than keyboard-first. Launchie opens as a fullscreen overlay on the Mac desktop, showing the app grid, folders and Spaces, and then closes again with Esc or a click outside so the user returns to whatever they were doing. Because ordering, folders, Spaces, hidden apps and the rest of the configuration are part of the setup, the launcher becomes a curated, persistent layout rather than a flat list of every installed application. The site contrasts this with keyboard productivity tools such as Raycast, noting that keyboard productivity and visual app launching solve different Mac workflow problems. For users, the benefit is getting a familiar visual browsing workflow back after upgrading to macOS 26 or macOS 27, and then getting more than the original offered: drag-and-drop reordering, custom folders, flexible layouts, hotkeys, themes and icons, backup and restore, and Smart Lists. Reviewers quoted on the site describe it as fast, elegantly designed, thoroughly customizable and actively developed, with one noting that they have hundreds of apps installed and that quickly finding and opening the ones they need is no trivial task, a problem Launchie's search and Smart Lists address. Another reviewer says the app includes so many more features than Launchpad ever did that they no longer miss it. The app holds a 4.6 out of 5 rating from 141 ratings on the Mac App Store. Launchie's use cases follow directly from its features. Someone who upgrades to macOS 26 Tahoe, discovers the launcher is gone, and wants a familiar fullscreen grid back can install Launchie and arrange apps the way they had them before. A user with hundreds of installed apps can rely on search and Smart Lists to find and open what they need quickly. A person who wants to keep work and personal apps apart can place them in separate Spaces, each with its own apps and folders. Someone who has carefully curated a layout can back it up and restore it on a new Mac so the setup carries over. Users who browse by eye rather than typing an app name get a grid organized around how they remember their apps. The site also provides guide pages aimed at people searching for a missing Launchpad on macOS Tahoe, the best macOS Launchpad replacement, or a Launchpad replacement for macOS 27 Golden Gate. Launchie is aimed at Mac users on macOS 26 Tahoe and macOS 27 Golden Gate, particularly those who valued Launchpad's visual browsing, folders and spatial memory. It requires macOS 26 Tahoe and is distributed through the Mac App Store and via Homebrew with the command brew install --cask launchie, with other installation options listed on the site. Pricing is free to use, with Pro available as a one-time purchase. The site reports its Mac App Store rating and press coverage from iDownloadBlog, Mac & i 6/2025 and MacGadget, and it also hosts comparison pages against LaunchOS, AppGrid and Raycast, along with guides, blog posts and a newsletter for release notes and launchpad replacement guides. Launchie's primary value proposition is simple: it restores the visual, customizable app launcher that macOS 26 removed, and it does so with drag-and-drop ordering, folders, Spaces, search, hidden apps, Smart Lists, backup and restore, and appearance options that go beyond the original Launchpad, in a package that is free to use with a one-time Pro purchase.
Epismo OS is a collaboration OS for people and AI agents. It keeps the purpose and constraints of real work, so the next person or AI can continue without starting over. Epismo is built for people who work with AI tools such as Claude, ChatGPT, and Cursor and who want to move between those tools — or hand work to a teammate — without a re-brief. The product's central promise is "Switch AI. Keep the work." Work is kept in a Case that holds the result, the decisions behind it, reviews, and the next step, so work in progress survives a change of model, tool, or person. The problem Epismo addresses is continuity. When a piece of work is done inside a single chat with a single AI tool, everything that made it meaningful — why it was started, what the constraints were, which decisions were made, which claims were still assumptions — is locked inside that conversation. Moving to another AI tool, coming back the next day, or passing the work to a teammate usually means starting over: re-explaining the brief, redoing the research, and rebuilding context that already existed. Epismo keeps the purpose and constraints of real work so the next person or AI can continue without starting over, in the tools you already use. Everything begins with saving. Epismo keeps the purpose, the constraints, and the current decisions of a piece of work, along with the result, the decisions behind it, reviews, and the next step. Once that is saved, continuing becomes the default rather than restarting. You do not need a new chat — you hand the work in progress to the next person or AI. You can hand the same work to Claude, ChatGPT, or Cursor without redoing the research. You can open the same work the next morning and find that what it is for is still there. Or a teammate can open it and see what happened, and where to pick up. The example shown in the product is an "Acme renewal" Case marked In progress: a research step in Claude Code left the evidence and open questions, and an account executive continuing in ChatGPT picks up from there with no restart. Auto review is Epismo's quality layer. Instead of manually re-checking a saved result, you leave the work with Epismo, which reads it and writes what still needs checking. Those notes become the starting point for the next turn in Cursor, Claude, or ChatGPT, so your AI fixes what Epismo flagged. In the example, the review states that usage isn't sourced and that the churn claim is still an assumption; the following Cursor turn adds the usage and the filing. Crucially, auto review gives a saved result a fresh review, flags issues, and leaves the original unchanged — so you get a second pass without overwriting the work you already have. When the same kind of work comes up again, Epismo turns what worked into a playbook. A playbook captures what counts as evidence and what a person should check, so the next piece of work starts from there. The recommended playbook shown in the product, "Enterprise renewal review", is built from four named steps: scope the renewal risk, pull filings, tickets, and usage into one set, separate verified facts from assumptions, and hand the call to the account owner. Each step can name the Skill, MCP, CLI, Plugin, or Approval it should use — for example a "Renewal risk rubric" Skill, MCP connectors for filings and earnings calls and for CRM plus ticket history, a "Claim-to-source audit" Plugin, an "Exec brief builder" CLI, and an Approval step. This means the pattern of work becomes reusable and explicit, rather than something each person has to remember. Epismo's methodology is deliberately work-first: work first, the pattern later. You do not start by writing a pattern. The flow is four steps. Save: keep purpose, constraints, and current decisions. Handoff: the next person or AI picks up from there. Discover: see what worked, and keep that as a pattern. Improve: lessons from real work feed the next run. Only after real work has been saved, handed off, and reviewed does Epismo surface the reusable pattern, which reduces the risk of designing an abstract process that does not match how the work actually gets done. The outcome for users is continuity. Work is no longer trapped in a single conversation with a single tool: switching from one AI to another, returning the next day, or involving a teammate all happen without a re-brief. Because Epismo keeps the purpose and constraints, the next person or AI continues rather than restarts. Because auto review reads saved results and writes what still needs checking, quality checks become part of the workflow instead of a separate manual pass, and the original result stays unchanged. Because patterns become playbooks, teams stop starting from zero on repeatable work and can carry lessons from real work into the next run. The product is shown around an enterprise renewal review, a scenario where evidence, assumptions, and human sign-off all matter: research is gathered with Claude Code, the renewal brief is drafted in Cursor, Epismo flags unsourced usage and an unverified churn claim, and the account owner receives the call through an Approval step. More broadly, Epismo signals the many kinds of work it is meant to hold through its categories, including deck, email, operations, approval, campaign, customers, meeting, coding, report, content, launch, hiring, bug, support, experiment, research, legal, and accounting. Any of these can be saved as a Case, continued by another AI or teammate, reviewed automatically, and — where it repeats — turned into a playbook whose steps name the Skills, MCP, CLI, Plugin, or Approval to use. Epismo is for teams and individuals who already work with AI assistants and want that work to survive a change of tool, day, or person. The product states that it works with the AI you already use, and names Claude, ChatGPT, Cursor, and Claude Code in its examples; playbook steps can reference Skills, MCP connectors, CLI tools, Plugins, and Approvals. Epismo is offered as a web product with a free start — the site prompts you to "Start free" with no credit card required — and a separate "Talk to sales" path for buyers who want to speak with the team. Epismo OS is the collaboration OS for people and AI agents: it keeps the purpose, constraints, and decisions of real work in a Case, hands that work forward to the next AI or teammate, reviews saved results without changing them, and turns what worked into reusable playbooks. The primary value proposition is continuity — switch AI, keep the work, and don't start from zero next time.

Scrapboard Cloud 4 is an iOS and iPadOS app that recreates the classic concept of a digital bulletin board, bringing the cozy feel of a family refrigerator door right onto your iPhone and iPad. It is part of the Scrapboard series, which the maker describes as having a 12-year heritage behind it, and it is designed to work hand-in-hand with its macOS counterpart, Scrapboard 4. The app lets you create and manage multi-page virtual boards on your mobile devices, pin all kinds of content to them, and keep those boards in sync with the boards you keep on your Mac. Its purpose is simple: give you a creative, personal place to pin things up and keep them visible, wherever you are. Background: The maker explains that the Scrapboard series has always been about bringing that cozy, creative, chaotic energy of pinning things to a family refrigerator door straight onto your screen. Following up on the release of Scrapboard 4 for Mac, the team introduced Scrapboard Cloud 4 as its mobile companion for iOS and iPadOS. The problem it addresses is one of reach and continuity: a bulletin board traditionally lives on one screen, and staying away from that screen means staying away from your boards. By making the concept pocket-sized and adding cloud sync, Scrapboard Cloud 4 keeps your pinned content available no matter which Apple device you happen to be holding. Sync is the heart of the Cloud edition. With version 4, mobile and desktop sync together seamlessly via iCloud and CloudKit, so the same boards appear across your iPads, iPhones, and Macs using your iCloud account. The app supports multi-page virtual boards and project management, and it lets you push and fetch changes instantly rather than waiting for a manual export or import. You also get instant push notifications whenever edits are synced over from your Mac or another device, which means you can see the moment a board changes somewhere else in your Apple ecosystem. That combination of instant push/fetch and notifications turns a set of separate screens into one shared workspace. Scrapboard Cloud 4 is packed with six versatile layer types right in your pocket, and the first three cover the everyday content you would pin to a real board. The Text layer supports full typography, including font families, text sizes, and custom colors, so labels, headings, and notes can be styled to match the mood of a board. The Picture layer pulls images straight from your photo library or device storage, letting you pin photos and artwork without leaving the app. The SF Symbol layer places clean, native scalable Apple icons onto a board, which is handy for visual markers, categories, and simple decoration that stays sharp at any size. The remaining three layer types add live, functional content to your boards. The Appointment layer renders real-time countdowns with flexible reminder intervals, making it possible to pin an upcoming event to a board and watch the time tick down. The Web layer embeds live web content via a URL, so a board can show an actual page rather than a static screenshot. The Map layer handles precise GPS locations and landmark search lookups, letting you pin exact places and find them by name. Together, these six layer types mean a Scrapboard can hold text, images, icons, timers, live web pages, and locations on the same multi-page canvas. How it works overall: Scrapboard Cloud 4 is built to feel completely native, fast, and delightful to use, in the maker's words. You create multi-page virtual boards on your iPhone or iPad, add the layer types you need, and manage your boards and projects in one place. Because the app is designed to work hand-in-hand with Scrapboard 4 for Mac and shares boards through your iCloud account using CloudKit, the workflow is cross-device by default: edit on one Apple device, push the change, and fetch it on another. The product's unique approach is that it treats the old physical bulletin board as a software concept — pinning, arranging, and glancing — and then extends it beyond a single screen through cloud sync. Benefits: the obvious outcome is that your boards are no longer tied to one device or one desk. Whether you are away from your desk or sketching out ideas on your iPad on the couch, Scrapboard Cloud 4 lets you create boards and manage projects wherever you are. Instant push notifications mean you are never left guessing whether a change made on your Mac or another device has arrived. Because the six layer types cover text, imagery, icons, countdowns, web content, and maps, one app can serve as a pinboard, a countdown display, a live web reference, and a location list at the same time. And the app is free on the App Store, so trying it costs nothing. Use cases: the most literal one is the digital family refrigerator door — pinning pictures, notes, and reminders the way you would stick them to the fridge, but on your iPhone or iPad. Another is sketching out ideas on an iPad on the couch and then syncing them back to the Mac. Project management is a stated use: creating multi-page virtual boards, managing projects, and pushing or fetching changes instantly. The Appointment layer supports countdown scenarios with reminder intervals for upcoming events. The Web layer supports boards that show live embedded web content pulled from a URL. The Map layer supports saving precise GPS locations and performing landmark search lookups. Push notifications cover the case where a board is edited from your Mac or another device and you want to know right away. Target users, platforms, and pricing: Scrapboard Cloud 4 targets people in the Apple ecosystem, specifically iPhone and iPad users, including existing users of the macOS counterpart Scrapboard 4 who want the same boards on the go. The app runs on iOS and iPadOS and is listed as Free on the App Store, where you can download it and test cross-device sync with your Mac. Sync relies on your iCloud account and CloudKit. The maker is Señor Tomato, and a support site is available for feature requests and questions. Summary: Scrapboard Cloud 4 takes a familiar, cozy idea — the family refrigerator door — and makes it pocket-sized, multi-page, and cloud-synced. With six layer types, instant iCloud and CloudKit sync, and push notifications, it keeps your pinned boards and projects consistent across your iPad, iPhone, and Mac.
Harbor is a private notes app and Evernote alternative that its website describes as a second brain you finally own, and own for life. It is designed to capture notes, documents, scans, photos, audio recordings, handwriting and web clips in one place, keep them searchable, and keep them for good. Harbor positions itself as a personal rather than an enterprise product: your data is never sold, mined or shared, and the promise is that your brain stays yours. It runs as native apps on Mac, Windows, iPhone, iPad, Android and the web, plus a CLI, and it opens with a free plan that requires no credit card. The product exists because of a specific frustration. As Harbor puts it, Evernote promised to be your second brain, then broke the promise: prices doubled, the free plan was gutted, the app got slow, and your data got harder to leave with. That story is familiar to many long-term note-takers, and it explains why people hesitate before committing years of notes, scans, photos and recordings to a single service. Harbor's answer is to pick up the original idea — one private place for everything, forever — and to commit to it in writing, with explicit promises about pricing, export and data ownership rather than vague reassurances. Capture is the first half of that promise. The app is built to save anything, in any form: notes, scans, photos, audio and handwriting, plus web clips gathered through the Web Clipper. The website shows this in a domestic scene — a couple sorting their mail and scanning documents together at a sunlit table — with the scanned document then saved in Harbor. The value of capturing in many formats is that you stop deciding in advance what is worth keeping. A receipt, a handwritten page or a voice recording can all go into the same second brain, and the decision about whether it matters can be made later, at the moment you actually need it. Finding is the second half, and it is where Harbor leans most heavily on technology. Harbor reads the words inside your photos, scanned PDFs and even your handwriting, so a short two-word search can surface the exact page you need. The site illustrates this with a search for 'receipt' that returns a Monroe County business tax receipt stored as a PDF, with the matched text — 'FLORIDA LOCAL BUSINESS TAX RECEIPT — issued pursuant to Ch. 205' — shown in context, alongside a scanned 2023 F-250 brake job invoice, from which Harbor has read details such as the 24-month warranty and the next service due. Recordings are handled in the same spirit: your audio becomes searchable transcripts. For anyone who scans paperwork or records spoken notes, this turns an archive of files into something closer to a memory that can actually be queried. Privacy is the third pillar. Harbor lets you turn on zero-knowledge encryption for any note or notebook, so that only you hold the key. The point of applying it selectively is that you can lock down the genuinely sensitive material while keeping everything else fully searchable and AI-ready; the site's example is an encrypted notebook that stays locked until you unlock it. Underpinning this, the security section lists zero-knowledge encryption and privacy by principle, with a commitment that your data is never sold, plus sign-in options that include passkeys, Apple, Google and full device control. Harbor is available everywhere you are. Its apps are described as genuinely native — fast and light, not a web page in a wrapper — and everything works with no signal and syncs the moment you are back online. The listed platforms are Mac, Windows, iPhone, iPad, Android and the web, and the same notes sync across all of them. The Web Clipper extends that reach into the browser: available for Chrome, Edge, Firefox and Safari, it can clip a simplified article, a full page, a bookmark or a screenshot, let you mark it up, and then drop it straight into the right notebook without ever leaving the page. That matters because the moment you leave a page to file a clip is usually the moment the clip is lost. Rather than building a weaker assistant into the product, Harbor opens the door to the AI you already pay for. You can connect ChatGPT or Claude, as well as tools such as Cursor, through an API, CLI and MCP, so your assistant can search, add and organize your notes in Harbor. The site's framing is direct: you already pay for ChatGPT or Claude, so instead of paying Harbor for a weaker one baked in, you connect the one you have. Access works with your keys and your data, and can be revoked at any time. The rest of the feature set covers the everyday mechanics of keeping a notebook. Notes and notebooks are deliberately simple, with no Markdown and no clever-tag gymnastics; tasks and reminders sit right next to your notes with due dates, recurrence and priority; templates provide ready-made note structures you build once and reuse; version history saves every change with one-click restore so an edit is never lost; and public links let you share any note read-only, with no account needed to view it. Import and export are treated as core features rather than afterthoughts: one-step import brings an Evernote library in, and full export takes everything out, anytime, in the open. Harbor's distinctive approach is less about any single feature than about the commitments wrapped around them. You are never held hostage: if you stop paying, your account goes read-only and you can still export everything, and delete it. A real API, MCP and one-click export mean you can leave whenever you want, on the explicit logic that Harbor wants you to stay because it is great, not because you are stuck. The pricing itself is framed as a promise: no price increase for three years, then capped at 10% a year. The product is cross-platform, starts free, and is priced as one simple plan. For users, the outcome is a library that behaves the way a second brain should. Everything you save syncs the moment you save it, on every device you own, so the same notes are available on a desktop, on a phone or in the browser, online or offline. Scans, receipts, photos and recordings stop being dead files and become searchable material. Sensitive items can be encrypted while the rest of the library stays usable and available to your own AI tools. And the commercial terms — locked pricing, read-only rather than deleted data, and full export on every plan — mean the cost of committing years of notes to Harbor is bounded in a way the site argues the previous generation of note apps was not. Concrete scenarios from the site include searching a short term such as 'receipt' to pull up a scanned business tax receipt or a vehicle service invoice and immediately see the matched line; scanning household mail and documents as they arrive and filing the results in Harbor; clipping an article from a news site, annotating it and saving it into the right notebook without leaving the browser; turning audio recordings into searchable transcripts so a spoken note can later be found by its words; and importing an entire Evernote library — notebooks, tags, checklists, attachments and clips — in one step when switching over. Shared read-only links cover the case where someone else needs to read a note without creating an account. Harbor is aimed at individuals rather than enterprises: people who keep personal notes, scans and recordings, people who care about privacy and ownership, and in particular people currently considering leaving Evernote — the site offers a dedicated switching path and a one-step importer for notebooks, tags, checklists, attachments and clips. Its integrations are the AI tools you already use, reached through API, CLI and MCP, and its browser extension works in Chrome, Edge, Firefox and Safari. Pricing is deliberately simple: a free plan to start with no credit card, and one paid plan, Harbor Unlimited, at $8.25 per month when billed yearly at $99, or monthly, with annual saving 17%. The paid plan includes unlimited notes, notebooks and devices, OCR search, all apps and the Web Clipper, optional zero-knowledge encryption, API, CLI and MCP access, and import and export at any time. In short, Harbor takes the familiar promise of a second brain and attaches guarantees to it: capture in any format, find anything with OCR and transcripts, encrypt what is sensitive, work natively on every device and offline, connect your own AI, and keep the ability to take everything with you. The claim is not that it does more than the alternatives, but that it can be trusted to keep doing it — with the price, the export and the ownership terms written down rather than merely implied.
Termphin is an SSH client that keeps the shell alive on the server so that sessions survive locked screens, lost signals, and network switches. It is a mobile terminal built for developers, system administrators, and anyone who manages remote machines from a phone, and it combines a fast terminal with an integrated SFTP browser and editor, a snippet runner, an SSH key manager, port forwarding, ProxyJump bastion chains, and a biometric lock. The stated purpose is simple and repeated throughout the site: never lose an SSH session again. Your shell stays alive on the server through locked screens and network drops, and when you come back you are put on the same screen you left. Termphin is available on Google Play, is free to use, and comes with no ads and no in-app purchases. The site also positions it explicitly as built for productivity and built for AI coding agents such as Claude Code and OpenCode. The problem Termphin targets is specific and well documented. A blog post on the site asks why your SSH session dies when you lock the screen, and answers with the mechanics of mobile app suspension: mobile SSH connections drop when an app is suspended, and the post covers what the client does to stay scheduled and how a remote helper keeps long-running shells alive. On a phone, locking the screen, losing a signal, or switching from Wi-Fi to mobile data has traditionally terminated the connection, and with it any job that was running. That matters most for work that takes minutes rather than seconds - deploy scripts, database migrations, builds, or AI coding agent tasks - where a dropped session can mean losing both the process and the context of what it was doing. Termphin's answer is to move the shell off the app and onto the server. Persistent sessions are the core of the product. Termphin maintains the connection while the app is backgrounded or the phone is locked, and it relies on the Termphin Agent: a tiny, open-source helper that holds the remote shell open and reattaches instantly when you return. Because the shell runs on the server rather than inside the app, your jobs keep running even if you lock your phone or lose signal. The FAQ explains that if the connection drops or you switch networks, the small open-source Rust agent on the server keeps the remote shell running and reattaches you seamlessly upon reconnect. For basic sessions no helper is required at all, since shell detection is automatic, which means the agent is an enhancement for persistence rather than a prerequisite for connecting. Terminal rendering gets its own emphasis. Termphin draws the TUI directly with Flutter rather than inside a web view, which the site says keeps htop, vim, and other terminal user interfaces rendering without broken box characters. The pixel-perfect TUI section adds that spinners, progress bars, and diff views render cleanly without mangled characters - a practical difference when you are reading a diff or watching a progress bar on a small screen. Appearance is configurable as well, with 14 color schemes and controls for font size, line height, and padding, all previewed live in the terminal before you commit to a setting. The toolbox covers the day-to-day tasks around a remote shell. SSH tunnels let you open local and remote port forwards per session, or save them with a profile so they come back with the connection. Integrated SFTP puts a full file browser a tab away from the terminal: you can browse remote files, edit them with syntax highlighting, preview images remotely, and resume file transfers that were interrupted. A one-tap SFTP upload flow lets you upload files from your phone and then paste their remote server path straight into your prompt, which removes the usual guesswork about where an upload landed. Machines, snippets, and key management round out the toolset. In the machines list you save the host, user, and credentials once, then tag, search, and connect in one tap; the site lists fast search and tags, ProxyJump bastion chains, and multi-tab concurrent sessions as the organizing features. Snippets let you save recurring commands once and trigger them instantly across your infrastructure, with a search-and-run palette, execution history that records exit codes, and a customizable action dock. Security is handled by a device-bound key vault: keys and profiles are sealed with AES-256-GCM behind your phone's PIN or fingerprint, you can generate ed25519 and RSA keys, biometric PIN and fingerprint lock gate access, and host key pinning happens on connect. The unique approach is the split between client and server. Instead of holding the shell inside a mobile app that the operating system can suspend, Termphin keeps the shell running remotely and treats the app as a window onto it, reattaching when you return. Termphin says it maintains the connection while backgrounded or locked, and connections go directly to your server with host key verification rather than through an intermediary. Data protection stays local: keys and profiles are sealed in an AES-256-GCM vault on the phone, gated by PIN or biometrics, and only opt-in anonymous crash analytics are ever sent. Two of the pieces are open source on GitHub - the terminal renderer, terminal_view, and the server helper, termphin-agent - so the persistence mechanism can be inspected rather than taken on trust. The benefits follow from that architecture. Long jobs keep running when the phone is locked or the signal drops, and you reattach anytime rather than restarting. Terminal output stays legible because the TUI is drawn natively, so htop, vim, spinners, progress bars, and diffs do not degrade into mangled characters. Credentials and keys stay on the device in an encrypted vault rather than being typed repeatedly, and profiles, tags, and search turn a list of servers into something you can navigate in a tap. Snippets cut repeated typing down to a single action, and because the session survives network changes, switching between Wi-Fi and mobile data stops being a destructive event. Concrete scenarios are described on the site. The AI coding agents section gives the clearest one: start a ten-minute Claude Code or OpenCode task and pocket your phone, because the agent runs on your server and the session never aborts. The FAQ confirms that Claude Code, Codex, and OpenCode run seamlessly, that tasks keep executing when the screen locks, and that TUI diffs and progress bars render cleanly. Other workflows in the content include reaching a server behind a bastion by pointing a profile at a jump host, running interactive keyboard prompts for 2FA authenticator codes (TOTP) and PAM passwords, browsing and editing a remote file over SFTP without leaving the app, and triggering saved recurring commands across infrastructure from a search-and-run palette. Termphin is aimed at people who work on remote servers from a phone: developers, administrators, and anyone running long-lived processes or AI coding agents over SSH. It works with any server reachable over standard SSH - Linux, macOS, BSD, or Windows - with automatic shell detection, and it interoperates with bastion setups through ProxyJump-style jump hosts and with 2FA through TOTP and PAM prompts. The stack described on the site includes Flutter for the terminal rendering, a Rust server agent, and AES-256-GCM for the local vault. Pricing is straightforward: Termphin is free to use with no ads and no in-app purchases, distributed through Google Play. In short, Termphin's value proposition is that the shell lives on the server while you live on your phone. By keeping sessions alive through locked screens, lost signals, and network switches, rendering terminal interfaces properly, and bundling SFTP, tunnels, snippets, key management, and bastion support into one free Android app, it turns mobile SSH from a fragile short-lived connection into something that behaves like a persistent workstation.
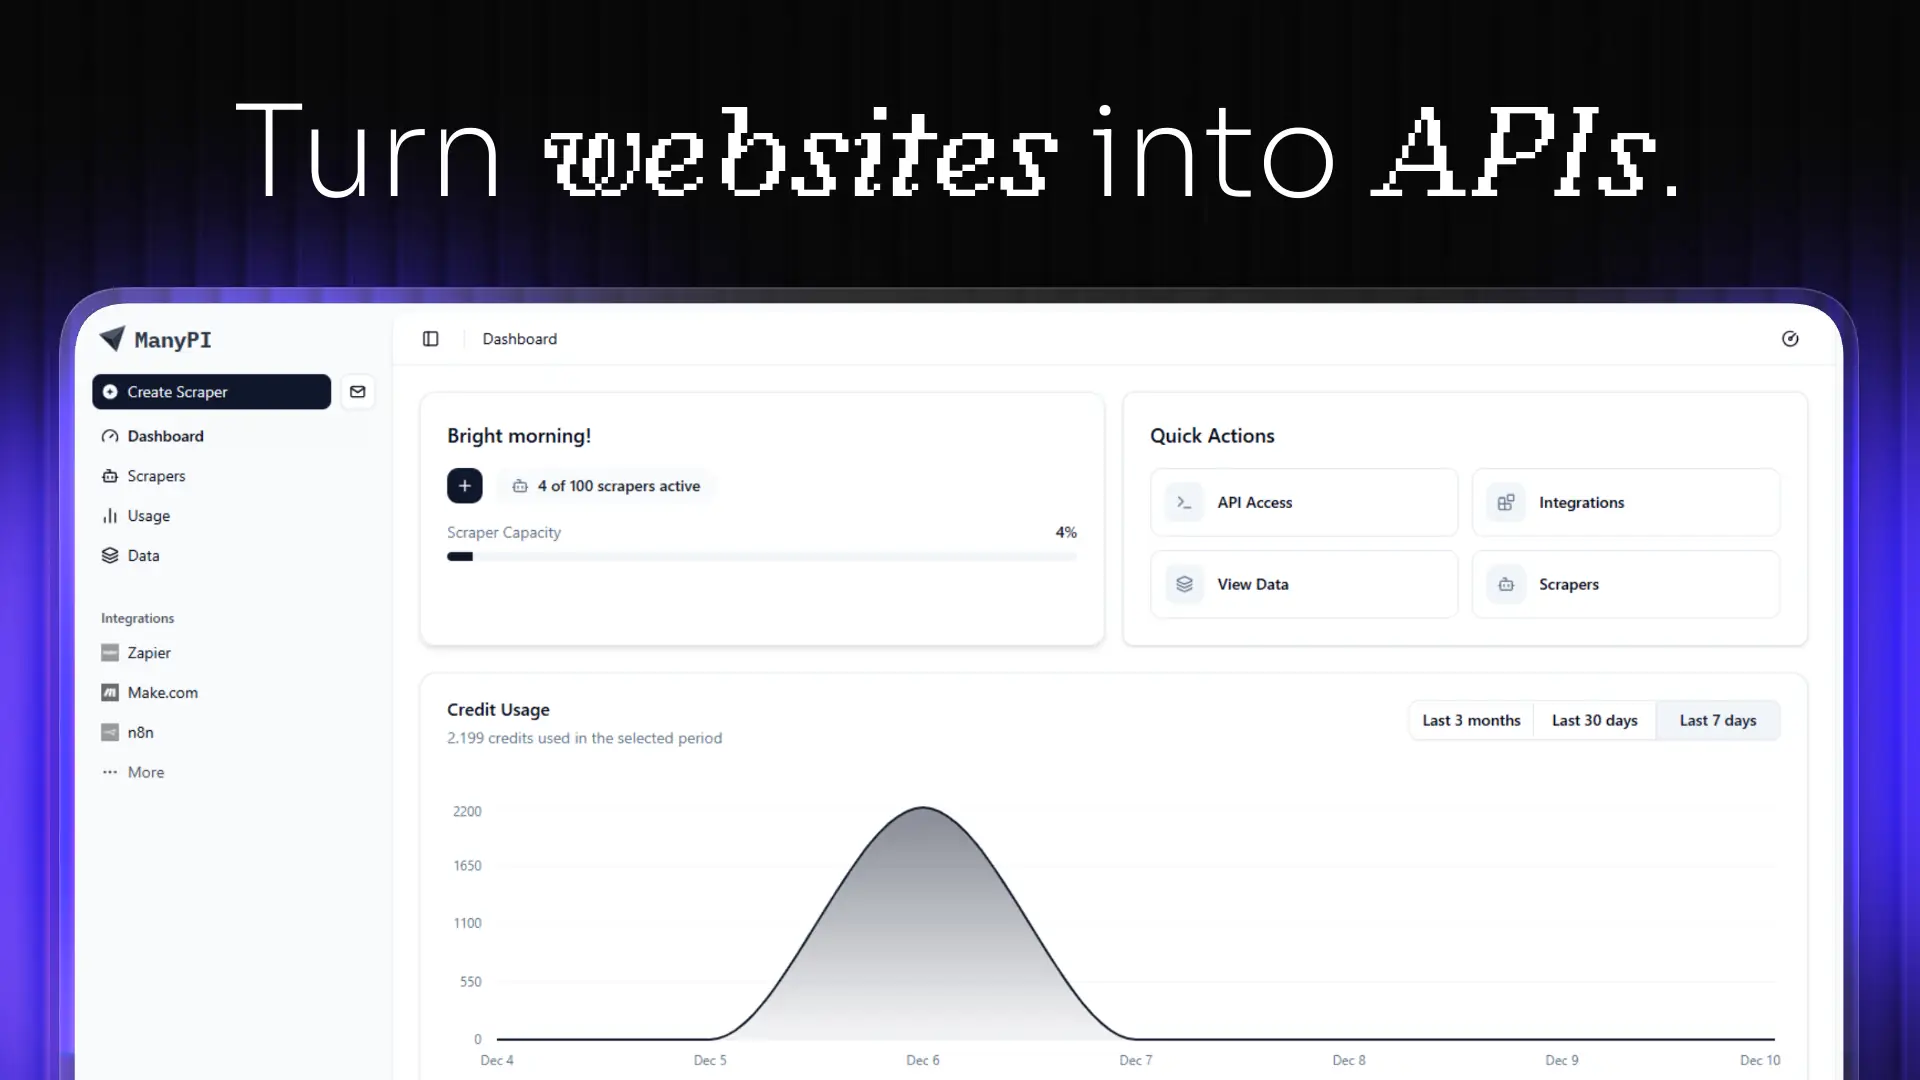
ManyPI is an AI sales agent built for lead generation and cold email outreach. It allows users to describe their ideal customer in a single sentence, then finds matching companies and the people who sign on the live web, verifies every email address, and runs multi-step cold email campaigns from the user's own inboxes. The product is designed for growing companies and sales teams that want more customers, and it states that it is already used by more than 1,700 growing companies. Its core promise is to find validated leads, reach out, and turn emails into sales, with a free plan and paid plans starting from $25 per month. Cold outreach is one of the most direct ways to win new customers, but the work behind it is fragmented. Teams often build lead lists manually, hunt for decision-maker email addresses, check each address by hand, write and schedule follow-ups, and then track replies across separate inboxes. Bad or duplicate addresses cause bounces, which can damage the reputation of a sending domain, while manual follow-up steps are easy to forget. ManyPI brings lead generation, email verification, cold email outreach, workflow automation, CRM, and a unified inbox into one subscription. According to its Product Hunt description, the AI agent also validates pain points and emotional buying triggers, then sends hyper-personalized outreach that turns those signals into sales. This matters because it reduces the number of disconnected tools a sales team has to maintain while keeping the focus on conversations that can become revenue. Lead generation in ManyPI starts with a plain-language description of the ideal customer. A user might type "Marketing agencies in Berlin with 10–50 employees," and the system returns matching companies together with the people who sign. In the example shown on the website, that search produced 1,284 company matches, including Northwind Studio in Berlin and Kranz & Partner in Hamburg. Because ManyPI searches the live web, the lists are meant to reflect current information rather than a static database. The homepage also offers separate starting points for finding new leads and for enriching a lead list, so users can either build a fresh list from scratch or improve contacts they already have. Email verification is built into the workflow so that every address is checked before a user sends. The website promises no bounces, no duplicates, and no burned domain, which addresses a common risk in cold outreach: sending to invalid addresses can hurt deliverability and make future emails look like spam. ManyPI verifies and scores addresses, then drops the ones that do not meet the bar. In the example on the site, Northwind Studio scored 92 and Kranz & Partner scored 87, while Wide Net GmbH scored 34 and was dropped, and Aurora Digital scored 90. This scoring step gives users a clear signal about which contacts are safe to email and which should be left out of a campaign. Cold email outreach is handled through multi-step campaigns sent from the user's own inboxes. Warmup is described as running, which is intended to help inboxes build sending reputation, and replies are collected in one place rather than scattered across separate accounts. A sample sequence shows an Intro sent on Day 0, a Follow-up sent on Day 3, and a Last touch queued for Day 7. The dashboard also shows a reply, such as "Northwind Studio replied 2h ago," making it easy to see which prospects have responded. This combination means users can plan a sequence once and let ManyPI manage the timing, while still sending from their own inboxes and keeping replies centralized. Workflow automation connects replies to the next action. The website presents a simple rule: when a lead replies, ManyPI tags it and starts the next step. There is no wiring to maintain, so users do not have to build or repair automation logic themselves. ManyPI also states that every plan includes CRM and pipeline, a unified inbox for replies, an AI agent, web scraping, data analysis, and API and webhooks. Having these capabilities in one subscription means a team can manage lead status, read and respond to replies, gather web data, analyze results, and connect other systems without purchasing separate products for each function. The ManyPI MCP Server is now live, and it lets users ask for leads from Claude, ChatGPT, Gemini, or any MCP client. The list lands in the user's table rather than in the chat transcript, and the endpoint is mcp.manypi.com/mcp. This gives teams a way to request prospect data from the AI tools they already use. ManyPI also integrates with HubSpot, Salesforce, Claude, and OpenAI, and it is designed to push verified leads straight into the CRM a team already runs on. Integration matters because sales teams rarely work in a single tool; sending verified leads into an existing CRM keeps data consistent and reduces manual entry after a list is built. The benefits described by ManyPI center on finding and converting ideal customers. The Product Hunt tagline says the product can "10x your revenue by finding your ideal customers," and the homepage says ManyPI finds validated leads, reaches out, and turns emails into sales. By verifying emails before sending, the product aims to protect sender reputation and reduce bounces. By automating follow-ups and tagging replies, it aims to save the manual work of tracking sequences and moving leads forward. The free plan and paid plans starting from $25 per month make it accessible to teams that want to test the workflow before committing. Concrete use cases shown on the website include finding new leads by describing an ideal customer, enriching an existing lead list, and sending outreach from the user's own inboxes. A sales team might search for marketing agencies in Berlin with 10–50 employees, review the matching companies and decision makers, verify and score the email addresses, then launch a multi-step sequence with an intro, a follow-up, and a final touch. When a lead replies, automation tags the lead and starts the next step. Teams can also push verified leads into HubSpot or Salesforce, or ask for leads through an MCP client such as Claude or ChatGPT and have the list appear in their table. ManyPI is aimed at growing companies and sales teams that need a steady flow of qualified leads. The website notes that more than 1,700 growing companies already use it, and the lead-generation example focuses on marketing agencies, which suggests agencies and B2B teams are a natural fit. The product is delivered as a web application and also exposes API and webhooks, along with an MCP server, so it can connect to other tools. Pricing is freemium: there is a free plan, and paid plans start from $25 per month. Integrations include HubSpot, Salesforce, Claude, and OpenAI, and the MCP endpoint is mcp.manypi.com/mcp. In short, ManyPI combines AI lead generation, email verification, cold email outreach, and workflow automation into one subscription. It is built for teams that want to describe their ideal customer once and then let an AI agent find matching companies and decision makers, verify every address, run personalized sequences, and route replies into a unified inbox. With CRM, pipeline, scraping, analysis, API, webhooks, and an MCP server included, it aims to reduce tool sprawl and help turn cold outreach into sales.
Embedful is a tool for building multi-tenant embedded dashboards that display personalized analytics to individual customers from a shared application database. It is aimed at SaaS teams that want to give their customers useful, customer-facing analytics without taking on an analytics infrastructure project. In practice, the product lets a team connect an existing data source, configure one dashboard, and securely embed personalized views for every customer directly inside their own product, website, or client portal, with the embedded view scoped to each customer's own data at render time. The problem Embedful addresses is a familiar one for product teams: showing customers their own data usually means either building and maintaining an analytics platform yourself or leaving customers without insights. Full analytics platforms are built for teams that need cloud deployment, data modeling, APIs, SDKs, and release management, which is a heavy footprint when the actual job is secure customer dashboards. Embedful positions itself as the shorter path to customer-facing analytics by keeping implementation focused on four steps — connect data, build the view, map each account, and embed it. The stated goal is to ship the dashboard, not an analytics platform. The first step is connecting existing data. Embedful's Query Builder lets you add a connection to an existing application database by entering credentials, with passwords encrypted at rest and connections that can be secured with SSL. Supported data sources include PostgreSQL, MySQL, and Firebase, as well as Google Analytics, spreadsheet files, and APIs and custom data sources. Because Embedful works from data you already have, there is no extra deployment to manage, and teams avoid standing up separate analytics storage purely to power customer dashboards. Once data is connected, a visual builder lets you select tables, choose columns, and apply dynamic filtering without writing SQL. Charts, tables, and counters can be combined into a single shareable dashboard view. These views are reusable across every customer, can be set to update automatically, and use responsive layouts. The stated benefit is that there is no charting UI to engineer: Embedful supplies the dashboard interface and rendering rather than expecting a team to build a bespoke front-end analytics stack alongside its existing product. The third stage is Paste, Map, and Publish. When building a Customer Dashboard, you select which database column identifies the customer, and that mapping enforces data separation so each customer sees only their own data. Before embedding, the dashboard can be previewed with real customer data, so the experience can be checked against actual accounts rather than samples. Embedful also generates backend code for creating secure, short-lived tokens for each viewer, and access is granted at the account level. A single dashboard configuration then serves all customers, with the embedded view dynamically scoped to each customer's data at render time. Embedful describes itself as right-sized by design. Instead of deploying an analytics platform in your own cloud environment, you configure a hosted dashboard layer that Embedful operates. The product highlights three principles: hosted for you, so there is no analytics infrastructure to operate; one build for every account, so mapping each customer's account ID to the right data turns a single dashboard into a secure, personalized view per account; and a lightweight embed, so dashboards can be added without a front-end analytics build. The embed is dropped into your SaaS app, website, or customer portal, and Embedful handles the dashboard UI and rendering. The outcome for SaaS teams is fewer moving parts: one dashboard to maintain, with updates to a single experience keeping every customer view in sync; no analytics services to deploy because Embedful hosts the dashboard layer; and useful insights placed in every customer's hands, described as supporting effectively unlimited customer viewers. Because data separation is enforced through the customer-identifying column, each account sees only its own data while the team maintains just one configuration. Concrete uses include embedding personalized dashboards inside a SaaS product's analytics area, adding a dashboard to a website, or delivering one through a client portal with secure, account-level access. Embedful also states that you can add a hosted dashboard to the tools you already use, listing Carrd, CMSMS, Coda, Drupal, Framer, Lovable, Notion, Obsidian, WordPress, Wix, and Xtensio, without rebuilding your product around an analytics SDK. Live dashboard examples are available for Lovable, Notion, Framer, and Xtensio. The primary audience is SaaS teams that need customer-facing analytics rather than an internal business intelligence platform, and builders working in website and no-code environments such as those listed above. The relevant tech surfaces are the product's own web application, the hosted dashboard layer, and the backend code Embedful generates for issuing secure, short-lived viewer tokens. On data sources, the site names PostgreSQL, MySQL, Firebase, Google Analytics, spreadsheet files, and APIs and custom data sources. The website invites visitors to start building free, and offers a how-it-works walkthrough plus a newsletter for updates on new dashboard features, integrations, and templates. Embedful's core value proposition is straightforward: it shortens the path from existing data to secure, personalized, customer-facing dashboards. By hosting the dashboard layer, enforcing per-customer data separation, and providing a ready-made embed, it lets SaaS teams deliver embedded analytics in minutes instead of taking on the deployment, data modeling, API, SDK, and release-management overhead of a full analytics platform.
ChainYourMac is a native scrolling window manager for macOS. Rather than squeezing every window into a fixed grid, it places each window as a column on a horizontal strip that runs past the edges of your display. You move around that strip with three- or four-finger trackpad swipes or with keyboard shortcuts, and every window keeps the width you gave it. It is built for Mac users who want the automatic layout management of a tiling window manager without their workspace reflowing every time another app opens. It ships as a real Mac app — SwiftUI on top, a Rust window engine underneath — and requires macOS 13 Ventura or later on Apple silicon. Grid tiling managers such as yabai, Amethyst and AeroSpace divide the screen again every time an app opens, so everything keeps getting smaller. With three windows open each one takes roughly a third of the screen, and the next launch narrows them all once more. Window snappers such as Rectangle and Magnet sit at the opposite end: you invoke them window by window, and they do not maintain a layout at all. ChainYourMac maintains a layout without the grid. The strip gets longer instead of the windows getting thinner: with three windows open, a grid gives each one about a third of the screen while the strip still gives each one half. New windows open beside the one you are using, nothing overlaps, and nothing gets lost behind another window, because every window has its own place on the strip. The strip follows your focus. Move focus from the keyboard or swipe the trackpad and the strip scrolls just far enough to bring the window into view, on a spring animation that starts the moment you press the key. The animation is a vsync-locked spring, so movement around the strip feels immediate. Layout is persistent as well: column order, widths and stacks come back after a restart, and every display and every Space keeps a strip of its own, so work and chat never get shuffled together. Session restore and launch at login are part of version 2.0, which means the app can start with your Mac and begin tiling automatically. Stacks let you put several windows in one column. You can pull a window into the column on its left or right, push it back out, reorder windows inside the stack, and make any window taller or shorter; heights can also be equalized with a single shortcut. When each window in a stack deserves the full height, one shortcut flips the column into a tabbed column and back again. Widths are handled with presets: cycle a window through the widths you choose, such as 25, 33, 50, 66 and 75 percent, or nudge it wider and narrower. Full width and centre are one key each. Gaps between windows and at the screen edges are configurable down to zero, and windows size themselves around the Dock so nothing ends up underneath it. Version 2.0 adds a strip minimap that appears while you navigate, shows where you are, and fades out again. An optional focus border can sit around the focused window and everything else can be dimmed; both features are off until you enable them. Centre modes let you keep the focused column centred never, only when the strip overflows, or always. You can drag a window onto another column and the strip rearranges around it. Per-app window rules let you float apps that should not tile or give an app a fixed slot on the strip, and native macOS fullscreen is left alone — put a window into fullscreen and ChainYourMac stays out of its way. Every shortcut is rebindable, one action can carry several bindings, and the recorder understands non-US layouts including AZERTY, QWERTZ and Dvorak. Settings apply instantly: change a gap, a width or a key and you see it on screen straight away, with no Save button and no restart. Multi-monitor support is built around one strip per display. Every display has its own independent strip with its own focus and scroll position, windows never spill onto the screen next door, and one shortcut sends the focused window to the next display. macOS Spaces work the same way, with each Space keeping a separate strip layout. The trackpad swipe is the signature interaction: swipe with three or four fingers and the strip moves with them one to one, then settles on the nearest column. Under the hood, ChainYourMac is a real Mac app rather than a script collection. The window engine is written in Rust and runs as a small background process that sits idle until a window changes or you press a shortcut; shortcuts are handled by the engine directly, so moving around the strip feels immediate. The interface is native SwiftUI: a menu bar item and a settings window where every option has a control. There is no Electron, no web view and no config file to learn. The app needs one permission, Accessibility, because that is how macOS lets any window manager move and resize other apps' windows; Rectangle, Magnet and others require the same one. Everything happens locally on your Mac — the app does not read your screen contents or send data anywhere, and there is no account and no telemetry in the app. A self-healing engine restarts the engine process if it ever stops and keeps an engine log showing what happened, while new versions arrive through Sparkle, the standard Mac updater. The outcome is a workspace that stays calm as you work. Because each window holds its width, opening another app never triggers a reflow, and you never have to hunt for a window that has been pushed behind another one. Navigation becomes a single gesture or keystroke in the direction you want to go, and because the position of every window is predictable, you build muscle memory for where things live. Column order, widths and stacks survive restarts, and displays and Spaces keep their own strips, so restarting your Mac does not mean rebuilding your workspace. Concrete workflows include a development session with a code editor, a terminal, a log window and documentation all open at once: stack the terminal and logs into one column, tab them, and keep the editor at full or half width without ever resizing the rest. Multi-monitor desks benefit from one strip per display, with a keystroke to throw a window to the other screen. People who liked PaperWM on GNOME or niri on Wayland get the same scrolling model with Mac manners, and anyone with an app that should not tile — a floating palette or a small utility window — can float it. Automating the strip is possible too: a chainyourmac:// URL scheme, Raycast script commands and a command-line tool let other tools drive the window manager. Requirements and pricing round out the picture. ChainYourMac needs macOS 13 Ventura or later and runs on Apple silicon (M1 or newer); Intel Macs are not supported. It is notarized by Apple and signed with a Developer ID, with no kernel extensions, no system modifications and no need to disable SIP. It is a one-time purchase rather than a subscription: the standard 1-Mac lifetime license is $19.99, with the first 20 launch licenses at half price, $9.99. Multi-Mac licenses are also available — 3 Macs for $24.99 launch price ($49.99 regular), 5 Macs for $39.99 ($79.99) and 20 Macs for $149.99 ($299.99) for teams — each giving one key with the corresponding number of activations, free updates forever, and the ability to move an activation to a different Mac after deactivating it. Checkout is handled by Gumroad, and the download and license key arrive by email. ChainYourMac takes the scrolling window model that Linux users know from PaperWM and niri and delivers it as a polished native Mac app: windows on an endless strip, trackpad swipes that follow your fingers, stacks and tabbed columns, per-app rules, multi-monitor strips and a SwiftUI interface over a Rust engine. It keeps the automation of tiling without the grid, so new windows never shrink the ones you are already using.
Minicart is a platform for launching and running an online store by chatting with AI. According to the website, you snap a photo of what you make and Minicart builds you a real website that you own, then gives you AI teammates to run it for you. The site positions Minicart for the people who make and sell things — it names makers, creators and resellers — rather than for developers or ecommerce specialists. Its stated purpose is to let someone launch and run a store without learning ecommerce software: no code, no design work, nothing to configure. The promise is deliberately plain: if you can take a photo and send a text, you can run a Minicart store. The site frames Minicart against selling inside someone else's platform. In its own words, a store should not be "a booth in someone else's marketplace." Marketplaces charge listing fees and keep the customer relationship buried in a feed, and building on existing store software can mean monthly fees and a stack of apps. The problem Minicart addresses is twofold. First, getting a real store live is usually slow and technical. Second, once a store is live, the everyday work — listings, marketing, shipping, customer replies, sales tax — turns into a second job. Minicart's answer is to give you a storefront of your own plus AI teammates that handle that busywork around the clock. Getting started is built around photos and imports. Minicart states that a single photo is enough to get started: you take a photo of what you make, answer a few quick questions, and Minicart builds the rest, turning the photo into a polished product listing and a full website automatically. The site advertises going from photo to live store in under ten minutes, with no design work to do. For sellers who are already trading elsewhere, Minicart offers one-click import. You paste your Etsy shop link and Minicart pulls in every listing — titles, prices, photos and variations — then rebuilds them on a site that is yours, while your Etsy shop keeps running. The same one-click approach works for Shopify, bringing products, images and collections across, and for eBay, importing titles, prices, photos and variations onto a site you own. Minicart describes these as read-only connections, so your existing store is never touched or paused. After launch, three named AI teammates take over the daily work. Sloane is the storefront teammate: she builds the site, takes payments, tracks sales and keeps listings current. Milo is the marketing teammate: Milo drafts lifestyle photos, social posts and discount codes that bring people in, and the site shows Milo drafting Instagram posts for new products. Logan is the logistics teammate: Logan ships orders, tracks inventory, handles refunds and drafts customer replies, with the site showing Logan preparing a shipping label and writing a reply to a customer question. The site describes these teammates as working 24/7 — its example timeline runs from turning photos into products in the morning through processing payments and sending a payout in the evening. Everything is driven through chat. The site says that if you can text, you can run a store: you manage inventory, draft social posts and talk to customers through a simple chat interface. Commands are given in plain language, and the site gives the example of creating a 20% summer promo code for all bracelets, which the assistant confirms with the code SUMMER20. The same chat interface powers a bulk editor for updating everything at once. Saying "increase price of all red necklaces by $5" makes the team line up the affected items and show a confirmation list before anything changes. Minicart makes clear that you review the list, uncheck anything you want to skip, and confirm — nothing changes until you say so. The same review-and-confirm pattern applies to inventory updates such as new stock numbers for bracelets and necklaces. The overall method is a three-step loop: snap a photo, let Minicart build your store, then go live and sell. Step one is taking a photo of what you make and answering a few quick questions. Step two is Minicart turning that photo into a polished product listing and a full website automatically. Step three is launching the site, sharing the link anywhere and taking orders in minutes. From there, the teammates keep running the operation under a single stated rule: you are always in control, and nothing goes out without your say-so. The stated outcomes for users are concrete and tied to ownership. You get your own website that lives on your own domain under your brand, rather than inside a marketplace feed, and you can bring your own domain or grab a new one, with your store carrying your name, colors and style from day one. There are no listing fees, so you can list as much as you want, and Minicart says it only charges a small card fee when you actually make a sale. Because the store is yours, you keep your customers: their emails are yours to build repeat business and a brand you can grow for years. The site also highlights speed — launch in minutes rather than weeks, and live in ten minutes — along with dropping monthly fees and the app stack associated with other platforms. The use cases shown on the site are drawn from real stores. Minicart says it helps you sell resin art, and its how-it-works example builds a store from a photo of a candle. It lists storefronts selling trading cards and sports memorabilia, sneakers, boutique gifts, handmade accessories and faith-inspired apparel, plus a diecast model car store. Imports are pitched at sellers who already trade on Etsy, Shopify or eBay and want a store they own while keeping their existing shop open. The bulk editor scenario — repricing a set of red necklaces or adding new butterfly bracelets and ruby necklaces — shows a typical day of small catalog updates handled by chatting. Minicart is aimed at makers, creators and resellers who have no interest in coding, designing or configuring ecommerce software; the FAQ states that if you can take a photo and send a text, you can run a Minicart store. Integrations explicitly mentioned are one-click imports from Etsy, Shopify and eBay, custom domains, and social posting such as Instagram. On pricing, Minicart says there is a generous free plan with no monthly fees to start selling, and that paid plans lower the card rates; no credit card is required to start. Every visitor can connect their own domain and brand, and the FAQ confirms the store runs on a Minicart domain such as yourstore.minicart.com or a custom domain you own, with the customer list yours to keep. In short, Minicart's value proposition is ownership without overhead. It pairs a real store on your own domain and your own customer list with AI teammates who handle listings, marketing, shipping, refunds, customer replies and sales tax through plain conversation — so makers and resellers can launch in minutes, list without listing fees, stay in control of every change, and spend their time making instead of managing store software.
Awnsy is a small menu bar translator for macOS that turns one keystroke into an instant translation. You select text in any app, press ⌘C twice, and the translation streams in live right over the window you are working in. For text you cannot select — words inside images, videos, or apps that will not let you highlight anything — you drag a box around the area and Awnsy reads the screen itself. Its stated goal is to be everything a translator should do on a Mac, with the translation model living inside the app and running on your machine, so what you translate stays with you. Why a dedicated Mac translator? The everyday friction of reading something in another language is rarely the translation itself — it is everything around it. Copying text out of one app, pasting it into a browser, waiting for a cloud round trip, and then matching the result back to what you were reading all break the flow. Worse, much of the foreign text Mac users meet is not selectable at all: it is baked into a screenshot, a scanned PDF, a video frame, or an interface that simply refuses to be highlighted. Awnsy is built around the idea that translation should happen where the text already is, with no account to create, no API key to manage, and no telemetry. The product is positioned as a small app with serious reach: everything a translator should do on a Mac, plus a couple of things that require reading the screen rather than the clipboard. One keystroke, any language. Double-pressing ⌘C is the entire interface — or you can assign your own hotkey instead. As soon as it is triggered, the translation streams in live rather than appearing only after the whole request is finished, and the result is shown over the window you are already looking at, so you never lose your place. Inside that window you can switch the target language or change which translation model is answering, without opening preferences, signing in, or restarting anything. Awnsy describes this as "one keystroke, any language" — the point being that translation should feel like a reflex on the Mac rather than a separate task you have to go and perform somewhere else. Reads the screen itself. Plenty of the text you want to translate cannot be selected: words inside images, frames of a video, scanned PDFs, or applications that do not allow text selection. For those cases Awnsy uses on-device text recognition — you drag a box around whatever is on screen, and the app pulls the words out of the picture before translating them. Because recognition happens on the device, the content being read is not sent anywhere for that step, which keeps the same privacy posture as the built-in translation model and means the feature keeps working even when the machine is offline. Private by default, and your models if you want them. The built-in translation model runs entirely on your Mac — offline, with no account, no API key, and no telemetry — so what you translate stays on your machine. If you would rather have cloud quality, you can bring your own OpenAI or Anthropic key instead; that key is stored in your Keychain rather than sitting in plain text somewhere in the app's files. The model switcher lives in the same translation window, so choosing between the on-device model and your own cloud provider is a toggle rather than a setup project. Native and featherlight is not just a slogan here: Awnsy is written in pure Swift rather than Electron, lives in the menu bar, and never clutters your Dock. That architecture is what makes the rest of the product possible — a lightweight, always-available companion that can be summoned with a keystroke from inside whatever you happen to be doing, rather than a heavyweight application you launch and manage. The overall approach is a single, narrow surface: trigger with your hotkey, get a streamed translation over the current window, switch language or model inline if you need to, and dismiss it. There is no dashboard, no project setup, and no dedicated translation screen to learn. The outcome is translation that costs almost nothing in attention. You do not leave the app you are reading, you do not copy and paste into a browser, and you do not need an account or a key to get started — the built-in model is there the first time you double-press ⌘C. Because that model runs on your Mac and works offline, results are available in situations where a cloud service would not be: no connection, a locked-down environment, or content you would simply rather not send to a third party. And because text recognition covers material you cannot select, the same gesture handles a paragraph, a screenshot, a scanned document page, or a line of on-screen text inside a video. Concretely, Awnsy fits the moments where foreign text appears in the middle of other work. Reading a foreign-language article, help thread, or documentation page in a browser or a document, you select the passage and double-press ⌘C, and the translation appears over the page. Reviewing a scanned PDF, you draw a box around a paragraph because there is no selectable text to copy. Watching a video whose on-screen text you cannot copy, you box the frame and read it in your language. Looking at a screenshot, a chart, or a third-party app whose text resists selection, the same box gesture works. And on a plane, on a locked-down network, or simply offline, the built-in model keeps working. Awnsy is built for Mac users — the Product Hunt listing files it under Mac, Productivity, and Artificial Intelligence — and particularly for people who encounter several languages during the day and would rather not context-switch to handle them. It runs on macOS and is distributed through the Mac App Store, where it is free to download; the paid Awnsy Pro tier unlocks unlimited screen translation. The app is written in pure Swift and integrates optionally with OpenAI and Anthropic as bring-your-own-key providers, keeping that key in the Keychain. No account is required for the on-device mode. The takeaway: Awnsy compresses Mac translation into a single gesture. Select text, double-press ⌘C, read the result where you are — or draw a box when the text is trapped in an image, a video, or an app that will not let you select it. Offline and private by default, cloud quality optional with your own key, and native enough to stay out of the way in the menu bar.
YABAI is a Japanese slang dictionary that gathers 308 real slang, internet, fandom and everyday words and gives each one a card built around giant Japanese typography. The site frames the project simply: やばい, 推し, 草, エモい — what they mean, how they sound, and who you can actually say them to. Every entry is treated as more than a translation lookup. Each word carries a meaning, an original example sentence, a vibe check that signals whether it is safe to use, friends only or something to be careful with, a culture note where there is something worth knowing, and a short story about where the word came from and who says it now. The result is a reference that answers the two questions a plain dictionary leaves open: how does this word actually sound in use, and can I say it? The 308 words can be read on the website, browsed alphabetically or by category, or carried in the Android app, which the site describes as putting all of them in your pocket. The gap YABAI is built to fill is the one left by formal language study. Textbooks teach Japanese that stops at the classroom door, and YABAI presents itself as the other half — the slang, internet, fandom and everyday vocabulary that lives outside a syllabus. Words like 草, described as 'lol, literally grass', or 推し or タイパ rarely come with the context a learner needs in order to use them without embarrassment: how casual is this, is it regional, is it tied to a particular subculture, is it something a visitor should avoid? A literal translation can be found almost anywhere, but a translation does not tell you whether a word is safe with a stranger, a colleague or only among friends. It also does not tell you the story, which is often the part that makes a word memorable. YABAI treats those missing layers — tone, social risk, cultural placement and origin — as the content, not as footnotes. The first of the five elements on every card is the meaning. Each word opens with one punchy line that captures its essence; やばい, for instance, is summed up as 'Amazing. Terrible. Insane.' — a deliberately informal line that mirrors how fluid the word is. That is followed by the full sense written in plain English, so a reader who wants precision is not left with a slogan. The second element is the example: an original Japanese sentence with a translation, showing the word at work rather than in isolation. The site is explicit that these sentences are never a quote and never a brand, which means the examples are written for the dictionary itself instead of being lifted from advertising or celebrity speech. For a learner, that distinction matters, because example sentences drawn from real but arbitrary sources can smuggle in formality levels or promotional tone that do not represent everyday use. The third element is the vibe check, and the site calls it out as the one thing dictionaries never give you. Each word is labelled Safe to use, Friends only, or Be careful, and is accompanied by tone hints such as self-deprecating, internet, or Kansai dialect. This is practical social information: it is the difference between a word a visitor can drop casually and one that will sound off, dated or too familiar in the wrong company. The fourth element is the culture note, which places the word in Japanese life — included when there is something worth knowing. Together, the vibe badge and the culture note turn a definition into a kind of usage briefing, so the reader learns not only what a word means but where it sits and who tends to say it. For anyone who has learned a word from a subtitle and then hesitated to use it, this is the layer that resolves the hesitation. The fifth element is the story: a short read on where the word came from and who says it now. The site takes an unusually honest stance here, stating that when an origin is genuinely disputed, the card says so instead of picking one version. In a space where slang etymologies are frequently repeated with false confidence online, admitting uncertainty is itself a feature — it tells readers which explanations are settled and which are guesses. All five elements are presented on cards designed to be looked at rather than merely consulted, with the headword set in giant Japanese typography alongside its romaji, its meaning, its example sentence and its vibe badge. The site's own phrasing for this is that each word is not a dictionary entry but a card you want to look at, reflecting a design choice to make browsing pleasant and screenshot-friendly rather than austere. A sample card shows やばい in large type with its romaji, meaning, example and vibe badge together. Structurally, the content is organized in two ways. Readers can browse all 308 words as an A–Z list, or move through the eight categories that describe where you hear each word: Slang with 72 entries, Internet with 58, Otaku with 46, Everyday with 44, Untranslatable with 30, Reactions with 26, Cute with 24, and Anime-ish with 8. The homepage introduces the collection with eight starter words, one from each category — やばい, 推し, 草, エモい, それな, もふもふ, タイパ and ツンデレ — each shown with a short gloss and a category tag. The app itself is designed for low-commitment use: the dictionary ships inside the app in 13 languages, works offline, and every word can be read aloud by your device. The site states that nothing you collect leaves your phone. There are no streaks, no tests, no levels and no guilt; the experience is described as a Japanese culture snack — open it for a minute, meet one word, close it. The site also hosts short video content, including a thirty-second explanation of やばい, and notes that there are more videos on the yabai page and on seven other word pages. The benefits follow directly from that structure. A learner gets the meaning quickly, then gets the surrounding context that makes the word usable: an example to model, a vibe badge to judge risk, a culture note to understand placement, and a story to remember it by. Because the origins of disputed words are labelled as disputed, readers are not handed confident misinformation. Because the dictionary ships offline in 13 languages and can read words aloud, it works without a signal and supports pronunciation and listening as well as reading. Because there are no streaks, tests or levels, there is no backlog to feel guilty about — the dictionary can be used in the small gaps of a day. And because it is a paid app with no ads, no sign-up and no subscription, the experience stays uninterrupted by advertising or account prompts, with nothing collected leaving the phone. Concretely, the dictionary fits several kinds of sessions. Someone who has just heard やばい in an anime or a video can look it up, read the one-line meaning, then check the vibe badge before deciding whether to try it with a Japanese friend. A fan of anime or otaku culture running into 推し or ツンデレ can browse the Otaku or Anime-ish category and find the term with its example and story attached. A reader curious about concepts that resist direct translation can explore the Untranslatable set of 30 words, such as エモい, described on the site as beautiful in a way that aches. An internet user puzzled by 草 can go straight to the Internet category, which holds 58 entries. Someone with a spare minute can open the app for a single card rather than a study session. Someone offline — on a flight, underground, or without data — still has the full dictionary available, and can have the device read a word aloud. And someone who prefers listening can start with the short videos, such as the thirty-second piece on how one Japanese word means both 'Amazing!' and 'Oh no'. The obvious audience is people learning Japanese who have moved past the beginner material and want the vocabulary that textbooks leave out, along with anyone who consumes Japanese media, anime, fandom or internet content and wants to understand what people are actually saying. It suits readers who care about appropriateness as much as definition, and who like the story and culture behind a word rather than only its translation. The app is available as a paid Android download on Google Play, with the website serving the full word list for reading in a browser; the site notes it is a paid app with no ads, no sign-up and no subscription. The project was built end to end with AI agents in Claude Code, according to its Product Hunt description, and it is published under the YABAI name with 'yabai' as its site and product slug. Its listed topics are Android, Education and Languages. Taken as a whole, YABAI's value proposition is context. It takes 308 Japanese slang, internet, fandom and everyday words and wraps each one in the meaning, example, vibe check, culture note and story that a plain translation omits — and it says so honestly when an origin is disputed. Read on the web or carried offline in the Android app across 13 languages, with read-aloud support and no streaks, tests or ads, it is a dictionary built for a minute at a time that still tells you exactly who you can say each word to.

The 101 Plays Itself is a live musical instrument made from a public traffic camera. The page plays a Caltrans camera on the US-101 in Studio City, Los Angeles, and turns that real traffic into music in the browser: every car that crosses a line on the road surface plays a note, and the music is being made as the cars go past. It needs nothing more than a browser with the sound turned up, and it is aimed at anyone who wants to hear a freeway playing itself — listeners, music fans, and people curious about what five lanes of LA highway sound like when they are treated as a score. The project takes something ordinary — a public Caltrans traffic camera — and treats it as an instrument rather than a feed. Nothing on the page is pre-recorded: the timestamp burned into the top of the picture is the real one, and if you come back at three in the morning you will hear an almost empty freeway. That contrast between a busy freeway and a nearly silent one at night is central to the piece, and the page states it plainly. The work has been called "a musical instrument" by kottke.org, featured by NBC4 Los Angeles on The News Zone, and covered by The Drive, which described it as "strangely beautiful" — a browser turning five lanes into a musical staff, with real highway traffic and a public camera providing the score. Three cameras are available to play. The page lists the US-101 Southbound at Moorpark St in Studio City, the US-101 Northbound at SR-170 / Tujunga in North Hollywood, and the US-101 Northbound at Balboa Blvd in Encino. A map shows every camera the page can play, with the lit pin marking the one you are listening to and other pins available to tap and switch. The map is built with Leaflet and OpenStreetMap tiles. The video comes from Caltrans CAM 618, a public traffic camera used under the department's conditions of use, with detection and synthesis running entirely in the browser. If the page reports Cameras Down — Caltrans' whole video network unreachable, not just this camera — it offers an alternative: tap to play a recording, three real minutes of the same freeway. Sixteen voices make up the instrument palette, and you can tap any pad and stack as many as you like; by default two play together. Each voice has its own described character: Theremin (gliding, breathing), Glass (inharmonic bells), Rhodes (warm electric piano), Strings (bowed, slow, swelling), Choir (vowels, distant), Flute (breath and air), Vibraphone (metallic, trembling), Handpan (warm steel, hollow), Gamelan (beating bronze), Harp (plucked, ringing), Music Box (tiny, brittle, sweet), Marimba (woody, struck), Kalimba (thumb piano, round), Organ (cathedral drawbars), Sub Bass (felt more than heard), and a Drum Kit where the lanes become the kit. This palette is what turns a single stream of passing vehicles into a layered, deliberately tonal piece of music rather than a series of beeps, and the ability to stack voices lets the same traffic be heard in completely different moods. The musical timing comes from ten sampling patches laid onto the road surface, two in each of the five lanes. They are not rectangles: each one is a slice of its own lane, leaning and narrowing with distance exactly as the lane does. The browser reads those patches fifteen times a second and watches for the road to stop looking like the road — that is a car, and that is a note. A vehicle trips one patch and then the other, and the gap between them gives its speed, forming a real speed trap 13.4 metres long. How long the vehicle covers a patch gives its length, which is how the page tells a truck from a car and hands it a different voice. A readout on the page tracks notes played, the speed of a vehicle passing, notes per minute, trucks, the five lanes, and how long you have been listening. The approach is unusual because everything happens inside the browser. Detection and synthesis run entirely in this browser — no server, no samples, no recordings — so the music you hear is generated from the live picture at the moment you hear it. Lane geometry was solved offline from an earlier recording of this same camera, which is how the patches line up correctly with the road surface. The page also surfaces live conditions such as the number of lanes, the speed trap length in metres, night and tail lights, and the sun angle, so you can see what state the freeway is in while you listen. The benefit is a piece of music that is never the same twice, because it is being composed by whatever traffic happens to be crossing the camera at that moment. Because the source is a public camera and the timestamp is real, the sound you hear corresponds exactly to conditions on the road right now — busy during the day, near-silent in the small hours. You do not need to install anything or operate a synthesiser; you open the page, turn your sound up, and start listening. Switching cameras changes both the view and the musical material, and stacking voices changes the instrumentation without changing the traffic that is driving it. Concrete uses follow directly from this. You can open the page and listen live to the southbound 101 at Moorpark St, or switch the map pin to the northbound camera at SR-170 / Tujunga or Balboa Blvd for a different stretch of freeway. You can return at three in the morning deliberately to hear how sparse the traffic becomes and how that changes the music. When the Caltrans network is down, you can play the recording of three real minutes of the same freeway instead of listening live. You can tap into the instrument pads and stack voices to hear the same traffic rendered as Theremin and Glass, or as Sub Bass and Drum Kit, and you can watch the on-page readout to follow the speed of a vehicle, the note count, and how many trucks have passed. Target users are anyone with a browser and speakers: casual listeners, music and sound enthusiasts, and people interested in the freeway as a subject. The page runs on the web in the browser, and its technical building blocks as described are Leaflet with OpenStreetMap tiles for the camera map, a public Caltrans video feed (CAM 618) as the live source, and in-browser detection and synthesis with no server, samples, or recordings. Lane geometry was solved offline from an earlier recording of the same camera. No pricing information is stated in the material provided. In short, The 101 Plays Itself turns five lanes of LA highway into an instrument: a live Caltrans camera, real cars passing in this minute, and a browser that reads the road and plays a note for every vehicle that crosses it. The value is the live, generative performance — traffic you can watch and hear at the same time, composed in the browser as you listen.
Soar90™ is a personal, self-guided 30-60-90 day onboarding plan for anyone starting a new job or stepping into a newly promoted role. It gives new hires a phase-by-phase roadmap of what to focus on each day, a simple Win Log for capturing accomplishments and praise while they are fresh, and a Review-Ready Report generated from that real progress. You choose a career track tailored to your role, set up your plan in under two minutes, and follow one clear task a day from pre-start through day 90. Soar90 works as a complete standalone plan or alongside whatever onboarding your employer already has in place. New hires and newly promoted professionals usually receive systems training, a laptop, and a first-week schedule. What they rarely receive is a plan for their own success: a clear answer to what to focus on this week, and a record of the impact they build along the way. Soar90 began with a pattern its founder kept seeing as a recruiter and HR professional: talented people start strong, work hard, and then show up to their first review with nothing to show for it. Not because they lacked impact, but because nobody ever taught them to keep the receipts. The first 90 days are too important to leave to chance, and starting a new job brings pressure to prove yourself, the overwhelm of everything new, and the worry of whether you are doing enough. Soar90 exists to turn that lesson into a simple daily habit: a task a day, a win logged in seconds, and a report ready when you need it. The core of Soar90 is a structured 30-60-90 day roadmap built around phase-specific tasks, mantras, and reflection prompts that guide you from learning the ropes to leading the charge. The journey is divided into four phases. Pre-Start helps you prepare before day one with pre-onboarding tasks that set you up to show up confident and prepared. Days 1-30, Learn, Listen & Orient, focuses on mapping the culture, building relationships, and understanding expectations, listening more than you talk. Days 31-60, Contribute & Connect, is about owning your first project, setting boundaries, and deepening relationships with your core collaborators. Days 61-90, Lead & Grow, asks you to deliver your quick win, build a roadmap, and proactively request your 90-day review. The app keeps that roadmap actionable by surfacing one clear task a day. The dashboard shows Today's Focus, your current day and phase, how many tasks are left in the phase, and overall phase progress. Milestone tracking and celebrations let you check off tasks, hit milestones, and receive visual celebrations that keep your momentum alive. Plan setup is tuned to your role and start date and takes under two minutes: you select a career track tailored to your specific role and enter your start date, and Soar90 places you in the right phase. If you have already started your new job, you can enter your actual start date and go back to complete tasks from earlier phases. The Win Log is where you capture accomplishments, recognition, praise, and shout-outs in seconds while they are fresh, so your record builds itself. Shout-Outs specifically capture the praise and recognition you receive along the way, including details such as who gave it, their role, the context, and whether it was public praise, written feedback, or a direct message. When your next review arrives, you have a complete record of the impact others see in you instead of scrambling to remember what you did months ago. The design is deliberate: log your impact, not internal secrets. The Review-Ready Report is generated from the tasks you completed and the wins you logged. One tap turns your real progress into a first-person summary you can share with your manager, and it can be printed or saved as a PDF. The report includes an executive summary of your onboarding journey, key accomplishments organized by phase, standout highlights and wins, documented wins from your Win Log, personal reflections and learnings, and forward-looking goals for your next quarter. AI is optional throughout: you can let it draft the report, or write it yourself in your own words. Support features keep you on track between tasks. Weekly Check-Ins and Guidance give you a 60-second pulse check with tailored scripts and boundary templates when you need support. Daily email reminders send personalized nudges with phase tips and motivational quotes. Beyond day 90, your Win Log and Review-Ready Report remain available forever, and you can keep logging wins, generating reports, and using the roadmap for promotions, role changes, and annual reviews. Soar90's approach is deliberately personal and standalone. Rather than explaining a specific company's systems and processes, it helps you organize your personal progress and preserve proof of your impact. It was created by a recruiter together with practicing HR and talent-acquisition managers, and it is designed to be used as your complete 90-day plan or alongside whatever your employer has in place. The methodology is a daily habit loop: follow the roadmap, log your wins as they happen, and generate a report from that real progress when you need it. Your plan, wins, and reflections are private to you, and your manager or employer cannot see your notes. The outcome Soar90 promises is that after 90 days you know exactly what you did, you can name the difference it made, and your Review-Ready Report says it in your own words. Rather than wondering whether you are on track, you have clear priorities, gentle reminders, and a way to capture every win so you never have to wonder if you are on track. Users describe feeling focused, confident, and organized from day one, and one hiring manager reported being impressed enough to gift the app to new hires. The product also points to external research: only 12% of employees strongly agree their company does a great job of onboarding them according to Gallup, while strong onboarding improves new-hire retention by 82% and productivity by over 70% according to Brandon Hall Group. Soar90 fits anyone starting fresh: a new job at a new company, an internal promotion, a role change, or a return from a career break. Because the plan adapts to your situation with tailored tasks for each scenario, the same app supports a first-time new hire and a newly promoted professional. It is also positioned as a gift from a recruiter or employer, and a hiring manager who tried it said they will gift it to new hires from now on. Users bring the Review-Ready Report to a performance review, use the Win Log to prepare for annual reviews, and keep the roadmap going for promotions and role changes well beyond the first 90 days. Soar90 is built for anyone starting a new role, and it is developed by recruiters, HR, and leadership professionals. It is available on the web, iPhone, iPad, and Android, and one purchase covers every device, with your plan, win log, and reports following you across them. On the web it is a one-time $9 purchase with lifetime access and a 7-day money-back guarantee, with checkout on the Soar90 site. On iPhone and iPad you purchase in the App Store app using your Apple account, and on Android in the Google Play store using your Google account; in-app pricing is set by Apple and Google and may differ from the web price. There is no subscription, no recurring charges, and no cancellation needed. A free demo is available with no signup and no credit card required, letting you preview the dashboard, browse sample tasks across all three phases, and experience a milestone celebration. Ultimately, Soar90 reinforces one simple promise: start with a 90-day plan, always know what to do next, and show up to your review with receipts. It combines a structured 30-60-90 day roadmap, a fast Win Log, and a first-person Review-Ready Report into a single personal platform that costs $9 once and lasts a lifetime. You got the job, and Soar90 is designed to help you make your first 90 days count while the record of your impact builds itself.

Creads is a marketing platform built around a team of AI agents that already knows your brand. It connects to your social and advertising accounts, then creates content, publishes it and launches ads on your behalf. The website describes the setup as taking about five minutes from a link: it reads your site, you pick your employees and connect your accounts, and then it runs. Creads positions itself as a full marketing team that runs itself, with chat and agents that hold real roles and handle ads, organic content and research on autopilot. It covers paid campaigns on Meta Ads and Google Ads and organic posting to Instagram, TikTok, LinkedIn, YouTube, X, Pinterest, Threads, Reddit and Google Business, and it reports back on how that content performs. The problem it addresses is the gap between having a product and having a marketing team. Founders, small brands and agencies often have a website and a set of social accounts but nobody whose only job is to write the ads, shoot the product imagery, cut the video, schedule the posts and read the numbers afterwards. The site frames the alternative bluntly: every other AI tool starts from zero, while Creads runs the whole loop of creating, publishing and reading results, and keeps what it learns on the way round. Instead of generating a single asset and forgetting the context, it accumulates brand knowledge and performance data so each batch of work starts better informed than the last. The first step is Business DNA. You paste your URL and Creads reads the site to learn your brand. In the walkthrough shown on the site it identifies brand colours, the typeface (Space Grotesk in the example), tone of voice (described as Direct and Gen-Z) and a product count of 12 products found, building a Business DNA that every employee works from. The FAQ explains the same mechanism: it reads the site for palette, fonts, tone of voice and your product catalogue. Corrections matter here, because if you fix something in chat the correction sticks, so the brand model gets sharper the more you use it. A dedicated Brand DNA and Memory area sits inside the workspace alongside chats and your asset library. The second step is hiring your team. Creads presents its AI agents as employees with one job each rather than one general-purpose assistant. The roster shown on the site includes Il Direttore as Orchestrator, Marco on Ads, Gaia on Social, Elena on Intelligence, Luca on Copy and Sofia on Video. You hire only the ones you need. The FAQ is explicit that each keeps its own memory, so the agent running your ads is not starting from zero every week. Because the roles are separated across paid, organic, analytics, copy and video, work can be routed to the right specialist while the orchestrator coordinates the rest. Connections come next. You link your accounts once and the platform publishes and launches by itself. The site lists Instagram, TikTok, Meta Ads with multiple ad accounts, LinkedIn, Google Ads, YouTube, X, Pinterest, Threads, Reddit, Google Business and Shopify among the connected or connectable destinations. The FAQ confirms that it schedules to Instagram, TikTok, LinkedIn, YouTube and the rest, and takes campaigns live on Meta and Google Ads. Everything lands on a calendar before it goes out, so you can cancel anything you do not want. The Scheduled view shows posts marked as published or scheduled with their times and account handles. Once set up, the core workflow is described in four steps. First, ask and it creates: you tell it what you want in plain words, with no prompts and no brief, and it shoots the photos, writes the script and edits the UGC video in your brand voice. The site shows a request as simple as Shoot my new drop producing four generated product shots, with the agent explaining that it pulled the brand palette and tone, leaned into close-ups because the last drop performed best there, kept the logo as the hero element in every frame and skipped a studio-white look that had been rejected previously. Second, it publishes itself: Marco launches the ads and Gaia schedules the posts straight to Meta, TikTok and every platform you connect. Third, it learns and reports back: performance flows back into the brand brain so every next batch is sharper than the last. Fourth, it runs itself daily: you save the flow as an automation and the entire loop repeats on its own. The content the platform produces is organised into named formats. These include UGC SAAS, described as creator-style video that sells software with a real face pitching your product; Product Reveal, short-form drops cut for the feed with captions and all; Instant Ad, a finished ad built from a product link with script, shoot and edit in one go; Static Ad, a headline, product line-up and call to action laid out and ready to run; UGC Unboxing, AI-generated unboxing videos that feel authentic and drive conversions; Styled Flat Lay, the product laid out with props and shot from above for the grid; and UGC Ad, creator-style content that blends into social feeds naturally. Each format targets a specific job, and the library lets the same brand brain feed several output types at once. Automations are the mechanism that turns creation into a repeating process. The Automations screen shows examples including Best-performer recap, Daily UGC reveal ad, Meta CPC guardrail running every 15 minutes, Weekly carousel drafts, Midnight reflection and Competitor scan, each with a schedule and a status such as running, auto or paused. Two modes are available per automation: ask-first, where the agent prepares the work and waits for your yes, or autopilot, where it ships and tells you afterwards. Reporting sits alongside this in a Social Insights view that tracks reach, impressions, engagements and video views for the current period against the previous one, so you can judge whether content is performing better than last time. Creads publishes headline results as averages across accounts running it on autopilot, measured against their own 60 days before: 41 percent lower cost per acquisition in the first 60 days, 3.2x blended ROAS across the accounts it runs, and 8x more creative shipped every month. It notes that individual results vary. The site also shows a conversions-by-creative breakdown and a results panel inside the chat workspace where figures such as ROAS and reach appear next to the scheduled asset. Concrete usage stories on the site include a DTC skincare founder, Luca R., who launched his first ads without ever having run one: he pasted his domain and went to bed, and Marco read the brand, wrote four creatives, launched at 40 euros a day and paused the two that never got going. Other named examples are Sara M., head of content at a fashion label, and Andrea C., founder of a creative agency. The site summarises these as three teams and three jobs they had nobody for, with the same brand brain behind all of them. Creads is positioned for founders, small brands, content leads and agencies, and it is explicitly built for people running several brands: every brand gets its own employees, its own memory and its own voice, with nothing bleeding between them, and agencies read one morning summary per brand instead of logging into eight dashboards. On pricing, the site states there is a monthly plan with a credit allowance included, where generating, editing, publishing and launching all draw from the same balance. Top-up packs never expire and stay yours even if you cancel, and new accounts start with free credits so you can run the whole loop before paying anything. The Product Hunt listing mentions a free 3-day trial. The FAQ also confirms that no prompt writing or video editing skill is required: you talk to it like a teammate, asking for it to be funnier or to try a younger actor, and it redoes that piece while keeping the rest, with cuts, captions, music and export all handled for you. The takeaway Creads offers is simple: stop writing prompts and start making ads. The claim on the site is that competitors using AI video ads spend about 90 minutes while a Creads user spends five, because the platform carries the brand knowledge, the creative production, the publishing and the optimisation loop in one place and keeps improving them together.
SmartPause is a free, open-source macOS menu bar app that sends the play/pause media key to the app that is actually making sound on your Mac, rather than to whatever the system remembers as "Now Playing." It is built for Mac users who listen to audio from more than one place at once — someone watching a YouTube video in Brave while Spotify sits paused, for example — and who simply want the play/pause key to do the obvious thing. The app lives in the menu bar, requires no account, and its stated purpose is direct: press play, and the right thing pauses. macOS routes media keys to its own idea of "Now Playing," a piece of state that is often stale and sometimes points at nothing at all. The practical result is a familiar annoyance: you are watching a YouTube video, you press play/pause, the video keeps going, and Apple Music opens by itself. The key press is delivered to the remembered app instead of the audible one. SmartPause exists to close that gap so the media key behaves the way users intuitively expect, controlling the audio they are actually hearing in that moment rather than a remembered guess. On every press, SmartPause asks Core Audio which process is outputting sound right now, and then sends the command to that app. Because the decision is made at the moment of the key press and is based on real audio output rather than remembered state, Apple Music stays closed when it is not the app making noise. Nothing has to be pre-configured per app for this core behavior to work. If nothing is playing at all, the press falls back to the last thing you paused and resumes it, so the key remains useful instead of doing nothing. When two apps are playing at the same time, one key still handles it. A single press switches between them: the currently playing app pauses, the other one starts, and it moves to the top. A double press plays or pauses the selected app. A widget at the top right of the screen shows what just happened and what the next press will do, so the current state is visible rather than guessed at. SmartPause is deliberately small. It asks for one permission — Accessibility — which it needs in order to hear the media keys, and it does not request the microphone or screen recording. Audio detection uses Core Audio's public process list and runs only when you press a key, so the app costs nothing when idle. Apps that have no adapter get the key handed back to the system untouched, so the media key is never dead. The app is open source under the MIT license, written in Swift, with no analytics and no accounts, so users can read every line. Out of the box, SmartPause works with Spotify, Apple Music, VLC, Chrome, Brave and Safari, which covers the mix of browser and native playback that causes most media key confusion in the first place. The app is available in English and Turkish. Installation is a one-minute job. You can install it with a single Homebrew command — brew install --cask yasinozmeen/smartpause/smartpause — or download the zip from the GitHub releases page. The app requires macOS 14.2 or newer and runs on both Apple Silicon and Intel Macs. On first launch it asks for the Accessibility permission, and that is the whole setup. The benefit is the removal of a small but daily annoyance. Instead of the media key triggering a surprise launch of Apple Music or doing nothing at all, it acts on the audio you can hear. Because unsupported apps get the key handed back to the system, the key never becomes dead just because SmartPause does not recognize the app. Because detection only runs on a key press, there is no idle cost. And because there is no analytics and no account, using the app does not add tracking to a routine keyboard shortcut. Concretely, the workflows are the ones that break today. You are watching YouTube in Brave and press the key; the video pauses and Apple Music stays closed. A browser and Spotify are both playing; a single press switches between them and the widget shows what happened. Nothing is playing; the press resumes the last thing you paused. The app making sound has no adapter; the key is handed back to the system untouched. SmartPause is aimed at Mac users who listen across browsers and native players, and at users who prefer small, private, open-source utilities that need no account. It is free and staying free; the developer accepts coffee donations that go toward the Apple Developer ID so the app can be notarized. The app is menu bar only, with no windows to manage. In short, SmartPause fixes a specific, repeatable macOS annoyance by aiming the play/pause key at the process that is genuinely producing sound right now — free, open source, and small enough to forget about until the moment you press the key.
>> ALL_LOGS
Steam Frame is a wireless SteamOS headset from Valve that brings your Steam library into virtual reality. It is built for Steam users who want to play the games they already own on a wearable device: the headset streams your whole library from a PC, a Steam Deck, or a Steam Machine, and it also runs standalone titles on its own hardware. The store page describes it as "wireless, comfortable, lightweight VR for your Steam library" and sums up the promise with the line "your games in every dimension." Steam Frame is therefore both a streaming client for an existing Steam library and a standalone VR device within the Steam ecosystem. The context for Steam Frame is the Steam library itself and the question of where and how players can reach it. Steam Frame takes the games a player already owns and makes them available on a wireless headset, either by streaming them from a PC, a Deck, or a Machine, or by running standalone titles directly on the device. Because streaming is central to the experience, stability matters, and Steam Frame addresses this with dual radios and an included adapter. Because standalone play is also supported, the headset is not limited to a single host machine at all times. Together, these choices are presented as a way to give players flexibility in where and how they play their existing games. Wireless streaming is the first core capability. Steam Frame streams your whole Steam library from a PC, a Steam Deck, or a Steam Machine, so the games you already own can be played on the headset rather than only on the machine where they are installed. To keep that streaming stable, the headset uses dual radios and ships with a wireless adapter included, listed as Wi-Fi 6E. The headset itself lists Wi-Fi 7, 2x2, dual radios, and Bluetooth 5.4. The combination of dual radios plus an included adapter is presented as the mechanism that keeps wireless streaming stable, which is what makes untethered play practical rather than dependent on a single fragile connection. Steam Frame Controllers provide full 6-DOF and gamepad controls. According to the product description, the controllers work as VR wands and as a full gamepad, which means the same pair of controllers can cover motion-based VR interaction and conventional gamepad-style input. Tracking is handled by inside-out camera based tracking, which is listed among the headset's specifications; inside-out tracking uses cameras on the headset itself to determine position and movement. Because the controllers are described as offering both full 6-DOF control and full gamepad controls, a player does not need to switch hardware to move between VR-style play and gamepad-style play. The display and audio specifications round out the experience. Steam Frame has a 2160 x 2160 LCD per eye with a 72-144Hz refresh rate, and 144Hz is noted as experimental on the store page. That is a high resolution for each eye, paired with a refresh range that spans 72Hz up to 144Hz. Audio is delivered by dual speaker drivers per ear and a dual microphone array, so sound comes from the headset itself rather than from separate headphones, and the dual microphone array provides input for voice. The compute and platform details explain how the headset operates. The Steam Frame 256GB Kit is built on a 4 nm Snapdragon 8 Gen 3 platform with ARM64 architecture, paired with 16GB of unified LPDDR5X RAM and 256GB of UFS storage, plus a microSD card slot for expansion. Power comes from a rechargeable 21.6 Wh Li-ion battery. The headset runs SteamOS 3, the same software family used across Valve's hardware line, and Half-Life: Alyx is included with the system. Notably, the specification list states that a power supply is not included. Steam Frame's overall approach is to combine two ways of playing in one device. One mode streams a whole Steam library from a host device, whether that is a PC, a Steam Deck, or a Steam Machine, with dual radios and an included wireless adapter used to keep the stream stable. The other mode runs standalone titles on the headset's own Snapdragon-based hardware running SteamOS 3. This dual approach is the core methodology behind the product: players are not forced to choose between an untethered headset and access to their existing PC library, because the headset supports both streaming and standalone play. The controllers reinforce that same flexibility by acting as VR wands and as a full gamepad. The benefits follow directly from those design choices. Because streaming is wireless and stability is supported by dual radios and an included adapter, players can use Steam Frame without being tied to a host machine for connection. Because the headset also runs standalone titles, it remains usable when streaming from a PC, Deck, or Machine is not the goal. Because the controllers function as both VR wands and a full gamepad, and the product is described as being for VR and non-VR gaming, one device covers a broader range of play styles. And because a whole Steam library can be streamed to the headset, the games a player already owns become available in a new form factor rather than requiring a separate library. Concrete use cases follow the same pattern. A player with a large Steam library on their PC can stream that library to Steam Frame and play it in VR without relocating the games. A player who games on a Steam Deck can stream from the Deck to the headset and play wirelessly. A player with a Steam Machine can stream from that machine in the same way. When streaming from a host is not in use, the headset runs standalone titles on its own hardware. Because the controllers double as a full gamepad and the product is described as being for non-VR gaming as well, a player can also use the headset for conventional gamepad-style play. And for purchase, a buyer selects either the 256GB Kit or the 1TB Kit on the Steam store page and joins the waitlist to be notified if units become available. Steam Frame is aimed at Steam users and VR players who want to play the games they already own on a wireless headset. It suits players with a gaming PC, a Steam Deck, or a Steam Machine who want to stream their whole Steam library to a wearable device, as well as players who want standalone VR titles without depending on a host machine. It is listed on the Steam store under hardware alongside Steam Deck, Steam Controller, and Steam Machine, and it appears on Product Hunt under the topics Virtual Reality, Hardware, and Games. Two kits are listed: the 256GB Kit at $1,059 and the 1TB Kit at $1,299, with a waitlist for both. The included items are Steam Frame Controllers and Half-Life: Alyx, and the store page notes that a power supply is not included. In summary, Steam Frame's primary value proposition is access: it turns an existing Steam library into a wireless VR and non-VR experience, streaming from a PC, Deck, or Machine with dual radios and an included adapter for stability, while also running standalone titles on its own SteamOS 3 hardware. With controllers that serve as both VR wands and a full gamepad, it is positioned as a single wearable device for the games a Steam player already owns.

Bolt Forge is a new agent inside Bolt.new, the AI app builder, that runs on open-source AI models only. It launched on September 14, 2026 as a research preview and sits in the agent picker next to the Standard and Max agents that Bolt users already work with. Forge is an agent rather than a single model, so builders can switch into it, build with open models, and switch back to Standard or Max at any time. Its headline promise is scale of usage: every individual Pro plan includes up to 50X more Forge usage at no extra cost through October 14, 2026, with no daily caps. In exchange, builders who opt in share de-identified build sessions that help train new open models, starting with the U.S. open-model lab Arcee AI. Bolt Forge was created because price has decided who gets to build with AI at speed and scale. Builders arrive at Bolt with an idea and the skill to see it through, then ration prompts like fuel: every brainstorm, every rough draft, every dead end burns credits priced for polished work. The drafting phase of building, the part where you need room to wander, is exactly the part usage caps punish. Forge removes that penalty by making the allocation big enough to draft, test, tear down, and rebuild, so builders can test a big idea, play around with new concepts, and experiment as far outside the box as they want, while saving premium credits for the work that needs them. A second motivation is the models themselves: Bolt states that AI inference costs have dropped 280x in 18 months according to the Stanford HAI AI Index 2025, a collapse that makes an allocation this large possible, and open-source models improve when they see how real software gets built, which is the one thing you cannot scrape. Opted-in Forge sessions provide exactly that, with consent. Forge runs a lineup of open models that users can see and select. As of September 2026 that means GLM 5.3 Flash with GLM 5.3 alongside it, plus Kimi K3 and DeepSeek v4 Pro as experimental options. The lineup will evolve, and when a new open model drops, Forge is the first place in Bolt it lands. Two honest notes accompany the lineup: these models are experimental inside Bolt, so builders should duplicate their project before switching a serious build into Forge and keep complex production work in Standard or Max; and they do not all cost the same to run, because Kimi K3 and DeepSeek v4 Pro burn through usage faster than the GLM pair, so starting on the default and reaching for the heavier models when the work calls for it is the recommended approach. Forge also cannot take PDF uploads yet. Capability was tested before shipping: the Forge lineup ran through the Bolt Build Index, Bolt's own benchmark for how well a model completes real Bolt projects, and came out at 92.2 against 101.0 for the top paid model, Claude Opus 5, which is 91% of the top score. The Forge allocation is a headline part of the offer. Every individual Pro plan includes it at no extra cost through October 14, drawn from a single monthly bar that resets on the renewal date, with no daily limits and a hard stop at 100%. Every Pro tier gets the same allowance, and Forge usage is separate from Standard and Max usage. When the bar hits 100%, Bolt switches the builder back to Standard rather than charging an overage, so usage can be read at a glance with no daily math and no surprise pause mid-project. Bolt describes the allocation itself as the payment for the data builders choose to share, and says the amount is big enough to draft, test, tear down, and rebuild. Training in Forge is opt-in. A one-tap consent screen spells out the trade in plain language before a builder begins working in Forge. The shared data includes prompts, code, project files and configuration, the tool calls Bolt makes, and edit histories including the fix traces Bolt creates. Bolt strips and de-identifies secrets and personal information before anything leaves its infrastructure, and validates the pipeline against seeded test data. Switching back to Standard or Max stops Forge from collecting anything new, and builders can email privacy@stackblitz.com to ask Bolt to stop using Forge content it has already collected. Teams and Enterprise workspaces are excluded from Forge and from AI training and dataset licensing, and sessions from the EEA, the UK, and Switzerland are not used for training or datasets either, so builders in those regions get the Forge allocation without the trade. The training side starts with Arcee AI, the U.S. open-model lab behind the Apache 2.0-licensed Trinity model family; Bolt has partnered with Arcee to help train a trillion-parameter-class model, and sessions shared during the preview window from September 14 to October 14, 2026 feed the first training run, which begins in October. A data license agreement governs every transfer, StackBlitz may be paid for the datasets it licenses, and those datasets may go to other AI developers as well as Arcee. Forge works in five steps from start to finish. First, pick Forge in the agent picker, where it appears as a third agent next to Standard and Max on every individual Pro plan. Second, opt in with one tap after a consent screen spells out the trade. Third, build: Forge usage draws from one monthly bar with no daily limits and a hard stop at 100%. Fourth, Bolt de-identifies shared sessions before anything leaves its infrastructure, stripping secrets, sensitive data, and personal information as a rule and validating the pipeline against seeded test data. Fifth, the sessions go into datasets that Bolt licenses to AI developers under a data license agreement, with Arcee AI as the first. Underneath, two pieces of infrastructure make the economics work. Bolt runs Forge on its own reserved hardware instead of paying a provider per request, so a fixed, predictable cost means more of what you pay goes to building instead of markup. And Forge projects run in the browser on WebContainers, the technology StackBlitz built and Bolt runs on, so there is no server rented for every build, builds stay fast, and costs stay low. Benefits of Forge centre on removing the competition between experimentation and production work. Brainstorms, MVPs, and experiments stop competing with production work for premium credits. Users get 91% of the top paid model's Bolt Build Index score included with Pro at no extra cost. Usage is readable at a glance: one monthly bar, no daily limits, and a hard stop instead of an overage bill. And builders get a hand in what comes next, because their sessions teach open models how real software actually gets built. Bolt frames it simply: every Forge build does two jobs, it ships your thing and it teaches open models how real software gets built. Already on Pro, there is nothing to buy and no line to stand in. In practice, Forge is designed for the drafting phase of building. It is the place to test a big idea, play around with new concepts, and experiment far outside the box, with enough room to draft, test, tear down, and rebuild without rationing prompts. Because the allocation is separate from Standard and Max usage and has no daily limits, builders can run brainstorms, MVPs, and experiments in Forge while keeping premium credits for production work. Users who want to try the heavier experimental models such as Kimi K3 and DeepSeek v4 Pro can do so when the work calls for it, while starting on the default GLM pair for everyday building. Duplicating a project before switching a serious build into Forge is the recommended workflow, given that the models are experimental inside Bolt. Forge is aimed at individual Pro plan builders on Bolt.new: people who arrive with an idea and the skill to see it through, and who want room to experiment without burning premium credits. Teams and Enterprise workspaces are excluded from Forge, and from AI training and dataset licensing, and sessions from the EEA, the UK, and Switzerland are not used for training or datasets. Getting started on an individual Pro plan means opening the agent picker, choosing Bolt Forge, and taking the one-tap opt-in; Bolt says you are building on open models in under a minute. Builders who are not on Pro have two doors: join the Bolt Lite waitlist, where codes go out in waves and the first seats open by September 21, 2026, or skip the line with Pro at $25 a month billed yearly, which includes up to 50X Forge usage at no extra cost and no access code required. Bolt Lite is offered at $9 a month, and anyone on Bolt Lite when sign-ups close on October 14, 2026 keeps the plan. Bolt Forge is Bolt.new's experiment in making open-source models the everyday building surface. It trades up to 50X more usage, no daily caps, and a dedicated allocation for opt-in, de-identified build sessions that help train open models with Arcee AI. The trade-off against Bolt's top paid model is nine index points; the payoff is room to draft, test, tear down, and rebuild without rationing prompts, plus a hand in what comes next for open models.

Lumiko is a free Chrome screen recorder and browser-based video editor that turns ordinary screen captures into polished, cinematic recordings. It is built for anyone who needs to show a screen — creators, developers, marketers, designers, founders, educators, and freelancers producing demos or client work — and its core promise is simple: you record your screen, and Lumiko edits the footage while you work. The extension captures your screen together with system audio and microphone voiceover, tracks where your cursor moves and clicks, and then automatically builds smooth zoom and pan moves over those moments, so the finished video guides the viewer's attention without any manual keyframing. A built-in editor in the browser lets you trim, split, and reorder clips, add a webcam bubble, apply backgrounds and click effects, and export up to 4K, all without creating an account or uploading anything to a queue. Traditional screen recording workflows are slow and fiddly. Recording is the easy part; making the result watchable is not. Editors normally have to scrub through the timeline, place keyframes by hand to zoom into the parts that matter, mask out anything sensitive, and then wait for a render before the file is ready to share. Cloud-based recorders add another layer of friction: clips go to a server, upload queues build up, accounts are required, and privacy becomes a question. Lumiko addresses this by treating the cursor and the clicks as the editing signal. Because the recording itself carries the information about where attention was, Lumiko can automate the zoom and pan work that would otherwise be done by hand, and it can do all of the processing locally in the browser rather than in the cloud. Auto Zoom & Pan is the headline feature. Lumiko analyzes your cursor and your clicks as you record, then creates smooth, cinematic zoom and pan moves that follow them automatically — no manual keyframes and no timeline gymnastics. The result is a recording that stays on the part of the screen that matters, guiding viewer focus the way a human editor would. Paired with this are click effects: ripple, orb, or pressure animations triggered on every mouse click, which make interactions visible and obvious to someone watching the video. Together these two capabilities mean a plain screen capture reads as a directed piece of footage rather than a flat, unedited dump of a desktop, which is especially valuable for demo videos where the viewer needs to understand exactly what was clicked and in what order. Smart Blur handles privacy. Drawing a box hides sensitive information such as API keys, emails, passwords, and revenue dashboards, with the stated purpose of obscuring that data instantly and automatically. For developers recording a terminal, a dashboard, or a settings screen, this removes the risk of leaking credentials or customer data in a published video. The Webcam Overlay adds a personal element: a draggable, resizable circular face-cam frame with a premium drop-shadow that stays perfectly synced with your screen recording. Because it can be moved and resized, it can be placed wherever it does not cover the part of the screen being demonstrated, giving the recording a presenter presence without requiring a separate camera setup or external compositing software. The Instant Editor is a browser-based timeline that runs with zero render queue. You can split clips, delete mistakes, and drag to reorder segments, then export in 4K, 1080p, or 720p in one click. Basic trimming with the timeline scissors removes dead space immediately. Beautiful Backgrounds lets you frame the recording with a preset gradient, a solid color, a transparent backdrop, a high-resolution Unsplash image, or your own uploaded brand assets, including a company logo. Multiple Aspect Ratios means the same video can be exported in 16:9 for YouTube, 9:16 for Shorts and TikTok, or 1:1 for LinkedIn, using intelligent auto-framing so the composition holds up in each format. Rendering is hardware-accelerated and local, so exports happen on your machine rather than through a cloud render farm. Overall, Lumiko is a Chrome extension built on Manifest V3 that works as a single integrated tool: record, edit, and export without leaving the browser. During recording it captures the screen and, on the free tier, system audio and microphone voiceover together. Because it tracks the cursor and clicks, it can generate the zoom and pan choreography as part of the recording rather than after it, which is what removes the keyframing step entirely. Editing then happens in the browser-based timeline, and export is performed with hardware-accelerated local rendering. Lumiko requests only four permissions — activeTab, storage, desktopCapture, and scripting — and states that there is no tracking, that recording and export processing happen locally in your browser, and that recordings are never uploaded, viewed, or retained. The practical benefits follow from that design. Creators get cinematic-looking recordings without learning an editor or placing a single keyframe. Because there is no render queue and no upload step, the gap between finishing a recording and sharing it shrinks considerably. Privacy is protected by default: sensitive data is hidden with Smart Blur before it ever leaves the machine, and no account is required to start. The pricing model is equally direct — free forever for unlimited recording, auto-zoom, Smart Blur, custom backgrounds, and exports up to 1440p, with a one-time Pro upgrade for watermark-free 4K exports and a lifetime license covering up to three device activations. There are no subscriptions and no surprise recurring charges, so the cost of producing professional demo videos stays predictable. Concrete workflows include recording product demos and feature walkthroughs where the viewer needs to follow a specific sequence of clicks; producing software tutorials and technical walkthroughs; and capturing bug reports or step-by-step reproductions for teammates. Marketers and founders can repurpose a single recording across channels by exporting it in the correct aspect ratio for YouTube, Shorts, TikTok, or LinkedIn. Freelancers and agencies record client-facing work with custom brand backgrounds, their own logo, no watermark, and a webcam overlay to add a personal introduction. Anyone recording a terminal, admin panel, analytics dashboard, or configuration screen can use Smart Blur to hide API keys, emails, passwords, and revenue figures before publishing. Educators and course creators can record lessons with system audio and voiceover, trim the dead space, and export in HD for a learning platform. Lumiko is aimed at makers — the site signs off with "built for makers" — which in practice covers developers, designers, product teams, marketers, founders, freelancers, agencies, educators, and course creators who publish screen recordings regularly. It runs as a Chrome extension and can be launched from the Chrome Web Store or the browser editor page, so the ecosystem it integrates with is the Chrome browser itself. Backgrounds can draw on preset gradients, solid colors, transparent options, or high-resolution images from Unsplash, and custom uploads for brand assets. Pricing is straightforward: a Free tier at $0 forever with unlimited recording, auto-zoom engine, click effects, timeline editing, Smart Blur, webcam overlay, and exports up to 1440p; and a Pro tier listed at $29 lifetime, discounted to a $9 one-time payment, adding 4K Ultra-HD exports, removal of the "Made with Lumiko" watermark, and a lifetime license with up to three device activations. Lumiko's value proposition is contained in a single idea: the recording edits itself. By turning cursor movement and clicks into automatic zoom and pan, adding Smart Blur, a webcam overlay, backgrounds, aspect-ratio exports, and a local timeline editor, it compresses what used to be a multi-step editing project into a record-and-export workflow that runs entirely in Chrome — free to start, and $9 once to unlock 4K, watermark-free output.
BiBimba is a Mac clipboard manager that keeps clipboard history, screenshots, and the text inside copied images in one searchable place. It is aimed at Mac users who copy and screenshot constantly and then need to find something again later without remembering where it came from. Instead of relying on memory, you type a few words, choose the item you need, and paste it straight back into the app you were using. Beyond history, BiBimba reads text inside screenshots with OCR and, on compatible Macs, runs on-device AI that can translate, summarize, or rewrite selected text. The entire experience is designed to be driven from the keyboard. The problem BiBimba addresses is simple and familiar to anyone who works on a Mac all day. The system clipboard only holds the last thing you copied, so everything before that is gone the moment you copy something new. Screenshots add a second layer of friction: an image can contain a receipt total, an error message, or a table of values, yet that text is locked inside a picture and cannot be searched or reused. The result is a lot of hunting — scrolling through folders, opening old screenshots, or copying the same information twice. BiBimba's answer, as its tagline puts it, is clipboard history that can read your screenshots, so copied text and screenshots become searchable together rather than living in separate silos. Search is the core of the product. With ⌃⇧C you open your history, then type a few words to search Mac clipboard history, screenshots, text inside images, and snippets all at once. You move through the results with ⌃N and ⌃P, choose an item, and paste it back into the app you were using. Because OCR results are indexed alongside ordinary copied text, the interface can even label matching items by type — the site shows an example query such as "invoice" returning a result group marked "@ocr · 6 items." For quick reuse without opening the full window, ⌃⇧V lets you pick an item and paste it directly, and the paste menu offers a plain paste with ↩ alongside text actions with ⌃K. The design goal is stated plainly on the site: you do not need to remember where something was saved; you search, choose, and use it. OCR is what separates BiBimba from a conventional clipboard history tool. BiBimba automatically reads the text in screenshots and copied images with OCR, so a screenshot stops being a dead-end image and becomes searchable, copyable text. You can copy the specific text you need rather than retyping it, and if BiBimba detects a table in an image, it can turn that detected table into Markdown, JSON, or HTML. The site illustrates this with a receipt screenshot reading "Receipt total ¥12,400" — the kind of detail that is easy to capture in a screenshot and painful to recover later. Dedicated shortcuts support the workflow: ⌃⇧S takes a screenshot and ⌃⇧O runs screen OCR, and the history view explicitly points out that you can search text inside screenshots and copy the part you need. Once text is in front of you, BiBimba can act on it. Selected text can be translated, summarized, or rewritten, and the site lists the built-in actions with their keyboard shortcuts: Translate (⌃T), Summarize (⌃S), Business email (⌃M), Bullet list (⌃L), and Format a table (⌃R). There is also a Saved actions entry on ⌃K, so the instructions you use often can be run from the keyboard rather than retyped. These operations run from the keyboard, which means you never have to leave the app you are working in or break your flow to open another tool. The site notes that summaries, rewrites, and some other features require a supported setup with Apple Intelligence enabled, so the AI actions depend on the capabilities of the Mac you are using. Snippets give you a small library of reusable text — the site shows a saved snippet reading "Thanks for reaching out." — which you can reach with ⌃⇧B and find through the same search you use for clipboard and screenshot content. Privacy is handled by keeping everything local. Clipboard and screenshot history is stored on your Mac, not in the cloud. You choose how many items to keep and for how long, older items are removed automatically, and you can delete anything you no longer need at any time. The site also states there are no ads and no clipboard or feature-usage analytics, so what you copy and screenshot stays on your machine. BiBimba's overall approach is keyboard-first and local-first. Everything is reached through a small set of shortcuts rather than menus or browser tabs: ⌃⇧C to open history, ⌃⇧V to pick and paste, ⌃⇧B for snippets, ⌃⇧S for a screenshot, ⌃⇧O for screen OCR, and ⌃K for text actions. Copying, screenshots, and OCR output all feed the same searchable history, and the AI text actions run on-device on compatible Macs instead of sending your content to a remote service. When an action produces a result — a translation, a summary, a rewrite, or a table converted to Markdown, JSON, or HTML — you paste the result straight back into the app you were using. The workflow loops cleanly: capture, search, transform, paste. The benefit is time and recall. Because clipboard history and screenshot text are searchable together, something you copied an hour or a week ago is still findable by typing a few words, which removes the need to remember where it was saved or to copy it again. Extracting text from an image saves retyping and makes screenshots of receipts, error messages, and tables usable as data rather than as pictures. Converting a detected table into Markdown, JSON, or HTML means an image can flow straight into documentation or code. Running translate, summarize, and rewrite actions from the keyboard keeps you inside your current app, and keeping history on your Mac with automatic cleanup and no usage analytics keeps the whole thing low-maintenance and private. Concrete scenarios follow directly from how the product is described. A shopper screenshots a receipt and later searches for the total instead of scrolling through photos. A developer captures an error message in a screenshot, finds it again with OCR search, and copies just the part needed. A support or sales person keeps snippets like "Thanks for reaching out." ready for quick replies. Someone preparing documentation finds a table in a screenshot, extracts it, and outputs Markdown, JSON, or HTML. A user reading something in another language selects the text, runs Translate with ⌃T, and pastes the result where they need it. And anyone drafting correspondence can select text and run Business email (⌃M), Bullet list (⌃L), or Format a table (⌃R) without leaving the app they are working in. BiBimba runs on Apple silicon Macs with macOS 26 or later; summaries, rewrites, and some other features require a supported setup with Apple Intelligence enabled, and the site notes it cannot run on non-Apple-silicon devices. The interface is available in ten languages: Japanese, English, Simplified and Traditional Chinese, Korean, Spanish, French, German, Portuguese, and Arabic. Pricing is a one-time US$9 purchase covering 3 active Macs, with all 1.x updates included; buying again with the same email adds 3 more Macs. A 7-day free trial is available inside the app via ⌃T, with no email, card, or automatic billing required. Installation is a DMG download from the site, moving BiBimba to the Applications folder, with distribution through Apple notarization. Refunds can be requested through Link Support from the purchase receipt; requests made within 60 days of purchase are responded to based on the circumstances, without affecting local consumer rights. The takeaway is that BiBimba turns the clipboard from a one-slot memory into a searchable, local archive that also understands the text hidden inside images. For anyone who copies and screenshots constantly on a Mac, it offers a keyboard-driven way to find anything again, extract text with OCR, and translate, summarize, or rewrite it with on-device AI before pasting the result straight back into the work at hand.
Punch is an app built around a simple idea: it is where your group chat keeps its stuff. Instead of treating notes as a private, single-user document, Punch gives you a shared space where the things you and your people actually need — the Airbnb address, the door code, the rendezvous spot, an important note, a link, a photo, a video, or even that meme you cannot stop laughing at — live in one place. The app is described on its site as a place where you can save anything, summarized in three words: notes, quick, shared. It is aimed at friends, family, and crews who coordinate in group chats and keep losing the details they need. Its purpose is to make that information easy to save once and easy to find again, whether you are planning a trip, coordinating a meetup, or simply collecting ideas you want to keep. Group chats are wonderful at generating conversation and terrible at keeping information retrievable. The classic example on Punch's Product Hunt page is a vacation with friends: you need to know the Airbnb address, the door code, and the rendezvous spot, and instead of scrolling through one hundred or more messages to find them, you save that information on Punch and share it with your friends and family. The site frames the same frustration with two questions people keep asking in chats: 'Where are we meeting again?' and 'Where's that link you sent a few days ago?' Punch's product page explains why existing options fall short. The Notes app on your phone can fill up quickly, can start to look clunky after a while, does not let you share individual pieces from a note, and suffers from incompatibility between operating systems. Cloud storage services like Drive and Dropbox have the storage and shareability aspect, but they are more geared toward storage than toward the quick, conversational sharing a group chat actually needs. The first thing Punch does is let you save anything. The examples given on the site span the mundane and the fun: the Airbnb address, important notes, gift ideas for your mom, and even that meme you cannot stop laughing at. A screenshot of the app referenced on the site shows a Punch space containing notes, links, photos, and videos, which indicates that a saved item is not limited to plain text — the things you keep can carry the visual context of the moment. Because the emphasis is on speed, saving is meant to be quick: the tagline on the site summarizes the product as 'Notes. Quick. Shared.' The value of that flexibility is that you do not have to decide in advance what counts as worth keeping. A door code, a link to a reservation, a photo of a meeting spot, and a joke you want to remember all go into the same shared space, and they can all be found again without scrolling back through the conversation. Sharing is the second half of the product. Punch is described as letting you save your brilliant ideas and share them with your crew in a snap, and the site positions it as where your group chat keeps its stuff — which means the people in the chat can see the same saved information. Because the content you save is stored as individual notes rather than as one monolithic document, the sharing model avoids one of the specific complaints Punch raises about the phone's built-in Notes app: that you cannot share individual pieces from a note. Instead, a single saved item — one address, one link, one photo — can be the unit you put in front of your friends and family. The description also frames Punch as a creative vault, ready to unleash inspiration whenever you need it, which suggests the shared space doubles as a place to keep ideas rather than only logistics. Punch is available as a mobile app. The site links directly to the App Store, where it appears under the name 'Punch: Visual Shared Spaces,' and to Google Play under the package com.remedy.punch, so it runs on both iOS and Android — which addresses the cross-operating-system incompatibility Punch calls out as a weakness of the built-in Notes app. The product is published by Remedy Apps LLC. On Product Hunt, Punch is listed under the topics Android, iOS, Productivity, and iMessage Apps, indicating that the product is positioned as a productivity tool spread across both major mobile platforms and that an iMessage app is part of how it reaches users. Being mobile-first matters for the audience: the information Punch holds is the information you need while you are out in the world — at the rental, at the meeting point, at the store looking for a gift. The overall approach is to move important information out of the river of chat messages and into a shared space. Rather than searching, scrolling, and asking people to repeat themselves, you save the thing when you see it, and it stays in a place your group can return to. The site describes the result as a visual shared space: notes, links, photos, and videos sit together, which makes it easier to recognize what you are looking for at a glance. The naming choices in the product's metadata reinforce the same idea — Punch is tagged around notes, ideas, a creative vault, sharing ideas, collaboration, and note taking. In practice, Punch functions as a lightweight shared clipboard for a group: whatever the chat produces that is worth keeping gets punched into the vault, and the vault is what the group consults afterward. The benefit a user gets is the end of repetitive questions. The site lists the things you will no longer have to say in the group chat: 'Where are we meeting again?' and 'Where's that link you sent a few days ago?' Those two questions are the symptom Punch is designed to remove. Instead of scrolling through one hundred or more messages, you look in Punch. Because notes are quick and shared, the effort of saving is small and the payoff is that everybody in the group has the same answer. Because you can save anything, the tool covers the full range of what a group needs — logistics like addresses and door codes, references like links, and lighter material like memes and gift ideas. And because the saved material is visual, you get recognition instead of recall: you can spot the photo of the meeting spot rather than remember which message it was buried in. The most concrete use case given is a vacation with friends: you need the Airbnb address, the door code, and the rendezvous spot, and you save all of that on Punch and share it with your friends and family. The same pattern applies to any group trip or family holiday where details are agreed in chat and then need to be found again later. Another use case is link keeping: the site asks where the link someone sent a few days ago went, and Punch answers by giving links a permanent home in a shared space. Gift ideas are a third: saving ideas for your mom is the example given, turning a passing chat message into something you can come back to when it is time to buy. Sharing memes is a fourth: the meme you cannot stop laughing at is explicitly listed among the things you can save and share. More broadly, any group coordinating a meetup, a plan, or a collection of ideas is a candidate. Punch is aimed at people who coordinate through group chats: friends planning and taking trips together, families sharing logistics, and crews keeping track of links, ideas, and running jokes. It is a mobile product for iOS and Android, downloadable from the App Store and Google Play, and listed on Product Hunt under Android, iOS, Productivity, and iMessage Apps. The app is published by Remedy Apps LLC. Beyond the availability of the app itself, the provided information does not state pricing or subscription plans, so no pricing detail is claimed here. Punch's proposition is narrow and clear: it is where your group chat keeps its stuff. Save anything — an address, a door code, a note, a link, a photo, a video, a meme, a gift idea — and share it with your crew in a snap, so nobody has to scroll through a hundred messages or ask where the meeting is again. Notes. Quick. Shared.

Lull is a personalized meditation app that writes a guided meditation based on what you tell it. Instead of browsing a library of pre-recorded sessions, you speak your mind for a minute or so about what is actually going on, and Lull creates the rest. You then hear the meditation read in one of 11 voices, with Oura recovery able to shape the tone and Apple Watch heart-rate tracking recording how your body settled. The app is built for people who want a meditation made for this moment rather than a generic recording, and it is distributed as an iOS app through the App Store. Most meditation products work like a feed. You open the app, scroll through options, and try to find something that roughly matches your state. Lull's site frames the alternative directly with the line 'Instead of an endless feed, scroll inward.' The problem it addresses is fit. A session recorded months ago for a general audience cannot know that you are carrying the weight of a specific day, that you are wired late at night, or that you need to let go of something particular. Lull starts from your own words — 'Tell it how you feel. It creates the rest' — so the practice begins with your moment rather than with a catalogue. The site also sums it up as 'Your moment. Your way. Your peace,' and promises no searching and no scrolling. The primary capability is spoken input turned into a written meditation. The landing page instructs simply: 'Speak your mind.' You talk through what is going on — the example shown is a person saying they need to let go of today's stress and find some peace — and Lull writes a meditation for that moment. The site states that it takes roughly two minutes from thought to session, and that the result is 100% personalized guidance. With Premium, every session is generated fresh, described as created just now for you, and the number of unique meditations is represented as unlimited. Even the sample listed on the site reflects this: 'The Weight of the Ground' is described as a meditation for settling at the end of the day, and the app notes that with Premium every session is written fresh for you. Lull includes mood tracking built around the question 'How are you feeling today?' The app presents a calendar view so you can log how you feel and watch the pattern build across days and weeks. Three statements describe the experience: every session adapts to your mood, your moment, and your rhythm; the more you practice, the more it understands what you need; and you can watch yourself evolve over days, weeks, and months. This matters because a meditation that fits you today is partly a function of what you have been feeling lately, and the calendar gives that history a visible shape instead of leaving it as a vague impression. Mood tracking turns a one-off session into something closer to an ongoing practice. The audio experience is described in specific terms. Lull promises crystal-clear audio that draws you deeper into stillness, and spatial audio that wraps around you like a warm blanket — 'depth you can feel.' Playback is seamless from start to finish, with no jarring volume changes, just smooth and continuous stillness. You can layer your perfect atmosphere by mixing ambient sounds such as rain or waves with your meditation. You can also share what helps by sending a meditation to someone who needs it, since the app notes that stillness is contagious. Finally, you choose the voice: Lull offers 11 voices described as warm, gentle, and grounding, so you can find a guide that feels right for you. Lull's methodology is what separates it from playback-based meditation apps: Lull does not play recordings. You talk for a minute about what is actually going on, and it writes a meditation for that moment. Two health integrations shape that session. Oura recovery can shape the tone, and Apple Watch records your heart rate during the meditation. Afterwards Lull shows 'one honest number' — how far your heart settled below your own resting baseline — or it shows nothing at all. The app deliberately avoids gamification: there are no streaks and no scores, and the site states plainly that there is nothing here to keep alive and that you should come when you need to. One plan, a real 7-day trial, and cancellation two taps away in Apple's own settings reinforce the same low-pressure philosophy. The site frames meditation as more than stillness: it describes clarity, focus, and resilience as what regular practice unlocks. Three outcomes are named. New pathways: your brain rewires itself with every session, old patterns soften, and new possibilities emerge. Sharper focus: scatter fades, clarity rises, and you find the concentration that has been there all along. Quiet strength: life will push, you will bend rather than break, and you build the inner steadiness that carries you. The app's own description adds that Lull helps reduce stress, improve sleep, and find your ease. The Apple Watch settle measurement gives these benefits a personal reference point — your own resting baseline — rather than a shared score to chase. Concrete scenarios appear throughout the content. The featured meditation 'The Weight of the Ground' is written for settling at the end of the day, which maps to unwinding after work or before sleep. The example spoken prompt on the landing page describes needing to let go of today's stress and find some peace, a scenario for coping with accumulated daily pressure. The mood calendar supports a daily check-in habit: logging how you feel and then receiving a session adapted to that mood. Sharing a meditation supports sending support to a friend or family member who needs it. And Quick Sessions, which stay free and unlimited, cover the moments when you want something short without a subscription. Lull is built for iOS and distributed through the App Store, with Android listed as coming soon. Its stated health integrations are Apple Watch, which records heart rate and shows the settle after a session, and Oura, whose recovery data shapes the tone. Pricing is deliberately simple: one plan, described as 'the price is the price,' with a real 7-day trial, and cancellation available two taps away in Apple's own settings. The free tier is positioned as a practice rather than a preview — Quick Sessions stay free and unlimited for as long as you want them. A path for people already subscribed on the web is also referenced. Lull's core proposition is meditation that listens. By turning a minute of honest speech into a freshly written, spatially mixed session — optionally shaped by Oura recovery and measured by Apple Watch — it replaces the endless feed with something made for this moment, delivered in a voice you choose. No streaks, no scores, one honest number, and unlimited free Quick Sessions make the practice feel sustainable rather than gamified, which is exactly the point the product is making.

LucentraCode is an AI coding CLI built for developers who want powerful models without constantly worrying about usage limits or expensive subscriptions. It runs directly from the terminal, letting developers choose from models such as GPT-6 Astra, GPT-5.6 Sol, Claude, Gemini, Grok, Kimi and more, and apply them to real development work — debugging, building features, refactoring, testing, and working across larger codebases. The product frames itself with a simple promise: "code without the clock," a runtime designed to keep developers in flow state instead of making them pause for quota windows to reset. The problem LucentraCode targets is the stop-start rhythm of many AI coding subscriptions. Quota windows expire, sessions are interrupted mid-execution, and the most capable models are frequently locked behind $100–$200 per month tiers. The site positions the product directly against that model. It states its aim as building for flow state with "no 5-hour resets," and highlights that work should not be interrupted by session quota timers or mid-execution lockouts. For developers who work in long, uninterrupted stretches, that reset cycle is more than an inconvenience: it fragments concentration, breaks context, and pushes people toward either paying for a higher tier or switching tools midway through a task. LucentraCode's answer is to remove the countdown clocks from the equation and replace them with a single, predictable allowance. The first pillar of the product is its approach to session limits. LucentraCode advertises a session quota timer that is uncapped, with no 5-hour limit, and zero interruptions caused by mid-execution lockouts. The intended outcome is a continuous flow state that remains guaranteed active throughout long working sessions, so developers are not forced to stop and wait for a quota window to reset. The site presents this as an always-on capability rather than a best-effort behaviour, contrasting it with the countdown clocks that characterise many competing coding assistants. In practice that means a developer can start a refactor, a debugging session, or a feature build and carry it through to completion without watching a timer or breaking their working context to check remaining quota. Long sessions become a normal way to work rather than something to ration. Second, LucentraCode brings frontier models within reach on a much lower tier. The site states that premium models such as GPT-6 Astra are available without jumping straight to a $100–$200 tier, and it contrasts that competitor requirement with its own $20 per month plan that includes all models. The model line-up shown on the site includes GPT-6 Astra, Claude 3.7 Sonnet, Opus 5, GLM 5.3, and Fable 5.1. To make a single monthly allowance stretch further, the product uses Smart Auto, which picks the right model for the job: cheaper models handle search, tests, and routine work, while stronger models handle implementation, architecture, and review. That division of labour is the mechanism behind the allowance efficiency the site claims — 3x–5x more code shipped from the same pool of usage. Third, usage is organised around one simple monthly pool. LucentraCode eliminates rolling timers and windows entirely — the site counts them as zero, describing them as eliminated — and instead uses a single unified balance presented as an account meter. The stated benefit is usage freedom: developers spend their allowance when they actually need it, inside a single monthly allowance that the site says involves zero artificial lockouts. Rather than juggling multiple reset timers and separate meters for different models or workloads, the developer has one balance to monitor, which makes both planning and day-to-day work simpler. The design philosophy is that the meter should reflect real work done, not an artificial schedule imposed by the provider. Getting started follows a short, terminal-native workflow. LucentraCode is installed globally with a single command, `npm install -g lucentracode`, and is then launched by running `lucentracode`. It requires Node.js v20 or later. The runtime is available on Linux, Windows, and macOS, so the same command-line workflow carries across the major desktop operating systems. Once launched, the terminal is where model selection, routing, and real development work take place — the product is built to be used inside the environment where many developers already spend their day, rather than through a separate IDE plugin or web application. There is no separate application to keep open or context to switch into; the CLI is the product. The benefits LucentraCode promises are practical rather than abstract. Uninterrupted sessions support deeper focus and preserve context across long tasks. A single monthly pool removes the arithmetic of multiple reset windows and separate balances. Smart Auto routing means the most expensive reasoning is reserved for the work that genuinely needs it, so routine tasks never consume premium capacity unnecessarily. Access to frontier models at a $20 entry point lowers the cost of working with the strongest available models, and the site summarises the combined effect as shipping 3x–5x more code within the same allowance. For teams, that translates into fewer decisions forced by quota mechanics and more decisions driven by the task at hand. LucentraCode is described as a tool for real development work, and the listed scenarios span the full development loop. They include debugging, building features, refactoring, testing, and working across larger codebases. The Smart Auto routing maps naturally onto that spread of work: search, tests, and routine tasks are handled by fast, efficient models, while implementation, architecture, and review are handled by frontier reasoning models. A developer working in a large codebase can therefore use the runtime for exploratory search and routine test generation, escalate to stronger models when implementing a substantial feature or reviewing an architectural decision, and keep the entire workflow inside a single terminal session. Because there is no 5-hour reset in play, a long debugging investigation or a multi-hour feature build does not have to be paused and resumed around a quota window. LucentraCode is aimed at developers and serious builders — people who want frontier models for everyday coding work without premium-tier pricing. Pricing is organised into named runtimes. The Operator plan costs $20 per month and offers more than 5X the usage of the ordinary plan, with models including everything available in Ordinary, plus claude-opus-5, claude-opus-4.8, and gpt-6-astra. The Obsessed plan costs $40 per month, gives 2.5X more usage than the Operator plan, and includes everything in Operator plus claude-fable-5.1 and claude-fable-5. The Ordinary entry tier is available in India only, and international pricing is displayed in USD and INR. Full plan details are available through the LucentraCode dashboard. The site notes that the pricing shown is a preview and that availability and billing details will be announced at launch. Taken together, LucentraCode's proposition is straightforward: keep the terminal workflow developers already use, give them a broad set of frontier models through a single monthly allowance, and remove the countdown clocks that interrupt long sessions. Smart Auto routing makes that allowance go further by matching model strength to task difficulty, and a $20 entry point brings premium models within reach of individual developers rather than only teams that can justify a $100–$200 monthly tier. For developers who judge a coding assistant by how little it interrupts them, that combination — one pool, many models, and no reset timer — is the core value proposition.

Ruby UTCP is the Ruby implementation of UTCP — the Universal Tool Calling Protocol — an open standard that gives apps and AI agents a single, consistent way to discover and call tools over native protocols. It brings UTCP 1.1 to Ruby, so Ruby developers can define the tools their agents are able to use and then call them directly, whether those tools live behind HTTP APIs, command-line interfaces, WebSocket endpoints, gRPC services, GraphQL schemas or other transports. The library is open source, MIT licensed and free, and it is built specifically for the Ruby ecosystem. Its intended audience is Ruby developers creating AI agents and tool-powered applications who want a standard way to handle tool calling instead of writing a bespoke integration for every service they connect. Tool calling became a mainstream developer concern once large language models started being wired into real, day-to-day tools. MCP (Model Context Protocol) paved the way for that ease of use, but it typically relies on a heavier client/server architecture: for Ruby specifically, connecting to a tool usually means running a separate server process that sits between the model and the underlying API. UTCP was created as a lightweight alternative to that arrangement. Instead of routing every call through an intermediary, UTCP uses a simple JSON manifest to describe how a tool is reached, then connects to the native API directly. The project calls the overhead it removes the "wrapper tax", and eliminating that layer is what delivers lower latency. As the makers put it, allowing LLMs to call endpoints directly is much easier and more efficient to implement than a heavy client/server setup, and reviewers have noted that UTCP takes the idea further with better specification and security from the get-go. The most visible capability of Ruby UTCP is the breadth of connectivity it offers. It supports 12 transports, including HTTP, CLI, WebSocket, gRPC, GraphQL, MCP and WebRTC, all from one open-source library. In practice this means a Ruby application does not have to change its tool-calling approach depending on how a given tool is exposed: a REST endpoint, a local command-line tool, a realtime WebSocket service, a gRPC service or a GraphQL API can all be described and invoked through the same protocol. For developers this reduces the amount of per-tool code they have to write and keep consistent, and reviewers have specifically highlighted that supporting 12 transports in a single library is a lot of surface area to keep coherent. A WebRTC transport also extends the reach of tool calling beyond conventional request/response APIs. Alongside raw transport support, Ruby UTCP provides tool discovery, so applications and agents can determine which tools are available rather than hard-coding a static list of endpoints. It also supports OpenAPI discovery, which means services that already publish an OpenAPI description can be discovered and used as tools, letting teams expose existing APIs to agents without hand-authoring manifest entries for every operation. Authentication is supported as part of the protocol as well, addressing a common gap in tool-calling setups where credentials have to be handled ad hoc outside the tool definition. Together, discovery and authentication make it practical to point an agent at a real, secured production API rather than a prototype endpoint. Ruby UTCP also supports streaming, so tools that return results progressively rather than in a single response can be used within the same unified tool-calling model. On top of that sits CodeMode, a capability for orchestrating multi-tool workflows with compact Ruby code. Rather than describing long chains of individual tool invocations one at a time, CodeMode lets developers express programmable, multi-step workflows in Ruby itself. A related UTCP launch, Code Mode, was positioned around slashing MCP token usage by 68%, and another project with similar goals, UTCP Agent, focused on building tool-calling agents in four lines of code — both illustrating the direction of travel toward less boilerplate and more compact orchestration. The overall approach is manifest-based and direct. A single JSON manifest describes the tool and how to reach it, and the library then calls the native transport rather than standing up a wrapper server. UTCP version 1.0.0 introduced a lean core, protocol plugins and a cleaner configuration, with the stated goal of letting teams scale their tool usage without wrestling with glue code. Because the protocol is plug-in oriented, the transport layer is extensible rather than monolithic, which is how one library can cover HTTP, CLI, WebSocket, gRPC, GraphQL, MCP, WebRTC and the other supported transports while keeping a consistent interface for the developer. The benefits that follow from this design are the ones the project states directly: lower latency because there is no intermediary wrapper layer, a lighter integration because no separate server process has to be run and maintained for a simple connection, and less glue code as tool usage grows. For Ruby teams, that means adopting UTCP does not require introducing a new runtime component into their stack — the gem lives inside the application they are already building. The protocol is also an open standard published by the Universal Tool Calling Protocol project, so work invested in tool manifests and workflows is not locked into a single vendor, and the MIT licence keeps both the specification implementation and the Ruby library free to use. Concrete uses follow from the stated capabilities. Ruby developers building AI agents can connect those agents to existing native APIs through a JSON manifest instead of running a wrapper server. Teams that need to combine several tools in a sequence can use CodeMode to express the multi-tool workflow as compact Ruby code rather than long chains of individual calls. Services that already publish an OpenAPI description can be picked up through OpenAPI discovery and exposed to an agent without hand-written definitions. Applications that need realtime tools can reach WebSocket, WebRTC or streaming endpoints. Ruby projects that already depend on MCP servers can consume them through the MCP transport while using UTCP for everything else, which a reviewer suggested as a desirable outcome: implementing the UTCP standard alongside MCP. The wider UTCP ecosystem also points to enterprise scenarios — a project called Hexis uses UTCP behind the hood for tool calling as a layer on top of Git where a company's AI skills, tools and knowledge live, centrally managed, reviewed and access-controlled. In terms of audience, tech stack and cost, Ruby UTCP is aimed squarely at Ruby developers creating AI agents and tool-powered applications, and it is distributed as an open-source Ruby gem. Its documentation and repository are published by the Universal Tool Calling Protocol organisation, and the launch page lists it as free. The makers explicitly invited feedback on the API and CodeMode, and on which integrations should come next, signalling that the library is intended to grow with the Ruby ecosystem it targets. Reviewers have noted that the docs cover the transports well individually, while suggesting that a single decision guide for picking the right transport for a given use case would help newcomers evaluating UTCP against MCP. Ruby UTCP's core value proposition is straightforward: it gives Ruby developers and their AI agents one open, manifest-based standard for discovering and calling tools across many native protocols, removing the wrapper-server overhead that makes tool calling heavier and slower than it needs to be. With 12 transports, streaming, authentication, OpenAPI discovery and CodeMode for programmable multi-tool workflows, all packaged as a free, MIT-licensed gem, it offers the Ruby ecosystem a scalable and secure alternative to MCP for connecting agents to the tools they need.
One More Thing is a micro-learning platform built to replace doomscrolling with something worth knowing. Instead of endlessly scrolling through content you will forget, you choose a subject you actually want to learn and work through it one card at a time. Every topic becomes a bite-sized learning deck you can swipe through in minutes, spanning areas such as psychology, history, science, money, culture, languages, and weird facts. The product describes itself simply as a place to learn anything, one card at a time, and it positions itself as a way to turn any subject into cards you swipe in minutes, not hours. The problem One More Thing addresses is stated directly on its website: your curiosity is the last real currency, and it should not be traded for noise. Endless feeds are designed to hold attention without leaving anything behind, and time spent scrolling typically produces nothing that sticks. One More Thing reframes that same swipe gesture as a step toward a sharper mind rather than a step deeper into the algorithm. The pitch is that every swipe becomes progress, and that reclaiming your feed for learning is a way to reignite the wonder you had as a kid. The goal is a daily dose of "huh, I didn't know that" instead of content you will forget. At the heart of the product is the deck. A deck is a set of bite-sized cards on a single subject, designed to be completed in one to three minutes. Each card carries one idea, with no fluff and no binge, so a session stays short and finishable. In the product's own demonstration, a card titled "Table Basics" states that the periodic table has 118 confirmed elements, and a "Tell me more" action lets you go deeper when you want the reasoning behind the fact. Navigation is gesture-based: you swipe a card up to flip to the next one. The stated outcome of this format is mastery in minutes — one to three minute decks on any subject, with one idea per card. Retention is handled by pairing the cards with quick quizzes. The website states that bite-sized cards plus quick quizzes add up to 50× better retention than cramming. In the demonstration flow, after swiping through cards you tap to reveal the why, then quiz yourself, and the session is finished in minutes. The claim is not that the app teaches more in a single sitting, but that the short, repeated format with immediate self-testing makes what you read actually stick. That combination — small cards, an explanation on demand, and a quick check — is the mechanism the product points to when it says learning here actually sticks. One More Thing is also a creation tool, not only a consumption tool. Its "Create, don't just consume" principle is implemented through AI: you type a topic and the AI builds you a deck on anything you can imagine, in seconds. That means the catalogue is not limited to whatever was pre-built — any subject you are curious about can become a swipeable deck. The site frames this as the difference between browsing someone else's library and making the learning yours. Combined with the "any subject you can imagine" claim on the landing page, AI deck generation is what lets the product cover the full range of curiosity rather than a fixed curriculum. Progress is made visible through gamification. The Product Hunt description notes that users earn XP, build streaks, unlock badges, and discover something new every day. In the interface, a deck such as "Elements: Sorted!" displays an XP total of 240 XP, giving an immediate, tangible signal of what a completed session was worth. Streaks turn the habit into something you do not want to break, and badges mark milestones along the way. "Keep curiosity alive" is described as a daily dose of discovery, which is why the product frames itself as a habit to build rather than a course to finish. There is, as the tagline says, always one more thing. Users who would rather start from a curated list can browse decks instead of generating their own. The site shows a topic row including Alkali Metals, Noble Gases, Halogens, Transition Metals, Table Basics, and Alkaline Earth Metals, plus a "Browse all" entry point. Named decks visible on the landing page include Elements: Sorted!, Fashion Unraveled: Style Secrets, Area 51: Secrets & Skies, Guinness Records Gone Wild, Master of Puppets: Metallica Unleashed, Master Manga Art & Technique, Laws Gone Wild, California's Best Kept Secrets, and Sweep of the Blade Deep Dive. The range is deliberately broad — science, fashion, mysteries, music, art, law, travel, and martial arts — reflecting the "any subject" positioning of the product. The product also lets you make it yours. Three looks are offered — Elegant Light, Royal Blue, and Dark Brown — and you can switch between them anytime, right from your profile. It is a small feature, but it supports the idea that the app is a personal space for your own curiosity rather than a single fixed interface, and it lets users match the reading surface to their preference for a daily swipe session. Putting it together, the workflow is deliberately short. You pick a subject, either from the browse list or by typing one for the AI to turn into a deck. You swipe through cards, one idea at a time, tapping when you want the deeper "why" behind a fact. You quiz yourself to check that it stuck. You finish in one to three minutes, and you earn XP while a streak and badges keep track of the habit. Repeat daily, and the product's promise is knowledge that accumulates rather than content that disappears — the same downward swipe you already know, pointed at something you would actually like to know. The benefits the site claims follow directly from that loop. The first is retention: 50× better retention than cramming, achieved through bite-sized cards and quick quizzes. The second is time well spent, with sessions of one to three minutes instead of hours. The third is a sharper mind, because every swipe is described as a step toward one rather than a step into the algorithm. The fourth is sustained curiosity — the daily "huh, I didn't know that" moment that reignites childhood wonder. The fifth is depth as an advantage: the product's framing is that you walk into every room with one more idea than yesterday and become the one who knows one more thing. Concretely, One More Thing fits the moments where scrolling usually happens. A commute, a queue, a few minutes before bed — the one to three minute session length is designed for exactly those gaps, so a deck can be finished instead of abandoned. Curated decks support browsing by interest: someone curious about chemistry can work through Elements: Sorted! and its related topics, while someone drawn to oddities can pick Guinness Records Gone Wild, Area 51: Secrets & Skies, or Laws Gone Wild. Music and culture fans can use Master of Puppets: Metallica Unleashed or Fashion Unraveled: Style Secrets, and art learners can take Master Manga Art & Technique. When nothing in the library matches a sudden question, typing the topic and letting AI generate a deck turns that flash of curiosity into something to swipe through immediately. One More Thing is aimed at anyone whose curiosity is currently being spent on an infinite feed: people who want to learn but do not want to commit to a course, a lecture, or a long article. The topics listed — psychology, history, science, money, culture, languages, and weird facts — suggest a general audience of casual learners rather than specialists. It is free to start, with no credit card required, and the site states that signing in takes ten seconds. Pricing beyond that is not described on the page. One More Thing is a micro-learning platform with a single clear proposition: turn doomscrolling into something worth knowing. Bite-sized decks, one idea per card, quick quizzes, XP, streaks and badges turn a few spare minutes into a daily learning habit — and AI deck creation means the subject can be anything you are curious about. Scroll less, know more: there is always one more thing.
Mise is a meal planner from Robot Recipes that focuses on cooking a whole meal on a single timeline rather than one dish at a time. You pick a recipe to start with, build out the rest of the menu around it, and say when you want to eat. Mise then back-schedules every dish from that minute so the entire meal lands on the table hot at once. It is designed for home cooks assembling multi-dish meals — breakfasts, dinners and holiday spreads alike — and it runs in the browser, free of charge, with no login, no app and no ads in the way. Recipes are written to help you cook one dish. But meals have multiple dishes, and that is where timing gets hard. Each dish has its own cooking duration, its own oven or stovetop demands, and its own hands-on steps that need your attention at a specific moment. When you try to manage several of those at once — from separate recipe pages, tabs or a handwritten list — it is easy for two hands-on steps to collide, for the oven to be busy when the next dish is due, or for one dish to finish long before the rest. Mise is built for that orchestration problem: instead of simply collecting recipes, it works out the running order for the whole meal so the dishes come together at the same time. At the centre of Mise is a back-scheduled timeline. Once you set the time you want to eat, every dish in the plan is scheduled backwards from that minute. The plan distinguishes between hands-on work and hands-free time — oven, simmering and resting — so you can see at a glance when you actually need to be at the stove and when a dish is quietly taking care of itself. Mise also nudges dishes earlier where necessary so that two hands-on steps never collide, keeping your attention on one task at a time instead of forcing you to choose between two dishes that are both demanding you right now. Choosing the menu is only half of the work, so Mise also produces a merged shopping list. The list is combined across every dish in the plan and scaled to the number of servings you have set, so quantities reflect the meal as a whole rather than each recipe in isolation. You can tap items to check them off as you shop. Alongside the list, Mise shows the tools a meal depends on — what the timing relies on — so you know before you start whether the plan assumes an oven, a particular pan or another piece of equipment. When cooking starts, Mise switches into a live cooking mode. Instead of showing the whole plan at once, cooking mode displays only what you need to do right now, with an up-next view of what follows. It keeps the screen awake where the browser allows it and beeps when a step comes due, so you can leave a device open on the counter and get on with the work rather than watching a clock. Cooking mode needs no connection once the page has loaded. The plan can also be printed or saved as a PDF, and a copy link lets anyone with the link open the same plan — it is not listed anywhere. Robot Recipes describes the Mise workflow in four steps. First, you start from one recipe: search any recipe on Robot Recipes and that dish anchors the meal. Second, the robots fill in the menu: they suggest dishes that go with your anchor recipe and read each recipe's steps to work out how long each one takes and which parts need your hands. Third, you say when you want to eat: every dish is scheduled backwards from that minute, and dishes are nudged earlier so two hands-on steps never collide. Fourth, you cook from the timeline: cooking mode shows only what to do right now, keeps the screen awake and beeps when a step is due. That combination — a menu the robots assemble, read and reorder around your chosen eating time — is the core of Mise's approach. The benefit is a meal that arrives together rather than a sequence of dishes that half-finish at different times. Because the timeline is back-scheduled from the minute you want to eat, you are working towards a single deadline instead of improvising around several. The hands-on and hands-free split makes the plan realistic about your attention, and the collision-avoiding nudges mean you are rarely asked to be in two places at once. A merged, scaled shopping list removes the arithmetic of buying for multiple recipes, and a single running order replaces the mental juggling that normally comes with a multi-dish meal. Typical uses follow the way people actually cook multiple dishes. A weeknight dinner built around one main recipe, with a side or sauce added from the robots' suggestions, is the everyday case. Holiday cooking, such as Thanksgiving, is the high-stakes version: several dishes competing for one oven and one pair of hands, all of which need to land on the table at the same time. Breakfast or brunch is another, with the goal stated plainly on the page — getting breakfast on the table all at once. The plan also scales: set the number of servings and every dish and the shopping list scale with it, which matters when cooking for a household or a crowd. Mise is aimed at home cooks who are putting together meals with more than one dish and want the timing handled for them. It runs in the browser, so there is no app to install, and the robot recipe library behind it spans courses — main course, snack, appetizer, dessert, breakfast, side dish, lunch, dinner, soup, beverage, condiment, salad, vegetarian, seafood, brunch, sauce, bread, vegan, dip, charcuterie, sandwich and gluten-free — as well as cuisines from Indian and Vietnamese to Italian, Mexican, Japanese, Korean, French and many more. Mise itself is free, requires no login, and shows no ads in the way. Robot Recipes notes a disclaimer: meal plans and their timing are not created by humans, and cooking times vary with your oven, your cookware and your ingredients, so meat should always be checked to a safe temperature. For anyone who has ever stood in a kitchen with three dishes at different stages, Mise replaces the guesswork with a single schedule. One start time, one running order, one merged shopping list and a cooking mode that only ever tells you the next thing to do — built so a whole meal finishes hot at the same moment. It is free, needs no login, and holds the promise in its tagline: getting all your dishes ready at once.
NotchOwl is a Mac productivity workspace that turns the notch at the top of your screen into a place to work. It brings together tasks, a focus timer, quick notes, calendar events, and productivity insights so that everything you need to stay on track sits one hover away. Instead of moving between windows and separate apps, you open NotchOwl in the notch, add a task, start a focus session, jot down a note, or check today's upcoming events, then close it and get back to work. It is built for Mac users who want their next task and their captured ideas to stay close to whatever they are doing, and its tagline captures the idea simply: keep your day a notch closer. Most productivity tools live in their own window or browser tab, which means using them requires leaving the thing you are actually working on. NotchOwl is built around the opposite idea: less switching, more doing. The product's website frames the benefit directly, describing a workspace where everything you need to stay on track is available without switching windows. The problem it addresses is twofold. First, tasks and timers are easy to lose sight of when they sit in another app, so the work you planned gets interrupted by the mechanics of managing it. Second, a busy week can be hard to remember, making it difficult to see what you actually finished and where your attention went. By keeping the workspace in the notch and its timer visible while you work, NotchOwl keeps your intentions in view rather than filed away. The focus timer is the core of the task workflow. You pick a task and give it a time limit, or you let a stopwatch run when you do not need a deadline. The timer stays visible in the notch while you work, so you can see the remaining time without opening anything. You can pause, resume, or add five minutes when you need a little longer, which makes the timer flexible enough for work that does not end exactly on schedule. Two details matter for accuracy: timers pause when your Mac sleeps, and Insights counts only active focus time. The result is a timer that reflects the time you actually spent focusing rather than wall-clock time that includes every interruption. The daily notepad is where thoughts get captured before they disappear. You can jot down an idea, a link, or something to follow up on, and the notepad saves as you type. When a line becomes something to do, you place the cursor on that line and press Command–Return to turn it into a task. That single shortcut closes the gap between capturing a thought and acting on it, so notes do not pile up as an unprocessed list. Because the notepad lives in the same workspace as your tasks and timer, the moment you write something actionable you can convert it without leaving the notch. Insights is the reflection layer. A busy week can be hard to remember, so Insights brings together completed tasks, active focus time, and daily activity in one place. That lets you see what you finished and where your attention went, turning a scattered set of sessions into a readable record of the work you put in. Because active focus time is counted separately, timers pause when your Mac sleeps, so the picture Insights shows is about deliberate work rather than time spent with the app open. Calendar events are available in the same notch workspace, and connecting Calendar is optional. The notch workspace shows today's upcoming events from the calendars you already have added to Apple Calendar on your Mac. NotchOwl is explicit about how this works: macOS calls the permission Full Access, but NotchOwl only reads events and never creates, edits, or deletes them. That means you can check what is coming up next without opening a calendar app, while your calendar data stays under the control of Apple Calendar on your Mac. Getting into the workspace is deliberately quick. You hover over your Mac's notch or press Option–N to open NotchOwl, then add a task, start a focus session, jot down a note, or check today's upcoming events. When you are ready to work, you close it, and your running timer stays visible in the notch. You do not need a Mac with a notch to use it: on displays without a notch, NotchOwl opens at the top center of the screen, below the menu bar, and you can also open a full dashboard. Your tasks, notes, and timers work locally and your planner data stays on your Mac, and you can export your planner data as a JSON backup. The stated outcomes are practical. Keeping the workspace one hover away means less switching and more doing, because checking your next task no longer means leaving the app you are working in. Because the timer stays visible in the notch, your commitment to a task stays in front of you, and the ability to pause, resume, or add five minutes keeps that commitment realistic. The notepad means ideas and follow-ups are captured as they happen rather than lost. Insights answers the question of what you actually got done, and the calendar view keeps the next appointment in view. Together these pieces support the product's closing invitation: make room for what matters. Several concrete workflows follow from the features described. During a focused piece of work, you can pick a task and give it a time limit, or run a stopwatch if the work has no clear deadline, and watch the countdown in the notch until you pause, resume, or add five minutes. Mid-task, you can hover the notch and jot an idea or a link into the daily notepad without switching windows, saving it as you type. If a line you wrote is something to do, Command–Return turns it into a task immediately. Before a meeting, you can open the workspace and check today's upcoming events from Apple Calendar. At the end of a busy week, you can open Insights to review completed tasks, active focus time, and daily activity. And if you need a broader view, you can open the full dashboard. NotchOwl also keeps working when you are offline: after license activation, tasks, notes, and timers work locally, and an internet connection is needed only for activation, deactivation, and update checks. NotchOwl is for Mac users. The current download requires macOS 14 or later and is built for Apple silicon Macs, and a notch is not required since the workspace also opens at the top center of the screen on displays without one, with a full dashboard option as well. It is a paid product sold as a one-time purchase rather than a subscription: the lifetime license is $4.9 USD and covers all NotchOwl features, lifetime updates, and activation on up to 3 Macs, with a 14-day money-back guarantee. The installer is free to download, but a paid license is required to use the app; after checkout the license key arrives in the Dodo Payments email and is entered in the Mac app. There is no recurring payment, and you can move the license to another Mac by choosing Deactivate this Mac in the License section of Settings, after which you can use the key on the new Mac, subject to the 3-Mac limit and an internet connection for deactivation. NotchOwl's value proposition is narrow and clear: instead of another window to manage, it puts tasks, a focus timer, quick notes, calendar events, and insights in the Mac's notch, one hover or Option–N away. For Mac users who want their next task and captured ideas to stay close, without switching windows, it offers a small, local, one-time-purchase workspace for the work in front of them.
Product Launch Checklist is a free list for people launching software, from the moment the product works to the first month after launch. It covers SaaS, mobile apps, AI tools, browser extensions, open source projects and developer tools. Every item says why it matters and says when you can skip it. Pick what you are launching and the list gets shorter, not longer: billing and trials come in for SaaS, store review and privacy labels for apps. Your ticks are remembered in the browser, and the whole thing is readable without an account, an email or a payment. It is also built for AI agents: the checklist is available as Markdown, through a no-auth MCP server and as an agent skill.
Pixolm is an AI image generation and editing workspace for creators and small teams. Generate from text or reference images, then refine results with prompts and optional masks. An AI creative agent and dedicated workflows support icons, hand-drawn illustrations and ecommerce visuals. Features vary by model and mode. New users receive 20 one-time welcome credits; paid plans start at $9.90 per month.
FATHER is a macOS application that serves as a mission-control dashboard for websites and deployments, built specifically for teams shipping on Vercel. Its stated purpose is simple: it watches the fleet so you do not have to, and it makes sure you know that a site is down before your clients do. The app is aimed at people who are responsible for more than one live site — studios, agencies and developers running client projects — and who need a single screen that answers the question of what is healthy, what is broken and what is about to expire. Connect your Vercel account and the dashboard fills itself: deployments, uptime and speed metrics appear live. The underlying problem is fragmentation. A team shipping on Vercel typically has to visit the Vercel dashboard for deploys, a search console for clicks and rankings, a separate source for page-speed scores, and yet another place to check whether an SSL certificate or a domain is about to lapse. GitHub checks live somewhere else again, and a failed build can sit unnoticed for hours if nobody happens to be looking at a browser tab. FATHER pulls those signals into one native macOS window, and — more importantly — into the menu bar, so monitoring stops being something you have to remember to do and becomes something that comes to you. FATHER is built on Vercel. Deploy tracking and the speed and uptime metrics all come from the Vercel API, so the integration is not a bolt-on but the foundation of the app. You connect your account token and your projects appear automatically; there is no manual inventory to maintain and nothing to keep in sync. Projects that are hosted somewhere other than Vercel can still be added manually so they get basic status checks, which means the dashboard can serve as a single view even for a mixed hosting estate. Because the app relies directly on the Vercel API, the numbers it shows come from the same place your deployments do. The core view is the fleet at a glance: the status, uptime and response of every site on one screen. Rather than opening projects one at a time, you get a single list you can scan in seconds to see which sites are responding, which are slow and which are down, so the morning check on a portfolio of client work takes moments instead of a tour through several dashboards. Deploy tracking is the second pillar. FATHER lets you watch builds progress and catch failures the moment they land, live from Vercel, so a broken deploy does not have to wait for a client email or a casual check-in to be discovered. Two features make sure that information actually reaches you. Menu-bar status shows an F in the macOS menu bar: it displays a dot while builds are running and turns red when something needs your attention, so the health of the fleet is legible at a glance from wherever you are on the Mac. Alerts go further — notifications fire even when the dashboard is closed, so a failed build or a site going down will find you rather than waiting to be found. Together they turn the app into something closer to a pager for your web estate than a traditional dashboard you have to remember to visit. Beyond deployments and uptime, FATHER covers the surrounding signals that usually live in separate tools. Traffic, PageSpeed scores, Search Console data and Bing data all appear in the dashboard, with clicks, rankings and indexing visible without leaving the app. SSL certificates and domain renewals get a countdown, so expirations stop being a nasty surprise, and failing GitHub checks get flagged alongside everything else. The result is a dashboard that answers both the operational question of whether a site is up and the marketing question of whether it is performing. The app's approach is deliberately local and deliberately simple. Tokens stay on your Mac rather than being shipped to a hosted service, and the product is sold as a one-time purchase instead of a subscription. It is a native macOS application — universal, so it runs on both Apple Silicon and Intel Macs — and it is menu-bar-first rather than browser-first. Every app in the studio's suite ships with the same set of themes, so the dashboard can be themed to taste like the rest of the collection. For the user, the benefit is timing. Knowing that a site is down before your clients do changes the conversation entirely: it turns a defensive, apologetic call into a proactive fix. Catching a failing deploy the moment it lands shortens the window in which a broken build is live. A countdown on SSL and domain renewals removes a class of avoidable outages, and having traffic, PageSpeed and search data in the same window reduces the number of tabs and logins needed to answer routine questions. All of it runs from the menu bar, so the information arrives without anyone having to go looking for it. Typical use looks like an agency or studio with a portfolio of client sites on Vercel: the dashboard becomes the first thing checked in the morning and the thing that taps you on the shoulder when a build fails overnight. Freelance developers use it to keep an eye on their own and their clients' projects without logging into the Vercel dashboard repeatedly. Teams with mixed hosting add their non-Vercel sites manually so the fleet view stays complete. Marketers and SEO-minded owners watch clicks, rankings and indexing alongside speed scores, and anyone responsible for renewals relies on the SSL and domain countdowns. FATHER is made for teams shipping on Vercel — studios, agencies and independent developers managing client work. The integrations named in the product material are Vercel, Google Search Console, Bing and GitHub, with PageSpeed scores surfaced in the dashboard. It is a macOS app that runs on Apple Silicon and Intel Macs. Pricing is a one-time $7.99 for FATHER alone, or $22.99 for the full Suite of all four apps from the same studio. In short, FATHER is a macOS mission-control dashboard that turns a scattered set of monitoring chores — deploys, uptime, speed, search visibility, renewals and checks — into a single live view with menu-bar alerts attached. Its value proposition is early warning: you find out first, act first, and keep your clients out of the loop only because there is nothing for them to worry about.
Axari is an AI twin for cybersecurity teams — an AI workforce product that is given real work rather than asked questions. The company's pitch is simple: you plus your AI twin equals indefatigable. A security leader spends the working day setting strategy and priorities, leading the security program, and making the decisions that matter. The twin, meanwhile, runs 24/7: it understands what needs attention, coordinates work across tools and teams, and executes, follows up and verifies until the work is actually done. Users can assign it a goal, let it work proactively, or give it recurring responsibilities, and all of this happens from within Slack or Microsoft Teams. It is aimed squarely at security organizations rather than general business users, and it is meant to be given real security work, not just to answer questions. The problem Axari addresses is the coordination overhead that surrounds security work. Security teams already own scanners, ticketing systems, identity platforms, cloud accounts and compliance tools; what they often lack is someone to keep the resulting work moving between them. Axari's own framing of this is quantitative: it claims time back of 10–15 hours per person, per week, on coordination-heavy work, notes that organizations spend $8–10 per $1 hiring people to operate a security tool, and describes a cognitive load of 17 of 20 items already in motion before a leader opens Slack — leaving only the 3 that genuinely need them. Its overhead claim is zero: no training sessions, onboarding programs, or new tools to learn. Customer quotes echo the same theme, including "We couldn't hire more people; we hired Axari," "We didn't rip out a single tool," and a fractional CISO noting that control drift used to be caught during the next audit cycle but is now flagged the same day it happens. Axari works across the tools a security team already runs instead of replacing them. The integrations shown on the site include Slack, Jira, GitHub, Gmail, Wiz, Splunk, Okta, Snyk, CyberArk, Tenable, Vanta, AWS, Datadog, Kubernetes, Google Cloud, Terraform, Confluence, CrowdStrike Falcon, Google Drive and HubSpot. The important point is what the twin does with those connections: it reads finding and asset context from a scanner, writes and assigns tickets, pulls policy language, collects evidence, scores vendors, lists entitlements, groups alerts and enriches them with telemetry. Because the twin operates inside the collaboration layer — Slack or Microsoft Teams — colleagues see the work happening in the channels they already use, and owners can be nudged or asked for a decision without anyone logging into a separate console. Several of the documented use cases concern exposure and threat work. In critical exposure protection, the twin pulls the finding and asset context from Wiz, creates the ticket in Jira and assigns the owner, then re-checks the scanner before anything is closed. In cloud exposure protection, it detects the misconfiguration, maps it to the owning AWS service, and prepares the fix in GitHub for review. In threat response assurance, it groups overnight alerts from Splunk, enriches them with endpoint telemetry from CrowdStrike Falcon, and opens the investigation in Jira with an owner assigned. In ransomware resilience, the twin confirms containment, revokes compromised sessions, and keeps legal and leadership on a single timeline in Slack. Each of these follows the same pattern: gather context, do the coordination, and hand the judgement call to a human. A second group of use cases covers governance and assurance work. For continuous compliance, the twin collects access evidence, maps that evidence to controls in Vanta, and chases owners in Slack who have not responded. For trusted vendor onboarding, it requests missing documents by email, scores the vendor against your policy, and routes the decision to the risk owner. For security review acceleration, it drafts from your approved answers, pulls current policy language from Confluence, and flags the answers that need human judgement. For access assurance, it lists every account and entitlement, nudges reviewers with a cutoff, then revokes and confirms the removal. The recurring theme is follow-up: the twin does not stop at producing an artifact, it pursues the response it needs and verifies that the change actually happened. Axari describes its approach in four stages. Connect: it maps what your tools do and learns exactly how your team operates daily. Understand: it works out who owns what, what matters, how work is routed, and where you are needed — the product illustration shows a daily brief in Slack summarizing priorities and where you are needed. Act: it prepares the work, assigns owners, follows up, and executes what you authorize; in the example shown, the twin drafts a SOC 2 reply in Slack with approve, edit and discard actions. Compound: it learns how you decide, anticipates what's next, and keeps getting smarter — for instance, proactively asking whether it should check with a colleague before sending a vendor exception approval. The site labels this "compounding intelligence," suggesting the twin's usefulness grows as it observes more of your decisions. The stated outcomes are time, money, cognitive load and overhead. The company reports 10–15 hours back per person, per week, on coordination-heavy work; a spend pattern of $8–10 per $1 currently going to people operating a security tool; a cognitive load figure of 17 of 20 items already in motion before the leader opens Slack, so only 3 need them; and zero overhead in training sessions, onboarding programs or new tools to learn. Testimonials support the positioning: one CISO says that nothing was ripped out and Axari simply made existing tools work harder, a CIO says the team could not hire more people so they hired Axari, and a former Google Chrome security lead describes Axari as a full AI security team that learns how an organization works and actually gets the work done. Concretely, a security team might use Axari in a daily rhythm. Overnight, the twin groups alerts, enriches them, and opens investigations with owners attached, so the morning starts with work already in motion rather than a blank page. During the day, it keeps compliance evidence flowing — collecting, mapping and chasing — and nudges access reviewers before a cutoff so certifications do not stall. When a vendor request arrives, it asks for the missing documents, applies the policy score, and asks a human before sending an exception. When a security questionnaire lands, it drafts from approved answers and flags what needs judgement. Because the twin lives in Slack or Teams, each of these shows up as a short, actionable exchange rather than another dashboard to check. The site names CISO / Head of Security, GRC, Security Operations, Security Engineering and Security PMO as the roles Axari serves, and lists customers and partners including HiddenLayer, Boyd, Supabase, CAVA, Yext, Hydrolix and OpenLoop. On trust, Axari emphasizes control, security-native design and security posture. Controls include scoped access, human approval for consequential actions, a complete audit trail, the promise that your data stays yours, and the ability to bring your own model. The company says the product is shaped by 300+ conversations with security leaders and built alongside security leaders from Google, Anthropic, Atlassian, Supabase and Roblox. It reports SOC 2 Type 1 complete, red-teaming against the OWASP Top 10, zero data retention where applicable, and BYOC / on-prem support in progress. A CISO testimonial notes that Axari earned access rather than asking for it all on day one. Axari's core proposition is straightforward: security leaders cannot hire their way out of coordination work, and attackers are not going to use less AI. By giving teams a persistent AI twin that lives in Slack or Microsoft Teams, understands the environment, coordinates across existing tools, and follows work through to verification, Axari aims to close the execution gap that sits between a security program's plans and its outcomes — without replacing a single tool in the stack. As the company puts it, you plus your AI twin equals indefatigable.
Voiskey is an AI voice typing tool that turns natural speech into polished, ready-to-use text. Rather than transcribing words literally, it starts from what you meant: you speak a rough thought and it comes back shaped for where it is going and who is reading it. It produces text for messages, emails, notes, documents, AI prompts and more. Voiskey is available on macOS, Windows, iOS and Android, works anywhere on your computer and in any language, and is described as 5x faster than typing. It is free to start, with a free month of Pro for people who join during launch. The problem Voiskey addresses is the gap between how quickly people think and how quickly they can type. An average keyboard runs at roughly 45 words per minute, while Voiskey voice is presented at 220+ words per minute. That gap shows up as friction in everyday work: the first draft is the hardest part, ideas hit fast but drafting is slow, thoughts disappear quickly before they can be captured, and meeting details are easy to forget. The same friction appears in professional routines — prompting takes longer than coding now, the faster the follow-up the warmer the deal, and tickets pile up faster than a support agent can type. Voiskey's answer is to let people speak the way they naturally would and let the product handle the shaping. Voiskey is built to listen for meaning rather than to capture every sound. The website describes it as more than listening — it understands. When you speak the way you naturally would, fillers, stumbles, changes of mind and grammar slips are all caught by Voiskey rather than passed through into the final text. The point is that you should not have to tidy your speech before you start; you think out loud, and Voiskey handles it. This is what makes the output ready to use rather than a raw transcript that still needs editing, and it is the foundation for everything else the product does with your words. Voiskey is built to adapt, and the content says it always lands right. It knows what you are going for and automatically tailors the formatting, tone and word choice so that every output fits your intent and is ready to send. The Product Hunt listing describes the same behaviour from the opposite direction: a spoken thought comes back shaped for its destination and its reader — casual with a friend, composed with a colleague, technical with an AI. This matters because the same idea needs a different form in a text message, an email, a meeting note or an AI prompt, and Voiskey applies that shaping automatically instead of leaving it to you to rewrite. Voiskey also learns your style. According to the website, it learns your names, jargon and spelling preferences so that your words always land in your style. This is a personalisation layer: rather than producing generic, uniform text, it keeps the vocabulary and spellings you actually use, which matters for people working with specialist terminology, product names, colleague names or in-house shorthand. The stated outcome is that you still sound like you — the product cleans up the mechanics of speech without erasing the voice of the person speaking. Voiskey covers voice to native-sounding text in more than 100 languages, and it presents a long list of supported languages on the site, including English, Japanese, Spanish, Korean, French, Portuguese, Arabic, Russian, Italian, Thai, Vietnamese, Dutch, Polish, Danish, Swedish, Finnish, Greek, Czech, Romanian, Hungarian, Bulgarian, Slovenian and Estonian, among others. The site states that Voiskey works anywhere on your computer and in any language. It also covers translation: you speak in your own language when you need to translate, and Voiskey turns your voice into fluent, native text across 100+ languages. That makes dictation and translation part of the same speaking workflow rather than two separate tools. A distinctive capability is turning spoken intent into AI-ready instructions. Voiskey lets you tell your AI what to build just by speaking: you talk through what you want to build or change, and Voiskey turns it into a clean AI-ready prompt with files, paths, commands and key details captured. This is presented as a practical answer to the observation that prompting now takes longer than coding, and it is a core part of how Voiskey is positioned for engineers — spoken intent becomes prompts, commits and design docs. Capturing files, paths and commands automatically means the details that are easy to lose when speaking are preserved in the final prompt. Voiskey's overall approach is a single voice experience that follows you across every device. It runs on macOS, Windows, iOS and Android, and the site states that it works anywhere on your computer — wherever you type and however you speak, Voiskey is ready. There is no separate destination app to paste into: you dictate into the place where the text is going, and the output arrives cleaned up and ready to send. The product is positioned as starting from what you meant rather than just what you said, which is the through-line connecting its filler handling, its adaptive tone and formatting, its style learning, its multilingual output and its AI prompt generation. The stated benefit is speed and readiness in the same step. Voiskey is described as arriving 5x faster than typing, cleaned up and ready to send, while you still sound like you. The comparison the site makes is 45 wpm for a keyboard against 220+ wpm for Voiskey voice, which means thoughts get out before the keyboard slows them down. Because formatting, tone and word choice are adapted automatically, the output is not a draft that needs a second pass. And because Voiskey learns names, jargon and spellings, the speed does not come at the cost of sounding generic. Voiskey frames its use cases around the formats people write in and the roles they work in. By format, the site names Messages (texts, DMs and quick replies), Emails (rough drafts shaped into clear, structured emails), Notes (reminders, quick lists and random ideas captured the moment they show up), Meetings (decisions, action items and follow-ups) and Teams (clear updates, handoffs and action items). By role, it lists Engineers (prompts, commits and design docs), Sales (call notes, CRM updates and replies), Customer Support (tickets, live chats and help articles), Writers and Creators (posts, scripts and book chapters), Students (lecture notes, essays and emails), Founders (updates, replies and job posts) and Legal and Consulting (memos, client letters and contracts). Voiskey is aimed at anyone who writes more slowly than they think, and the role pages make that concrete: engineers, sales people, customer support teams, writers and creators, students, founders, and legal and consulting professionals. It is available on macOS, Windows, iOS and Android, with a single voice experience across all four. Pricing is free to start, and the launch offer includes a free month of Pro for people who join during the launch period. No specific price points or further plan details are stated in the provided content. Voiskey's core promise is that you can say it rough and send it right. It listens for meaning rather than words, strips out fillers and stumbles, adapts tone, formatting and word choice to the reader and destination, learns your names, jargon and spellings, works in 100+ languages with translation, and turns spoken intent into AI-ready prompts. It delivers all of that across macOS, Windows, iOS and Android at a stated 5x faster than typing, and it is free to start. For anyone whose ideas outrun their keyboard, that combination is the value proposition.
Narrative is an AI-first video editor built around a simple idea: bring your footage, say what you want made, and cut it together with an editor that does the work with you. Rather than assembling cuts by hand, you upload clips, describe the edit you want in plain words, and keep refining the result through chat. Narrative brings video editing, custom motion graphics and reference-video style matching into one interface. It builds a finished draft on a timeline you can still open and change, so the output is not a locked black box but a real project you can adjust. It is designed for people who already have footage and a clear idea of the outcome, but who do not want to learn Premiere or After Effects to get there. From podcast clips to launch videos, the first step is the same: say what you want. The problem Narrative addresses is the gap between having footage and having a finished cut. Editing traditionally means learning complex software, understanding timelines and motion graphics, and spending hours scrubbing through material to find the good bits. One producer notes that every episode used to cost an afternoon of finding the good bits. A media lead describes the difficulty of finding every goal in a ninety minute match, including the one the camera nearly missed. A product marketing team says their unboxing demos went from a freelancer and a week to a sentence and ten minutes. Narrative targets exactly that gap: the time, cost and specialised skill that sit between raw footage and a usable edit, whether the material is a two hour shoot, a wedding, a podcast or a match recording. The core of the product is editing by talking. You ask in ordinary language, and the agent does the work. An example from the site is a request to make a 15 second reel of the best rides, with a title at the start and music under it. The agent then reads the transcript, edits the clips and reports back what it did, explaining that four rides were placed on the strip with the tightest one first, the title running from 0:00 to 0:03 and the music bed sitting under everything. Anything you would say to an editor, you can say to this one — it works from the words, not a menu. The site lists prompts such as cutting to the beat, making it feel like a trailer, putting every goal in order, removing the ums, going vertical with captions, starting on the best line, tightening to thirty seconds, warming it up a little, and putting the title back at the end. Everything lives in the same editor as the conversation: the transcript, captions, versions, the frame and the models behind it. The editing surface is the editor itself, not a picture of it — you can press play, scrub the strip and mute a track. Tracks and elements shown in the interface include graphics, clips, dialogue and music, along with elements such as a title and a location card, with individual clips listed by timecode and duration. You can add music, sound effects and transitions, and Narrative also supports custom motion graphics and reference-video style matching, so you can take inspiration from reference videos. Because the assistant reads the transcript while cutting, requests such as removing filler words or placing captions are grounded in what was actually said in the footage. Every turn is a version. The version history in the interface shows a numbered list of states, with the current one marked and older entries available to restore — for example v12 as the current turn, v11 with edited styles, v10 where a clip was trimmed, and v9 where the frame was set to 9:16. Each entry carries a restore action, so you can step back to any of them or put the project back to how a turn left it. A completed turn also reports what it used, such as the number of tools and credits consumed. For teams, this matters: one testimonial notes that with every version kept, nobody on the staff can break the cut. You can choose the speed, or the brains. Narrative offers three model tiers: Fast, for quick cuts and small changes; Balanced, for most edits most of the time; and Max, for long footage and hard briefs. The frame control handles aspect ratio, starting at 16:9 and switching to others on request. The options shown are 16:9 (original), 9:16 described as both speakers stacked, 1:1 for feed and 4:5 for portrait feed. The 9:16 example is instructive: start in 16:9 and ask for 9:16, and both speakers stay in the shot, stacked. That means social-ready vertical versions can be produced from the same source project rather than being re-cut from scratch in another tool. Overall, Narrative's approach is to treat the conversation and the timeline as one workspace rather than bolting a chat box onto a traditional editor. You upload your footage, describe the edit, and the agent reads the material — including the transcript — makes the cut, and tells you what it did. Every instruction becomes a version you can inspect or restore, and each turn reports the tools and credits it used. You decide how much horsepower to apply by choosing Fast, Balanced or Max, and you control the output shape through the frame settings. Narrative handles rendering and storage, so you are not managing exports, disk space or a render queue yourself. The result keeps a real, open timeline at the centre instead of a one-shot generated file. The stated benefits follow from that model. Edits arrive faster: a three minute highlight from two hours of wedding footage was on the timeline before a coffee was cold, and a producer can ask for the five best moments as verticals with captions and then open the timeline to check the work. Work that previously required a freelancer and a week can become a sentence and ten minutes. Because the output is a real editor rather than a fixed render, changes stay possible — when legal wants a frame changed, the frame is changed. Version history protects the cut from accidental damage, and Narrative's own launch video was made entirely in Narrative. Concrete scenarios named on the site include wedding films, podcasts, match highlights and product demos. A wedding filmmaker asked for a three minute highlight with the vows in the middle from two hours of footage. A podcast producer asks for the five best moments as verticals with captions. A football club's media lead asks for every goal in a ninety minute match. A product marketer produces unboxing demos. Broader examples include a rough cut, a supercut, or a vertical reel from a two hour shoot, plus podcast clips and launch videos. The audience is filmmakers, producers, media leads, product marketers and teams who cut regularly. Plans run from Free at $0/month with 3 AI prompts, the whole editor and your own footage, through Plus at $20/month with 2,000 AI credits, 10 projects, 100 GB of footage, 4K renders without watermark, every model tier including Max and version history kept for a year, and Pro at $40/month with 4,000 AI credits, 30 projects and 500 GB of footage, to Studio at $100/month for teams cutting every day with 10,000 AI credits, unlimited projects, unmetered renders with priority in the queue, 1 TB of footage and priority support. Paid plans include a 3-day trial and can be cancelled any time, and there is an iOS app in addition to the web editor. Narrative's value proposition is straightforward: describe the edit you want in plain words, and get a finished draft on a timeline you can still open and change. It compresses the distance between raw footage and a usable cut while keeping the edit genuinely editable, with versions, model tiers and frame controls under your hand.
Multimodal Agents by Sierra are AI agents that bring voice, text, and visuals into the same customer conversation. Sierra has long believed that the conversation is the interface: the customer says what they need and the agent figures out the rest. Multimodal agents extend that belief beyond a single medium. Rather than making customers choose between talking, typing, or looking at something, the agent gives them the best of each — voice to explain what you need, a visual to compare options side by side, and text when you want to reference something later. The result is a single, continuous conversation that adapts to what the customer is trying to accomplish at that moment. The problem this solves is familiar to anyone who has tried to make a decision over the phone. Sierra describes trying to upgrade a mobile plan over the phone: the representative talks through models, colors, storage sizes, and monthly rates, and the customer is left comparing things in their head and picking a phone they cannot picture. Voice is genuinely good for parts of that interaction — you can say what you actually need and ask questions more easily than you can over text — but you cannot see the thing you are about to buy. Multimodal agents close that gap. Stitching channels together is not the hard part; the real trick, as Sierra puts it, is knowing which one to use when. That is where the agent's judgement comes in. Agents built on Sierra anticipate what is needed for each conversation and automatically shift between modes — voice, visuals, or text — without making the customer start over or repeat themselves. The choice of medium follows the shape of the task: voice to explain what you need, a visual to compare options side by side, or text when you want to reference something later. Because that switching is automatic, the customer never has to manage the interface. They simply continue the conversation, and the agent keeps the relevant context intact as the medium changes, which is precisely what prevents the restarting and repeating that usually happens when a support interaction jumps between a phone call, a chat window, and a web page. Visuals are part of the conversation rather than a separate destination. Sierra's example is a disrupted flight: you call the airline to get a new flight, and instead of a representative reading off alternate options one by one, you see them laid out with departure times, layovers, and pricing right in the conversation. You pick one, and the agent keeps going from there. Choosing a seat works the same way — you see the map and tap the seat you want. And for times when it is easier to talk than type, you can switch to voice and explain exactly what you need; the agent captures those details without making you type a paragraph into a text box. In each case the visual carries the comparison work that language handles poorly, while voice carries the nuance that menus and forms handle poorly. Sierra's approach is also designed to avoid rebuilding the same experience for every place the agent lives. With Sierra, you can build your agent once and easily deploy across all channels, and the same is true for multimodal agents: once you build a visual component, your agent can use it everywhere it lives. A comparison table or a calendar does not need to be recreated for each surface the agent operates on. That single-build approach reduces duplication for the team maintaining the experience and keeps behaviour consistent for the customer, who encounters the same kind of interactive element regardless of where the conversation happens to be taking place. Sierra's MCP UI integration is what lets teams bring interactive components into the conversation: product cards, comparison tables, calendars, and forms. Those components are designed and hosted by your own team, so you decide how they look, what they show, and when they change. That control matters because the visual layer is often the part of a customer experience that carries brand and merchandising decisions, not just function. Because your team hosts the components, when you make an update it is automatically reflected everywhere without needing to redeploy or maintain different versions for each platform. And when a component needs more room, it can expand to full screen to show calendars, long comparison tables, multi-step forms, and more — so the same building block can serve as an inline detail inside a conversation or as a focused, full-attention task when the customer needs to complete something substantial. Taken together, the methodology is straightforward: keep the conversation as the interface, let the agent decide which medium each moment calls for, and make the interactive pieces reusable across every surface. Sierra frames the goal as customers never having to choose. On one call, customers can talk through what they need, glance at a screen to compare their options, and tap to confirm — without ever pausing the conversation to switch tools. The agent, not the customer, manages the transitions, which is what makes an interaction that spans voice, visuals, and text feel like a single continuous exchange rather than three separate ones. The outcomes described are practical. Customers get through decisions faster because they can see options while hearing about them, and they avoid the frustration of describing the same need twice or rebuilding context after a channel change. They can also reference something later in text when that is easier than listening. Businesses, meanwhile, get a single deployment path: build the agent and its visual components once, use them across channels, update them in one place, and avoid maintaining separate versions per platform. And the experience is described as being as easy to build and deploy as it is for customers to use, which lowers the practical barrier to offering a multimodal customer experience at all. Concrete workflows in Sierra's own examples include upgrading a mobile plan, where a customer talks through what they need and compares phones, colors, storage sizes, and monthly rates visually instead of holding the options in their head. A disrupted flight is another: the agent surfaces alternate flights with departure times, layovers, and pricing in the conversation, and the customer picks one and continues. Seat selection follows the same pattern, with a map the customer taps rather than a description they have to parse. Voice-first moments are covered too — when it is easier to explain something than to type it, the customer can switch to voice and the agent captures the details. More broadly, any conversation that involves comparing options side by side, filling in a form, or choosing a time can use interactive components inside the exchange itself. Multimodal Agents by Sierra are aimed at organizations that handle customer conversations and want those conversations to adapt to the customer rather than the other way around — customer experience and support functions in particular. The people who build the visual layer are the customer's own teams: Sierra states that your team designs and hosts the components used in the conversation. Deployment is described in terms of channels rather than a single app, since the same agent and the same visual components are meant to work everywhere the agent lives. Sierra's MCP UI integration is the mechanism named in the content for bringing interactive components such as product cards, comparison tables, calendars, and forms directly into a conversation. The core idea behind Multimodal Agents by Sierra is that the best interface is the one the conversation needs. Voice, visuals, and text stop being competing options and become modes the agent moves between as the situation changes — voice when explaining is easier, a visual when comparing side by side helps, text when something needs to be referenced later. Because agents built on Sierra anticipate what is needed and shift automatically, customers never start over or repeat themselves, and because visual components are built once and hosted by your team, they can appear everywhere the agent works. That is the promise: one agent, every surface, and a conversation that morphs to fit the customer.
Idlen is an advertising network built around the idle time that appears while AI models are thinking. Its promise is short and direct: AI thinks, you earn. The product puts native developer-tool ads in three places — the IDE, the browser, and the chat app you shipped. Developers install the Idlen extension for VS Code, Cursor, or Chrome and see a native ad during the moments their AI assistant is processing a request, keeping 70% of the revenue. Advertisers use the same network to reach developers inside the tools they already use every day, targeted by the stack they actually work with, including React, Python, and AWS. AI app builders add three lines of code with npm i @idlen/chat-sdk to monetize their own chat products, and ads remain optional there: no key, no ads. Developers spend a large part of their day waiting on AI. A prompt is sent, the model thinks, and the editor sits idle for a few seconds at a time. Idlen takes that observation literally: the wait is an ad slot. Instead of treating AI processing time as dead time, the network fills it with a native, relevant sponsor message — the demo shows a sponsored slot carrying Neon, described as serverless Postgres for modern apps. The reasoning behind the product is that the waiting is unavoidable: developers are already using Claude, ChatGPT, Cursor, and other AI tools, and they change nothing about their workflow. Idlen simply adds an ad during processing and pays the developer a share. At the same time, developer-tool companies struggle to reach this audience precisely, and AI app builders who ship chat products have usage but often no monetization. Idlen answers all three sides with one network and three doors. The earning side of Idlen is built for individual developers first. The extension is described as earning €20-100 per month passively, without lifting a finger, and earnings go directly to the developer's account. Payouts are flexible: Stripe, PayPal, or a 10% bonus taken as credits. Idlen also supports teams through a shared earnings pool, so an entire group can collect the income generated by its members. An earnings calculator on the site lets developers model the result using their coding hours per day and a target subscription — ChatGPT Plus, Claude Pro, or v0 Premium — showing, for example, that four hours per day yields 150% coverage, making ChatGPT Plus free with surplus pocket money. The site notes these figures are based on average developer activity and ad inventory fill rates. Onboarding is presented as taking under two minutes. Privacy is treated as a core feature rather than a footnote. Idlen states plainly that your code stays on your machine, and the privacy process is spelled out in three steps. First, no code access: the extension never reads, stores, or transmits your source code. Second, local analysis only: package.json is analyzed on your machine to determine ad relevance, and nothing leaves the device. Third, the ad request itself is anonymous — the illustrative code shows dependencies read locally, keywords matched from those dependencies, and then an anonymous fetch for an ad. The company also describes the extension code as transparent and auditable and available for security review. For developers, that means the monetization does not come at the cost of handing over a codebase or prompts; Idlen states that it does not read your prompts. Idlen is designed to stay out of the way. Its zero-latency claim rests on timing: ads load during AI processing only, so they occupy time the developer is already waiting rather than adding delay to normal editing. It works everywhere in practice — VS Code, Chrome, and all the AI tools the developer already uses, with support listed for Claude, ChatGPT, V0, Bolt, Lovable, Cursor, Windsurf, and Replit, plus downloads for VS Code, Cursor, Open VSX, Chrome, and Firefox. On the advertising side, the network claims to avoid spam and clickbait, promising only curated developer tools, organized into categories such as Cloud & Hosting for deploying, scaling, and monitoring apps; Databases for modern databases; APIs & Services covering payment, email, and SMS; and Dev Tools for boosting productivity. The core workflow is deliberately small. Step one: install the extension — add Idlen to VS Code or Chrome in one click, and it works with all your AI tools. Step two: use AI as usual — keep coding with Claude, ChatGPT, Cursor, or any other AI tool, with no workflow changes. Step three: earn passively — relevant dev tool ads appear during wait time and earnings go directly to your account. The site summarizes the whole journey as starting to earn in under 2 minutes. The demo interaction reinforces it: a user sends a message such as "Add proper error handling and improve the loading state," and the assistant thinks for three seconds; during that window a sponsored Idlen slot appears in the chat, and the panel reports earning tokens while you wait. Advertisers enter through a different door: they buy the slot and appear in the IDE and browser, targeted by the stack the developer actually uses. Publishers enter through a third door: they paste a message in the sandbox to preview which ad would serve, then run npm i @idlen/chat-sdk, three lines of code, and keep 70%. The benefits differ by side but share one shape — value extracted from time that was previously wasted. For developers, the outcome is passive income on top of work they were already doing, with no change to workflow, zero tracking, and no exposure of code or prompts. Reported earnings of €20-100 per month can offset or fully cover an AI subscription, and the calculator turns that into a concrete target: pick your hours and your subscription and see the coverage percentage. Flexible payouts and a team pool make the income usable for individuals and groups alike. For advertisers, the benefit is placement inside the tools where developers spend their day, targeted by real stack signals rather than guesswork, with a welcome offer that doubles the first deposit: pay €200 and get €400 this week. For AI app builders, the benefit is monetization of an existing chat product with a very small integration surface — three lines — while keeping 70% and retaining the option to show no ads at all. A few concrete workflows illustrate where Idlen is used. A developer using Cursor or VS Code spends a few seconds waiting for code generation; the Idlen extension fills that moment with a native, stack-relevant sponsor message and credits the earnings. A developer working in the browser with ChatGPT or Claude gets the same treatment through the Chrome or Firefox extension. An advertising team that sells a serverless database or a hosting platform buys slots and appears while developers are actively coding, matched against the technologies visible in that project. An AI app builder who shipped a chat product installs @idlen/chat-sdk, previews a message in the sandbox to see which ad would serve, and switches on monetization without managing keys. A team adopts the extension together and pools its earnings through the shared team pool. And a prospective advertiser tests the waters with the €200-to-€400 welcome offer before committing further spend. Idlen is explicitly built for every side of the ecosystem it touches. The first group is AI users — developers who want passive income while using their favorite AI tools. The second is advertisers selling developer tools who want to appear in the IDE and browser, targeted by the stack developers actually use. The third is AI app builders and publishers who want to monetize an AI product with three lines of code. Integrations and downloads cover VS Code, Cursor, Open VSX, Chrome, and Firefox, with the network listed as working alongside Claude, ChatGPT, V0, Bolt, Lovable, Cursor, Windsurf, and Replit. Installing Idlen is free for developers, who keep 70% of earnings; the paid side of the marketplace is advertising, where the entry offer is €200 matched with €200 for €400 to spend this week. The site also highlights privacy first, zero latency, and cancel anytime as standing commitments. Idlen's core proposition can be stated in one line: the seconds you spend waiting for AI are already being spent, so the network turns them into income for developers, distribution for developer-tool advertisers, and revenue for AI app builders. One network, three doors — install the extension, buy the slot, or try the sandbox.
DynamicLake 2.0 is a Mac application that brings a Dynamic Island style experience to the Mac desktop. Its website describes it simply as "Dynamic Island for Mac", and its Product Hunt listing calls it "Dynamic Island for Mac with 3rd Live Activities and more". The product's own description lists plugins, notifications, drag and drop, a converter, calls, AirDrop and a timer among the things it offers. The site states that it is "Inspired by Apple Dynamic Island" and that it follows a "Liquid Glass Design - Inspired by Apple Liquid glass". It is intended for Mac users who want a compact, interactive presence on their screen that surfaces notifications and small everyday utilities in one place, rather than scattering them across separate apps and windows. The concept behind DynamicLake comes from Apple's Dynamic Island, the interactive element Apple introduced on iPhone that turns a small area at the top of the display into a live, changing surface for activities and alerts. DynamicLake translates that idea to the Mac. On Product Hunt the product is filed under the topics Mac, Menu Bar Apps and Apple, which places it in the family of small Mac utilities that live persistently on the desktop or in the menu bar area so they are always within reach. The appeal of such tools is that they reduce the friction of switching contexts: instead of hunting through windows or opening a separate application, users can glance at a single spot and interact with what is happening right there. Live Activities and notifications are central to the product. The Product Hunt tagline highlights "3rd Live Activities", indicating that third-party Live Activities are part of what DynamicLake displays, and the official description lists notifications as one of its main capabilities. The website's FAQ devotes specific questions to this area, including "How does Dynamic Lake Pro handle my notifications?" and "Will there be new features added to DynamicLake Pro?", which shows that notification handling is treated as a core part of the Pro experience. For a Mac user, having notifications presented in a single, consistent, island-style surface means the most relevant updates stay visible and actionable without covering the work in progress. Beyond notifications, DynamicLake bundles a set of small everyday tools. The product description names plugins, drag and drop, a converter and a timer. A converter and a timer are the kind of utilities that are frequently needed for a few seconds at a time and then abandoned, so placing them inside an always-accessible island removes the need to open a dedicated app or a web page for each one. Drag and drop suggests that items can be moved onto the island directly as part of the workflow, and plugins indicate that the surface can be extended with additional pieces of functionality. The tagline's "and more" leaves room for further tools within the same interface. Communication and file transfer features also appear in the description: calls and AirDrop. Calls listed alongside the other capabilities implies that call information or call handling is surfaced through the same Dynamic Island interface, keeping it visible while the user continues working. AirDrop being included points to dragging files onto the island to send them, or receiving them, through Apple's own transfer mechanism. The FAQ also references "DynaMusix" in the question "Does DynaMusix support all music apps?", which indicates a music-related component associated with the product. Visually, the site states the design is a Liquid Glass design inspired by Apple Liquid Glass, giving the interface a translucent, modern look that sits alongside macOS. Overall, DynamicLake works as a persistent, interactive layer on the Mac that is modelled on Apple's Dynamic Island. Rather than being a single-purpose utility, it acts as a container: Live Activities, notifications, a converter, a timer, calls, AirDrop and plugins all flow through the same island-shaped surface, and the Liquid Glass styling keeps it visually integrated with the system. The website's FAQ shows that the team thinks about the practical details of running the app day to day, covering which macOS versions are supported, whether it works on non-notch MacBooks, whether it supports external displays, and whether it is compatible with the BetterDisplay app. There are also questions about updating the app to the latest version and what to do when a bug is encountered. The benefits follow from that design. Placing frequently needed information and mini-tools in one persistent spot reduces app switching and keeps the user's attention on the task at hand. Notifications and Live Activities remain glanceable instead of interrupting with full-screen or modal interruptions. Small jobs such as converting a value or starting a timer no longer require leaving the current window. Communication cues for calls and file transfers arrive in the same place. Because it is inspired by Apple's own Dynamic Island and Liquid Glass design language, the experience feels familiar to anyone who uses an iPhone, while remaining a native-feeling part of the Mac desktop. Concrete situations the product is suited to include monitoring ongoing Live Activities while working in other applications, keeping notifications under control in a single island surface, running a quick conversion without opening another tool, timing a short task, managing calls so that call information stays visible during work, and sending or receiving files through AirDrop from the same interface. The FAQ also raises external displays and non-notch MacBooks, which correspond to the common setups where users would want the island to remain usable: a MacBook with an external monitor, or a Mac model that does not have a notch at the top of its built-in display. The music-app question tied to DynaMusix points to another scenario, listening to music while working. On requirements and practicalities, the FAQ covers which macOS versions are supported and whether DynamicLake works on non-notch MacBooks, so compatibility with a range of Mac hardware is part of the pitch. It also asks about external display support and BetterDisplay compatibility. The app appears to be a paid product with a Pro tier: the FAQ asks whether DynamicLake can be tried before purchasing, whether payment can be made with PayPal, and how DynamicLake Pro can be activated on multiple devices. New features are also signalled, with the site asking whether more will be added to DynamicLake Pro. Language support is another documented question. On the technical side, the site notes that the software uses code of FFmpeg licensed under LGPLv3.0. The site carries a 2025 copyright for Aviorrok, and the FAQ also clarifies that AppleLake or Dynamiclake.net are not the same as DynamicLake. In summary, DynamicLake 2.0 takes the Dynamic Island idea that Apple popularised on iPhone and carries it to the Mac, combining third-party Live Activities, notifications, plugins, drag and drop, a converter, calls, AirDrop and a timer into one Liquid Glass-styled surface. For Mac users who want their alerts, activities and small utilities in a single always-available place, it offers a focused, Apple-inspired way to keep that information close at hand.

Anthropologic is a zero distance consumer research platform that reads the whole internet through its Human Context Protocol to uncover consumer, category and cultural truths. It is built for people who need consumer understanding that is both fast and deep: research, innovation, marketing and foresight teams who cannot wait weeks for fieldwork but also cannot act on shallow social listening. The platform covers 239 markets and more than 100 languages, and it organises its capabilities into nine workflows, each aimed at a different type of question — what is moving in a category, what people think and feel, how segments behave online, what futures are probable, how creative performs, how a brand is read across social, search and LLMs, and where a brand can stand within a market's cultural codes. The promise is straightforward: research, innovation and foresight answers in minutes. Traditional research is deep but slow. Social listening is fast but shallow. LLMs are fluent but culturally blind. That is how Anthropologic frames the state of consumer insight, and it is the gap the platform exists to close. Deep research — surveys, ethnographic work, segmentation studies — produces trustworthy understanding, but it arrives on a timeline that rarely matches the pace at which categories move. Social listening moves at the speed of the feed but tends to capture volume and sentiment rather than meaning, leaving researchers to guess at the cultural logic underneath. Large language models can generate convincing text about consumers, yet by the platform's own description they lack cultural grounding, so their fluency masks a blindness to the codes that actually govern a market. Anthropologic positions itself between these three approaches: fast like listening, interpretive like research, and grounded in cultural context rather than surface fluency. For teams making decisions about products, positioning and communication, that combination matters because the cost of being slow is measured in missed trends, and the cost of being shallow is measured in misread consumers. The first group of workflows answers the question of what is happening. Trends shows what is moving in a category, pairing social proof with search patterns so that a signal is visible both in conversation and in demand. The live trend examples shown on the site make the shape of the output concrete: a search volume for alcohol-free club nights in the UK, a multiple showing how many scents now sit in a wardrobe where a single signature perfume once did, the number of US stores stocking overnight oats, or a search rate for Filipiniana bridal looks. Discourse goes a layer deeper and covers what people think, say and feel, mapping the positions, tensions and narratives inside a conversation rather than stopping at sentiment. Digital Segmentation takes the behavioural record and turns it into psychographic segments based on online behaviours, so teams can see not only that a category is moving but which kinds of people are moving it and with what mindset. Once a team knows what is happening, the next group of workflows helps it look forward and test. Foresight Simulator uncovers probable future scenarios reshaping a category, giving innovation and strategy teams a structured way to consider what comes next instead of relying on a single forecast. Synthetic Survey simulates consumer responses at scale using cultural ontologies, which allows researchers to explore how different audiences would respond without running a full field study for every hypothesis. Creative Evaluation scores a video ad for cultural strength across grounded signals, endorser and pillars, turning creative judgement into something that can be assessed against cultural evidence rather than taste alone. Together these workflows cover the middle of the research process: the stage where teams need to stress-test ideas, creative and scenarios before committing budget to production or media. Interpretation comes next. Ask an Anthropologist interprets an insight using cultural codes, giving teams a way to ask what a signal actually means rather than only what it says. Brand Performance shows how a brand performs across Social, Search and LLM, extending brand tracking into the place where many consumers now form impressions — the answers language models give. Cultural Semiotics reads a space in a market: the codes that govern it, the tensions between them, and where a brand can stand, which is directly useful for positioning work. The site also lists Innovation as coming soon, described as identifying opportunity spaces through convergence modelling and developing novel concepts, alongside a Research Thinking section where longer-form perspectives are published, with example essays such as 'Death of the Sugar High', 'Future of Fashion is Value', 'Medicalized Mouth', 'Beyond Classrooms' Four Walls' and 'Redesigned: Future of Aging'. The overall approach is what Anthropologic calls the Human Context Protocol: the platform reads the whole internet, rather than a single social network or a survey panel, and interprets what it finds through cultural context instead of raw keyword matching. Nine workflows sit on top of that reading, each packaged as a launchable tool with a defined question and a defined output, so a researcher does not have to assemble a methodology from scratch. Coverage is broad by design — 239 markets and 100+ languages — which means the same method can be applied across geographies and language communities rather than only in the markets where a team happens to have local researchers. The workflows range from descriptive (Trends, Discourse, Digital Segmentation) through projective (Foresight Simulator, Synthetic Survey, Creative Evaluation) to interpretive (Ask an Anthropologist, Cultural Semiotics) and diagnostic (Brand Performance). The through-line is that every output is meant to be grounded in something observable — social proof, search patterns, online behaviours, cultural codes or ontologies — rather than in a model's unaided opinion. The stated benefit is speed without sacrificing depth: research, innovation and foresight answers in minutes. For a category team, that means trend questions can be answered while a campaign or product decision is still open, rather than in a retrospective deck delivered after the moment has passed. For innovation teams, probable future scenarios and simulated consumer responses reduce the cost of exploring many hypotheses before narrowing to the few worth real investment. For brand and marketing teams, scoring creative for cultural strength and tracking performance across social, search and LLM gives a more complete picture of how a brand is actually being read. And because the platform works across 239 markets and 100+ languages, the same questions can be asked consistently in many places at once, which is difficult to do with traditional fieldwork and easy to get wrong with a culturally ungrounded model. The result is fewer decisions made on instinct alone and fewer insights that arrive too late to use. Concrete scenarios follow from the workflow list. A beauty or fashion brand tracking a new behaviour — the site's own examples include Gen Z fragrance, secondhand shopping, slow fashion and beauty after GLP-1 — would use Trends to see whether the movement shows up in both conversation and search, then Discourse to understand the narratives around it, and Digital Segmentation to identify which psychographic groups are driving it. A creative team preparing a video ad would run it through Creative Evaluation to score its cultural strength against grounded signals, endorser and pillars before committing media spend. A strategy team planning ahead would use Foresight Simulator to unpack probable future scenarios in a category and Synthetic Survey to test how consumers might respond. A brand lead would use Brand Performance to compare how the brand reads across Social, Search and LLM, and Cultural Semiotics to understand the codes and tensions in a market and where the brand can credibly stand. A researcher holding an ambiguous insight would use Ask an Anthropologist to interpret it through cultural codes. The Research Thinking section shows how those outputs are turned into published perspective pieces across topics such as fashion, education, wellness, entertainment and sportswear. Anthropologic is aimed at research, innovation and foresight functions — the product description names research, innovation and foresight answers explicitly — as well as the marketing and brand teams that consume that work. The scope is global by default: 239 markets and 100+ languages, covering categories visible in the platform's own examples, such as beauty, fashion, travel, fitness, food and drink, entertainment, education, wellness, pets and motherhood. No pricing or plan details appear on the page, and no specific third-party integrations are listed; the data domains the product describes are Social, Search and LLM, plus the platform's own cultural ontologies and semiotic codes. The product is delivered on the web at anthropologic.quilt.ai, and its Product Hunt listing categorises it under Marketing, Artificial Intelligence, and Data & Analytics. Anthropologic's core proposition is zero distance: closing the gap between a consumer signal and the decision it should inform. By combining a Human Context Protocol that reads the whole internet with nine purpose-built workflows spanning 239 markets and 100+ languages, it offers research depth at listening speed — trends with social proof and search patterns, discourse with tensions and narratives, psychographic segmentation, foresight scenarios, creative scoring, synthetic surveys, cultural interpretation, brand performance across social, search and LLM, and semiotic reading of a market. The takeaway is that cultural context, not fluency alone, is what makes consumer insight usable.
Thoughts for Mac is a native macOS menubar application for capturing notes, images, and voice recordings without leaving what you are doing. It sits in the Mac menubar, and a single click opens it so you can quickly save whatever is on your mind. The app captures structured text notes, checklists, code blocks, standalone links with previews, voice recordings, images, and text-like files such as TXT and CSV. It is presented as a small multi-tool for the menubar, and it is free to download and use, with all future updates included and no subscription. Because it lives alongside your other menu bar icons, it stays within reach while you work in other applications. The thinking behind Thoughts for Mac is speed of capture. Rather than opening a full note-taking application, creating a document, and finding a place to file it, the app puts a capture surface in the menubar where it is always one click away. The website frames this simply: Thoughts sits in your menubar, you click it anytime and anywhere, and you quickly save what is on your mind. That makes the app useful for the moment a thought, link, image, or spoken idea appears in the middle of other work. It also supports captures that arrive from outside the app itself: desktop builds can receive shared text, images, and audio through URL schemes, open-with actions, macOS Services, and native imports, so content can be sent to Thoughts from elsewhere on the system. The core capture experience covers the three input types the website presents as Write it, Drag in an image, and Talk to it. Writing produces structured text notes, and the app also handles checklists, code blocks, and standalone links that carry previews. Dragging an image in saves the image itself as a note, and screenshot capturing is listed among the app's capabilities. Talking records voice, which becomes a voice note that can later be transcribed with your own AI provider key. Beyond those interactive paths, Thoughts also accepts text-like files such as TXT and CSV, and on desktop it can take in shared text, images, and audio from URL schemes, open-with, macOS Services, and native imports. Voice recordings can be exported as MP3 in the desktop app whenever you want them. AI is optional and brought by you. In Settings you can connect OpenAI, Claude, or Gemini with your own API key. Once connected, the app can transcribe voice notes, context images to text, and perform simple text transforms such as capitalization, translations, spelling fixes, shortening, lengthening, summarizing, and converting case. The website also lists extracting text from images among the available actions. Claude is available for text actions, while transcription support depends on the provider you connect. Only AI-powered actions require a key: capturing notes, images, and audio does not need one. The app is free, and you use your own OpenAI, Gemini, or Claude API key for features like transcription, OCR, summaries, translations, and rewrites. Organizing what you capture is handled by search and pinning. Search works across notes, links, screenshots, and image names instantly, so a note can be found even when you only remember part of an image's name. Pinned Thoughts let you keep important notes at the top of your list so they are not buried under newer captures. The app also supports light and dark mode and adapts to whichever you prefer. Instant access is provided by a custom shortcut of your own choosing, meaning you can open Thoughts from anywhere on your Mac with a keystroke rather than reaching for the mouse. Thoughts works as a local-first menubar utility. In the desktop app, notes and settings are saved locally on your Mac, and media files are stored in the app's user data folder, with no account required. That means there is no sign-up step and no server-side account to manage for the core experience; AI actions are the exception, since they rely on the API key of the provider you connect. A browser preview mode also exists, but it is session-only, so notes created there are temporary. The free model and the bring-your-own-key approach combine to keep the tool light: you pay nothing to download or use it, including future updates, and you decide separately which AI provider, if any, powers the optional text and audio actions. Export and sharing are built in, so what you capture is not locked in. You can share notes as text, and you can export audio recordings whenever you want them. If you ever decide to leave, you can export all notes from Settings as JSON, or export individual notes in the best available format: text notes as TXT, image notes as image files, PDF attachments as PDF, and voice notes as MP3 in the desktop app. Benefits stated on the site include instant capture from the menubar, quick access through a custom shortcut, search that reaches into images and image names, pinning for important items, and both light and dark appearance modes. Concrete workflows follow from the capture types. During a call or a meeting you can talk to Thoughts and keep the recording as a voice note, then transcribe it later with your connected provider. While browsing, you can save a standalone link with its preview, or capture a screenshot of something you want to keep. When you drag in an image, the app can extract text from it through OCR once an API key is connected, turning a picture of text into usable content. You can bring in text-like files such as TXT and CSV, jot checklists, or store a code block you want to find again. Text actions handle small chores — summarizing a note, fixing spelling, converting case, shortening or lengthening text, or translating it. On the Mac, other apps and system services can send text, images, or audio into Thoughts through URL schemes, open-with, macOS Services, and native imports. Thoughts for Mac is built for macOS users who want a fast place to put thoughts, notes, links, images, and voice memos without opening a larger note-taking app. The site lists its topics as Productivity, Writing, and Menu Bar Apps. Integrations are limited to the AI providers you connect — OpenAI, Claude, or Gemini — using your own API key, and to macOS system entry points such as URL schemes, open-with, macOS Services, and native imports. Pricing is straightforward: the app is free to download and use, including future updates, with no subscription; the only cost you may incur comes from the API provider whose key you use for AI features. The download is delivered through the linked Gumroad page, and the app is native to macOS. Thoughts for Mac keeps capture at the edge of your screen: a menubar click or a custom shortcut, a written note, a dragged image, or a spoken thought, all saved locally with no account required. Search, pinning, export, and light and dark modes make the notes usable afterwards, while optional bring-your-own-key AI actions add transcription, OCR, summaries, and translations through OpenAI, Claude, or Gemini. It is free, and every feature is available at no cost with future updates included.
tiun. is the AI-native backend for builders, positioned as one system for authentication, payments, a customer database, and analytics. According to the website, tiun gives AI and SaaS companies the backend they need to ship, scale, and grow their business in one unified platform. Rather than assembling a stack of separate services, teams get a single place where user accounts, billing, transactions, and product usage data live together. The product describes itself as the backend powering the AI engineering era, built from an ecosystem of services that are designed to work together from the start. Its stated goal is to remove webhook logic and business logic that developers would otherwise have to write and maintain themselves, so a builder can launch a paid product the same day they start building. The problem tiun addresses is the hidden complexity created by single-purpose tools. When authentication, payments, customer data, and analytics each come from a different provider, teams end up juggling multiple accounts, scattered data, and costs that compound as they scale. Keeping those separate systems in sync requires maintaining business logic purely for the sake of consistency, and that maintenance burden grows alongside the business. The website notes that this fragmentation also makes the insights a company needs harder to reach, because the information required to understand customers, usage, and revenue sits in disconnected places. tiun's answer is an ecosystem of services designed to work together from the start, so there is no webhook logic and no business logic to handle just to keep tools aligned. The way to adopt tiun is described as installing its skills, connecting its MCP endpoint, and letting an AI agent do the hard work. The site provides a single command — npx skills add https://mcp.tiun.business — and links to documentation at docs.tiun.io. This integration path is highlighted by customers on the page: one founding member at Braintonic comments that it worked so well there was no backend, no webhooks, and no custom logic, while a founder describes integrating it for a side project as working like a charm and an absolute no brainer for future solo builders and founders. The significance of this approach is that it shifts setup work away from manual backend engineering and toward an agent-driven installation flow, which lowers the barrier for builders who want working infrastructure without writing and maintaining the usual glue code. tiun's authentication section aims to provide everything needed for user authentication. Sign up, login, and logout are ready to use out of the box, and the platform describes them as simple and secure. Beyond those basics, tiun supplies a User Button and User Profile, giving users a dropdown menu where they can access their account and manage their profile and security settings. Multifactor authentication is included, with SMS passcodes, email, and social SSO listed as supported methods. For a builder, this means the account layer that normally requires careful implementation — credential handling, profile management, and stronger sign-in options — is available as pre-built functionality rather than something to design from scratch. Payments are handled without the need to write payment code or wrangle webhooks. With tiun, builders can create products and billing plans and accept one-time payments, subscriptions, and usage-based billing from day one. Pre-built checkout components can be dropped in as an overlay, so users never leave the page during the purchase flow. tiun also acts as the Merchant of Record: it processes payments, pays out monthly, and includes tax compliance and chargebacks. The site states that this model brings better fees and more functionality, and its example pricing shows transaction fees of 2.9% + $0.30, for a total of roughly 3.4% + $0.30 on international transactions. The third part of the system is a customer database where every user, transaction, and session is stored in one place, with no syncing between tools. User management keeps customers' subscription status up to date and stored alongside their user data, removing the need to build or maintain complex synchronization logic. Advanced event and session tracking logs every login, purchase, and product interaction at profile level, so teams can understand how users move through the product. The same area covers transactional emails for key user actions such as confirmations, password resets, and purchases, invoice history that lets customers view and download receipts and invoices from their profile, and plan management so users can upgrade, downgrade, or cancel directly without a support ticket. Data APIs expose one queryable API built on a consistent model that stays in sync and is ready to plug into an existing stack. Analytics is presented as one system your entire team can work with, so the full picture is finally visible and actionable. All data lives in one place, letting business, engineering, product, and marketing see who is signing up, who is paying, how they use the product, where they get value, and how to price it. Because authentication, billing, and product events share the same underlying model, these questions can be answered from a single source instead of being stitched together across separate tools. The site illustrates the value with a case study: Res Publica reported a 21% increase in paying users and grew its user base by 21% in the last 12 months after introducing usage-based billing with tiun, as described by CEO Martin Stedler. Overall, tiun's approach is to treat authentication, payments, the customer database, and analytics as one connected system rather than four independent products. The website frames this as an ecosystem of services designed to work together from the start, which is why there is no webhook logic and no business logic to handle simply to keep systems in sync. Integration follows an AI-native path: install the skills, connect the MCP endpoint, and let an agent carry out the setup, with the command npx skills add https://mcp.tiun.business and documentation available for reference. Installation is described as one command, and the promise is that a builder can launch a paid product the same day they start building. The benefits follow directly from that consolidation. Teams avoid multiple accounts and scattered data, and they avoid the compounding costs that come with maintaining several single-purpose tools as they scale. Because subscription status, session activity, and transactions all sit with the user record, there is no synchronization logic to build or maintain. Customers can manage their own plans, invoices, and profiles, which reduces the need for support tickets. And because business, engineering, product, and marketing all read from the same data, the insights needed to understand signups, payments, usage, and pricing are reachable rather than buried in disconnected systems. tiun is aimed at AI and SaaS companies and the builders behind them, including solo founders and developers who want to launch a paid product quickly; commenters on the site describe using it for side projects. Typical scenarios reflect the product's shape: adding sign-up, login, and multifactor authentication to a new application; accepting one-time payments, subscriptions, or usage-based billing from day one; offering checkout as an overlay so users stay on the page; giving customers self-service control over plans, receipts, and invoices; and asking who is signing up, who is paying, and how to price the product from a single place. tiun can be tried for free, pricing details are published on its pricing page, and the platform is used through the web as well as its MCP and data APIs. tiun's core value proposition is consolidation: one system that supplies the authentication, payments, customer database, and AI analytics an AI or SaaS business needs, installed with one command and connected through MCP so an agent can do the heavy lifting. By removing webhook and synchronization logic and keeping every user, transaction, and session in one place, tiun promises to help builders ship, scale, and grow from a single backend — and start charging on day one.
Oats is a free, open-source meeting notetaker that records your meetings directly on your Mac — and on Windows in beta — without a bot joining the call and without sending your audio to a third-party cloud. When a meeting is over, Oats gives you a clean summary and a todo list you can actually work through, pulling out every action item along with who owns it, all from what was actually said. It is built for people who treat notes as the place a meeting's work starts rather than where it ends, and who want their recordings and AI processing to stay on their own machine. Oats is distributed as a desktop app, published openly on GitHub, and is free forever. Most note-takers want your recordings in their cloud. Many of them also join your calls as a visible bot, which can be awkward in external meetings and often needs host approval. Others put a paywall in the way — a seat count, a trial timer, or a limit that shows up around meeting number six. Oats was designed to not get in the way of your meetings: no bots, and no subscription needed when it runs locally with an on-device LLM. The product's stated principle is simple: your meetings stay on your machine. Oats records locally, runs AI locally, and never forces your audio off-device, while still offering richer cloud-backed features for people who want them. On-device recording is the foundation. Oats records directly from your Mac's audio — there is no browser extension, no bot, and no third-party server that ever touches the audio stream. It also works everywhere, because it captures any audio your Mac can hear: Zoom, Google Meet, Microsoft Teams, a phone call, or even a hallway chat. That means the tool does not depend on which conferencing platform a meeting happens in, and it does not require the meeting host to admit a recording bot before the conversation can be captured. After each meeting, Oats produces AI-written notes. These include a quick digest, a full summary, action items broken out per person, and a quality score derived from the conversation itself. In the app's own example, a weekly sync with three attendees and a #standup tag produces a quick digest noting the roadmap was at risk of slipping, that the team aligned on an August 12 ship date, and that Q3 pricing was locked — followed by two action items, one owned by Sarah (own the API rework, unblock by Friday) and one owned by Max (confirm the August 12 ship date with the PM), plus a meeting quality score. The result is a summary you can read in seconds and a task list that already names the owner. Action items are not left buried in a document. They collect in a Todos tab, and when you tick one off in the notes it closes, so follow-ups actually get followed up on. On the local backend, notes are plain Markdown and action items are stored as Obsidian Tasks inside a vault you choose — you can open the vault in Obsidian, sync it, or move it anywhere. Oats also lets you download a meeting's recording and export its notes wherever you want them in one click, and every meeting you record lands in a searchable library where you can ask questions across your whole history, such as what you decided about pricing. Oats works in three steps: hit record, get notes instantly, follow through. You start Oats and begin your meeting; it listens on your Mac with no bot and no third-party cloud, and nothing joins the call. When the meeting ends, Oats writes a structured summary and pulls out every action item with its owner. Those action items then land in your Todos, and ticking one off in the notes or in Obsidian closes it. You can run everything on-device with a local model and keep audio fully private, or connect your Ariso account for richer AI features — the Ariso.ai cloud backend adds enhanced transcription, multi-language support, speaker recognition, assessment, coaching, and auto-tracking of follow-ups. Speaker tagging matches each voice in a recording to the person who said it, so notes say who rather than "Speaker 2" (currently available on the ariso.ai backend), and you can sign in with Microsoft using your work account alongside Google from onboarding, Settings, or the menu bar. The benefits follow from that design. Because recording and AI notes can run entirely on your Mac with a local model, zero data leaves your device when you choose the local path. Because the software is free forever — no seats, no trial timer, no paywall waiting at meeting six — there is no cost barrier to capturing every meeting. Because it is fully open source on GitHub, you can audit every line, fork it, self-host it, or ship your own features on top. And because local notes are plain Markdown in an Obsidian vault, there is no lock-in: you can export anything, owe nothing, and leave whenever you want. In practice, Oats fits recurring team rituals and ad-hoc conversations alike. A weekly sync or standup becomes a digest, a decision log, and a per-person task list without anyone taking minutes. Calls that happen across Zoom, Meet, or Teams are captured the same way, since Oats listens to system audio rather than integrating with one platform. A phone call or an in-person hallway chat your Mac can hear can be turned into notes too. Afterwards, action items flow into a Todos list or into an Obsidian vault, and the searchable library lets you look back across your entire meeting history to answer questions like what was decided about pricing. Oats is aimed at individuals and teams who hold meetings on a Mac and want notes without a bot in the room, including people who care about keeping audio on-device and users who prefer open-source, self-hostable software. It also suits Obsidian users, since local notes are plain Markdown with Obsidian Tasks and can live in a vault of their choosing. Related integrations mentioned in the content include Google and Microsoft sign-in and the optional Ariso.ai cloud backend. Oats ships as a desktop download for macOS and Windows (beta), and pricing is free — free forever, with no seats or trial timer. Oats is a free, open-source, on-device meeting notetaker whose core promise is that your meetings stay on your machine. It records without a bot, writes summaries and owner-tagged action items from what was actually said, pushes follow-ups into Todos or an Obsidian vault, and lets you add cloud AI only if you want it.

Image to ASCII is a free, browser-based converter that turns a picture into a composition of characters. Users drop, paste, or choose a JPG, PNG, WebP, or GIF image — or load a built-in sample such as the neon jellyfish — and the tool renders it as text art in a live preview. From there they refine the output and either copy it as plain text or Markdown, or export it as TXT, PNG, SVG, HTML, or ANSI. It is made for developers, designers, and creators who need text-based artwork for README files, Discord servers, blog covers, terminals, and posters, and it works without a signup. ASCII art has always been a practical way to put imagery into places that only accept text: source files, README files, terminal screens, forums, and chat code blocks. The traditional route is a command-line utility, a script, or a lot of manual retyping, and the result often falls apart the moment it lands somewhere with a different font or line wrapping. Online converters solve part of that, but many require uploading a private image or creating an account first. This tool addresses both problems: the conversion happens inside the browser so the file never leaves the device, and the export options are matched to the destination, so the artwork keeps its shape whether it is pasted into a code block or shared as an image. The conversion runs locally. As the site puts it, images are processed locally and never uploaded — the image is read by the browser and converted with Canvas, so the file stays on the device. Supported inputs are JPG, PNG, WebP, and GIF, provided the browser can decode them; a GIF conversion uses the frame the browser provides, which means the output is a still result rather than an animation. Users can upload a file, paste an image, or start from a sample and replace it later. Because nothing is transmitted, the tool suits portraits, logos, and other images that should not leave a personal machine. Width and character set are the two controls that decide how much detail the artwork carries. The ASCII width can be set from very compact output — 56 columns for a Discord mascot — up to 220 columns for detailed studies. Fewer columns produce bolder characters; more columns produce finer detail. Character ramps determine the texture of the result: Detailed uses a smooth photo ramp, Dense uses @%#*+=-:. , Blocks uses Unicode symbols, Simple uses #*+=-. , and Minimal uses @. . According to the FAQ, making art more detailed means increasing the ASCII width, choosing the Dense character set, and raising contrast slightly, since detailed photos often need more width than simple icons. Advanced tuning gives control over light, texture, and background: tonal balance, brightness, contrast, sharpen, saturation, background cleanup, and dither, plus an invert toggle. The interface shows starting values such as tonal balance 1.25, brightness 0, contrast 8, sharpen 18, saturation 110, and background cleanup 99%, with dither available as a separate switch. Tonal balance is described as a way to recover midtones without clipping the extremes. These controls sit close to the preview so every change is visible immediately in the live canvas, which can be viewed as paper or as characters, expanded, and compared against the original image. Presets cover two kinds of starting points. Visual style presets — Auto, Neon, Pixel, Gallery, Fine Art, and Portrait — set a look, while destination presets — Logo, README, Terminal, Social, and Poster — are tuned for where the artwork will end up. The site also publishes practical recipes: Portrait uses a detailed ramp with dither on, mild sharpen, and medium contrast; Logo uses the Blocks style at a smaller width with high contrast and dither off; README uses a simple ramp around 80 columns followed by Copy README or Copy Markdown; Terminal uses 80 columns with clean light backgrounds and exports ANSI or TXT; Social uses 56 columns for chat code blocks or PNG export when spacing may collapse; and Poster uses a wider 200-column output exported as PNG, SVG, or HTML. Presets are starting points, not platform limits. Color is handled separately from structure. Color output uses sampled image colors, and color is preserved in PNG, SVG, HTML, and ANSI exports, while TXT, Markdown, README, and comment exports remain plain so they stay valid inside code blocks. The plain text formats keep editable characters; the image formats preserve the visual appearance, which matters when a destination font would distort the letters. The site explains why colored ASCII does not work in TXT: text files store plain characters, not per-character colors, so PNG, SVG, or HTML should be used when the colored preview needs to travel with the artwork. Exports and copy actions are grouped so the common path is one click: Copy Plain, Download TXT, Download PNG, Copy Markdown, Copy README, Copy Comment, Copy ANSI, Copy Share Caption, Download SVG, Download HTML, and Download ANSI. A typical workflow is three steps — upload, paste, or try a sample; choose a preset and fine-tune width, style, dither, sharpen, and color; then copy plain or Markdown ASCII or download TXT, PNG, SVG, or HTML. A before/after comparison slider makes it easy to check the original against the characters, and a gallery of example studies (Chrome muse, Silk in motion, Into the light, and Electric deep) can be loaded with their settings so users can see how each result was produced. Under the hood, the converter reads the brightness and detail in a picture and maps them to text characters, so light, shadow, and form become a graphic text landscape. It compensates for tall text cells when sampling the image so the result is not stretched, which is why changing the column width changes the level of detail rather than the character proportions. Because spacing is what keeps ASCII art readable, the tool advises using a code block to preserve spaces or exporting PNG when the destination changes the font, and it recommends keeping the result in a monospace font with line breaks intact. For READMEs it suggests starting around 70 to 90 columns with the README preset so the art fits code blocks on laptops and mobile screens. Three purpose-built destinations show how settings and export choices line up. For blogs and editorial work, a glass flower is rendered at 200 columns with the Detailed ramp and color, then exported as PNG or SVG so the character texture and colors survive, while the headline stays in the blog editor so it remains readable and searchable. For GitHub, a geometric fox becomes an 80-column Simple monochrome mark whose clean outline stays recognizable at small size, copied with Copy README for a fenced text block while the project name and links stay outside the artwork. For Discord, a ghost mascot is rendered at 56 columns in the Dense style and copied as Markdown so spacing holds in a code block, or exported as PNG when the message would wrap or clip. Beyond those, the tool lists code comment artwork, terminal welcome screens, forum text art, profile images, posters, and landing accents. Image to ASCII is aimed at developers, designers, and creators who publish in text-first environments, and it is free to use with no signup. It runs as a web application with a mobile-friendly workbench, so upload, tuning, copy, and export actions stay reachable on small screens. The workbench includes single-click samples, the before/after comparison, a character-oriented preview, and links to dedicated guides for blog ASCII covers, GitHub READMEs, and Discord messages, so users can follow a documented path instead of guessing at settings. The takeaway is that Image to ASCII turns an ordinary photo, logo, or illustration into text art without giving up control or privacy. Conversion happens locally in the browser, the controls beside the live preview make every setting's effect visible, presets and guides cover the destinations people actually publish to, and the export formats — TXT, PNG, SVG, HTML, and ANSI — let the same artwork travel either as editable characters or as a faithful colored image.

Web Search Agents by Nimble are self-learning agents that become experts at your specific research task. They are web crawling and research agents built for a specific domain — company enrichment, regulations research, and other focused use cases — and they crawl the web with surgical accuracy. Instead of returning generic results, the agents self-learn your use case to go deeper into the sources that matter most to you, giving your AI deeper and more relevant web context. The product is aimed at agent builders and teams that need expert-level web search for their AI agents, delivering higher accuracy at a fraction of the token cost. You can start by giving your AI the Nimble agent onboarding link, start building for free, or book a demo with the team. Web search is usually judged on generic benchmarks that do not resemble the queries a real agent builder faces. Nimble evaluates web search by domain instead, because that lets agent builders judge solutions against queries that resemble their own rather than generic benchmarks. Nimble argues that specialized intelligence needs a specialized web search, and invites teams whose domain is not listed to contact the company to see how Web Search Agents adapt to their use case. A second problem is cost: retrieving web context typically means redundant searches and parsing raw pages with an LLM, which consumes tokens. Nimble positions Web Search Agents as a way to retrieve exactly what is needed — with no redundant searches and no parsing of raw pages with an LLM — so teams get expert-level web search for their AI agents with higher accuracy at a fraction of the token cost. Web Search Agents are built to execute hyper-specific research workflows, crawling the web with surgical accuracy for the task at hand. They can also build and enrich web datasets: you define your schema and the agents return consistent results on every run, which makes it practical to assemble structured web data without manual cleanup. A monitoring capability, currently in beta, lets you continuously track any data point on any webpage in real time, so changes on the web surface as they happen. Together these three capabilities — hyper-specific research, schema-driven dataset building, and continuous monitoring — cover the common shapes of web data work an agent needs to perform, from answering a single research question to maintaining a dataset that stays current. Three capabilities underpin how the agents adapt to your use case and self-improve. First, compounding domain knowledge: the agents accumulate web context over time to master your domain, so their understanding of relevant sources grows with use. Second, deep web access for your sources: the agents combine web search with domain crawling to reach subpages that other tools cannot access, which matters when the useful information sits deeper than a top-level page. Third, full control over search methodology: the agents retrieve data within the scope and guardrails defined by your search plan, so you decide what is in bounds. Nimble summarizes this as agents that adapt to your use case and self-improve, rather than behaving the same way for every customer and every query. Governance is part of the design. Web Search Agents operate with full governance and control through auditable Search Plans that show exactly what was searched, where, and why — so you can inspect the path the agent took rather than trusting an opaque set of results. Accuracy compounds over time through a Proprietary Index and Memory that gets smarter with every query, meaning the agents retain and reuse what they have learned. The same retrieval discipline addresses cost: by retrieving exactly what is needed, the system avoids redundant searches and avoids the expense of parsing raw pages with an LLM. These three elements — auditable Search Plans, compounding memory, and precise retrieval — are the core promises Nimble makes for expert-level web search delivered to AI agents. The overall approach is that the agents self-learn your use case. Rather than being configured once and left static, Web Search Agents learn from the searches they run, building a memory and a Proprietary Index that improve the relevance of later results. They combine two access paths — web search and domain crawling — to reach both broad results and the deeper subpages that other tools cannot access. Each retrieval stays inside the scope and guardrails you define for the search plan, and every search is recorded so you can audit what was searched, where, and why. Nimble describes this as specialized intelligence for a specialized web search, and documents an onboarding path so your AI agent can be pointed at the product and begin building. The stated benefits concentrate on accuracy and cost. Nimble says Web Search Agents deliver expert-level web search for your AI agents with higher accuracy at a fraction of the token cost. Because retrieval returns exactly what is needed, there are no redundant searches and no need to parse raw pages with an LLM — two of the main sources of token spend in agentic web research. Accuracy compounds over time as the Proprietary Index and Memory get smarter with every query, so results improve rather than plateau. Control and trust are the other stated outcomes: auditable Search Plans show exactly what was searched, where, and why, and the agents work within the scope and guardrails you set, which makes it easier for teams to explain how a result was produced. Nimble publishes cookbook examples of what teams can build. Company research and due diligence can be run from a single prompt at audit grade. Teams can research case laws and regulations, enrich dependencies with health indicators, and find assortment gaps on the digital shelf. Retail and brand teams can find where products are sold to enforce MAP compliance, and go-to-market teams can discover businesses that match an ideal customer profile. Finance workflows include tracking analyst earnings predictions against actuals, and recruiting workflows include building a dataset of job candidates. Nimble also names the domains it evaluates and adapts to: market analysis, real estate, social media monitoring, travel and hospitality, company research, finance, product intelligence, and GTM. In those benchmarks, contestants independently completed 96 tasks per domain — covering reports, enrichment, and discovery — with each result graded fact-by-fact by an independent AI judge against a gold standard built without any contestant's input. Web Search Agents are aimed at agent builders and teams that need their AI agents to research the web reliably. Nimble says it is trusted by organizations including Databricks, Qudo and Uber under a "Trusted By" heading, and its site also displays a broader logo wall featuring brands such as Microsoft, Coca-Cola, L'Oréal, LG, TripAdvisor, Semrush and Browserbase. Native integrations are offered including Anthropic, GPT, LangChain and Vercel, and the product is documented as a Nimble SDK with an agent onboarding page you can give to your AI to get started. Security and compliance features include zero data retention, flexible PII masking, audit logs, data encryption in transit, and no training, alongside CCPA, GDPR and SOC 2 badges. Nimble invites teams to start building for free, try the product now, or book a demo to discuss use cases and see how Nimble delivers higher accuracy at a fraction of the token cost. For teams building AI agents that need reliable web context, Web Search Agents by Nimble offer a self-learning approach: agents that adapt to your domain, crawl the web with surgical accuracy, build and enrich datasets against your schema, and monitor pages for change. Auditable Search Plans provide governance, while a Proprietary Index and Memory compound accuracy over time and precise retrieval reduces token cost. The result is deeper, more relevant web context for your AI, evaluated by domain against queries that resemble your own rather than generic benchmarks.

LLMagnet is the official WordPress plugin that makes a website visible and understandable to AI assistants such as ChatGPT, Claude, Perplexity and Gemini. It tracks visits from AI bots in real time, gives insights into how language models interpret your content, measures an AI Visibility Score, automatically generates llms.txt files and manages schema.org structured data so that models can accurately read, cite and act on your pages. The product is made by web creators and built for agents and marketers, helping brands build a measurable presence in the AI ecosystem instead of guessing how AI search treats them. Search behavior is shifting. People increasingly ask AI assistants directly for answers, recommendations and products, so the traffic that matters no longer arrives only from classic search engines. AI crawlers and assistants fetch, parse and summarize pages on their own terms, and llms.txt is described by LLMagnet as an emerging standard, like robots.txt for search engines, that helps AI models understand a site's structure and content. Without that guidance, and without any data about which bots visit and what they read, site owners are essentially blind to how AI represents them. LLMagnet closes that gap by giving websites an AI visibility layer: real-time analytics on AI bot activity plus the files and schema data that make content easier for models to read, rank, connect with and trust. It turns an opaque new channel into something that can be watched, measured and improved. The core of the plugin is LLM Analytics, which tracks real AI-bot traffic and reports detailed insights into visits, impressions and clicks coming from major models including ChatGPT, Gemini, Claude and more. LLMagnet detects visits from ChatGPT, Claude, Perplexity, Gemini, Grok, Bing AI, Mistral, DeepSeek, Llama and others. Sitting alongside the raw traffic numbers is the AI Visibility Score, a single metric that reflects how well large language models can access and understand your content across the web. Trends & Insights then tracks that visibility over time so you can spot rising opportunities and content drops instantly, turning scattered bot activity into a picture of whether your AI footprint is growing or decaying. To make a site AI-ready, LLMagnet automatically builds and maintains an llms.txt file so AI crawlers can better understand site structure and content focus, and it keeps that file up to date without manual work. Depending on the plan, it also generates a Full-llms.txt and .md files. The plugin manages schema.org structured data as well, which helps AI assistants accurately read and cite pages. Because llms.txt is positioned as robots.txt for AI, it acts as a signpost for crawlers; generating it automatically means site owners do not have to research the format, write the file or remember to refresh it whenever content changes. Prompt Tracking & Optimization shows where your brand actually appears in AI answers. LLMagnet tracks the prompts that mention your site and shows how your ranking evolves over time, including which prompts include your brand, how visibility shifts by LLM, and what to improve next. Alongside this, Automated Reports & Insights sends weekly and monthly reports that summarize your visibility and growth, with auto performance reports, visual traffic breakdowns and actionable visibility tips. Together these features move the product beyond measurement into guidance: you can see not only that AI assistants are reading your pages, but which questions bring you in and where you are missing. For stores, LLMagnet is positioned around the future of AI-driven commerce. It turns a shop into AI-ready content by connecting to your product data so that AI can display accurate information in generative search, with auto product and price sync keeping details current, an AI-search visibility boost and product mention tracking. WooCommerce integration and product tracking are part of the Plus plan, and the FAQ notes that Plus and Enterprise plans add product visibility scores and AI revenue funnel tracking for WooCommerce stores. The result is that product listings, prices and brand mentions stay aligned with what assistants tell shoppers. Installing LLMagnet starts from the WordPress plugin directory: you enter your WordPress site and are redirected to your site's plugin installer so the plugin can be added in one click, with no setup or code required. Once active, it begins capturing real-time AI bot activity. The dashboard reveals which AI bots visit your site, what they read and how to improve your visibility inside AI answers through visual dashboards. Compatibility is broad: the plugin works with Elementor, Gutenberg, Divi, WooCommerce and more, runs alongside Yoast SEO and RankMath without conflicts, and integrates into the Elementor editor with per-page AI visibility scores and schema management. On WordPress 6.9 and later it connects directly to Claude, ChatGPT and Cursor via the WordPress Abilities API so AI assistants can query your site's data natively, and an MCP Connector is included in the plans. The approach is deliberately lightweight and privacy-safe: file generation and analytics run in the background, so there is no impact on front-end performance or page load speed, and bot visit analytics are stored locally in your WordPress database and never sent externally. Optional integrations are off by default, and the tool is fully GDPR-compliant with built-in data export and erasure tools. The stated benefits revolve around control and clarity. AI Visibility Control means knowing exactly how large models see your content; Smart Automation keeps llms.txt and your data always updated automatically; Deep Insights analyze which pages drive the most AI engagement; Enhanced Collaboration streamlines workflows with team-friendly features; Data Security safeguards your data with top-tier encryption; and Continuous Improvement lets AI adapt and improve with evolving data. In practice, users describe straightforward setup, clear understanding of AI-related traffic to their site, and a practical llms.txt generator that saved them time. LLMagnet is explicitly not framed as a magic SEO plugin, but as a solid tool for gaining visibility into how AI search is evolving. LLMagnet is aimed at web creators, marketers, solopreneur store owners and WooCommerce store managers who want to prepare for AI-driven discovery rather than react later. The free plan is available with no credit card required, and core features such as analytics, llms.txt generation and schema tools work on any WordPress site. Paid tiers add depth: Pro at $29 per month per site covering analytics from ChatGPT, Claude and Perplexity plus Full-llms.txt, .md files and an MCP connector; Plus at $100 per month per site with analytics from all bots, WooCommerce integration, product tracking and product visibility; and Ultra at $149 per month per user with prompt tracking and chat support. Yearly billing lowers those prices, and a Product Hunt launch offer advertises 50% off. A Shopify app is also available alongside the WordPress plugin. LLMagnet gives WordPress and Shopify sites a measurable AI visibility layer. By tracking AI bot traffic, scoring how well models can access your content, generating the llms.txt and schema data crawlers look for, and tracking the prompts where your brand appears, it converts an opaque new channel into something you can watch, report on and improve. For teams that want evidence of how AI assistants read, cite and recommend them, that combination of analytics, AI-ready files and prompt tracking is the product's core value proposition.
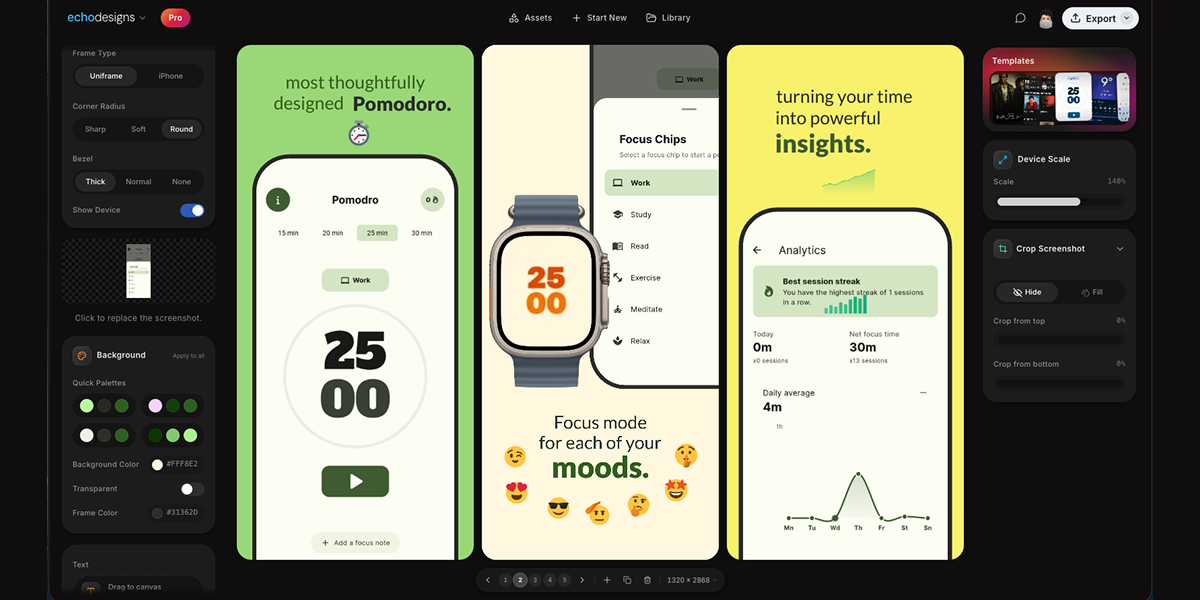
appdesigns is a free, in-browser editor for making App Store and Google Play screenshots. It is aimed at people who need to create app listing visuals, including app developers, designers, and marketers. The product's stated purpose is to help users design amazing app screenshots completely free. Users can drop in their screens, frame them in device mockups, add headlines, backgrounds and stickers, and export at the exact sizes App Store Connect asks for. The website emphasizes that no account is needed, there is no watermark, and exports are unlimited. The editor is accessed through appdesigns.click and is described as needing a laptop-sized window. The Product Hunt tagline says Design amazing appstore screenshots for free. The problem context is stated directly: many screenshot tools are free to start but then impose limits. appdesigns positions itself as truly free, not free to start. It highlights unlimited exports, no watermark, and no account required. This matters for app developers and teams preparing store listings because screenshots are a required part of presenting an app on the App Store and Google Play. The product removes sign-up friction and export restrictions, while keeping the creation process inside the browser. The metadata description says Make App Store and Google Play screenshots in your browser. Truly free, not free to start: unlimited exports, no watermark, no account required. The website also says support is appreciated but never required, reinforcing that the tool does not require payment to use its stated core capabilities. Device framing is a core part of the editor. The Device section lists Mobile, iPad, Mac, and Watch. Frame Type includes Uniframe and iPhone. Available device options include iPhone Duo, marked New; iPhone 18 Pro, marked New; iPhone 18 Pro Max, marked New; iPhone 17 Pro Max; and three more. Users can choose Portrait or Landscape orientation. There is a Show Device toggle, which lets users decide whether the device frame is visible. The product description also mentions framing screens in the latest iPhone, iPad or Mac. These options help users present screenshots in the context of real devices and match the type of app being shown. The Device section provides Mobile, iPad, Mac, and Watch options, while the Frame Type section offers Uniframe and iPhone choices. Uploading and customizing the screenshot content happens on the canvas. Users upload a screenshot, and the interface includes a Background section with Apply to all, Background Color, and Transparent. The background color example shown is #FF512F, and Transparent is an available choice. Text can be added directly to the canvas; users can click or drag to place it, or press T to place text. The Text section includes an Add text control and instructions: Click or drag to the canvas. Press T to place. The canvas displays slides numbered 1, 2, and 3, along with a canvas size of 1242 × 2688. These controls support adding headlines and visual treatments to app screens before export. Templates and transformation tools help shape the overall screenshot set. The website displays a Templates section with template artwork that users can browse. The Product Hunt description states users can start from a community template. Scale & Tilt controls let users adjust device presentation; the interface shows Scale at 135% and Tilt at 0°. The interface shows Scale 135% and Tilt 0° as example values, with the ability to adjust scale and tilt. The product description says users can design the whole set side by side, tilt and scale devices, or start from a community template. This combination supports creating a coordinated group of screenshots rather than editing each image in isolation. The overall workflow is explained in three steps: 1 Upload your app screenshots, 2 Choose a device frame, 3 Customise and export. This straightforward approach is presented as the main method for using the editor. Users begin with their own app screens, select a frame from the available device options, then customise with backgrounds, text, templates, scale, and tilt before exporting. The editor runs in the browser and the website notes that the editor needs a laptop-sized window, with a prompt to copy the link for your laptop. This indicates the tool is used in a desktop or laptop browser environment. Exporting is aimed at the exact sizes App Store Connect asks for, and the free offer includes unlimited exports, no watermark, and no account needed to start. Benefits and outcomes stated or directly implied by the content include creating app screenshots for free and without an account. The product removes the need to sign up before starting, and it does not add a watermark to exports, according to the website and metadata. Unlimited exports mean users can produce as many screenshot files as their listing requires. The in-browser editor avoids a separate desktop installation. The three-step workflow and community templates provide a guided path for users who may not be professional designers. The product also supports every device, every size, and no account needed, as stated on the website. Concrete use cases include preparing App Store and Google Play listing screenshots. A developer can upload app screens, frame them in iPhone, iPad, Mac, or Watch device mockups, add headlines and backgrounds, and export at required sizes. A designer or marketer can create a consistent set of screenshots side by side, using templates and background colour changes applied to all. A user who wants a device mockup without signing up can open the editor in a laptop browser, upload a screenshot, choose a frame such as iPhone 18 Pro or iPad, add text, and export. The editor also shows slides numbered 1, 2, and 3, which supports working with multiple screens in one session. The target users are app developers, designers, marketers, and teams who need store listing visuals. The product is designed for users who want a free, browser-based screenshot editor with no account required, no watermark, and unlimited exports. It supports Mobile, iPad, Mac, and Watch device frames and references exact export sizes for App Store Connect. Because the website states the editor needs a laptop-sized window, it is intended for use on a laptop or desktop browser rather than on a mobile phone. The website mentions support is appreciated, never required, but does not present it as a mandatory part of using the free editor. No pricing tiers, paid plans, or subscription details are stated; the pricing model is free. In summary, appdesigns is a free in-browser tool for making App Store and Google Play screenshots. It combines device frames, background controls, text, community templates, and scale and tilt adjustments with a simple upload, frame, customise, and export workflow. Its primary value proposition is stated clearly: amazing app screenshots for free, with no account, no watermark, and unlimited exports.
Naoma AI is an AI video sales agent that runs personalized product demos for B2B SaaS companies. It gives every prospect a live demo instantly, walking them through your product, answering their questions, qualifying them, and routing them to your CRM, calendar, or checkout. Naoma runs 24/7, starts demos in about 10 seconds, and speaks 33 languages, so buyers can explore your product in the language they think in, without scheduling a call or waiting for a rep to reply. The problem Naoma solves is the gap between a visitor's intent and a sales rep's availability. A typical book-a-demo button converts only 1–2% of visitors, and the rest leave. Prospects arrive across every time zone and in many languages, and a form means they must wait for a reply before they can see anything at all. In enterprise software, a single opportunity often involves multiple decision-makers across marketing, operations, IT, procurement, and management, each with different priorities, KPIs, and questions. Feature-rich platforms can also lose value in a self-serve trial, because people never discover what makes them powerful on their own. Naoma closes that gap by delivering a real, interactive demo at the moment of peak buying interest rather than after a scheduling delay. Naoma runs the entire product demo in four automated steps. First, a prospect on your website or in your app requests a product demonstration: there is no scheduling and no waiting, and the demo starts immediately. Second, the AI sales agent initiates a live, personalized demo tailored to the prospect's needs, industry, and role; it handles discovery, shows relevant features, and answers questions. Third, every qualified lead is sent straight to your CRM, and Naoma can book a meeting with your sales team or send high-intent buyers to checkout, with no manual handoff. Fourth, Naoma surfaces insights your buyers never tell a rep: competitors, objections, questions, and feature requests, giving sales, marketing, and product teams intelligence rather than just revenue. Hyper-personalization is central to how Naoma behaves. Every demo adapts to each customer's needs and context, and Naoma learns your product from your sales scripts, demo recordings, knowledge base, sales presentations, and demo environment, so it is positioned to handle even complex technical questions better than your reps. Demonstrations can be delivered through your website, in-app, or in outbound emails, so prospects get demos exactly when they need them. The agent remembers returning visitors and picks up where they left off, and every session is written back to your CRM, keeping the record of each conversation in one place. Language is handled natively. Naoma speaks 33 languages because buyers prefer to explore in their native language, and removing that friction helps every prospect understand your product and its value in the language they think in. Named agents illustrate the range: Alexandra Chen, VP of Sales, for English; Carlos Rodriguez, Head of Customer Success, for Spanish; and Sophie Martin, Product Marketing Director, for French. Customers report qualifying prospects in more than 10 languages they could never staff for. Avatars let you give demos a face that fits your brand. You can choose the signature Naoma agent, a branded mascot, or a static realistic avatar created from a real photo. Naoma adapts to your brand and creates memorable demo experiences while keeping the visual identity consistent with how you present your company. Naoma reports measurable quality from real end-user feedback across live AI demos. 89% of end users mention how human the experience feels, fewer than 2% of sessions hit any technical issue, and 77% of end users praise how it handles interruptions. The product is rated 4.9 on G2 by verified B2B SaaS reviewers, and it is GDPR compliant, protecting both your data and your customers' information with enterprise-grade security. The commercial outcome teams highlight is conversion from traffic they already have. Typical visitor-to-demo conversion is 1–2%; with Naoma, visitor-to-AI-demo conversion reaches 6–20%, so teams capture more qualified leads without increasing spend. Same traffic and same budget produce more demos and more qualified leads. Naoma's own product page illustrates the moments it covers: a VP of Sales at TechScale requests a demo at 11:42 PM and completes it at 11:42 PM, a Head of Marketing at CloudNexus requests one at 3:15 AM, a founder at DataViz at 8:23 PM, and a Director of Operations at SyncWare at 5:07 AM. The same flow is shown across growth stages — emerging, growth stage, scale-up, and established — with qualified customers produced in different regions. The point is straightforward: buying interest does not keep office hours, and Naoma is available whenever a prospect is ready. Naoma is used by B2B SaaS teams across many product categories. AiSDR, an AI sales development platform, uses Naoma to run personalized demos for website visitors, aiming to attract more qualified leads and book more product demos without adding sales headcount. UXPressia, a collaborative customer journey mapping platform, uses Naoma to give visitors a real interactive demo of its journey maps, personas, and AI persona builder, qualifying them around the clock. Hoteza, a web-based guest engagement platform for hotels, placed Naoma right after its book-a-demo form and behind a "Get AI demo now" button; since April, 57 hotels explored the product this way, and one regional partner signed after going through the AI demo. Mellow, which helps companies hire, manage, and pay freelance contractors across 150+ countries, uses Naoma to run personalized demos for its visitors. App Radar, an app store optimization platform, uses Naoma to qualify visitors and surface larger accounts worth routing into a sales-assisted funnel. Verified G2 reviews describe how teams use it day to day. A CMO at Hoteza noted that enterprise hospitality software involves long, complex buying processes with decision-makers across marketing, operations, IT, procurement, and management; Naoma lets each stakeholder explore the product independently, ask questions in context, and revisit specific features between meetings, reducing sales workload while keeping prospects engaged. A founder at UXPressia said its deep, feature-rich platform did not always come across in a self-serve trial, and that Naoma greets visitors, runs a real interactive demo of journey maps, personas, and the AI persona builder, and qualifies them around the clock. Another reviewer described Naoma as an additional source of leads that provides qualification information and effectively does discovery, freeing the sales team to focus on higher-value conversations. Naoma is built for B2B SaaS teams that want to convert more of their existing website traffic without adding sales headcount. The product is now self-serve: teams can upload their product and knowledge base and test the agent themselves, and a separate app is available to build your agent, along with an ROI calculator. Naoma has run 50,000+ demos for B2B SaaS teams, holds Product Hunt daily and monthly top-post awards plus a Tekpon Top Demo Automation Software Q1 2026 recognition, and was named in a Global Startup Award by The Ventures. The company raised $440k in pre-seed funding to scale AI video sales demos. The takeaway is that Naoma turns the moment a prospect is interested into a completed, qualified demo. Instead of a form that converts 1–2% of visitors, teams get an AI sales agent that demos the live product instantly, in 33 languages, 24/7, remembers returning visitors, writes every session back to CRM, and reports the objections and feature requests buyers never tell a rep. For B2B SaaS teams that want more demos from the same traffic and budget, Naoma provides an automated pipeline from first click to booked, qualified meeting.
OzBrain is a hosted knowledge base that acts as a shared brain every AI agent you use can read and write. Instead of each assistant keeping its own private memory, OzBrain provides one structured source of truth that sits underneath Claude, ChatGPT, Cursor, Claude Code and other connected agents. It is built for people and teams who already use several AI tools every day and want the work they have already done to be available the next time any agent starts a task. The company describes it as your Dropbox for agent knowledge: a place where structured articles with links, provenance and freshness live behind the connector menu that Claude and ChatGPT already show you. Today, context lives in your chats and your teammate's context lives in theirs, and the two never meet. People share a doc, drop a message and paste the same things over and over again. Meanwhile copies of the same plan sit in Drive, on laptops, in Downloads, in email, and no one is sure which version is current. Platform memory does not solve this either: as the site puts it, that memory is a few preferences and a thin summary of past chats. OzBrain's answer is to hold the work itself — your projects, decisions, research and the thinking you have already done — so an agent starts with what the task needs instead of whatever fits in a profile. The centrepiece is a single shared brain. Point everyone at one OzBrain and your agents and their agents read and write to the same place, so what one person works out, everyone's agents already have. The site illustrates this with a team view: a company brain holding company vision, rules and skills, engineering plans, customers, research and the roadmap, with individual people connected through Claude, Cursor, Codex and Claude Code. Because the knowledge sits outside any single chat product, it is not owned by whichever assistant happened to be used first. Sharing on brains you own is included in every plan, including the free one. OzBrain breaks your knowledge into nested pieces so that an agent pulls the exact slice it needs — the email body, not the whole launch plan. The site shows a launch plan at 11,842 tokens and 47.3 KB nesting into launch campaigns at 1,486 tokens and 5.9 KB, which in turn nests into launch email at 218 tokens and 0.87 KB. The argument is straightforward: the less an agent has to load, the faster and cheaper it answers, and the less it invents from context it never needed. Alongside this, OzBrain keeps the latest version out front. Instead of copies of the same plan scattered across Drive, laptops, Downloads and email, every agent decides from the current version rather than an old copy. When newer thinking lands, OzBrain goes back through your knowledge on its own, marks the old notes as replaced and points to the latest. You never have to hunt down every place an old decision lived, and no agent answers from a version you have moved past. The site gives the example of a website launch plan being updated when the company acquired a new domain, with related company details marked as updated to ozbrain.com. Every change is also on the record: which agent made it, what changed and the reasoning. Changes are proposed before they land, so several agents can work at once without writing over each other, and a recent-changes table shows the time, agent, article and reason for each edit. Privacy and ownership are handled explicitly. Your brain is encrypted at rest and sealed to your account, so nothing leaks between tenants. The site states that it never trains on your data and never sells it, describing OzBrain as a sovereign place for your data. Export is available at any time — everything as markdown, including after you cancel — on the principle that your knowledge should not be locked in anywhere, including OzBrain. Deleting your account removes your content: delete means deleted. The company also notes that it runs OzBrain on OzBrain, with its own data sitting next to yours, because it wanted the safest and easiest tool for itself as well as for users. Getting started does not require any coding. You add OzBrain from the connector menu in Claude or ChatGPT, sign in and approve it; there is nothing to install. Connect guides exist for Claude and ChatGPT, and the same brain can be reached from Claude Code, Cursor, OpenClaw, Hermes Agent, Gemini Spark where Google makes it available (US, Spark eligibility) and any client that supports connectors. Because it is one URL, anything that speaks the protocol can hold the same brain. Rather than being a memory API that developers code against, OzBrain is described as a brain you connect — structured articles with links, provenance and freshness, and one source of truth rather than a separate memory in each product. The stated outcomes for users are practical. Agents make fewer mistakes because they pull only the slice of knowledge a task needs. Answers are faster and cheaper because less context has to be loaded. Nobody has to maintain or "work" the brain, since replaced notes are marked automatically and the current version stays out front. Teams stop pasting the same context into several separate chats, and a brand-new chat can know what everyone has already worked on. Because everything is exportable as markdown, users keep an exit route and can move their knowledge to whichever tools serve them best. Concrete scenarios appear throughout the site. In one, a team connects individual agents through Claude, Cursor, Codex and Claude Code so the whole team's agents work together on the same knowledge — company vision, rules and skills, engineering plans, customers, research and roadmap — instead of each person's context living in a separate chat. In another, a website launch plan is updated when the company acquires a new domain, and OzBrain marks related articles, such as company details, as updated so no agent answers from the old domain. The changelog example shows several agents, including Claude, making coordinated changes to articles such as a website launch plan, an MCP setup guide and a surfaces page with a stated reason for each edit. A further scenario is a new chat starting with what a team has already worked on rather than from a blank slate. OzBrain is aimed at individuals and teams whose work already runs through multiple AI agents, from a single person's venture and personal knowledge to an organisation where agents run the operation from one brain. Supported integrations include Claude and ChatGPT through their native connector flows, plus Claude Code, Cursor, OpenClaw, Hermes Agent, Gemini Spark where Google makes it available (US, Spark eligibility) and any client that supports connectors. Pricing starts with Free at $0 forever, with up to 50 articles, sharing on brains you own, unlimited brains, reads, writes and connections, write-time size discipline and markdown export anytime. Pro is $20 per month with up to 500 articles, described as room for one venture plus personal knowledge. Max is $99 per month with up to 5,000 articles, for when agents run the operation from one brain. Enterprise sits above the Max ceiling with org-owned shared brains and per-seat pricing designed with you. Every plan includes unlimited reads and writes, and free plans mean you can start without a credit card. The takeaway is that OzBrain turns scattered, agent-specific context into one shared, encrypted and exportable brain that every agent and teammate can read and write. It keeps the current version out front, prunes replaced notes automatically, records who changed what and why, and lets you walk away with everything in markdown whenever you choose.
AppZapper 3000 is an uninstaller for macOS - the most fun uninstaller for the Mac, according to its developers. The idea behind it is deliberately simple: you drag any app into the AppZapper 3000 window, the app instantly finds all of the extra files that application has left around your system, and then you delete them with a real 3D zapper. The tagline for the product says it plainly: this is the uninstaller Apple forgot. It is made for Mac users who want to remove an application properly, along with everything that application installed, instead of only dragging a single icon to the Trash. It suits both people who have zapped apps for years and anyone who has never used a dedicated uninstaller before and simply wants a cleaner Mac. The original AppZapper was first released in 2006, and AppZapper 3000 is described as a rebuild of that tool for the 31st century. The site marks a 20 year legacy and states that the team is forever grateful to everyone who has been zapping apps over the past twenty years. That history points to the problem the product addresses. A Mac application does not consist of one file: alongside the app itself, there are caches, preferences and support files. Removing only the application leaves all of that material where it was. AppZapper 3000 exists to close that gap - to find everything an app installed and deal with it as a group, rather than leaving pieces behind for the user to hunt down manually. The problem matters because it is a routine, repetitive chore that is easy to do incompletely, and the tool turns it into a single, decisive action. The core interaction is drag, drop, zap. The first step is an empty AppZapper 3000 window, waiting for an app to be dragged into it. Once you drop an app in, AppZapper 3000 instantly rings in and targets every related file: caches, preferences and support files, described on the site as the junk an app installs. A ring-in moment announces that the related files have been located - the site's phrase, target locked, captures the point at which the app has assembled the complete set of items belonging to the application you dropped in. Nothing here requires you to know where macOS keeps application support data. The point of the feature is that you do not have to go looking through system folders yourself, and you do not have to guess which files are safe to remove. You see what was found, and you decide to zap. The deletion itself is the distinctive part: a real 3D zapper, with real laser bolts that blast away your unwanted apps and the junk they install. The business end of the zapper is a genuine laser bolt effect rather than a progress bar, and it is aimed with instant mouse aiming, so pointing at your target feels immediate rather than stepped or delayed. Recoil is described as manageable, which means the shooting mechanic stays controllable while still feeling physical. Firing is a single action - one click, one shot - which gives each removal a clear, satisfying conclusion. The site also shows explosion and smoke effect artwork that reinforces the zap. The zapper turns an otherwise invisible housekeeping task into something you can actually watch happen. AppZapper 3000 has also been rebuilt with the fluidity, agility and smoothness that the team says it always dreamed of - built to fly, in the site's words. That matters for a tool used in quick bursts: drag, aim, fire. Alongside the performance work, the app offers cosmetic choice through its sleek finish options. You can keep the classic livery, the look long-time users will recognise, or apply one of the new blaster themes to zap in style, so the tool can match your taste without changing how it works. For bulk cleanup there is Zap All, which lets you skip the one-click-one-shot rhythm entirely and blast them all away automatically. Between the single-shot mode and Zap All, the app covers both the careful, one-app-at-a-time case and the broader sweep when you have several applications you want gone. The overall approach is built around a deliberately playful metaphor: uninstalling as shooting. Rather than presenting a list of checkboxes and filenames and calling it housekeeping, AppZapper 3000 turns the same underlying job into a physical act, with an aim, laser bolts, recoil and a target-locked moment when the app's related files have been found. The workflow stays three steps - drag, drop, zap - and the fun is layered on top rather than offered in place of function. That is also why the 20 year legacy matters to the design: this is a rebuild of a tool people have used for two decades, keeping the same core promise of finding all of an app's extra files while updating the feel, the speed and the visual style for a new release. Some of the clearest statements of value come from the user comments gathered on the site. One user calls AppZapper an indispensable app, another says it is one of the first apps they install on a new machine, and others describe it as simple yet powerful, accurate, and something that just works. Several long-term users describe more than a decade of use - since a first Mac 15 years ago, over 15 years in the dock, and years of use without it ever failing. The recurring theme is reliability combined with simplicity: people expect it to remove an app and its extra files, and they expect the process to be quick. For anyone with the same expectation, the outcome is a Mac that no longer carries the residue of software you have already decided to remove. Concretely, AppZapper 3000 fits a handful of recurring situations. You have decided an app is no longer wanted and you want it gone properly, along with the caches, preferences and support files that belong to it. You have a batch of apps to clear out and use Zap All to blast them all away automatically rather than shooting them one at a time. You are setting up a new Mac and want to be able to install and remove software freely without leaving a trail of files behind - several commenters note the app is among the first things they install on a new machine. Or you simply want to try the tool before committing, in which case three free zaps let you drag, aim and fire a few times to see how it feels. In each case the workflow is the same: drag the app in, let AppZapper 3000 find everything, and zap. AppZapper 3000 is available for download from the AppZapper website, where there are also Try, Buy and Help options. The app is version 1.0 and requires macOS 15 or later. Pricing works as a try-then-buy arrangement: you can try three free zaps before deciding, and the Buy page handles the purchase. Existing customers are looked after through a license resend option on the site, and support is available by email, so recovering a license or getting help with the app does not require anything more than the website. AppZapper 3000 takes a task most Mac users treat as an afterthought - deleting an application - and gives it a full ritual: drag the app in, watch it find every cache, preference and support file it left behind, then destroy all of it with a real 3D zapper, one click at a time or all at once with Zap All. It is the legendary Mac uninstaller, first released in 2006, rebuilt with the fluidity, agility and smoothness the team always dreamed of and standing on a 20 year legacy of zapping apps. Its promise is narrow and clear, and that is the point: when you remove an app, remove everything it installed too.
Resurf is a personal context library — one place to keep the things you like, care about, and work on. It saves notes, links, images, PDFs, and documents into a fully local library, so the material you collect stays in one searchable spot instead of being scattered across browsers, folders, and apps. The app is built for Mac, iPhone, and iPad, and it is written entirely in native Swift. Its stated purpose is twofold: capture what you find, and then find it again — or hand that accumulated context to AI when you need a model to work with your own material. There is no Resurf account required, the app works offline, and sync through your own private iCloud is optional. The problem Resurf addresses is fragmentation. The things a person wants to remember arrive in wildly different formats and from wildly different places: an article on Substack, a PDF of a paper, a screenshot, a tweet, a GitHub repository, a YouTube video, a code snippet, a voice note recorded in the middle of a walk. Each of those lands wherever the app that produced it decides to put it. Later, when the thought returns — 'I read something about typography,' 'there was a paper worth revisiting' — there is no single place to look. Resurf's answer is the inbox model: save now, organize later. The library is meant to get more useful every time you save, because a growing personal collection becomes more valuable as long as it remains findable. A second, newer problem motivates the AI side of the product: AI tools are only as good as the context you give them, and most people have no structured way to hand over what they have saved. Capture is designed to stay out of the way. Quick Capture, bound to ⌘⇧C, lets you save something without switching context — the point being that a capture tool fails if it interrupts whatever you were doing. Content can come from any app: Resurf captures from Mac, Chrome, and iPhone into the same library, and a Chrome extension is available from the Chrome Web Store for browser-based saving. The library accepts a wide range of formats — articles, PDFs, images, audio, video, code, tweets, GitHub, YouTube, and notes — and every format renders natively, meaning you view the saved item as it was rather than as a degraded copy. Once something is saved, Resurf leans on an inbox-first approach: you do not have to decide where a capture belongs at the moment you make it. Organization happens later, through Spaces and Tags that let you group material around projects, research, and ideas — the page shows examples such as Research and Writing spaces and tags like #ml, #philosophy, and #ideas. A Visual Library complements that structure by letting you browse what you saved the way you remember it, which suits image-heavy or reference-heavy collections where a thumbnail is easier to recognize than a filename. Instant Search, triggered with ⌘K, finds notes, links, PDFs, images, and files quickly across the library — the page illustrates it with an example of searching typography notes across 24 captures from the last six months. Resurf also covers the moment after capture, when you have something to say about what you saved. Highlight & Annotate keeps your thoughts beside the source, so commentary lives with the material rather than in a separate document — useful when a highlighted passage only makes sense in relation to your note about it. Voice Memos capture thoughts before they disappear, which matters for ideas that arrive away from a keyboard. The Notes surface provides a rich-text editor with a formatting toolbar and highlights, and the product describes five surfaces — Library, Inbox, View, Notes, and Assistant — as the five places you will actually spend your time in the app. AI in Resurf is opt-in across the board, and the product is explicit about that. AI Summaries help you revisit articles, links, and PDFs faster by producing a short summary of the saved item. Bring Your Own AI lets you supply your own AI key rather than relying on a bundled service, and on Mac you can hand off saved context to AI agents through MCP or the CLI — a documented connection path in the guides. Ask Your Library lets you ask questions across the context you have saved; the page illustrates this with a query such as 'What did I save about typography?' answered against a reading list. Because the library lives locally, the material used for these questions is your own collection rather than a shared index. How the product works is defined by its architecture. Resurf is written entirely in native Swift for Mac, iPhone, and iPad, so the same library runs natively across all three rather than being wrapped in a cross-platform shell. Your library lives on-device — the page names the location ~/Library/Resurf — which is what makes the 'fully local' and 'private by default' claims concrete: data stays on your Mac, the app works offline, and no account is required. Sync is optional and runs through your own private iCloud rather than a Resurf-operated service. The Chrome extension and the MCP/CLI connection on Mac are the two extensions beyond the core Apple-platform apps: the first brings browser captures into the library, the second takes the library out to AI agents. The benefits follow from those choices. Because everything lands in one library with instant search, the answer to 'where did I put that?' is a single search rather than a tour of multiple apps. Because capture is bound to a keyboard shortcut and does not require switching context, saving feels lightweight enough to actually do. Because storage is local and sync is optional and private, the library can hold personal reading, screenshots, and voice memos without being uploaded to a third-party service. And because the library is exposed to AI through your own key, MCP, or the CLI, the collection becomes an input rather than a dead archive. The app is also free to try and, per the page, free on iPhone and iPad, with a separate license purchase for Mac. Concrete uses appear throughout the product's own examples. A reader saves a Substack article tagged #reading so it can be found later, and highlights passages while annotating them. A designer or writer keeps typography references and design notes in a space, browsing them visually — the page shows a query about typography answered from saved captures. A researcher stores papers such as a PDF of 'Attention is all you need,' marking it as worth revisiting. Someone away from a desk records a voice memo about a headline's typography. A developer saves GitHub repositories, code, and YouTube videos alongside everything else. Once the library has grown, the same collection can be queried directly — 'What did I save about typography?' — or handed off to an AI agent on Mac through MCP or the CLI. Resurf is aimed at people who collect: designers gathering visual references, writers and researchers assembling sources, developers saving code and repositories, and anyone who already runs a personal knowledge practice or wants to. Availability reflects that audience. The app runs on Mac (Apple Silicon and Intel) with macOS 14.3 or later, and is free on iPhone and iPad; the Mac app can be downloaded free to try or licensed through a purchase. A Chrome extension is available for browser capture, and a guide covers connecting agents over MCP or the CLI on Mac. The library itself is stored locally at ~/Library/Resurf, with optional private iCloud sync and no Resurf account required. The takeaway is that Resurf treats your saved material as an asset with two uses: a private library you actually revisit, and a context source you can hand to AI. It is fully local by default, native across Mac, iPhone, and iPad, built around quick capture and instant search, and organized through inboxes, spaces, tags, and a visual library. Its AI capabilities — summaries, asking your library, and agent handoff through MCP or the CLI — are opt-in and can run on your own key. For anyone whose best ideas and references are currently spread across browsers, folders, and screenshots, Resurf's proposition is a single, private, searchable place to put them.
ScreenCursor is a Chrome extension that records your screen and hands back a finished video with the camera moves already in place. Rather than returning a raw capture and leaving the zooming to you, it turns every click, drag and keystroke into a camera move while you are still recording. The result is a screen recording that is already watchable the moment you stop: there is no timeline to learn and no second pass in a video editor required. It is built for anyone who needs to show how something works on a screen — a demo, a walkthrough, a piece of work in progress — and who wants that video done without spending time on editing afterwards. As the site puts it, the middle step of the workflow, the zooming, is the whole product and it is the one you do not have to do. The problem ScreenCursor sets out to solve is a familiar one. Most screen recording software gives you back exactly what you recorded and leaves the camera work to you in a video editor. That means every demo becomes a two-stage job: record first, then sit down and manually place zooms, trim dead air and frame the footage so a viewer can actually follow what is happening. The site states plainly that the best screen recorders for sharing work are the ones that produce something watchable without a second pass, and that producing that is the only thing this product is trying to be. In other words, the tool is not trying to be a general-purpose video editor; it is trying to remove the editing step from screen recording altogether. The first feature is the automatic camera work, and it is the one that happens on its own. Clicks, drags and keystrokes are all picked up while you record. Each one gets a zoom at the same depth, and the zoom arrives a beat before the action so the viewer is already looking at the right place at the moment the action happens. Because the timing is anticipatory rather than reactive, the viewer's eye is guided to the click rather than chasing it afterwards. On the site this is summarised as every click, drag and keystroke becoming a camera move, placed and timed for you, with nothing to place by hand. The remaining features are there for when you want them, and the first of those is full control over every zoom. Nothing is baked in. You can retime a zoom, push its depth in or out, move it, switch the motion between snappy and gentle, or delete the one you did not want, and you can add your own zooms anywhere as well. The camera rebuilds as you drag, so what you are watching is what exports. This matters because automatic placement is only useful if it can be corrected; preserving full adjustment means the automation is a starting point rather than a fixed output. Framing and timing make up the next group of capabilities. For framing, you can sit the recording on a wallpaper, a gradient or your own image, softened so the backdrop never competes with the picture. You can add a browser frame carrying the real page title, round the corners, and pick the aspect ratio for wherever the video is going. For timing, you can split the clip anywhere, delete the stretches nobody needs to sit through, and speed up the ones that merely drag. Importantly, the zooms move with the cut, so nothing drifts out of step with the picture. Together these let a recording be dressed and paced for its destination without exporting into another tool. How the product works overall is described in three steps, with the explicit note that the middle one is the whole product and is also the one you do not have to do. Step one is to hit record: you pick your screen and go, and ScreenCursor waits three seconds so you can hide Chrome's sharing bar first, then stays out of your way. Step two is that it zooms itself, turning every click, drag and keystroke into a camera move that arrives before the click, holds steady, and then follows your cursor. Step three is export and ship: you can trim, cut or adjust any zoom if you want to, then export MP4 at up to 1080p straight to your Downloads folder. The whole pipeline — recording, editing and export — happens inside your browser, and the video never leaves your computer. There is no account to create and no server for it to go to. The benefits that follow from that approach are stated directly on the site. There is no watermark, no account and no subscription, and there is no limit on how much you record. Because everything stays local, recording and editing work offline and nothing is uploaded, ever. The purchase is one payment of $49 at early pricing (regularly listed at $79), yours permanently, with updates included, and one purchase activates on up to three of your own computers. Export is MP4 at 720p or 1080p, delivered to your Downloads folder like any other file, ready to upload anywhere without conversion. The Chrome Web Store rating shown is 5.0. In practical terms, ScreenCursor is aimed at scenarios where someone has to show a process rather than describe it. That includes recording your whole screen, including anything outside the browser such as other apps, your desktop or a design tool, and producing something a viewer can follow without having sat through the raw capture. It suits demo videos and work-sharing clips where the site's own framing is "sharing work" and, in its closing line, "stop editing your demos." The workflow is deliberately short: pick the screen, hide the sharing bar during the three-second wait, perform the task once while the zooms are placed for you, optionally trim the dead air, and export. One purchase covers a laptop, a desktop and a work computer, and if you replace a machine you can free its slot from the license page inside the extension or from your Polar account and activate the new one. Because it is a Chrome extension it runs wherever Chrome does, including macOS, Windows and Linux; recording performance depends on the machine having hardware video encoding, which the site says almost everything made in the last decade has. The site also positions it against Screen Studio, noting that Screen Studio is macOS-only and costs about $108 a year, while ScreenCursor is $49 once and runs anywhere Chrome does, though it acknowledges Screen Studio does more, including webcam overlay, motion blur and recording an iPhone over USB. The takeaway is narrow and deliberate: ScreenCursor exists to make screen recordings that are watchable without a second pass. It automates the camera work that normally lands in a video editor, keeps full manual control for when you want to change something, and does all of it locally in the browser with no account, no watermark, no subscription and no upload. If the goal is a demo that is finished when the recording stops, that is the entire value proposition.
DemoTV is a 24/7, television-style channel where short product demos play continuously and the audience — not advertisers — decides what sits at the top. Founders submit a demo, viewers watch two products go head to head in a Channel Battle and back the one they would actually try, and that pick becomes the audience rank. Channels 1, 2 and 3 are the current top three on the station, driven by an Elo-style audience score built from wins and battles. The station is made for independent makers, startups and product teams who want their demo discovered by people genuinely interested in trying new tools, rather than ranked by whoever spends the most money. Watching and voting requires no sign-up. Getting a new product in front of the right people is hard, and most channels hand the top slots to whoever pays for them. That leaves independent builders competing for attention against budgets they cannot match. DemoTV separates the two ideas: exposure can be bought through clearly labelled placements, but standing on the station cannot. Rank 1 on a channel is the demo viewers picked most — the page states plainly that it is not a paid slot and that airtime never buys rank or a channel. This gives founders a place where a strong demo can outrank a bigger budget, and gives viewers a feed of products that other people, not ad buyers, decided were worth a look. The core mechanic is the Channel Battle. Two products built for the same job are shown head to head, and the viewer simply backs the one they would try — no sign-up required. That pick feeds the audience rank, and the resulting ranking decides which demos occupy Channels 1–3, the current top three on the TV. Each demo carries an audience score alongside a win and battle count; the number one entry at the time of capture showed a score of 1368 from 145 wins across 178 battles, with Channels 2 and 3 close behind on 1344 and 1315. The directory board mirrors the channel: rank 1 sits first on the board and is the same tape as Channel 1, and Channels 2 and 3 are the next two. Demos only start playing when a viewer presses play or selects a channel, so nothing auto-plays just because someone scrolled past. For founders, getting on the station starts with a free submission — no card needed. A demo can be a YouTube link or an MP4 upload (40 MB maximum), and every submission is reviewed before it goes live. The submission flow runs through four steps: website details, video, visitor action, and review. Before submitting, makers can have DemoTV suggest a title and tagline from their project URL, and they choose the category whose battles the demo will join. Once approved, a private dashboard provides a single embed code for the maker's own website — a widget containing the video, an optional try link and a chosen button label such as Visit website, Start free, Join waitlist, Book a demo or Claim offer, with a configurable button destination. From the dashboard, founders can also request testers, cap reveals, and claim their company. Makers who want to reward viewers who picked them can attach an optional viewer thank-you — a backer code such as a time-boxed free week or a percentage discount, which never moves the Elo score and does not appear on battle buttons. Paid reach exists, but it is kept separate and clearly labelled. After claiming a listing, a founder can buy airtime units (5, 10, 25 or 100, with the price shown at checkout) which add promoted placements across the reel and directory; the page states repeatedly that these units never change a demo's audience score or channel. Featured partners pay $39 for 30 days of labelled placement as a homepage card — the copy notes that partners support the station, never the rank. Demo Studio is a paid option, priced at $79 for “Make my tape,” where a maker pastes their site and gets automated production with station QA before air, subject to their approval, while rank remains audience-only. Launch Week is a labelled 7-day sponsorship. Every one of these options buys exposure, completed views and clicks, never the ranking. The overall workflow is deliberately simple and stated on the site as three steps. First, submit your demo for free — a YouTube link or MP4, no card needed, reviewed before it goes live, with the message that submitting is free to founders. Second, win Channel Battles, because viewers pick the demo they would try and those wins move Channels 1–3. Third, boost with airtime if you want extra reach — optional labelled ads that become available after claiming the listing and that never touch the rank. A new entry begins as a pending station approval; the demo stays private until review is complete, and the maker receives a private management link and an email when it is live. For makers, the outcomes are discovery and validation rather than empty impressions. A demo that viewers would genuinely try climbs, so the success metric is real audience preference instead of ad spend. Founders get an embeddable widget they can place on their own site, a way to recruit testers, a company listing with a contact-the-maker form and reporting tools, and a channel that keeps showing their tape to people browsing the station. For viewers, DemoTV offers a way to discover independent products, watch short demos and try something new — with the ability to influence what gets seen next by backing the products they would try. Use cases follow directly from this setup. An indie founder launching a new app can submit a short demo for free, get it reviewed, and enter the relevant category battle without spending anything. A product with a direct competitor can be placed head to head in a Channel Battle — the site itself shows a battle between two app builders — and let viewers decide which one they would try. A maker who wants to test demand can attach a backer code and give viewers who picked them a time-boxed free week or discount, then measure interest. A team that already has a demo video can embed the widget on its own site so visitors watch the demo and take the try action directly. Advertisers and companies with budget can buy labelled airtime, featured partner placement or Launch Week sponsorship to reach the station's audience while leaving the ranking untouched. And a viewer simply looking for new tools can browse the demo directory, sorted by audience rank or newest, to find products to try. The directory itself is organised around categories that define which battles a demo joins: AI agents, AI app builders, video generation, chat assistants, computer use, developer tools, design & no-code, data & analytics, marketing & sales, productivity, infra & APIs, games, crypto & web3, crypto wallets, crypto infra, robotics & hardware, fintech & payments, security & privacy, education, consumer & social, climate & energy, and other. Makers can suggest a new category of 2–40 characters, which is listed under Other until reviewed. The board is paginated at 10 demos per page with sorting by audience rank or newest, and the station reported 110 live demos, 571 audience backings, 54.2K views and 6,845 visitors at the time of capture. Station numbers only appear once live demos exist. Contact for takedowns, press or submissions is hello@demotv.lol, reporting options cover scams, spam, malware, adult content, impersonation and broken videos, and the site's optional first-party analytics are explicitly described as containing no ad trackers or search terms. The takeaway is straightforward: DemoTV is an audience-ranked channel for product demos. It gives founders free airtime that is earned by the audience's own picks, keeps paid promotion clearly labelled and strictly separate from rank, and gives viewers a simple, sign-up-free way to watch demos and decide which product deserves the top channels.
Visiby is an AI visibility platform that measures and grows how brands appear across AI search platforms, including ChatGPT, Claude, Perplexity, Gemini, Google AI Overviews and Copilot. It acts as a visibility layer for the AI-search era, mapping entity presence across the top AI engines so marketing teams can see where they are recommended, where they are missing, and which competitor is being cited instead. The product is built for marketing operators and agencies who need to own the answer layer rather than only rank in traditional search results. Vendor discovery has moved. According to the content, 1 in 3 B2B buyers now start vendor research inside an AI assistant, and ChatGPT, Perplexity, Google AI Overviews, Gemini and Copilot are quietly intercepting traffic that used to land on a company's site — if the model does not surface the brand, the conversation never starts. The site states that 62% of enterprise marketers are already optimising for AI engines, citing the State of AEO 2026 from FNA Research, while the well-funded brand in a category treats Answer Engine Optimisation as a budget line whose citations compound week over week. Meanwhile, Visiby argues that zero tools in a typical stack measure what AI is saying about a brand: Semrush ranks, Ahrefs ranks, GA counts clicks, but none of them sample prompts, parse model answers, or explain why ChatGPT recommended a competitor instead of you. Visiby exists to close that blind spot with a continuous, prompt-level view of AI answers. The workspace opens on an Overview that serves as the weekly headline: search performance, AI visibility and the next moves the team should ship, readable in 90 seconds. Headline scores include Visibility, Share of Voice, Prompts won and Briefs ready. Search Performance explains a brand's organic traffic and click-through rates, tracking clicks over 28 days with month-over-month change, impressions, click-through rate and average position across tracked non-brand terms. AI Visibility shows where a brand appears and where it does not, presenting per-engine citation share across every prompt in the universe, with each cell clickable to reveal the underlying answer. In the illustrated workspace, ChatGPT sits at 42%, Perplexity at 51%, Claude at 34%, Gemini at 24% and AI Overviews at 18%. The Prompts Explorer is a workbench for the full prompt universe — more than 50,000 AI prompts are tracked weekly, and the sample workspace shows 50,127. It supports stacked filters, a cluster view and a three-way live answer diff, and each row drills into which competitor was cited, why, and the play to win the prompt back. The Citations Explorer works beneath the prompt universe across every URL the engines cite — 2,418 URLs in the example — ranking every cited URL and identifying honey-pot pages, dead-weight pages and counter-content briefs, with passage-level provenance. The Brand Entity module shows the adjectives a brand owns and the ones owned against it across engines, with per-engine portraits and reframe plays to move them; the sample adjective sets include trustworthy, established, enterprise, scalable, innovative, modern, consultative, agile, long-tenured and data-driven. Competitor Intelligence reads the field at a glance, presenting citation share by brand and topic with clickable cells that drill to the prompts and passages behind them, plus a per-competitor recipe diff comparing cited elements across engines, such as H2 headings, FAQ blocks, tables and lists. Recipe Intelligence delivers a per-engine pulse on which on-page element the AI is actually extracting from, producing the structural blueprint a team should publish to; Visiby reports that seven elements are tracked, including H2 headings, FAQ blocks with FAQPage schema, tables, bulleted lists and case studies. Site Audit is a citability-first audit that ranks every issue by AI impact with the fix and affected URLs attached, surfacing examples such as pages blocked from indexing, pages missing OpenGraph tags and meta descriptions, thin pages under 250 words, missing Organization schema, missing FAQ schema and image alt text gaps. The Action Plan converts all of this into a prioritised, priced playbook ranked by effort against impact, where every move carries an argument, a score breakdown covering why-now signal, forecast confidence, effort and dependency, evidence links, and a ready-to-ship deliverable brief. Visiby runs as a weekly ritual. Every Tuesday at 07:42 IST, the platform fuses three live data streams — the prompts buyers actually ask, where the brand is losing citations, and the recipes competitors win with — into one prioritised action plan, with no analyst required. The pipeline runs overnight and lands in the inbox as a citation sweep, share-of-voice deltas, a prioritised action plan, content briefs and an executive summary. A weekly digest email example reports the number of prompts run across engines, the movement in citation share, the action moves ranked by projected lift in points, and a forecast of the week when citation share returns to a target level. The platform continuously samples engines, and the site positions the cadence at seven days from signal to a shipped fix. Benefits described include replacing guesswork with evidence about what AI engines recommend, seeing exactly which competitor is being cited first on high-value prompts, and knowing which structural elements and content formats win citations on each engine. Instead of a dashboard nobody opens or a spreadsheet exercise, teams receive an inbox-ready brief with ranked moves and attached briefs, so prioritisation and writing can start immediately. Ranking moves by effort against impact lets a small team focus on the highest-lift work, and the prescribed fixes — schema, content refresh, comparison pages, original research — are tied to specific projected visibility gains. Concrete scenarios in the content include a marketing team reading the weekly overview and shipping the queued moves; a brand losing citation share to a named competitor and building a comparison page in response; refreshing a contact page for AI parseability because it lacks crucial entity definitions and brand identifiers; adding FAQ schema to a services pillar of 14 core URLs missing structured Q&A data; producing original research on AEO benchmarks to capture data and stats queries; and running community and earned-media plays such as a Reddit thread cluster or listicle outreach to G2 and Capterra. Agencies can use the same workspace to run client AEO programmes, and the Agency tier supports white-label client reports and multi-workspace reporting. Visiby is aimed at marketing operators, enterprise marketers, SEO and AEO specialists, and agencies. It complements rather than replaces existing SEO platforms, and the site compares its capabilities against Semrush, Profound, Conductor and Ahrefs across AI visibility tracking on five engines, SEO and rank tracking, brand entity audits, passage-level citation provenance, recipe intelligence, priced action plans, ready-to-ship content briefs, an autonomous weekly pipeline and multi-workspace reporting. Pricing has four tiers: Lite at $49/mo with 25 prompts a month and one seat; Starter at $99/mo with 50 prompts a month, 10 action items and Site Audit plus Action Plan; Pro at $249/mo with 150 prompts, 30 action items, three seats and three brands, daily refresh, Brand Entity, Competitor Intelligence, Sentiment Analysis and priority support; and Agency at $499/mo with 500 pooled prompts, 50 action items, 10 seats and 10 workspaces, white-label client reports, API access and SSO/SAML, custom engines and regions, and a dedicated success manager with an SLA. A free visibility report is offered in 60 seconds with no card required. That combination makes Visiby a visibility layer for the AI-search era: it measures how brands and competitors appear inside AI-generated answers, explains the structural recipes that earn citations, and turns those signals into a prioritised, priced plan a team can ship on Monday.
Ghostwriter by MyHandler is a Windows desktop writing tool that drafts text for you directly inside whatever application you are already using. Instead of opening a separate chat window and describing what you want written, you place your cursor in a text field, double-tap the hotkey, and your Handler reads what is actually on your screen — the thread above the cursor, the question beside it, the half-finished sentence inside it — works out what you would write next, and types that draft at your cursor in your voice. There is no prompt to type and nothing to say out loud. It is built for people who spend their day answering messages, email threads, Slack conversations, browser forms and comment boxes, and who want the first draft of a reply to already be there, in their own style, without leaving the app they are working in. The problem Ghostwriter addresses is the gap between knowing what to say and getting it written. Most AI writing tools require the user to describe the request first: you have to summarise the thread, explain the tone, paste in context, and then copy the result back to where it belongs. That description step is often the same work the user was trying to avoid — as the site puts it, describing what you want was the work you were avoiding. Meanwhile the context that actually matters — the conversation on screen, who is speaking to whom, what is being asked — is already sitting in front of the user, and the calendar that determines whether a proposed time is even possible lives somewhere else entirely. Ghostwriter's approach is to take the screen itself as the input, remove the prompt, remove the copy-and-paste round trip, and leave the final decision — whether to send — with the person. The interaction model is deliberately minimal. There is no prompt field, no sidebar, no dictation. You put your cursor where the words go and double-tap the hotkey in any text field, in any app — the Product Hunt listing names double-tap Left Ctrl. The Handler then captures the screen around that cursor: the thread above it, the question beside it, the unfinished sentence in it. That capture happens on your own machine, against an encrypted vault on your PC, and the assembled context is sent to the cloud model with zero data retention to write the draft. Because the screen in front of you is the entire input, it works the same way across the applications the site names — your mail client, Slack, a browser form, a comment box — with nothing per-app to set up. Before writing a single word, Ghostwriter decides what kind of writing it is looking at. The site describes the situations it distinguishes: a reply owed in a thread, a sentence to continue from exactly where it stops, a blank box under a question that wants a real answer, and a message the context obviously calls for. Getting that classification right is described as most of the job, which is why the decision is made before any drafting begins. The consequence is behavioural: a continuation does not restate your own sentence back at you, and a reply does not summarise the thread back at the person who just wrote it. If the reply it produces proposes a time, that time is checked against the next two weeks of your calendar first — the product states plainly that it won't double-book you. Ghostwriter also tracks who is who in a conversation. It maps each message to its sender, works out which handle is yours, and follows who asked whom for what, so that the draft answers the other party rather than replying to your own words. On top of that identity mapping, it matches how you write to that specific person, down to the sign-off. The material it draws on can include the thread on screen, your calendar, your files and your past meetings, indexed in an encrypted vault on your PC. Together these two behaviours — correct attribution and per-person voice — are what separate a draft you can send from one you have to rewrite. Nothing is ever sent. Ghostwriter types its draft into the text box and stops; you read it, change it, delete it or send it, and that last step stays yours. If you select text first, the double-tap rewrites the selection instead of drafting something new. Architecturally the product is split: the screen capture and the encrypted vault live on your own PC, while the assembled context goes to a cloud model with zero data retention in order to write the draft. Ghostwriter is part of the MyHandler desktop app, so it ships alongside the same Handler's other capabilities — Dictation, which turns held-key speech into text at the cursor; an AI Gatekeeper that watches every connected channel, screens the noise on your PC and never sends a word on its own; Contact Intelligence, which builds living contact profiles automatically on your machine from messages, meetings and activity already in your vault; and a Daily Briefing written from local data. The stated benefits follow directly from that design. There is no prompt to write, so the whole interaction collapses to a double-tap. The Handler reads the situation rather than just the words, so the draft lands in the right register: a continuation continues, a reply replies, a form gets filled, and a message the context calls for gets composed from scratch. It gets who's who right, so the answer addresses the other party rather than your own words. And because the draft arrives at the cursor in your voice, in the style you use with that person, the editing pass is a light one rather than a full rewrite. The outcome the product advertises is the end of rewriting the same reply over and over: it drafts, and you decide. Concrete scenarios come straight from the described workflow. You are in your mail client with a thread open and your cursor in the reply box; a double-tap puts a reply drawn from the thread above the cursor in place. You are in Slack and a question is sitting there for you; the Handler maps the message to its sender and drafts the answer to the other party. You are in a browser form or a comment box with a blank field under a question, and it composes a real answer rather than leaving the box empty. You have half a sentence on screen and want the next part; it continues from exactly where the text stops. You are arranging a meeting and the draft proposes a time; the next two weeks of your calendar are checked before the words appear. Or you have already written something and want it said differently: select the text, double-tap, and the selection is rewritten. Ghostwriter is aimed at people whose working day is made of written replies — anyone living in email, team chat, browser forms and comment boxes who wants the first draft to already exist and to sound like them. It runs on Windows 10 or 11, requires a cursor in a text field to trigger, and needs a connected calendar only for the scheduling cross-check; everything else works without one. The product is described as free for Windows 10 and 11, with macOS and Linux coming soon. Because the screen capture happens locally and the index lives in an encrypted vault on the PC, that side stays on your machine, while the drafting step uses a cloud model with zero data retention. Ghostwriter's proposition is narrow and clear: two taps and it's already written. Every other AI writes what you tell it; Ghostwriter writes what you already know, using the screen in front of you as the input and your own voice as the output, and it hands the last step — sending — back to you.
Kirokune is an iPhone app for logging work and personal incidents. It lets you capture what happened in your own words — through a short note, a voice recording, or a photo — and keeps that record on your iPhone, organized into a timeline inside a private case. The app is designed for people who have been told to document everything but have no simple, private place to do it. Unlimited records in one case are free, and no account is required to start; you open the app and begin. Kirokune also offers a free workplace incident log template and example on its website, so you can start documenting even before you install anything. Everyone says document everything, but the practical question of where to write it down rarely gets answered. Work and personal incidents often happen at moments when you have neither the energy nor the time to sit down and compose a careful written account. Details fade, exact wording is lost, and the sequence of events blurs together. Kirokune addresses that gap by lowering the effort of capture to almost nothing: one tap starts a recording, and a photo or a quick note works just as well. The record you create while it is fresh stays on your iPhone until you decide what, if anything, you want to do with it — you do not have to let it go just to get through the day. The core of Kirokune is capturing what happened while it is fresh. A short note written in your own words is enough to begin, and a single tap starts an audio recording for the moments when you cannot bring yourself to type. Photos can be saved alongside notes and recordings, so a visual detail sits with the written account rather than in a separate camera roll. All of these record types live together in the same place, which means you are not choosing one format at the expense of another. The app does not require any setup before you start — you open it and immediately begin a note, a recording, or a photo. Once records exist, Kirokune organizes them rather than rewriting them. Events are shown in time order — dates, times, and exact words — and the timeline is reviewed alongside your original notes. Critically, nothing you already wrote gets changed; the app keeps your own record organized and that is all. Records are grouped into cases, and the free plan allows unlimited records inside one case. Kirokune Plus adds unlimited cases, so people who are tracking more than one situation can keep each one separate. Sorting happens later, when you have the energy, rather than at the moment of capture. Kirokune can also save a chat export as a record. You choose a supported export file from Apple Messages, Messenger, or Instagram — without connecting your chat accounts to the app. Kirokune keeps the file's whole original text alongside the messages it can display, so the original wording stays attached to the record. Because the app does not connect to those services, the guidance suggests choosing the conversation and date range before exporting, where the service allows it. This makes it possible to fold a written conversation into the same private case as your notes, recordings, and photos. The workflow Kirokune describes has three steps. First, get it down: open the app and start a note, a recording, or a photo, with no setup first. Second, sort it later: when you have the energy, group what you saved into a private case. Third, look back: everything is in order, exactly the way you wrote it. Underneath that workflow is a deliberate approach — the app stores records on your device and requires no account. Nothing leaves the app unless you export it yourself. Kirokune states plainly that it does not decide what happened, does not diagnose, and does not give legal advice; it keeps your own record organized. The benefit is that you won't have to go from memory. When you decide to talk it through — with someone you trust, HR, a lawyer, or a support service — having it written down in your own words helps you explain what happened. Because capture takes one tap or one short note, you can document something at the moment it happens instead of reconstructing it weeks later. Because records stay on your iPhone, privacy is the default rather than a setting you have to find. And because you can name the other person however you like — initials or a nickname you would recognize later — you are never forced to record a name you don't want to write. Typical uses follow the situations the app was built for. Someone documenting a workplace incident notes the date, the time, where it happened, what was said, and who was there, as soon as they can, and Kirokune keeps all of that together in one private place in time order. Someone who wants a record in the moment but cannot type taps record instead. Someone preparing for a conversation looks back at what they saved, at their own pace, and pulls it into a summary they can walk someone through. Someone with a written chat conversation exports it and saves the file as a record so the original text stays with it. The free worksheet on the website lets anyone start this practice without an app at all. Kirokune is for iPhone users running iOS 17 or later. There is no Android app; the website's free worksheet can be saved and used in your own notes without installing anything or creating an account. The app is available in the United States and India, with English, Japanese, Traditional Chinese, Korean, and Spanish interfaces. Kirokune is a free download with in-app purchases: the free plan covers unlimited notes, recordings, photos and other records organized in one case, with no account required. Optional Kirokune Plus adds unlimited cases, detailed reviews, PDF export, and removal of ads, available as monthly, yearly, or one-time lifetime purchases, with local price and renewal terms shown in the purchase screen. Two practical notes appear in the app's own guidance. Rules about recording and sharing a conversation vary by place and by situation, so Kirokune suggests considering letting the other person know and checking the rules where you are; the app cannot tell you whether a recording is lawful or how it would be treated. Also, Restore Purchases checks access to your paid plan and does not restore a backup of your records, because records are stored on your device and the app currently provides no automatic sync or cloud backup — so keep your own copies before deleting the app. The takeaway is simple: Kirokune is a private place to write down what happened, on your iPhone, until you decide to talk to someone.
Cue is an Awwwards-tier UI component library for anyone building to stand out. It gathers best-in-class components from across the internet and curates them by hand, offering bold hero sections, smooth interactions, unique layouts and thoughtful micro-animations that help teams ship websites that do not just work but stand out. Cue is made not only for AI builders but also for designers, developers, agencies, solo makers and product teams who refuse to ship generic-looking work. It describes itself simply as the taste layer on top of the tools people already use, and today every component ships with an AI prompt so users can recreate what they see inside their own projects. The starting point for Cue is a familiar frustration: most component libraries, template packs and AI-generated interfaces look interchangeable, and shipping something distinctive usually means hours of reverse-engineering interactions spotted on award-winning sites. Cue approaches that problem from the opposite direction. Rather than generating components to fill a grid, the library is assembled from hand-picked references, sourced from an Awwwards Site of the Day, a Behance-featured interaction, or a production output the founder considered best-of-class. The editorial section describes the collection as the best web interactions from Awwwards, CollectUI and X, delivered together with the code and prompt needed to recreate them in your own project. The stated bar is taste, not volume: if a user finds a better reference for the same component, the founder replaces the existing item, so the catalogue keeps improving instead of merely growing. The library itself is organised around the building blocks of a high-end marketing site. Cue lists bold hero sections, smooth interactions, unique layouts and micro-animations, and the site exposes tags for sections and interactions alongside filters for new versus old entries. At the time of writing the library advertises 75+ components with daily drops, so the collection is presented as a growing, frequently refreshed catalogue rather than a fixed download. A dedicated Editorial stream highlights a new drop each day. An email signup lets visitors be notified when new components ship, described as no spam and unsubscribe anytime, and the founder states that every drop is hand-picked personally. What makes Cue unusual among reference galleries is that every component ships with an AI prompt. Those prompts are designed to be dropped straight into Bolt, v0, Cursor, Framer AI, ChatGPT or Claude, so instead of studying a screenshot and rebuilding an animation by hand, a user can hand the prompt to the AI tool they already work in and adapt the result to their own project. The free tier of Cue allows visitors to browse the whole library and copy two AI prompts every 24 hours, which lets people test the workflow before committing. Because the prompt travels with the component reference, the interaction and the implementation guidance stay together. Beyond prompts, Cue states that React source code and an MCP server are actively rolling out. The MCP server is described as giving native access from Cursor, Claude Desktop, or any MCP-aware AI tool, which means an assistant can reach the component library directly rather than relying on copy and paste. React source code targets the developers who want the underlying implementation rather than only a description. Together these additions move Cue from a browsable gallery toward a resource that plugs into the toolchain of AI-assisted development. Cue's positioning is deliberately narrow. It does not host projects, deploy code, or run an AI model of its own; it is the taste layer sitting on top of the tools people already use. It also states plainly what it is not: not a template pack, not a subscription, not a course, not an AI wrapper, and not a marketplace. Curation is done by founder Alok, a founder-designer who hand-picks every drop and describes the work as building the taste layer for AI components. Because access is offered as a one-time lifetime payment rather than a recurring fee, the emphasis stays on singular, vetted references instead of a constantly billed content feed. The promised outcome is straightforward: build less and create more. Teams that struggle to produce distinctive interfaces get a shortcut to the interactions and layouts that define award-winning sites, without spending days dissecting how they were built. Designers gain a curated reference library that reflects a single, consistent point of view rather than an unfiltered dump of community uploads. Developers get prompts and, as they roll out, React source and MCP access, which shortens the distance between seeing an interaction and shipping it. AI builders get a way to raise the visual quality of what their assistants generate. For solo makers and agencies, the appeal is the same: differentiate visually while keeping the existing toolchain. Concrete uses follow from the components on offer. A designer putting together a portfolio can browse hero sections and unique layouts for a starting point rather than a blank canvas. A developer building a landing page in React can copy a prompt, paste it into Cursor or v0, and adapt a micro-animation that would otherwise take hours to recreate. An agency can use Cue as a reference source when pitching or producing client work that needs to look handcrafted. A solo maker launching a product can pull in an interaction that lifts the site above a default template. Teams working inside Claude Desktop or another MCP-aware client can eventually reach the library natively. Community activity is part of the workflow too: a Discord invitation lets members pick the next drop, and the founder is directly reachable for questions or for hire. Cue is aimed at designers, developers, agencies, solo makers and product teams, as well as AI builders, who refuse to ship generic-looking work. Pricing is structured as a free tier plus one-time lifetime access. Free browsing includes the full library with two AI-prompt copies per 24 hours. Cue+ Founding Lifetime is USD $99 as a one-time payment, capped at the first 50 members. Cue+ Lifetime at the standard rate is USD $249 one-time after the founding tier sells out. Promotional pricing has been offered at $79 lifetime, and the site also mentions custom pricing where you pay only for the components you pick. Technically, Cue centres on AI prompts for Bolt, v0, Cursor, Framer AI, ChatGPT and Claude, with React source code and an MCP server rolling out. The takeaway is that Cue sells taste rather than volume. By hand-picking Awwwards-tier components and pairing each one with an AI prompt, and soon React source code and MCP access, it gives designers, developers and AI builders a faster route to interfaces that stand out, while staying a layer on top of the tools they already use.
Neopress is an AI website builder that lets you build, publish, and grow a website by chatting with an AI assistant. Instead of assembling pages by hand, you describe what you want in plain language and the assistant helps create pages, organise structured content, and refine the result. It is aimed at people who need a real content workflow behind their site — a built-in CMS, server-rendered SEO, GEO tools, forms, and analytics — rather than a static page that never changes. Neopress describes itself as connecting website creation, structured content publishing, SEO tools, and traffic insights into a single workspace so you can keep improving after launch. The problem Neopress addresses is that a website is not finished when it goes live. As the site explains, a website needs ongoing content updates, search settings, and performance review after launch, and those tasks usually live in separate tools. Neopress was built by a team that has shipped hundreds of content sites, and it is optimised for one thing: websites that get found — clean structure, a real CMS, and SEO that works by default. The product brings content management, search configuration, and analytics into one place, so the post-launch loop of updating, measuring, and improving becomes part of the same workflow as building the site in the first place. Neopress works through agents that operate alongside you. The first is a design agent: describe the page you want in plain language and watch it take shape, then refine layout, copy, and style through conversation. The stated advantage is that there are no templates to wrestle with and no design tools to learn. The second is a CMS agent: work with AI to draft and organise content in CMS collections, review the copy and SEO settings, then publish when you are ready. The Launch plan includes unlimited pages, unlimited CMS collections, and unlimited forms and lead capture, so the content structure of the site is not capped by the plan. Search visibility is handled by built-in SEO and GEO tools. Neopress delivers page content as server-rendered HTML, so search engines and AI crawlers read the structure and text of a page instead of an empty browser-rendered shell. Metadata and Open Graph settings can be reviewed and edited for search results and social previews. Neopress generates a sitemap.xml automatically so search engines can understand and crawl the site structure, and it publishes the emerging llms.txt standard for you — a clean, curated map of your key pages for AI assistants. Structured data (JSON-LD) can be added and reviewed to help search engines understand a page's content, and robots.txt gives control over crawler access so you can block pages you do not want indexed. Beyond the core tags, Neopress adds the plumbing that content sites usually need later: HTTPS with SSL by default, automatic canonical tags to avoid duplicate content, a custom 404 page, 308 redirects from old URLs to new pages when reorganising a site, an automatically generated RSS feed, image alt text for accessibility and image search, and clean, human-readable, keyword-friendly URL slugs. Fonts are self-hosted and preloaded to cut layout shift and speed up first paint, images are optimised for size, format, and delivery, and pages are responsive so you can review how they appear on mobile screens. Neopress states it is built for Core Web Vitals, with server rendering, caching, and a global CDN supporting fast page delivery. Multilingual publishing lets you configure site languages, review translations, and publish language versions with hreflang support. Neopress describes its overall approach as a flywheel with four stages: build, publish, measure, and improve. You build by chatting with AI, publish structured content through the CMS, measure with the analytics dashboard, and improve by asking AI to review site and performance data. One agent focuses on measurement: ask AI about the analytics available for your site, review its explanation and suggested changes, then choose what to improve. Another agent reviews available site and performance data, identifies issues, and suggests changes for you to decide which improvements to apply. The recurring theme is that AI proposes and explains, while you review and decide — publishing and publishing changes always remain your choice. The stated outcome is a website that gets found and keeps improving. Because every page ships as real HTML rendered on the server, crawlers can access content without relying on browser-side rendering. Because the CMS, SEO settings, and analytics sit in the same workspace, there is no gap between writing content and configuring how it is indexed. Analytics covers tracking search queries, checking post indexing status, seeing which LLMs crawl your pages, and tracking paid, campaign, and visitor data, with Google Search Console and Google Analytics integrations available on the Growth plan. On ownership, Neopress states that you retain full ownership of all content, copy, and structural assets generated by the AI — Neopress provides the hosting and the engine. Neopress is used to build and grow content-driven websites. Its template gallery shows the range: Blog & Editorial, Corporate, Documentation, and Landing Page templates, with published examples spanning skincare and dermatology clinics, a non-surgical spine and joint hospital, an oriental medicine clinic, a boutique Pilates studio, an artisan bakery and cafe, a design studio journal, and a bespoke jewellery atelier. For teams with an existing site, Neopress offers website migration — moving your existing pages, content, domain, and redirects over without a rebuild from scratch — and design services for a new page or a fresh look, discussed directly with the Neopress team. Day to day, the workflow is drafting and organising content in CMS collections, publishing pages, then reviewing analytics and applying SEO improvements. Pricing is subscription-based with plan-based AI usage and traffic allowances, and it starts with a 7-day free trial. Launch costs $25 per month per site with 10,000 pageviews per month included and $1 per additional 1,000 pageviews. It includes AI chat creation and editing, unlimited pages, unlimited CMS collections, unlimited forms and lead capture, built-in SEO and AEO optimisation, search-readable pages via SSR, llms.txt, robots.txt and sitemap control, JSON-LD structured data, RSS feed, URL redirect rules, custom domain connection, logo and favicon settings, a social share (OG) image, a custom 404 page, removal of the Made by Neopress badge, a real-time analytics dashboard covering the last three months, one editor seat with unlimited viewers, version history and Rewind restore, and MCP support. Growth costs $99 per month per site with 50,000 pageviews included, about three times the AI usage of Launch, ten editor seats with role-based permissions, real-time collaboration presence, full analytics with paid, campaign and visitor tracking, visibility into which LLMs crawl your pages, search query tracking, post indexing status, Google Search Console and Google Analytics integrations, two years of data history, multi-language support, a multilingual sitemap with hreflang, and priority support. When a trial ends or you stop paying, published content remains available on your Neopress subdomain on the Free plan while custom domains pause. Pageviews count human visits plus crawls made by AI to cite your pages in its answers; search engine indexing and AI training crawlers are not counted. Security and trust features include Supabase infrastructure with authentication-controlled database access, Supabase Auth, Vercel's DDoS protection, Polar as merchant of record for payments, and version history for restoring previous versions of pages and site layout. In short, Neopress positions itself as one AI-powered loop for building and growing a website: you create pages through conversation, publish structured content through a real CMS, ship server-rendered HTML that search engines and AI crawlers can read, and then use analytics plus AI review to decide what to improve next. The core value proposition is a website that gets found and keeps getting better, managed end to end in a single workspace rather than scattered across separate building, CMS, SEO, and analytics tools.
Youkti is an outbound system of thinking and action that turns account knowledge and relationship data into revenue. It is built to help sales teams win more new logos, move more pipeline, and reactivate dormant accounts using intelligent outbound, live signals, and a complete memory of every account. Youkti combines conversational campaign building through its AI GTM agent ARYA, a daily execution cockpit for reps, automatic account journey tracking, and deep account intelligence with deal context and recommended next actions. The product is aimed at sales leaders, revenue operations teams, account executives, and outbound representatives, and it gives each of those roles a command surface tuned to their job — intelligence for leaders and RevOps, actions for AEs and sales leaders, and outbound workflows for reps and GTM teams. The problem Youkti addresses is that momentum inside a pipeline is easy to lose. Deals slip without anyone noticing in time, dormant accounts quietly fire buying signals nobody sees, and reps walk into strategic meetings without knowing which stakeholder joined or which questions are still unresolved. Youkti keeps a memory of every account, conversation, and deal, then tells the sales team the exact next move: which deal is slipping, which dormant account just fired a signal, and what to prepare for tomorrow's meeting. Instead of relying on static workflows, stale battlecards, and manual CRM updates, the system continuously overlays live signals and relationship data onto every account so the next best action is always visible. The first major capability is the conversational GTM builder. Rather than dragging and dropping blocks or writing if-else logic, users tell ARYA what they want in plain English, and it builds the entire flow through conversation — signal triggers, persona matching, outreach rules, and cadence. The configuration updates live as you talk, and the flow editor shows a live config review alongside run history and settings. Example flows shown in the product combine triggers such as Funding Raised or Hiring Surge with target personas such as VP Sales, CRO, Head of Sales, VP Marketing, or CMO. If both a funding raise and a hiring surge are detected, the flow can apply an aggressive tone on a cadence of every three to four days across five emails; if only one condition fires, it can apply a consultative tone weekly across three emails. Because the configuration is generated through conversation, there is no drag-and-drop canvas and no if-else branching to maintain. The second capability group covers daily execution. Every morning, reps open a single screen — the Cockpit — where accounts are prioritized, signals are overlaid, personas are matched, and sequence hooks are already written, with one click to push. The cockpit shows counts such as total accounts, active signals, today's plays, high-priority plays, live sequences, pending replies, and meetings for the day. Accounts are queued with the detected signal and the reason it matters — for example, a hot account showing a hiring surge signal detected yesterday — together with matched personas such as a CTO or Senior Director of Product, the linked sequence such as a five-step, 18-day Sales Leaders Outreach play, and a send action. This is described as what a true system of action looks like: signal-driven prioritization, one-click sequence push, and the thinking layer made visible to the rep. The third capability group is tracking and account intelligence. After a sequence is pushed, every account enters an Account Journey, where Youkti tracks status, engagement, replies, meetings, and surfaces the next step automatically — no manual updates, no digging, and no missed follow-ups. The journey view summarizes total accounts, meetings today, unactioned items, and total actions, and it segments accounts into states like Growing, Stable, Needs Attention, and At Risk, showing a summary of outreach, status, last contact, and AI-generated next steps such as high buying intent detected or an active email thread that should be pushed toward a meeting. Clicking into any account opens a deep-dive board with emails sent, replies, meetings, next actions with reasoning, the latest meeting brief with talking points, stakeholder maps, a full account timeline, signals, insights, sales actions, and talk tracks — plus automatic meeting prep. The system recommends; the user decides. A further capability is the intelligence layer, described as 100+ parameters and every signal in one snapshot. Youkti Execute scores every account on readiness, ICP fit, budget, timeline, and sales cycle, then generates deal actions, strategic approach, entry points, key messages, and email templates — a six-step account-based campaign in one click. The scorecard example shows readiness of 9/10 and ICP fit of 8/10 with explicit reasoning such as Highly Qualified Enterprise Target rather than a black-box number, alongside budget context, timeline for pilot approval, sales cycle length, ROI potential, effort level, best timing, the account's competitive edge, and recommended next steps such as launching an outbound sequence, connecting on LinkedIn, proposing a tech-stack consolidation audit, or pitching a pilot. Strategic deal enablement material includes ROI potential, effort level, success metrics, value demo scripts, and a phased execution timeline. The system also monitors signals across the entire TAM — funding, hiring, leadership changes, lawsuits, competitive moves, and tech stack swaps. When something fires, the user does not just get an alert: they get the analysis, the reasoning, and the timing window, including confidence scoring with reasoning, a Why It Matters explanation for every signal, and timing windows such as Next 2-4 weeks that indicate when to act rather than only that something happened. Those signals feed sequence generation: Youkti writes complete multi-step sequences with A/B variants, each tied to specific signals and account context, including campaign strategy, messaging angles, subject lines, and email bodies. A generated sequence example shows six steps, twelve emails, and a sixteen-day duration, with one click to push the selected variant into a sequencer such as Lemlist, Outreach, or any SEP. The platform modules that make this up are built to work together. Prospects & Lists lets teams build, distribute, and track high-quality prospect lists at scale, assign ICP-fit companies to reps, and monitor execution centrally. Account Intelligence delivers 100+ parameters of contextual company intelligence on any account in under 60 seconds with a single click. Outreach Automation generates messaging angles, follow-ups, and outreach guidance tied to real signals and account insights. Competitive Intelligence tracks competitors, comparisons, and real-time changes that impact active deals. Sales Enablement centralizes decks, case studies, and battlecards so reps always use the latest narrative. CRM Enrichment automatically enriches and updates accounts, contacts, and activity so CRM data stays accurate without manual effort. ARYA is the AI GTM agent that builds the flow, writes the outreach, and tracks what's next. Account Journey builds personalized, multi-touch engagement journeys that adapt to signal changes and rep activity, and Execution Analytics tracks outbound execution across every rep, account, and play. The benefits described are concrete: winning more new logos, moving more pipeline, and reactivating dormant accounts; seeing which deals are slipping and why before they stall out of the pipeline; understanding the top competitors in your deals and the top objections from your clients; preparing strategic conversations with the messages that landed you deals; and giving every rep exactly what to do each day. The vendor also states it helps avoid spending $100K+ on Salesforce Data Cloud 360 and implementations, because Youkti has your data covered. Customer stories cited on the site include NeoSOFT generating $50K+ pipeline growth, Samvidh Technologies increasing revenue 20% quarter over quarter, and Deeploop increasing selling time by 3×. Use cases shown in the product illustrate how this plays out. Protecting an at-risk deal: an account flagged At-Risk, awaiting board approval for 16 days, with the suggested action of scheduling a meeting with the VP of Operations who was last contacted 16 days ago. Prioritizing a high-intent account: a SaaS Series B company marked High Priority with a new CRO hired, nine sales leadership roles open, and Series B funding raised, carrying an ICP score of 96/100, with LinkedIn and email actions for the named contact. Reactivating a dormant account: a healthcare enterprise where the last contact was 94 days ago and a new signal was detected about a digital transformation initiative, with a drafted email to the named contact. Opening an expansion opportunity: an enterprise manufacturer with a renewal in 60 days where the Operations business unit is 78% engaged and Supply Chain is 62% engaged, prompting a call with the named contact. And preparing for a strategic meeting: a retail enterprise meeting tomorrow where the CIO has joined the meeting, with tasks to review a new stakeholder map, resolve unresolved security questions, prepare recommended talking points, confirm the CIO attendee, and schedule an internal team meeting. Youkti is built for AEs, RevOps, sales leaders, and outbound reps, and its integrations cover the surrounding stack. Email and calendar integrations include Gmail, Google Calendar, Outlook, Exchange, and Office 365. Data integrations include Snowflake, AWS, OneDrive, SharePoint, and Google Drive. CRM integrations include Salesforce, HubSpot, Zoho CRM, Pipedrive, and Freshsales. Prospecting data providers include LinkedIn Sales Navigator, Apollo.io, Lusha, Cognism, Clearbit, People Data Labs, ZoomInfo, Full Enrich, Kipplo, Prospeo, BetterContact, Clay, and Bitscale. Sales engagement integrations include Outreach, Salesloft, Apollo.io, and HubSpot Sales, and signal integrations include Google Analytics, rB2B, SEMrush, Ahrefs, and Hotjar. Youkti states it is constantly adding new integrations. Contact data, buying signals, and intent are described as free, with no card and no meter. In summary, Youkti's core value proposition is that it is the outbound system that thinks: it remembers every account, conversation, and deal, continuously watches for signals across the market, scores and reasons about that intelligence, and then converts it into specific actions — from building a campaign through conversation to pushing a personalized sequence and tracking what happens next.

Work Life Panda is a task manager and calendar that live together in one calm app, available on iPhone, iPad, Android and the web. Instead of asking you to rebuild your life inside a new tool, it starts with the life you already have: you connect the calendar you already use and your week is simply there, then you capture everything else in a sentence. Every task and every event carries its own chat, its own files, its own people and its own tracked history, so the plan and the conversation about it stay in the same place. It is built for personal and family life as well as for teams and small businesses, and it is designed to be a single connected workspace rather than one more app in the stack. Most task apps start empty and ask you to rebuild your life inside them. Your week, meanwhile, lives in a calendar, your to-dos live in a list, and your plans live in a group chat - three separate places that rarely agree with each other. Work Life Panda's stated position is that this scattering is the problem: the product asks you to stop scattering your life across separate tools. By connecting the calendar you already use rather than importing a copy of it, the app arrives already full of the week you have. Invitations that sit in your email become events on their own, so nothing has to be forwarded, copied or retyped. The result is meant to be one calm place for everything you have to do and everywhere you have to be. Calendar connectivity is the foundation. Work Life Panda supports Google, Apple iCloud and Microsoft Outlook calendars, all syncing both ways, plus Fastmail and Zoho, and it can follow any calendar that is published as a link. The stated approach is that the calendar remains yours rather than becoming a copy: change something in either place and both stay right. Because your to-dos and your whole schedule sit together, planning happens against the real week you actually have. The product also connects to email: a booking that lands in your inbox becomes an event on your calendar, and connecting an iCloud or Outlook mailbox turns the invitations already sitting there into events on their own, with no forwarding and no copying. Gmail support is described as waiting on Google's security review. Panda AI handles the busy steps. It turns a sentence or your voice into a task, smoothing the parts of capture and structuring that usually slow people down. Crucially, it runs on your device rather than in the cloud, so nothing goes to the cloud, and it works with no internet connection. That design choice is presented as a privacy and control feature: the AI that turns a sentence into a task runs on your device, so your data stays with you. Capture is meant to be fast enough to keep up with a passing thought, and the structure the AI produces keeps that thought connected to the rest of your life instead of leaving it loose in a notes app. The stated goal is that you keep control while safe local AI automates the busy steps, moving faster without handing your life to an opaque cloud. A chat on everything is the second core idea. Every task and every event carries its own chat, files, people and tracked history, so the conversation lives on the thing it is about. You can discuss and decide on the item itself, assign it, hand it off and see what moved. Sharing one with your partner, your family or your team means nobody has to ask where it was decided. You can also connect a calendar into a shared space so everyone sees it. In teams and shared contexts this replaces the familiar pattern of a plan living in one tool while the discussion about it lives in a noisy chat thread - the plan and the conversation stay together. Work Life Panda organizes life into shared spaces. You pick the shape that fits - a home for personal and family life, or one for the teams, groups and small businesses you plan with; the app is described as the same calm place either way. Within that, the product manages people, roles, kids and rewards from the same core workflow, covering shared responsibilities, family routines and reward systems. Birthdays, anniversaries and other important dates are kept in one place so the personal moments that matter do not slip through the cracks. Notes stay connected too: ideas, lists, meeting notes or family context can be captured without losing the connection to what needs doing. Together these make the product, in its own words, more than a task app - one evolving operating layer for life. The same source of truth follows you across phone, tablet and desktop, so your life does not split just because your devices change. On iPhone and iPad you capture, plan, collaborate and stay on top of life from the device already in your hand; Android keeps the same connected workflow with the same shared model, collaboration and AI-assisted experience; and the web app is there when you want a larger workspace for planning, reviewing and coordinating. The app can be downloaded from the App Store and Google Play, or opened in your browser. Because the AI runs on-device and the app works offline, using it across devices does not mean depending on a connection. The stated benefit is calm and continuity: everything you have to do and everywhere you have to be in one place, with nothing to import and nothing to retype. Because the calendar is connected rather than copied, there is no duplicate to maintain and no drift between two schedules. Because every task and event has its own chat, decisions are recorded where the work is, and no one has to reconstruct where something was decided. Because the AI is local, privacy is preserved and capture still works without a connection. And because the app opens on the life you already have rather than an empty list, that value is available from the first moment instead of after a long setup. Work Life Panda describes itself in terms of real scenarios. For personal and family life, that means chores, kids, plans, reminders, notes and birthdays captured in a sentence and kept in one private place on every device you already own, with no shared wall tablet required. For teams and business, it covers trips, clubs, shared houses, side projects and small teams, giving a plan a real home where tasks, events, files and the conversation about them live together instead of being scattered across a chat thread and three tools. A concrete flow the product illustrates is a booking landing in your inbox and the event landing on your calendar, alongside a weekly calendar with an event imported from email shown next to the day's task list. Shared spaces let a partner, family or team discuss, decide, assign and hand off on the item itself. Work Life Panda is free to use - completely free during early access, including every Pro feature - and the company states that early members always get its best pricing later. It works on iPhone, iPad, Android and the web, with downloads from the App Store and Google Play and a browser app for a larger workspace. Calendar integrations explicitly named are Google, Apple iCloud and Microsoft Outlook, all syncing both ways, plus Fastmail and Zoho, with support for any calendar published as a link; iCloud and Outlook mailboxes can be connected so invitations become events automatically, while Gmail is waiting on Google's security review. The audience is described as two broad groups: personal and family life, and teams, groups and small businesses. Early access members can tell the team what they want directly from the app, and the roadmap includes smarter capture and more ways to share. Work Life Panda's primary value proposition is simple: every task, every calendar and every conversation in one calm place, with private on-device AI smoothing the busy parts. It does not ask you to start from an empty list - it starts with the life you already have, keeps your existing calendar connected rather than copied, and puts a chat, files, people and tracked history on every task and event so decisions stay with the things they are about. Free during early access, available across iOS, Android and the web, and private by design because its AI runs on your device, it positions itself as one evolving operating layer for the way you live and work.
The macOS Dock does very little, and you cannot personalise any of it. DockFix replaces it with a dock you control completely, adding colours, opacity, size, position, animations, custom app icons, folders, website shortcuts, presets, a file shelf, widgets and window previews. It is built for macOS users who want their Dock to feel personal while still looking and behaving like it came with the Mac, and it runs on macOS 14 or later on both Apple silicon and Intel machines. DockFix exists for one reason, as founder Gustav Lübker of AppVerge puts it: the Dock that comes with your Mac is not yours. Apple designed it to be fast and reliable and then closed it, so you cannot personalise its colour, its icons, its animations, or much of what sits inside it. DockFix was built to hand all of that back to the user. The hard part, according to the founder, is that a dock you have made your own is only worth having if it still feels like part of macOS — the magnification has to carry the right weight, a window has to fold toward the corner it came from, and an icon has to appear the instant the app does. Miss any of that and people feel it straight away, even when they could not tell you what is wrong. Customisation is the core of the product. Colours, opacity, size, position, animations and icons can all be configured to your likings, so the dock can match a wallpaper, a workflow or a mood. DockFix also supports folders, website shortcuts and presets, meaning items can be grouped, a site can be pinned to the dock, and a complete configuration can be saved and reapplied. Community presets take this further: a theme can be applied instantly with one click, and the site points to a Community Docks gallery at dockfix.app/discover where users share the setups they have built. Custom app icons let you apply your own artwork to any app on the system, including the native apps macOS will not otherwise let you touch. That means Finder, Launchpad, Safari, Mail and the rest can be redrawn to match a theme rather than being locked to Apple's originals. For anyone who cares about visual consistency across the desktop, this removes the last element that Apple's closed Dock design left unchangeable, and it works app by app rather than as an all-or-nothing switch. Widgets place useful information and quick controls directly in the dock itself. The site names media playback, the clock and shortcuts as examples, so a now-playing panel, a time display and quick actions can live in the same strip as your apps and folders, available wherever you are. Because they sit in the dock rather than in a separate window or the menu bar, they stay within reach without adding another place to look, and they are described as useful information and quick controls in one place. Window previews are billed as the most requested feature. Hovering over an app shows its open windows live, and you can jump straight to the one you want instead of cycling through them one by one. That turns the dock into a way of navigating open work rather than only launching it. The rebuild also delivered a completely new interface, designed from the ground up to be modern and intuitive, alongside a new engine. DockFix's custom dock is built to look and animate exactly like the system dock straight out of the box, with the same magnification and true liquid glass, so customisation does not come at the cost of the feel people expect from macOS. The current release is a ground-up rebuild rather than an update layered on the old app. Every part of DockFix was rebuilt: a new engine, a new interface, and a dock that looks and behaves like it came with your Mac, with every bit of customisation that existed before still present and a great deal more added. The founder notes that the team stopped adding to what they had and rebuilt the app from nothing, with no line of the old code left in place, because a rewrite is not something you can do halfway. The result is a dock that moves like Apple's and then does what Apple's will not, without any of it feeling bolted on. Performance is treated as a feature rather than an afterthought: the new version uses under one percent CPU on average, and it runs on both Apple silicon and Intel Macs running macOS 14 or later. DockFix requires no special permissions and never asks you to disable System Integrity Protection. While it runs it hides the system Dock and restores it when you quit, so nothing on the system is changed permanently. On privacy, the site states plainly that there is no tracking and no usage collection of any kind; the only data stored is your email address, kept to manage your licence and answer support requests. The outcome for users is a dock that feels personal without feeling foreign — Apple's speed and polish, but configured however you like, with the features Apple never added. Because DockFix keeps the same magnification and liquid glass appearance as the system dock, switching is not jarring; because it stays under one percent CPU on average, it is not something you have to worry about leaving running. Existing owners get the rebuilt version free, with the licence carrying over automatically and nothing to move or reactivate, so upgrading carries no risk, no extra cost and no configuration work. In practice, DockFix suits a range of everyday workflows. A user who wants a dock that matches a wallpaper or a desktop theme can set colours, opacity, size and position, then apply a community preset in one click rather than rebuilding the look by hand. Someone working with many open windows can hover over an app, see those windows live and jump straight to the one they need. Anyone who keeps media playing can leave playback controls and the clock in the dock itself. Users who dislike Apple's default icons can apply their own artwork to the native apps macOS usually locks down, and people who keep files or links close at hand can use the file shelf, folders and website shortcuts. Students get 30% off, and anyone with an older licence simply updates to the new version at no cost. DockFix is aimed at macOS users on macOS 14 or later, on Apple silicon and Intel machines, who want to personalise the Dock beyond what Apple allows. It is a paid desktop app priced at €14.99, paid once and used forever, with no subscription. Every purchase comes with a seven-day free trial with every feature unlocked and no card required, and settings carry over if you buy during or after the trial. There is a 30% discount for enrolled students. Support is available through the support page and a Discord server, where the site says most questions are answered within a day, and a lost licence key can be recovered from inside the app. The new version is free for anyone who already owns DockFix. Taken together, DockFix is a macOS Dock replacement built around one idea: the dock that ships with your Mac is not yours, and it should be. By rebuilding the app from nothing — new engine, new interface — AppVerge delivered a dock that looks and animates like Apple's, keeps the magnification and liquid glass feel intact, and then adds everything Apple's Dock will not do: window previews, widgets, custom icons, folders, presets and the file shelf. For €14.99 once, with a free seven-day trial and a free upgrade for existing owners, it offers a fully customisable dock that stays light, safe and private.
Captain Kill Switch is a free utility for macOS, Windows, and Linux that lives as a quiet menu-bar or system-tray button. Its purpose is simple and focused: close every running app the instant you need a clean slate. It is for anyone who wants to reset their desktop without manually quitting applications one by one—whether before a presentation, a screen-share, a game, or just to clear their head. The product runs 100% locally, requires no account, and is described as private and cross-platform. It is built to do one thing extremely well, with no bloat, no dashboards, and no upsell. Instead of a complex interface, it offers one calm, decisive click. Modern desktops get cluttered. Multiple apps, windows, and background processes accumulate, and closing them manually takes time and attention. The traditional methods—Alt-Tab, Cmd-Q, clicking each dock icon—can be slow and distracting, especially when you are about to present, share your screen, or start a game. Captain Kill Switch addresses this by replacing the multi-step cleanup with a single action. Instead of hunting through open windows, you click one button or press one hotkey, and every open application closes. The product is designed for the moment you need a fresh start immediately, not after a slow shutdown routine. It solves the problem of chaos on the desktop by making the reset instantaneous. The core feature is instant, one-click reset. When you click the menu-bar icon, every open application closes in milliseconds. This is positioned as perfect before a presentation, a screen-share, a game, or simply to clear your head. A second key feature is the global hotkey. You can bind a keyboard shortcut and fire it from anywhere, so you do not need to find the menu bar first. The website calls this your panic button, always one keystroke away. To set it, you open the menu-bar icon, go to Preferences, then Shortcut, and press the key combination you want. The recommendation is to pick something deliberate so you never trigger it by accident. Together, these two features mean the cleanup action is always accessible and takes only a moment. Captain Kill Switch lives in your menu bar or system tray. It is a discreet tray icon, nothing more. The product uses minimal memory, creates no dock clutter, and has no background CPU usage. You can forget it is there until you need it. It also requires zero configuration. You install it, and it just works. There is no setup wizard, no permissions maze, and no manual. The entire interface is a quiet tray icon and a single button. This minimalist approach keeps the utility out of your way while still being immediately available. It is designed to do one thing extremely well without adding bloat, dashboards, or upsells. The app includes smart detection that closes your applications while leaving critical system processes untouched. This protects what matters, so your Mac or PC stays stable rather than becoming stranded. It also is truly cross-platform, offering the same calm, single-button experience on macOS, Windows, and Linux. You learn it once and can use it on every machine you own. This consistency means the product fits into mixed-device environments without requiring different habits or relearning. The cross-platform nature is a core selling point: the same button, the same behavior, across all supported operating systems. The workflow is described in three steps. Step one is install and forget: download for your OS and open it once. Captain Kill Switch tucks itself into your menu bar or system tray automatically. Step two is hit the button: when you need a fresh start, click the tray icon or press your global hotkey. One action is the whole interface. Step three is clean slate: every app closes at once, leaving you a quiet, empty desktop ready for whatever is next. You can repeat the process whenever the chaos returns. This methodology relies on a single-purpose utility that waits in the background and acts only when triggered. There is no complex configuration or ongoing management. The benefits are speed, simplicity, and stability. You get a clean desktop almost instantly, without the Alt-Tab or Cmd-Q marathon. Because each app is asked to quit properly first, your next launch is clean with no crash-recovery prompts—though anything still open a couple of seconds later is force-closed, unsaved work included, so you should save what matters before firing. The app stays private: it runs 100% locally, never phones home, requires no account, and has no ads. Anonymous usage statistics and crash reports help improve the product, but events carry only a random install ID, never your name or information about the apps, files, or windows on your machine. Nothing is sold or shared. On macOS, builds are signed with an Apple Developer ID and notarised by Apple, so the app opens with a normal double-click and no security warnings. On Windows, SmartScreen may show a warning because the app has not been widely downloaded yet; you can click More info, then Run anyway. The app is tiny and runs locally. Several concrete scenarios are highlighted. Before a presentation, one click removes every open app so your audience sees a clean desktop. Before a screen-share, the same action prevents distracting windows from appearing. Before a game, it clears the desktop so you can start fresh. When you simply need to clear your head, it creates a quiet, empty workspace in milliseconds. It is also useful whenever the chaos returns and you need to repeat the reset, or when you are moving from one task to another and want a clean slate. The product is ready whenever you are, and installs in under a minute. You can forget about it until the moment you need it most. Captain Kill Switch is for users of macOS, Windows, and Linux who want a fast, private, one-button way to close all apps. It is available as a free download for all three platforms. On Windows 10/11, the latest version is v0.4.4, with an EXE installer recommended, plus an MSI installer, winget, and Scoop options. On macOS 10.15+, the same version offers a DMG package recommended, a PKG installer, and Homebrew formulas for the app and CLI. On Linux (Ubuntu, Debian, Arch), there is a DEB package recommended, an APT repository, and a terminal CLI install script. The latest release v0.4.4 covers macOS, Windows, and Linux and was released August 28, 2026. Pricing is free forever, with no account and no ads. Uninstalling is straightforward: quit it from the menu bar, then drag the app to the Trash on macOS, uninstall from Apps & Features on Windows, or remove the package on Linux. It leaves nothing lingering behind. In short, Captain Kill Switch is a focused, free, cross-platform utility that puts one button between you and a clean slate. It closes every running app on demand, protects critical system processes, respects your privacy, and stays out of your way until the moment you need it most. If you value a calm, decisive reset without dashboards, upsells, or manual app quitting, this product is designed exactly for that purpose.
FrameSketch is a video annotation tool that lets you sketch right on top of your footage. It is built for animators, VFX artists, and motion designers who need to mark up arcs, poses, and breakdowns on moving images instead of describing them in words. You step through frames, draw over the canvas, and keep your lines exactly where you left them, then hand the result to whoever needs to see the shot. The site states the intent plainly: no uploads, no lag, just your lines exactly where you left them. FrameSketch runs in the browser at app.framesketch.xyz and is free to use. The problem the product addresses is the friction of reviewing and annotating motion. The site describes the alternative as animation-suite bloat: heavy software where you open a file, fight plugins, and juggle exports before you can get back to the shot. It also promises there is no export roulette and no timeline lag, which are the usual complaints when scrubbing footage and drawing over it in a general-purpose tool. The other half of the problem is privacy and waiting. Cloud-based annotation means uploading footage before anyone can mark it up; FrameSketch instead keeps everything on your machine, so your footage never leaves your device and cloud sync, when enabled, only carries annotations. For studios handling unreleased client work, that distinction matters. The drawing tools are organised around frame accuracy. Lines land on the exact frame, and you can step forward, step back, or scrub while the canvas never drifts from the video, so a mark you place on a frame stays on that frame. Onion skin lets you peek at the frames before and after and tune the ghosting until it feels right, which is how animators check spacing, timing, and the read of a pose. Strokes stay put: each line is fixed the moment you lift the pen, so your marks stay exactly as drawn, frame after frame, without re-tracing as you move through the timeline. The brush setup is described as four pens and one palette, and the tool strip lists pressure-sensitive input. The page also shows a scrubber running from frame 0000 to frame 0144 as an example of stepping through a section of footage. The studio adds the tools a shot review normally needs, built in rather than bolted on. A frame-by-frame timeline lets you walk the footage frame by frame, mark a stretch of it, and play just that range on a loop, which is useful when a single cycle or transition needs repeated scrutiny. Layers let you stack strokes, shapes, and notes on real layers, then reorder them, hide them, and dial in each layer's opacity, which keeps a busy annotation from turning into one inseparable mess. Notes and comments appear as sticky notes and comment markers pinned right on the frame; you can move, resize, recolor, and edit them at any time, so feedback stays attached to the exact moment it refers to. Alignment and navigation tools help you place marks precisely. Grid, rulers, and guides offer rectangular or isometric grids drawn as dots or lines, and you can drag guides out of the rulers to line your marks up where you need them. Pan and zoom let you zoom into the detail and move around the shot while your marks stay exactly where you left them. Scenes and backgrounds support one project with many scenes, and every scene sits on a solid background layer, so you can hide or dim the video whenever you want to see your own drawn lines without the footage competing for attention. The welcome screen rounds this out with recent projects one click away, described as an escape from project browser rabbit holes. Underneath, FrameSketch takes a local-first approach. It runs entirely on your machine; cloud sync is optional and, when switched on, only carries annotations rather than media, and you can turn it off so everything stays local. Projects are saved as a single small .fsk file that holds every stroke; the site says a whole project is a few hundred kilobytes, small enough to email, stash, or version. Because the file is that light, sharing a review does not mean exporting video or uploading anything: you send the .fsk, the other person opens it, and they can keep going. The app reads video files straight from your machine and re-encodes nothing. The file picker only lists what your platform can really play: MP4 with H.264 in an MP4 container is recommended and plays on every platform, browser and desktop; MOV is a QuickTime container whose H.264 content plays everywhere; M4V shares the same H.264 core as MP4; and WebM uses the open VP8/VP9 codec, playing on Windows, Linux, and Chromium, though on macOS MP4 or MOV is advised. Anything else can be converted once to H.264 MP4 and it will play anywhere. The product is described as working in the browser with web and PWA support, and desktop apps for Windows and Linux are coming soon. The practical benefits follow from those choices. Privacy is the headline: your footage never uploads, so confidential or unreleased material stays on your own device while you still get optional sync for annotations. Speed is the second: drawing at 60fps and a frame-accurate canvas that never drifts means marking up a shot feels immediate rather than waiting on a round trip to a server. Small project files make collaboration cheap, since emailing a few hundred kilobytes and versioning it like any other small asset is far easier than moving video around. And because the tool deliberately avoids suite-level complexity, time to first mark is short; the site claims your first arc takes about ten seconds. Concrete workflows the tool is built around include animating arcs and poses over reference footage: load a shot, step to a frame, and draw the arc, breakdown, or pose directly on the picture. Shot review is another: pin sticky notes and comment markers to specific frames, then send the project to a colleague or director who can open it and add to it. Timing and spacing checks lean on onion skin, letting you compare neighbouring frames with adjustable ghosting to judge how a movement reads. Aligning marks to a layout uses the grids and rulers, whether rectangular or isometric. Privacy-sensitive work benefits from the local-first model, since client footage never needs to be uploaded. And because a project travels as one .fsk file, remote collaboration is as simple as emailing an attachment and continuing where the other person left off. FrameSketch is aimed at animators, VFX artists, and motion designers, the people who think about motion frame by frame, and its marketing addresses animators directly. It is available as a web app and installable as a PWA at app.framesketch.xyz, with desktop apps for Windows and Linux listed as coming soon. Pricing is free to use, and the site reiterates that your footage never leaves your device. No plugins or additional software are needed for the core workflow, and the tool opens straight from the browser ready for you to draw. FrameSketch's value proposition is narrow and deliberate: annotate video the way animators actually think, frame by frame, on top of the footage, without uploading anything. Drop in a local file, draw arcs, breakdowns, and notes with tools like onion skin and frame-accurate stepping, share a tiny .fsk file with collaborators, and keep your footage private the entire time. It is a free, browser-based video annotation tool for animators, VFX artists, and motion designers who want to mark up motion quickly and get back to the shot.

LinkFlick is a macOS menu bar app that switches your Magic Mouse, Magic Keyboard, and Magic Trackpad between any Macs on your local network. Its purpose is simple: hand off Apple's Magic peripherals from one Mac to another in a single gesture, with no cables, no dongles, no iCloud, and no re-pairing. You install LinkFlick on each Mac you want to move devices between, and it waits quietly in the menu bar until you need it. The app is built for people who work across more than one Mac — a laptop and a desktop, a personal machine and a work machine — and who want their keyboard, mouse, and trackpad to follow them to whichever screen they are working on rather than staying stuck on the Mac that last claimed them. The problem LinkFlick addresses is the friction of shared Apple peripherals. Magic devices can only talk to one Mac at a time, so anyone moving between machines has to go through the Bluetooth pairing process again and again: unpair here, discover there, confirm, and repeat on the way back. The launch notes describe exactly this frustration — re-pairing a Magic Keyboard and Magic Mouse every time the maker moved between a personal MacBook and a work MacBook. Because those two machines used different Apple IDs, Universal Control was never going to be an option. LinkFlick takes a different route: it works at the Bluetooth and local network level instead of depending on Apple's ecosystem features, so it does not care which Apple ID is signed in, whether the Macs belong to the same person, or how the two machines are configured. The goal is to remove the digging through menus that makes peripheral sharing painful. Switching is deliberately minimal. LinkFlick lives in your menu bar and presents your Macs as a cluster of trusted peers that are instantly available for a switch. A single click — or a customizable hotkey, or a spoken command to Siri to flick devices — moves the keyboard, mouse, and trackpad to the other Mac in one gesture. There are no cables and no dongles involved; it is a hand-off of your controls between machines. Because the control is explicit and lives in the menu bar rather than following the cursor across screens, you do not have to worry about your pointer drifting off the edge of the screen by accident. As the site puts it, everything is there and you simply continue exactly where you left off. LinkFlick's key technical idea is that it moves the physical hardware, not just the cursor. Instead of bridging an input stream across the network, it re-pairs the peripherals at the Bluetooth layer, so the destination Mac sees a real Magic device — a genuine Magic Keyboard, Magic Mouse, or Magic Trackpad — rather than a forwarded or emulated input signal. The site describes this as native by design, with no iCloud dependency, no network relays, and no limits. LinkFlick supports 1st and 2nd generation Magic hardware, covering keyboard, mouse, and trackpad. The app intentionally supports Apple's Magic peripherals only, and the FAQ explains why: these devices enter Bluetooth discovery mode automatically after unpairing, which allows LinkFlick to perform a silent re-pair on the other Mac without PIN codes or confirmation dialogs. The site explicitly notes that third-party devices from Logitech, Razer, and similar brands are not currently supported. Because LinkFlick operates at the Bluetooth and local network level, it has no dependency on iCloud or Apple ID. You can move a Magic Mouse between a personal MacBook and a work Mac Studio signed into different accounts without any configuration. Macs are discovered automatically: LinkFlick uses Bonjour to find your Macs on the local subnet, with no cloud servers involved, and both Wi-Fi and Ethernet work as long as all Macs are on the same network. The app also keeps an eye on your peripherals. It displays battery levels, and the launch post notes that it nags you before your Magic Mouse battery dies. Alongside that, LinkFlick senses power and display status: the moment you connect power or a display, it wakes up, checks where your devices need to be, and offers a gentle nudge that your Magic Keyboard, Mouse, and Trackpad are still on another Mac. Putting it together, LinkFlick forms a cluster of trusted Macs. You install the app on every Mac you want to transfer devices between; it runs as a lightweight menu bar extra that uses almost no resources when idle. When you switch, the app hands off each device silently in the background — no pairing screens, no interruption — typically in 5 to 15 seconds, depending on how quickly macOS processes the Bluetooth pairing request internally. Before any of that, it needs two permissions: Bluetooth access to re-pair devices, and Local Network access to discover other Macs via Bonjour. It does not require administrator privileges, does not read keyboard input, and keeps all communication within your home or office network — nothing is sent to the cloud. If the destination Mac is off or asleep, your devices simply stay connected to the current Mac, and the other machine reappears in the Flick List as soon as it wakes and LinkFlick reconnects. The outcome is continuity. Your workflow follows you between machines: you open your editor on the other Mac, pick up your mouse, and carry on right where you left off, without touching a Bluetooth settings pane. Devices arrive waiting rather than requiring you to go find them. Switching happens in the background while you are already turning to face the other screen, and if a transfer cannot happen because the target Mac is unavailable, nothing breaks — your devices stay where they are and the opportunity to move them returns on its own. With no cloud, no account, and no admin rights required, the setup is also private and lightweight by construction: your input devices and your data never leave the local network that your Macs already share. Concrete scenarios are easy to picture. A developer plugs their MacBook into a desk setup with an external display; the moment power and display connect, LinkFlick notices and offers to bring the Magic Keyboard, Mouse, and Trackpad back from the desktop Mac. Someone who splits their day between a personal MacBook and a work Mac with a different Apple ID uses a hotkey or a Siri command to flick devices over and back as meetings and tasks demand. A home user with a laptop and a desktop moves their Magic Mouse and Keyboard between the two without re-pairing either time. Power users with a full multi-Mac setup — up to five Macs on the Pro plan — keep one set of peripherals useful across every machine on the same network. LinkFlick is aimed at Mac users who own more than one Mac and at least one Magic peripheral: people working across laptop and desktop, individuals bridging personal and work machines, and power users running a full multi-Mac arrangement. The app requires macOS 14 Sonoma or later, and all Macs must be on the same local network. Pricing is a one-time purchase with no subscriptions: the Personal plan costs $14.99 and covers up to 3 Macs, described as perfect for working between a laptop and a desktop at home, while the Pro plan costs $19.99 and covers up to 5 Macs for power users and full multi-Mac setups. Both plans include auto device discovery, instant switching, battery level display, trusted peers, free updates, and no cloud or account requirement. A 14-day free trial is available with no credit card required; on the trial you can connect up to 3 Macs — your local Mac plus 2 trusted peers. LinkFlick's core value proposition is straightforward: stop re-pairing your Magic Keyboard, Mouse, and Trackpad every time you change Macs. By moving devices at the Bluetooth layer, discovering Macs over Bonjour on the local network, and keeping the whole experience inside a menu bar app with a hotkey or a Siri command, it turns a tedious pairing ritual into a one-click hand-off — no iCloud, no Apple ID dependency, no cloud servers, and no admin privileges, just your Magic devices following you between the Macs you already trust.
Coldline AI, also styled ColdLine.ai, is an AI-powered outreach tool that turns cold prospects into hot leads with personalized pitches. As described in its Product Hunt listing, users simply add their prospect's details and Coldline AI creates a relevant, human-sounding pitch in seconds. Its stated purpose is to help users save time, personalize outreach, and get more replies without writing every message from scratch. It is presented as a fit for founders, sales teams, marketers, recruiters, and agencies, and its official website summarizes the brand's positioning with the headline "Innovate with AI Today." Cold outreach is a numbers game, but the numbers only work when messages feel like they were written for the individual receiving them. The tension Coldline AI is built around is the trade-off between personalization and time: crafting a tailored pitch for every prospect means writing every message from scratch, which scales poorly for anyone reaching out to more than a handful of people. At the same time, outreach that is not personalized tends not to earn replies, and recipients can generally tell when a message is a template with a name dropped in. Coldline AI addresses this tension by automating the pitch-writing step while keeping the output relevant and human-sounding, so personalization no longer has to be sacrificed in the name of speed. The result the product aims for is outreach that is both fast to produce and specific enough to deserve an answer. The core capability described for Coldline AI is AI-powered personalized pitch generation. Instead of starting from a blank page, the user provides details about their prospect, and the product uses that information to produce a pitch that is relevant to that specific person. This is the mechanism behind the promise of turning cold prospects into hot leads: the message is built around the prospect's details rather than being a generic template that could be sent to anyone. The pitch is also described as human-sounding, so the personalization is not just factual but tonal. For anyone who sends outreach regularly, this means the personal touch that normally requires research and careful drafting becomes part of an automated step rather than a manual chore. Speed is an explicit part of the product's value proposition: Coldline AI creates the pitch in seconds. The immediate benefit is that a task which would otherwise take minutes of drafting — and much longer when multiplied across an entire prospect list — is compressed into a moment. Seconds matter in outreach because the real constraint is usually not the quality of a single message but the number of messages a person or team is able to send. When each pitch is produced in seconds, users can work through more of their prospect list without giving up the personalization that makes outreach worth sending. The speed also lowers the friction of starting: there is no blank page to fill, only details to add. The content emphasizes that the generated pitch is relevant and human-sounding. Relevance ties the message to the prospect's details, while the human-sounding quality addresses the risk that automatically written outreach reads as stiff or obviously machine-generated — a tone recipients tend to ignore or delete. The stated outcome is more replies, which means the pitch is written to be something a prospect will actually respond to rather than something that merely fills a message field. Combined with the promise of not writing from scratch, this positions Coldline AI as a way to produce outreach that feels personal without hand-crafting every sentence. For users, that distinction matters because a pitch that sounds human is more likely to be read to the end and answered. The overall workflow described by Coldline AI is deliberately simple. The user adds their prospect's details, and the product generates the pitch from that input. There is no described requirement to build templates in advance or to write a draft for the tool to edit — the pitch is created for the user from the details they provide. This input-then-generate approach is what makes the tool usable by people who are not professional copywriters, including founders, recruiters, and agency teams for whom outreach is one part of a much larger job. The methodology is essentially to let AI handle the composition while the human focuses on choosing who to contact, sending the message, and following up on the replies that come back. The benefits stated for Coldline AI are saving time, personalizing outreach, and getting more replies. These three are connected: time saved comes from not writing every message from scratch, personalization comes from generating a pitch around each prospect's details, and more replies are the expected result of outreach that is both relevant and human-sounding. For an individual, the benefit is fewer hours spent drafting and less fatigue from staring at empty message boxes. For a team, the benefit compounds, because every member can produce personalized outreach at a pace that previously would have required generic templates. The product frames these outcomes as the reason to change how outreach is written. Coldline AI is presented as suitable for a range of outreach scenarios. Founders can use it to reach prospective customers, partners, or investors without blocking out hours for writing, since each pitch is generated from the details they add for that person. Sales teams can use it to personalize cold outreach across a pipeline, producing a relevant pitch for each prospect they enter instead of choosing between volume and relevance. Marketers and agencies can use it for outbound campaigns and client prospecting, where personalization at the individual level is what separates a campaign from spam. Recruiters can use it to reach candidates with messages tailored to the person, rather than sending the same note to everyone. In each case the described workflow is the same: add the prospect's details, generate a relevant pitch, and send it. The explicit target audiences for Coldline AI are founders, sales teams, marketers, recruiters, and agencies — essentially anyone whose work involves reaching out to people they do not yet know. These are people who send outreach regularly and need it to feel personal in order to get replies, but who do not want to write every message from scratch. The Product Hunt listing also categorizes the product under Sales, Marketing, and Artificial Intelligence, which reflects that dual identity of an AI tool applied to a go-to-market function. Coldline AI is accessed through its official website at coldlineai.xyz, making it a web-based product, and it is listed on Product Hunt as "Coldlineai" with the tagline "Turn cold prospects into hot leads with AI-powered pitches." No pricing details are stated in the available content. In short, Coldline AI takes the most time-consuming part of cold outreach — writing a personalized pitch for every prospect — and turns it into a seconds-long automated step. By taking prospect details as input and producing a relevant, human-sounding pitch, it aims to let founders, sales teams, marketers, recruiters, and agencies save time, personalize their outreach, and get more replies without writing every message from scratch. That combination of personalization and speed is the core value proposition the product states.

Wisry is an agentic ad platform for ecommerce brands that turns an existing store into a source of high-ROAS campaigns. Described as an Agentic AdClone for ecommerce, it uses AI agents that analyze winning ads and generate high ROAS campaigns. The workflow begins when you paste your store URL: Wisry builds brand memory covering your products, voice, visual identity, and audience so that every agent stays on-brand. It then researches the ads already working in your market, generates evidence-backed campaign angles, generates video and static ads cloned from the best performing creative, and ships them to Meta and Google. It is built for ecommerce brands and agencies that want to launch high-ROAS ads roughly ten times faster, with research, creative, and launch handled end to end in minutes rather than weeks. The problem Wisry addresses is the guesswork behind ecommerce advertising. Advertisers typically start from a blank canvas, invent angles, produce creative, and then wait to see what converts, which is an expensive and slow loop. Wisry starts from a different premise: winning ads already exist in the market. Its research agent reads the Meta ad library and TikTok top ads, deep-analyzes competitor ads and content, and identifies what is already converting. Instead of briefs built on assumptions, campaigns begin from ads with a live track record. In the studio's ad library view, ads are ranked to clone, for example one ad shown at 64 days live with 17 variants and 2.4M impressions, another at 35 days live with 10 variants and 1.1M impressions, and a third at 23 days live with 6 variants and 740K impressions, drawn from a set of 1,323 reviewed. That ranking makes the market's proven patterns visible before any budget is spent, which matters because in categories such as supplements the window for a trend closes quickly, and teams that spot and replicate what is winning first gain the advantage. Agentic ad research is one of Wisry's two flagship features. Research agents read the ads already running in your market, cite what they found, and turn the winners into angles you can brief. This is not a list of raw ads: the strategist agent converts research into campaign concepts covering audience, hooks, and messages, and provides source citations behind every angle. Evidence-backed angles mean the reasoning behind a campaign is traceable back to a real, running ad rather than to opinion. In practice, an ecommerce team can see which concept has survived the longest, which format has survived a full test cycle, and which has the fastest variant ramp in the category, and then brief creative against those findings. Wisry's second flagship feature is video ad cloning. You point Wisry at a video ad that works and get your own version of it, with the same structure and pacing but your product and your brand; the structure matched includes the hook, proof, and close. Static ad cloning works on the same principle: Wisry rebuilds a winning static in your palette, with your type and your product shots, then fans it out into every placement you need. What is kept and what is swapped is explicit: layout, headline structure, and type are retained from the source, while the palette and product are swapped for yours. This lets a brand reuse a proven creative formula without copying a competitor's product or visual identity. The studio also includes ad templates and video editing. Templates let you start from formats with a track record instead of a blank canvas, and every template arrives sized and safe-area-checked for its placement. Formats shown include listicle, problem-solution, quiz, portrait, us-versus-them, seasonal, feature-benefit, and how-to, sized for Feed 1:1, Feed 4:5, Portrait 2:3, Landscape 16:9, Reels 9:16, and Story 9:16, so the same idea can be produced across the placements a campaign actually needs. Video editing means every generated cut opens in a real editor where you can retime scenes, restyle captions, swap a shot, and re-render without leaving Wisry. Together these capabilities keep generated creative editable and controllable rather than locked, so teams can fine-tune an asset before it ships. Wisry works as a five-step loop handled end to end by agents. Step one: Wisry pulls your brand and products, so you paste your store URL and it builds brand memory covering products, voice, visual identity, and audience, keeping every agent on-brand. Step two: it studies your market's winning ads, with a research agent deep-analyzing your Meta and TikTok competitors' ads and content to find what is already converting. Step three: it generates evidence-backed angles for your campaigns, turning research into campaign concepts covering audience, hooks, and messages, with source citations behind every angle. Step four: it copies winning creatives for your products, generating video and static ads from the best performing ads and your chosen angles. Step five: the ads agent launches, optimizes, and repeats 24/7, shipping your ads to Meta and Google, watching performance, moving budget to winners, and keeping new creatives coming. The studio ships nine capabilities in total, all pointed at selling more of your products, with research and cloning described as the two flagship capabilities and the rest downstream of them. The stated outcomes are speed and performance. Wisry reports a +200% average boost in ad performance, says its strategist was trained on over $1B in ad spend, and claims it is 10x faster to launch a high-ROAS campaign with AI, with research, creative, and launch handled end to end in minutes rather than weeks. The intended benefit is that advertisers stop testing blindly and start scaling what is proven. In testimonials, a seller of a hardware product to Tesla owners, a niche audience where every ad dollar counts, says Wisry took what was already working in the account and multiplied it, with ROAS up 300%. A supplements advertiser says the value is spotting what is winning and replicating it before the window closes, shipping winning variations twice as fast. An agency says the bottleneck of research and iteration was removed, letting it scale client accounts much faster than a manual team could. Concrete scenarios follow from the workflow. An ecommerce brand pastes its store URL, lets Wisry build brand memory, and receives campaign angles plus cloned static and video ads ready to launch on Meta and Google. A growth team watching the ad library ranking picks a proven concept, such as a long-running contrarian concept with many live variants, and clones its structure into its own product. A creative team takes a generated cut into the editor to retime scenes, restyle captions, or swap a shot, then re-renders and ships. A media buyer uses the ads agent to keep optimizing, watching performance, moving budget to winners, and continuously receiving new creatives. An agency runs the same research and cloning loop for multiple client accounts, turning market research into output at a pace the testimonial describes as beyond what a team could touch manually. Brands in trend-driven categories such as supplements use it to react to what is winning while the window is open. Wisry is aimed at ecommerce brands and the agencies and media buyers serving them, particularly teams that want to scale paid social and search without adding research and creative headcount. Its agents are orchestrated using leading models: Grok, Gemini, OpenAI, Claude, KlingAI, and Nano Banana. The product is web-based, and the connections described in the content cover the Meta and TikTok ad libraries for research and Meta and Google for ad delivery. Pricing is a paid, prepaid subscription: 2 weeks at $49.50, 4 weeks at $99 marked Most Popular and offered at $49.50 with a 50% saving, and 8 weeks at $198 offered at $89.10 with a 55% saving. The checkout note states one payment of $49.50 for 4 weeks, then $99 per month, cancel anytime, secured by Stripe, and plans are described as costing less per day the longer you commit. Wisry was featured on Product Hunt with 308 votes and 49 comments. Wisry's proposition is straightforward: your store in, winning ads out. By turning the public ad libraries of Meta and TikTok into a ranked source of proven creative, rebuilding that creative for your brand as static and video ads, and then launching, optimizing, and repeating around the clock on Meta and Google, Wisry compresses ecommerce ad research, production, and optimization into minutes. For ecommerce brands and agencies that want high-ROAS campaigns without the guesswork, it positions the market's already-winning ads as the starting point rather than a blank canvas.
Devin Voice is the voice mode built into Devin, Cognition's AI software engineer. It lets you talk naturally with Devin to explore ideas, pressure-test an approach, and hand off work while you are away from your keyboard. Rather than typing every instruction, you start a voice call, speak your thoughts out loud, and let the conversation move at the speed of speech. Any message you have already typed is sent when you start the call, so you can move directly from a written prompt into a spoken discussion inside the same session. The Product Hunt listing describes the same idea more bluntly: you say it, Devin ships it, and you speak a task out loud while Devin plans, codes, and delivers. The capability is aimed at people who already work with Devin in Agent mode or in an existing session and want a conversational way to think through problems, ask questions, and keep work moving. Software work has long been keyboard-centric: you type a prompt, wait for a response, read it, and type again. Voice mode changes that rhythm by making the spoken conversation itself the interface between you and the agent. The documentation frames voice mode around three activities: exploring ideas, pressure-testing an approach, and handing off work while you are away from your keyboard. The stated tips reinforce how this is meant to feel in practice. You should not be afraid to interrupt Devin's work, and you should ask questions and clarify your thoughts as you have them. You are also free to interrupt Devin while it is talking. Together, those instructions describe a working style where clarification is welcome at any moment rather than something you have to schedule between long silences, and where getting your thinking out loud is part of the process rather than a disruption to it. Getting into voice mode is deliberately simple. On the home page in Agent mode, or inside an existing session, you click the voice call button that sits beside the message box and then allow microphone access. Hovering over the waveform icon shows a "Start voice call" tooltip, so the control is discoverable before you commit to a call. One detail worth noting: any message you have already typed is sent when you start the call. That means a half-written prompt or a queued instruction is not lost; it is delivered as the call begins, so your spoken conversation continues from the written context you had already built up. Starting from either the home page or an in-progress session means you can begin a call at the moment an idea strikes rather than having to set up something new first. Once a call is running, the documentation lists a small, clear set of controls. Mute microphone pauses your microphone, and clicking Unmute microphone lets you speak again. If you are muted but still want to say something without leaving the call, you can hold Space to talk while muted when you are not typing. Silence Devin turns off Devin's audio without muting your own microphone, and clicking Unsilence Devin brings the audio back. End voice call hangs up. These controls separate the two directions of the conversation, your input and Devin's output, so you can mute yourself while listening to a long explanation, or silence Devin's audio while keeping your own microphone live and ready to respond. Voice mode is not a separate, isolated room. You can navigate within Devin while the call stays connected, so you can move around the product without dropping the conversation. Your conversation appears in the session history, which means the spoken exchange becomes part of the recorded session rather than disappearing when you hang up. The documentation also notes that you can shape how Devin speaks: if you have preferences for how Devin should speak, for example to speak faster or slower, or a particular communication style, you can simply ask. There is no described settings panel for this; the adjustment happens through the conversation itself, which keeps the interaction consistent with the rest of the voice experience. Under the hood, the Product Hunt listing states that Devin Voice is powered by GPT-Live for natural conversation, with Cognition's new SWE-2 coding model under the hood. That combination is what the listing describes as letting Devin plan, code, and deliver after you speak a task out loud. Devin Voice connects you to Devin, described in the listing as Cognition's AI software engineer. On the documentation side, the overall description of how the feature works is straightforward: you talk naturally with Devin, in Agent mode or in an existing session, and the conversation is tied into the same session context, appearing in session history and continuing even as you navigate within Devin. The documentation also carries a standard note that responses are generated using AI and may contain mistakes. The benefits follow directly from those mechanics. Voice mode lets you explore ideas out loud instead of composing them in a text box, which the documentation positions as a way to pressure-test an approach. It lets you hand off work while you are away from your keyboard, so time spent away from a desk does not have to mean the work stops. Because you can interrupt Devin's work and ask questions as they occur to you, clarifications do not have to wait for a complete response, and because you can interrupt Devin while it is talking, you are not locked into listening to everything before you can steer the conversation. And because you can ask Devin to speak faster, slower, or in a different communication style, the spoken interaction can be tuned to your preferences. Concrete use cases flow from the documented behaviour. You might start a call on the home page in Agent mode, with a task already typed into the message box, and have that message sent as the call begins so you can talk through the task instead of typing more. You might be inside an existing session and open a voice call there to hand off work while you step away from your keyboard. You might keep the call connected while navigating within Devin, moving around the product without breaking the conversation. You might mute your microphone while Devin talks, or hold Space to talk while muted when you are not typing. You might silence Devin's audio without muting your own microphone so you can think or speak without the audio running. And afterwards, you can revisit the conversation in the session history. In terms of audience and context, the documentation is written for people using Devin itself, referring to the home page in Agent mode and to existing sessions, and describing the voice call button beside the message box. Product Hunt lists Devin Voice under Productivity, Developer Tools, and Artificial Intelligence, and the listing points readers to devin.ai to try Devin. The named technologies associated with the product are GPT-Live for natural conversation and Cognition's SWE-2 coding model under the hood. The documentation page does not describe pricing, plans, or platform availability beyond the described interface, and the listing does not state pricing either. The takeaway is straightforward: Devin Voice turns talking to Devin into a first-class way of working. You say it, and Devin ships it. By letting you start a call from the message box in Agent mode or an existing session, carry a typed message into the call, mute or silence either side of the conversation, keep working while Devin navigates alongside you, and simply ask for the speech style you prefer, voice mode makes it possible to explore ideas, pressure-test an approach, and hand off work away from your keyboard, with the conversation preserved in the session history.

TIM PG is a privacy guard utility that wraps intelligent data protection and security around the everyday use of artificial intelligence. It is built for people and teams who want to take advantage of large language models and other AI tools without handing over sensitive information, and it does this by automatically masking personal data from the clipboard before that data is pasted anywhere. Alongside clipboard protection, TIM PG anonymizes documents such as PDF and Office files, and uses Smart Bubble technology to protect individual text segments locally on a PC. The product is presented as a strictly offline, 100 percent AI-free Windows utility, so protection happens on the machine itself rather than in a cloud service. AI assistants have become part of ordinary working life, and the fastest way to use them is to paste text straight into the prompt. The trouble is that the text people paste often contains personal data — the kind of sensitive detail that was never meant to leave the organization or the user's own machine. Once such content reaches a cloud-based model, it is difficult to know where it goes or who may see it. TIM PG addresses this specific moment of risk: the copy-and-paste step that happens between a user's own documents and an external AI tool. Rather than asking people to change their habits or stop using AI, it intervenes at the clipboard itself, before the sensitive data has a chance to leave the local machine. The core of TIM PG is automatic masking of personal data from the clipboard. Before a user pastes anything into an LLM, the utility masks the sensitive data inside the clipboard content, so what reaches the AI tool is a version of the text without that personal data. Once the AI produces its answer, TIM PG restores the sensitive data back into the AI's response. That round trip matters because it means the AI's output stays usable: the user still sees their own real data in the final answer, even though the model itself never received it. Both the masking and the restoration are performed locally on the PC, so the protection step does not become another place where data can leak. Beyond the clipboard, TIM PG offers document anonymization for PDF and Office files. This extends the same principle from a single copy-and-paste action to complete documents, which are typically the source of the most detailed content in a business workflow. A user who needs to work with a PDF or an Office document alongside an AI tool can anonymize that document first, so the content that travels onward carries no personal data. Because document anonymization is part of the same local utility, it keeps the whole process inside the user's existing environment rather than requiring a separate hosted service or an upload to a third party. It is the same idea as clipboard masking, applied at document scale. TIM PG also introduces Smart Bubble technology for protecting text segments. Rather than relying on a single blanket rule for everything, Smart Bubble is designed to protect text segments locally on the user's PC. For people who work with mixed material — where some parts of a document need shielding and others do not — this offers a way to apply protection at the level of individual segments instead of treating the entire piece of content as one block. Like the rest of the product, Smart Bubble operates on the local machine, so protected segments are never exposed to an external service as part of the protection process. The overall approach of TIM PG is deliberately local. It is described as a strictly offline, 100 percent AI-free Windows utility, which means it neither relies on a cloud connection nor uses AI of its own to do its work. Masking, document anonymization and the restoration of sensitive data all take place on the user's PC. This design choice is what separates the product from privacy add-ons that route content through a hosted service: there is no server in the middle, so nothing about the user's data is transmitted as part of the protection step. The utility sits between the user's clipboard or documents and the AI tool they want to use, and it does its work in that gap. The promised outcome is straightforward: no cloud, no leaked data — just secure local data privacy for everyday workflows. Users can keep using the AI tools they have already chosen while reducing the exposure of personal data. Because the masking is automatic, the protection does not depend on the user remembering to redact text by hand, and because the restoration is seamless, the final AI answer still contains the real details that make it useful. The result is that privacy stops being a trade-off against productivity: a user can copy, paste, prompt and read the response much as they normally would, with an extra layer of protection working locally in the background on their Windows machine. TIM PG is designed for the everyday scenarios in which text moves from private material into an AI tool. The most direct example is pasting clipboard content into an LLM, where TIM PG masks the personal data on the way in and restores it on the way out. A second scenario is working with PDF and Office documents that need to be anonymized before they are used with AI assistance. A third is the handling of individual text segments that require local protection through Smart Bubble technology. In each case the workflow ends the same way: the user gets the benefit of AI processing while the sensitive data stays on their own PC. TIM PG is a Windows utility, so it fits naturally into Windows-based business environments. It is presented on a website that also describes TIM, a next-generation business platform, and TIM TL, smart helper tools for daily business processes, alongside a statement that the team brings decades of development and IT security background to guarantee business stability. That positioning suggests the product is aimed at business operations and utilities users who need practical, secure tooling rather than experimental AI features. The site states that intelligent data protection and security are the goal for the safe use of artificial intelligence, and it offers a demo as well as a way to request a consultation. No pricing or plan information is stated in the available content. TIM PG's value proposition is narrow, clear and practical: it protects sensitive data at the exact moment it would otherwise be exposed — when it is pasted into an AI tool. By masking personal data from the clipboard, anonymizing PDF and Office documents, restoring protected data into the AI's response and using Smart Bubble technology to protect text segments locally, it lets people keep working with AI without sending their private information to the cloud. Strictly offline and 100 percent AI-free, TIM PG is local data privacy built for workflows that depend on AI.

Design Studio by Monday Merch is a browser-based canvas that lets anyone design custom merchandise directly onto the product they are ordering. It brings together more than 1,000 products—from Premium T-Shirts, Premium Polos, hoodies and caps to drinkware like the Sleek Bottle and Dopper Original, tote bags, mugs, pens and jackets—inside a single design environment. Instead of designing artwork in one tool and then guessing how it will look on a finished item, you place your logo, artwork or text straight onto the product, viewing it from every angle in 2D, with selected products also available in 3D. The tool is meant for anyone who needs to produce branded or custom merch, including teams, businesses and individuals, and it is free to use with no design skills needed. Traditionally, creating branded merchandise is a fragmented, error-prone process. A designer might prepare artwork in a separate graphics program, then hand it off to a printer, only to discover that the placement, size or format does not match the product's printing requirements. Colour choices, print areas and production rules often live outside the design tool, which means a design can look right on screen but fail in production. Design Studio addresses this by keeping the design and the production requirements in the same place, so what you create is grounded in the realities of the product you are ordering. It aims to reduce the back-and-forth between design and production and to make merch design accessible to people who are not professional designers. The backbone of Design Studio is its catalogue of product templates. The platform offers over 1,000 products, organised so that you can browse and start from a template. Featured examples include the Premium T-Shirt, Premium Polo, Unstructured 6 Panel Cap, Structured 5 Panel Cap, Vintage Low Profile Cap, Dad Cap, Classic Hoodie, Premium Hoodie, Classic Sweatshirt, Fleece Zipper Jacket, Columbia Men's Full Zip Fleece Jacket, Heavyweight Oversized T-Shirt, Lightweight T-Shirt, Classic T-Shirt and Premium Women's T-Shirt, alongside drinkware such as the Sleek Bottle (500 ml), the Dopper Original (450 ml) and the Ceramic Glazed Mug, plus the Stainless Camp Mug, Dual Color Shopper Tote and Contemporary Pen. Each template can be opened directly with a "Design Now" action, so you can begin placing your artwork onto a realistic product view. Products are grouped into categories such as Apparel, Bags, Drinkware, Office, Packaging, Stickers & Print, Tech and Events, making it easier to find the right blank item for a given project. Beyond product templates, Design Studio also provides a library of print templates for paper-based and printed items. These include Christmas cards such as the Merry & Mint Xmas Card and Santa Xmas Card, thank-you cards, invitation cards like the Wax Seal Invitation Card, event materials such as the Running Event Flyer, posters such as the Good Vibes Poster, the Office Values Poster and the Mental Health Awareness Poster, menu cards such as the Alcohol Menu Card, and guides like the Recipe How To Guide Flyer. Print templates make it possible to design a broader range of collateral—everything from cards and flyers to posters—inside the same environment you use to design physical merchandise, so a single brand look can be applied across apparel, drinkware and printed materials. Design Studio includes several features that streamline the design process. You can add your brand hub with a click, which lets you create designs instantly using your own brand assets, so you do not have to rebuild your logo or colours from scratch each time. You design straight on the product, with every angle available in 2D and selected products also available in 3D, which helps you understand how the finished item will look from different viewpoints. The price is shown while you design, so you can see the cost implications of your choices as you make them. Printing rules and requirements are baked into the tool, meaning the designs you create are set up to be ready for production. And you can easily share and collaborate, which supports team workflows around a design. The core approach of Design Studio is to collapse the gap between designing and producing. Rather than treating design as an abstract exercise, it treats the product as the canvas. You choose a product template, then place your logo, artwork or text straight onto the product you are ordering. Because printing rules and requirements are built in, the tool guides your design toward something that can actually be manufactured, reducing the risk of a design that looks good but cannot be printed. The combination of a large product catalogue, brand hub assets, multi-angle viewing, live pricing and sharing tools means the entire journey—from idea to a production-ready design—happens in one browser-based workspace. For users, these capabilities translate into practical benefits. Because no design skills are needed and the tool is free to use, designing custom merch becomes accessible to people without a design background. Seeing the price while you design gives you immediate feedback on budget, helping you make informed choices about products and design details. The built-in printing rules and requirements reduce the chance of production errors, and the ability to design straight onto the product gives a realistic preview rather than a guess. Sharing and collaboration features make it easier to work with teammates or stakeholders, and the option to add a brand hub with a click speeds up the creation of on-brand designs. Design Studio supports a range of concrete scenarios. A company can design branded apparel and drinkware for its team, using product templates like the Premium T-Shirt, Classic Hoodie or Ceramic Glazed Mug and applying its brand hub assets. An individual or small business can create custom merch for sale, starting from a template and placing artwork directly onto a chosen product. A team can prepare printed materials such as Christmas cards, thank-you cards, invitation cards, flyers or posters using the print templates. Event organisers can design event-related items, given the Events category and templates like the Running Event Flyer. Because designs can be shared and collaborated on, multiple stakeholders can review and refine a design before it goes to production. Design Studio is designed for anyone who needs to create custom merchandise or printed materials without deep design expertise. Its categories—Apparel, Bags, Drinkware, Office, Packaging, Stickers & Print, Tech and Events—suggest users ranging from businesses and teams producing branded goods to individuals creating personal or resale items. The tool is free to use, and it runs in the browser. The website also presents country and language options, indicating availability across regions with multiple languages. The exact tech stack and third-party integrations are not specified in the available content. In summary, Design Studio by Monday Merch turns the browser into a merch design workspace where over 1,000 products serve as the canvas. By letting you design straight onto the product, add your brand hub with a click, see the price as you work, and rely on built-in printing rules, it aims to make every design ready for production while remaining free and accessible to non-designers. With product templates, print templates, multi-angle 2D and 3D viewing, and easy sharing and collaboration, it positions itself as "Figma, but for creating real products."
