Discover next-gen
AI tools & startups.
Curated directory of the best AI tools. Submit your project to get high-quality backlinks and traffic.
Why Choose thistools?
thistools is your go-to platform for discovering cutting-edge AI tools and innovative tech products. We curate the best tools from around the world, helping you find the perfect solutions for your productivity, automation, and creative needs.
Daily Curated Picks
Every day, we feature fresh AI tools and startups selected for quality and launch momentum.
Quality-First Curation
We prioritize tools that solve genuine problems and offer exceptional user experiences.
Community-Driven Rankings
Trending lists are driven by real user feedback so the most valuable tools rise.
>> LAUNCHING_TODAY
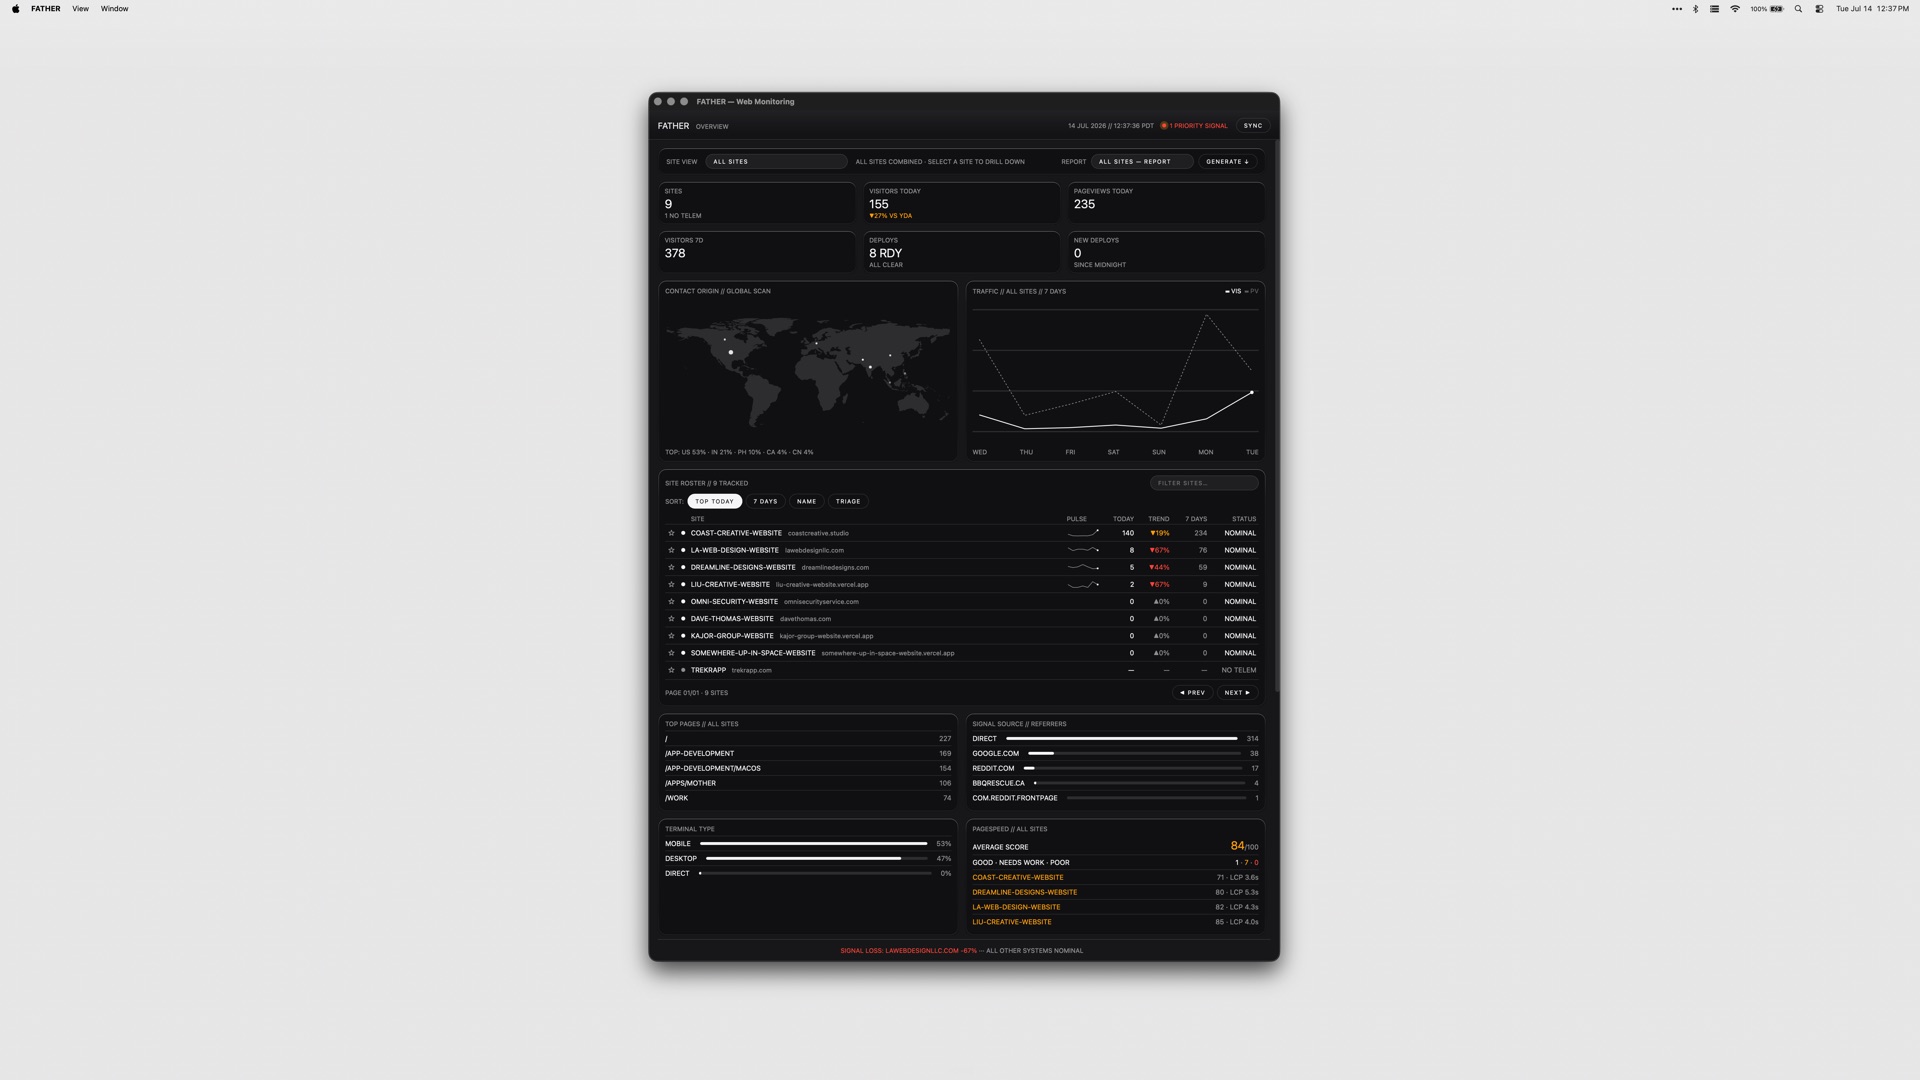
FATHER is a macOS application that serves as a mission-control dashboard for websites and deployments, built specifically for teams shipping on Vercel. Its stated purpose is simple: it watches the fleet so you do not have to, and it makes sure you know that a site is down before your clients do. The app is aimed at people who are responsible for more than one live site — studios, agencies and developers running client projects — and who need a single screen that answers the question of what is healthy, what is broken and what is about to expire. Connect your Vercel account and the dashboard fills itself: deployments, uptime and speed metrics appear live. The underlying problem is fragmentation. A team shipping on Vercel typically has to visit the Vercel dashboard for deploys, a search console for clicks and rankings, a separate source for page-speed scores, and yet another place to check whether an SSL certificate or a domain is about to lapse. GitHub checks live somewhere else again, and a failed build can sit unnoticed for hours if nobody happens to be looking at a browser tab. FATHER pulls those signals into one native macOS window, and — more importantly — into the menu bar, so monitoring stops being something you have to remember to do and becomes something that comes to you. FATHER is built on Vercel. Deploy tracking and the speed and uptime metrics all come from the Vercel API, so the integration is not a bolt-on but the foundation of the app. You connect your account token and your projects appear automatically; there is no manual inventory to maintain and nothing to keep in sync. Projects that are hosted somewhere other than Vercel can still be added manually so they get basic status checks, which means the dashboard can serve as a single view even for a mixed hosting estate. Because the app relies directly on the Vercel API, the numbers it shows come from the same place your deployments do. The core view is the fleet at a glance: the status, uptime and response of every site on one screen. Rather than opening projects one at a time, you get a single list you can scan in seconds to see which sites are responding, which are slow and which are down, so the morning check on a portfolio of client work takes moments instead of a tour through several dashboards. Deploy tracking is the second pillar. FATHER lets you watch builds progress and catch failures the moment they land, live from Vercel, so a broken deploy does not have to wait for a client email or a casual check-in to be discovered. Two features make sure that information actually reaches you. Menu-bar status shows an F in the macOS menu bar: it displays a dot while builds are running and turns red when something needs your attention, so the health of the fleet is legible at a glance from wherever you are on the Mac. Alerts go further — notifications fire even when the dashboard is closed, so a failed build or a site going down will find you rather than waiting to be found. Together they turn the app into something closer to a pager for your web estate than a traditional dashboard you have to remember to visit. Beyond deployments and uptime, FATHER covers the surrounding signals that usually live in separate tools. Traffic, PageSpeed scores, Search Console data and Bing data all appear in the dashboard, with clicks, rankings and indexing visible without leaving the app. SSL certificates and domain renewals get a countdown, so expirations stop being a nasty surprise, and failing GitHub checks get flagged alongside everything else. The result is a dashboard that answers both the operational question of whether a site is up and the marketing question of whether it is performing. The app's approach is deliberately local and deliberately simple. Tokens stay on your Mac rather than being shipped to a hosted service, and the product is sold as a one-time purchase instead of a subscription. It is a native macOS application — universal, so it runs on both Apple Silicon and Intel Macs — and it is menu-bar-first rather than browser-first. Every app in the studio's suite ships with the same set of themes, so the dashboard can be themed to taste like the rest of the collection. For the user, the benefit is timing. Knowing that a site is down before your clients do changes the conversation entirely: it turns a defensive, apologetic call into a proactive fix. Catching a failing deploy the moment it lands shortens the window in which a broken build is live. A countdown on SSL and domain renewals removes a class of avoidable outages, and having traffic, PageSpeed and search data in the same window reduces the number of tabs and logins needed to answer routine questions. All of it runs from the menu bar, so the information arrives without anyone having to go looking for it. Typical use looks like an agency or studio with a portfolio of client sites on Vercel: the dashboard becomes the first thing checked in the morning and the thing that taps you on the shoulder when a build fails overnight. Freelance developers use it to keep an eye on their own and their clients' projects without logging into the Vercel dashboard repeatedly. Teams with mixed hosting add their non-Vercel sites manually so the fleet view stays complete. Marketers and SEO-minded owners watch clicks, rankings and indexing alongside speed scores, and anyone responsible for renewals relies on the SSL and domain countdowns. FATHER is made for teams shipping on Vercel — studios, agencies and independent developers managing client work. The integrations named in the product material are Vercel, Google Search Console, Bing and GitHub, with PageSpeed scores surfaced in the dashboard. It is a macOS app that runs on Apple Silicon and Intel Macs. Pricing is a one-time $7.99 for FATHER alone, or $22.99 for the full Suite of all four apps from the same studio. In short, FATHER is a macOS mission-control dashboard that turns a scattered set of monitoring chores — deploys, uptime, speed, search visibility, renewals and checks — into a single live view with menu-bar alerts attached. Its value proposition is early warning: you find out first, act first, and keep your clients out of the loop only because there is nothing for them to worry about.
Axari is an AI twin for cybersecurity teams — an AI workforce product that is given real work rather than asked questions. The company's pitch is simple: you plus your AI twin equals indefatigable. A security leader spends the working day setting strategy and priorities, leading the security program, and making the decisions that matter. The twin, meanwhile, runs 24/7: it understands what needs attention, coordinates work across tools and teams, and executes, follows up and verifies until the work is actually done. Users can assign it a goal, let it work proactively, or give it recurring responsibilities, and all of this happens from within Slack or Microsoft Teams. It is aimed squarely at security organizations rather than general business users, and it is meant to be given real security work, not just to answer questions. The problem Axari addresses is the coordination overhead that surrounds security work. Security teams already own scanners, ticketing systems, identity platforms, cloud accounts and compliance tools; what they often lack is someone to keep the resulting work moving between them. Axari's own framing of this is quantitative: it claims time back of 10–15 hours per person, per week, on coordination-heavy work, notes that organizations spend $8–10 per $1 hiring people to operate a security tool, and describes a cognitive load of 17 of 20 items already in motion before a leader opens Slack — leaving only the 3 that genuinely need them. Its overhead claim is zero: no training sessions, onboarding programs, or new tools to learn. Customer quotes echo the same theme, including "We couldn't hire more people; we hired Axari," "We didn't rip out a single tool," and a fractional CISO noting that control drift used to be caught during the next audit cycle but is now flagged the same day it happens. Axari works across the tools a security team already runs instead of replacing them. The integrations shown on the site include Slack, Jira, GitHub, Gmail, Wiz, Splunk, Okta, Snyk, CyberArk, Tenable, Vanta, AWS, Datadog, Kubernetes, Google Cloud, Terraform, Confluence, CrowdStrike Falcon, Google Drive and HubSpot. The important point is what the twin does with those connections: it reads finding and asset context from a scanner, writes and assigns tickets, pulls policy language, collects evidence, scores vendors, lists entitlements, groups alerts and enriches them with telemetry. Because the twin operates inside the collaboration layer — Slack or Microsoft Teams — colleagues see the work happening in the channels they already use, and owners can be nudged or asked for a decision without anyone logging into a separate console. Several of the documented use cases concern exposure and threat work. In critical exposure protection, the twin pulls the finding and asset context from Wiz, creates the ticket in Jira and assigns the owner, then re-checks the scanner before anything is closed. In cloud exposure protection, it detects the misconfiguration, maps it to the owning AWS service, and prepares the fix in GitHub for review. In threat response assurance, it groups overnight alerts from Splunk, enriches them with endpoint telemetry from CrowdStrike Falcon, and opens the investigation in Jira with an owner assigned. In ransomware resilience, the twin confirms containment, revokes compromised sessions, and keeps legal and leadership on a single timeline in Slack. Each of these follows the same pattern: gather context, do the coordination, and hand the judgement call to a human. A second group of use cases covers governance and assurance work. For continuous compliance, the twin collects access evidence, maps that evidence to controls in Vanta, and chases owners in Slack who have not responded. For trusted vendor onboarding, it requests missing documents by email, scores the vendor against your policy, and routes the decision to the risk owner. For security review acceleration, it drafts from your approved answers, pulls current policy language from Confluence, and flags the answers that need human judgement. For access assurance, it lists every account and entitlement, nudges reviewers with a cutoff, then revokes and confirms the removal. The recurring theme is follow-up: the twin does not stop at producing an artifact, it pursues the response it needs and verifies that the change actually happened. Axari describes its approach in four stages. Connect: it maps what your tools do and learns exactly how your team operates daily. Understand: it works out who owns what, what matters, how work is routed, and where you are needed — the product illustration shows a daily brief in Slack summarizing priorities and where you are needed. Act: it prepares the work, assigns owners, follows up, and executes what you authorize; in the example shown, the twin drafts a SOC 2 reply in Slack with approve, edit and discard actions. Compound: it learns how you decide, anticipates what's next, and keeps getting smarter — for instance, proactively asking whether it should check with a colleague before sending a vendor exception approval. The site labels this "compounding intelligence," suggesting the twin's usefulness grows as it observes more of your decisions. The stated outcomes are time, money, cognitive load and overhead. The company reports 10–15 hours back per person, per week, on coordination-heavy work; a spend pattern of $8–10 per $1 currently going to people operating a security tool; a cognitive load figure of 17 of 20 items already in motion before the leader opens Slack, so only 3 need them; and zero overhead in training sessions, onboarding programs or new tools to learn. Testimonials support the positioning: one CISO says that nothing was ripped out and Axari simply made existing tools work harder, a CIO says the team could not hire more people so they hired Axari, and a former Google Chrome security lead describes Axari as a full AI security team that learns how an organization works and actually gets the work done. Concretely, a security team might use Axari in a daily rhythm. Overnight, the twin groups alerts, enriches them, and opens investigations with owners attached, so the morning starts with work already in motion rather than a blank page. During the day, it keeps compliance evidence flowing — collecting, mapping and chasing — and nudges access reviewers before a cutoff so certifications do not stall. When a vendor request arrives, it asks for the missing documents, applies the policy score, and asks a human before sending an exception. When a security questionnaire lands, it drafts from approved answers and flags what needs judgement. Because the twin lives in Slack or Teams, each of these shows up as a short, actionable exchange rather than another dashboard to check. The site names CISO / Head of Security, GRC, Security Operations, Security Engineering and Security PMO as the roles Axari serves, and lists customers and partners including HiddenLayer, Boyd, Supabase, CAVA, Yext, Hydrolix and OpenLoop. On trust, Axari emphasizes control, security-native design and security posture. Controls include scoped access, human approval for consequential actions, a complete audit trail, the promise that your data stays yours, and the ability to bring your own model. The company says the product is shaped by 300+ conversations with security leaders and built alongside security leaders from Google, Anthropic, Atlassian, Supabase and Roblox. It reports SOC 2 Type 1 complete, red-teaming against the OWASP Top 10, zero data retention where applicable, and BYOC / on-prem support in progress. A CISO testimonial notes that Axari earned access rather than asking for it all on day one. Axari's core proposition is straightforward: security leaders cannot hire their way out of coordination work, and attackers are not going to use less AI. By giving teams a persistent AI twin that lives in Slack or Microsoft Teams, understands the environment, coordinates across existing tools, and follows work through to verification, Axari aims to close the execution gap that sits between a security program's plans and its outcomes — without replacing a single tool in the stack. As the company puts it, you plus your AI twin equals indefatigable.
Voiskey is an AI voice typing tool that turns natural speech into polished, ready-to-use text. Rather than transcribing words literally, it starts from what you meant: you speak a rough thought and it comes back shaped for where it is going and who is reading it. It produces text for messages, emails, notes, documents, AI prompts and more. Voiskey is available on macOS, Windows, iOS and Android, works anywhere on your computer and in any language, and is described as 5x faster than typing. It is free to start, with a free month of Pro for people who join during launch. The problem Voiskey addresses is the gap between how quickly people think and how quickly they can type. An average keyboard runs at roughly 45 words per minute, while Voiskey voice is presented at 220+ words per minute. That gap shows up as friction in everyday work: the first draft is the hardest part, ideas hit fast but drafting is slow, thoughts disappear quickly before they can be captured, and meeting details are easy to forget. The same friction appears in professional routines — prompting takes longer than coding now, the faster the follow-up the warmer the deal, and tickets pile up faster than a support agent can type. Voiskey's answer is to let people speak the way they naturally would and let the product handle the shaping. Voiskey is built to listen for meaning rather than to capture every sound. The website describes it as more than listening — it understands. When you speak the way you naturally would, fillers, stumbles, changes of mind and grammar slips are all caught by Voiskey rather than passed through into the final text. The point is that you should not have to tidy your speech before you start; you think out loud, and Voiskey handles it. This is what makes the output ready to use rather than a raw transcript that still needs editing, and it is the foundation for everything else the product does with your words. Voiskey is built to adapt, and the content says it always lands right. It knows what you are going for and automatically tailors the formatting, tone and word choice so that every output fits your intent and is ready to send. The Product Hunt listing describes the same behaviour from the opposite direction: a spoken thought comes back shaped for its destination and its reader — casual with a friend, composed with a colleague, technical with an AI. This matters because the same idea needs a different form in a text message, an email, a meeting note or an AI prompt, and Voiskey applies that shaping automatically instead of leaving it to you to rewrite. Voiskey also learns your style. According to the website, it learns your names, jargon and spelling preferences so that your words always land in your style. This is a personalisation layer: rather than producing generic, uniform text, it keeps the vocabulary and spellings you actually use, which matters for people working with specialist terminology, product names, colleague names or in-house shorthand. The stated outcome is that you still sound like you — the product cleans up the mechanics of speech without erasing the voice of the person speaking. Voiskey covers voice to native-sounding text in more than 100 languages, and it presents a long list of supported languages on the site, including English, Japanese, Spanish, Korean, French, Portuguese, Arabic, Russian, Italian, Thai, Vietnamese, Dutch, Polish, Danish, Swedish, Finnish, Greek, Czech, Romanian, Hungarian, Bulgarian, Slovenian and Estonian, among others. The site states that Voiskey works anywhere on your computer and in any language. It also covers translation: you speak in your own language when you need to translate, and Voiskey turns your voice into fluent, native text across 100+ languages. That makes dictation and translation part of the same speaking workflow rather than two separate tools. A distinctive capability is turning spoken intent into AI-ready instructions. Voiskey lets you tell your AI what to build just by speaking: you talk through what you want to build or change, and Voiskey turns it into a clean AI-ready prompt with files, paths, commands and key details captured. This is presented as a practical answer to the observation that prompting now takes longer than coding, and it is a core part of how Voiskey is positioned for engineers — spoken intent becomes prompts, commits and design docs. Capturing files, paths and commands automatically means the details that are easy to lose when speaking are preserved in the final prompt. Voiskey's overall approach is a single voice experience that follows you across every device. It runs on macOS, Windows, iOS and Android, and the site states that it works anywhere on your computer — wherever you type and however you speak, Voiskey is ready. There is no separate destination app to paste into: you dictate into the place where the text is going, and the output arrives cleaned up and ready to send. The product is positioned as starting from what you meant rather than just what you said, which is the through-line connecting its filler handling, its adaptive tone and formatting, its style learning, its multilingual output and its AI prompt generation. The stated benefit is speed and readiness in the same step. Voiskey is described as arriving 5x faster than typing, cleaned up and ready to send, while you still sound like you. The comparison the site makes is 45 wpm for a keyboard against 220+ wpm for Voiskey voice, which means thoughts get out before the keyboard slows them down. Because formatting, tone and word choice are adapted automatically, the output is not a draft that needs a second pass. And because Voiskey learns names, jargon and spellings, the speed does not come at the cost of sounding generic. Voiskey frames its use cases around the formats people write in and the roles they work in. By format, the site names Messages (texts, DMs and quick replies), Emails (rough drafts shaped into clear, structured emails), Notes (reminders, quick lists and random ideas captured the moment they show up), Meetings (decisions, action items and follow-ups) and Teams (clear updates, handoffs and action items). By role, it lists Engineers (prompts, commits and design docs), Sales (call notes, CRM updates and replies), Customer Support (tickets, live chats and help articles), Writers and Creators (posts, scripts and book chapters), Students (lecture notes, essays and emails), Founders (updates, replies and job posts) and Legal and Consulting (memos, client letters and contracts). Voiskey is aimed at anyone who writes more slowly than they think, and the role pages make that concrete: engineers, sales people, customer support teams, writers and creators, students, founders, and legal and consulting professionals. It is available on macOS, Windows, iOS and Android, with a single voice experience across all four. Pricing is free to start, and the launch offer includes a free month of Pro for people who join during the launch period. No specific price points or further plan details are stated in the provided content. Voiskey's core promise is that you can say it rough and send it right. It listens for meaning rather than words, strips out fillers and stumbles, adapts tone, formatting and word choice to the reader and destination, learns your names, jargon and spellings, works in 100+ languages with translation, and turns spoken intent into AI-ready prompts. It delivers all of that across macOS, Windows, iOS and Android at a stated 5x faster than typing, and it is free to start. For anyone whose ideas outrun their keyboard, that combination is the value proposition.
Narrative is an AI-first video editor built around a simple idea: bring your footage, say what you want made, and cut it together with an editor that does the work with you. Rather than assembling cuts by hand, you upload clips, describe the edit you want in plain words, and keep refining the result through chat. Narrative brings video editing, custom motion graphics and reference-video style matching into one interface. It builds a finished draft on a timeline you can still open and change, so the output is not a locked black box but a real project you can adjust. It is designed for people who already have footage and a clear idea of the outcome, but who do not want to learn Premiere or After Effects to get there. From podcast clips to launch videos, the first step is the same: say what you want. The problem Narrative addresses is the gap between having footage and having a finished cut. Editing traditionally means learning complex software, understanding timelines and motion graphics, and spending hours scrubbing through material to find the good bits. One producer notes that every episode used to cost an afternoon of finding the good bits. A media lead describes the difficulty of finding every goal in a ninety minute match, including the one the camera nearly missed. A product marketing team says their unboxing demos went from a freelancer and a week to a sentence and ten minutes. Narrative targets exactly that gap: the time, cost and specialised skill that sit between raw footage and a usable edit, whether the material is a two hour shoot, a wedding, a podcast or a match recording. The core of the product is editing by talking. You ask in ordinary language, and the agent does the work. An example from the site is a request to make a 15 second reel of the best rides, with a title at the start and music under it. The agent then reads the transcript, edits the clips and reports back what it did, explaining that four rides were placed on the strip with the tightest one first, the title running from 0:00 to 0:03 and the music bed sitting under everything. Anything you would say to an editor, you can say to this one — it works from the words, not a menu. The site lists prompts such as cutting to the beat, making it feel like a trailer, putting every goal in order, removing the ums, going vertical with captions, starting on the best line, tightening to thirty seconds, warming it up a little, and putting the title back at the end. Everything lives in the same editor as the conversation: the transcript, captions, versions, the frame and the models behind it. The editing surface is the editor itself, not a picture of it — you can press play, scrub the strip and mute a track. Tracks and elements shown in the interface include graphics, clips, dialogue and music, along with elements such as a title and a location card, with individual clips listed by timecode and duration. You can add music, sound effects and transitions, and Narrative also supports custom motion graphics and reference-video style matching, so you can take inspiration from reference videos. Because the assistant reads the transcript while cutting, requests such as removing filler words or placing captions are grounded in what was actually said in the footage. Every turn is a version. The version history in the interface shows a numbered list of states, with the current one marked and older entries available to restore — for example v12 as the current turn, v11 with edited styles, v10 where a clip was trimmed, and v9 where the frame was set to 9:16. Each entry carries a restore action, so you can step back to any of them or put the project back to how a turn left it. A completed turn also reports what it used, such as the number of tools and credits consumed. For teams, this matters: one testimonial notes that with every version kept, nobody on the staff can break the cut. You can choose the speed, or the brains. Narrative offers three model tiers: Fast, for quick cuts and small changes; Balanced, for most edits most of the time; and Max, for long footage and hard briefs. The frame control handles aspect ratio, starting at 16:9 and switching to others on request. The options shown are 16:9 (original), 9:16 described as both speakers stacked, 1:1 for feed and 4:5 for portrait feed. The 9:16 example is instructive: start in 16:9 and ask for 9:16, and both speakers stay in the shot, stacked. That means social-ready vertical versions can be produced from the same source project rather than being re-cut from scratch in another tool. Overall, Narrative's approach is to treat the conversation and the timeline as one workspace rather than bolting a chat box onto a traditional editor. You upload your footage, describe the edit, and the agent reads the material — including the transcript — makes the cut, and tells you what it did. Every instruction becomes a version you can inspect or restore, and each turn reports the tools and credits it used. You decide how much horsepower to apply by choosing Fast, Balanced or Max, and you control the output shape through the frame settings. Narrative handles rendering and storage, so you are not managing exports, disk space or a render queue yourself. The result keeps a real, open timeline at the centre instead of a one-shot generated file. The stated benefits follow from that model. Edits arrive faster: a three minute highlight from two hours of wedding footage was on the timeline before a coffee was cold, and a producer can ask for the five best moments as verticals with captions and then open the timeline to check the work. Work that previously required a freelancer and a week can become a sentence and ten minutes. Because the output is a real editor rather than a fixed render, changes stay possible — when legal wants a frame changed, the frame is changed. Version history protects the cut from accidental damage, and Narrative's own launch video was made entirely in Narrative. Concrete scenarios named on the site include wedding films, podcasts, match highlights and product demos. A wedding filmmaker asked for a three minute highlight with the vows in the middle from two hours of footage. A podcast producer asks for the five best moments as verticals with captions. A football club's media lead asks for every goal in a ninety minute match. A product marketer produces unboxing demos. Broader examples include a rough cut, a supercut, or a vertical reel from a two hour shoot, plus podcast clips and launch videos. The audience is filmmakers, producers, media leads, product marketers and teams who cut regularly. Plans run from Free at $0/month with 3 AI prompts, the whole editor and your own footage, through Plus at $20/month with 2,000 AI credits, 10 projects, 100 GB of footage, 4K renders without watermark, every model tier including Max and version history kept for a year, and Pro at $40/month with 4,000 AI credits, 30 projects and 500 GB of footage, to Studio at $100/month for teams cutting every day with 10,000 AI credits, unlimited projects, unmetered renders with priority in the queue, 1 TB of footage and priority support. Paid plans include a 3-day trial and can be cancelled any time, and there is an iOS app in addition to the web editor. Narrative's value proposition is straightforward: describe the edit you want in plain words, and get a finished draft on a timeline you can still open and change. It compresses the distance between raw footage and a usable cut while keeping the edit genuinely editable, with versions, model tiers and frame controls under your hand.
Multimodal Agents by Sierra are AI agents that bring voice, text, and visuals into the same customer conversation. Sierra has long believed that the conversation is the interface: the customer says what they need and the agent figures out the rest. Multimodal agents extend that belief beyond a single medium. Rather than making customers choose between talking, typing, or looking at something, the agent gives them the best of each — voice to explain what you need, a visual to compare options side by side, and text when you want to reference something later. The result is a single, continuous conversation that adapts to what the customer is trying to accomplish at that moment. The problem this solves is familiar to anyone who has tried to make a decision over the phone. Sierra describes trying to upgrade a mobile plan over the phone: the representative talks through models, colors, storage sizes, and monthly rates, and the customer is left comparing things in their head and picking a phone they cannot picture. Voice is genuinely good for parts of that interaction — you can say what you actually need and ask questions more easily than you can over text — but you cannot see the thing you are about to buy. Multimodal agents close that gap. Stitching channels together is not the hard part; the real trick, as Sierra puts it, is knowing which one to use when. That is where the agent's judgement comes in. Agents built on Sierra anticipate what is needed for each conversation and automatically shift between modes — voice, visuals, or text — without making the customer start over or repeat themselves. The choice of medium follows the shape of the task: voice to explain what you need, a visual to compare options side by side, or text when you want to reference something later. Because that switching is automatic, the customer never has to manage the interface. They simply continue the conversation, and the agent keeps the relevant context intact as the medium changes, which is precisely what prevents the restarting and repeating that usually happens when a support interaction jumps between a phone call, a chat window, and a web page. Visuals are part of the conversation rather than a separate destination. Sierra's example is a disrupted flight: you call the airline to get a new flight, and instead of a representative reading off alternate options one by one, you see them laid out with departure times, layovers, and pricing right in the conversation. You pick one, and the agent keeps going from there. Choosing a seat works the same way — you see the map and tap the seat you want. And for times when it is easier to talk than type, you can switch to voice and explain exactly what you need; the agent captures those details without making you type a paragraph into a text box. In each case the visual carries the comparison work that language handles poorly, while voice carries the nuance that menus and forms handle poorly. Sierra's approach is also designed to avoid rebuilding the same experience for every place the agent lives. With Sierra, you can build your agent once and easily deploy across all channels, and the same is true for multimodal agents: once you build a visual component, your agent can use it everywhere it lives. A comparison table or a calendar does not need to be recreated for each surface the agent operates on. That single-build approach reduces duplication for the team maintaining the experience and keeps behaviour consistent for the customer, who encounters the same kind of interactive element regardless of where the conversation happens to be taking place. Sierra's MCP UI integration is what lets teams bring interactive components into the conversation: product cards, comparison tables, calendars, and forms. Those components are designed and hosted by your own team, so you decide how they look, what they show, and when they change. That control matters because the visual layer is often the part of a customer experience that carries brand and merchandising decisions, not just function. Because your team hosts the components, when you make an update it is automatically reflected everywhere without needing to redeploy or maintain different versions for each platform. And when a component needs more room, it can expand to full screen to show calendars, long comparison tables, multi-step forms, and more — so the same building block can serve as an inline detail inside a conversation or as a focused, full-attention task when the customer needs to complete something substantial. Taken together, the methodology is straightforward: keep the conversation as the interface, let the agent decide which medium each moment calls for, and make the interactive pieces reusable across every surface. Sierra frames the goal as customers never having to choose. On one call, customers can talk through what they need, glance at a screen to compare their options, and tap to confirm — without ever pausing the conversation to switch tools. The agent, not the customer, manages the transitions, which is what makes an interaction that spans voice, visuals, and text feel like a single continuous exchange rather than three separate ones. The outcomes described are practical. Customers get through decisions faster because they can see options while hearing about them, and they avoid the frustration of describing the same need twice or rebuilding context after a channel change. They can also reference something later in text when that is easier than listening. Businesses, meanwhile, get a single deployment path: build the agent and its visual components once, use them across channels, update them in one place, and avoid maintaining separate versions per platform. And the experience is described as being as easy to build and deploy as it is for customers to use, which lowers the practical barrier to offering a multimodal customer experience at all. Concrete workflows in Sierra's own examples include upgrading a mobile plan, where a customer talks through what they need and compares phones, colors, storage sizes, and monthly rates visually instead of holding the options in their head. A disrupted flight is another: the agent surfaces alternate flights with departure times, layovers, and pricing in the conversation, and the customer picks one and continues. Seat selection follows the same pattern, with a map the customer taps rather than a description they have to parse. Voice-first moments are covered too — when it is easier to explain something than to type it, the customer can switch to voice and the agent captures the details. More broadly, any conversation that involves comparing options side by side, filling in a form, or choosing a time can use interactive components inside the exchange itself. Multimodal Agents by Sierra are aimed at organizations that handle customer conversations and want those conversations to adapt to the customer rather than the other way around — customer experience and support functions in particular. The people who build the visual layer are the customer's own teams: Sierra states that your team designs and hosts the components used in the conversation. Deployment is described in terms of channels rather than a single app, since the same agent and the same visual components are meant to work everywhere the agent lives. Sierra's MCP UI integration is the mechanism named in the content for bringing interactive components such as product cards, comparison tables, calendars, and forms directly into a conversation. The core idea behind Multimodal Agents by Sierra is that the best interface is the one the conversation needs. Voice, visuals, and text stop being competing options and become modes the agent moves between as the situation changes — voice when explaining is easier, a visual when comparing side by side helps, text when something needs to be referenced later. Because agents built on Sierra anticipate what is needed and shift automatically, customers never start over or repeat themselves, and because visual components are built once and hosted by your team, they can appear everywhere the agent works. That is the promise: one agent, every surface, and a conversation that morphs to fit the customer.
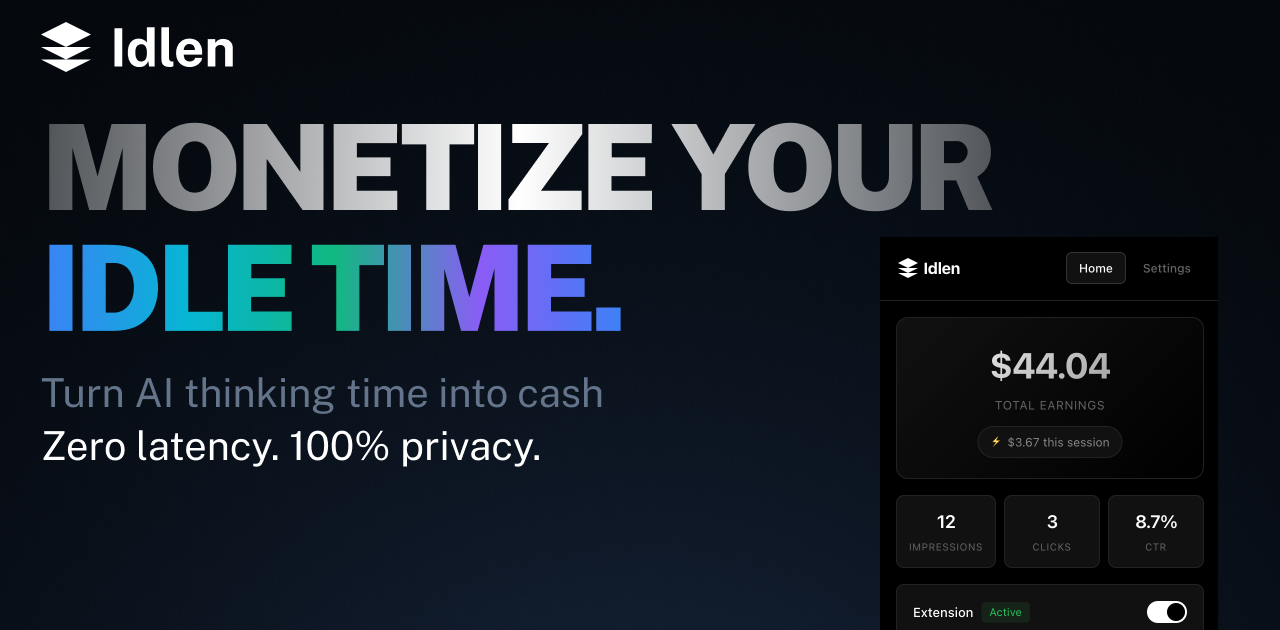
Idlen is an advertising network built around the idle time that appears while AI models are thinking. Its promise is short and direct: AI thinks, you earn. The product puts native developer-tool ads in three places — the IDE, the browser, and the chat app you shipped. Developers install the Idlen extension for VS Code, Cursor, or Chrome and see a native ad during the moments their AI assistant is processing a request, keeping 70% of the revenue. Advertisers use the same network to reach developers inside the tools they already use every day, targeted by the stack they actually work with, including React, Python, and AWS. AI app builders add three lines of code with npm i @idlen/chat-sdk to monetize their own chat products, and ads remain optional there: no key, no ads. Developers spend a large part of their day waiting on AI. A prompt is sent, the model thinks, and the editor sits idle for a few seconds at a time. Idlen takes that observation literally: the wait is an ad slot. Instead of treating AI processing time as dead time, the network fills it with a native, relevant sponsor message — the demo shows a sponsored slot carrying Neon, described as serverless Postgres for modern apps. The reasoning behind the product is that the waiting is unavoidable: developers are already using Claude, ChatGPT, Cursor, and other AI tools, and they change nothing about their workflow. Idlen simply adds an ad during processing and pays the developer a share. At the same time, developer-tool companies struggle to reach this audience precisely, and AI app builders who ship chat products have usage but often no monetization. Idlen answers all three sides with one network and three doors. The earning side of Idlen is built for individual developers first. The extension is described as earning €20-100 per month passively, without lifting a finger, and earnings go directly to the developer's account. Payouts are flexible: Stripe, PayPal, or a 10% bonus taken as credits. Idlen also supports teams through a shared earnings pool, so an entire group can collect the income generated by its members. An earnings calculator on the site lets developers model the result using their coding hours per day and a target subscription — ChatGPT Plus, Claude Pro, or v0 Premium — showing, for example, that four hours per day yields 150% coverage, making ChatGPT Plus free with surplus pocket money. The site notes these figures are based on average developer activity and ad inventory fill rates. Onboarding is presented as taking under two minutes. Privacy is treated as a core feature rather than a footnote. Idlen states plainly that your code stays on your machine, and the privacy process is spelled out in three steps. First, no code access: the extension never reads, stores, or transmits your source code. Second, local analysis only: package.json is analyzed on your machine to determine ad relevance, and nothing leaves the device. Third, the ad request itself is anonymous — the illustrative code shows dependencies read locally, keywords matched from those dependencies, and then an anonymous fetch for an ad. The company also describes the extension code as transparent and auditable and available for security review. For developers, that means the monetization does not come at the cost of handing over a codebase or prompts; Idlen states that it does not read your prompts. Idlen is designed to stay out of the way. Its zero-latency claim rests on timing: ads load during AI processing only, so they occupy time the developer is already waiting rather than adding delay to normal editing. It works everywhere in practice — VS Code, Chrome, and all the AI tools the developer already uses, with support listed for Claude, ChatGPT, V0, Bolt, Lovable, Cursor, Windsurf, and Replit, plus downloads for VS Code, Cursor, Open VSX, Chrome, and Firefox. On the advertising side, the network claims to avoid spam and clickbait, promising only curated developer tools, organized into categories such as Cloud & Hosting for deploying, scaling, and monitoring apps; Databases for modern databases; APIs & Services covering payment, email, and SMS; and Dev Tools for boosting productivity. The core workflow is deliberately small. Step one: install the extension — add Idlen to VS Code or Chrome in one click, and it works with all your AI tools. Step two: use AI as usual — keep coding with Claude, ChatGPT, Cursor, or any other AI tool, with no workflow changes. Step three: earn passively — relevant dev tool ads appear during wait time and earnings go directly to your account. The site summarizes the whole journey as starting to earn in under 2 minutes. The demo interaction reinforces it: a user sends a message such as "Add proper error handling and improve the loading state," and the assistant thinks for three seconds; during that window a sponsored Idlen slot appears in the chat, and the panel reports earning tokens while you wait. Advertisers enter through a different door: they buy the slot and appear in the IDE and browser, targeted by the stack the developer actually uses. Publishers enter through a third door: they paste a message in the sandbox to preview which ad would serve, then run npm i @idlen/chat-sdk, three lines of code, and keep 70%. The benefits differ by side but share one shape — value extracted from time that was previously wasted. For developers, the outcome is passive income on top of work they were already doing, with no change to workflow, zero tracking, and no exposure of code or prompts. Reported earnings of €20-100 per month can offset or fully cover an AI subscription, and the calculator turns that into a concrete target: pick your hours and your subscription and see the coverage percentage. Flexible payouts and a team pool make the income usable for individuals and groups alike. For advertisers, the benefit is placement inside the tools where developers spend their day, targeted by real stack signals rather than guesswork, with a welcome offer that doubles the first deposit: pay €200 and get €400 this week. For AI app builders, the benefit is monetization of an existing chat product with a very small integration surface — three lines — while keeping 70% and retaining the option to show no ads at all. A few concrete workflows illustrate where Idlen is used. A developer using Cursor or VS Code spends a few seconds waiting for code generation; the Idlen extension fills that moment with a native, stack-relevant sponsor message and credits the earnings. A developer working in the browser with ChatGPT or Claude gets the same treatment through the Chrome or Firefox extension. An advertising team that sells a serverless database or a hosting platform buys slots and appears while developers are actively coding, matched against the technologies visible in that project. An AI app builder who shipped a chat product installs @idlen/chat-sdk, previews a message in the sandbox to see which ad would serve, and switches on monetization without managing keys. A team adopts the extension together and pools its earnings through the shared team pool. And a prospective advertiser tests the waters with the €200-to-€400 welcome offer before committing further spend. Idlen is explicitly built for every side of the ecosystem it touches. The first group is AI users — developers who want passive income while using their favorite AI tools. The second is advertisers selling developer tools who want to appear in the IDE and browser, targeted by the stack developers actually use. The third is AI app builders and publishers who want to monetize an AI product with three lines of code. Integrations and downloads cover VS Code, Cursor, Open VSX, Chrome, and Firefox, with the network listed as working alongside Claude, ChatGPT, V0, Bolt, Lovable, Cursor, Windsurf, and Replit. Installing Idlen is free for developers, who keep 70% of earnings; the paid side of the marketplace is advertising, where the entry offer is €200 matched with €200 for €400 to spend this week. The site also highlights privacy first, zero latency, and cancel anytime as standing commitments. Idlen's core proposition can be stated in one line: the seconds you spend waiting for AI are already being spent, so the network turns them into income for developers, distribution for developer-tool advertisers, and revenue for AI app builders. One network, three doors — install the extension, buy the slot, or try the sandbox.
DynamicLake 2.0 is a Mac application that brings a Dynamic Island style experience to the Mac desktop. Its website describes it simply as "Dynamic Island for Mac", and its Product Hunt listing calls it "Dynamic Island for Mac with 3rd Live Activities and more". The product's own description lists plugins, notifications, drag and drop, a converter, calls, AirDrop and a timer among the things it offers. The site states that it is "Inspired by Apple Dynamic Island" and that it follows a "Liquid Glass Design - Inspired by Apple Liquid glass". It is intended for Mac users who want a compact, interactive presence on their screen that surfaces notifications and small everyday utilities in one place, rather than scattering them across separate apps and windows. The concept behind DynamicLake comes from Apple's Dynamic Island, the interactive element Apple introduced on iPhone that turns a small area at the top of the display into a live, changing surface for activities and alerts. DynamicLake translates that idea to the Mac. On Product Hunt the product is filed under the topics Mac, Menu Bar Apps and Apple, which places it in the family of small Mac utilities that live persistently on the desktop or in the menu bar area so they are always within reach. The appeal of such tools is that they reduce the friction of switching contexts: instead of hunting through windows or opening a separate application, users can glance at a single spot and interact with what is happening right there. Live Activities and notifications are central to the product. The Product Hunt tagline highlights "3rd Live Activities", indicating that third-party Live Activities are part of what DynamicLake displays, and the official description lists notifications as one of its main capabilities. The website's FAQ devotes specific questions to this area, including "How does Dynamic Lake Pro handle my notifications?" and "Will there be new features added to DynamicLake Pro?", which shows that notification handling is treated as a core part of the Pro experience. For a Mac user, having notifications presented in a single, consistent, island-style surface means the most relevant updates stay visible and actionable without covering the work in progress. Beyond notifications, DynamicLake bundles a set of small everyday tools. The product description names plugins, drag and drop, a converter and a timer. A converter and a timer are the kind of utilities that are frequently needed for a few seconds at a time and then abandoned, so placing them inside an always-accessible island removes the need to open a dedicated app or a web page for each one. Drag and drop suggests that items can be moved onto the island directly as part of the workflow, and plugins indicate that the surface can be extended with additional pieces of functionality. The tagline's "and more" leaves room for further tools within the same interface. Communication and file transfer features also appear in the description: calls and AirDrop. Calls listed alongside the other capabilities implies that call information or call handling is surfaced through the same Dynamic Island interface, keeping it visible while the user continues working. AirDrop being included points to dragging files onto the island to send them, or receiving them, through Apple's own transfer mechanism. The FAQ also references "DynaMusix" in the question "Does DynaMusix support all music apps?", which indicates a music-related component associated with the product. Visually, the site states the design is a Liquid Glass design inspired by Apple Liquid Glass, giving the interface a translucent, modern look that sits alongside macOS. Overall, DynamicLake works as a persistent, interactive layer on the Mac that is modelled on Apple's Dynamic Island. Rather than being a single-purpose utility, it acts as a container: Live Activities, notifications, a converter, a timer, calls, AirDrop and plugins all flow through the same island-shaped surface, and the Liquid Glass styling keeps it visually integrated with the system. The website's FAQ shows that the team thinks about the practical details of running the app day to day, covering which macOS versions are supported, whether it works on non-notch MacBooks, whether it supports external displays, and whether it is compatible with the BetterDisplay app. There are also questions about updating the app to the latest version and what to do when a bug is encountered. The benefits follow from that design. Placing frequently needed information and mini-tools in one persistent spot reduces app switching and keeps the user's attention on the task at hand. Notifications and Live Activities remain glanceable instead of interrupting with full-screen or modal interruptions. Small jobs such as converting a value or starting a timer no longer require leaving the current window. Communication cues for calls and file transfers arrive in the same place. Because it is inspired by Apple's own Dynamic Island and Liquid Glass design language, the experience feels familiar to anyone who uses an iPhone, while remaining a native-feeling part of the Mac desktop. Concrete situations the product is suited to include monitoring ongoing Live Activities while working in other applications, keeping notifications under control in a single island surface, running a quick conversion without opening another tool, timing a short task, managing calls so that call information stays visible during work, and sending or receiving files through AirDrop from the same interface. The FAQ also raises external displays and non-notch MacBooks, which correspond to the common setups where users would want the island to remain usable: a MacBook with an external monitor, or a Mac model that does not have a notch at the top of its built-in display. The music-app question tied to DynaMusix points to another scenario, listening to music while working. On requirements and practicalities, the FAQ covers which macOS versions are supported and whether DynamicLake works on non-notch MacBooks, so compatibility with a range of Mac hardware is part of the pitch. It also asks about external display support and BetterDisplay compatibility. The app appears to be a paid product with a Pro tier: the FAQ asks whether DynamicLake can be tried before purchasing, whether payment can be made with PayPal, and how DynamicLake Pro can be activated on multiple devices. New features are also signalled, with the site asking whether more will be added to DynamicLake Pro. Language support is another documented question. On the technical side, the site notes that the software uses code of FFmpeg licensed under LGPLv3.0. The site carries a 2025 copyright for Aviorrok, and the FAQ also clarifies that AppleLake or Dynamiclake.net are not the same as DynamicLake. In summary, DynamicLake 2.0 takes the Dynamic Island idea that Apple popularised on iPhone and carries it to the Mac, combining third-party Live Activities, notifications, plugins, drag and drop, a converter, calls, AirDrop and a timer into one Liquid Glass-styled surface. For Mac users who want their alerts, activities and small utilities in a single always-available place, it offers a focused, Apple-inspired way to keep that information close at hand.

Anthropologic is a zero distance consumer research platform that reads the whole internet through its Human Context Protocol to uncover consumer, category and cultural truths. It is built for people who need consumer understanding that is both fast and deep: research, innovation, marketing and foresight teams who cannot wait weeks for fieldwork but also cannot act on shallow social listening. The platform covers 239 markets and more than 100 languages, and it organises its capabilities into nine workflows, each aimed at a different type of question — what is moving in a category, what people think and feel, how segments behave online, what futures are probable, how creative performs, how a brand is read across social, search and LLMs, and where a brand can stand within a market's cultural codes. The promise is straightforward: research, innovation and foresight answers in minutes. Traditional research is deep but slow. Social listening is fast but shallow. LLMs are fluent but culturally blind. That is how Anthropologic frames the state of consumer insight, and it is the gap the platform exists to close. Deep research — surveys, ethnographic work, segmentation studies — produces trustworthy understanding, but it arrives on a timeline that rarely matches the pace at which categories move. Social listening moves at the speed of the feed but tends to capture volume and sentiment rather than meaning, leaving researchers to guess at the cultural logic underneath. Large language models can generate convincing text about consumers, yet by the platform's own description they lack cultural grounding, so their fluency masks a blindness to the codes that actually govern a market. Anthropologic positions itself between these three approaches: fast like listening, interpretive like research, and grounded in cultural context rather than surface fluency. For teams making decisions about products, positioning and communication, that combination matters because the cost of being slow is measured in missed trends, and the cost of being shallow is measured in misread consumers. The first group of workflows answers the question of what is happening. Trends shows what is moving in a category, pairing social proof with search patterns so that a signal is visible both in conversation and in demand. The live trend examples shown on the site make the shape of the output concrete: a search volume for alcohol-free club nights in the UK, a multiple showing how many scents now sit in a wardrobe where a single signature perfume once did, the number of US stores stocking overnight oats, or a search rate for Filipiniana bridal looks. Discourse goes a layer deeper and covers what people think, say and feel, mapping the positions, tensions and narratives inside a conversation rather than stopping at sentiment. Digital Segmentation takes the behavioural record and turns it into psychographic segments based on online behaviours, so teams can see not only that a category is moving but which kinds of people are moving it and with what mindset. Once a team knows what is happening, the next group of workflows helps it look forward and test. Foresight Simulator uncovers probable future scenarios reshaping a category, giving innovation and strategy teams a structured way to consider what comes next instead of relying on a single forecast. Synthetic Survey simulates consumer responses at scale using cultural ontologies, which allows researchers to explore how different audiences would respond without running a full field study for every hypothesis. Creative Evaluation scores a video ad for cultural strength across grounded signals, endorser and pillars, turning creative judgement into something that can be assessed against cultural evidence rather than taste alone. Together these workflows cover the middle of the research process: the stage where teams need to stress-test ideas, creative and scenarios before committing budget to production or media. Interpretation comes next. Ask an Anthropologist interprets an insight using cultural codes, giving teams a way to ask what a signal actually means rather than only what it says. Brand Performance shows how a brand performs across Social, Search and LLM, extending brand tracking into the place where many consumers now form impressions — the answers language models give. Cultural Semiotics reads a space in a market: the codes that govern it, the tensions between them, and where a brand can stand, which is directly useful for positioning work. The site also lists Innovation as coming soon, described as identifying opportunity spaces through convergence modelling and developing novel concepts, alongside a Research Thinking section where longer-form perspectives are published, with example essays such as 'Death of the Sugar High', 'Future of Fashion is Value', 'Medicalized Mouth', 'Beyond Classrooms' Four Walls' and 'Redesigned: Future of Aging'. The overall approach is what Anthropologic calls the Human Context Protocol: the platform reads the whole internet, rather than a single social network or a survey panel, and interprets what it finds through cultural context instead of raw keyword matching. Nine workflows sit on top of that reading, each packaged as a launchable tool with a defined question and a defined output, so a researcher does not have to assemble a methodology from scratch. Coverage is broad by design — 239 markets and 100+ languages — which means the same method can be applied across geographies and language communities rather than only in the markets where a team happens to have local researchers. The workflows range from descriptive (Trends, Discourse, Digital Segmentation) through projective (Foresight Simulator, Synthetic Survey, Creative Evaluation) to interpretive (Ask an Anthropologist, Cultural Semiotics) and diagnostic (Brand Performance). The through-line is that every output is meant to be grounded in something observable — social proof, search patterns, online behaviours, cultural codes or ontologies — rather than in a model's unaided opinion. The stated benefit is speed without sacrificing depth: research, innovation and foresight answers in minutes. For a category team, that means trend questions can be answered while a campaign or product decision is still open, rather than in a retrospective deck delivered after the moment has passed. For innovation teams, probable future scenarios and simulated consumer responses reduce the cost of exploring many hypotheses before narrowing to the few worth real investment. For brand and marketing teams, scoring creative for cultural strength and tracking performance across social, search and LLM gives a more complete picture of how a brand is actually being read. And because the platform works across 239 markets and 100+ languages, the same questions can be asked consistently in many places at once, which is difficult to do with traditional fieldwork and easy to get wrong with a culturally ungrounded model. The result is fewer decisions made on instinct alone and fewer insights that arrive too late to use. Concrete scenarios follow from the workflow list. A beauty or fashion brand tracking a new behaviour — the site's own examples include Gen Z fragrance, secondhand shopping, slow fashion and beauty after GLP-1 — would use Trends to see whether the movement shows up in both conversation and search, then Discourse to understand the narratives around it, and Digital Segmentation to identify which psychographic groups are driving it. A creative team preparing a video ad would run it through Creative Evaluation to score its cultural strength against grounded signals, endorser and pillars before committing media spend. A strategy team planning ahead would use Foresight Simulator to unpack probable future scenarios in a category and Synthetic Survey to test how consumers might respond. A brand lead would use Brand Performance to compare how the brand reads across Social, Search and LLM, and Cultural Semiotics to understand the codes and tensions in a market and where the brand can credibly stand. A researcher holding an ambiguous insight would use Ask an Anthropologist to interpret it through cultural codes. The Research Thinking section shows how those outputs are turned into published perspective pieces across topics such as fashion, education, wellness, entertainment and sportswear. Anthropologic is aimed at research, innovation and foresight functions — the product description names research, innovation and foresight answers explicitly — as well as the marketing and brand teams that consume that work. The scope is global by default: 239 markets and 100+ languages, covering categories visible in the platform's own examples, such as beauty, fashion, travel, fitness, food and drink, entertainment, education, wellness, pets and motherhood. No pricing or plan details appear on the page, and no specific third-party integrations are listed; the data domains the product describes are Social, Search and LLM, plus the platform's own cultural ontologies and semiotic codes. The product is delivered on the web at anthropologic.quilt.ai, and its Product Hunt listing categorises it under Marketing, Artificial Intelligence, and Data & Analytics. Anthropologic's core proposition is zero distance: closing the gap between a consumer signal and the decision it should inform. By combining a Human Context Protocol that reads the whole internet with nine purpose-built workflows spanning 239 markets and 100+ languages, it offers research depth at listening speed — trends with social proof and search patterns, discourse with tensions and narratives, psychographic segmentation, foresight scenarios, creative scoring, synthetic surveys, cultural interpretation, brand performance across social, search and LLM, and semiotic reading of a market. The takeaway is that cultural context, not fluency alone, is what makes consumer insight usable.
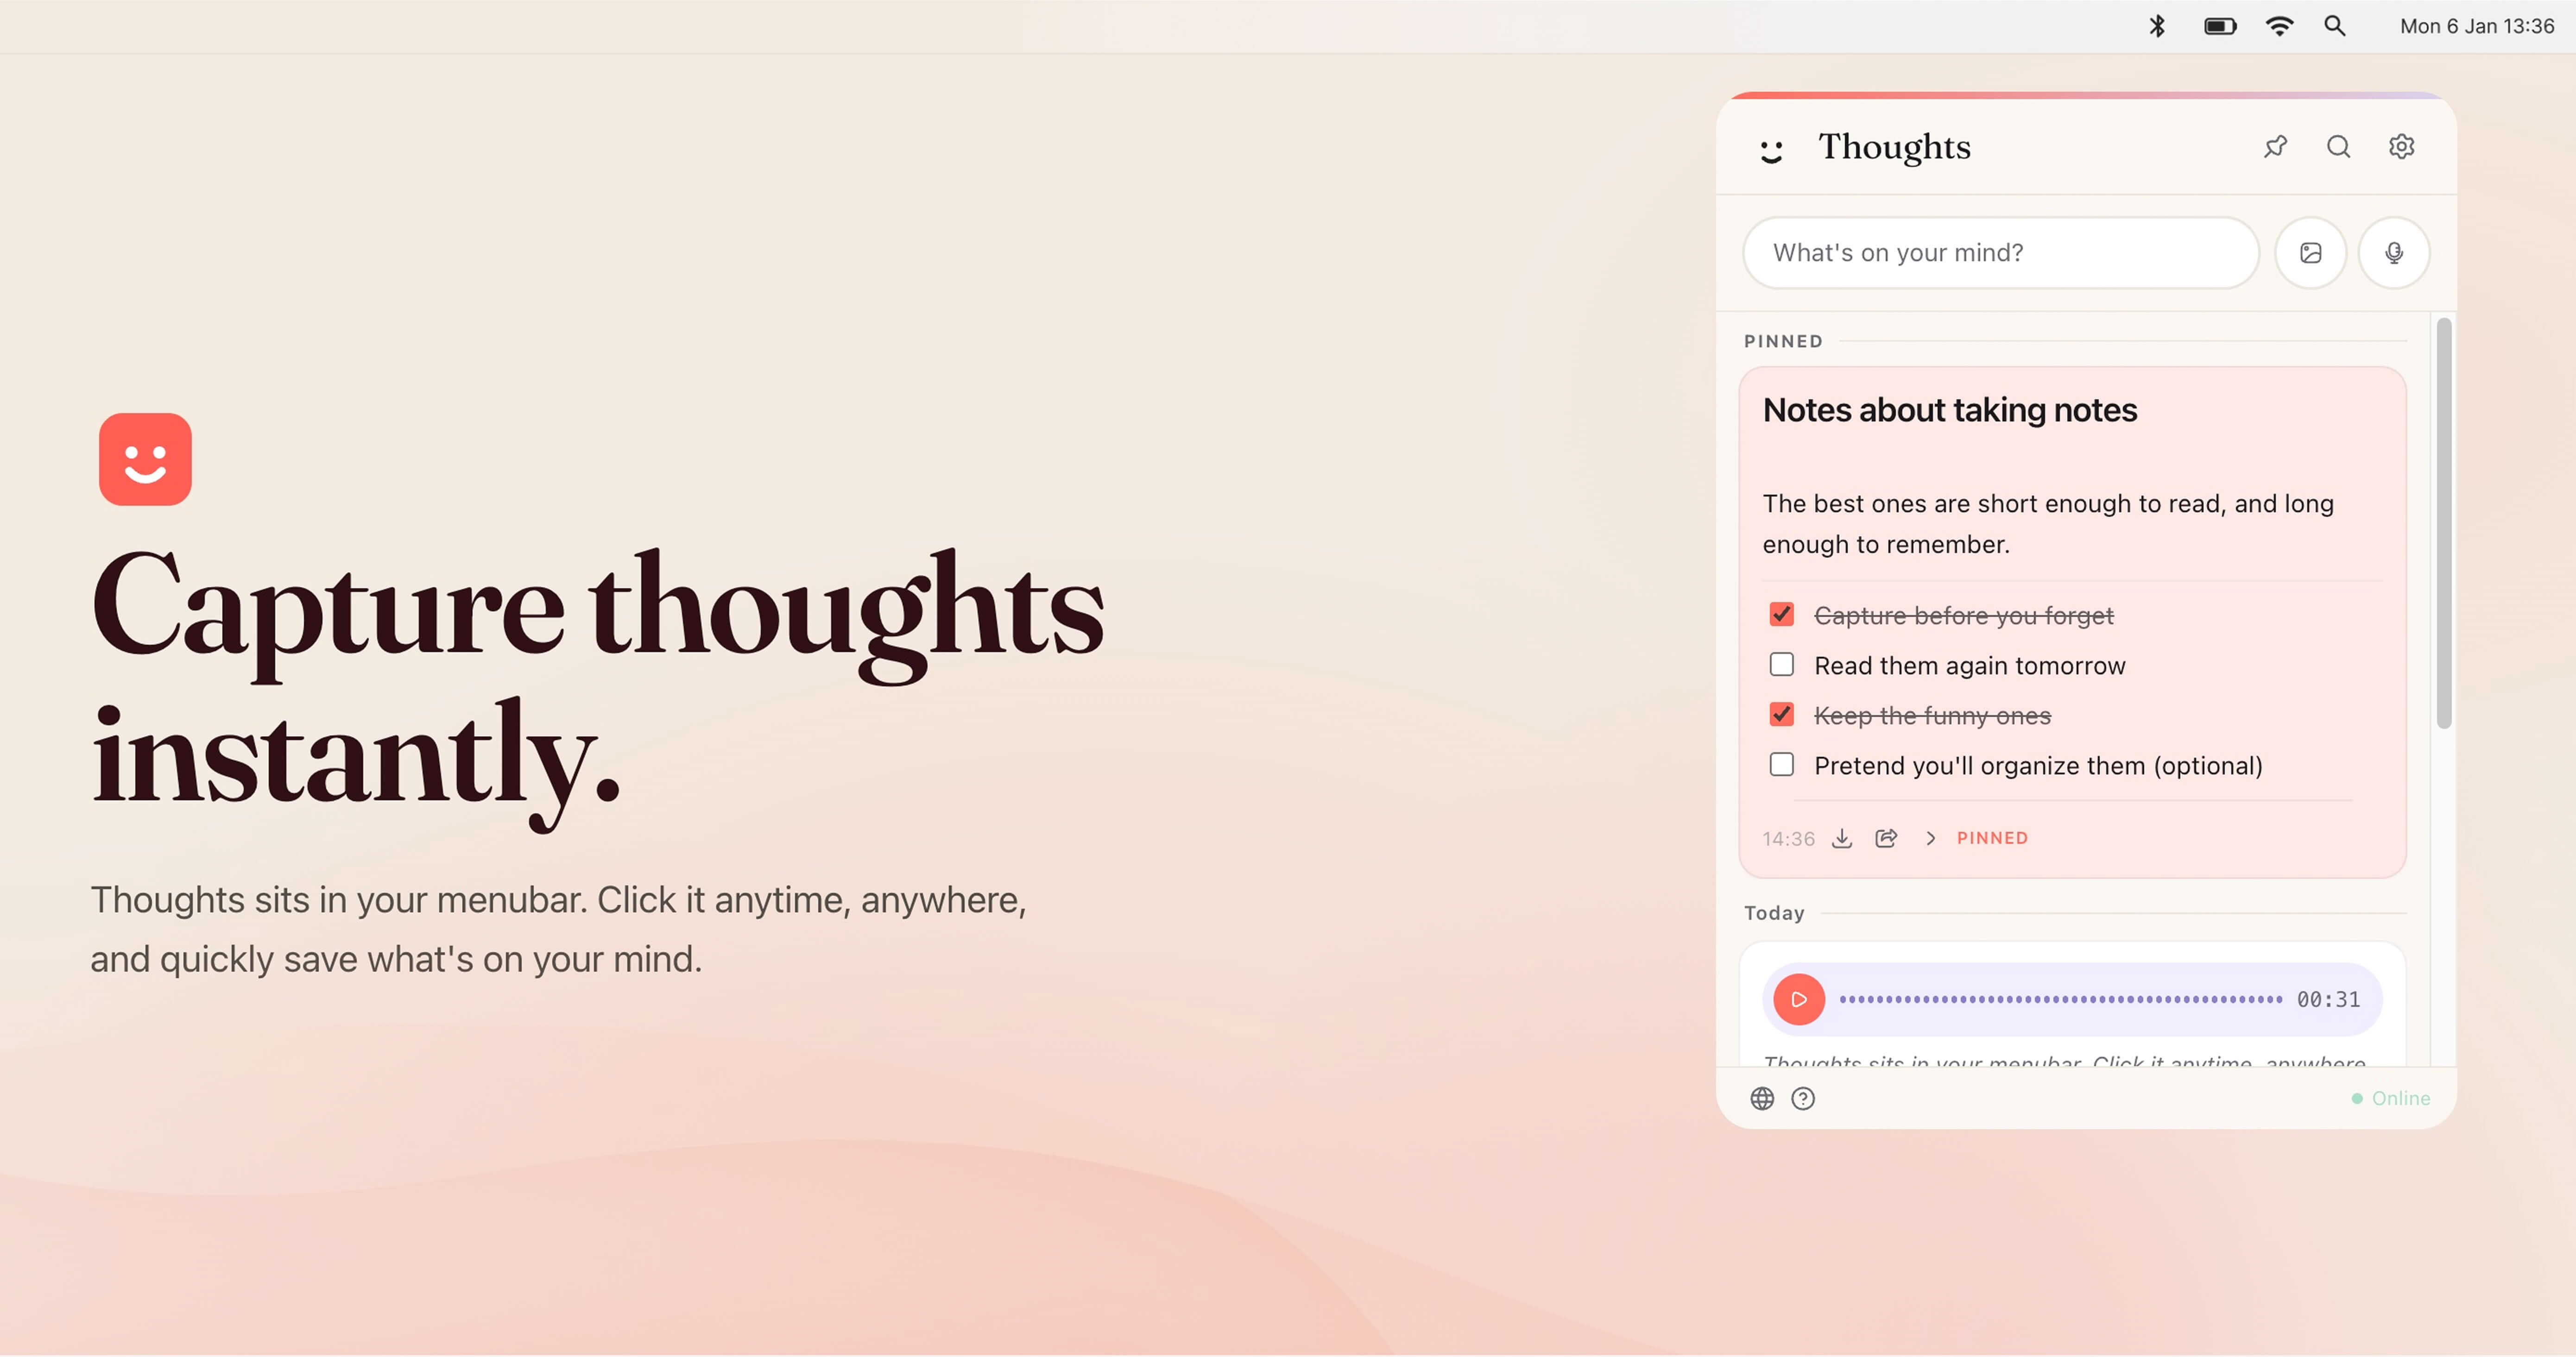
Thoughts for Mac is a native macOS menubar application for capturing notes, images, and voice recordings without leaving what you are doing. It sits in the Mac menubar, and a single click opens it so you can quickly save whatever is on your mind. The app captures structured text notes, checklists, code blocks, standalone links with previews, voice recordings, images, and text-like files such as TXT and CSV. It is presented as a small multi-tool for the menubar, and it is free to download and use, with all future updates included and no subscription. Because it lives alongside your other menu bar icons, it stays within reach while you work in other applications. The thinking behind Thoughts for Mac is speed of capture. Rather than opening a full note-taking application, creating a document, and finding a place to file it, the app puts a capture surface in the menubar where it is always one click away. The website frames this simply: Thoughts sits in your menubar, you click it anytime and anywhere, and you quickly save what is on your mind. That makes the app useful for the moment a thought, link, image, or spoken idea appears in the middle of other work. It also supports captures that arrive from outside the app itself: desktop builds can receive shared text, images, and audio through URL schemes, open-with actions, macOS Services, and native imports, so content can be sent to Thoughts from elsewhere on the system. The core capture experience covers the three input types the website presents as Write it, Drag in an image, and Talk to it. Writing produces structured text notes, and the app also handles checklists, code blocks, and standalone links that carry previews. Dragging an image in saves the image itself as a note, and screenshot capturing is listed among the app's capabilities. Talking records voice, which becomes a voice note that can later be transcribed with your own AI provider key. Beyond those interactive paths, Thoughts also accepts text-like files such as TXT and CSV, and on desktop it can take in shared text, images, and audio from URL schemes, open-with, macOS Services, and native imports. Voice recordings can be exported as MP3 in the desktop app whenever you want them. AI is optional and brought by you. In Settings you can connect OpenAI, Claude, or Gemini with your own API key. Once connected, the app can transcribe voice notes, context images to text, and perform simple text transforms such as capitalization, translations, spelling fixes, shortening, lengthening, summarizing, and converting case. The website also lists extracting text from images among the available actions. Claude is available for text actions, while transcription support depends on the provider you connect. Only AI-powered actions require a key: capturing notes, images, and audio does not need one. The app is free, and you use your own OpenAI, Gemini, or Claude API key for features like transcription, OCR, summaries, translations, and rewrites. Organizing what you capture is handled by search and pinning. Search works across notes, links, screenshots, and image names instantly, so a note can be found even when you only remember part of an image's name. Pinned Thoughts let you keep important notes at the top of your list so they are not buried under newer captures. The app also supports light and dark mode and adapts to whichever you prefer. Instant access is provided by a custom shortcut of your own choosing, meaning you can open Thoughts from anywhere on your Mac with a keystroke rather than reaching for the mouse. Thoughts works as a local-first menubar utility. In the desktop app, notes and settings are saved locally on your Mac, and media files are stored in the app's user data folder, with no account required. That means there is no sign-up step and no server-side account to manage for the core experience; AI actions are the exception, since they rely on the API key of the provider you connect. A browser preview mode also exists, but it is session-only, so notes created there are temporary. The free model and the bring-your-own-key approach combine to keep the tool light: you pay nothing to download or use it, including future updates, and you decide separately which AI provider, if any, powers the optional text and audio actions. Export and sharing are built in, so what you capture is not locked in. You can share notes as text, and you can export audio recordings whenever you want them. If you ever decide to leave, you can export all notes from Settings as JSON, or export individual notes in the best available format: text notes as TXT, image notes as image files, PDF attachments as PDF, and voice notes as MP3 in the desktop app. Benefits stated on the site include instant capture from the menubar, quick access through a custom shortcut, search that reaches into images and image names, pinning for important items, and both light and dark appearance modes. Concrete workflows follow from the capture types. During a call or a meeting you can talk to Thoughts and keep the recording as a voice note, then transcribe it later with your connected provider. While browsing, you can save a standalone link with its preview, or capture a screenshot of something you want to keep. When you drag in an image, the app can extract text from it through OCR once an API key is connected, turning a picture of text into usable content. You can bring in text-like files such as TXT and CSV, jot checklists, or store a code block you want to find again. Text actions handle small chores — summarizing a note, fixing spelling, converting case, shortening or lengthening text, or translating it. On the Mac, other apps and system services can send text, images, or audio into Thoughts through URL schemes, open-with, macOS Services, and native imports. Thoughts for Mac is built for macOS users who want a fast place to put thoughts, notes, links, images, and voice memos without opening a larger note-taking app. The site lists its topics as Productivity, Writing, and Menu Bar Apps. Integrations are limited to the AI providers you connect — OpenAI, Claude, or Gemini — using your own API key, and to macOS system entry points such as URL schemes, open-with, macOS Services, and native imports. Pricing is straightforward: the app is free to download and use, including future updates, with no subscription; the only cost you may incur comes from the API provider whose key you use for AI features. The download is delivered through the linked Gumroad page, and the app is native to macOS. Thoughts for Mac keeps capture at the edge of your screen: a menubar click or a custom shortcut, a written note, a dragged image, or a spoken thought, all saved locally with no account required. Search, pinning, export, and light and dark modes make the notes usable afterwards, while optional bring-your-own-key AI actions add transcription, OCR, summaries, and translations through OpenAI, Claude, or Gemini. It is free, and every feature is available at no cost with future updates included.
tiun. is the AI-native backend for builders, positioned as one system for authentication, payments, a customer database, and analytics. According to the website, tiun gives AI and SaaS companies the backend they need to ship, scale, and grow their business in one unified platform. Rather than assembling a stack of separate services, teams get a single place where user accounts, billing, transactions, and product usage data live together. The product describes itself as the backend powering the AI engineering era, built from an ecosystem of services that are designed to work together from the start. Its stated goal is to remove webhook logic and business logic that developers would otherwise have to write and maintain themselves, so a builder can launch a paid product the same day they start building. The problem tiun addresses is the hidden complexity created by single-purpose tools. When authentication, payments, customer data, and analytics each come from a different provider, teams end up juggling multiple accounts, scattered data, and costs that compound as they scale. Keeping those separate systems in sync requires maintaining business logic purely for the sake of consistency, and that maintenance burden grows alongside the business. The website notes that this fragmentation also makes the insights a company needs harder to reach, because the information required to understand customers, usage, and revenue sits in disconnected places. tiun's answer is an ecosystem of services designed to work together from the start, so there is no webhook logic and no business logic to handle just to keep tools aligned. The way to adopt tiun is described as installing its skills, connecting its MCP endpoint, and letting an AI agent do the hard work. The site provides a single command — npx skills add https://mcp.tiun.business — and links to documentation at docs.tiun.io. This integration path is highlighted by customers on the page: one founding member at Braintonic comments that it worked so well there was no backend, no webhooks, and no custom logic, while a founder describes integrating it for a side project as working like a charm and an absolute no brainer for future solo builders and founders. The significance of this approach is that it shifts setup work away from manual backend engineering and toward an agent-driven installation flow, which lowers the barrier for builders who want working infrastructure without writing and maintaining the usual glue code. tiun's authentication section aims to provide everything needed for user authentication. Sign up, login, and logout are ready to use out of the box, and the platform describes them as simple and secure. Beyond those basics, tiun supplies a User Button and User Profile, giving users a dropdown menu where they can access their account and manage their profile and security settings. Multifactor authentication is included, with SMS passcodes, email, and social SSO listed as supported methods. For a builder, this means the account layer that normally requires careful implementation — credential handling, profile management, and stronger sign-in options — is available as pre-built functionality rather than something to design from scratch. Payments are handled without the need to write payment code or wrangle webhooks. With tiun, builders can create products and billing plans and accept one-time payments, subscriptions, and usage-based billing from day one. Pre-built checkout components can be dropped in as an overlay, so users never leave the page during the purchase flow. tiun also acts as the Merchant of Record: it processes payments, pays out monthly, and includes tax compliance and chargebacks. The site states that this model brings better fees and more functionality, and its example pricing shows transaction fees of 2.9% + $0.30, for a total of roughly 3.4% + $0.30 on international transactions. The third part of the system is a customer database where every user, transaction, and session is stored in one place, with no syncing between tools. User management keeps customers' subscription status up to date and stored alongside their user data, removing the need to build or maintain complex synchronization logic. Advanced event and session tracking logs every login, purchase, and product interaction at profile level, so teams can understand how users move through the product. The same area covers transactional emails for key user actions such as confirmations, password resets, and purchases, invoice history that lets customers view and download receipts and invoices from their profile, and plan management so users can upgrade, downgrade, or cancel directly without a support ticket. Data APIs expose one queryable API built on a consistent model that stays in sync and is ready to plug into an existing stack. Analytics is presented as one system your entire team can work with, so the full picture is finally visible and actionable. All data lives in one place, letting business, engineering, product, and marketing see who is signing up, who is paying, how they use the product, where they get value, and how to price it. Because authentication, billing, and product events share the same underlying model, these questions can be answered from a single source instead of being stitched together across separate tools. The site illustrates the value with a case study: Res Publica reported a 21% increase in paying users and grew its user base by 21% in the last 12 months after introducing usage-based billing with tiun, as described by CEO Martin Stedler. Overall, tiun's approach is to treat authentication, payments, the customer database, and analytics as one connected system rather than four independent products. The website frames this as an ecosystem of services designed to work together from the start, which is why there is no webhook logic and no business logic to handle simply to keep systems in sync. Integration follows an AI-native path: install the skills, connect the MCP endpoint, and let an agent carry out the setup, with the command npx skills add https://mcp.tiun.business and documentation available for reference. Installation is described as one command, and the promise is that a builder can launch a paid product the same day they start building. The benefits follow directly from that consolidation. Teams avoid multiple accounts and scattered data, and they avoid the compounding costs that come with maintaining several single-purpose tools as they scale. Because subscription status, session activity, and transactions all sit with the user record, there is no synchronization logic to build or maintain. Customers can manage their own plans, invoices, and profiles, which reduces the need for support tickets. And because business, engineering, product, and marketing all read from the same data, the insights needed to understand signups, payments, usage, and pricing are reachable rather than buried in disconnected systems. tiun is aimed at AI and SaaS companies and the builders behind them, including solo founders and developers who want to launch a paid product quickly; commenters on the site describe using it for side projects. Typical scenarios reflect the product's shape: adding sign-up, login, and multifactor authentication to a new application; accepting one-time payments, subscriptions, or usage-based billing from day one; offering checkout as an overlay so users stay on the page; giving customers self-service control over plans, receipts, and invoices; and asking who is signing up, who is paying, and how to price the product from a single place. tiun can be tried for free, pricing details are published on its pricing page, and the platform is used through the web as well as its MCP and data APIs. tiun's core value proposition is consolidation: one system that supplies the authentication, payments, customer database, and AI analytics an AI or SaaS business needs, installed with one command and connected through MCP so an agent can do the heavy lifting. By removing webhook and synchronization logic and keeping every user, transaction, and session in one place, tiun promises to help builders ship, scale, and grow from a single backend — and start charging on day one.
>> ALL_LOGS
Pixolm is an AI image generation and editing workspace for creators and small teams. Generate from text or reference images, then refine results with prompts and optional masks. An AI creative agent and dedicated workflows support icons, hand-drawn illustrations and ecommerce visuals. Features vary by model and mode. New users receive 20 one-time welcome credits; paid plans start at $9.90 per month.
Oats is a free, open-source meeting notetaker that records your meetings directly on your Mac — and on Windows in beta — without a bot joining the call and without sending your audio to a third-party cloud. When a meeting is over, Oats gives you a clean summary and a todo list you can actually work through, pulling out every action item along with who owns it, all from what was actually said. It is built for people who treat notes as the place a meeting's work starts rather than where it ends, and who want their recordings and AI processing to stay on their own machine. Oats is distributed as a desktop app, published openly on GitHub, and is free forever. Most note-takers want your recordings in their cloud. Many of them also join your calls as a visible bot, which can be awkward in external meetings and often needs host approval. Others put a paywall in the way — a seat count, a trial timer, or a limit that shows up around meeting number six. Oats was designed to not get in the way of your meetings: no bots, and no subscription needed when it runs locally with an on-device LLM. The product's stated principle is simple: your meetings stay on your machine. Oats records locally, runs AI locally, and never forces your audio off-device, while still offering richer cloud-backed features for people who want them. On-device recording is the foundation. Oats records directly from your Mac's audio — there is no browser extension, no bot, and no third-party server that ever touches the audio stream. It also works everywhere, because it captures any audio your Mac can hear: Zoom, Google Meet, Microsoft Teams, a phone call, or even a hallway chat. That means the tool does not depend on which conferencing platform a meeting happens in, and it does not require the meeting host to admit a recording bot before the conversation can be captured. After each meeting, Oats produces AI-written notes. These include a quick digest, a full summary, action items broken out per person, and a quality score derived from the conversation itself. In the app's own example, a weekly sync with three attendees and a #standup tag produces a quick digest noting the roadmap was at risk of slipping, that the team aligned on an August 12 ship date, and that Q3 pricing was locked — followed by two action items, one owned by Sarah (own the API rework, unblock by Friday) and one owned by Max (confirm the August 12 ship date with the PM), plus a meeting quality score. The result is a summary you can read in seconds and a task list that already names the owner. Action items are not left buried in a document. They collect in a Todos tab, and when you tick one off in the notes it closes, so follow-ups actually get followed up on. On the local backend, notes are plain Markdown and action items are stored as Obsidian Tasks inside a vault you choose — you can open the vault in Obsidian, sync it, or move it anywhere. Oats also lets you download a meeting's recording and export its notes wherever you want them in one click, and every meeting you record lands in a searchable library where you can ask questions across your whole history, such as what you decided about pricing. Oats works in three steps: hit record, get notes instantly, follow through. You start Oats and begin your meeting; it listens on your Mac with no bot and no third-party cloud, and nothing joins the call. When the meeting ends, Oats writes a structured summary and pulls out every action item with its owner. Those action items then land in your Todos, and ticking one off in the notes or in Obsidian closes it. You can run everything on-device with a local model and keep audio fully private, or connect your Ariso account for richer AI features — the Ariso.ai cloud backend adds enhanced transcription, multi-language support, speaker recognition, assessment, coaching, and auto-tracking of follow-ups. Speaker tagging matches each voice in a recording to the person who said it, so notes say who rather than "Speaker 2" (currently available on the ariso.ai backend), and you can sign in with Microsoft using your work account alongside Google from onboarding, Settings, or the menu bar. The benefits follow from that design. Because recording and AI notes can run entirely on your Mac with a local model, zero data leaves your device when you choose the local path. Because the software is free forever — no seats, no trial timer, no paywall waiting at meeting six — there is no cost barrier to capturing every meeting. Because it is fully open source on GitHub, you can audit every line, fork it, self-host it, or ship your own features on top. And because local notes are plain Markdown in an Obsidian vault, there is no lock-in: you can export anything, owe nothing, and leave whenever you want. In practice, Oats fits recurring team rituals and ad-hoc conversations alike. A weekly sync or standup becomes a digest, a decision log, and a per-person task list without anyone taking minutes. Calls that happen across Zoom, Meet, or Teams are captured the same way, since Oats listens to system audio rather than integrating with one platform. A phone call or an in-person hallway chat your Mac can hear can be turned into notes too. Afterwards, action items flow into a Todos list or into an Obsidian vault, and the searchable library lets you look back across your entire meeting history to answer questions like what was decided about pricing. Oats is aimed at individuals and teams who hold meetings on a Mac and want notes without a bot in the room, including people who care about keeping audio on-device and users who prefer open-source, self-hostable software. It also suits Obsidian users, since local notes are plain Markdown with Obsidian Tasks and can live in a vault of their choosing. Related integrations mentioned in the content include Google and Microsoft sign-in and the optional Ariso.ai cloud backend. Oats ships as a desktop download for macOS and Windows (beta), and pricing is free — free forever, with no seats or trial timer. Oats is a free, open-source, on-device meeting notetaker whose core promise is that your meetings stay on your machine. It records without a bot, writes summaries and owner-tagged action items from what was actually said, pushes follow-ups into Todos or an Obsidian vault, and lets you add cloud AI only if you want it.

Image to ASCII is a free, browser-based converter that turns a picture into a composition of characters. Users drop, paste, or choose a JPG, PNG, WebP, or GIF image — or load a built-in sample such as the neon jellyfish — and the tool renders it as text art in a live preview. From there they refine the output and either copy it as plain text or Markdown, or export it as TXT, PNG, SVG, HTML, or ANSI. It is made for developers, designers, and creators who need text-based artwork for README files, Discord servers, blog covers, terminals, and posters, and it works without a signup. ASCII art has always been a practical way to put imagery into places that only accept text: source files, README files, terminal screens, forums, and chat code blocks. The traditional route is a command-line utility, a script, or a lot of manual retyping, and the result often falls apart the moment it lands somewhere with a different font or line wrapping. Online converters solve part of that, but many require uploading a private image or creating an account first. This tool addresses both problems: the conversion happens inside the browser so the file never leaves the device, and the export options are matched to the destination, so the artwork keeps its shape whether it is pasted into a code block or shared as an image. The conversion runs locally. As the site puts it, images are processed locally and never uploaded — the image is read by the browser and converted with Canvas, so the file stays on the device. Supported inputs are JPG, PNG, WebP, and GIF, provided the browser can decode them; a GIF conversion uses the frame the browser provides, which means the output is a still result rather than an animation. Users can upload a file, paste an image, or start from a sample and replace it later. Because nothing is transmitted, the tool suits portraits, logos, and other images that should not leave a personal machine. Width and character set are the two controls that decide how much detail the artwork carries. The ASCII width can be set from very compact output — 56 columns for a Discord mascot — up to 220 columns for detailed studies. Fewer columns produce bolder characters; more columns produce finer detail. Character ramps determine the texture of the result: Detailed uses a smooth photo ramp, Dense uses @%#*+=-:. , Blocks uses Unicode symbols, Simple uses #*+=-. , and Minimal uses @. . According to the FAQ, making art more detailed means increasing the ASCII width, choosing the Dense character set, and raising contrast slightly, since detailed photos often need more width than simple icons. Advanced tuning gives control over light, texture, and background: tonal balance, brightness, contrast, sharpen, saturation, background cleanup, and dither, plus an invert toggle. The interface shows starting values such as tonal balance 1.25, brightness 0, contrast 8, sharpen 18, saturation 110, and background cleanup 99%, with dither available as a separate switch. Tonal balance is described as a way to recover midtones without clipping the extremes. These controls sit close to the preview so every change is visible immediately in the live canvas, which can be viewed as paper or as characters, expanded, and compared against the original image. Presets cover two kinds of starting points. Visual style presets — Auto, Neon, Pixel, Gallery, Fine Art, and Portrait — set a look, while destination presets — Logo, README, Terminal, Social, and Poster — are tuned for where the artwork will end up. The site also publishes practical recipes: Portrait uses a detailed ramp with dither on, mild sharpen, and medium contrast; Logo uses the Blocks style at a smaller width with high contrast and dither off; README uses a simple ramp around 80 columns followed by Copy README or Copy Markdown; Terminal uses 80 columns with clean light backgrounds and exports ANSI or TXT; Social uses 56 columns for chat code blocks or PNG export when spacing may collapse; and Poster uses a wider 200-column output exported as PNG, SVG, or HTML. Presets are starting points, not platform limits. Color is handled separately from structure. Color output uses sampled image colors, and color is preserved in PNG, SVG, HTML, and ANSI exports, while TXT, Markdown, README, and comment exports remain plain so they stay valid inside code blocks. The plain text formats keep editable characters; the image formats preserve the visual appearance, which matters when a destination font would distort the letters. The site explains why colored ASCII does not work in TXT: text files store plain characters, not per-character colors, so PNG, SVG, or HTML should be used when the colored preview needs to travel with the artwork. Exports and copy actions are grouped so the common path is one click: Copy Plain, Download TXT, Download PNG, Copy Markdown, Copy README, Copy Comment, Copy ANSI, Copy Share Caption, Download SVG, Download HTML, and Download ANSI. A typical workflow is three steps — upload, paste, or try a sample; choose a preset and fine-tune width, style, dither, sharpen, and color; then copy plain or Markdown ASCII or download TXT, PNG, SVG, or HTML. A before/after comparison slider makes it easy to check the original against the characters, and a gallery of example studies (Chrome muse, Silk in motion, Into the light, and Electric deep) can be loaded with their settings so users can see how each result was produced. Under the hood, the converter reads the brightness and detail in a picture and maps them to text characters, so light, shadow, and form become a graphic text landscape. It compensates for tall text cells when sampling the image so the result is not stretched, which is why changing the column width changes the level of detail rather than the character proportions. Because spacing is what keeps ASCII art readable, the tool advises using a code block to preserve spaces or exporting PNG when the destination changes the font, and it recommends keeping the result in a monospace font with line breaks intact. For READMEs it suggests starting around 70 to 90 columns with the README preset so the art fits code blocks on laptops and mobile screens. Three purpose-built destinations show how settings and export choices line up. For blogs and editorial work, a glass flower is rendered at 200 columns with the Detailed ramp and color, then exported as PNG or SVG so the character texture and colors survive, while the headline stays in the blog editor so it remains readable and searchable. For GitHub, a geometric fox becomes an 80-column Simple monochrome mark whose clean outline stays recognizable at small size, copied with Copy README for a fenced text block while the project name and links stay outside the artwork. For Discord, a ghost mascot is rendered at 56 columns in the Dense style and copied as Markdown so spacing holds in a code block, or exported as PNG when the message would wrap or clip. Beyond those, the tool lists code comment artwork, terminal welcome screens, forum text art, profile images, posters, and landing accents. Image to ASCII is aimed at developers, designers, and creators who publish in text-first environments, and it is free to use with no signup. It runs as a web application with a mobile-friendly workbench, so upload, tuning, copy, and export actions stay reachable on small screens. The workbench includes single-click samples, the before/after comparison, a character-oriented preview, and links to dedicated guides for blog ASCII covers, GitHub READMEs, and Discord messages, so users can follow a documented path instead of guessing at settings. The takeaway is that Image to ASCII turns an ordinary photo, logo, or illustration into text art without giving up control or privacy. Conversion happens locally in the browser, the controls beside the live preview make every setting's effect visible, presets and guides cover the destinations people actually publish to, and the export formats — TXT, PNG, SVG, HTML, and ANSI — let the same artwork travel either as editable characters or as a faithful colored image.

Web Search Agents by Nimble are self-learning agents that become experts at your specific research task. They are web crawling and research agents built for a specific domain — company enrichment, regulations research, and other focused use cases — and they crawl the web with surgical accuracy. Instead of returning generic results, the agents self-learn your use case to go deeper into the sources that matter most to you, giving your AI deeper and more relevant web context. The product is aimed at agent builders and teams that need expert-level web search for their AI agents, delivering higher accuracy at a fraction of the token cost. You can start by giving your AI the Nimble agent onboarding link, start building for free, or book a demo with the team. Web search is usually judged on generic benchmarks that do not resemble the queries a real agent builder faces. Nimble evaluates web search by domain instead, because that lets agent builders judge solutions against queries that resemble their own rather than generic benchmarks. Nimble argues that specialized intelligence needs a specialized web search, and invites teams whose domain is not listed to contact the company to see how Web Search Agents adapt to their use case. A second problem is cost: retrieving web context typically means redundant searches and parsing raw pages with an LLM, which consumes tokens. Nimble positions Web Search Agents as a way to retrieve exactly what is needed — with no redundant searches and no parsing of raw pages with an LLM — so teams get expert-level web search for their AI agents with higher accuracy at a fraction of the token cost. Web Search Agents are built to execute hyper-specific research workflows, crawling the web with surgical accuracy for the task at hand. They can also build and enrich web datasets: you define your schema and the agents return consistent results on every run, which makes it practical to assemble structured web data without manual cleanup. A monitoring capability, currently in beta, lets you continuously track any data point on any webpage in real time, so changes on the web surface as they happen. Together these three capabilities — hyper-specific research, schema-driven dataset building, and continuous monitoring — cover the common shapes of web data work an agent needs to perform, from answering a single research question to maintaining a dataset that stays current. Three capabilities underpin how the agents adapt to your use case and self-improve. First, compounding domain knowledge: the agents accumulate web context over time to master your domain, so their understanding of relevant sources grows with use. Second, deep web access for your sources: the agents combine web search with domain crawling to reach subpages that other tools cannot access, which matters when the useful information sits deeper than a top-level page. Third, full control over search methodology: the agents retrieve data within the scope and guardrails defined by your search plan, so you decide what is in bounds. Nimble summarizes this as agents that adapt to your use case and self-improve, rather than behaving the same way for every customer and every query. Governance is part of the design. Web Search Agents operate with full governance and control through auditable Search Plans that show exactly what was searched, where, and why — so you can inspect the path the agent took rather than trusting an opaque set of results. Accuracy compounds over time through a Proprietary Index and Memory that gets smarter with every query, meaning the agents retain and reuse what they have learned. The same retrieval discipline addresses cost: by retrieving exactly what is needed, the system avoids redundant searches and avoids the expense of parsing raw pages with an LLM. These three elements — auditable Search Plans, compounding memory, and precise retrieval — are the core promises Nimble makes for expert-level web search delivered to AI agents. The overall approach is that the agents self-learn your use case. Rather than being configured once and left static, Web Search Agents learn from the searches they run, building a memory and a Proprietary Index that improve the relevance of later results. They combine two access paths — web search and domain crawling — to reach both broad results and the deeper subpages that other tools cannot access. Each retrieval stays inside the scope and guardrails you define for the search plan, and every search is recorded so you can audit what was searched, where, and why. Nimble describes this as specialized intelligence for a specialized web search, and documents an onboarding path so your AI agent can be pointed at the product and begin building. The stated benefits concentrate on accuracy and cost. Nimble says Web Search Agents deliver expert-level web search for your AI agents with higher accuracy at a fraction of the token cost. Because retrieval returns exactly what is needed, there are no redundant searches and no need to parse raw pages with an LLM — two of the main sources of token spend in agentic web research. Accuracy compounds over time as the Proprietary Index and Memory get smarter with every query, so results improve rather than plateau. Control and trust are the other stated outcomes: auditable Search Plans show exactly what was searched, where, and why, and the agents work within the scope and guardrails you set, which makes it easier for teams to explain how a result was produced. Nimble publishes cookbook examples of what teams can build. Company research and due diligence can be run from a single prompt at audit grade. Teams can research case laws and regulations, enrich dependencies with health indicators, and find assortment gaps on the digital shelf. Retail and brand teams can find where products are sold to enforce MAP compliance, and go-to-market teams can discover businesses that match an ideal customer profile. Finance workflows include tracking analyst earnings predictions against actuals, and recruiting workflows include building a dataset of job candidates. Nimble also names the domains it evaluates and adapts to: market analysis, real estate, social media monitoring, travel and hospitality, company research, finance, product intelligence, and GTM. In those benchmarks, contestants independently completed 96 tasks per domain — covering reports, enrichment, and discovery — with each result graded fact-by-fact by an independent AI judge against a gold standard built without any contestant's input. Web Search Agents are aimed at agent builders and teams that need their AI agents to research the web reliably. Nimble says it is trusted by organizations including Databricks, Qudo and Uber under a "Trusted By" heading, and its site also displays a broader logo wall featuring brands such as Microsoft, Coca-Cola, L'Oréal, LG, TripAdvisor, Semrush and Browserbase. Native integrations are offered including Anthropic, GPT, LangChain and Vercel, and the product is documented as a Nimble SDK with an agent onboarding page you can give to your AI to get started. Security and compliance features include zero data retention, flexible PII masking, audit logs, data encryption in transit, and no training, alongside CCPA, GDPR and SOC 2 badges. Nimble invites teams to start building for free, try the product now, or book a demo to discuss use cases and see how Nimble delivers higher accuracy at a fraction of the token cost. For teams building AI agents that need reliable web context, Web Search Agents by Nimble offer a self-learning approach: agents that adapt to your domain, crawl the web with surgical accuracy, build and enrich datasets against your schema, and monitor pages for change. Auditable Search Plans provide governance, while a Proprietary Index and Memory compound accuracy over time and precise retrieval reduces token cost. The result is deeper, more relevant web context for your AI, evaluated by domain against queries that resemble your own rather than generic benchmarks.

LLMagnet is the official WordPress plugin that makes a website visible and understandable to AI assistants such as ChatGPT, Claude, Perplexity and Gemini. It tracks visits from AI bots in real time, gives insights into how language models interpret your content, measures an AI Visibility Score, automatically generates llms.txt files and manages schema.org structured data so that models can accurately read, cite and act on your pages. The product is made by web creators and built for agents and marketers, helping brands build a measurable presence in the AI ecosystem instead of guessing how AI search treats them. Search behavior is shifting. People increasingly ask AI assistants directly for answers, recommendations and products, so the traffic that matters no longer arrives only from classic search engines. AI crawlers and assistants fetch, parse and summarize pages on their own terms, and llms.txt is described by LLMagnet as an emerging standard, like robots.txt for search engines, that helps AI models understand a site's structure and content. Without that guidance, and without any data about which bots visit and what they read, site owners are essentially blind to how AI represents them. LLMagnet closes that gap by giving websites an AI visibility layer: real-time analytics on AI bot activity plus the files and schema data that make content easier for models to read, rank, connect with and trust. It turns an opaque new channel into something that can be watched, measured and improved. The core of the plugin is LLM Analytics, which tracks real AI-bot traffic and reports detailed insights into visits, impressions and clicks coming from major models including ChatGPT, Gemini, Claude and more. LLMagnet detects visits from ChatGPT, Claude, Perplexity, Gemini, Grok, Bing AI, Mistral, DeepSeek, Llama and others. Sitting alongside the raw traffic numbers is the AI Visibility Score, a single metric that reflects how well large language models can access and understand your content across the web. Trends & Insights then tracks that visibility over time so you can spot rising opportunities and content drops instantly, turning scattered bot activity into a picture of whether your AI footprint is growing or decaying. To make a site AI-ready, LLMagnet automatically builds and maintains an llms.txt file so AI crawlers can better understand site structure and content focus, and it keeps that file up to date without manual work. Depending on the plan, it also generates a Full-llms.txt and .md files. The plugin manages schema.org structured data as well, which helps AI assistants accurately read and cite pages. Because llms.txt is positioned as robots.txt for AI, it acts as a signpost for crawlers; generating it automatically means site owners do not have to research the format, write the file or remember to refresh it whenever content changes. Prompt Tracking & Optimization shows where your brand actually appears in AI answers. LLMagnet tracks the prompts that mention your site and shows how your ranking evolves over time, including which prompts include your brand, how visibility shifts by LLM, and what to improve next. Alongside this, Automated Reports & Insights sends weekly and monthly reports that summarize your visibility and growth, with auto performance reports, visual traffic breakdowns and actionable visibility tips. Together these features move the product beyond measurement into guidance: you can see not only that AI assistants are reading your pages, but which questions bring you in and where you are missing. For stores, LLMagnet is positioned around the future of AI-driven commerce. It turns a shop into AI-ready content by connecting to your product data so that AI can display accurate information in generative search, with auto product and price sync keeping details current, an AI-search visibility boost and product mention tracking. WooCommerce integration and product tracking are part of the Plus plan, and the FAQ notes that Plus and Enterprise plans add product visibility scores and AI revenue funnel tracking for WooCommerce stores. The result is that product listings, prices and brand mentions stay aligned with what assistants tell shoppers. Installing LLMagnet starts from the WordPress plugin directory: you enter your WordPress site and are redirected to your site's plugin installer so the plugin can be added in one click, with no setup or code required. Once active, it begins capturing real-time AI bot activity. The dashboard reveals which AI bots visit your site, what they read and how to improve your visibility inside AI answers through visual dashboards. Compatibility is broad: the plugin works with Elementor, Gutenberg, Divi, WooCommerce and more, runs alongside Yoast SEO and RankMath without conflicts, and integrates into the Elementor editor with per-page AI visibility scores and schema management. On WordPress 6.9 and later it connects directly to Claude, ChatGPT and Cursor via the WordPress Abilities API so AI assistants can query your site's data natively, and an MCP Connector is included in the plans. The approach is deliberately lightweight and privacy-safe: file generation and analytics run in the background, so there is no impact on front-end performance or page load speed, and bot visit analytics are stored locally in your WordPress database and never sent externally. Optional integrations are off by default, and the tool is fully GDPR-compliant with built-in data export and erasure tools. The stated benefits revolve around control and clarity. AI Visibility Control means knowing exactly how large models see your content; Smart Automation keeps llms.txt and your data always updated automatically; Deep Insights analyze which pages drive the most AI engagement; Enhanced Collaboration streamlines workflows with team-friendly features; Data Security safeguards your data with top-tier encryption; and Continuous Improvement lets AI adapt and improve with evolving data. In practice, users describe straightforward setup, clear understanding of AI-related traffic to their site, and a practical llms.txt generator that saved them time. LLMagnet is explicitly not framed as a magic SEO plugin, but as a solid tool for gaining visibility into how AI search is evolving. LLMagnet is aimed at web creators, marketers, solopreneur store owners and WooCommerce store managers who want to prepare for AI-driven discovery rather than react later. The free plan is available with no credit card required, and core features such as analytics, llms.txt generation and schema tools work on any WordPress site. Paid tiers add depth: Pro at $29 per month per site covering analytics from ChatGPT, Claude and Perplexity plus Full-llms.txt, .md files and an MCP connector; Plus at $100 per month per site with analytics from all bots, WooCommerce integration, product tracking and product visibility; and Ultra at $149 per month per user with prompt tracking and chat support. Yearly billing lowers those prices, and a Product Hunt launch offer advertises 50% off. A Shopify app is also available alongside the WordPress plugin. LLMagnet gives WordPress and Shopify sites a measurable AI visibility layer. By tracking AI bot traffic, scoring how well models can access your content, generating the llms.txt and schema data crawlers look for, and tracking the prompts where your brand appears, it converts an opaque new channel into something you can watch, report on and improve. For teams that want evidence of how AI assistants read, cite and recommend them, that combination of analytics, AI-ready files and prompt tracking is the product's core value proposition.
appdesigns is a free, in-browser editor for making App Store and Google Play screenshots. It is aimed at people who need to create app listing visuals, including app developers, designers, and marketers. The product's stated purpose is to help users design amazing app screenshots completely free. Users can drop in their screens, frame them in device mockups, add headlines, backgrounds and stickers, and export at the exact sizes App Store Connect asks for. The website emphasizes that no account is needed, there is no watermark, and exports are unlimited. The editor is accessed through appdesigns.click and is described as needing a laptop-sized window. The Product Hunt tagline says Design amazing appstore screenshots for free. The problem context is stated directly: many screenshot tools are free to start but then impose limits. appdesigns positions itself as truly free, not free to start. It highlights unlimited exports, no watermark, and no account required. This matters for app developers and teams preparing store listings because screenshots are a required part of presenting an app on the App Store and Google Play. The product removes sign-up friction and export restrictions, while keeping the creation process inside the browser. The metadata description says Make App Store and Google Play screenshots in your browser. Truly free, not free to start: unlimited exports, no watermark, no account required. The website also says support is appreciated but never required, reinforcing that the tool does not require payment to use its stated core capabilities. Device framing is a core part of the editor. The Device section lists Mobile, iPad, Mac, and Watch. Frame Type includes Uniframe and iPhone. Available device options include iPhone Duo, marked New; iPhone 18 Pro, marked New; iPhone 18 Pro Max, marked New; iPhone 17 Pro Max; and three more. Users can choose Portrait or Landscape orientation. There is a Show Device toggle, which lets users decide whether the device frame is visible. The product description also mentions framing screens in the latest iPhone, iPad or Mac. These options help users present screenshots in the context of real devices and match the type of app being shown. The Device section provides Mobile, iPad, Mac, and Watch options, while the Frame Type section offers Uniframe and iPhone choices. Uploading and customizing the screenshot content happens on the canvas. Users upload a screenshot, and the interface includes a Background section with Apply to all, Background Color, and Transparent. The background color example shown is #FF512F, and Transparent is an available choice. Text can be added directly to the canvas; users can click or drag to place it, or press T to place text. The Text section includes an Add text control and instructions: Click or drag to the canvas. Press T to place. The canvas displays slides numbered 1, 2, and 3, along with a canvas size of 1242 × 2688. These controls support adding headlines and visual treatments to app screens before export. Templates and transformation tools help shape the overall screenshot set. The website displays a Templates section with template artwork that users can browse. The Product Hunt description states users can start from a community template. Scale & Tilt controls let users adjust device presentation; the interface shows Scale at 135% and Tilt at 0°. The interface shows Scale 135% and Tilt 0° as example values, with the ability to adjust scale and tilt. The product description says users can design the whole set side by side, tilt and scale devices, or start from a community template. This combination supports creating a coordinated group of screenshots rather than editing each image in isolation. The overall workflow is explained in three steps: 1 Upload your app screenshots, 2 Choose a device frame, 3 Customise and export. This straightforward approach is presented as the main method for using the editor. Users begin with their own app screens, select a frame from the available device options, then customise with backgrounds, text, templates, scale, and tilt before exporting. The editor runs in the browser and the website notes that the editor needs a laptop-sized window, with a prompt to copy the link for your laptop. This indicates the tool is used in a desktop or laptop browser environment. Exporting is aimed at the exact sizes App Store Connect asks for, and the free offer includes unlimited exports, no watermark, and no account needed to start. Benefits and outcomes stated or directly implied by the content include creating app screenshots for free and without an account. The product removes the need to sign up before starting, and it does not add a watermark to exports, according to the website and metadata. Unlimited exports mean users can produce as many screenshot files as their listing requires. The in-browser editor avoids a separate desktop installation. The three-step workflow and community templates provide a guided path for users who may not be professional designers. The product also supports every device, every size, and no account needed, as stated on the website. Concrete use cases include preparing App Store and Google Play listing screenshots. A developer can upload app screens, frame them in iPhone, iPad, Mac, or Watch device mockups, add headlines and backgrounds, and export at required sizes. A designer or marketer can create a consistent set of screenshots side by side, using templates and background colour changes applied to all. A user who wants a device mockup without signing up can open the editor in a laptop browser, upload a screenshot, choose a frame such as iPhone 18 Pro or iPad, add text, and export. The editor also shows slides numbered 1, 2, and 3, which supports working with multiple screens in one session. The target users are app developers, designers, marketers, and teams who need store listing visuals. The product is designed for users who want a free, browser-based screenshot editor with no account required, no watermark, and unlimited exports. It supports Mobile, iPad, Mac, and Watch device frames and references exact export sizes for App Store Connect. Because the website states the editor needs a laptop-sized window, it is intended for use on a laptop or desktop browser rather than on a mobile phone. The website mentions support is appreciated, never required, but does not present it as a mandatory part of using the free editor. No pricing tiers, paid plans, or subscription details are stated; the pricing model is free. In summary, appdesigns is a free in-browser tool for making App Store and Google Play screenshots. It combines device frames, background controls, text, community templates, and scale and tilt adjustments with a simple upload, frame, customise, and export workflow. Its primary value proposition is stated clearly: amazing app screenshots for free, with no account, no watermark, and unlimited exports.
Naoma AI is an AI video sales agent that runs personalized product demos for B2B SaaS companies. It gives every prospect a live demo instantly, walking them through your product, answering their questions, qualifying them, and routing them to your CRM, calendar, or checkout. Naoma runs 24/7, starts demos in about 10 seconds, and speaks 33 languages, so buyers can explore your product in the language they think in, without scheduling a call or waiting for a rep to reply. The problem Naoma solves is the gap between a visitor's intent and a sales rep's availability. A typical book-a-demo button converts only 1–2% of visitors, and the rest leave. Prospects arrive across every time zone and in many languages, and a form means they must wait for a reply before they can see anything at all. In enterprise software, a single opportunity often involves multiple decision-makers across marketing, operations, IT, procurement, and management, each with different priorities, KPIs, and questions. Feature-rich platforms can also lose value in a self-serve trial, because people never discover what makes them powerful on their own. Naoma closes that gap by delivering a real, interactive demo at the moment of peak buying interest rather than after a scheduling delay. Naoma runs the entire product demo in four automated steps. First, a prospect on your website or in your app requests a product demonstration: there is no scheduling and no waiting, and the demo starts immediately. Second, the AI sales agent initiates a live, personalized demo tailored to the prospect's needs, industry, and role; it handles discovery, shows relevant features, and answers questions. Third, every qualified lead is sent straight to your CRM, and Naoma can book a meeting with your sales team or send high-intent buyers to checkout, with no manual handoff. Fourth, Naoma surfaces insights your buyers never tell a rep: competitors, objections, questions, and feature requests, giving sales, marketing, and product teams intelligence rather than just revenue. Hyper-personalization is central to how Naoma behaves. Every demo adapts to each customer's needs and context, and Naoma learns your product from your sales scripts, demo recordings, knowledge base, sales presentations, and demo environment, so it is positioned to handle even complex technical questions better than your reps. Demonstrations can be delivered through your website, in-app, or in outbound emails, so prospects get demos exactly when they need them. The agent remembers returning visitors and picks up where they left off, and every session is written back to your CRM, keeping the record of each conversation in one place. Language is handled natively. Naoma speaks 33 languages because buyers prefer to explore in their native language, and removing that friction helps every prospect understand your product and its value in the language they think in. Named agents illustrate the range: Alexandra Chen, VP of Sales, for English; Carlos Rodriguez, Head of Customer Success, for Spanish; and Sophie Martin, Product Marketing Director, for French. Customers report qualifying prospects in more than 10 languages they could never staff for. Avatars let you give demos a face that fits your brand. You can choose the signature Naoma agent, a branded mascot, or a static realistic avatar created from a real photo. Naoma adapts to your brand and creates memorable demo experiences while keeping the visual identity consistent with how you present your company. Naoma reports measurable quality from real end-user feedback across live AI demos. 89% of end users mention how human the experience feels, fewer than 2% of sessions hit any technical issue, and 77% of end users praise how it handles interruptions. The product is rated 4.9 on G2 by verified B2B SaaS reviewers, and it is GDPR compliant, protecting both your data and your customers' information with enterprise-grade security. The commercial outcome teams highlight is conversion from traffic they already have. Typical visitor-to-demo conversion is 1–2%; with Naoma, visitor-to-AI-demo conversion reaches 6–20%, so teams capture more qualified leads without increasing spend. Same traffic and same budget produce more demos and more qualified leads. Naoma's own product page illustrates the moments it covers: a VP of Sales at TechScale requests a demo at 11:42 PM and completes it at 11:42 PM, a Head of Marketing at CloudNexus requests one at 3:15 AM, a founder at DataViz at 8:23 PM, and a Director of Operations at SyncWare at 5:07 AM. The same flow is shown across growth stages — emerging, growth stage, scale-up, and established — with qualified customers produced in different regions. The point is straightforward: buying interest does not keep office hours, and Naoma is available whenever a prospect is ready. Naoma is used by B2B SaaS teams across many product categories. AiSDR, an AI sales development platform, uses Naoma to run personalized demos for website visitors, aiming to attract more qualified leads and book more product demos without adding sales headcount. UXPressia, a collaborative customer journey mapping platform, uses Naoma to give visitors a real interactive demo of its journey maps, personas, and AI persona builder, qualifying them around the clock. Hoteza, a web-based guest engagement platform for hotels, placed Naoma right after its book-a-demo form and behind a "Get AI demo now" button; since April, 57 hotels explored the product this way, and one regional partner signed after going through the AI demo. Mellow, which helps companies hire, manage, and pay freelance contractors across 150+ countries, uses Naoma to run personalized demos for its visitors. App Radar, an app store optimization platform, uses Naoma to qualify visitors and surface larger accounts worth routing into a sales-assisted funnel. Verified G2 reviews describe how teams use it day to day. A CMO at Hoteza noted that enterprise hospitality software involves long, complex buying processes with decision-makers across marketing, operations, IT, procurement, and management; Naoma lets each stakeholder explore the product independently, ask questions in context, and revisit specific features between meetings, reducing sales workload while keeping prospects engaged. A founder at UXPressia said its deep, feature-rich platform did not always come across in a self-serve trial, and that Naoma greets visitors, runs a real interactive demo of journey maps, personas, and the AI persona builder, and qualifies them around the clock. Another reviewer described Naoma as an additional source of leads that provides qualification information and effectively does discovery, freeing the sales team to focus on higher-value conversations. Naoma is built for B2B SaaS teams that want to convert more of their existing website traffic without adding sales headcount. The product is now self-serve: teams can upload their product and knowledge base and test the agent themselves, and a separate app is available to build your agent, along with an ROI calculator. Naoma has run 50,000+ demos for B2B SaaS teams, holds Product Hunt daily and monthly top-post awards plus a Tekpon Top Demo Automation Software Q1 2026 recognition, and was named in a Global Startup Award by The Ventures. The company raised $440k in pre-seed funding to scale AI video sales demos. The takeaway is that Naoma turns the moment a prospect is interested into a completed, qualified demo. Instead of a form that converts 1–2% of visitors, teams get an AI sales agent that demos the live product instantly, in 33 languages, 24/7, remembers returning visitors, writes every session back to CRM, and reports the objections and feature requests buyers never tell a rep. For B2B SaaS teams that want more demos from the same traffic and budget, Naoma provides an automated pipeline from first click to booked, qualified meeting.
OzBrain is a hosted knowledge base that acts as a shared brain every AI agent you use can read and write. Instead of each assistant keeping its own private memory, OzBrain provides one structured source of truth that sits underneath Claude, ChatGPT, Cursor, Claude Code and other connected agents. It is built for people and teams who already use several AI tools every day and want the work they have already done to be available the next time any agent starts a task. The company describes it as your Dropbox for agent knowledge: a place where structured articles with links, provenance and freshness live behind the connector menu that Claude and ChatGPT already show you. Today, context lives in your chats and your teammate's context lives in theirs, and the two never meet. People share a doc, drop a message and paste the same things over and over again. Meanwhile copies of the same plan sit in Drive, on laptops, in Downloads, in email, and no one is sure which version is current. Platform memory does not solve this either: as the site puts it, that memory is a few preferences and a thin summary of past chats. OzBrain's answer is to hold the work itself — your projects, decisions, research and the thinking you have already done — so an agent starts with what the task needs instead of whatever fits in a profile. The centrepiece is a single shared brain. Point everyone at one OzBrain and your agents and their agents read and write to the same place, so what one person works out, everyone's agents already have. The site illustrates this with a team view: a company brain holding company vision, rules and skills, engineering plans, customers, research and the roadmap, with individual people connected through Claude, Cursor, Codex and Claude Code. Because the knowledge sits outside any single chat product, it is not owned by whichever assistant happened to be used first. Sharing on brains you own is included in every plan, including the free one. OzBrain breaks your knowledge into nested pieces so that an agent pulls the exact slice it needs — the email body, not the whole launch plan. The site shows a launch plan at 11,842 tokens and 47.3 KB nesting into launch campaigns at 1,486 tokens and 5.9 KB, which in turn nests into launch email at 218 tokens and 0.87 KB. The argument is straightforward: the less an agent has to load, the faster and cheaper it answers, and the less it invents from context it never needed. Alongside this, OzBrain keeps the latest version out front. Instead of copies of the same plan scattered across Drive, laptops, Downloads and email, every agent decides from the current version rather than an old copy. When newer thinking lands, OzBrain goes back through your knowledge on its own, marks the old notes as replaced and points to the latest. You never have to hunt down every place an old decision lived, and no agent answers from a version you have moved past. The site gives the example of a website launch plan being updated when the company acquired a new domain, with related company details marked as updated to ozbrain.com. Every change is also on the record: which agent made it, what changed and the reasoning. Changes are proposed before they land, so several agents can work at once without writing over each other, and a recent-changes table shows the time, agent, article and reason for each edit. Privacy and ownership are handled explicitly. Your brain is encrypted at rest and sealed to your account, so nothing leaks between tenants. The site states that it never trains on your data and never sells it, describing OzBrain as a sovereign place for your data. Export is available at any time — everything as markdown, including after you cancel — on the principle that your knowledge should not be locked in anywhere, including OzBrain. Deleting your account removes your content: delete means deleted. The company also notes that it runs OzBrain on OzBrain, with its own data sitting next to yours, because it wanted the safest and easiest tool for itself as well as for users. Getting started does not require any coding. You add OzBrain from the connector menu in Claude or ChatGPT, sign in and approve it; there is nothing to install. Connect guides exist for Claude and ChatGPT, and the same brain can be reached from Claude Code, Cursor, OpenClaw, Hermes Agent, Gemini Spark where Google makes it available (US, Spark eligibility) and any client that supports connectors. Because it is one URL, anything that speaks the protocol can hold the same brain. Rather than being a memory API that developers code against, OzBrain is described as a brain you connect — structured articles with links, provenance and freshness, and one source of truth rather than a separate memory in each product. The stated outcomes for users are practical. Agents make fewer mistakes because they pull only the slice of knowledge a task needs. Answers are faster and cheaper because less context has to be loaded. Nobody has to maintain or "work" the brain, since replaced notes are marked automatically and the current version stays out front. Teams stop pasting the same context into several separate chats, and a brand-new chat can know what everyone has already worked on. Because everything is exportable as markdown, users keep an exit route and can move their knowledge to whichever tools serve them best. Concrete scenarios appear throughout the site. In one, a team connects individual agents through Claude, Cursor, Codex and Claude Code so the whole team's agents work together on the same knowledge — company vision, rules and skills, engineering plans, customers, research and roadmap — instead of each person's context living in a separate chat. In another, a website launch plan is updated when the company acquires a new domain, and OzBrain marks related articles, such as company details, as updated so no agent answers from the old domain. The changelog example shows several agents, including Claude, making coordinated changes to articles such as a website launch plan, an MCP setup guide and a surfaces page with a stated reason for each edit. A further scenario is a new chat starting with what a team has already worked on rather than from a blank slate. OzBrain is aimed at individuals and teams whose work already runs through multiple AI agents, from a single person's venture and personal knowledge to an organisation where agents run the operation from one brain. Supported integrations include Claude and ChatGPT through their native connector flows, plus Claude Code, Cursor, OpenClaw, Hermes Agent, Gemini Spark where Google makes it available (US, Spark eligibility) and any client that supports connectors. Pricing starts with Free at $0 forever, with up to 50 articles, sharing on brains you own, unlimited brains, reads, writes and connections, write-time size discipline and markdown export anytime. Pro is $20 per month with up to 500 articles, described as room for one venture plus personal knowledge. Max is $99 per month with up to 5,000 articles, for when agents run the operation from one brain. Enterprise sits above the Max ceiling with org-owned shared brains and per-seat pricing designed with you. Every plan includes unlimited reads and writes, and free plans mean you can start without a credit card. The takeaway is that OzBrain turns scattered, agent-specific context into one shared, encrypted and exportable brain that every agent and teammate can read and write. It keeps the current version out front, prunes replaced notes automatically, records who changed what and why, and lets you walk away with everything in markdown whenever you choose.
AppZapper 3000 is an uninstaller for macOS - the most fun uninstaller for the Mac, according to its developers. The idea behind it is deliberately simple: you drag any app into the AppZapper 3000 window, the app instantly finds all of the extra files that application has left around your system, and then you delete them with a real 3D zapper. The tagline for the product says it plainly: this is the uninstaller Apple forgot. It is made for Mac users who want to remove an application properly, along with everything that application installed, instead of only dragging a single icon to the Trash. It suits both people who have zapped apps for years and anyone who has never used a dedicated uninstaller before and simply wants a cleaner Mac. The original AppZapper was first released in 2006, and AppZapper 3000 is described as a rebuild of that tool for the 31st century. The site marks a 20 year legacy and states that the team is forever grateful to everyone who has been zapping apps over the past twenty years. That history points to the problem the product addresses. A Mac application does not consist of one file: alongside the app itself, there are caches, preferences and support files. Removing only the application leaves all of that material where it was. AppZapper 3000 exists to close that gap - to find everything an app installed and deal with it as a group, rather than leaving pieces behind for the user to hunt down manually. The problem matters because it is a routine, repetitive chore that is easy to do incompletely, and the tool turns it into a single, decisive action. The core interaction is drag, drop, zap. The first step is an empty AppZapper 3000 window, waiting for an app to be dragged into it. Once you drop an app in, AppZapper 3000 instantly rings in and targets every related file: caches, preferences and support files, described on the site as the junk an app installs. A ring-in moment announces that the related files have been located - the site's phrase, target locked, captures the point at which the app has assembled the complete set of items belonging to the application you dropped in. Nothing here requires you to know where macOS keeps application support data. The point of the feature is that you do not have to go looking through system folders yourself, and you do not have to guess which files are safe to remove. You see what was found, and you decide to zap. The deletion itself is the distinctive part: a real 3D zapper, with real laser bolts that blast away your unwanted apps and the junk they install. The business end of the zapper is a genuine laser bolt effect rather than a progress bar, and it is aimed with instant mouse aiming, so pointing at your target feels immediate rather than stepped or delayed. Recoil is described as manageable, which means the shooting mechanic stays controllable while still feeling physical. Firing is a single action - one click, one shot - which gives each removal a clear, satisfying conclusion. The site also shows explosion and smoke effect artwork that reinforces the zap. The zapper turns an otherwise invisible housekeeping task into something you can actually watch happen. AppZapper 3000 has also been rebuilt with the fluidity, agility and smoothness that the team says it always dreamed of - built to fly, in the site's words. That matters for a tool used in quick bursts: drag, aim, fire. Alongside the performance work, the app offers cosmetic choice through its sleek finish options. You can keep the classic livery, the look long-time users will recognise, or apply one of the new blaster themes to zap in style, so the tool can match your taste without changing how it works. For bulk cleanup there is Zap All, which lets you skip the one-click-one-shot rhythm entirely and blast them all away automatically. Between the single-shot mode and Zap All, the app covers both the careful, one-app-at-a-time case and the broader sweep when you have several applications you want gone. The overall approach is built around a deliberately playful metaphor: uninstalling as shooting. Rather than presenting a list of checkboxes and filenames and calling it housekeeping, AppZapper 3000 turns the same underlying job into a physical act, with an aim, laser bolts, recoil and a target-locked moment when the app's related files have been found. The workflow stays three steps - drag, drop, zap - and the fun is layered on top rather than offered in place of function. That is also why the 20 year legacy matters to the design: this is a rebuild of a tool people have used for two decades, keeping the same core promise of finding all of an app's extra files while updating the feel, the speed and the visual style for a new release. Some of the clearest statements of value come from the user comments gathered on the site. One user calls AppZapper an indispensable app, another says it is one of the first apps they install on a new machine, and others describe it as simple yet powerful, accurate, and something that just works. Several long-term users describe more than a decade of use - since a first Mac 15 years ago, over 15 years in the dock, and years of use without it ever failing. The recurring theme is reliability combined with simplicity: people expect it to remove an app and its extra files, and they expect the process to be quick. For anyone with the same expectation, the outcome is a Mac that no longer carries the residue of software you have already decided to remove. Concretely, AppZapper 3000 fits a handful of recurring situations. You have decided an app is no longer wanted and you want it gone properly, along with the caches, preferences and support files that belong to it. You have a batch of apps to clear out and use Zap All to blast them all away automatically rather than shooting them one at a time. You are setting up a new Mac and want to be able to install and remove software freely without leaving a trail of files behind - several commenters note the app is among the first things they install on a new machine. Or you simply want to try the tool before committing, in which case three free zaps let you drag, aim and fire a few times to see how it feels. In each case the workflow is the same: drag the app in, let AppZapper 3000 find everything, and zap. AppZapper 3000 is available for download from the AppZapper website, where there are also Try, Buy and Help options. The app is version 1.0 and requires macOS 15 or later. Pricing works as a try-then-buy arrangement: you can try three free zaps before deciding, and the Buy page handles the purchase. Existing customers are looked after through a license resend option on the site, and support is available by email, so recovering a license or getting help with the app does not require anything more than the website. AppZapper 3000 takes a task most Mac users treat as an afterthought - deleting an application - and gives it a full ritual: drag the app in, watch it find every cache, preference and support file it left behind, then destroy all of it with a real 3D zapper, one click at a time or all at once with Zap All. It is the legendary Mac uninstaller, first released in 2006, rebuilt with the fluidity, agility and smoothness the team always dreamed of and standing on a 20 year legacy of zapping apps. Its promise is narrow and clear, and that is the point: when you remove an app, remove everything it installed too.
Resurf is a personal context library — one place to keep the things you like, care about, and work on. It saves notes, links, images, PDFs, and documents into a fully local library, so the material you collect stays in one searchable spot instead of being scattered across browsers, folders, and apps. The app is built for Mac, iPhone, and iPad, and it is written entirely in native Swift. Its stated purpose is twofold: capture what you find, and then find it again — or hand that accumulated context to AI when you need a model to work with your own material. There is no Resurf account required, the app works offline, and sync through your own private iCloud is optional. The problem Resurf addresses is fragmentation. The things a person wants to remember arrive in wildly different formats and from wildly different places: an article on Substack, a PDF of a paper, a screenshot, a tweet, a GitHub repository, a YouTube video, a code snippet, a voice note recorded in the middle of a walk. Each of those lands wherever the app that produced it decides to put it. Later, when the thought returns — 'I read something about typography,' 'there was a paper worth revisiting' — there is no single place to look. Resurf's answer is the inbox model: save now, organize later. The library is meant to get more useful every time you save, because a growing personal collection becomes more valuable as long as it remains findable. A second, newer problem motivates the AI side of the product: AI tools are only as good as the context you give them, and most people have no structured way to hand over what they have saved. Capture is designed to stay out of the way. Quick Capture, bound to ⌘⇧C, lets you save something without switching context — the point being that a capture tool fails if it interrupts whatever you were doing. Content can come from any app: Resurf captures from Mac, Chrome, and iPhone into the same library, and a Chrome extension is available from the Chrome Web Store for browser-based saving. The library accepts a wide range of formats — articles, PDFs, images, audio, video, code, tweets, GitHub, YouTube, and notes — and every format renders natively, meaning you view the saved item as it was rather than as a degraded copy. Once something is saved, Resurf leans on an inbox-first approach: you do not have to decide where a capture belongs at the moment you make it. Organization happens later, through Spaces and Tags that let you group material around projects, research, and ideas — the page shows examples such as Research and Writing spaces and tags like #ml, #philosophy, and #ideas. A Visual Library complements that structure by letting you browse what you saved the way you remember it, which suits image-heavy or reference-heavy collections where a thumbnail is easier to recognize than a filename. Instant Search, triggered with ⌘K, finds notes, links, PDFs, images, and files quickly across the library — the page illustrates it with an example of searching typography notes across 24 captures from the last six months. Resurf also covers the moment after capture, when you have something to say about what you saved. Highlight & Annotate keeps your thoughts beside the source, so commentary lives with the material rather than in a separate document — useful when a highlighted passage only makes sense in relation to your note about it. Voice Memos capture thoughts before they disappear, which matters for ideas that arrive away from a keyboard. The Notes surface provides a rich-text editor with a formatting toolbar and highlights, and the product describes five surfaces — Library, Inbox, View, Notes, and Assistant — as the five places you will actually spend your time in the app. AI in Resurf is opt-in across the board, and the product is explicit about that. AI Summaries help you revisit articles, links, and PDFs faster by producing a short summary of the saved item. Bring Your Own AI lets you supply your own AI key rather than relying on a bundled service, and on Mac you can hand off saved context to AI agents through MCP or the CLI — a documented connection path in the guides. Ask Your Library lets you ask questions across the context you have saved; the page illustrates this with a query such as 'What did I save about typography?' answered against a reading list. Because the library lives locally, the material used for these questions is your own collection rather than a shared index. How the product works is defined by its architecture. Resurf is written entirely in native Swift for Mac, iPhone, and iPad, so the same library runs natively across all three rather than being wrapped in a cross-platform shell. Your library lives on-device — the page names the location ~/Library/Resurf — which is what makes the 'fully local' and 'private by default' claims concrete: data stays on your Mac, the app works offline, and no account is required. Sync is optional and runs through your own private iCloud rather than a Resurf-operated service. The Chrome extension and the MCP/CLI connection on Mac are the two extensions beyond the core Apple-platform apps: the first brings browser captures into the library, the second takes the library out to AI agents. The benefits follow from those choices. Because everything lands in one library with instant search, the answer to 'where did I put that?' is a single search rather than a tour of multiple apps. Because capture is bound to a keyboard shortcut and does not require switching context, saving feels lightweight enough to actually do. Because storage is local and sync is optional and private, the library can hold personal reading, screenshots, and voice memos without being uploaded to a third-party service. And because the library is exposed to AI through your own key, MCP, or the CLI, the collection becomes an input rather than a dead archive. The app is also free to try and, per the page, free on iPhone and iPad, with a separate license purchase for Mac. Concrete uses appear throughout the product's own examples. A reader saves a Substack article tagged #reading so it can be found later, and highlights passages while annotating them. A designer or writer keeps typography references and design notes in a space, browsing them visually — the page shows a query about typography answered from saved captures. A researcher stores papers such as a PDF of 'Attention is all you need,' marking it as worth revisiting. Someone away from a desk records a voice memo about a headline's typography. A developer saves GitHub repositories, code, and YouTube videos alongside everything else. Once the library has grown, the same collection can be queried directly — 'What did I save about typography?' — or handed off to an AI agent on Mac through MCP or the CLI. Resurf is aimed at people who collect: designers gathering visual references, writers and researchers assembling sources, developers saving code and repositories, and anyone who already runs a personal knowledge practice or wants to. Availability reflects that audience. The app runs on Mac (Apple Silicon and Intel) with macOS 14.3 or later, and is free on iPhone and iPad; the Mac app can be downloaded free to try or licensed through a purchase. A Chrome extension is available for browser capture, and a guide covers connecting agents over MCP or the CLI on Mac. The library itself is stored locally at ~/Library/Resurf, with optional private iCloud sync and no Resurf account required. The takeaway is that Resurf treats your saved material as an asset with two uses: a private library you actually revisit, and a context source you can hand to AI. It is fully local by default, native across Mac, iPhone, and iPad, built around quick capture and instant search, and organized through inboxes, spaces, tags, and a visual library. Its AI capabilities — summaries, asking your library, and agent handoff through MCP or the CLI — are opt-in and can run on your own key. For anyone whose best ideas and references are currently spread across browsers, folders, and screenshots, Resurf's proposition is a single, private, searchable place to put them.
ScreenCursor is a Chrome extension that records your screen and hands back a finished video with the camera moves already in place. Rather than returning a raw capture and leaving the zooming to you, it turns every click, drag and keystroke into a camera move while you are still recording. The result is a screen recording that is already watchable the moment you stop: there is no timeline to learn and no second pass in a video editor required. It is built for anyone who needs to show how something works on a screen — a demo, a walkthrough, a piece of work in progress — and who wants that video done without spending time on editing afterwards. As the site puts it, the middle step of the workflow, the zooming, is the whole product and it is the one you do not have to do. The problem ScreenCursor sets out to solve is a familiar one. Most screen recording software gives you back exactly what you recorded and leaves the camera work to you in a video editor. That means every demo becomes a two-stage job: record first, then sit down and manually place zooms, trim dead air and frame the footage so a viewer can actually follow what is happening. The site states plainly that the best screen recorders for sharing work are the ones that produce something watchable without a second pass, and that producing that is the only thing this product is trying to be. In other words, the tool is not trying to be a general-purpose video editor; it is trying to remove the editing step from screen recording altogether. The first feature is the automatic camera work, and it is the one that happens on its own. Clicks, drags and keystrokes are all picked up while you record. Each one gets a zoom at the same depth, and the zoom arrives a beat before the action so the viewer is already looking at the right place at the moment the action happens. Because the timing is anticipatory rather than reactive, the viewer's eye is guided to the click rather than chasing it afterwards. On the site this is summarised as every click, drag and keystroke becoming a camera move, placed and timed for you, with nothing to place by hand. The remaining features are there for when you want them, and the first of those is full control over every zoom. Nothing is baked in. You can retime a zoom, push its depth in or out, move it, switch the motion between snappy and gentle, or delete the one you did not want, and you can add your own zooms anywhere as well. The camera rebuilds as you drag, so what you are watching is what exports. This matters because automatic placement is only useful if it can be corrected; preserving full adjustment means the automation is a starting point rather than a fixed output. Framing and timing make up the next group of capabilities. For framing, you can sit the recording on a wallpaper, a gradient or your own image, softened so the backdrop never competes with the picture. You can add a browser frame carrying the real page title, round the corners, and pick the aspect ratio for wherever the video is going. For timing, you can split the clip anywhere, delete the stretches nobody needs to sit through, and speed up the ones that merely drag. Importantly, the zooms move with the cut, so nothing drifts out of step with the picture. Together these let a recording be dressed and paced for its destination without exporting into another tool. How the product works overall is described in three steps, with the explicit note that the middle one is the whole product and is also the one you do not have to do. Step one is to hit record: you pick your screen and go, and ScreenCursor waits three seconds so you can hide Chrome's sharing bar first, then stays out of your way. Step two is that it zooms itself, turning every click, drag and keystroke into a camera move that arrives before the click, holds steady, and then follows your cursor. Step three is export and ship: you can trim, cut or adjust any zoom if you want to, then export MP4 at up to 1080p straight to your Downloads folder. The whole pipeline — recording, editing and export — happens inside your browser, and the video never leaves your computer. There is no account to create and no server for it to go to. The benefits that follow from that approach are stated directly on the site. There is no watermark, no account and no subscription, and there is no limit on how much you record. Because everything stays local, recording and editing work offline and nothing is uploaded, ever. The purchase is one payment of $49 at early pricing (regularly listed at $79), yours permanently, with updates included, and one purchase activates on up to three of your own computers. Export is MP4 at 720p or 1080p, delivered to your Downloads folder like any other file, ready to upload anywhere without conversion. The Chrome Web Store rating shown is 5.0. In practical terms, ScreenCursor is aimed at scenarios where someone has to show a process rather than describe it. That includes recording your whole screen, including anything outside the browser such as other apps, your desktop or a design tool, and producing something a viewer can follow without having sat through the raw capture. It suits demo videos and work-sharing clips where the site's own framing is "sharing work" and, in its closing line, "stop editing your demos." The workflow is deliberately short: pick the screen, hide the sharing bar during the three-second wait, perform the task once while the zooms are placed for you, optionally trim the dead air, and export. One purchase covers a laptop, a desktop and a work computer, and if you replace a machine you can free its slot from the license page inside the extension or from your Polar account and activate the new one. Because it is a Chrome extension it runs wherever Chrome does, including macOS, Windows and Linux; recording performance depends on the machine having hardware video encoding, which the site says almost everything made in the last decade has. The site also positions it against Screen Studio, noting that Screen Studio is macOS-only and costs about $108 a year, while ScreenCursor is $49 once and runs anywhere Chrome does, though it acknowledges Screen Studio does more, including webcam overlay, motion blur and recording an iPhone over USB. The takeaway is narrow and deliberate: ScreenCursor exists to make screen recordings that are watchable without a second pass. It automates the camera work that normally lands in a video editor, keeps full manual control for when you want to change something, and does all of it locally in the browser with no account, no watermark, no subscription and no upload. If the goal is a demo that is finished when the recording stops, that is the entire value proposition.
DemoTV is a 24/7, television-style channel where short product demos play continuously and the audience — not advertisers — decides what sits at the top. Founders submit a demo, viewers watch two products go head to head in a Channel Battle and back the one they would actually try, and that pick becomes the audience rank. Channels 1, 2 and 3 are the current top three on the station, driven by an Elo-style audience score built from wins and battles. The station is made for independent makers, startups and product teams who want their demo discovered by people genuinely interested in trying new tools, rather than ranked by whoever spends the most money. Watching and voting requires no sign-up. Getting a new product in front of the right people is hard, and most channels hand the top slots to whoever pays for them. That leaves independent builders competing for attention against budgets they cannot match. DemoTV separates the two ideas: exposure can be bought through clearly labelled placements, but standing on the station cannot. Rank 1 on a channel is the demo viewers picked most — the page states plainly that it is not a paid slot and that airtime never buys rank or a channel. This gives founders a place where a strong demo can outrank a bigger budget, and gives viewers a feed of products that other people, not ad buyers, decided were worth a look. The core mechanic is the Channel Battle. Two products built for the same job are shown head to head, and the viewer simply backs the one they would try — no sign-up required. That pick feeds the audience rank, and the resulting ranking decides which demos occupy Channels 1–3, the current top three on the TV. Each demo carries an audience score alongside a win and battle count; the number one entry at the time of capture showed a score of 1368 from 145 wins across 178 battles, with Channels 2 and 3 close behind on 1344 and 1315. The directory board mirrors the channel: rank 1 sits first on the board and is the same tape as Channel 1, and Channels 2 and 3 are the next two. Demos only start playing when a viewer presses play or selects a channel, so nothing auto-plays just because someone scrolled past. For founders, getting on the station starts with a free submission — no card needed. A demo can be a YouTube link or an MP4 upload (40 MB maximum), and every submission is reviewed before it goes live. The submission flow runs through four steps: website details, video, visitor action, and review. Before submitting, makers can have DemoTV suggest a title and tagline from their project URL, and they choose the category whose battles the demo will join. Once approved, a private dashboard provides a single embed code for the maker's own website — a widget containing the video, an optional try link and a chosen button label such as Visit website, Start free, Join waitlist, Book a demo or Claim offer, with a configurable button destination. From the dashboard, founders can also request testers, cap reveals, and claim their company. Makers who want to reward viewers who picked them can attach an optional viewer thank-you — a backer code such as a time-boxed free week or a percentage discount, which never moves the Elo score and does not appear on battle buttons. Paid reach exists, but it is kept separate and clearly labelled. After claiming a listing, a founder can buy airtime units (5, 10, 25 or 100, with the price shown at checkout) which add promoted placements across the reel and directory; the page states repeatedly that these units never change a demo's audience score or channel. Featured partners pay $39 for 30 days of labelled placement as a homepage card — the copy notes that partners support the station, never the rank. Demo Studio is a paid option, priced at $79 for “Make my tape,” where a maker pastes their site and gets automated production with station QA before air, subject to their approval, while rank remains audience-only. Launch Week is a labelled 7-day sponsorship. Every one of these options buys exposure, completed views and clicks, never the ranking. The overall workflow is deliberately simple and stated on the site as three steps. First, submit your demo for free — a YouTube link or MP4, no card needed, reviewed before it goes live, with the message that submitting is free to founders. Second, win Channel Battles, because viewers pick the demo they would try and those wins move Channels 1–3. Third, boost with airtime if you want extra reach — optional labelled ads that become available after claiming the listing and that never touch the rank. A new entry begins as a pending station approval; the demo stays private until review is complete, and the maker receives a private management link and an email when it is live. For makers, the outcomes are discovery and validation rather than empty impressions. A demo that viewers would genuinely try climbs, so the success metric is real audience preference instead of ad spend. Founders get an embeddable widget they can place on their own site, a way to recruit testers, a company listing with a contact-the-maker form and reporting tools, and a channel that keeps showing their tape to people browsing the station. For viewers, DemoTV offers a way to discover independent products, watch short demos and try something new — with the ability to influence what gets seen next by backing the products they would try. Use cases follow directly from this setup. An indie founder launching a new app can submit a short demo for free, get it reviewed, and enter the relevant category battle without spending anything. A product with a direct competitor can be placed head to head in a Channel Battle — the site itself shows a battle between two app builders — and let viewers decide which one they would try. A maker who wants to test demand can attach a backer code and give viewers who picked them a time-boxed free week or discount, then measure interest. A team that already has a demo video can embed the widget on its own site so visitors watch the demo and take the try action directly. Advertisers and companies with budget can buy labelled airtime, featured partner placement or Launch Week sponsorship to reach the station's audience while leaving the ranking untouched. And a viewer simply looking for new tools can browse the demo directory, sorted by audience rank or newest, to find products to try. The directory itself is organised around categories that define which battles a demo joins: AI agents, AI app builders, video generation, chat assistants, computer use, developer tools, design & no-code, data & analytics, marketing & sales, productivity, infra & APIs, games, crypto & web3, crypto wallets, crypto infra, robotics & hardware, fintech & payments, security & privacy, education, consumer & social, climate & energy, and other. Makers can suggest a new category of 2–40 characters, which is listed under Other until reviewed. The board is paginated at 10 demos per page with sorting by audience rank or newest, and the station reported 110 live demos, 571 audience backings, 54.2K views and 6,845 visitors at the time of capture. Station numbers only appear once live demos exist. Contact for takedowns, press or submissions is hello@demotv.lol, reporting options cover scams, spam, malware, adult content, impersonation and broken videos, and the site's optional first-party analytics are explicitly described as containing no ad trackers or search terms. The takeaway is straightforward: DemoTV is an audience-ranked channel for product demos. It gives founders free airtime that is earned by the audience's own picks, keeps paid promotion clearly labelled and strictly separate from rank, and gives viewers a simple, sign-up-free way to watch demos and decide which product deserves the top channels.
Visiby is an AI visibility platform that measures and grows how brands appear across AI search platforms, including ChatGPT, Claude, Perplexity, Gemini, Google AI Overviews and Copilot. It acts as a visibility layer for the AI-search era, mapping entity presence across the top AI engines so marketing teams can see where they are recommended, where they are missing, and which competitor is being cited instead. The product is built for marketing operators and agencies who need to own the answer layer rather than only rank in traditional search results. Vendor discovery has moved. According to the content, 1 in 3 B2B buyers now start vendor research inside an AI assistant, and ChatGPT, Perplexity, Google AI Overviews, Gemini and Copilot are quietly intercepting traffic that used to land on a company's site — if the model does not surface the brand, the conversation never starts. The site states that 62% of enterprise marketers are already optimising for AI engines, citing the State of AEO 2026 from FNA Research, while the well-funded brand in a category treats Answer Engine Optimisation as a budget line whose citations compound week over week. Meanwhile, Visiby argues that zero tools in a typical stack measure what AI is saying about a brand: Semrush ranks, Ahrefs ranks, GA counts clicks, but none of them sample prompts, parse model answers, or explain why ChatGPT recommended a competitor instead of you. Visiby exists to close that blind spot with a continuous, prompt-level view of AI answers. The workspace opens on an Overview that serves as the weekly headline: search performance, AI visibility and the next moves the team should ship, readable in 90 seconds. Headline scores include Visibility, Share of Voice, Prompts won and Briefs ready. Search Performance explains a brand's organic traffic and click-through rates, tracking clicks over 28 days with month-over-month change, impressions, click-through rate and average position across tracked non-brand terms. AI Visibility shows where a brand appears and where it does not, presenting per-engine citation share across every prompt in the universe, with each cell clickable to reveal the underlying answer. In the illustrated workspace, ChatGPT sits at 42%, Perplexity at 51%, Claude at 34%, Gemini at 24% and AI Overviews at 18%. The Prompts Explorer is a workbench for the full prompt universe — more than 50,000 AI prompts are tracked weekly, and the sample workspace shows 50,127. It supports stacked filters, a cluster view and a three-way live answer diff, and each row drills into which competitor was cited, why, and the play to win the prompt back. The Citations Explorer works beneath the prompt universe across every URL the engines cite — 2,418 URLs in the example — ranking every cited URL and identifying honey-pot pages, dead-weight pages and counter-content briefs, with passage-level provenance. The Brand Entity module shows the adjectives a brand owns and the ones owned against it across engines, with per-engine portraits and reframe plays to move them; the sample adjective sets include trustworthy, established, enterprise, scalable, innovative, modern, consultative, agile, long-tenured and data-driven. Competitor Intelligence reads the field at a glance, presenting citation share by brand and topic with clickable cells that drill to the prompts and passages behind them, plus a per-competitor recipe diff comparing cited elements across engines, such as H2 headings, FAQ blocks, tables and lists. Recipe Intelligence delivers a per-engine pulse on which on-page element the AI is actually extracting from, producing the structural blueprint a team should publish to; Visiby reports that seven elements are tracked, including H2 headings, FAQ blocks with FAQPage schema, tables, bulleted lists and case studies. Site Audit is a citability-first audit that ranks every issue by AI impact with the fix and affected URLs attached, surfacing examples such as pages blocked from indexing, pages missing OpenGraph tags and meta descriptions, thin pages under 250 words, missing Organization schema, missing FAQ schema and image alt text gaps. The Action Plan converts all of this into a prioritised, priced playbook ranked by effort against impact, where every move carries an argument, a score breakdown covering why-now signal, forecast confidence, effort and dependency, evidence links, and a ready-to-ship deliverable brief. Visiby runs as a weekly ritual. Every Tuesday at 07:42 IST, the platform fuses three live data streams — the prompts buyers actually ask, where the brand is losing citations, and the recipes competitors win with — into one prioritised action plan, with no analyst required. The pipeline runs overnight and lands in the inbox as a citation sweep, share-of-voice deltas, a prioritised action plan, content briefs and an executive summary. A weekly digest email example reports the number of prompts run across engines, the movement in citation share, the action moves ranked by projected lift in points, and a forecast of the week when citation share returns to a target level. The platform continuously samples engines, and the site positions the cadence at seven days from signal to a shipped fix. Benefits described include replacing guesswork with evidence about what AI engines recommend, seeing exactly which competitor is being cited first on high-value prompts, and knowing which structural elements and content formats win citations on each engine. Instead of a dashboard nobody opens or a spreadsheet exercise, teams receive an inbox-ready brief with ranked moves and attached briefs, so prioritisation and writing can start immediately. Ranking moves by effort against impact lets a small team focus on the highest-lift work, and the prescribed fixes — schema, content refresh, comparison pages, original research — are tied to specific projected visibility gains. Concrete scenarios in the content include a marketing team reading the weekly overview and shipping the queued moves; a brand losing citation share to a named competitor and building a comparison page in response; refreshing a contact page for AI parseability because it lacks crucial entity definitions and brand identifiers; adding FAQ schema to a services pillar of 14 core URLs missing structured Q&A data; producing original research on AEO benchmarks to capture data and stats queries; and running community and earned-media plays such as a Reddit thread cluster or listicle outreach to G2 and Capterra. Agencies can use the same workspace to run client AEO programmes, and the Agency tier supports white-label client reports and multi-workspace reporting. Visiby is aimed at marketing operators, enterprise marketers, SEO and AEO specialists, and agencies. It complements rather than replaces existing SEO platforms, and the site compares its capabilities against Semrush, Profound, Conductor and Ahrefs across AI visibility tracking on five engines, SEO and rank tracking, brand entity audits, passage-level citation provenance, recipe intelligence, priced action plans, ready-to-ship content briefs, an autonomous weekly pipeline and multi-workspace reporting. Pricing has four tiers: Lite at $49/mo with 25 prompts a month and one seat; Starter at $99/mo with 50 prompts a month, 10 action items and Site Audit plus Action Plan; Pro at $249/mo with 150 prompts, 30 action items, three seats and three brands, daily refresh, Brand Entity, Competitor Intelligence, Sentiment Analysis and priority support; and Agency at $499/mo with 500 pooled prompts, 50 action items, 10 seats and 10 workspaces, white-label client reports, API access and SSO/SAML, custom engines and regions, and a dedicated success manager with an SLA. A free visibility report is offered in 60 seconds with no card required. That combination makes Visiby a visibility layer for the AI-search era: it measures how brands and competitors appear inside AI-generated answers, explains the structural recipes that earn citations, and turns those signals into a prioritised, priced plan a team can ship on Monday.
Ghostwriter by MyHandler is a Windows desktop writing tool that drafts text for you directly inside whatever application you are already using. Instead of opening a separate chat window and describing what you want written, you place your cursor in a text field, double-tap the hotkey, and your Handler reads what is actually on your screen — the thread above the cursor, the question beside it, the half-finished sentence inside it — works out what you would write next, and types that draft at your cursor in your voice. There is no prompt to type and nothing to say out loud. It is built for people who spend their day answering messages, email threads, Slack conversations, browser forms and comment boxes, and who want the first draft of a reply to already be there, in their own style, without leaving the app they are working in. The problem Ghostwriter addresses is the gap between knowing what to say and getting it written. Most AI writing tools require the user to describe the request first: you have to summarise the thread, explain the tone, paste in context, and then copy the result back to where it belongs. That description step is often the same work the user was trying to avoid — as the site puts it, describing what you want was the work you were avoiding. Meanwhile the context that actually matters — the conversation on screen, who is speaking to whom, what is being asked — is already sitting in front of the user, and the calendar that determines whether a proposed time is even possible lives somewhere else entirely. Ghostwriter's approach is to take the screen itself as the input, remove the prompt, remove the copy-and-paste round trip, and leave the final decision — whether to send — with the person. The interaction model is deliberately minimal. There is no prompt field, no sidebar, no dictation. You put your cursor where the words go and double-tap the hotkey in any text field, in any app — the Product Hunt listing names double-tap Left Ctrl. The Handler then captures the screen around that cursor: the thread above it, the question beside it, the unfinished sentence in it. That capture happens on your own machine, against an encrypted vault on your PC, and the assembled context is sent to the cloud model with zero data retention to write the draft. Because the screen in front of you is the entire input, it works the same way across the applications the site names — your mail client, Slack, a browser form, a comment box — with nothing per-app to set up. Before writing a single word, Ghostwriter decides what kind of writing it is looking at. The site describes the situations it distinguishes: a reply owed in a thread, a sentence to continue from exactly where it stops, a blank box under a question that wants a real answer, and a message the context obviously calls for. Getting that classification right is described as most of the job, which is why the decision is made before any drafting begins. The consequence is behavioural: a continuation does not restate your own sentence back at you, and a reply does not summarise the thread back at the person who just wrote it. If the reply it produces proposes a time, that time is checked against the next two weeks of your calendar first — the product states plainly that it won't double-book you. Ghostwriter also tracks who is who in a conversation. It maps each message to its sender, works out which handle is yours, and follows who asked whom for what, so that the draft answers the other party rather than replying to your own words. On top of that identity mapping, it matches how you write to that specific person, down to the sign-off. The material it draws on can include the thread on screen, your calendar, your files and your past meetings, indexed in an encrypted vault on your PC. Together these two behaviours — correct attribution and per-person voice — are what separate a draft you can send from one you have to rewrite. Nothing is ever sent. Ghostwriter types its draft into the text box and stops; you read it, change it, delete it or send it, and that last step stays yours. If you select text first, the double-tap rewrites the selection instead of drafting something new. Architecturally the product is split: the screen capture and the encrypted vault live on your own PC, while the assembled context goes to a cloud model with zero data retention in order to write the draft. Ghostwriter is part of the MyHandler desktop app, so it ships alongside the same Handler's other capabilities — Dictation, which turns held-key speech into text at the cursor; an AI Gatekeeper that watches every connected channel, screens the noise on your PC and never sends a word on its own; Contact Intelligence, which builds living contact profiles automatically on your machine from messages, meetings and activity already in your vault; and a Daily Briefing written from local data. The stated benefits follow directly from that design. There is no prompt to write, so the whole interaction collapses to a double-tap. The Handler reads the situation rather than just the words, so the draft lands in the right register: a continuation continues, a reply replies, a form gets filled, and a message the context calls for gets composed from scratch. It gets who's who right, so the answer addresses the other party rather than your own words. And because the draft arrives at the cursor in your voice, in the style you use with that person, the editing pass is a light one rather than a full rewrite. The outcome the product advertises is the end of rewriting the same reply over and over: it drafts, and you decide. Concrete scenarios come straight from the described workflow. You are in your mail client with a thread open and your cursor in the reply box; a double-tap puts a reply drawn from the thread above the cursor in place. You are in Slack and a question is sitting there for you; the Handler maps the message to its sender and drafts the answer to the other party. You are in a browser form or a comment box with a blank field under a question, and it composes a real answer rather than leaving the box empty. You have half a sentence on screen and want the next part; it continues from exactly where the text stops. You are arranging a meeting and the draft proposes a time; the next two weeks of your calendar are checked before the words appear. Or you have already written something and want it said differently: select the text, double-tap, and the selection is rewritten. Ghostwriter is aimed at people whose working day is made of written replies — anyone living in email, team chat, browser forms and comment boxes who wants the first draft to already exist and to sound like them. It runs on Windows 10 or 11, requires a cursor in a text field to trigger, and needs a connected calendar only for the scheduling cross-check; everything else works without one. The product is described as free for Windows 10 and 11, with macOS and Linux coming soon. Because the screen capture happens locally and the index lives in an encrypted vault on the PC, that side stays on your machine, while the drafting step uses a cloud model with zero data retention. Ghostwriter's proposition is narrow and clear: two taps and it's already written. Every other AI writes what you tell it; Ghostwriter writes what you already know, using the screen in front of you as the input and your own voice as the output, and it hands the last step — sending — back to you.
Kirokune is an iPhone app for logging work and personal incidents. It lets you capture what happened in your own words — through a short note, a voice recording, or a photo — and keeps that record on your iPhone, organized into a timeline inside a private case. The app is designed for people who have been told to document everything but have no simple, private place to do it. Unlimited records in one case are free, and no account is required to start; you open the app and begin. Kirokune also offers a free workplace incident log template and example on its website, so you can start documenting even before you install anything. Everyone says document everything, but the practical question of where to write it down rarely gets answered. Work and personal incidents often happen at moments when you have neither the energy nor the time to sit down and compose a careful written account. Details fade, exact wording is lost, and the sequence of events blurs together. Kirokune addresses that gap by lowering the effort of capture to almost nothing: one tap starts a recording, and a photo or a quick note works just as well. The record you create while it is fresh stays on your iPhone until you decide what, if anything, you want to do with it — you do not have to let it go just to get through the day. The core of Kirokune is capturing what happened while it is fresh. A short note written in your own words is enough to begin, and a single tap starts an audio recording for the moments when you cannot bring yourself to type. Photos can be saved alongside notes and recordings, so a visual detail sits with the written account rather than in a separate camera roll. All of these record types live together in the same place, which means you are not choosing one format at the expense of another. The app does not require any setup before you start — you open it and immediately begin a note, a recording, or a photo. Once records exist, Kirokune organizes them rather than rewriting them. Events are shown in time order — dates, times, and exact words — and the timeline is reviewed alongside your original notes. Critically, nothing you already wrote gets changed; the app keeps your own record organized and that is all. Records are grouped into cases, and the free plan allows unlimited records inside one case. Kirokune Plus adds unlimited cases, so people who are tracking more than one situation can keep each one separate. Sorting happens later, when you have the energy, rather than at the moment of capture. Kirokune can also save a chat export as a record. You choose a supported export file from Apple Messages, Messenger, or Instagram — without connecting your chat accounts to the app. Kirokune keeps the file's whole original text alongside the messages it can display, so the original wording stays attached to the record. Because the app does not connect to those services, the guidance suggests choosing the conversation and date range before exporting, where the service allows it. This makes it possible to fold a written conversation into the same private case as your notes, recordings, and photos. The workflow Kirokune describes has three steps. First, get it down: open the app and start a note, a recording, or a photo, with no setup first. Second, sort it later: when you have the energy, group what you saved into a private case. Third, look back: everything is in order, exactly the way you wrote it. Underneath that workflow is a deliberate approach — the app stores records on your device and requires no account. Nothing leaves the app unless you export it yourself. Kirokune states plainly that it does not decide what happened, does not diagnose, and does not give legal advice; it keeps your own record organized. The benefit is that you won't have to go from memory. When you decide to talk it through — with someone you trust, HR, a lawyer, or a support service — having it written down in your own words helps you explain what happened. Because capture takes one tap or one short note, you can document something at the moment it happens instead of reconstructing it weeks later. Because records stay on your iPhone, privacy is the default rather than a setting you have to find. And because you can name the other person however you like — initials or a nickname you would recognize later — you are never forced to record a name you don't want to write. Typical uses follow the situations the app was built for. Someone documenting a workplace incident notes the date, the time, where it happened, what was said, and who was there, as soon as they can, and Kirokune keeps all of that together in one private place in time order. Someone who wants a record in the moment but cannot type taps record instead. Someone preparing for a conversation looks back at what they saved, at their own pace, and pulls it into a summary they can walk someone through. Someone with a written chat conversation exports it and saves the file as a record so the original text stays with it. The free worksheet on the website lets anyone start this practice without an app at all. Kirokune is for iPhone users running iOS 17 or later. There is no Android app; the website's free worksheet can be saved and used in your own notes without installing anything or creating an account. The app is available in the United States and India, with English, Japanese, Traditional Chinese, Korean, and Spanish interfaces. Kirokune is a free download with in-app purchases: the free plan covers unlimited notes, recordings, photos and other records organized in one case, with no account required. Optional Kirokune Plus adds unlimited cases, detailed reviews, PDF export, and removal of ads, available as monthly, yearly, or one-time lifetime purchases, with local price and renewal terms shown in the purchase screen. Two practical notes appear in the app's own guidance. Rules about recording and sharing a conversation vary by place and by situation, so Kirokune suggests considering letting the other person know and checking the rules where you are; the app cannot tell you whether a recording is lawful or how it would be treated. Also, Restore Purchases checks access to your paid plan and does not restore a backup of your records, because records are stored on your device and the app currently provides no automatic sync or cloud backup — so keep your own copies before deleting the app. The takeaway is simple: Kirokune is a private place to write down what happened, on your iPhone, until you decide to talk to someone.
Cue is an Awwwards-tier UI component library for anyone building to stand out. It gathers best-in-class components from across the internet and curates them by hand, offering bold hero sections, smooth interactions, unique layouts and thoughtful micro-animations that help teams ship websites that do not just work but stand out. Cue is made not only for AI builders but also for designers, developers, agencies, solo makers and product teams who refuse to ship generic-looking work. It describes itself simply as the taste layer on top of the tools people already use, and today every component ships with an AI prompt so users can recreate what they see inside their own projects. The starting point for Cue is a familiar frustration: most component libraries, template packs and AI-generated interfaces look interchangeable, and shipping something distinctive usually means hours of reverse-engineering interactions spotted on award-winning sites. Cue approaches that problem from the opposite direction. Rather than generating components to fill a grid, the library is assembled from hand-picked references, sourced from an Awwwards Site of the Day, a Behance-featured interaction, or a production output the founder considered best-of-class. The editorial section describes the collection as the best web interactions from Awwwards, CollectUI and X, delivered together with the code and prompt needed to recreate them in your own project. The stated bar is taste, not volume: if a user finds a better reference for the same component, the founder replaces the existing item, so the catalogue keeps improving instead of merely growing. The library itself is organised around the building blocks of a high-end marketing site. Cue lists bold hero sections, smooth interactions, unique layouts and micro-animations, and the site exposes tags for sections and interactions alongside filters for new versus old entries. At the time of writing the library advertises 75+ components with daily drops, so the collection is presented as a growing, frequently refreshed catalogue rather than a fixed download. A dedicated Editorial stream highlights a new drop each day. An email signup lets visitors be notified when new components ship, described as no spam and unsubscribe anytime, and the founder states that every drop is hand-picked personally. What makes Cue unusual among reference galleries is that every component ships with an AI prompt. Those prompts are designed to be dropped straight into Bolt, v0, Cursor, Framer AI, ChatGPT or Claude, so instead of studying a screenshot and rebuilding an animation by hand, a user can hand the prompt to the AI tool they already work in and adapt the result to their own project. The free tier of Cue allows visitors to browse the whole library and copy two AI prompts every 24 hours, which lets people test the workflow before committing. Because the prompt travels with the component reference, the interaction and the implementation guidance stay together. Beyond prompts, Cue states that React source code and an MCP server are actively rolling out. The MCP server is described as giving native access from Cursor, Claude Desktop, or any MCP-aware AI tool, which means an assistant can reach the component library directly rather than relying on copy and paste. React source code targets the developers who want the underlying implementation rather than only a description. Together these additions move Cue from a browsable gallery toward a resource that plugs into the toolchain of AI-assisted development. Cue's positioning is deliberately narrow. It does not host projects, deploy code, or run an AI model of its own; it is the taste layer sitting on top of the tools people already use. It also states plainly what it is not: not a template pack, not a subscription, not a course, not an AI wrapper, and not a marketplace. Curation is done by founder Alok, a founder-designer who hand-picks every drop and describes the work as building the taste layer for AI components. Because access is offered as a one-time lifetime payment rather than a recurring fee, the emphasis stays on singular, vetted references instead of a constantly billed content feed. The promised outcome is straightforward: build less and create more. Teams that struggle to produce distinctive interfaces get a shortcut to the interactions and layouts that define award-winning sites, without spending days dissecting how they were built. Designers gain a curated reference library that reflects a single, consistent point of view rather than an unfiltered dump of community uploads. Developers get prompts and, as they roll out, React source and MCP access, which shortens the distance between seeing an interaction and shipping it. AI builders get a way to raise the visual quality of what their assistants generate. For solo makers and agencies, the appeal is the same: differentiate visually while keeping the existing toolchain. Concrete uses follow from the components on offer. A designer putting together a portfolio can browse hero sections and unique layouts for a starting point rather than a blank canvas. A developer building a landing page in React can copy a prompt, paste it into Cursor or v0, and adapt a micro-animation that would otherwise take hours to recreate. An agency can use Cue as a reference source when pitching or producing client work that needs to look handcrafted. A solo maker launching a product can pull in an interaction that lifts the site above a default template. Teams working inside Claude Desktop or another MCP-aware client can eventually reach the library natively. Community activity is part of the workflow too: a Discord invitation lets members pick the next drop, and the founder is directly reachable for questions or for hire. Cue is aimed at designers, developers, agencies, solo makers and product teams, as well as AI builders, who refuse to ship generic-looking work. Pricing is structured as a free tier plus one-time lifetime access. Free browsing includes the full library with two AI-prompt copies per 24 hours. Cue+ Founding Lifetime is USD $99 as a one-time payment, capped at the first 50 members. Cue+ Lifetime at the standard rate is USD $249 one-time after the founding tier sells out. Promotional pricing has been offered at $79 lifetime, and the site also mentions custom pricing where you pay only for the components you pick. Technically, Cue centres on AI prompts for Bolt, v0, Cursor, Framer AI, ChatGPT and Claude, with React source code and an MCP server rolling out. The takeaway is that Cue sells taste rather than volume. By hand-picking Awwwards-tier components and pairing each one with an AI prompt, and soon React source code and MCP access, it gives designers, developers and AI builders a faster route to interfaces that stand out, while staying a layer on top of the tools they already use.
Neopress is an AI website builder that lets you build, publish, and grow a website by chatting with an AI assistant. Instead of assembling pages by hand, you describe what you want in plain language and the assistant helps create pages, organise structured content, and refine the result. It is aimed at people who need a real content workflow behind their site — a built-in CMS, server-rendered SEO, GEO tools, forms, and analytics — rather than a static page that never changes. Neopress describes itself as connecting website creation, structured content publishing, SEO tools, and traffic insights into a single workspace so you can keep improving after launch. The problem Neopress addresses is that a website is not finished when it goes live. As the site explains, a website needs ongoing content updates, search settings, and performance review after launch, and those tasks usually live in separate tools. Neopress was built by a team that has shipped hundreds of content sites, and it is optimised for one thing: websites that get found — clean structure, a real CMS, and SEO that works by default. The product brings content management, search configuration, and analytics into one place, so the post-launch loop of updating, measuring, and improving becomes part of the same workflow as building the site in the first place. Neopress works through agents that operate alongside you. The first is a design agent: describe the page you want in plain language and watch it take shape, then refine layout, copy, and style through conversation. The stated advantage is that there are no templates to wrestle with and no design tools to learn. The second is a CMS agent: work with AI to draft and organise content in CMS collections, review the copy and SEO settings, then publish when you are ready. The Launch plan includes unlimited pages, unlimited CMS collections, and unlimited forms and lead capture, so the content structure of the site is not capped by the plan. Search visibility is handled by built-in SEO and GEO tools. Neopress delivers page content as server-rendered HTML, so search engines and AI crawlers read the structure and text of a page instead of an empty browser-rendered shell. Metadata and Open Graph settings can be reviewed and edited for search results and social previews. Neopress generates a sitemap.xml automatically so search engines can understand and crawl the site structure, and it publishes the emerging llms.txt standard for you — a clean, curated map of your key pages for AI assistants. Structured data (JSON-LD) can be added and reviewed to help search engines understand a page's content, and robots.txt gives control over crawler access so you can block pages you do not want indexed. Beyond the core tags, Neopress adds the plumbing that content sites usually need later: HTTPS with SSL by default, automatic canonical tags to avoid duplicate content, a custom 404 page, 308 redirects from old URLs to new pages when reorganising a site, an automatically generated RSS feed, image alt text for accessibility and image search, and clean, human-readable, keyword-friendly URL slugs. Fonts are self-hosted and preloaded to cut layout shift and speed up first paint, images are optimised for size, format, and delivery, and pages are responsive so you can review how they appear on mobile screens. Neopress states it is built for Core Web Vitals, with server rendering, caching, and a global CDN supporting fast page delivery. Multilingual publishing lets you configure site languages, review translations, and publish language versions with hreflang support. Neopress describes its overall approach as a flywheel with four stages: build, publish, measure, and improve. You build by chatting with AI, publish structured content through the CMS, measure with the analytics dashboard, and improve by asking AI to review site and performance data. One agent focuses on measurement: ask AI about the analytics available for your site, review its explanation and suggested changes, then choose what to improve. Another agent reviews available site and performance data, identifies issues, and suggests changes for you to decide which improvements to apply. The recurring theme is that AI proposes and explains, while you review and decide — publishing and publishing changes always remain your choice. The stated outcome is a website that gets found and keeps improving. Because every page ships as real HTML rendered on the server, crawlers can access content without relying on browser-side rendering. Because the CMS, SEO settings, and analytics sit in the same workspace, there is no gap between writing content and configuring how it is indexed. Analytics covers tracking search queries, checking post indexing status, seeing which LLMs crawl your pages, and tracking paid, campaign, and visitor data, with Google Search Console and Google Analytics integrations available on the Growth plan. On ownership, Neopress states that you retain full ownership of all content, copy, and structural assets generated by the AI — Neopress provides the hosting and the engine. Neopress is used to build and grow content-driven websites. Its template gallery shows the range: Blog & Editorial, Corporate, Documentation, and Landing Page templates, with published examples spanning skincare and dermatology clinics, a non-surgical spine and joint hospital, an oriental medicine clinic, a boutique Pilates studio, an artisan bakery and cafe, a design studio journal, and a bespoke jewellery atelier. For teams with an existing site, Neopress offers website migration — moving your existing pages, content, domain, and redirects over without a rebuild from scratch — and design services for a new page or a fresh look, discussed directly with the Neopress team. Day to day, the workflow is drafting and organising content in CMS collections, publishing pages, then reviewing analytics and applying SEO improvements. Pricing is subscription-based with plan-based AI usage and traffic allowances, and it starts with a 7-day free trial. Launch costs $25 per month per site with 10,000 pageviews per month included and $1 per additional 1,000 pageviews. It includes AI chat creation and editing, unlimited pages, unlimited CMS collections, unlimited forms and lead capture, built-in SEO and AEO optimisation, search-readable pages via SSR, llms.txt, robots.txt and sitemap control, JSON-LD structured data, RSS feed, URL redirect rules, custom domain connection, logo and favicon settings, a social share (OG) image, a custom 404 page, removal of the Made by Neopress badge, a real-time analytics dashboard covering the last three months, one editor seat with unlimited viewers, version history and Rewind restore, and MCP support. Growth costs $99 per month per site with 50,000 pageviews included, about three times the AI usage of Launch, ten editor seats with role-based permissions, real-time collaboration presence, full analytics with paid, campaign and visitor tracking, visibility into which LLMs crawl your pages, search query tracking, post indexing status, Google Search Console and Google Analytics integrations, two years of data history, multi-language support, a multilingual sitemap with hreflang, and priority support. When a trial ends or you stop paying, published content remains available on your Neopress subdomain on the Free plan while custom domains pause. Pageviews count human visits plus crawls made by AI to cite your pages in its answers; search engine indexing and AI training crawlers are not counted. Security and trust features include Supabase infrastructure with authentication-controlled database access, Supabase Auth, Vercel's DDoS protection, Polar as merchant of record for payments, and version history for restoring previous versions of pages and site layout. In short, Neopress positions itself as one AI-powered loop for building and growing a website: you create pages through conversation, publish structured content through a real CMS, ship server-rendered HTML that search engines and AI crawlers can read, and then use analytics plus AI review to decide what to improve next. The core value proposition is a website that gets found and keeps getting better, managed end to end in a single workspace rather than scattered across separate building, CMS, SEO, and analytics tools.
Youkti is an outbound system of thinking and action that turns account knowledge and relationship data into revenue. It is built to help sales teams win more new logos, move more pipeline, and reactivate dormant accounts using intelligent outbound, live signals, and a complete memory of every account. Youkti combines conversational campaign building through its AI GTM agent ARYA, a daily execution cockpit for reps, automatic account journey tracking, and deep account intelligence with deal context and recommended next actions. The product is aimed at sales leaders, revenue operations teams, account executives, and outbound representatives, and it gives each of those roles a command surface tuned to their job — intelligence for leaders and RevOps, actions for AEs and sales leaders, and outbound workflows for reps and GTM teams. The problem Youkti addresses is that momentum inside a pipeline is easy to lose. Deals slip without anyone noticing in time, dormant accounts quietly fire buying signals nobody sees, and reps walk into strategic meetings without knowing which stakeholder joined or which questions are still unresolved. Youkti keeps a memory of every account, conversation, and deal, then tells the sales team the exact next move: which deal is slipping, which dormant account just fired a signal, and what to prepare for tomorrow's meeting. Instead of relying on static workflows, stale battlecards, and manual CRM updates, the system continuously overlays live signals and relationship data onto every account so the next best action is always visible. The first major capability is the conversational GTM builder. Rather than dragging and dropping blocks or writing if-else logic, users tell ARYA what they want in plain English, and it builds the entire flow through conversation — signal triggers, persona matching, outreach rules, and cadence. The configuration updates live as you talk, and the flow editor shows a live config review alongside run history and settings. Example flows shown in the product combine triggers such as Funding Raised or Hiring Surge with target personas such as VP Sales, CRO, Head of Sales, VP Marketing, or CMO. If both a funding raise and a hiring surge are detected, the flow can apply an aggressive tone on a cadence of every three to four days across five emails; if only one condition fires, it can apply a consultative tone weekly across three emails. Because the configuration is generated through conversation, there is no drag-and-drop canvas and no if-else branching to maintain. The second capability group covers daily execution. Every morning, reps open a single screen — the Cockpit — where accounts are prioritized, signals are overlaid, personas are matched, and sequence hooks are already written, with one click to push. The cockpit shows counts such as total accounts, active signals, today's plays, high-priority plays, live sequences, pending replies, and meetings for the day. Accounts are queued with the detected signal and the reason it matters — for example, a hot account showing a hiring surge signal detected yesterday — together with matched personas such as a CTO or Senior Director of Product, the linked sequence such as a five-step, 18-day Sales Leaders Outreach play, and a send action. This is described as what a true system of action looks like: signal-driven prioritization, one-click sequence push, and the thinking layer made visible to the rep. The third capability group is tracking and account intelligence. After a sequence is pushed, every account enters an Account Journey, where Youkti tracks status, engagement, replies, meetings, and surfaces the next step automatically — no manual updates, no digging, and no missed follow-ups. The journey view summarizes total accounts, meetings today, unactioned items, and total actions, and it segments accounts into states like Growing, Stable, Needs Attention, and At Risk, showing a summary of outreach, status, last contact, and AI-generated next steps such as high buying intent detected or an active email thread that should be pushed toward a meeting. Clicking into any account opens a deep-dive board with emails sent, replies, meetings, next actions with reasoning, the latest meeting brief with talking points, stakeholder maps, a full account timeline, signals, insights, sales actions, and talk tracks — plus automatic meeting prep. The system recommends; the user decides. A further capability is the intelligence layer, described as 100+ parameters and every signal in one snapshot. Youkti Execute scores every account on readiness, ICP fit, budget, timeline, and sales cycle, then generates deal actions, strategic approach, entry points, key messages, and email templates — a six-step account-based campaign in one click. The scorecard example shows readiness of 9/10 and ICP fit of 8/10 with explicit reasoning such as Highly Qualified Enterprise Target rather than a black-box number, alongside budget context, timeline for pilot approval, sales cycle length, ROI potential, effort level, best timing, the account's competitive edge, and recommended next steps such as launching an outbound sequence, connecting on LinkedIn, proposing a tech-stack consolidation audit, or pitching a pilot. Strategic deal enablement material includes ROI potential, effort level, success metrics, value demo scripts, and a phased execution timeline. The system also monitors signals across the entire TAM — funding, hiring, leadership changes, lawsuits, competitive moves, and tech stack swaps. When something fires, the user does not just get an alert: they get the analysis, the reasoning, and the timing window, including confidence scoring with reasoning, a Why It Matters explanation for every signal, and timing windows such as Next 2-4 weeks that indicate when to act rather than only that something happened. Those signals feed sequence generation: Youkti writes complete multi-step sequences with A/B variants, each tied to specific signals and account context, including campaign strategy, messaging angles, subject lines, and email bodies. A generated sequence example shows six steps, twelve emails, and a sixteen-day duration, with one click to push the selected variant into a sequencer such as Lemlist, Outreach, or any SEP. The platform modules that make this up are built to work together. Prospects & Lists lets teams build, distribute, and track high-quality prospect lists at scale, assign ICP-fit companies to reps, and monitor execution centrally. Account Intelligence delivers 100+ parameters of contextual company intelligence on any account in under 60 seconds with a single click. Outreach Automation generates messaging angles, follow-ups, and outreach guidance tied to real signals and account insights. Competitive Intelligence tracks competitors, comparisons, and real-time changes that impact active deals. Sales Enablement centralizes decks, case studies, and battlecards so reps always use the latest narrative. CRM Enrichment automatically enriches and updates accounts, contacts, and activity so CRM data stays accurate without manual effort. ARYA is the AI GTM agent that builds the flow, writes the outreach, and tracks what's next. Account Journey builds personalized, multi-touch engagement journeys that adapt to signal changes and rep activity, and Execution Analytics tracks outbound execution across every rep, account, and play. The benefits described are concrete: winning more new logos, moving more pipeline, and reactivating dormant accounts; seeing which deals are slipping and why before they stall out of the pipeline; understanding the top competitors in your deals and the top objections from your clients; preparing strategic conversations with the messages that landed you deals; and giving every rep exactly what to do each day. The vendor also states it helps avoid spending $100K+ on Salesforce Data Cloud 360 and implementations, because Youkti has your data covered. Customer stories cited on the site include NeoSOFT generating $50K+ pipeline growth, Samvidh Technologies increasing revenue 20% quarter over quarter, and Deeploop increasing selling time by 3×. Use cases shown in the product illustrate how this plays out. Protecting an at-risk deal: an account flagged At-Risk, awaiting board approval for 16 days, with the suggested action of scheduling a meeting with the VP of Operations who was last contacted 16 days ago. Prioritizing a high-intent account: a SaaS Series B company marked High Priority with a new CRO hired, nine sales leadership roles open, and Series B funding raised, carrying an ICP score of 96/100, with LinkedIn and email actions for the named contact. Reactivating a dormant account: a healthcare enterprise where the last contact was 94 days ago and a new signal was detected about a digital transformation initiative, with a drafted email to the named contact. Opening an expansion opportunity: an enterprise manufacturer with a renewal in 60 days where the Operations business unit is 78% engaged and Supply Chain is 62% engaged, prompting a call with the named contact. And preparing for a strategic meeting: a retail enterprise meeting tomorrow where the CIO has joined the meeting, with tasks to review a new stakeholder map, resolve unresolved security questions, prepare recommended talking points, confirm the CIO attendee, and schedule an internal team meeting. Youkti is built for AEs, RevOps, sales leaders, and outbound reps, and its integrations cover the surrounding stack. Email and calendar integrations include Gmail, Google Calendar, Outlook, Exchange, and Office 365. Data integrations include Snowflake, AWS, OneDrive, SharePoint, and Google Drive. CRM integrations include Salesforce, HubSpot, Zoho CRM, Pipedrive, and Freshsales. Prospecting data providers include LinkedIn Sales Navigator, Apollo.io, Lusha, Cognism, Clearbit, People Data Labs, ZoomInfo, Full Enrich, Kipplo, Prospeo, BetterContact, Clay, and Bitscale. Sales engagement integrations include Outreach, Salesloft, Apollo.io, and HubSpot Sales, and signal integrations include Google Analytics, rB2B, SEMrush, Ahrefs, and Hotjar. Youkti states it is constantly adding new integrations. Contact data, buying signals, and intent are described as free, with no card and no meter. In summary, Youkti's core value proposition is that it is the outbound system that thinks: it remembers every account, conversation, and deal, continuously watches for signals across the market, scores and reasons about that intelligence, and then converts it into specific actions — from building a campaign through conversation to pushing a personalized sequence and tracking what happens next.

Work Life Panda is a task manager and calendar that live together in one calm app, available on iPhone, iPad, Android and the web. Instead of asking you to rebuild your life inside a new tool, it starts with the life you already have: you connect the calendar you already use and your week is simply there, then you capture everything else in a sentence. Every task and every event carries its own chat, its own files, its own people and its own tracked history, so the plan and the conversation about it stay in the same place. It is built for personal and family life as well as for teams and small businesses, and it is designed to be a single connected workspace rather than one more app in the stack. Most task apps start empty and ask you to rebuild your life inside them. Your week, meanwhile, lives in a calendar, your to-dos live in a list, and your plans live in a group chat - three separate places that rarely agree with each other. Work Life Panda's stated position is that this scattering is the problem: the product asks you to stop scattering your life across separate tools. By connecting the calendar you already use rather than importing a copy of it, the app arrives already full of the week you have. Invitations that sit in your email become events on their own, so nothing has to be forwarded, copied or retyped. The result is meant to be one calm place for everything you have to do and everywhere you have to be. Calendar connectivity is the foundation. Work Life Panda supports Google, Apple iCloud and Microsoft Outlook calendars, all syncing both ways, plus Fastmail and Zoho, and it can follow any calendar that is published as a link. The stated approach is that the calendar remains yours rather than becoming a copy: change something in either place and both stay right. Because your to-dos and your whole schedule sit together, planning happens against the real week you actually have. The product also connects to email: a booking that lands in your inbox becomes an event on your calendar, and connecting an iCloud or Outlook mailbox turns the invitations already sitting there into events on their own, with no forwarding and no copying. Gmail support is described as waiting on Google's security review. Panda AI handles the busy steps. It turns a sentence or your voice into a task, smoothing the parts of capture and structuring that usually slow people down. Crucially, it runs on your device rather than in the cloud, so nothing goes to the cloud, and it works with no internet connection. That design choice is presented as a privacy and control feature: the AI that turns a sentence into a task runs on your device, so your data stays with you. Capture is meant to be fast enough to keep up with a passing thought, and the structure the AI produces keeps that thought connected to the rest of your life instead of leaving it loose in a notes app. The stated goal is that you keep control while safe local AI automates the busy steps, moving faster without handing your life to an opaque cloud. A chat on everything is the second core idea. Every task and every event carries its own chat, files, people and tracked history, so the conversation lives on the thing it is about. You can discuss and decide on the item itself, assign it, hand it off and see what moved. Sharing one with your partner, your family or your team means nobody has to ask where it was decided. You can also connect a calendar into a shared space so everyone sees it. In teams and shared contexts this replaces the familiar pattern of a plan living in one tool while the discussion about it lives in a noisy chat thread - the plan and the conversation stay together. Work Life Panda organizes life into shared spaces. You pick the shape that fits - a home for personal and family life, or one for the teams, groups and small businesses you plan with; the app is described as the same calm place either way. Within that, the product manages people, roles, kids and rewards from the same core workflow, covering shared responsibilities, family routines and reward systems. Birthdays, anniversaries and other important dates are kept in one place so the personal moments that matter do not slip through the cracks. Notes stay connected too: ideas, lists, meeting notes or family context can be captured without losing the connection to what needs doing. Together these make the product, in its own words, more than a task app - one evolving operating layer for life. The same source of truth follows you across phone, tablet and desktop, so your life does not split just because your devices change. On iPhone and iPad you capture, plan, collaborate and stay on top of life from the device already in your hand; Android keeps the same connected workflow with the same shared model, collaboration and AI-assisted experience; and the web app is there when you want a larger workspace for planning, reviewing and coordinating. The app can be downloaded from the App Store and Google Play, or opened in your browser. Because the AI runs on-device and the app works offline, using it across devices does not mean depending on a connection. The stated benefit is calm and continuity: everything you have to do and everywhere you have to be in one place, with nothing to import and nothing to retype. Because the calendar is connected rather than copied, there is no duplicate to maintain and no drift between two schedules. Because every task and event has its own chat, decisions are recorded where the work is, and no one has to reconstruct where something was decided. Because the AI is local, privacy is preserved and capture still works without a connection. And because the app opens on the life you already have rather than an empty list, that value is available from the first moment instead of after a long setup. Work Life Panda describes itself in terms of real scenarios. For personal and family life, that means chores, kids, plans, reminders, notes and birthdays captured in a sentence and kept in one private place on every device you already own, with no shared wall tablet required. For teams and business, it covers trips, clubs, shared houses, side projects and small teams, giving a plan a real home where tasks, events, files and the conversation about them live together instead of being scattered across a chat thread and three tools. A concrete flow the product illustrates is a booking landing in your inbox and the event landing on your calendar, alongside a weekly calendar with an event imported from email shown next to the day's task list. Shared spaces let a partner, family or team discuss, decide, assign and hand off on the item itself. Work Life Panda is free to use - completely free during early access, including every Pro feature - and the company states that early members always get its best pricing later. It works on iPhone, iPad, Android and the web, with downloads from the App Store and Google Play and a browser app for a larger workspace. Calendar integrations explicitly named are Google, Apple iCloud and Microsoft Outlook, all syncing both ways, plus Fastmail and Zoho, with support for any calendar published as a link; iCloud and Outlook mailboxes can be connected so invitations become events automatically, while Gmail is waiting on Google's security review. The audience is described as two broad groups: personal and family life, and teams, groups and small businesses. Early access members can tell the team what they want directly from the app, and the roadmap includes smarter capture and more ways to share. Work Life Panda's primary value proposition is simple: every task, every calendar and every conversation in one calm place, with private on-device AI smoothing the busy parts. It does not ask you to start from an empty list - it starts with the life you already have, keeps your existing calendar connected rather than copied, and puts a chat, files, people and tracked history on every task and event so decisions stay with the things they are about. Free during early access, available across iOS, Android and the web, and private by design because its AI runs on your device, it positions itself as one evolving operating layer for the way you live and work.
The macOS Dock does very little, and you cannot personalise any of it. DockFix replaces it with a dock you control completely, adding colours, opacity, size, position, animations, custom app icons, folders, website shortcuts, presets, a file shelf, widgets and window previews. It is built for macOS users who want their Dock to feel personal while still looking and behaving like it came with the Mac, and it runs on macOS 14 or later on both Apple silicon and Intel machines. DockFix exists for one reason, as founder Gustav Lübker of AppVerge puts it: the Dock that comes with your Mac is not yours. Apple designed it to be fast and reliable and then closed it, so you cannot personalise its colour, its icons, its animations, or much of what sits inside it. DockFix was built to hand all of that back to the user. The hard part, according to the founder, is that a dock you have made your own is only worth having if it still feels like part of macOS — the magnification has to carry the right weight, a window has to fold toward the corner it came from, and an icon has to appear the instant the app does. Miss any of that and people feel it straight away, even when they could not tell you what is wrong. Customisation is the core of the product. Colours, opacity, size, position, animations and icons can all be configured to your likings, so the dock can match a wallpaper, a workflow or a mood. DockFix also supports folders, website shortcuts and presets, meaning items can be grouped, a site can be pinned to the dock, and a complete configuration can be saved and reapplied. Community presets take this further: a theme can be applied instantly with one click, and the site points to a Community Docks gallery at dockfix.app/discover where users share the setups they have built. Custom app icons let you apply your own artwork to any app on the system, including the native apps macOS will not otherwise let you touch. That means Finder, Launchpad, Safari, Mail and the rest can be redrawn to match a theme rather than being locked to Apple's originals. For anyone who cares about visual consistency across the desktop, this removes the last element that Apple's closed Dock design left unchangeable, and it works app by app rather than as an all-or-nothing switch. Widgets place useful information and quick controls directly in the dock itself. The site names media playback, the clock and shortcuts as examples, so a now-playing panel, a time display and quick actions can live in the same strip as your apps and folders, available wherever you are. Because they sit in the dock rather than in a separate window or the menu bar, they stay within reach without adding another place to look, and they are described as useful information and quick controls in one place. Window previews are billed as the most requested feature. Hovering over an app shows its open windows live, and you can jump straight to the one you want instead of cycling through them one by one. That turns the dock into a way of navigating open work rather than only launching it. The rebuild also delivered a completely new interface, designed from the ground up to be modern and intuitive, alongside a new engine. DockFix's custom dock is built to look and animate exactly like the system dock straight out of the box, with the same magnification and true liquid glass, so customisation does not come at the cost of the feel people expect from macOS. The current release is a ground-up rebuild rather than an update layered on the old app. Every part of DockFix was rebuilt: a new engine, a new interface, and a dock that looks and behaves like it came with your Mac, with every bit of customisation that existed before still present and a great deal more added. The founder notes that the team stopped adding to what they had and rebuilt the app from nothing, with no line of the old code left in place, because a rewrite is not something you can do halfway. The result is a dock that moves like Apple's and then does what Apple's will not, without any of it feeling bolted on. Performance is treated as a feature rather than an afterthought: the new version uses under one percent CPU on average, and it runs on both Apple silicon and Intel Macs running macOS 14 or later. DockFix requires no special permissions and never asks you to disable System Integrity Protection. While it runs it hides the system Dock and restores it when you quit, so nothing on the system is changed permanently. On privacy, the site states plainly that there is no tracking and no usage collection of any kind; the only data stored is your email address, kept to manage your licence and answer support requests. The outcome for users is a dock that feels personal without feeling foreign — Apple's speed and polish, but configured however you like, with the features Apple never added. Because DockFix keeps the same magnification and liquid glass appearance as the system dock, switching is not jarring; because it stays under one percent CPU on average, it is not something you have to worry about leaving running. Existing owners get the rebuilt version free, with the licence carrying over automatically and nothing to move or reactivate, so upgrading carries no risk, no extra cost and no configuration work. In practice, DockFix suits a range of everyday workflows. A user who wants a dock that matches a wallpaper or a desktop theme can set colours, opacity, size and position, then apply a community preset in one click rather than rebuilding the look by hand. Someone working with many open windows can hover over an app, see those windows live and jump straight to the one they need. Anyone who keeps media playing can leave playback controls and the clock in the dock itself. Users who dislike Apple's default icons can apply their own artwork to the native apps macOS usually locks down, and people who keep files or links close at hand can use the file shelf, folders and website shortcuts. Students get 30% off, and anyone with an older licence simply updates to the new version at no cost. DockFix is aimed at macOS users on macOS 14 or later, on Apple silicon and Intel machines, who want to personalise the Dock beyond what Apple allows. It is a paid desktop app priced at €14.99, paid once and used forever, with no subscription. Every purchase comes with a seven-day free trial with every feature unlocked and no card required, and settings carry over if you buy during or after the trial. There is a 30% discount for enrolled students. Support is available through the support page and a Discord server, where the site says most questions are answered within a day, and a lost licence key can be recovered from inside the app. The new version is free for anyone who already owns DockFix. Taken together, DockFix is a macOS Dock replacement built around one idea: the dock that ships with your Mac is not yours, and it should be. By rebuilding the app from nothing — new engine, new interface — AppVerge delivered a dock that looks and animates like Apple's, keeps the magnification and liquid glass feel intact, and then adds everything Apple's Dock will not do: window previews, widgets, custom icons, folders, presets and the file shelf. For €14.99 once, with a free seven-day trial and a free upgrade for existing owners, it offers a fully customisable dock that stays light, safe and private.
Captain Kill Switch is a free utility for macOS, Windows, and Linux that lives as a quiet menu-bar or system-tray button. Its purpose is simple and focused: close every running app the instant you need a clean slate. It is for anyone who wants to reset their desktop without manually quitting applications one by one—whether before a presentation, a screen-share, a game, or just to clear their head. The product runs 100% locally, requires no account, and is described as private and cross-platform. It is built to do one thing extremely well, with no bloat, no dashboards, and no upsell. Instead of a complex interface, it offers one calm, decisive click. Modern desktops get cluttered. Multiple apps, windows, and background processes accumulate, and closing them manually takes time and attention. The traditional methods—Alt-Tab, Cmd-Q, clicking each dock icon—can be slow and distracting, especially when you are about to present, share your screen, or start a game. Captain Kill Switch addresses this by replacing the multi-step cleanup with a single action. Instead of hunting through open windows, you click one button or press one hotkey, and every open application closes. The product is designed for the moment you need a fresh start immediately, not after a slow shutdown routine. It solves the problem of chaos on the desktop by making the reset instantaneous. The core feature is instant, one-click reset. When you click the menu-bar icon, every open application closes in milliseconds. This is positioned as perfect before a presentation, a screen-share, a game, or simply to clear your head. A second key feature is the global hotkey. You can bind a keyboard shortcut and fire it from anywhere, so you do not need to find the menu bar first. The website calls this your panic button, always one keystroke away. To set it, you open the menu-bar icon, go to Preferences, then Shortcut, and press the key combination you want. The recommendation is to pick something deliberate so you never trigger it by accident. Together, these two features mean the cleanup action is always accessible and takes only a moment. Captain Kill Switch lives in your menu bar or system tray. It is a discreet tray icon, nothing more. The product uses minimal memory, creates no dock clutter, and has no background CPU usage. You can forget it is there until you need it. It also requires zero configuration. You install it, and it just works. There is no setup wizard, no permissions maze, and no manual. The entire interface is a quiet tray icon and a single button. This minimalist approach keeps the utility out of your way while still being immediately available. It is designed to do one thing extremely well without adding bloat, dashboards, or upsells. The app includes smart detection that closes your applications while leaving critical system processes untouched. This protects what matters, so your Mac or PC stays stable rather than becoming stranded. It also is truly cross-platform, offering the same calm, single-button experience on macOS, Windows, and Linux. You learn it once and can use it on every machine you own. This consistency means the product fits into mixed-device environments without requiring different habits or relearning. The cross-platform nature is a core selling point: the same button, the same behavior, across all supported operating systems. The workflow is described in three steps. Step one is install and forget: download for your OS and open it once. Captain Kill Switch tucks itself into your menu bar or system tray automatically. Step two is hit the button: when you need a fresh start, click the tray icon or press your global hotkey. One action is the whole interface. Step three is clean slate: every app closes at once, leaving you a quiet, empty desktop ready for whatever is next. You can repeat the process whenever the chaos returns. This methodology relies on a single-purpose utility that waits in the background and acts only when triggered. There is no complex configuration or ongoing management. The benefits are speed, simplicity, and stability. You get a clean desktop almost instantly, without the Alt-Tab or Cmd-Q marathon. Because each app is asked to quit properly first, your next launch is clean with no crash-recovery prompts—though anything still open a couple of seconds later is force-closed, unsaved work included, so you should save what matters before firing. The app stays private: it runs 100% locally, never phones home, requires no account, and has no ads. Anonymous usage statistics and crash reports help improve the product, but events carry only a random install ID, never your name or information about the apps, files, or windows on your machine. Nothing is sold or shared. On macOS, builds are signed with an Apple Developer ID and notarised by Apple, so the app opens with a normal double-click and no security warnings. On Windows, SmartScreen may show a warning because the app has not been widely downloaded yet; you can click More info, then Run anyway. The app is tiny and runs locally. Several concrete scenarios are highlighted. Before a presentation, one click removes every open app so your audience sees a clean desktop. Before a screen-share, the same action prevents distracting windows from appearing. Before a game, it clears the desktop so you can start fresh. When you simply need to clear your head, it creates a quiet, empty workspace in milliseconds. It is also useful whenever the chaos returns and you need to repeat the reset, or when you are moving from one task to another and want a clean slate. The product is ready whenever you are, and installs in under a minute. You can forget about it until the moment you need it most. Captain Kill Switch is for users of macOS, Windows, and Linux who want a fast, private, one-button way to close all apps. It is available as a free download for all three platforms. On Windows 10/11, the latest version is v0.4.4, with an EXE installer recommended, plus an MSI installer, winget, and Scoop options. On macOS 10.15+, the same version offers a DMG package recommended, a PKG installer, and Homebrew formulas for the app and CLI. On Linux (Ubuntu, Debian, Arch), there is a DEB package recommended, an APT repository, and a terminal CLI install script. The latest release v0.4.4 covers macOS, Windows, and Linux and was released August 28, 2026. Pricing is free forever, with no account and no ads. Uninstalling is straightforward: quit it from the menu bar, then drag the app to the Trash on macOS, uninstall from Apps & Features on Windows, or remove the package on Linux. It leaves nothing lingering behind. In short, Captain Kill Switch is a focused, free, cross-platform utility that puts one button between you and a clean slate. It closes every running app on demand, protects critical system processes, respects your privacy, and stays out of your way until the moment you need it most. If you value a calm, decisive reset without dashboards, upsells, or manual app quitting, this product is designed exactly for that purpose.
FrameSketch is a video annotation tool that lets you sketch right on top of your footage. It is built for animators, VFX artists, and motion designers who need to mark up arcs, poses, and breakdowns on moving images instead of describing them in words. You step through frames, draw over the canvas, and keep your lines exactly where you left them, then hand the result to whoever needs to see the shot. The site states the intent plainly: no uploads, no lag, just your lines exactly where you left them. FrameSketch runs in the browser at app.framesketch.xyz and is free to use. The problem the product addresses is the friction of reviewing and annotating motion. The site describes the alternative as animation-suite bloat: heavy software where you open a file, fight plugins, and juggle exports before you can get back to the shot. It also promises there is no export roulette and no timeline lag, which are the usual complaints when scrubbing footage and drawing over it in a general-purpose tool. The other half of the problem is privacy and waiting. Cloud-based annotation means uploading footage before anyone can mark it up; FrameSketch instead keeps everything on your machine, so your footage never leaves your device and cloud sync, when enabled, only carries annotations. For studios handling unreleased client work, that distinction matters. The drawing tools are organised around frame accuracy. Lines land on the exact frame, and you can step forward, step back, or scrub while the canvas never drifts from the video, so a mark you place on a frame stays on that frame. Onion skin lets you peek at the frames before and after and tune the ghosting until it feels right, which is how animators check spacing, timing, and the read of a pose. Strokes stay put: each line is fixed the moment you lift the pen, so your marks stay exactly as drawn, frame after frame, without re-tracing as you move through the timeline. The brush setup is described as four pens and one palette, and the tool strip lists pressure-sensitive input. The page also shows a scrubber running from frame 0000 to frame 0144 as an example of stepping through a section of footage. The studio adds the tools a shot review normally needs, built in rather than bolted on. A frame-by-frame timeline lets you walk the footage frame by frame, mark a stretch of it, and play just that range on a loop, which is useful when a single cycle or transition needs repeated scrutiny. Layers let you stack strokes, shapes, and notes on real layers, then reorder them, hide them, and dial in each layer's opacity, which keeps a busy annotation from turning into one inseparable mess. Notes and comments appear as sticky notes and comment markers pinned right on the frame; you can move, resize, recolor, and edit them at any time, so feedback stays attached to the exact moment it refers to. Alignment and navigation tools help you place marks precisely. Grid, rulers, and guides offer rectangular or isometric grids drawn as dots or lines, and you can drag guides out of the rulers to line your marks up where you need them. Pan and zoom let you zoom into the detail and move around the shot while your marks stay exactly where you left them. Scenes and backgrounds support one project with many scenes, and every scene sits on a solid background layer, so you can hide or dim the video whenever you want to see your own drawn lines without the footage competing for attention. The welcome screen rounds this out with recent projects one click away, described as an escape from project browser rabbit holes. Underneath, FrameSketch takes a local-first approach. It runs entirely on your machine; cloud sync is optional and, when switched on, only carries annotations rather than media, and you can turn it off so everything stays local. Projects are saved as a single small .fsk file that holds every stroke; the site says a whole project is a few hundred kilobytes, small enough to email, stash, or version. Because the file is that light, sharing a review does not mean exporting video or uploading anything: you send the .fsk, the other person opens it, and they can keep going. The app reads video files straight from your machine and re-encodes nothing. The file picker only lists what your platform can really play: MP4 with H.264 in an MP4 container is recommended and plays on every platform, browser and desktop; MOV is a QuickTime container whose H.264 content plays everywhere; M4V shares the same H.264 core as MP4; and WebM uses the open VP8/VP9 codec, playing on Windows, Linux, and Chromium, though on macOS MP4 or MOV is advised. Anything else can be converted once to H.264 MP4 and it will play anywhere. The product is described as working in the browser with web and PWA support, and desktop apps for Windows and Linux are coming soon. The practical benefits follow from those choices. Privacy is the headline: your footage never uploads, so confidential or unreleased material stays on your own device while you still get optional sync for annotations. Speed is the second: drawing at 60fps and a frame-accurate canvas that never drifts means marking up a shot feels immediate rather than waiting on a round trip to a server. Small project files make collaboration cheap, since emailing a few hundred kilobytes and versioning it like any other small asset is far easier than moving video around. And because the tool deliberately avoids suite-level complexity, time to first mark is short; the site claims your first arc takes about ten seconds. Concrete workflows the tool is built around include animating arcs and poses over reference footage: load a shot, step to a frame, and draw the arc, breakdown, or pose directly on the picture. Shot review is another: pin sticky notes and comment markers to specific frames, then send the project to a colleague or director who can open it and add to it. Timing and spacing checks lean on onion skin, letting you compare neighbouring frames with adjustable ghosting to judge how a movement reads. Aligning marks to a layout uses the grids and rulers, whether rectangular or isometric. Privacy-sensitive work benefits from the local-first model, since client footage never needs to be uploaded. And because a project travels as one .fsk file, remote collaboration is as simple as emailing an attachment and continuing where the other person left off. FrameSketch is aimed at animators, VFX artists, and motion designers, the people who think about motion frame by frame, and its marketing addresses animators directly. It is available as a web app and installable as a PWA at app.framesketch.xyz, with desktop apps for Windows and Linux listed as coming soon. Pricing is free to use, and the site reiterates that your footage never leaves your device. No plugins or additional software are needed for the core workflow, and the tool opens straight from the browser ready for you to draw. FrameSketch's value proposition is narrow and deliberate: annotate video the way animators actually think, frame by frame, on top of the footage, without uploading anything. Drop in a local file, draw arcs, breakdowns, and notes with tools like onion skin and frame-accurate stepping, share a tiny .fsk file with collaborators, and keep your footage private the entire time. It is a free, browser-based video annotation tool for animators, VFX artists, and motion designers who want to mark up motion quickly and get back to the shot.

LinkFlick is a macOS menu bar app that switches your Magic Mouse, Magic Keyboard, and Magic Trackpad between any Macs on your local network. Its purpose is simple: hand off Apple's Magic peripherals from one Mac to another in a single gesture, with no cables, no dongles, no iCloud, and no re-pairing. You install LinkFlick on each Mac you want to move devices between, and it waits quietly in the menu bar until you need it. The app is built for people who work across more than one Mac — a laptop and a desktop, a personal machine and a work machine — and who want their keyboard, mouse, and trackpad to follow them to whichever screen they are working on rather than staying stuck on the Mac that last claimed them. The problem LinkFlick addresses is the friction of shared Apple peripherals. Magic devices can only talk to one Mac at a time, so anyone moving between machines has to go through the Bluetooth pairing process again and again: unpair here, discover there, confirm, and repeat on the way back. The launch notes describe exactly this frustration — re-pairing a Magic Keyboard and Magic Mouse every time the maker moved between a personal MacBook and a work MacBook. Because those two machines used different Apple IDs, Universal Control was never going to be an option. LinkFlick takes a different route: it works at the Bluetooth and local network level instead of depending on Apple's ecosystem features, so it does not care which Apple ID is signed in, whether the Macs belong to the same person, or how the two machines are configured. The goal is to remove the digging through menus that makes peripheral sharing painful. Switching is deliberately minimal. LinkFlick lives in your menu bar and presents your Macs as a cluster of trusted peers that are instantly available for a switch. A single click — or a customizable hotkey, or a spoken command to Siri to flick devices — moves the keyboard, mouse, and trackpad to the other Mac in one gesture. There are no cables and no dongles involved; it is a hand-off of your controls between machines. Because the control is explicit and lives in the menu bar rather than following the cursor across screens, you do not have to worry about your pointer drifting off the edge of the screen by accident. As the site puts it, everything is there and you simply continue exactly where you left off. LinkFlick's key technical idea is that it moves the physical hardware, not just the cursor. Instead of bridging an input stream across the network, it re-pairs the peripherals at the Bluetooth layer, so the destination Mac sees a real Magic device — a genuine Magic Keyboard, Magic Mouse, or Magic Trackpad — rather than a forwarded or emulated input signal. The site describes this as native by design, with no iCloud dependency, no network relays, and no limits. LinkFlick supports 1st and 2nd generation Magic hardware, covering keyboard, mouse, and trackpad. The app intentionally supports Apple's Magic peripherals only, and the FAQ explains why: these devices enter Bluetooth discovery mode automatically after unpairing, which allows LinkFlick to perform a silent re-pair on the other Mac without PIN codes or confirmation dialogs. The site explicitly notes that third-party devices from Logitech, Razer, and similar brands are not currently supported. Because LinkFlick operates at the Bluetooth and local network level, it has no dependency on iCloud or Apple ID. You can move a Magic Mouse between a personal MacBook and a work Mac Studio signed into different accounts without any configuration. Macs are discovered automatically: LinkFlick uses Bonjour to find your Macs on the local subnet, with no cloud servers involved, and both Wi-Fi and Ethernet work as long as all Macs are on the same network. The app also keeps an eye on your peripherals. It displays battery levels, and the launch post notes that it nags you before your Magic Mouse battery dies. Alongside that, LinkFlick senses power and display status: the moment you connect power or a display, it wakes up, checks where your devices need to be, and offers a gentle nudge that your Magic Keyboard, Mouse, and Trackpad are still on another Mac. Putting it together, LinkFlick forms a cluster of trusted Macs. You install the app on every Mac you want to transfer devices between; it runs as a lightweight menu bar extra that uses almost no resources when idle. When you switch, the app hands off each device silently in the background — no pairing screens, no interruption — typically in 5 to 15 seconds, depending on how quickly macOS processes the Bluetooth pairing request internally. Before any of that, it needs two permissions: Bluetooth access to re-pair devices, and Local Network access to discover other Macs via Bonjour. It does not require administrator privileges, does not read keyboard input, and keeps all communication within your home or office network — nothing is sent to the cloud. If the destination Mac is off or asleep, your devices simply stay connected to the current Mac, and the other machine reappears in the Flick List as soon as it wakes and LinkFlick reconnects. The outcome is continuity. Your workflow follows you between machines: you open your editor on the other Mac, pick up your mouse, and carry on right where you left off, without touching a Bluetooth settings pane. Devices arrive waiting rather than requiring you to go find them. Switching happens in the background while you are already turning to face the other screen, and if a transfer cannot happen because the target Mac is unavailable, nothing breaks — your devices stay where they are and the opportunity to move them returns on its own. With no cloud, no account, and no admin rights required, the setup is also private and lightweight by construction: your input devices and your data never leave the local network that your Macs already share. Concrete scenarios are easy to picture. A developer plugs their MacBook into a desk setup with an external display; the moment power and display connect, LinkFlick notices and offers to bring the Magic Keyboard, Mouse, and Trackpad back from the desktop Mac. Someone who splits their day between a personal MacBook and a work Mac with a different Apple ID uses a hotkey or a Siri command to flick devices over and back as meetings and tasks demand. A home user with a laptop and a desktop moves their Magic Mouse and Keyboard between the two without re-pairing either time. Power users with a full multi-Mac setup — up to five Macs on the Pro plan — keep one set of peripherals useful across every machine on the same network. LinkFlick is aimed at Mac users who own more than one Mac and at least one Magic peripheral: people working across laptop and desktop, individuals bridging personal and work machines, and power users running a full multi-Mac arrangement. The app requires macOS 14 Sonoma or later, and all Macs must be on the same local network. Pricing is a one-time purchase with no subscriptions: the Personal plan costs $14.99 and covers up to 3 Macs, described as perfect for working between a laptop and a desktop at home, while the Pro plan costs $19.99 and covers up to 5 Macs for power users and full multi-Mac setups. Both plans include auto device discovery, instant switching, battery level display, trusted peers, free updates, and no cloud or account requirement. A 14-day free trial is available with no credit card required; on the trial you can connect up to 3 Macs — your local Mac plus 2 trusted peers. LinkFlick's core value proposition is straightforward: stop re-pairing your Magic Keyboard, Mouse, and Trackpad every time you change Macs. By moving devices at the Bluetooth layer, discovering Macs over Bonjour on the local network, and keeping the whole experience inside a menu bar app with a hotkey or a Siri command, it turns a tedious pairing ritual into a one-click hand-off — no iCloud, no Apple ID dependency, no cloud servers, and no admin privileges, just your Magic devices following you between the Macs you already trust.
Coldline AI, also styled ColdLine.ai, is an AI-powered outreach tool that turns cold prospects into hot leads with personalized pitches. As described in its Product Hunt listing, users simply add their prospect's details and Coldline AI creates a relevant, human-sounding pitch in seconds. Its stated purpose is to help users save time, personalize outreach, and get more replies without writing every message from scratch. It is presented as a fit for founders, sales teams, marketers, recruiters, and agencies, and its official website summarizes the brand's positioning with the headline "Innovate with AI Today." Cold outreach is a numbers game, but the numbers only work when messages feel like they were written for the individual receiving them. The tension Coldline AI is built around is the trade-off between personalization and time: crafting a tailored pitch for every prospect means writing every message from scratch, which scales poorly for anyone reaching out to more than a handful of people. At the same time, outreach that is not personalized tends not to earn replies, and recipients can generally tell when a message is a template with a name dropped in. Coldline AI addresses this tension by automating the pitch-writing step while keeping the output relevant and human-sounding, so personalization no longer has to be sacrificed in the name of speed. The result the product aims for is outreach that is both fast to produce and specific enough to deserve an answer. The core capability described for Coldline AI is AI-powered personalized pitch generation. Instead of starting from a blank page, the user provides details about their prospect, and the product uses that information to produce a pitch that is relevant to that specific person. This is the mechanism behind the promise of turning cold prospects into hot leads: the message is built around the prospect's details rather than being a generic template that could be sent to anyone. The pitch is also described as human-sounding, so the personalization is not just factual but tonal. For anyone who sends outreach regularly, this means the personal touch that normally requires research and careful drafting becomes part of an automated step rather than a manual chore. Speed is an explicit part of the product's value proposition: Coldline AI creates the pitch in seconds. The immediate benefit is that a task which would otherwise take minutes of drafting — and much longer when multiplied across an entire prospect list — is compressed into a moment. Seconds matter in outreach because the real constraint is usually not the quality of a single message but the number of messages a person or team is able to send. When each pitch is produced in seconds, users can work through more of their prospect list without giving up the personalization that makes outreach worth sending. The speed also lowers the friction of starting: there is no blank page to fill, only details to add. The content emphasizes that the generated pitch is relevant and human-sounding. Relevance ties the message to the prospect's details, while the human-sounding quality addresses the risk that automatically written outreach reads as stiff or obviously machine-generated — a tone recipients tend to ignore or delete. The stated outcome is more replies, which means the pitch is written to be something a prospect will actually respond to rather than something that merely fills a message field. Combined with the promise of not writing from scratch, this positions Coldline AI as a way to produce outreach that feels personal without hand-crafting every sentence. For users, that distinction matters because a pitch that sounds human is more likely to be read to the end and answered. The overall workflow described by Coldline AI is deliberately simple. The user adds their prospect's details, and the product generates the pitch from that input. There is no described requirement to build templates in advance or to write a draft for the tool to edit — the pitch is created for the user from the details they provide. This input-then-generate approach is what makes the tool usable by people who are not professional copywriters, including founders, recruiters, and agency teams for whom outreach is one part of a much larger job. The methodology is essentially to let AI handle the composition while the human focuses on choosing who to contact, sending the message, and following up on the replies that come back. The benefits stated for Coldline AI are saving time, personalizing outreach, and getting more replies. These three are connected: time saved comes from not writing every message from scratch, personalization comes from generating a pitch around each prospect's details, and more replies are the expected result of outreach that is both relevant and human-sounding. For an individual, the benefit is fewer hours spent drafting and less fatigue from staring at empty message boxes. For a team, the benefit compounds, because every member can produce personalized outreach at a pace that previously would have required generic templates. The product frames these outcomes as the reason to change how outreach is written. Coldline AI is presented as suitable for a range of outreach scenarios. Founders can use it to reach prospective customers, partners, or investors without blocking out hours for writing, since each pitch is generated from the details they add for that person. Sales teams can use it to personalize cold outreach across a pipeline, producing a relevant pitch for each prospect they enter instead of choosing between volume and relevance. Marketers and agencies can use it for outbound campaigns and client prospecting, where personalization at the individual level is what separates a campaign from spam. Recruiters can use it to reach candidates with messages tailored to the person, rather than sending the same note to everyone. In each case the described workflow is the same: add the prospect's details, generate a relevant pitch, and send it. The explicit target audiences for Coldline AI are founders, sales teams, marketers, recruiters, and agencies — essentially anyone whose work involves reaching out to people they do not yet know. These are people who send outreach regularly and need it to feel personal in order to get replies, but who do not want to write every message from scratch. The Product Hunt listing also categorizes the product under Sales, Marketing, and Artificial Intelligence, which reflects that dual identity of an AI tool applied to a go-to-market function. Coldline AI is accessed through its official website at coldlineai.xyz, making it a web-based product, and it is listed on Product Hunt as "Coldlineai" with the tagline "Turn cold prospects into hot leads with AI-powered pitches." No pricing details are stated in the available content. In short, Coldline AI takes the most time-consuming part of cold outreach — writing a personalized pitch for every prospect — and turns it into a seconds-long automated step. By taking prospect details as input and producing a relevant, human-sounding pitch, it aims to let founders, sales teams, marketers, recruiters, and agencies save time, personalize their outreach, and get more replies without writing every message from scratch. That combination of personalization and speed is the core value proposition the product states.

Wisry is an agentic ad platform for ecommerce brands that turns an existing store into a source of high-ROAS campaigns. Described as an Agentic AdClone for ecommerce, it uses AI agents that analyze winning ads and generate high ROAS campaigns. The workflow begins when you paste your store URL: Wisry builds brand memory covering your products, voice, visual identity, and audience so that every agent stays on-brand. It then researches the ads already working in your market, generates evidence-backed campaign angles, generates video and static ads cloned from the best performing creative, and ships them to Meta and Google. It is built for ecommerce brands and agencies that want to launch high-ROAS ads roughly ten times faster, with research, creative, and launch handled end to end in minutes rather than weeks. The problem Wisry addresses is the guesswork behind ecommerce advertising. Advertisers typically start from a blank canvas, invent angles, produce creative, and then wait to see what converts, which is an expensive and slow loop. Wisry starts from a different premise: winning ads already exist in the market. Its research agent reads the Meta ad library and TikTok top ads, deep-analyzes competitor ads and content, and identifies what is already converting. Instead of briefs built on assumptions, campaigns begin from ads with a live track record. In the studio's ad library view, ads are ranked to clone, for example one ad shown at 64 days live with 17 variants and 2.4M impressions, another at 35 days live with 10 variants and 1.1M impressions, and a third at 23 days live with 6 variants and 740K impressions, drawn from a set of 1,323 reviewed. That ranking makes the market's proven patterns visible before any budget is spent, which matters because in categories such as supplements the window for a trend closes quickly, and teams that spot and replicate what is winning first gain the advantage. Agentic ad research is one of Wisry's two flagship features. Research agents read the ads already running in your market, cite what they found, and turn the winners into angles you can brief. This is not a list of raw ads: the strategist agent converts research into campaign concepts covering audience, hooks, and messages, and provides source citations behind every angle. Evidence-backed angles mean the reasoning behind a campaign is traceable back to a real, running ad rather than to opinion. In practice, an ecommerce team can see which concept has survived the longest, which format has survived a full test cycle, and which has the fastest variant ramp in the category, and then brief creative against those findings. Wisry's second flagship feature is video ad cloning. You point Wisry at a video ad that works and get your own version of it, with the same structure and pacing but your product and your brand; the structure matched includes the hook, proof, and close. Static ad cloning works on the same principle: Wisry rebuilds a winning static in your palette, with your type and your product shots, then fans it out into every placement you need. What is kept and what is swapped is explicit: layout, headline structure, and type are retained from the source, while the palette and product are swapped for yours. This lets a brand reuse a proven creative formula without copying a competitor's product or visual identity. The studio also includes ad templates and video editing. Templates let you start from formats with a track record instead of a blank canvas, and every template arrives sized and safe-area-checked for its placement. Formats shown include listicle, problem-solution, quiz, portrait, us-versus-them, seasonal, feature-benefit, and how-to, sized for Feed 1:1, Feed 4:5, Portrait 2:3, Landscape 16:9, Reels 9:16, and Story 9:16, so the same idea can be produced across the placements a campaign actually needs. Video editing means every generated cut opens in a real editor where you can retime scenes, restyle captions, swap a shot, and re-render without leaving Wisry. Together these capabilities keep generated creative editable and controllable rather than locked, so teams can fine-tune an asset before it ships. Wisry works as a five-step loop handled end to end by agents. Step one: Wisry pulls your brand and products, so you paste your store URL and it builds brand memory covering products, voice, visual identity, and audience, keeping every agent on-brand. Step two: it studies your market's winning ads, with a research agent deep-analyzing your Meta and TikTok competitors' ads and content to find what is already converting. Step three: it generates evidence-backed angles for your campaigns, turning research into campaign concepts covering audience, hooks, and messages, with source citations behind every angle. Step four: it copies winning creatives for your products, generating video and static ads from the best performing ads and your chosen angles. Step five: the ads agent launches, optimizes, and repeats 24/7, shipping your ads to Meta and Google, watching performance, moving budget to winners, and keeping new creatives coming. The studio ships nine capabilities in total, all pointed at selling more of your products, with research and cloning described as the two flagship capabilities and the rest downstream of them. The stated outcomes are speed and performance. Wisry reports a +200% average boost in ad performance, says its strategist was trained on over $1B in ad spend, and claims it is 10x faster to launch a high-ROAS campaign with AI, with research, creative, and launch handled end to end in minutes rather than weeks. The intended benefit is that advertisers stop testing blindly and start scaling what is proven. In testimonials, a seller of a hardware product to Tesla owners, a niche audience where every ad dollar counts, says Wisry took what was already working in the account and multiplied it, with ROAS up 300%. A supplements advertiser says the value is spotting what is winning and replicating it before the window closes, shipping winning variations twice as fast. An agency says the bottleneck of research and iteration was removed, letting it scale client accounts much faster than a manual team could. Concrete scenarios follow from the workflow. An ecommerce brand pastes its store URL, lets Wisry build brand memory, and receives campaign angles plus cloned static and video ads ready to launch on Meta and Google. A growth team watching the ad library ranking picks a proven concept, such as a long-running contrarian concept with many live variants, and clones its structure into its own product. A creative team takes a generated cut into the editor to retime scenes, restyle captions, or swap a shot, then re-renders and ships. A media buyer uses the ads agent to keep optimizing, watching performance, moving budget to winners, and continuously receiving new creatives. An agency runs the same research and cloning loop for multiple client accounts, turning market research into output at a pace the testimonial describes as beyond what a team could touch manually. Brands in trend-driven categories such as supplements use it to react to what is winning while the window is open. Wisry is aimed at ecommerce brands and the agencies and media buyers serving them, particularly teams that want to scale paid social and search without adding research and creative headcount. Its agents are orchestrated using leading models: Grok, Gemini, OpenAI, Claude, KlingAI, and Nano Banana. The product is web-based, and the connections described in the content cover the Meta and TikTok ad libraries for research and Meta and Google for ad delivery. Pricing is a paid, prepaid subscription: 2 weeks at $49.50, 4 weeks at $99 marked Most Popular and offered at $49.50 with a 50% saving, and 8 weeks at $198 offered at $89.10 with a 55% saving. The checkout note states one payment of $49.50 for 4 weeks, then $99 per month, cancel anytime, secured by Stripe, and plans are described as costing less per day the longer you commit. Wisry was featured on Product Hunt with 308 votes and 49 comments. Wisry's proposition is straightforward: your store in, winning ads out. By turning the public ad libraries of Meta and TikTok into a ranked source of proven creative, rebuilding that creative for your brand as static and video ads, and then launching, optimizing, and repeating around the clock on Meta and Google, Wisry compresses ecommerce ad research, production, and optimization into minutes. For ecommerce brands and agencies that want high-ROAS campaigns without the guesswork, it positions the market's already-winning ads as the starting point rather than a blank canvas.
Devin Voice is the voice mode built into Devin, Cognition's AI software engineer. It lets you talk naturally with Devin to explore ideas, pressure-test an approach, and hand off work while you are away from your keyboard. Rather than typing every instruction, you start a voice call, speak your thoughts out loud, and let the conversation move at the speed of speech. Any message you have already typed is sent when you start the call, so you can move directly from a written prompt into a spoken discussion inside the same session. The Product Hunt listing describes the same idea more bluntly: you say it, Devin ships it, and you speak a task out loud while Devin plans, codes, and delivers. The capability is aimed at people who already work with Devin in Agent mode or in an existing session and want a conversational way to think through problems, ask questions, and keep work moving. Software work has long been keyboard-centric: you type a prompt, wait for a response, read it, and type again. Voice mode changes that rhythm by making the spoken conversation itself the interface between you and the agent. The documentation frames voice mode around three activities: exploring ideas, pressure-testing an approach, and handing off work while you are away from your keyboard. The stated tips reinforce how this is meant to feel in practice. You should not be afraid to interrupt Devin's work, and you should ask questions and clarify your thoughts as you have them. You are also free to interrupt Devin while it is talking. Together, those instructions describe a working style where clarification is welcome at any moment rather than something you have to schedule between long silences, and where getting your thinking out loud is part of the process rather than a disruption to it. Getting into voice mode is deliberately simple. On the home page in Agent mode, or inside an existing session, you click the voice call button that sits beside the message box and then allow microphone access. Hovering over the waveform icon shows a "Start voice call" tooltip, so the control is discoverable before you commit to a call. One detail worth noting: any message you have already typed is sent when you start the call. That means a half-written prompt or a queued instruction is not lost; it is delivered as the call begins, so your spoken conversation continues from the written context you had already built up. Starting from either the home page or an in-progress session means you can begin a call at the moment an idea strikes rather than having to set up something new first. Once a call is running, the documentation lists a small, clear set of controls. Mute microphone pauses your microphone, and clicking Unmute microphone lets you speak again. If you are muted but still want to say something without leaving the call, you can hold Space to talk while muted when you are not typing. Silence Devin turns off Devin's audio without muting your own microphone, and clicking Unsilence Devin brings the audio back. End voice call hangs up. These controls separate the two directions of the conversation, your input and Devin's output, so you can mute yourself while listening to a long explanation, or silence Devin's audio while keeping your own microphone live and ready to respond. Voice mode is not a separate, isolated room. You can navigate within Devin while the call stays connected, so you can move around the product without dropping the conversation. Your conversation appears in the session history, which means the spoken exchange becomes part of the recorded session rather than disappearing when you hang up. The documentation also notes that you can shape how Devin speaks: if you have preferences for how Devin should speak, for example to speak faster or slower, or a particular communication style, you can simply ask. There is no described settings panel for this; the adjustment happens through the conversation itself, which keeps the interaction consistent with the rest of the voice experience. Under the hood, the Product Hunt listing states that Devin Voice is powered by GPT-Live for natural conversation, with Cognition's new SWE-2 coding model under the hood. That combination is what the listing describes as letting Devin plan, code, and deliver after you speak a task out loud. Devin Voice connects you to Devin, described in the listing as Cognition's AI software engineer. On the documentation side, the overall description of how the feature works is straightforward: you talk naturally with Devin, in Agent mode or in an existing session, and the conversation is tied into the same session context, appearing in session history and continuing even as you navigate within Devin. The documentation also carries a standard note that responses are generated using AI and may contain mistakes. The benefits follow directly from those mechanics. Voice mode lets you explore ideas out loud instead of composing them in a text box, which the documentation positions as a way to pressure-test an approach. It lets you hand off work while you are away from your keyboard, so time spent away from a desk does not have to mean the work stops. Because you can interrupt Devin's work and ask questions as they occur to you, clarifications do not have to wait for a complete response, and because you can interrupt Devin while it is talking, you are not locked into listening to everything before you can steer the conversation. And because you can ask Devin to speak faster, slower, or in a different communication style, the spoken interaction can be tuned to your preferences. Concrete use cases flow from the documented behaviour. You might start a call on the home page in Agent mode, with a task already typed into the message box, and have that message sent as the call begins so you can talk through the task instead of typing more. You might be inside an existing session and open a voice call there to hand off work while you step away from your keyboard. You might keep the call connected while navigating within Devin, moving around the product without breaking the conversation. You might mute your microphone while Devin talks, or hold Space to talk while muted when you are not typing. You might silence Devin's audio without muting your own microphone so you can think or speak without the audio running. And afterwards, you can revisit the conversation in the session history. In terms of audience and context, the documentation is written for people using Devin itself, referring to the home page in Agent mode and to existing sessions, and describing the voice call button beside the message box. Product Hunt lists Devin Voice under Productivity, Developer Tools, and Artificial Intelligence, and the listing points readers to devin.ai to try Devin. The named technologies associated with the product are GPT-Live for natural conversation and Cognition's SWE-2 coding model under the hood. The documentation page does not describe pricing, plans, or platform availability beyond the described interface, and the listing does not state pricing either. The takeaway is straightforward: Devin Voice turns talking to Devin into a first-class way of working. You say it, and Devin ships it. By letting you start a call from the message box in Agent mode or an existing session, carry a typed message into the call, mute or silence either side of the conversation, keep working while Devin navigates alongside you, and simply ask for the speech style you prefer, voice mode makes it possible to explore ideas, pressure-test an approach, and hand off work away from your keyboard, with the conversation preserved in the session history.

TIM PG is a privacy guard utility that wraps intelligent data protection and security around the everyday use of artificial intelligence. It is built for people and teams who want to take advantage of large language models and other AI tools without handing over sensitive information, and it does this by automatically masking personal data from the clipboard before that data is pasted anywhere. Alongside clipboard protection, TIM PG anonymizes documents such as PDF and Office files, and uses Smart Bubble technology to protect individual text segments locally on a PC. The product is presented as a strictly offline, 100 percent AI-free Windows utility, so protection happens on the machine itself rather than in a cloud service. AI assistants have become part of ordinary working life, and the fastest way to use them is to paste text straight into the prompt. The trouble is that the text people paste often contains personal data — the kind of sensitive detail that was never meant to leave the organization or the user's own machine. Once such content reaches a cloud-based model, it is difficult to know where it goes or who may see it. TIM PG addresses this specific moment of risk: the copy-and-paste step that happens between a user's own documents and an external AI tool. Rather than asking people to change their habits or stop using AI, it intervenes at the clipboard itself, before the sensitive data has a chance to leave the local machine. The core of TIM PG is automatic masking of personal data from the clipboard. Before a user pastes anything into an LLM, the utility masks the sensitive data inside the clipboard content, so what reaches the AI tool is a version of the text without that personal data. Once the AI produces its answer, TIM PG restores the sensitive data back into the AI's response. That round trip matters because it means the AI's output stays usable: the user still sees their own real data in the final answer, even though the model itself never received it. Both the masking and the restoration are performed locally on the PC, so the protection step does not become another place where data can leak. Beyond the clipboard, TIM PG offers document anonymization for PDF and Office files. This extends the same principle from a single copy-and-paste action to complete documents, which are typically the source of the most detailed content in a business workflow. A user who needs to work with a PDF or an Office document alongside an AI tool can anonymize that document first, so the content that travels onward carries no personal data. Because document anonymization is part of the same local utility, it keeps the whole process inside the user's existing environment rather than requiring a separate hosted service or an upload to a third party. It is the same idea as clipboard masking, applied at document scale. TIM PG also introduces Smart Bubble technology for protecting text segments. Rather than relying on a single blanket rule for everything, Smart Bubble is designed to protect text segments locally on the user's PC. For people who work with mixed material — where some parts of a document need shielding and others do not — this offers a way to apply protection at the level of individual segments instead of treating the entire piece of content as one block. Like the rest of the product, Smart Bubble operates on the local machine, so protected segments are never exposed to an external service as part of the protection process. The overall approach of TIM PG is deliberately local. It is described as a strictly offline, 100 percent AI-free Windows utility, which means it neither relies on a cloud connection nor uses AI of its own to do its work. Masking, document anonymization and the restoration of sensitive data all take place on the user's PC. This design choice is what separates the product from privacy add-ons that route content through a hosted service: there is no server in the middle, so nothing about the user's data is transmitted as part of the protection step. The utility sits between the user's clipboard or documents and the AI tool they want to use, and it does its work in that gap. The promised outcome is straightforward: no cloud, no leaked data — just secure local data privacy for everyday workflows. Users can keep using the AI tools they have already chosen while reducing the exposure of personal data. Because the masking is automatic, the protection does not depend on the user remembering to redact text by hand, and because the restoration is seamless, the final AI answer still contains the real details that make it useful. The result is that privacy stops being a trade-off against productivity: a user can copy, paste, prompt and read the response much as they normally would, with an extra layer of protection working locally in the background on their Windows machine. TIM PG is designed for the everyday scenarios in which text moves from private material into an AI tool. The most direct example is pasting clipboard content into an LLM, where TIM PG masks the personal data on the way in and restores it on the way out. A second scenario is working with PDF and Office documents that need to be anonymized before they are used with AI assistance. A third is the handling of individual text segments that require local protection through Smart Bubble technology. In each case the workflow ends the same way: the user gets the benefit of AI processing while the sensitive data stays on their own PC. TIM PG is a Windows utility, so it fits naturally into Windows-based business environments. It is presented on a website that also describes TIM, a next-generation business platform, and TIM TL, smart helper tools for daily business processes, alongside a statement that the team brings decades of development and IT security background to guarantee business stability. That positioning suggests the product is aimed at business operations and utilities users who need practical, secure tooling rather than experimental AI features. The site states that intelligent data protection and security are the goal for the safe use of artificial intelligence, and it offers a demo as well as a way to request a consultation. No pricing or plan information is stated in the available content. TIM PG's value proposition is narrow, clear and practical: it protects sensitive data at the exact moment it would otherwise be exposed — when it is pasted into an AI tool. By masking personal data from the clipboard, anonymizing PDF and Office documents, restoring protected data into the AI's response and using Smart Bubble technology to protect text segments locally, it lets people keep working with AI without sending their private information to the cloud. Strictly offline and 100 percent AI-free, TIM PG is local data privacy built for workflows that depend on AI.

Design Studio by Monday Merch is a browser-based canvas that lets anyone design custom merchandise directly onto the product they are ordering. It brings together more than 1,000 products—from Premium T-Shirts, Premium Polos, hoodies and caps to drinkware like the Sleek Bottle and Dopper Original, tote bags, mugs, pens and jackets—inside a single design environment. Instead of designing artwork in one tool and then guessing how it will look on a finished item, you place your logo, artwork or text straight onto the product, viewing it from every angle in 2D, with selected products also available in 3D. The tool is meant for anyone who needs to produce branded or custom merch, including teams, businesses and individuals, and it is free to use with no design skills needed. Traditionally, creating branded merchandise is a fragmented, error-prone process. A designer might prepare artwork in a separate graphics program, then hand it off to a printer, only to discover that the placement, size or format does not match the product's printing requirements. Colour choices, print areas and production rules often live outside the design tool, which means a design can look right on screen but fail in production. Design Studio addresses this by keeping the design and the production requirements in the same place, so what you create is grounded in the realities of the product you are ordering. It aims to reduce the back-and-forth between design and production and to make merch design accessible to people who are not professional designers. The backbone of Design Studio is its catalogue of product templates. The platform offers over 1,000 products, organised so that you can browse and start from a template. Featured examples include the Premium T-Shirt, Premium Polo, Unstructured 6 Panel Cap, Structured 5 Panel Cap, Vintage Low Profile Cap, Dad Cap, Classic Hoodie, Premium Hoodie, Classic Sweatshirt, Fleece Zipper Jacket, Columbia Men's Full Zip Fleece Jacket, Heavyweight Oversized T-Shirt, Lightweight T-Shirt, Classic T-Shirt and Premium Women's T-Shirt, alongside drinkware such as the Sleek Bottle (500 ml), the Dopper Original (450 ml) and the Ceramic Glazed Mug, plus the Stainless Camp Mug, Dual Color Shopper Tote and Contemporary Pen. Each template can be opened directly with a "Design Now" action, so you can begin placing your artwork onto a realistic product view. Products are grouped into categories such as Apparel, Bags, Drinkware, Office, Packaging, Stickers & Print, Tech and Events, making it easier to find the right blank item for a given project. Beyond product templates, Design Studio also provides a library of print templates for paper-based and printed items. These include Christmas cards such as the Merry & Mint Xmas Card and Santa Xmas Card, thank-you cards, invitation cards like the Wax Seal Invitation Card, event materials such as the Running Event Flyer, posters such as the Good Vibes Poster, the Office Values Poster and the Mental Health Awareness Poster, menu cards such as the Alcohol Menu Card, and guides like the Recipe How To Guide Flyer. Print templates make it possible to design a broader range of collateral—everything from cards and flyers to posters—inside the same environment you use to design physical merchandise, so a single brand look can be applied across apparel, drinkware and printed materials. Design Studio includes several features that streamline the design process. You can add your brand hub with a click, which lets you create designs instantly using your own brand assets, so you do not have to rebuild your logo or colours from scratch each time. You design straight on the product, with every angle available in 2D and selected products also available in 3D, which helps you understand how the finished item will look from different viewpoints. The price is shown while you design, so you can see the cost implications of your choices as you make them. Printing rules and requirements are baked into the tool, meaning the designs you create are set up to be ready for production. And you can easily share and collaborate, which supports team workflows around a design. The core approach of Design Studio is to collapse the gap between designing and producing. Rather than treating design as an abstract exercise, it treats the product as the canvas. You choose a product template, then place your logo, artwork or text straight onto the product you are ordering. Because printing rules and requirements are built in, the tool guides your design toward something that can actually be manufactured, reducing the risk of a design that looks good but cannot be printed. The combination of a large product catalogue, brand hub assets, multi-angle viewing, live pricing and sharing tools means the entire journey—from idea to a production-ready design—happens in one browser-based workspace. For users, these capabilities translate into practical benefits. Because no design skills are needed and the tool is free to use, designing custom merch becomes accessible to people without a design background. Seeing the price while you design gives you immediate feedback on budget, helping you make informed choices about products and design details. The built-in printing rules and requirements reduce the chance of production errors, and the ability to design straight onto the product gives a realistic preview rather than a guess. Sharing and collaboration features make it easier to work with teammates or stakeholders, and the option to add a brand hub with a click speeds up the creation of on-brand designs. Design Studio supports a range of concrete scenarios. A company can design branded apparel and drinkware for its team, using product templates like the Premium T-Shirt, Classic Hoodie or Ceramic Glazed Mug and applying its brand hub assets. An individual or small business can create custom merch for sale, starting from a template and placing artwork directly onto a chosen product. A team can prepare printed materials such as Christmas cards, thank-you cards, invitation cards, flyers or posters using the print templates. Event organisers can design event-related items, given the Events category and templates like the Running Event Flyer. Because designs can be shared and collaborated on, multiple stakeholders can review and refine a design before it goes to production. Design Studio is designed for anyone who needs to create custom merchandise or printed materials without deep design expertise. Its categories—Apparel, Bags, Drinkware, Office, Packaging, Stickers & Print, Tech and Events—suggest users ranging from businesses and teams producing branded goods to individuals creating personal or resale items. The tool is free to use, and it runs in the browser. The website also presents country and language options, indicating availability across regions with multiple languages. The exact tech stack and third-party integrations are not specified in the available content. In summary, Design Studio by Monday Merch turns the browser into a merch design workspace where over 1,000 products serve as the canvas. By letting you design straight onto the product, add your brand hub with a click, see the price as you work, and rely on built-in printing rules, it aims to make every design ready for production while remaining free and accessible to non-designers. With product templates, print templates, multi-angle 2D and 3D viewing, and easy sharing and collaboration, it positions itself as "Figma, but for creating real products."

chat-recall is, in its own words, Ctrl+F for every conversation you've had with an AI. Your team has done months of work with AI assistants, and a single command — npx chat-recall init — reads what those assistants already wrote down and turns it into one searchable history. The product is aimed at teams and developers who work daily with AI coding assistants and who have accumulated a large, scattered record of that work: the chats, the plans, the task lists and the notes. Rather than asking people to remember which tool holds which decision, chat-recall collects everything into one place that is searchable the moment it arrives. Critically, passwords are removed before anything leaves your computer, so the searchable history can be assembled without shipping secrets off the machine. The stated purpose is simple: make months of AI-assisted work findable, and stop teams from redoing work they already finished. The problem it addresses is fragmentation and loss of recall. Claude Code, Codex, Cursor and OpenCode each keep a full record of a team's work, in its own format, and none can read the others. The result, as the site puts it, is that none of it is searchable — until now. The headline framing is that Ctrl+F doesn't work on your brain, but chat-recall makes it work on your chat history. That matters in two directions. First, knowledge: decisions, plans and completed work live inside conversation histories nobody can search, so your assistant keeps asking what was decided last month, and people repeat work that was already done. Second, security: conversations with AI assistants are a place where credentials leak, and an API key pasted into an old chat is a live liability that nobody can audit by hand across months of history. chat-recall addresses both the recall problem and the leaked-secret problem from the same source of truth. The first capability group is unified, searchable history. chat-recall reads the record your assistants already wrote — conversations, plans, task lists and notes, across five AI coding tools — and assembles everything into one searchable history. Everything is searchable the moment it arrives, so there is no separate export or migration step to perform. Beyond manual searching, your assistant searches the history itself, which means it stops asking what you decided last month. That closes the loop: instead of a person being the only bridge between five separate chat tools, the assistant you are currently talking to can reach the shared record and pick up the context the team has already established. For a team whose decisions live in chat, this converts an unsearchable archive into a lookup. The second capability group is secret handling and leaked-key detection. Password removal happens on your own computer, before anything leaves the machine, and the system only ever sees the last few characters of a value — the site illustrates this with a masked key that keeps only its final characters visible. On top of that, chat-recall finds keys that leaked into old chats and checks which ones still work. The security view shows every key that was found, whether it still works, and how many conversations it turned up in. Each row presents a masked preview, a live-or-dead verdict, the detectors that matched, and how many sessions the key appeared in, with entries grouped by rule. Detection is based on the key formats the big services publish. If a company invented its own key format, users can tell the system the pattern and it gets checked too. Together this turns an unbounded audit problem — months of chat logs and unknown leakage — into a screen with a concrete verdict per credential. The third capability group is keeping every assistant and every machine on the same setup. The toolkit coverage matrix shows six skills down the left-hand side and a column for each AI tool on each of two computers; a filled cell means the skill is installed there, an empty ring means it is not. Each row carries a coverage count and a sync-to-all action, so a blank cell can be clicked to copy the missing add-on across. This makes consistency visible rather than assumed. A new laptop already knows everything: sign in and your whole history is right there, with nothing to copy over by hand. Every add-on you have built up follows you to whichever assistant you pick up next, so trying a new assistant does not mean starting over. Rules are set once, per project: mark a project a prototype or a live product, and every assistant that opens it plays by the right rules. And bugs turn into tasks on their own — each one shows up with the fix already sketched out, and closes itself once the problem is actually gone. The methodology behind all of this is local-first. Steps one through three — reading your conversations, removing passwords, and producing one searchable history — happen on your computer, and that history never leaves your computer. The ordering is deliberate: redaction is applied at the point of collection rather than after transmission, so the pipeline that aggregates five tools' worth of chat data does not also aggregate the secrets inside them. Your assistants then reach that local history themselves, which is what makes "your assistant searches it itself" possible without a manual export-and-import cycle between tools. The benefits follow directly from those mechanics. Teams stop redoing work they already finished, because completed work is findable. Passwords come out before anything leaves the computer, and leaked credentials are surfaced with a verdict rather than buried in old chats. People see what to fix next instead of guessing. Moving to a new computer means signing in rather than copying files by hand. Adopting an additional assistant no longer resets the accumulated add-on setup. Project rules are applied consistently across every assistant that opens a given project, and bugs become tracked tasks that close themselves once the underlying problem is actually resolved. In practice, the described workflows are concrete. A developer installs the tool with one command and gains a searchable history spanning the five AI coding tools they already use. A team opens the security view and sees each leaked key grouped by rule, with a masked preview, a live-or-dead verdict and the number of sessions it appeared in, then decides what to act on. Someone sets up a second computer, signs in, and finds the whole history already there. A developer who wants to try a different assistant carries their add-ons with them instead of rebuilding them. A project is marked a prototype or a live product so every assistant that opens it applies the right rules. A bug reported during a session arrives as a task with the fix already sketched out, and closes itself once the problem is gone. And an assistant asked about an earlier decision searches the shared history itself rather than asking the user to repeat it. On audience and integrations, the content points to teams that run multiple AI coding assistants — Claude Code, Codex, Cursor and OpenCode are named, and the diagrams consistently describe five AI coding tools and two computers. Installation is a Node command run with npx: npx chat-recall init. The product also exposes a way for the assistant to query the history directly, described on the site as "what your assistant can ask" and linked at the /mcp/ path, which indicates an MCP-based interface for assistants. No pricing, plan tiers, or supported operating systems are stated in the provided content. The takeaway is that chat-recall treats AI chat history as a first-class, searchable, shared asset while treating the secrets inside that history as something to strip before it goes anywhere. One command turns scattered records from five AI coding tools into one history your assistant can search itself; passwords come out before anything leaves your computer; leaked keys get a verdict instead of a guess. Ctrl+F doesn't work on your brain, but with chat-recall it works on your chat history.

Formesign is a tool for collecting legally binding eSignatures inside Google Forms. It adds signature fields to the forms you have already built, so the people who fill in your form can sign it directly instead of printing, signing and scanning a document. When a form is submitted, Formesign converts the responses into signed PDF files, saves an audit-ready copy to Google Drive, and syncs the submission to Google Sheets. Signed forms can also be emailed to respondents and collaborators for record-keeping. Formesign is built for compliance-focused businesses and organisations that need signatures as a normal part of a data-collection workflow, and it is used across healthcare, HR, education, events, real estate and construction. Its purpose is simple: keep the Google Forms workflow an organisation already relies on, and add a signature step to it that stands up as legally enforceable. Google Forms is great at collecting data from users, but it does not have a built-in option to collect signatures. That gap matters whenever a form is not just information gathering but an agreement: a consent form, an acknowledgement, a rental agreement or an approval request. Organisations in these situations often fall back on printing forms, asking people to sign by hand, and then scanning and storing the paper themselves, or they turn to dedicated eSignature platforms that charge far more than the workflow justifies. A customer quoted on the Formesign site describes the industry-standard signature provider as "TOO expensive" for their HIPAA-compliant Google Forms signature needs. Formesign addresses exactly that problem: it keeps the Google Forms workflow the organisation already uses, while adding a signature collection step that meets electronic signature regulations, so organisations that care about compliance do not have to leave the tools they know or pay enterprise eSignature prices. Formesign ensures that signatures collected through Google Forms are legally enforceable, meeting electronic signature regulations, so a signed Google Form can be relied on as a record of agreement rather than a loose acknowledgement. Alongside a single signer, Formesign supports collecting multiple signatures, so a document can require additional parties such as a witness or a guardian to sign as well. This lets organisations ensure that all necessary parties sign the document before the form submission is complete, rather than chasing missing signatures after the fact. For compliance-focused teams, the practical result is that the signature step is built into the same submission that captures the rest of the data, so the signed record and the submitted answers stay tied together. Google Drive integration is central to how Formesign handles documents. It automatically converts form responses into signed PDF files and syncs them to a Google Drive folder when the user submits the form, which gives the organisation a stored, audit-ready copy of every signed document without manual exports or filing. Email delivery complements this: Formesign sends customised emails with the signed PDF files to respondents and collaborators for seamless communication and record-keeping. A respondent can therefore keep their own copy of what they signed, while internal collaborators receive the same document inside the workflow that collected the signature, removing the need to forward attachments or reconcile separate copies by hand. Responses also sync automatically to Google Sheets, providing a familiar interface for organising and analysing the data that accompanies each signature, so the answers people submit alongside the signature remain usable for reporting and follow-up. The signing experience itself is designed to be seamless: users can easily sign forms on any device, including mobiles and tablets, for a convenient, secure and accessible signing experience. One customer highlights the ability to update a form without needing to regenerate the link, which means corrections can be made to a live form without invalidating links that have already been distributed to signers — particularly useful for teams that send consent, registration or application links out widely. The overall approach is to keep the form the organisation already has and add to it, rather than replace it. You add signature fields to your existing Google Form and continue to publish and share it as usual. When someone submits the form, Formesign generates a signed PDF from that submission, stores the file in Drive, emails it out to the relevant parties, and records the response in Sheets. Because the whole flow runs through Google Forms, Google Drive and Google Sheets, the process stays inside the tools the team already uses, and the signature becomes part of the submission itself rather than a separate document-handling exercise. There is also a library of blank, ready-made signature forms on the site, so teams can start from a template rather than building a signature form from scratch. The benefits follow directly from that design: legally enforceable signatures without leaving Google Forms, signed PDFs generated and filed automatically, email copies in the hands of respondents and collaborators, and response data arriving in Sheets ready to organise and analyse. The site emphasises a secure, accessible signing experience across devices, and it highlights customers moving from paper-based processes to a modern digital workflow — one customer describes their company as having moved "from the stone age to modern age" through the ability to use the feature. Another customer, working with HIPAA-compliant Google Forms, notes that they needed a way to collect signatures and that Formesign worked perfectly, and that the company worked with them to evolve the product so that a PDF copy of the form could be provided after signing. With more than 500 organisations trusting Formesign, the product is positioned for teams that need signature collection at volume and at a lower cost than dedicated eSignature platforms. The site also presents a range of ready-made signature forms, which show the kinds of concrete workflows Formesign supports: an employee handbook acknowledgement form for HR, a HIPAA privacy notice acknowledgement form for healthcare, photo release forms and catering agreements for events, a tattoo consent form for legal compliance, a rental agreement form for real estate, an equipment rental agreement and a vendor application form for business, a school application form for education, a contest entry form for events, a reference request for HR, an IT service request for IT, and a purchase request approval form for finance. Each of these is a scenario where a signature is required alongside the data a Google Form already collects, and where the signed PDF then needs to be retained and circulated to the right people. Formesign is aimed at compliance-focused businesses and organisations working in healthcare, HR, education, events, real estate, finance, IT, construction and legal-compliance contexts — the site notes that its customers span from healthcare to construction, and that more than 500 organisations trust it. It is used by organisations working with HIPAA-compliant Google Forms, and by small teams that describe themselves as not tech savvy and who use it to create registration links for clients. Because Formesign operates as an add-on to Google Forms, the integrations it relies on are Google Drive for document storage and signed PDFs, Google Sheets for response data, and email for delivering signed PDFs to respondents and collaborators. In short, Formesign adds the missing signature step to Google Forms: legally binding eSignatures, multiple signers when a witness or guardian must also sign, signed PDFs generated and saved to Drive, customised emails to respondents and collaborators, and responses synced to Sheets — all inside the Google tools a team is already using. For organisations that need signature collection to be compliant, simple and affordable, it turns an ordinary Google Form into a source of signed, audit-ready documents.
Raycast 2.0 is the next generation of Raycast, the macOS launcher that acts as a single shortcut to everything you do on your Mac. This release is built on a new foundation and redesigned from the inside out, with a refreshed interface that feels right at home on macOS Tahoe. It is made for people who work from the keyboard: it brings AI that can take action across your apps, Automations for recurring tasks, and Projects to keep ongoing work together, alongside the commands and extensions you already use every day. Raycast 2.0 replaces Raycast V1 on installation, and existing users can import their existing setup during onboarding so everything feels familiar. Raycast 2.0 is described as a major update rather than a small point release. On installation, the new Raycast replaces Raycast V1; there are just a handful of missing features, and these will be added soon. The team notes that users should expect frequent updates and occasional rough edges, which signals the product is being shipped and improved continuously. The reason for the rebuild is the scope of what has been added on top of a launcher: an AI experience that can take action across your apps, Automations for recurring tasks, and Projects that keep ongoing work together. Delivering that on top of the original foundation required building a new one, which is why the release is described as redesigned from the inside out and as the launcher, relaunched. The most visible change is the AI experience. Quick AI lives in the same Tab as your existing search, so you do not have to learn a new place to type — it simply brings more power from the surface you already use. AI Chat brings skills, agents, and memory together in one place, so longer-running work can build on what came before instead of starting from zero each time. Raycast 2.0 also brings AI that can take action across your apps, and you can connect your own ChatGPT or Claude account, which means the assistant works alongside the commands and extensions you use every day rather than in a separate tool. Built-in dictation lets you type with your voice, covering the moments when speaking is faster or more practical than using the keyboard. Navigation and search received attention too. File Search now sits in root, described simply as one less step to find your files, while file search itself is faster. Quicklinks and snippets tagging are listed among what is new, and hotkey handling has been improved. Settings have been reorganized so configuration is easier to find, and you can configure inline: hotkeys and aliases can be assigned directly from root search, so a command can be set up the moment you find it. The overall look and feel has been updated to feel right at home on macOS Tahoe, so the launcher matches the operating system it runs on. Beyond the interface, Raycast 2.0 adds two organizing concepts: Automations for recurring tasks and Projects to keep ongoing work together. Automations address the work you repeat — instead of walking through the same steps by hand, the recurring task is handled by Raycast. Projects give ongoing work a home so related items stay together rather than being scattered across your setup. The extension story carries over as well: custom extensions continue to work, and for extensions that do not import automatically you can run npx @raycast/api@latest dev, with the dev command described as clever enough to pick up the new version if it is running. Commands and extensions remain the everyday surface that AI works alongside. Getting started with Raycast 2.0 follows a defined path. You download the build for macOS — version 2.3.1.0 is referenced on the site — and macOS Tahoe and Apple Silicon are required. Raycast v2 is built for macOS Tahoe; if you are still on Sequoia or earlier, you need to upgrade macOS before installing v2. To ensure a seamless onboarding experience, Raycast asks you to install the latest version of Raycast v1, or at least v1.104.16. During onboarding you are prompted to import or migrate your data from Raycast v1. If you skip that step or want to rerun it, you can do it manually with one of two commands: Migrate from Raycast v1, which automatically migrates your data from v1, or Import Settings and Data, a manual import from a .rayconfig file that you must export from Raycast v1. The recommended migration approach also protects your habits. Migrate from Raycast v1 imports settings and migrates all of your shortcuts to Raycast 2.0 while disabling them from working in Raycast v1, which ensures your hotkeys do not conflict. Raycast notes this is the recommended approach because there is some extra data that is not imported with the manual import — this includes Clipboard History, Wrapped and the Emoji picker. The outcome is that you keep a familiar setup while gaining the new capabilities: AI in the same surface as your commands, voice dictation, faster file search, Automations for repeated work, and Projects that keep related work together. Because the update replaces V1 on installation, the transition is a single step rather than running two launchers side by side. Concrete workflows follow the same shape. A developer can keep using Raycast to run commands and custom extensions, and can hand recurring steps to Automations. Someone who works across several apps can use AI that takes action across those apps and connect their own ChatGPT or Claude account so the assistant sits next to the commands and extensions they already use. When files need to be found, File Search in root removes a step and faster file search shortens the wait. When typing is impractical, built-in dictation turns speech into text. Ongoing efforts, rather than one-off tasks, can be grouped into Projects, while quicklinks and snippets tagging cover the links and text that get pasted again and again. Raycast 2.0 is built for macOS users who want a keyboard-first way to work: Product Hunt classifies it under Mac, Productivity and Developer Tools, and the site's own navigation points developers to an API, a manual, a browser extension and a dedicated Developers area. The release requires macOS Tahoe and Apple Silicon and is installed as an app on the Mac. Integrations explicitly mentioned include connecting your own ChatGPT or Claude account and the extension ecosystem, including custom extensions built with the Raycast API and the npx @raycast/api@latest dev command. On the commercial side, the site links to Pro, Teams, Enterprise and Pricing pages, which indicates offerings for both individuals and organizations, although no specific prices are stated on this page. Taken together, Raycast 2.0 is a rethink of an everyday Mac launcher rather than a feature patch. It keeps the launcher at the center — commands, extensions, search and shortcuts — and layers on AI that can take action across your apps, Automations for recurring tasks, Projects for ongoing work, and built-in dictation, all wrapped in an interface redesigned for macOS Tahoe. The goal is stated plainly by the product itself: your shortcut to everything, now with AI put to work alongside the commands and extensions you use every day.
EasySpecs is a spec engineering assistant and spec review platform built for Spec-Driven Development. It documents undocumented codebases and turns them into trustworthy specifications, so that spec review becomes the new merge request review. The product is aimed at developers, product owners, technical product managers, and organization leaders who need shared, trustworthy understanding of their software at the speed AI now changes it. EasySpecs produces functional documentation of the real system, helps teams polish intent and ground it against the current codebase, and then creates Trust by Design Specs before the code is written rather than after bugs pile up. EasySpecs frames its purpose around a shift in how teams ship software. AI agents generate code far faster than humans write it, but teams cannot review it all. The platform's own framing is that the gap between 1.5x and 100x is not speed, it is trust. Developers describe babysitting an agent for an entire run because looking away causes things to go wrong, while engineering leads and CTOs describe drowning in AI pull requests because agents generate faster than their teams can review. In parallel, merge requests have surged and code review has become a bottleneck. Documentation lags behind the system, shared context goes stale, and product and engineering overlap in their work with no single place to align. Spec Driven Development is presented as the new standard — and the consequence is that teams need a tool for quality specs, spec management, and spec-driven change management. The first capability EasySpecs describes is code understanding. The platform produces functional documentation of a project with up to 98% LOC coverage assignment, which it calls the first stone of Trust Engineering. Rather than relying on stale docs or guesswork, this functional documentation describes the real system as it actually behaves. The benefit is that later change requests and specs start from how the application really works and what users actually intend, not from an assumption. The platform's narrative illustrates this with the "Docs lag" scenario: when documentation falls behind the code, shared context goes stale, and EasySpecs responds with auto-sync documentation so the shared understanding stays current. The second capability is intent. When intent is fuzzy, EasySpecs helps teams craft, clarify, and ground it to the current codebase before agents generate code, so that Spec-Driven Development has something trustworthy to drive. What EasySpecs captures is "the ask behind the change" — grounded in how the app actually works, so product and engineering share one picture before specs are written. A screenshot illustrating this for technical product managers shows a Specs accordion with Change, Intent, Diagram, and Spec steps, taking a team from change request to a Spec that agents can ship against. This is how EasySpecs addresses the scenario where product and engineering overlap but have no place to align together: they align in one place. Once intent is clear, EasySpecs creates Trust by Design Specs with structured views and HTML-rendered views, so a change is visible and checkable before any code is written. Every Spec is sided by a Trust Spec. The Spec is described as the standard SDD spec — what to build, presented in structured and HTML views the team can actually read. The Trust Spec holds validators, evals, and checks that sit beside the Spec, so the team knows how it will trust the change before agents generate code. The product description summarises this as reviewing specs including Oracles and Rubrics. The underlying idea is Trust by Design: define how you will trust the code before you write it, not after bugs pile up — and the sooner that bar is set, the less cost and fewer problems the team carries. EasySpecs connects into the tooling teams already use. It is integrated with Jira and Linear for tracking work, and it has IDE integration with VS Code, Cursor, Antigravity, and any VS Code–compatible IDE, so developers can work from specs and Trust Spec validators where they already write code. On the product side, EasySpecs is integrated with Jira so that specs written by technical product managers are ready the moment engineering picks them up. For organization leaders, the dashboard shows change requests and linked Spec status across projects, tracking every change request and its Spec. EasySpecs describes itself as one Spec-Driven operating system for Tech and Product, giving both sides the same source of truth. EasySpecs lays its methodology out in three steps that follow the theme "trust before you code." Step one is Understand the code: EasySpecs produces functional documentation of your project with up to 98% LOC coverage assignment, so change requests start aware of real behavior and user intent. Step two is Polish the intent and ground it to the current codebase: when intent is fuzzy, EasySpecs helps craft, clarify, and ground it before agents generate code, so Spec-Driven Development has something trustworthy to drive. Step three is Create Trust by Design Specs: with intent clear, the platform generates structured and HTML-rendered views of the change, sided by a Trust Spec of validators, evals, and checks. Around this loop, EasySpecs organises stories of change as change → consequence → EasySpecs, covering spec-driven change management, auto-sync documentation, shared alignment, and Trust Engineering that eases merge requests. The platform's use-case page and conference appearances — including a presentation at an agentic coding conference in Hamburg, Germany — sit alongside these ideas. The outcome EasySpecs describes for users is scale without babysitting. Developers stop sitting with the agent for the whole run and instead work from Specs and Spec of Trust validators, so generation starts from clear intent and checks rather than vibes. Engineering leads and CTOs get a way out from under a growing pile of AI pull requests: instead of reviewing every generated change, teams review specs, and spec review becomes the new merge request review. Product owners can ground change requests in the real app, polish intent, and shape Trust by Design Specs the team can actually see, instead of fuzzy stories that burn engineering time. One quoted customer summarises the effect: "My team finally speaks the same language about specs. The pace of change was so fast we could not align. Now with EasySpecs, all clear." Several concrete workflows are described in the content. Teams with undocumented codebases use EasySpecs to document the real system once, creating a foundation for later specs. Engineering organisations facing a surge of AI-generated merge requests use spec review as the review gate, trusting specs before the next change lands. Technical product managers write specs that developers can ship against, working through Change, Intent, Diagram, and Spec steps in Jira, ready the moment engineering picks them up. Organization leaders introduce Spec-Driven Development across tech and product as a shared operating system, and track every change request and its linked Spec status across projects from the dashboard. Developers, meanwhile, use the IDE integration to work from specs and validators inside VS Code, Cursor, Antigravity, or any VS Code–compatible IDE. EasySpecs is built for product owners and developers as two sides of the same Trust by Design loop, and it also speaks directly to technical product managers and organization leaders. Its integrations cover Jira and Linear on the work-tracking side and VS Code, Cursor, Antigravity, and any VS Code–compatible IDE on the development side. The content reviewed here does not state pricing details or the underlying tech stack. EasySpecs positions itself as your spec engineering assistant: document the real system, polish intent, and create Trust by Design Specs with validators and evals, so teams can review specs instead of every generated change. Ground your agents in reality, scale agentic development without babysitting, and ship code you actually verified.
GLYPH Immersive is a free browser-based tool for drawing modular grid letterforms and shapes. You paint rounded-pixel forms onto an adjustable grid and control spacing, corners, and edges directly, then export your work for free. It is built for anyone who wants to construct letters and geometric artwork from elementary parts — type designers, graphic designers, letterers, artists, and students. No signup is required; the whole tool runs in the browser. It also includes a beta type tool for turning painted characters into a basic OTF font, and a reference system for placing a photo behind or inside your grid. GLYPH Immersive sits at the end of a long history of grids. Long before the digital pixel — earlier even than the concept of design — humans used math to create precise guides for art, architecture, and the page. Weaving, tiling, and writing were the foundation for humankind's earliest grids: Andean weavers encoded modular symbols across bands of textiles, Ibn Muqla proportioned Arabic script using rhombic dots, kolam artists built patterns across fields of points, and Hangul assembled circles, squares, and lines into 1:1 blocks. Later, Bauhaus stripped design to those same elementary parts, with Anni Albers crediting Andean weavers as her teachers. The early digital age relied on this foundation, using pixels to create efficient symbols on tiny screens, and that era's constraints and possibilities inspired New Alphabet by Wim Crouwel, Reticuláreas by Gego, Lance Wyman's Huichol-inspired Mexico 68, and Waldemar Cordeiro's computer art. GLYPH Immersive presents itself as a simple space that balances possibility with constraint, encouraging experimentation, play, and reflection about the systems we inherit, no matter how basic they may seem. At the center of GLYPH Immersive is a grid you paint on. You click or drag to paint cells, and Shift+click fills a line between two cells, which makes it fast to lay down a straight run of pixels. Joints follow a three-step cycle: the first click fills and joins a cell, the second click removes joints, and the third click resets the cell. Because the letterforms are drawn as rounded pixels rather than freeform curves, the results stay modular and systematic. A Detail control and an Invert option sit at the top of the interface for refining how the artwork reads, and a Clear board action wipes the surface when you want to start fresh. The control menu adjusts the artwork while the guide menu controls the artboard, keeping the drawing separate from its underlying structure. The guide menu controls the artboard. You can set Width, Height, and Spacing, add guides, and define a typographic layout with a font name, columns, gutter, rows, and gutter. Guide display options cover Grid, Dots, and Vertex modes, and a GuideView entry opens the Settings & Guide panel. Navigation is deliberately lightweight: scroll or two-finger drag to pan, pinch or use the Zoom slider to zoom, and drag to move or use corners to scale. A percentage readout tracks zoom, and a Preview Type option lets you check type output before exporting. Corners and Edges controls shape how letterforms and shapes are finished, which matters when you are working with rounded pixels instead of hard squares. When a design is finished, GLYPH Immersive exports it as SVG, PNG, JPG, ASCII MAP, or TYPE. The TYPE export is only available when Create type is on. The GLYPH Type Tool is described as a simple way to create your own font: each labeled green box is one character, covering A–Z, digits, and punctuation. You adjust the guides to change width, height, and spacing, then paint within the boxes to create each letter. When you are happy with your glyphs, you download TYPE to export a basic OTF you can install and try. The type tool is marked beta in the interface, and the workflow stays inside the same grid you use for everything else, so letterforms, spacing decisions, and the grid they sit on are all visible at once. GLYPH Immersive also supports working from existing imagery. You insert a photo, place it, and then choose Save as reference for a soft overlay behind your grid or Save as dots to convert it into editable grid art. Color in the guide menu cycles fill and background modes, so you can flip between painting the form and painting the ground. Wander plays a calm loop of designs, which makes the tool usable as a passive display as well as an editor. A Sound setting and a Language setting, which includes EN and ES, appear in the guide menu. The project is an open source resource by Kate Ander, with questions, ideas, and bugs directed to a dedicated email address, and an optional newsletter for occasional notes on GLYPH and new work. GLYPH Immersive's approach is deliberately reductive. Everything is built from elementary parts arranged on an adjustable grid, and the tool keeps possibility and constraint in balance rather than offering unlimited freeform control. The site notes that technology has continued to present new possibilities while at times numbing life's necessary friction — the constraints and discomfort that produce great art and ideas — and positions GLYPH as a simple counterweight to that. It runs in the browser with no signup, so nothing stands between an idea and the canvas, and the full workflow, from painting a first cell to exporting an OTF, an SVG, or an ASCII map, happens in one place. By naming the weaving, calligraphy, kolam, Hangul, and Bauhaus traditions that its grid logic descends from, it also treats the interface itself as a way of reflecting on inherited systems. The benefits follow directly from that design. Because export is free and no account is needed, you can move from experiment to finished file without friction — an SVG or PNG for further design work in another program, a JPG for quick sharing, an ASCII MAP for text-based environments, or a basic OTF font you can install and try out. Adjustable width, height, and spacing give you consistent control over rhythm across a whole set of letterforms, and separate corners and edges controls let you vary the finish without redrawing anything. The three-step joint cycle and line-fill shortcut make drawing fast enough to stay playful, which supports the experimentation and reflection the tool is built around. Concrete uses follow the tool's structure. A type designer or letterer can draw a modular alphabet cell by cell, tuning spacing and corners until the set reads consistently, then turn it into a basic OTF with Create type. An illustrator can place a photo, save it as dots, and repaint it as grid art, or keep it as a soft reference underneath while drawing. A student or teacher exploring grid systems can use the guide menu to change columns, gutters, and rows and see how proportion affects a form. Wander turns the board into a calm loop of designs, and exports cover SVG, PNG, JPG, and ASCII MAP for whatever the finished piece is headed toward. GLYPH Immersive is aimed at designers, type designers, letterers, artists, and students — anyone working with modular letterforms, symbols, or grid-based composition, from first experiments to finished artwork. It is free, runs in the browser, and requires no signup, so there is no cost or account barrier to trying it. The site presents it as an open source resource by Kate Ander, with copyright noted as 2026, contact by email for questions, ideas, and bugs, and an optional newsletter for occasional updates about GLYPH and new work. Beyond the browser itself, no specific frameworks, integrations, or third-party services are named in the content. Taken together, GLYPH Immersive is a free, no-signup workspace for building letters and shapes from rounded pixels on an adjustable grid, with fine control over spacing, corners, and edges. It pairs a fast paint-style drawing surface with a beta type tool that exports an installable OTF and a range of image and ASCII exports, making it equally useful for quick experiments and finished modular lettering work.
Anysite.io is a B2B data layer that lives inside the AI agent you already use. Rather than writing queries or maintaining scrapers, you describe the list you need in plain language — companies by geography, industry and size, the people inside them, their current job titles and emails — and Anysite.io returns it. The product is aimed at GTM and marketing teams that want fresh, ready-to-use web data for outbound, ABM, research and monitoring, and it works over MCP or a REST API inside agents including Claude, Codex, Cursor, OpenCode and others. The product is positioned against three walls that GTM and marketing teams hit every week. First, basic AI research is not enough: you ask an LLM to conduct research, but it is scratching the surface with old SEO links, bold assumptions and a lack of real-time market data. Second, lead enrichment is extremely expensive: using GTM tools for enrichment such as social media account summaries or news about a new company raise can easily land $3–5k invoices every month. Third, category intelligence means hours of scrolling: what is working in your category — competitor moves, brand mentions, posts that pop — hides behind manual feed-scrolling, and you still get no clear read. The first building block is live, typed web data. Ask your agent for a list and Anysite returns typed fields — people, companies, posts, prices — rather than a page of text you still have to parse, with one schema per source. Coverage spans 650+ sources and 3,500+ endpoints across social, e-commerce, news, finance, maps and code, business data included. Freshness is explicit rather than implied: data is pulled live from the source at the moment you ask, not served from a warehouse snapshot, so if a title changed this morning, that is the title you get. The site is also honest about the edges — niche sites with heavy bot protection are handled case by case. The second building block is plain-language briefing. You describe the task the way you would brief a teammate — an ICP, a competitor, a topic — and there is no query language, no endpoint IDs, no field mapping, no pagination to handle and no maintenance when a source changes. In the example shown on the site, the brief is "Find heads of growth at seed-stage fintechs in Europe who posted about outbound this month." The agent matches endpoints — people search, profiles and email finder — fills parameters such as geography, industry, founding year, role and verified-email-only, pages through results and deduplicates by company domain, then returns 50 prospects as rows containing name, role, company and email. The agent decides which endpoints to call; nothing about the underlying plumbing is left to the user. The third building block is a flat, data-based cost model combined with resilience and monitoring. MCP plans start at $30/month flat with fair-use throughput and a 7-day free trial, and on the API you pay for data returned rather than for attempts. On the monitoring side, your agent watches the category: competitors, mentions and top posts by topic arrive on a schedule, with the engagement numbers behind them, so you get the pattern rather than a feed. On reliability, when a site changes or blocks access, that is Anysite's problem rather than yours — endpoints heal themselves when a platform shifts its defenses, and requests route across multiple sources so no single provider can vanish and take your workflow down. Getting your web data runs in three steps and is described as needing only a few clicks, with no pipeline to build. In the Connect step you plug Anysite into your tools: add the MCP server to Claude, Cursor or ChatGPT, or take the REST API — the same catalog either way, every source included, nothing to install and nothing to keep running. The site shows a Claude Code command (claude mcp add --transport http anysite "https://mcp.anysite.io/mcp?api_key=YOUR_KEY"), a Cursor configuration block that goes in ~/.cursor/config.json, and a REST example that POSTs to https://api.anysite.io/api/people/profile with an access-token header and returns a typed profile. In the Ask step you describe the task in plain language, briefing it the way you would brief a teammate — an ICP, a competitor, a topic. In the Get step, typed, up-to-the-moment results land in your chat, sheet or CRM, ready for the sequence or the deck. The stated benefits follow directly from that flow. Because there is no pipeline to build and no query language to learn, no engineer is required to get value from the product, and teams can plug in and launch outbound data collection the same day. Because data is pulled live at query time, results reflect what is actually on the web now rather than a stale snapshot or a search index. Because output is typed and delivered where the team already works — chat, spreadsheet or CRM — results are ready for a sequence or a deck without a parsing step. And because pricing on the API is tied to data returned rather than attempts, enrichment work does not generate surprise invoices for tries that came back empty. Anysite lists concrete tasks by role. For Outbound & Sales it is building ICP lists with live buying signals to book meetings from lists nobody else has, rather than the tired database everyone else mails. For ABM it is walking into a call knowing the account's latest move, with this week's funding, hires and product news briefed before every call. For Market & Competitor Research it is building campaigns on data rather than guesses, with offers, prices and ads tracked as they change and no tab-by-tab copying. For Brand & Social Monitoring it is tracking mentions, sentiment and conversation shifts as a single morning read on brand health. For Content & Viral Intel it is publishing what a niche actually rewards, using top posts by topic and the engagement behind them instead of hours of scrolling. For Creator & Influencer work it is choosing creators on real numbers rather than edited ones, looking at true engagement, comment sentiment and brand fit instead of a media kit built to flatter. Beyond GTM and marketing, the site points to agentic products, e-commerce intelligence, due diligence, finance research, HR and recruiting, science research and reviews, and everyday life. On the audience side, the product speaks to GTM and marketing teams, outbound and sales teams, ABM programs, market and competitor researchers, brand and social monitoring teams, content teams and creator or influencer marketers, along with the broader use cases listed above. On the integration side, it states that it works with agents including Claude, Cursor, Manus, Grok, Gemini CLI, Codex, Antigravity, OpenClaw and OpenAgent, and it is described as a verified app on Make. Pricing is split into MCP plans and usage-based API plans. MCP costs $30/month for everyday research, MCP x5 is $99/month for active daily agents, and MCP x15 is $199/month for agents that never sleep; all MCP tiers include a 7-day free trial with full plan access and all 650+ sources with one key, and work with Claude, Cursor, ChatGPT and any MCP client. API plans are credit-based: Starter gives 15K credits/month for $49/mo ($3.27 per 1K credits) with the full REST API, a CLI tool and MCP server access; Growth gives 100K credits/month for $200/mo ($2.00 per 1K), 39% cheaper per request with higher rate limits for batch; Scale gives 190K credits/month for $300/mo ($1.58 per 1K), 52% cheaper with throughput sized for production; Pro gives 425K credits/month for $549/mo ($1.29 per 1K), 61% cheaper with max rate limits; and Enterprise gives 1.2M credits/month for $1,199/mo ($1.00 per 1K) with white-glove onboarding and custom rate limits. A Custom tier offers custom credit volume and rate limits, dedicated support and SLA, volume discounts and custom sources on request. Anysite.io's core proposition is simple: the web is the largest database ever built, nobody shipped it with a query language, and Anysite provides one — in the form of a plain-language agent interface backed by live, typed data from 650+ sources. For teams that need fresh B2B and web data for outbound, ABM, research and monitoring without writing queries or maintaining scrapers, it offers the same catalog over MCP or REST, flat MCP pricing from $30/month, usage-based API pricing that charges for data returned rather than attempts, and a 7-day free trial to start.

Cadenya is a hosted agent runtime that layers tools, agents, and objectives on top of the APIs you already run. Rather than a framework you bolt into your application stack, Cadenya runs the agentic loop for you, so you can build, test, and improve agents without rebuilding your stack. You connect your MCP servers, OpenAPI specs, and existing endpoints through a single tool layer agents can use as they are. From there you define an agent, shape its abilities, and run objectives. It is built for teams that already have working systems and want to add agentic capability on top of them. Teams that want agents in their product usually face an awkward choice: adopt a framework and integrate and maintain it inside their own stack, or build the agentic loop themselves — handling context windows, approvals, event delivery, and model comparison along the way. Cadenya starts from the opposite assumption, that the APIs already exist and already work. Its stated purpose is to layer tools, agents, and objectives on top of the APIs you already run so you can build, test, and improve agents without rebuilding your stack. Because the runtime is hosted and model-agnostic, teams can adopt frontier models fast, test behaviors, compare approaches, and add functionality rather than complexity. You start with your stack. Cadenya connects your MCP servers, OpenAPI specs, and existing endpoints through a single tool layer agents can use, and the documentation states plainly that you do not rewrite your APIs to use it. Tools are connected using specs you already know, so existing endpoints become usable capabilities for agents as they are. Inference is kept separate from that tool layer: Cadenya is model-agnostic, so you point it at OpenRouter or any OpenAI-compatible endpoint and it uses that for inference. Each new account comes with $5 in credits on OpenRouter pre-configured for you, and after that you provide your own LLM provider credentials. That separation is what allows you to swap models, evolve behaviors, and expand capabilities while retaining infrastructure. Defining an agent means assembling concrete building blocks. An agent has assignments — individual tools, tool sets, and sub-agents — shown in the product's interface as items like a reroute shipment tool, an update ETA tool, a dispatch API tool set, and a customs broker sub-agent. It has memory layers, such as a carrier playbook or SLA policies, and a system prompt that describes the agent's role and how it should behave. Agents can dispatch sub-agents, and the model configuration for sub-agents can be changed to best suit the job, which the product describes as the most efficient approach for token usage and outcome. Objectives are then run against that configuration, and each objective keeps its trail. Token usage is managed inside the runtime rather than left to chance. Cadenya provides live token metering so you can stay on top of costs, reduce waste through progressive discovery, and improve efficiency as agents adapt. Progressive tool discovery keeps tool schemas out of the context window until the agent asks for them — only names ride along, so every request gets smaller. It is configurable: you can enable progressive tool discovery, set the maximum number of tools per search, provide search hints such as delays, reroutes, or customs, and set a rerank threshold, which can be left blank to skip reranking. Context compaction is handled out of the box, and context window compaction is also emitted as a webhook event type. Real-time behavior is a first-class part of the runtime. Webhooks and SSE push agent events into your apps as they happen, so downstream services react immediately, and the documentation notes that Cadenya makes it easy to wire agent events into your applications. Every event in your agentic loop is sent to a webhook endpoint you provide; the interface lists event types including assistant message, tool result, tool approval requested, sub-agent spawned, context window compacted, and timed out, each with a delivery status such as HTTP 204 and a completed state. When a tool call needs sign-off, approval-gated tools pause the agent and deliver a tool_approval_requested event so a person or system can approve before anything runs. Cadenya also ships Widgets that can be dropped into any frontend to enable agentic features like conversations and more, alongside SDKs in four languages. Observation and experimentation are built in. Cadenya lets you monitor outcomes and understand how behaviors take shape in the real world, on the premise that clear visibility means your agents show their worth. You can run variations — the interface shows a Default and a Canary side by side with different models, creation dates, assignments, memory layers, and system prompts — which lets you test behaviors and compare approaches without uprooting what already works. Feedback is captured against variations and objectives with sentiment-style scores, so a reroute that happened before an SLA breach scores positively while a case where the agent held at a facility when a reroute was available scores negatively. Every objective keeps its trail: tool calls, webhook deliveries, token usage, and the feedback people leave on the outcome. The benefits follow from that structure. You iterate without uprooting: swap models, evolve behaviors, and expand capabilities while retaining infrastructure. You evolve with what's next by adopting frontier models fast, testing behaviors, and comparing approaches, so the unified runtime lets you add functionality, not complexity. You experiment safely because variations and feedback let you evaluate behavior before and while real objectives run. Costs stay visible through live token metering and progressive discovery. And because agents can talk to your systems in real time and every objective keeps its trail, you can answer the question of what an agent actually did. Concrete workflows run through the product's own material. A freight shipment-exceptions agent watches for stalled deliveries and reroutes them via a dispatch API; the interface describes a system prompt for the shipment-exceptions agent that instructs it to reroute when a delivery stalls. A related feedback comment credits the agent with catching a customs hold and updating the ETA proactively, and another with escalating a frozen-goods lane correctly. Approval-gated tool calls pause for sign-off before running. Webhook deliveries notify an application endpoint as events occur. Widgets embed agentic conversation into a frontend. And canary variations let the same objectives be run against different models for comparison. Cadenya is aimed at developers and teams that already run APIs and want agentic capabilities without a rewrite. Getting started is deliberately short — kick off an agent using APIs you already have, and the first step is signing up. New accounts receive $5 in OpenRouter credits pre-configured, after which you bring your own LLM provider credentials; the team also offers a free month for those who email support@cadenya.com. API documentation is published, SDKs come in four languages, and the product runs as a hosted runtime rather than something you install and maintain in your own stack. Cadenya's value proposition is straightforward: bring agentic possibilities to life on top of the stack you already have. By layering tools, agents, and objectives over your MCP servers, OpenAPI specs, and existing endpoints, keeping inference model-agnostic, and shipping the operational pieces — context compaction, tool approvals, webhooks and SSE, widgets, SDKs, token metering, and observability — it lets teams start with one agent and grow from there.
Loqua is AI voice typing and dictation software for Mac and Windows that turns speech into polished, ready-to-use text. The product's core promise is captured in its own words: from voice to text, from screen to insight. Instead of typing, you speak naturally and Loqua transcribes, cleans up, formats, translates, and even acts on what you say. It is built for people who would rather think than type — professionals, founders, engineers, designers, writers, students, and anyone whose hands are busy or who simply speaks faster than they type. One shortcut works across any text field, so dictation happens right where the cursor is without switching apps. The keyboard is the bottleneck Loqua was built to remove. Traditional keyboard typing runs at roughly 45 words per minute, while Loqua's dictation is presented at 220 words per minute — a speed difference the product sums up as saving 3 hours per day. Speed is only part of the problem. Speaking out loud naturally produces filler words, repetition, and half-finished thoughts, and the person then has to re-read and re-edit everything just said. Work is also fragmented across dozens of apps, so writing a message, checking a chart, looking something up, or setting a reminder each require switching context. Language barriers add another layer for people who work across borders. Loqua's answer is to let you keep thinking out loud and let the software handle the cleanup, structure, and follow-through. At its core, Loqua is voice typing that produces clean output. As you speak, it removes filler words, cuts repetition, and refines your phrasing in real time, so what lands on screen is ready to send. The product frames this as Say it rough. Get it clean. and directly addresses the annoyance of re-reading everything you just said. Users describe the result as sounding exactly like they meant it — clear, sharp, and effortless. Words appear quickly enough that users describe a zero-latency feel which makes them forget the tool is even there. Loqua also handles technical vocabulary: one engineer noted that a screen full of framework names, library names, and acronyms was transcribed accurately, removing the need to go back and proofread. Structure is handled automatically. Instead of dictating formatting commands, you think in bullets or speak in blocks and Loqua hears the structure in your speech, building lists, headings, and hierarchy on its own. This means outlining a document, a plan, or a set of risks can be done conversationally and still arrive formatted. Translation removes language barriers: you speak in your own language and get native phrasing in nearly 100 languages, instantly. The product highlights speaking in English while sending emails in Spanish to a Latin America team, with the translation described as instant and natural. Together these two capabilities mean voice input produces not just words, but organized, shareable, multilingual output. Capture to Ask lets you act on what is on your screen. You use a shortcut to select a table, a chart, or anything else, speak your question, and receive an answer, analysis, translation, or summary without switching apps — a three-step flow the product labels Capture, Ask, and Know. Ask and Edit handles rewriting: you highlight anything, whether a product, a draft, or a note, speak to edit it, and it is rewritten on the spot. A related capability, Ask anything, answers a quick question instantly without leaving the app you are already working in. Together these features address moments when you are looking at something you cannot figure out, or when rewriting is eating up more time than writing. Command to Go turns voice into a hands-free command hub. Triggered by a shortcut, it can set reminders, open apps, search routes, place calls, and send texts, so you can move work forward without jumping between apps and tasks. For people who prefer listening over reading, Loqua offers AI Podcast read-aloud: select text and have it read to you as a hands-free text-to-speech assistant, which the product positions as ideal for morning news and multitasking. This extends the product beyond writing into consumption and control — you can dictate output, edit what already exists, ask about what you see, and listen to what you would otherwise have to read. Loqua's approach is context-aware. The stated promise is voice typing that understands what you mean, not just what you say — the system is designed around context rather than raw transcription, which is why it can clean up phrasing, infer structure, and translate into natural-sounding language. Everything is reached through a single global shortcut that works in a terminal, Slack, Notion, email, or any text field, with no switching and no waiting; your voice hits the screen right where your cursor is. That universality is central: rather than being a destination app you visit, Loqua runs across the apps you already use and is invoked from wherever you happen to be typing. The team states that the product is backed by a dedicated voice AI team with full model iteration capabilities. The outcomes users report are consistently about speed and reduced friction. Loqua contrasts roughly 45 words per minute at the keyboard with 220 words per minute by dictation, and estimates a saving of 3 hours per day. Testimonials cite 25 minutes saved in under 4 minutes of use, PRDs written by voice saving at least an hour a day, 30-minute writing sessions turning into 5-minute speaking sessions, and more than 60 daily emails taking half the time — while reading better than before. Other reported benefits are less about time and more about access: one user with RSI in both wrists said Loqua made work possible again, a designer with ADHD said talking to Loqua feels like chatting with a friend and the document writes itself, and non-native English speakers said the cleanup makes their writing sound native. Trust matters too — a corporate legal counsel handling client financial data described Loqua as the first voice tool they trust enough to use at work. Concrete use cases appear throughout the product page and its testimonials. For writing and documentation, engineers explain things out loud and get documentation formatted perfectly, product managers dictate PRDs, standup notes, sprint recaps, and stakeholder updates, and consultants talk through client debriefs and receive clean summaries. For communication, users draft emails, Slack messages, and LinkedIn posts by voice, with tone switching automatically between an email to a CEO and a message to a team. For research and study, a UX researcher dictates research notes between interviews and PhD candidates use it for academic writing and dissertations, where the cleanup and formatting alone is described as worth it. For design and creative work, designers keep their hands on Figma while narrating design processes and case studies. Developers use it in terminals, GitHub, VS Code, and IntelliJ IDEA, including for coding notes. On the move, one user talks while walking and finds the draft waiting for them at the office. Loqua runs on macOS and Windows and installs as a downloadable desktop application, with a 14-day free trial. It is used across a long list of applications, including Google Docs, Microsoft Word, Notion, Slack, Gmail, Figma, VS Code, Microsoft Teams, Obsidian, Google Sheets, Zoom, Excel, GitHub, Terminal, Discord, Outlook, IntelliJ IDEA, PowerPoint, GitLab, WhatsApp, Telegram, Stack Overflow, OneNote, Canva, Photoshop, LinkedIn, Google Slides, X, Sketch, Reddit, Illustrator, Confluence, Evernote, Facebook, Adobe XD, and Google Keep. The company states that it supports the open-source community, with maintainers of public OSS projects getting free access through a Developer Grant application. Its shared roadmap includes meeting transcription, multimodal capabilities, and a Skill Market, with the stated intent of becoming a reliable work companion through continuous iteration driven by user feedback. Loqua's primary value proposition is simple: your thoughts should not have to slow down for a keyboard. By combining fast, context-aware dictation with real-time cleanup, automatic structure, translation across nearly 100 languages, screen-based question answering, voice editing, hands-free commands, and read-aloud, it turns rough speech into polished work and keeps you in flow. The result, in the product's own framing, is less typing, less context switching, and more time in flow — one shortcut that moves you from thoughts to being done.

Spaces is a desktop app that gives a team one shared space per project, where the people on the team and their AI agents work together. Instead of each person holding a private AI chat history, a space keeps the project's chats, files, and routines in one place, so Monday's decision is still there on Thursday for everyone. It is built for teams that already use AI assistants every day and want that work to be shared rather than scattered across separate laptops and browser tabs. Spaces runs as a desktop application on Apple silicon Macs and Windows PCs, and a single person can start with it free before inviting anyone else. The problem the product sets out to solve is described on its own site as five people with five private chat histories. Everyone on a team has their own AI thread, and none of them can see each other's. The project's context ends up spread across browser tabs on separate machines, so every new question begins by re-explaining the job to the assistant. Each individual gets faster, but the team as a whole does not. A shared space is the product's answer to that gap: one project, one conversation, with chats and files living in the space rather than in somebody's personal thread. Getting started follows three explicit steps. First you download Spaces; it is free, needs no account, and installs like any other desktop app. Next you connect your AI by pasting the ChatGPT, Claude, or Gemini key you already have — one provider is enough to begin with. Then you open a space by naming the project and putting a specialist to work, and from that moment the space starts holding the context. Because each person's agents, API keys, and connected accounts stay on their own computer, the account you connect is not moved into someone else's cloud. The shared space is the core of the product. Chats and files live in the space itself, not in one person's thread, so a Product Launch space can show a press list for launch week, waitlist copy, and a battery claims comparison beside a launch brief, all visible to everyone in the space. The example space is managed by a Launch Lead and also includes a Copywriter and a Researcher. Because the space holds the history, nobody has to reconstruct what was decided or re-feed the same background into a fresh chat. Rather than one general assistant, a space can hold specialists. The site frames this as hiring agents, not one assistant: a researcher, a copywriter, a launch lead, each keeping its own notes so anyone in the space can put them to work. Each specialist gets its own instructions, memory, and tools, so it can research, draft, work through an inbox, or run a report. Agents have skills and tools attached, and the studio view lets you pick an agent to chat with or add someone new to the space. Routines are the part of Spaces that keeps working when nobody is watching. They are described as things that run on a schedule — check-ins, follow-ups, and reminders. In the product demo there are three routines in the Product Launch space: a launch morning brief that runs daily at 9:00 AM, a Friday recap that runs at 4:00 PM, and a paused waitlist follow-up. The stated behaviour is that the space does the standing work and pings someone only when it needs a decision, which means routine output does not depend on a person remembering to ask. Spaces takes the position that teams should use the models they already pay for. You connect ChatGPT, Claude, or Gemini, or run a model on the computer itself — Ollama is shown running locally — and the keys stay on that person's computer. Providers can be switched per agent at any time, and more than one provider can be brought in. The stated benefit is that you are buying the space, not another subscription for tokens: Spaces is not a reseller of AI, it is the app those models work in. Agents can also use the real web through a built-in browser. Research, clicking through, and staying signed in all happen inside the app, so the agent sees the page the user sees. The site illustrates this with a supplier specification page for a solar backpack being checked against claims held in the space's files — a 65W peak panel, a 20,000 mAh pack, and a weatherproof shell — along with the instruction not to claim that the pack charges a laptop in an hour. Having the browser inside the app keeps the agent's view and the team's files in the same workspace. Spaces separates what stays local from what the cloud carries. Each person's agents, API keys, and connected accounts stay on their own computer and never go to the cloud. The cloud carries the space, the chats, the files, and the routines, and nothing else, and shared-space content is encrypted at rest with a per-space key held in Google Cloud KMS; only members of the space receive it. A space begins as yours, and when you invite someone it becomes a shared space you both work in — the same chats, the same files, the same routines, with their agents alongside yours. The outcomes stated on the site follow from that structure. Context stops being personal: the project's history, decisions, and files belong to the space and remain available to everyone in it. Standing work continues without anyone prompting it, because routines run on a schedule. Each person keeps control of their own keys and accounts, so joining a shared space does not mean handing a colleague access to a personal AI account. And because the team is not buying tokens from Spaces, adding a seat does not add an AI subscription — the models are the ones the team already pays for. Concrete scenarios appear throughout the site. A product launch team keeps a press list for launch week, drafts waitlist copy, and compares battery claims against a launch brief with a researcher, all inside one space. The same space runs a morning brief at 9:00 AM and a Friday recap at 4:00 PM, and it can follow up on a waitlist when someone switches that routine on. Agents use the built-in browser to check supplier specification pages against internal claims. A solo user can run unlimited spaces on their own machine with specialists, routines, and playbooks, and only moves to a shared cloud space when other people need to work in it. Pricing is stated clearly. The desktop app is free on your own computer with no account, and includes unlimited local spaces, specialists, routines, and playbooks, plus your own AI keys. Spaces Cloud is listed at $10.99 a year per person, described on the pricing panel as $0.92 a month, and the FAQ gives $1.49 a month or $10.99 a year per person; it adds cloud-hosted spaces with shared chats, files, and routines, plus the ability to invite anyone who has a seat. A team of five is $55 a year. Everyone who works in a shared space needs their own seat because each person runs their own agents, and anyone who works alone stays free. Enterprise is a conversation rather than a checkout, and puts Spaces inside your own cloud so the data never leaves it, with help setting the whole thing up. The desktop app runs on Apple silicon Macs and Windows PCs. The takeaway Spaces promotes is that AI work on a team should live in a place the team can see. One space per project holds the chats, files, and routines; specialists take on defined roles; routines keep the standing work moving; and the models doing the work are the ones you already pay for. Start free on your own computer, connect a key, and invite the team when you are ready.

Moji is a desktop Markdown reader and editor that lets you open Markdown files the way you open a PDF: double-click a file and start reading. It displays your document with clear typography, tables and diagrams, while editing and export stay ready when you need them. Built for Windows, macOS and Linux, Moji is lightweight, comfortable for long-form reading, and simple enough to disappear while you read. It is free, open source under the MIT license, requires no account, and its interface is available in Portuguese, English, Spanish, Japanese, Chinese and Russian. The official site presents version 1.0.7. Moji exists because of a simple observation: opening Markdown should be as simple as opening a PDF. The creator built Moji because a Markdown file ought to open the way a PDF does — with a double-click, instantly readable, with clean typography and no setup. Usability came first from day one, and editing and export were added afterward without losing that focus, so the reader never turned into something heavier than the task required. The supporting idea is stated plainly on the site as a motto: "Less interface. More document." That framing explains nearly every decision in the product, from how files are opened, to how previews are rendered, to how diagrams and exports are handled. How you get a file into Moji reflects that same philosophy. You can open documents through a file dialog, drag and drop them into the application, rely on file associations so a double-click opens Moji directly, or keep several documents open at once in a multi-tab workspace. Once a document is open, the preview is described as rich and secure: it renders tables, task lists, footnotes, LaTeX, code highlighting and emoji, and it provides outline navigation so you can move through a long document by its structure rather than by scrolling blindly. Because the goal is comfortable reading, the preview keeps your content in the foreground, with synced outline navigation and a dark theme available for focused sessions. When reading is not enough, Moji becomes an editor. Editing is built on CodeMirror 6 and includes Markdown shortcuts, line numbers, history, and search and replace, so precise editing stays available without turning the reader into a full code editor. A live preview keeps the rendered output in view as you work, which means you can see the effect of a change immediately rather than bouncing between windows. Exports are described as predictable: PDF, HTML and PNG outputs preserve typography, diagrams and very long documents, so what you see in Moji is what you get in the exported file. The export dialog is deliberately simple — you choose a format and a layout and proceed. Diagrams are handled without leaving the document. Valid Mermaid blocks become responsive diagrams inside the preview, effectively going from code to diagram instantly, and the supported range covers flowcharts, sequence diagrams, Gantt charts, class diagrams, ER diagrams and more. Clicking a diagram opens a viewer with 10% to 1000% zoom, free pan and fit to view, plus a minimap for orientation on larger diagrams, and each image can be exported individually as PNG. The rendered diagrams are self-contained SVG in HTML, PDF and PNG exports, which means the diagrams travel with the document and keep their fidelity outside Moji. Moji's overall approach is to keep the interface quiet and the document loud. Subtle chrome, comfortable reading and compact controls are meant to keep you in the flow, with the content rather than the application occupying the foreground. Focused reading is supported by a synced outline and a dark theme; precise editing is supported by code, shortcuts and search; exporting is handled through a simple dialog where you pick a format and layout. The site organizes these capabilities as "the essentials, done well" and describes an interface that gets out of the way, which is also why the reader is presented as the primary mode and the editor as something that is there when you need it. The practical benefit is immediacy: no setup, no account, and no friction between a Markdown file and the text inside it. Because Moji is lightweight, it stays comfortable during long-form reading sessions and can be left open without demanding attention. Because it is free and open source under the MIT license, there is no cost or lock-in to evaluate before trying it, and the code can be explored or contributed to. Because the preview covers the formatting people actually use — tables, tasks, footnotes, LaTeX, code, emoji and diagrams — you rarely need a second tool to check what a document looks like. And because exports preserve typography, diagrams and very long documents, the same file can be shared, published or archived in a different format without rework. Concrete scenarios follow the reading-first design. You can open a README or project documentation by double-clicking it and read it like a PDF, using the outline to jump between sections. You can draft or fix a Markdown note in the editor with Markdown shortcuts, line numbers and search and replace, watching the live preview update. You can author a Mermaid flowchart or sequence diagram inside the document, zoom and pan around it in the viewer, and export that single diagram as a PNG. You can turn a long Markdown document into a PDF with precise layout, into HTML that is web ready, or into a PNG for very long documents. And you can keep several documents open in tabs while working across a project. In terms of audience and delivery, Moji is aimed at people who read and write Markdown on the desktop and want that experience to feel like opening a document rather than launching a technical tool. Official installers are published directly through GitHub Releases: an NSIS installer for Windows x64 with automatic updates, a universal DMG for macOS covering Apple Silicon and Intel with manual updates, and for Linux an AppImage with automatic updates or a DEB package for manual installation. The editing surface is built on CodeMirror 6, diagrams are rendered with Mermaid, and the interface speaks Portuguese, English, Spanish, Japanese, Chinese and Russian. Moji is free and distributed under the MIT license, with no account required. Taken together, Moji's value proposition is straightforward: it treats Markdown as something you should be able to simply read. Double-click a file, get clean typography, navigate by outline, edit when necessary, render diagrams inline, and export to PDF, HTML or PNG without surprises. The interface stays out of the way, the software stays free and open source, and the document remains the point.

sizeless is an AI-powered documentation platform for civil engineering that turns a smartphone video of an open trench into the deliverables utilities and contractors are legally required to produce: a 3D model, CAD/BIM plans, and the quantities they bill from. It is built for network operators and construction teams working on civil engineering, district heating, and house connections who need precise 3D twins of open trenches and house connections delivered directly for GIS and CAD. The platform pairs a guided iPhone Pro capture app called SiteScan with processing that generates high-resolution 3D reconstructions, industry-standard as-built plans, and GIS-ready digital twins, so that a single scan produces every output a team already works with. The problem sizeless addresses is the gap between how fast underground infrastructure is built and how slowly it is documented. Producing compliant as-built documentation has traditionally taken months and required a surveyor, which means trenches must either stay open or be revisited, crews wait for separate surveying appointments, and the final record is assembled from manual sketches that end up in disconnected data silos. Because documentation lags behind construction, billing and cash flow slow down, and construction errors can go unnoticed until they are buried under backfill. sizeless moves documentation into the moment of excavation: the existing project team films the open trench themselves, and the required outputs are generated from that single capture, in hours rather than months. The workflow begins with trench capture. Using a standardized capture process on an iPhone Pro directly at the excavation, the existing project team records the open trench. No special hardware is required and no extra appointments have to be scheduled, which means documentation starts while the trench is still open rather than in a later, separate surveying visit. Because capture is carried out by the people already on site, the process does not depend on specialists being available, and technicians can document house connections independently via smartphone. The same guided approach is used by the SiteScan iPhone app to capture properties, trenches, and technical rooms in minutes. From that captured video, algorithms developed at ETH Zurich generate a high-resolution 3D point cloud of the open trench that is centimeter-accurate. The point cloud is the objective basis for earthwork volumes, dimensions, and audit trails, giving teams a measurable 3D reconstruction of the scanned space instead of a hand-drawn approximation. The reconstruction is interactive, so users can rotate and zoom through it to inspect the captured geometry. This continuous 3D evidence also covers third-party utilities and house entries, and it works without GPS in basement areas, which keeps documentation complete in places where positioning signals are unavailable. The capture then converts into a 2D CAD as-built plan in DWG/DXF, the industry-standard format for revision documentation. In these plans, couplings and pipes are quickly identified and measurement extraction is simplified, so the as-built record can be handed to the processes and tools that already consume CAD drawings. Alongside the 2D plan, sizeless produces a 3D model and digital twin of the pipe route including house entries, with seamless integration into GIS systems for future-proof planning and maintenance. Together these outputs mean one capture yields a 3D point cloud, 2D CAD, and BIM/GIS deliverables ready to drop into existing tools. sizeless describes its approach as a four-step AI-powered workflow. Step one is trench capture at the excavation by the existing project team. Step two is the generation of a centimeter-accurate 3D point cloud using algorithms developed at ETH Zurich. Step three is the production of 2D CAD as-built plans in DWG/DXF for revision documentation. Step four is the 3D model and GIS output that represents the pipe route as a digital twin, including house entries. The differentiating idea is that no surveyor and no special hardware are needed: the documentation is filmed by the crew themselves and turned into compliant deliverables from a single scan, which is why sizeless can produce documentation in hours where the traditional route takes months. The benefits follow directly from that workflow. Trenches can be backfilled immediately after the video, with no waiting for separate surveying appointments, and complete documentation is available weeks earlier, which enables faster billing and cash flow. Documentation is described as quality-assured and audit-proof, because the continuous 3D evidence eliminates manual sketches and data silos and allows construction errors to be identified before backfilling. Process autonomy is another stated outcome: technicians document house connections independently with a smartphone, and existing internal or external teams can handle a higher project volume through more efficient workflows, without specialists. The headline references include 72-hour documentation, DWG/DXF outputs, instant backfill, iPhone Pro capture, GIS-ready data, and higher throughput. Concrete use cases include documenting open trenches for civil engineering and district heating projects, capturing house connections and house entries, documenting third-party utilities encountered in the trench, and scanning properties and technical rooms with the SiteScan iPhone app. Because the outputs include as-built plans and quantities, the documentation also feeds revision documentation and the measurement quantities that contractors bill from. For network operators, the resulting digital twin of the pipe route integrates into GIS systems to support future planning and maintenance of underground infrastructure. The primary audience is network operators, utilities, and contractors active in civil engineering, district heating, and house connections, along with the existing field teams and technicians who carry out the work on site. Documentation is available through the web platform at sizeless.co, where users can book a demo, request an in-person demo, or see the workflow in action, and through SiteScan, the sizeless iPhone app available on the App Store. sizeless was founded by engineers from ETH Zurich and UC Berkeley and is backed by Y Combinator, ETH Zurich, UC Berkeley, Cambridge, and MIT. In summary, sizeless replaces months of surveying and manual sketching with an AI-powered, video-first documentation workflow for underground infrastructure. A single smartphone scan of an open trench becomes a centimeter-accurate 3D point cloud, DWG/DXF as-built plans, and a GIS-ready digital twin of the pipe route, giving utilities and contractors audit-proof documentation, faster backfill, faster billing, and greater process autonomy without special hardware or specialist surveyors.
ChatHop is a browser-based tool that moves your AI conversation from one assistant to another mid-thought, with the context included. Instead of starting over on a different AI service, you take the conversation you were already having and carry it into a fresh chat on the assistant you choose. ChatHop is aimed at people who work inside AI chat interfaces every day and want the freedom to switch without losing the thread. It is not a new place to chat; it is a way to move the chats you already have. Its purpose is a single idea: your conversation should be able to travel with you, so you never have to re-explain what you were doing, what you asked, or what you already got back. The problem ChatHop addresses is the wall. You ask something and get a bad answer. You hit a rate limit. You want a second opinion on the response you just received. Any of these moments can stop a session dead, and the usual workaround — opening another AI, copying fragments of the old conversation, and retyping your instructions — costs time and breaks the flow of thought. It arrives at the worst possible moment, right when the work is going well. Re-explaining context is not only tedious; it can change the result, because the new assistant never sees the full exchange that led to your question. ChatHop treats the conversation itself as the thing worth moving, so the work you have already done stays intact. The site sums the promise up in one line: your conversation, carried over, no re-explaining. The core capability is a one-click transfer of conversation context into a fresh chat on the AI you pick. When you run into a bad answer, a rate limit, or a need for a second opinion, you trigger a hop rather than start from scratch. ChatHop asks you to choose why you are moving the conversation and then to choose your destination, and it carries the conversation into the new chat. Answering that first question turns a vague urge to escape a stuck conversation into a deliberate choice about where the work should go next. The result lands in the destination composer, ready for you to review and continue. Auto-send is optional and off by default, so nothing sends without you — you keep control of what leaves your hands and when it does. ChatHop also copies the complete conversation to your clipboard in plain text or Markdown. This is the 'take it with you' half of the product: when you need the conversation somewhere other than another AI chat, you can paste it into a document, an email, a notes app, a code editor, Slack, another AI, or anywhere else you choose. The format choice matters for practical reasons, since plain text drops cleanly into almost any destination while Markdown preserves structure in the tools that read it. Because the copy is a full conversation rather than a single reply, it captures the back-and-forth that gives the exchange its meaning. ChatHop's framing is that you decide where it goes — the copy is an export you control, not an automatic sync. Privacy is presented as a design principle rather than an afterthought. ChatHop reads conversation context only when you initiate a transfer or a copy action, meaning it acts on your instruction instead of scanning continuously in the background. Conversation text is never sent to ChatHop's billing service, which keeps the content of your chats out of the payment path. Your chats are not used for advertising, profiling, or chat analytics, and ChatHop states that it does not sell conversation data. The design intent is that the tool holds your text only long enough to do the job you asked for. Taken together, these commitments mean the product's access to your conversations is bounded by the specific action you take. The workflow is deliberately three steps. First, open your conversation and work where you already work, because ChatHop supports the major AI chat services you use every day. Second, click and pick: choose why you are moving the conversation, then choose your destination, and ChatHop carries the conversation into the new chat. Third, review, send, and flow on — the conversation is placed in the destination composer for your review, and if you have enabled Auto-send, ChatHop can send it automatically, though it never does so without your say-so. Each step hands a decision back to you before the next one begins. Putting the review step in the middle keeps the human decision point inside the process rather than bolted on at the end. The stated benefit is speed and continuity. The site puts it as seconds from stuck to shipping — that is a hop. Instead of losing a session to a rate limit or a weak answer, you keep the thread alive somewhere new, with the previous exchange in hand. Because context travels with the conversation, you do not pay the re-explaining tax. Because nothing auto-sends by default, you do not trade that convenience for loss of control. For anyone working through a long problem in stages, that continuity is the difference between a session that survives the interruption and one that quietly dies. The product is positioned around a simple expectation: switching assistants should feel like continuing, not restarting. Concrete scenarios follow directly from the page. You get a bad answer and want to see whether a different assistant handles the same prompt history better. You hit a rate limit mid-task and need to keep working rather than wait. You want a second opinion on a response you already received, with the original exchange in front of the new assistant. Or you need the conversation outside an AI chat altogether — pasted into a document, an email, a notes app, a code editor, Slack, or anywhere else you choose, in plain text or Markdown. Each case is the same underlying move: take what exists and put it somewhere it can continue. ChatHop is built for people who treat AI chat interfaces as a working environment rather than a novelty, and who would rather carry a conversation forward than rebuild it. It is distributed as a browser tool; its Product Hunt listing places it under Chrome Extensions, Productivity, and Artificial Intelligence. It supports the major AI chat services you use every day, without naming individual providers on the page. Pricing starts free: 20 free uses every month, with no signup, no password, and no card required to start. That free tier reads as a way to learn the habit rather than a hard wall. There is no ChatHop account or password. If you upgrade, Stripe securely handles checkout and subscription management, and ChatHop never sees your full card details. ChatHop's value proposition is portable conversation. It takes the moment you hit a wall — a bad answer, a rate limit, a need for a second opinion — and turns it into one click that carries your context into a fresh chat on the AI you choose, or copies the whole exchange to your clipboard as plain text or Markdown. With 20 free uses a month, no signup to begin, review-before-send by default, and a privacy stance built around acting only when you do, ChatHop is a focused utility for a specific and recurring friction: your chat should be yours to move.

Vibe Eyes is a macOS menu bar app that puts your pet in your menu bar. You drop in a photo of your own pet, and the app turns that pet into a tiny animated avatar that lives at the top of your screen. Eleven pets also ship built in for free, so you can try the experience immediately without uploading anything. The app is aimed at people who spend long days at a desk, staring at a screen, and miss the animal they share their home with. Instead of taking over your screen with a window, Vibe Eyes stays in the menu bar, where it becomes a small, permanent presence you catch sight of while you work. The idea comes directly from the maker's own routine. Working from home, with a dog sleeping two rooms away all day, he kept missing him while staring at a screen. The solution was to put the dog on the screen, in the menu bar, in a spot he already looked at a hundred times a day. That is the entire premise of the product: take the pet you miss, and place them somewhere you naturally glance during the workday. Because the menu bar is always visible and always in the corner of your eye, it becomes a low-effort way to keep a pet present without adding another app to manage or another window to switch to. The core workflow is simple. You supply a photo of your pet, and the app generates a small animated head from it that appears in the menu bar. Making your own pet is a one-time $14.99 unlock, and it requires you to connect your own AI key. There is no subscription attached to that unlock. Because the maker does not run a backend, your photo is sent to the AI provider you connect and nowhere else. That structure puts the user in control of both the generation step and the image data: you choose which provider handles the photo, and the developer's servers are never part of the path. Once the avatar is up, it behaves like a tiny companion. Its eyes follow your cursor as you move around the screen. It blinks on its own. It winks when you click. And when you have been idle for a while, it glances up at you. These four behaviours are the entire interaction model: there is nothing to configure and no window to open. The design leans on small, ambient signals rather than notifications or badges, so the pet reacts to what you are already doing at the machine rather than demanding attention. The result is a character that feels alive in the corner of the menu bar without interrupting the task in front of you. The hardest part of building it was not producing a cute head from a photo. It was the blink. A generated head has its eyes wherever the model decided to place them, which means the app has to measure the real eyeballs in the image and bake a closed-lid frame that matches them. When that frame is even slightly off, the result becomes uncanny: white crescents show through the lid, or the fur changes colour around the eye. According to the maker, most of the last few months of development went into that single frame, because a pet that blinks wrong stops looking like your pet. That attention to one detail is what separates the avatar from a generic animated sticker. Beyond custom pets, Vibe Eyes comes with eleven pets built in, free. Those built-in animals let you use the app straight away, with no photo, no AI key and no purchase. If you want your own pet in the menu bar, the custom path is a one-time $14.99 unlock plus your own AI key. There is no subscription and no backend. That combination gives the app a straightforward pricing shape: a free tier with eleven ready-made pets, and a single paid unlock for personalising the avatar with a photo of your own animal, paid once rather than monthly. The app is deliberately lightweight in how it occupies your Mac. There is no window, no dock icon, and no permissions to grant. Vibe Eyes lives only in the menu bar, which is the same place the avatar itself appears, so there is nothing else to manage or dismiss. Privacy is handled by omission: the maker does not run a backend, so your photo goes to the provider you connect and nowhere else. For anyone cautious about uploading pictures of their pet, that architecture is the point: you control the AI key, you control the provider, and the developer's server never receives the image. The outcome the app aims for is small but real. The maker's own description of the experience is that you catch yourself glancing up and smiling. It is not a productivity tool and it is not trying to change how you work; it adds a tiny, personal detail to an environment you stare at for hours. For people who work from home with a pet asleep in another room, or who simply like having a familiar face nearby, that detail changes the texture of a long desk session. The value is emotional and ambient rather than functional, and the app is honest about that scope. Typical use looks like this: you are working from home, your dog or cat is asleep two rooms away, and you are at the desk for hours. Vibe Eyes puts that pet in your menu bar so they are in view whenever you glance up. Another common path is dropping in a photo to turn your own pet into a custom animated avatar rather than picking one of the eleven built-in animals. Others start with the built-in pets simply to try the app, then move to a personalised version later. And, as the Product Hunt launch thread shows, people also enjoy deciding which pet they would put in their menu bar and sharing photos of them with other users. Vibe Eyes is a macOS app distributed through an App Store listing linked from its Product Hunt page. It is tagged on Product Hunt under Mac, Pets and Menu Bar Apps, and filed in the avatar generators category. At launch it gathered 86 votes, 5 comments and 78 followers, with commenters praising the attention paid to the blink, asking whether a Windows version is planned, and requesting additional pets such as a shiba inu. Those questions and requests appear in the launch discussion rather than as a formal roadmap, so capabilities beyond what is described here should not be assumed. In short, Vibe Eyes takes a photo of your pet, or one of eleven built-in animals, and turns it into a tiny animated avatar that lives in your macOS menu bar, following your cursor, blinking, winking when you click and glancing up when you have been away. It is free at the built-in tier, with a one-time $14.99 unlock plus your own AI key for a custom pet, and no subscription or backend behind it. The promise is modest and specific: a pet you miss, placed somewhere you already look a hundred times a day.
Modeinspect is a design canvas with your codebase and agents built in, positioned as a production-grade AI design tool that runs in your codebase. It is built for design engineers and for teams that want to design high-fidelity product features directly on the real thing rather than in a separate mockup tool. Teams connect their codebase, open an existing screen, and design with their own components, tokens, live data, states, and breakpoints. The canvas is deliberately framed as a means to an end: as the company puts it, the canvas is not the destination, the product is. Design on a real canvas that sits on top of the real product, with all the freedom of a design tool and none of the throwaway mockups. The problem Modeinspect addresses is stated plainly: most software is designed twice, a picture first and then again in code, with intent drifting in between. The traditional path runs through what the product calls the handoff chain, where design passes work down a chain and then waits for it to come back. Mockups are rebuilt in Figma away from the real product, specs and redlines document every state, engineers reinterpret the design in code, and every change restarts the whole loop. Modeinspect describes that old way as taking 45+ days from design to ship, and contrasts it with a canvas-to-PR loop it says runs about 10 days — roughly 4.5× faster. The argument is that design should not be detached from the thing it is designing, because the moment intent is copied into a picture, it begins to drift. The core promise is unified, collaborative design in code. Everything is in one place: your codebase, the canvas, and coding agents are integrated out of the box, with no MCP servers, no localhost, and no devops glue required. A live product can be pulled onto the canvas, letting you capture any element of your live product, pixel perfect and fully editable, so work starts from where things actually are. Rather than prompting for every adjustment, Modeinspect emphasizes controls, not prompts: a padding change should not take a paragraph, so you edit anything, on canvas or in code, with the visual controls you already know. Your changes then build back as canvas to code in one shot, producing clean, scoped diffs with your design system enforced. The canvas is also built for collaboration, with no localhost to share and no branches to wrangle, so you can send a link, collect comments, and open the PR in one click. Modeinspect is built for design engineers, and its component story is deliberately literal. Components are 1:1: you drop in the actual components your product ships, with every variant and every state intact, rather than a redrawn look-alike that quietly drifts from the real thing. Tokens are enforced, so every color, space, and text style comes straight from your library, and everything you place is automatically on-brand — nothing off-system can sneak in. Breakpoints are native: mobile, tablet, and desktop are laid out side by side and each one reflows live, instead of relying on one frozen frame you just hope survives on a phone. And capture to canvas means that when you spot something in the real product you want to rework, you can pull it straight onto the canvas pixel-exact and fully live, and start from where things actually are rather than from an approximation. Dynamic states and real data are treated as first-class parts of the design rather than afterthoughts. Hover, focus, error, empty, loading, and success states are shaped on the real component, so a design never falls apart the moment someone actually uses it. Real data and real flows mean designing on top of live data and genuine journeys — long names, empty states, and the messy edge cases — so your work holds up in the wild and not just in a tidy mockup. AI exploration uses the latest AI models to explore variants, restyle a section, adjust copy, or apply a design direction while you stay in control, which keeps the AI in a supporting role instead of taking over. And because every move you make on the canvas becomes the real product as you make it, there are no redlines, no spec docs, and no waiting on a rebuild: what you design is what ships. A large part of the product's approach is the quality of the code that comes out the other side. Mode reads your file layout, components, tokens, conventions, and existing logic, then writes within them, so PRs land scoped, type-safe, and ready for engineering review. Diffs are scoped and clean, letting engineers review focused changes rather than rewritten surface area or noisy AI churn. Your design system is enforced throughout: Mode pulls from your component library and design tokens, with no hardcoded colors, no magic numbers, and no throwaway components. There is no generated UI debt, because changes reuse your components, tokens, utilities, and styling system instead of creating a parallel design system. And changes are type-safe, with props, state, events, and data shape checked against the product instead of guessed from a mockup. This is the methodology that separates Modeinspect from AI app builders that generate new surface area alongside the one you already maintain. The stated benefits are framed as measurable rather than aspirational. Modeinspect says production-grade is not a tagline but the metric, and it highlights one customer story in which a team merged design and engineering into the same loop, saving 22 days on the delivery cycle, with zero engineering handoffs and design QA removed. Prelude's Chief Product & Design Officer, Quentin Le Bras, is quoted saying his designers explore on the actual codebase, with real data, and open the PR themselves, going from idea to a merged PR without a handoff in between. A Product Design Manager at Kiwi.com describes the tool integrating seamlessly with their codebase and design system, which is exactly what they had been looking for in AI design tools, enabling iteration on top of an already complex product. A Principal Product Manager at Moss calls it the first AI tool that respects their design system 1:1, allowing the team to create production-like prototypes and making the whole team faster. A UX Designer at NCCER highlights the ability to make changes in real time using their design system and immediately push those changes to code for senior developers to review and merge. The product organizes this into three workflows that share one production loop, all inside your real codebase at production fidelity. Prototyping covers prototypes that feel like the product, built with real data, dynamic states, breakpoints, and interactions — so instead of pitching with mockups, teams pitch with the thing itself. Design QA happens all in one loop: compare canvas to live build pixel-by-pixel, spot drift, fix it, and keep moving, with no round-trips through Figma. Shipping PRs covers pushing minor visual changes or new components as merge-ready PRs, with context, screenshots, and a clean diff. Concrete scenarios follow from these: reworking a screen you spotted in production by capturing it to the canvas, exploring variant directions with AI while keeping control of the final decision, validating a layout against long names and empty states using live data, checking a live build against the canvas for visual drift, and sending a link to stakeholders for comments before opening the pull request. Modeinspect is aimed at design engineers and at teams where design and engineering work in the same loop. The marketing site notes that the product is optimized for larger screens, which fits a workflow built around a canvas, a codebase, and side-by-side breakpoints. The company reports being loved by design engineers at Kiwi, Moss, Apify, e2b, Prelude, NCCER, and Deepnote. Pricing is listed at three monthly tiers: $0/mo, $24/mo, and $48/mo, so there is a free entry point alongside paid plans. Sign-in and the working canvas live at app.modeinspect.com, and the site offers an option to email yourself a link for later. In summary, Modeinspect's primary value proposition is that design stops being a picture that must be rebuilt and becomes the production loop itself. By putting an AI design canvas on top of your real codebase — with your components, tokens, live data, states, and breakpoints — and by writing changes back as scoped, type-safe, merge-ready diffs, it removes the handoff in between and lets teams go from an idea to a merged PR in a single pass.

Drive is an iOS app that turns the phone already in your car into a vehicle telemetry rig. It captures g-force, braking, cornering, and the full trace of a drive, and it flags license plate reader (LPR) cameras as you approach them. The app is built for driving enthusiasts who want telemetry data on their next weekend drive without installing specialized hardware, wiring looms, or dongles. Drive requires no laptop and no sign up — you open the app and drive. It positions itself as a simple route to driving fun with real driving data attached. The product grew out of a gap its maker experienced firsthand. The maker spent a few years as a design lead on autonomous driving interfaces for Android Auto — the work of making a car drive itself well — and then spent weekends in a 27-year-old car doing precisely the opposite, badly, for fun. Drive is what came out of that gap. The problem it addresses is that dedicated vehicle telemetry setups are expensive and complicated: the category Drive is up against costs between $800 and $3,000 and involves installing a wiring loom. Meanwhile, the phone already sitting in the car has contained an accelerometer, a gyroscope, and GPS for a decade. Drive's premise is that this gap between costly telemetry hardware and the sensors already in your pocket is most of the product. The core of Drive is its telemetry capture. The app measures g-force, braking, and cornering, and records the full trace of a drive. Rather than relying on external sensors, it draws on the phone's existing hardware to log how the car behaves through acceleration, deceleration, and turns. This gives drivers a record of the dynamics of a session — the kind of data that enthusiast drivers and track-day participants traditionally gather with dedicated data loggers. For anyone who wants to see how a particular corner was taken or how hard a braking zone was, the trace provides that feedback. Because the trace is captured from the phone, there is no wiring loom, no dongle, and no laptop involved anywhere in the process. Drive also flags license plate reader cameras as you approach them. This feature began as a personal itch: the maker noticed Flock cameras appearing everywhere and wanted an alert when a drive came up on them. In the app, LPR camera locations surface as you come up on them, so drivers know about the cameras before passing rather than discovering them after the fact. For people who care about privacy, this turns an otherwise invisible part of the roadside into something the driver is consciously aware of. A user in the launch discussion asked where the camera locations come from — whether something like DeFlock's OpenStreetMap layer or a dataset of the app's own — but the available content does not state the underlying data source. A defining characteristic of Drive is everything it does not require. There is no wiring loom to install, no dongle to pair, no laptop needed to run it, and no sign up before you can start driving. Those omissions are deliberate rather than incidental: the product's value comes largely from removing the setup that usually stands between a driver and telemetry data. The phone already in the car, with its accelerometer, gyroscope, and GPS, supplies the measurements instead of dedicated hardware. This makes Drive dramatically simpler to begin using than hardware-based telemetry rigs, which cost far more and demand installation. The maker summarizes the whole proposition as no wiring loom, no dongle, no laptop, no sign up — just driving fun. Drive's overall approach is to replace dedicated telemetry hardware with software running on a device the driver already owns. The phone's onboard accelerometer and gyroscope sense motion and orientation, while GPS provides positional context for the drive. From those inputs, the app produces g-force, braking, and cornering readings and assembles them into a full trace of the session. Alongside the driving data, the app uses location to flag license plate reader cameras as they are approached. The result is a telemetry experience with essentially no hardware footprint: nothing to wire in, nothing to plug in, and nothing to carry beyond the phone. The maker frames this substitution — an expensive rig versus the sensors already in your pocket — as the essence of the product, and as the thing that made the app worth building. For drivers, the benefit is access to telemetry that would otherwise demand a costly, hardware-heavy setup. Instead of spending $800 to $3,000 and installing a wiring loom, a driver can use the phone already in the car. There is nothing to wire up, nothing to plug in, and no account required before driving, so the time between deciding to go for a drive and capturing data is effectively zero. The LPR alert adds a distinct privacy benefit: drivers concerned about license plate reader cameras get a heads-up as they approach those locations. Together these benefits point to a single outcome the maker names directly — driving fun, made measurable, without the usual friction. Drive is designed around the weekend drive. The maker's own scenario — spending weekends in a 27-year-old car, driving for fun — is the canonical use case: a driver takes the car out, launches the app, and captures the g-force, braking, and cornering trace of the run. Because there is no setup cost in time or hardware, the app also suits spontaneous drives rather than only planned track sessions. Privacy-conscious drivers can use the LPR flagging to stay aware of license plate reader cameras along familiar or unfamiliar routes, a use that arose from the maker noticing Flock cameras everywhere. Experienced users of dedicated data loggers are invited to try Drive and compare. Drive is an iOS app, available on the App Store, and it has been tagged with iOS, Cars, and Privacy on Product Hunt under a Maps and GPS category. It targets driving enthusiasts — people who take weekend drives, drivers of older cars, and users who have experience with real data loggers such as AiM, VBOX, or Racelogic. The maker has explicitly asked that audience what they would miss most when moving from dedicated data loggers to a phone, and said that is the list the product is being built from. Drive is free to start. No specific third-party integrations, additional hardware, or broader tech stack components are described in the available content. Drive's core value proposition is straightforward: it makes the phone you already carry into a vehicle telemetry rig, capturing g-force, braking, and cornering traces without a wiring loom, dongle, or laptop, while also flagging license plate reader cameras as you approach them. Free to start and requiring no sign up, it lowers the barrier to measuring your driving to essentially nothing. It is, in the maker's own words, just driving fun.
Wealthfolio is a private, open-source investing and personal finance app that runs locally on all your devices. It lets you track holdings, performance, allocation and income across your accounts, follow your net worth, understand your spending, and plan for goals and retirement. The product is aimed at people who want to grow their wealth while keeping control of their financial data, and its core app works without an account or a subscription. Wealthfolio is available on desktop, iPhone and iPad, and can also be self-hosted so you can access it through a web browser on infrastructure you control. The project describes itself as a beautiful, private and open-source investing and personal finance app that runs locally. The problem Wealthfolio addresses is the trade-off many people face between useful financial software and control over sensitive data. Traditional money apps typically require an account and keep financial history in a cloud platform, which means your financial history becomes dependent on another service. Wealthfolio takes the opposite approach: it runs locally, works without an account, and keeps your financial history under your control. The project is also open source, so the code can be inspected, contributed to and run on infrastructure you choose, and users are not forced to create an account or commit to a subscription before they can start. In the investments area, Wealthfolio brings all your brokers and banks into one view. You can track holdings, performance, allocation and income across your accounts, and import CSV statements from anywhere, which means data from a brokerage or bank that is not automatically supported can still be brought into the app. Portfolio Insights help you understand your asset allocation, sector exposure and geographic distribution, so you can see how your money is spread rather than just what it is worth. A Performance Dashboard lets you compare accounts and benchmark against the S&P 500 or any ETF. Allocation Targets & Rebalance let you set target weights, see your drift and get a clear rebalance plan, while Income Tracking follows dividends and interest income across your entire portfolio. Net Worth Tracking pulls all your assets and liabilities together so you can see your complete financial picture over time, rather than looking at individual accounts in isolation. The Spending & Budgets area tracks cash flow, auto-categorizes transactions and helps you build budgets that fit you. Together these tools let you follow both sides of your finances: what you own and what you owe, and where your money is going month to month. Planning tools cover both long-term retirement and shorter-term goals. The Retirement & FIRE Planner provides a year-by-year simulation with a Monte Carlo Risk Lab and a dedicated FIRE mode, so you can model how a plan might evolve under different conditions rather than relying on a single projection. The Goals & Save-Up Planner projects savings to a target with a milestone glide path and an on-track status, which makes it easier to see whether you are moving toward a specific purchase or savings milestone. Contribution Limits help you stay on top of IRA, 401(k) and TFSA contribution room, so you do not lose track of how much you have already contributed or how much room remains. Architecturally, Wealthfolio keeps a local database on your device where accounts, transactions and history are stored. You can install it directly as a standalone application, or self-host it with a Docker deployment and access it through a browser. Wealthfolio Connect is not a third way to run the app; it is an optional paid service that adds automation and synchronization on top of a standalone or self-hosted setup. Connect automatically imports from your brokerages through aggregators such as SnapTrade and keeps your Wealthfolio database in sync across devices. The core app remains fully usable on its own, with manual accounts and transactions, CSV imports and local data ownership. The main benefit is keeping your financial life under your control. Because the app runs locally and works without an account, your financial history stays on your devices instead of becoming dependent on another cloud platform. Because it is open source, you can inspect the implementation, follow development, contribute through GitHub, or run the software on infrastructure you control. Flexibility is another outcome: you can start free with manual tracking and add automation only when manually maintaining your financial data no longer makes sense. Typical use cases include importing CSV statements from a broker or bank to consolidate holdings in one view; tracking net worth across assets and liabilities over time; tracking cash flow and building budgets with automatically categorized transactions; comparing accounts and benchmarking returns against the S&P 500 or an ETF; setting target allocation weights and following a rebalance plan; and projecting retirement or FIRE scenarios year by year. Users who want everything in one always-available place can self-host with Docker and reach Wealthfolio from a browser, and households that want shared finances can use Connect's household sharing. Wealthfolio is available as a standalone install for macOS, Windows, Linux, iPhone and iPad, and as a self-hosted instance reachable through a web browser. The Wealthfolio app is free and open source and does not require an account, while Wealthfolio Connect is an optional subscription for automatic brokerage imports, encrypted device sync, household sharing, background updates and connection management. The project can be extended through add-ons such as the Investment Fees Tracker, Goal Progress Tracker and Stock Trading Tracker, and through custom price feeds for assets and markets not covered by the default providers. Supported AI and agent integrations are available through an MCP server, and an AI Assistant lets you ask questions about your portfolio. In short, Wealthfolio combines investment tracking, net worth tracking, spending and budgeting, and retirement and goal planning in one app that stores your data locally. It is free and open source by default, works without an account, and can be extended with automation through the optional Connect service. For anyone who wants a complete picture of their finances without handing their financial history to another cloud platform, Wealthfolio's primary value proposition is simple: grow wealth, keep control.
Mock Magic is a browser-based device mockup generator for images and video. It lets you upload a screenshot or a screen recording, drop it into a realistic device frame — an iPhone, iPad, MacBook, Android phone, desktop monitor or smartwatch — and export the result in high resolution within seconds. The tool is built for designers, developers, freelancers and marketing teams who need to present apps, websites and digital products inside convincing device hardware. Everything runs in the browser: there is nothing to install, and no Photoshop or After Effects is required. The site positions the product simply as a way to create beautiful device mockups — upload your design, select a device, and download your mockup in seconds — with unlimited free image mockups and video mockups available on the paid subscription. Most mockup tools stop at images. That is the gap Mock Magic was built to close: a static device frame is often enough for a screenshot, but apps, websites and digital products increasingly need motion — a screen recording wrapped in a phone frame, an animated product demo inside a laptop, a short branded clip for a launch. Producing that kind of device video has traditionally meant heavyweight desktop software such as Photoshop or After Effects, plus the skills, licences and time to use them. Mock Magic removes that friction by moving the workflow into the browser and by supporting video sources alongside images. According to the product description, the tool turns a screen recording into a polished device video, in your brand colours, in the browser, in seconds — with nothing to install. Device coverage is one of Mock Magic's core strengths. The site says the tool supports 54+ device variants, spanning the latest iPhones, Android phones, iPads, MacBooks, desktop monitors and smartwatches, and that the library is constantly updated with new devices. Dedicated pages exist for individual device families, including iPhone mockups, MacBook mockups, iPad mockups, Android mockups, desktop mockups and smartwatch mockups, so visitors can start from the hardware they care about. Alongside raw device frames, Mock Magic offers a template library. Templates cover different orientations, single-device layouts and multi-device compositions, so you are not limited to one screen in one position. Some templates are included in the free plan, while premium templates with advanced layouts and features are available exclusively to Pro subscribers. The site describes templates as a way to create professional-looking mockups with minimal effort. Backgrounds are optional but well covered. Mock Magic lets you highlight your design against a solid colour or a gradient, and both options sit behind the device frame rather than competing with it. Customisation goes further than presets: you can choose your own background colour using a colour picker, or upload your own background image. Custom backgrounds are saved to your account so they can be reused in future mockups, which makes it practical to keep a recurring brand backdrop on hand instead of rebuilding it each time. The product description also mentions setting a brand colour with a hex code, which suits teams that work from a defined palette. In short, the background system is designed to help you create the perfect setting to showcase your design, whether that setting is a plain colour, a gradient, or an image of your own. Mock Magic handles both still and moving content. Images can be added on the free plan, while video mockups are a Pro feature. Supported image formats are PNG, JPG and SVG; supported video formats are MP4 and WebM. All mockups — image or video — can be downloaded in high resolution, and the site promises high quality exports. Video support means moving content renders inside the device frame rather than being flattened into a screenshot, which is what makes an app promo video or an animated landing page asset possible. The other half of the workflow is repeatability. You can save your device selection, background choice and template preference as default settings, so every new mockup starts with your preferred options already selected. The Product Hunt listing frames the same idea as presets: save your setup once and reuse it, so every mockup for your app store, website or socials matches. The workflow is deliberately short. You start by uploading a screenshot or screen recording into the browser editor at Mock Magic's studio. Next you pick a device frame from the 54+ variants, choose a template if you want a particular orientation or a multi-device composition, and set a background — a solid colour, a gradient, a hex-code brand colour, or an uploaded image. Then you export in high resolution and download. The distinctive part is what happens after that first export: Mock Magic remembers your setup. Device selection, background and template can be saved as defaults, and presets let you reuse a branded configuration for future files. That turns mockup production from a one-off design task into a repeatable, consistent process that lives entirely in the browser, with no installable software in the loop. The benefits follow directly from that workflow. Speed: the site repeatedly describes exports in seconds and a process that takes a few steps — upload, select a device, download. Consistency: saved defaults and presets mean a series of mockups shares the same device, background and layout, which matters when assets sit next to each other on a store listing, a landing page or a social grid. Accessibility: because the tool is browser-based, there is no Photoshop or After Effects licence, no install, and no specialist motion-design skill implied. Cost: unlimited image mockups are free, and video mockups are available on the Pro plan at €7.99 per month. Quality: exports are high resolution, whether the asset is a static screenshot or a moving device video. Mock Magic lists typical applications for device mockups, and they map closely to its features. App Store screenshots are the classic case: a phone frame in the right orientation with a branded background. Social media posts reuse the same assets in different formats. Landing page hero images benefit from the desktop and laptop frames, and from gradient or solid-colour backgrounds that blend into a site design. Pitch decks use device mockups to make a product feel tangible during a demo or investor presentation. App promo videos are where video support earns its keep: a screen recording placed inside a phone or laptop frame becomes a moving product demo rather than a static picture. The Product Hunt listing adds a related scenario — turning a screen recording into a branded device video using a saved preset, so a whole series of clips shares one look. Mock Magic names its audience directly: designers, developers, freelancers and marketing teams. Anyone who needs to present an app, website or digital product inside device hardware fits the description, and the free image tier lowers the barrier for individuals testing the tool. Pricing is split between a Free plan and a Pro plan at €7.99 per month. The pricing section lists device selection, background colours and gradients, high-quality export, saved selections, unlimited video mockups, Pro templates and custom background image uploads against both plans; the FAQ clarifies the intent, stating that image mockups are unlimited and free, that video mockups are a premium feature for paid subscribers, and that premium templates with advanced layouts are available exclusively to Pro subscribers. Access is browser-based through the Mock Magic studio. For anyone who needs device mockups without a design suite, Mock Magic condenses the job into a browser tab: upload an image or a screen recording, choose from 54+ device variants, dress it in a branded background, and export in high resolution. Templates cover single-device and multi-device layouts, saved defaults and presets keep a series of assets consistent, and video support on Pro turns screen recordings into finished device videos. Free unlimited image mockups make it easy to start, and €7.99 per month unlocks video and premium templates. The result is faster, more consistent product presentation — built for app stores, websites, socials and pitch decks.

Viso Now is a self-building AI vision platform that turns images, video, and camera feeds into working computer vision applications. Instead of training models, annotating data, or writing code, users describe in plain language what they want to understand, and Viso Now builds the agentic vision logic and custom live dashboards for them. The platform is aimed at teams and individuals who need to solve real-world visual problems across industries such as construction, manufacturing, logistics, healthcare, food and beverage, oil and gas, hospitality, and transport, and who want to create, run, and manage entire computer vision products and systems from scratch on one platform. Traditional computer vision projects depend on model training, data annotation, and custom software engineering. That work is slow, expensive, and hard to maintain, and it often results in isolated, single-purpose solutions that address one use case at a time. The website states this directly: not all computer vision is equal, and isolated solutions are no longer enough. Viso's stated answer is a platform that drives business capabilities rather than leasing a single outcome that solves a single use case, offering flexibility, extensibility, and complete control of data across multiple locations. Because prompt-driven building removes labeling and model maintenance, the platform reports 90% less ML engineering effort compared with conventional approaches, along with an 85% reduction in the time-to-value of computer vision applications. At the center of Viso Now is prompt-based application building. A user describes the real-world situation they want AI to solve in plain language, and watches as Viso builds the application with them in real time. No model training and no annotation are needed. Each build produces agentic vision logic together with a custom live dashboard, so the result is not simply a detection model but an application that can be monitored and operated. The product page describes prompt-to-live-vision-agent in minutes and Visual General Intelligence for any use case, meaning the same engine is applied regardless of the industry or the problem being addressed, and applications connect seamlessly to other systems. Viso Now accepts multiple kinds of visual input. Users can click to upload or drag video files in MP4, MOV, or MKV, and images in PNG or JPG, or they can capture media directly using a device camera by taking a photo or recording video. When building, users choose how much effort the system applies by selecting between Fast, Balanced, and In-Depth modes. They can also start from a template or an example instead of a blank prompt. Once a draft application exists, users iterate on it until they are happy with the finished solution, and then go live by connecting cameras or uploading connectors so the application can be used immediately. The platform provides a template gallery of ready-made vision applications that illustrate what can be built. Templates include Task-Aware PPE Check, Excavator Near-Miss Monitor, Hot Work Safety Check, Work-at-Height Safety Check, MEWP Fall Protection Check, Clinical PPE Protocol Check, GMP Hygiene Check, Loading Dock Exclusion Zone, Dock Turnaround Intelligence, Front Desk Wait Tracking, Check-in Queue Orchestrator, Restricted Site Vehicle Alert, Hazardous Area PPE Check, Pipeline Integrity Scout, Visible Release Detection, Robot Cell Intrusion Detection, Production Area Access Check, 5S Shop Floor Audit, Emergency Exit Clearance, Reversing Vehicle Danger Zone, HSE Workplace Audit, Commercial Vehicle Safety Screening, Dump Zone Safety Inspector, Abandoned Luggage Response, Handling Risk Assessment, and Service Queue Pressure Analysis. Each template describes the assessment it performs — for example assessing truck handling performance at loading bays, or tracking whether a warehouse is safe, clear, and compliant for operation. Viso handles the end-to-end infrastructure behind these applications, from compute and visual analysis to governance, authentication, and integrations, so teams do not have to assemble and maintain that stack themselves. The offering is organized as two products on one platform. Viso Now is the free entry point with no credit card required; it is free forever, users can invite their team, and sign-up works with Google, Microsoft, or an email address. Viso Suite is the enterprise product for running vision intelligence at the scale of an operation: 10,000+ cameras across hundreds of sites, a full lifecycle of build, deploy, govern, and scale, edge AI with on-premises or cloud support, and compliance with SOC 2, ISO 27001, GDPR, and CCPA. Overall, Viso Now follows a describe, build, refine, and operate workflow. A user uploads or captures media and describes the situation they want the AI to solve. The system then generates agentic vision logic and a live dashboard in real time, so the application is visible and testable while it is being created. The user iterates until the solution matches the requirement. Going live is a matter of connecting cameras or uploading connectors, at which point the application runs continuously. Because Viso manages compute, visual analysis, governance, authentication, and integrations, the same platform supports building, running, and managing complete computer vision systems, and the enterprise tier extends that approach to governed applications and agentic workflows across many sites. Viso states a number of outcomes for users. Visual data can be understood ten times faster, to drive efficiency, automation, and innovation. The company reports an 85% reduction in time-to-value of computer vision applications and a 90% reduction in ML engineering effort, since there is no labeling and no model maintenance. A customer story describes a global manufacturer that replaced four point solutions with one Viso deployment and saw near-miss incidents fall 54% within 90 days, with the safety team spending zero hours rebuilding models. The platform is described as giving 24/7 eyes on every camera that never blink and never tire, and as running AI vision ten times faster than other methods. PwC is quoted saying that building computer vision applications with Viso Suite allows them to deliver business value faster and easier, while Stadt Schaffhausen notes that Viso Suite let them integrate existing camera and software systems across platforms while meeting strict privacy requirements. The applications listed on the site show the practical range of use cases. In construction, templates cover PPE compliance, near-miss monitoring around excavators and plant, hot work safety, work-at-height checks, and MEWP fall protection. In manufacturing, they cover robot cell intrusion detection, production area access checks, 5S shop floor audits, emergency exit clearance, and handling risk assessment for lifting tasks. In logistics and warehousing, they cover loading dock exclusion zones, dock turnaround intelligence, and warehouse HSE audits. In healthcare, they cover clinical PPE protocol checks and service queue pressure analysis; in food and beverage, GMP hygiene checks and foreign object detection; in oil and gas, hazardous area PPE checks, restricted site vehicle alerts, pipeline integrity scouting, and visible release detection; and in hospitality and transport, front desk wait tracking, check-in queue orchestration, airport baggage detection, and abandoned luggage response. Customer stories reference worksite safety for a rail group, safety and compliance oversight for a global food retailer, PPE detection for a leading oil company, and crowd safety at a major annual event. Viso Now is designed for people who need vision AI but do not want to run a machine learning program — operators, safety and compliance teams, and builders who want to turn an idea into a working vision agent quickly. The free tier requires no credit card and allows inviting a team. Enterprise customers move to Viso Suite for camera fleets at scale, governed applications, edge, on-premises or cloud deployment, and formal compliance certifications. Access is through the web, with sign-in via Google, Microsoft, or email. The company reports that its platform covers 136+ applications tuned for every industry, all running on the same Visual General Intelligence engine, and states that it is trusted by Fortune 500 organizations, with customer logos including Enpro, Vinci, CPI, Intel, Rhomberg, and Datwyler. Viso Now's core promise is that if you can describe it, you can build it. By removing model training, annotation, and coding from the computer vision workflow, and by generating agentic vision logic and live dashboards from a plain-language prompt, the platform lets teams go from an idea to a running vision agent in minutes and then scale the same approach across many cameras and sites with Viso Suite. The result is faster time-to-value, far less ML engineering effort, and continuous, tireless monitoring of the physical world — detecting, inspecting, alerting, and understanding — without assembling a large specialist team.

Thousand is a documentation engineering platform that provides git-backed docs for both humans and AI agents. It is built around a single markdown repository that supports folder-level access control, so every reader gets a workspace shaped exactly like their permissions. The product is designed for teams that want their documentation to serve a post-AI workforce, where teammates, outsiders, and AI agents all interact with the same source material. Thousand positions markdown as the document format, ensuring that a human reads the same bytes as a document that an agent reads as markdown. There is no export step and no second copy that can drift from the original. The platform addresses a fundamental limitation of markdown and git when used for documentation alone. Git traditionally shares all or nothing, which means access control at the folder or path level is not natively supported. At the same time, half of a typical team will never open a terminal, yet they still need to read and edit documentation. AI agents introduce another class of reader that requires programmatic access with expiring credentials. Thousand solves these problems by adding path-level access control on top of a markdown repo, enforcing rules even for readers who never touch git. It also provides a document editing experience for non-technical teammates while preserving clean markdown on disk. A core capability of Thousand is that one file is first-class for both readers. A teammate sees the markdown as a formatted document, while an agent reads the same bytes directly. This eliminates export and prevents copy drift. The platform enforces path-level access control through access rules. For example, admins can be granted write access everywhere, a design folder can be writable by a specific person, an engineering folder by another, a notes folder readable by an agent named summarizer-bot, and a marketing folder readable by the team. If no rule matches a path, the content remains hidden. These rules are enforced for all readers, regardless of whether they use git. Thousand can sync every codebase’s context into one place. Each repository’s docs folder mirrors into the workspace on every commit, read-only and stamped with its source. Because nobody maintains a copy, the documentation never rots. For teammates who never open a terminal, Thousand offers a document editor that lets them edit markdown without seeing markdown. They write in a familiar interface, but the file on disk stays clean markdown, and every save becomes a named commit. Any document can also be sent to someone who has no account: it becomes a link that opens in their browser, requiring no sign-up on their side, while the owner retains a revoke button. Comments in Thousand never touch the document file itself. Threads live beside the document, not inside it, and are saved as markdown that a clone carries too. This keeps the source clean while preserving discussion context. The platform also handles decks and PDFs: Office files and PDFs render in place and are searchable by what they say, not just by filename. Beyond prose, Thousand supports drawings and tables as first-class files in the repo. An Excalidraw canvas or a CSV table opens ready to edit under the same access rules as everything else, so structured and visual content remains governed by the same permissions model. An agent is treated as a member of the workspace, not an add-on. A bot gets its own name, its own folders, and a token that always expires. The profile card acts as a preflight check, showing exactly what the agent can access. Tokens are shown once and die with the agent. A Thousand workspace can also tidy itself: duplicates, stale drafts, and dead ends get swept out on a schedule, but nothing is removed without a human merging the change. Thousand keeps company with your remotes. It acts as one more remote on the same repo, so it works alongside GitHub or GitLab without conflict. For agents, the site answers markdown when requested, serving /AGENTS.md instead of a page built for eyes. Thousand’s approach is fundamentally git-backed and markdown-native. The workspace is a git remote: you can add it to an existing markdown repo, push, and retain history. Access rules are defined per folder or path, and the platform filters what each reader sees. Humans interact through a document editor or a reading view, while agents interact through tokens and markdown endpoints. The same repository powers all readers, with access control enforced at the path level. This means the repo remains the single source of truth, and the platform adds boundaries without creating a proprietary format or a separate copy of the content. The primary benefit is that documentation can serve both people and agents without sacrificing control or cleanliness. Teams avoid exporting content or maintaining duplicate copies, so documentation does not drift. Non-technical teammates can contribute without learning git or markdown syntax. External sharing is simple and revocable, with no account required for the recipient. AI agents get scoped access with expiring tokens, reducing security risk. The self-tidying workspace keeps documentation current by surfacing duplicates and stale files for human review. Because the repo is yours, there is no lock-in: a git clone yields the same files, same history, and same markdown. Concrete use cases include internal team documentation such as budgets, forecasts, and board notes, where folder-level access ensures only the right people see finance or legal content. Engineering teams can mirror codebase docs from multiple repositories into one workspace, keeping context synced on every commit. Marketing and design teams can collaborate on pricing pages and assets with comment threads that stay beside the document. Companies can share decks or PDFs with external parties via revocable links. AI agents can be given read access to specific folders for tasks like summarization, while their tokens expire automatically. Teams already using GitHub or GitLab can add Thousand as an additional remote without disrupting existing workflows. Thousand is for teams that rely on markdown documentation and need real access control, especially those working alongside AI agents. It suits organizations where some members are highly technical and others never open a terminal. Integration points include GitHub and GitLab as remotes, and agents that consume markdown via HTTP with an Accept header. The tech stack centers on markdown and git, with support for Office files, PDFs, Excalidraw canvases, and CSV tables as repo files. Pricing is free while Thousand is early, and the exit policy is explicit: git clone is always the whole exit. In summary, Thousand provides documentation engineering with plain markdown, real boundaries, and one clone to leave, making it a git-backed documentation platform for a post-AI workforce.

FreeScan.app is a website audit tool that reviews any public URL across SEO, AEO, GEO, website security, accessibility, and design. It is built for builders, developers, and site owners who want to know what is hurting their visibility, trust, and conversions. A single scan runs 40 focused checks and returns scores, supporting evidence, prioritized fixes, and insights. The free audit requires no signup and no private access, so anyone can paste a public page and immediately see where the page stands and what to work on next. The stated purpose is to uncover problems and missed opportunities and turn them into an actionable plan rather than an unexplained score. Most site owners do not know which specific issues are holding a page back. Auditing normally means piecing together separate tools for SEO, security headers, accessibility, and design, then interpreting raw output without context. FreeScan.app addresses that fragmentation by running discoverability, security, accessibility, design, and page quality checks in one focused scan on one public URL. Every finding is paired with evidence and an explanation of why it matters, so the user can decide what to fix first. The site positions this as a way to stop guessing whether a page is crawlable, secure, accessible, clearly designed, or ready to convert before a launch, campaign, or SEO push. Running the free audit is deliberately simple. You paste any public page URL and start a scan without signing up or granting private access. The scan performs 40 focused checks across discoverability, security, accessibility, design, and page quality. Results are presented as four category scores — SEO / AEO / GEO, security, accessibility, and design — that can be compared side by side, plus an overall view. The report bundles scores, supporting evidence, prioritized fixes, and insights into one shareable audit report. Results are organized into three action-ready views: Fixes, which shows what is costing points, why it matters, and what to change first, ordered by impact; Opportunities, which surfaces high-leverage ways to improve visibility, trust, usability, and conversion beyond failed checks; and Insights, which explains what the page already does well, backed by rendered checks, schema, previews, and page signals. The SEO, AEO, and GEO portion of the audit covers technical SEO and answer-engine readiness. It reviews titles, meta descriptions, headings, canonical tags, robots.txt, sitemap.xml, structured data, Open Graph, internal links, llms.txt, and answer-ready page structure. The stated goal is to see whether the site is structured for search engines and AI answer systems to understand it. Pro extends this into site-wide AI visibility, where FreeScan.app looks for crawler blocks, content gaps, and citation-readiness issues across scanned pages, showing what needs attention for search and AI discovery. For teams tracking how generative and answer engines surface their content, these checks translate directly into specific pages and specific problems rather than a general recommendation to improve SEO. The security checks look at public website signals visible from the page: HTTPS, mixed-content indicators, common public security headers, insecure forms, sensitive file exposure, and cookie flags. The accessibility fundamentals check finds missing alt text, form labels, heading-order problems, landmark gaps, unclear controls, language issues, contrast risks, small tap targets, and rendered accessibility errors. The design evaluation is conversion-focused, assessing hero and CTA clarity, content density, trust signals, mobile viewport setup, readability, spacing, visual hierarchy, runtime health, performance, and layout stability. FreeScan.app is explicit that this is a focused public-page audit and not a replacement for expert SEO strategy, penetration testing, accessibility certification, or analytics, so the checks should be read as signals and starting points rather than formal certification. The methodology centers on evidence over totals. Instead of returning a single number, FreeScan.app attaches supporting evidence to each finding, explains why it matters, and states how to fix it — the site describes this as turning audit results into clear next steps. Findings are ordered by impact so the highest-value work is visible first, and the report includes practical next steps for every result, along with opportunities and insights derived from rendered checks, schema, previews, and page signals. Because the output is framed as fixes plus explanations rather than vague advice, results can be handed to a coding agent. Builders in community testimonials describe running a scan, giving the results URL to their agent, reviewing the pull request, and shipping — with accessibility scores moving from 72 to 100, or an overall page score going from 40 to 86 after working the list. FreeScan Pro is a single plan at $19 per month, cancellable at any time, that moves from a single page to the whole site. Pro runs automated site-wide audits and organizes results into SEO, AI Visibility, and Fixes workspaces in one private dashboard. A site-wide fix board groups findings from across the site into a prioritized board where you can see affected pages, track each fix, and give your agent the evidence to act. Agent workspaces let you export full SEO, AI Visibility, and Fixes workspaces as Markdown, and Pro MCP lets a coding agent read private findings and request rescans. Pro also audits key pages automatically each week, sends email reports, compares progress, monitors uptime, and supports an optional shareable status page. Stated limits include up to 60 baseline and 25 recurring pages, five sites, and five manual scans per week per site. FreeScan.app also publishes a leaderboard of the highest scoring Pro homepages, ranked by each website's latest homepage audit. Users come to FreeScan.app to find out what a page is missing and exactly what to fix. The stated outcomes are improved search rankings, AI visibility, user trust, and conversions. Because each failed check includes evidence and a concrete fix, teams can turn audit output into a work list — one testimonial describes shipping against the list like a sprint backlog and reaching 100 out of 100 across SEO/AEO, security, accessibility, and design. Pro adds tracking so you can see what improves and catch new issues as the site changes, with weekly audits, progress comparisons, uptime monitoring, and downtime alerts. Public, shareable audit reports also make it easy to show progress before and after a fix cycle. Together these turn a one-time score into an ongoing improvement loop for visibility and trust. The most obvious use case is running the free audit before a launch, campaign, or SEO push, so you do not guess whether a page is crawlable, secure, accessible, and ready to convert. Another is remediation with coding agents: scan a page, hand the findings or the results URL to an agent such as Claude Code, apply the suggested fix, and rescan to confirm. Teams also use it to check a single public URL for SEO, security, accessibility, and design issues and see what to fix first, and to review answer-engine and AI visibility signals such as llms.txt, structured data, and crawler access. For ongoing operations, Pro supports weekly site-wide audits of key pages, a fix board for tracking work across the site, and uptime monitoring with a shareable status page. FreeScan.app also publishes practical guides on website audit checklists, technical SEO audits, and auditing a SaaS website safely. The product targets builders, developers, indie makers, and website owners who ship sites and want fast, evidence-backed feedback, including teams working with coding agents. The audit is a web-based, public-page tool: you paste a URL and it scans, with no signup required for the free check. Pro is priced at $19 per month with cancellation at any time and covers up to 60 baseline and 25 recurring pages, five sites, and five manual scans per week per site. Integration points explicitly described are Markdown export of SEO, AI Visibility, and Fixes workspaces, connection through Pro MCP so agents can read private findings and request rescans, weekly email reports, and an optional shareable status page. The site also notes the tool complements rather than replaces expert SEO strategy, penetration testing, accessibility certification, and analytics. FreeScan.app gives anyone a fast, free way to see what a public page is missing across SEO, AEO, GEO, security, accessibility, and design, and exactly what to fix first. The free 40-check audit runs without signup and returns four category scores, prioritized fixes, opportunities, and insights in one shareable report. Pro at $19 per month turns that into whole-site monitoring: automated weekly audits, a unified fix board, agent workspaces and MCP access, private scan history, and uptime monitoring with status pages. For builders who need to know whether a page is crawlable, secure, accessible, and ready to convert — and who want evidence they can hand straight to a coding agent — FreeScan.app packages discovery, diagnosis, and next steps into one workspace.
Gojo is a macOS app that puts the everyday tools you reach for inside the MacBook notch. Instead of living in the menu bar or behind a buried shortcut, the app turns the notch into a control surface you reach by hovering, and it gathers dictation, window snapping, clipboard history, a file shelf, music controls and screen warmth into that one place. It is built for people who work on a MacBook every day and want fast access to the small utilities they constantly reach for, without installing and maintaining a separate app for every job. The website frames it simply: everything you reach for, right in the notch — dictation, window snapping, clipboard history, a file shelf, music and screen warmth — "one surface, always a hover away." Gojo is described as one native workspace covering all of those jobs. Every long-time Mac user accumulates a stack of single-purpose utilities, and the Gojo website names them directly: Boring Notch, Maccy, f.lux, Rectangle and Dropover. Each of those apps handles one distinct job — a notch overlay, clipboard history, screen warmth, window management and a file shelf — and each arrives with its own menu bar icon, its own settings pane and its own set of keyboard shortcuts to learn and remember. The problem Gojo identifies is the sprawl. As the site puts it, these jobs "usually mean a separate utility each, and a separate menu bar icon, settings pane and set of shortcuts to go with it." Gojo's answer is consolidation: it does all of those jobs from one surface you already have, replacing several downloads and several configuration screens with a single workspace that lives in the hardware you are already looking at. The site includes an independent feature comparison between Gojo and those five apps, and notes that Gojo is not affiliated with or endorsed by the products shown. The dictation feature is the centrepiece, and it is built around privacy. You hold one shortcut, ⌃ ⌥, and speak; when you release it, the words appear wherever your cursor already is — in Mail, Slack, a commit message or a search box. Speech recognition runs on a model you download once, so there is no API key and no account required, and the site states that no audio ever leaves your Mac. Because recognition is local, dictation still works on a plane. You choose your model during setup and can swap it later, and it runs offline on-device every time. The site's own screenshot shows that model list: Parakeet Unified from FluidAudio, 614 MB, marked as in use on that Mac, with Parakeet v3 available below it. The point the screenshot makes is that models live on your Mac locally and you can see exactly which one is doing the work, rather than trusting a black box in the cloud. Media controls move your music out of the way. Artwork, the track title and a scrubber sit in the notch, so you can skip, shuffle and seek whatever is playing without raising a window and losing your place. Gojo follows your current media source, and it lets you reorder the controls you actually use, so the buttons you care about sit where you want them. A screenshot shows the notch open on the media tab with album art, the track "Sunset Linen" by LoFi Serenity, a scrubber and playback controls, with a Spotify badge on the artwork. Alongside it sits Night Shift, which gives you a warmer screen after dark on your own schedule, controlled from the notch instead of System Settings. Sunset times are worked out on your Mac from a location you set once, and that location is used locally and never sent anywhere. Night Shift can start with your Mac if you want it to, and the site includes an interactive comparison — drag the divider to compare the same screen with Night Shift off and on. The clipboard tab keeps everything you have copied. Every item you copy is saved and searchable from the notch, so you can find that thing you copied ten minutes ago without opening another app or switching context. Anything a supported password manager marks as private is skipped, which means passwords and secrets stay out of your history rather than piling up in a list you might later paste into the wrong place. Search happens right in the notch, in a search field above a list of recently copied text entries, so retrieving an old snippet is a hover and a few keystrokes rather than a trip through another utility. The shelf solves the problem of holding files while you move between places. You drag files to the notch and they wait there while you move between folders, desktops and apps, then drag them back out when you arrive — or send them straight to AirDrop. The shelf survives folder, Space and app switches, so a file you picked up in one Space is still staged when you land in another, and an AirDrop target is built into the shelf itself. A screenshot shows the shelf tab with an AirDrop drop target beside two staged files waiting to be dragged out. Window management gets the same treatment. Gojo includes a switcher that shows you the window before you land on it, replacing ⌘ ⇥ with per-window previews, so you can confirm you are choosing the right document or terminal before you commit to the switch. It also provides a snap grid with the shortcut printed under every layout: halves, thirds, maximize and zoom. Because the keyboard shortcut is labelled on the layout itself, you are not guessing or memorising combinations — the grid doubles as a reference. A screenshot shows the windows tab with a list of open apps, a live preview pane for Ghostty, and a grid of six snap layouts each labelled with its keyboard shortcut. Gojo also invites you to make it yours. You can use all six tools or just one: turn off what you do not need, reorder the rest, and the notch stops showing what you have disabled, tabs included. Beyond the six main tools, the notch can also host optional extras if you switch them on — Spotlight-replacement search on ⌥ Space, a calendar and next-event glance, battery and charge state, a camera mirror for checking your framing before a call, shortcuts you already built, and brightness and volume HUDs. Overall, Gojo's approach is to treat the notch as a single surface for controls that are otherwise scattered across menu bar apps and System Settings. You hover to reach it, tabs separate the individual tools, and everything is configured from one place with toggles and reordering so the surface only shows what you actually use. The dictation model runs locally on the Mac, and location data used for Night Shift is also local. The app is native to macOS and requires macOS 14 or later, and the download is offered as a three-day free trial with no card and no account required. The outcome for users is less clutter and less context switching. Instead of keeping five utilities running with five menu bar icons and five sets of preferences, you keep one app that covers dictation, windows, clipboard, files, media and screen warmth, and you turn off the parts you do not want. Because dictation never leaves the machine, you can dictate sensitive work and still stay private, and because the shelf and clipboard persist across Spaces and apps, small interruptions stop costing you the thing you were carrying. Concrete scenarios show up throughout the site. You dictate into whatever field you are already in — composing a reply in Mail, a message in Slack, a commit message or a search box — by holding ⌃ ⌥ and releasing when you are done. You paste a snippet from clipboard history by searching the notch instead of retyping it. You pick up a file in one folder, work across several Spaces, and drop it into AirDrop at the end without losing it in between. You preview a window before switching to it, then snap it to a half, a third, maximize or zoom. You skip, shuffle or seek a track without pulling a player window forward, and you let Night Shift warm the display after dark without opening System Settings. Gojo is aimed at MacBook users on macOS 14 or later who want their everyday utilities in one place and prefer speech recognition that runs on-device rather than in the cloud. Pricing is available for either one Mac or up to three Macs, and every plan includes the full app and all future updates. On the personal, single-Mac tier there is a monthly subscription at $2.99 per month, or a lifetime licence originally $14.99 and now $9.99 as a one-time payment. On the multi-Mac tier covering three Macs, the subscription is $4.99 per month, or a lifetime licence originally $24.99 and now $19.99 one time. A three-day free trial is available with no card and no account. The takeaway is straightforward: Gojo consolidates the small tools Mac users reach for dozens of times a day — private local dictation, clipboard history, window switching and snapping, a file shelf, media controls and Night Shift — into the MacBook notch, one surface that is always a hover away.
Typewise Nova is an AI customer experience platform that businesses use to run AI agents resolving customer service requests end to end across email, chat, WhatsApp and social. Nova, described as the AI Operator, builds and improves an AI customer experience team without a developer. Agents resolve whole requests — from orders and refunds to plan changes — across email, chat and WhatsApp, while the team stays in control. It is built for modern customer teams, from small and mid-size businesses just getting started to enterprises running support at scale, and it helps them boost customer satisfaction and reduce costs with next-gen AI they can trust. Traditional CX platforms and chatbots are measured on deflection rather than resolution, and running them typically requires an IT or dev team, with total cost described as $$$. Typewise positions itself differently: it is a resolution engine, not another chatbot, and it is measured on resolution. Rather than deflecting a customer, it completes the whole request — looking up the order, applying your policy, closing the ticket — and hands anything needing judgment to a person with full context. Typewise began in 2019 as a consumer keyboard app; that chapter closed in 2022 when the company joined Y Combinator and moved to business software. Today it is solely an AI customer experience platform for businesses. At the center of the platform is Nova, the AI operator that sets everything up. You describe in plain language how customers should be handled and connect your tools, and Nova builds the agents, tests them on past tickets and shows you what failed before anything goes live. There are no flowcharts, no code and no waiting on IT. Nova runs on conversation: asking 'Nova, create a specialist for billing & payments' produces a drafted Billing & Payments specialist that reads Stripe and your order system, with refunds over €100 kept human-approved. 'Nova, update the returns policy from this doc' recognizes that the return window goes from 14 to 30 days and that opened items are now eligible, and can update the specialist and the help-center article. 'Nova, connect WhatsApp as a support channel' prepares to connect WhatsApp Business with the same rules as email and chat, running a test message first. 'Nova, why did refund tickets spike this week?' reports that refunds are up 38%, mostly citing 'wrong size' after Tuesday's size-chart update, and offers to draft a reply macro. The workspace brings AI agents and human agents together in one place. A supervisor routes each request to the right specialist, works across your systems, brings in a person when it matters, and picks the ticket back up. The ticket view displays fields including Ticket #, Title, Customer, Channel, Priority, Status, CX score and Assigned to, with statuses such as 'AI resolving', 'AI asking an agent' and 'Done'. This lets teams see at a glance which requests are being handled autonomously and which have been handed to a person, while keeping every conversation visible in a single queue. Typewise meets customers where they already are. Support can start on Chat, Email, WhatsApp, Social, Voice, ChatGPT, Claude or In-App, and customers can start anywhere, switch channels freely, and keep context end to end. Channels are not isolated, so a conversation can move between them without the customer repeating the request. The platform also handles any language in and out, so a request that arrives in one language can be understood and answered in another without changing how the customer gets in touch. The platform's approach is summarized in three steps. It resolves: looks up the order, applies your policy and closes the ticket. You decide: your rules apply, every action is logged, and you can pause anytime. It learns: quality is watched, fixes are proposed, and nothing ships untested. Nova is the AI operator behind this — describe what you want in plain language, and Nova builds it, tests it, and takes it live in about 15 minutes. Unlike a traditional chatbot rollout, setup is conversational rather than technical, and the system keeps improving after launch by monitoring quality and proposing fixes 24/7 for approval. Real teams report measurable outcomes. Beurer achieved a 90% resolution rate on autonomous cases, with its Head of Service Team noting that changing the AI instructions directly changes how the AI Agents behave. Lehner Versand saw 95% of chat requests resolved by AI, with its Head of Customer Service saying every request now comes together in one place while people stay involved where experience and approval are decisive. HealGreen reports 70% of inquiries handled by AI across channels, with its CEO describing connecting systems directly with Typewise as a game-changer and Nova as making onboarding incredibly fast. Across the platform, Typewise cites 10M+ tickets resolved, 3,500+ integrations and a rating from G2 users. Because unresolved requests are free, the model rewards actual resolution rather than volume. Concrete workflows on the platform include resolving refund and returns requests by looking up the order and applying policy, handling order tracking help, and processing plan changes end to end. Teams also use Nova to create dedicated specialists, such as one for billing and payments that reads Stripe and the order system, or to update policies and help-center articles from a document. Support leaders can investigate trends, such as a spike in refund tickets, and have Nova propose a reply macro for affected customers. Connecting a new channel like WhatsApp Business is another workflow, where Nova applies the same rules as email and chat and runs a test message first. Typewise serves two broad groups. Small and mid-size businesses can go live in 15 minutes with easy conversational setup, getting better every week as it learns the business, with no developer needed. Enterprises get ISO 27001, GDPR and EU AI Act compliance, approvals and clean human hand-off they control, guided onboarding, a dedicated support team, and connections to their stack through 3,500+ integrations spanning CRM, ERP and ITSM, as well as help desks, inboxes, commerce and internal systems. Nothing has to be migrated to get started. Pricing is success based: a monthly plan plus a per-resolution rate that drops as volume grows, where a fully resolved request counts once, a partial hand-off counts half, and unresolved requests are free. You can start free with a batch of free resolutions and no credit card, connect your own inbox, and see performance on real tickets before paying. EU data residency is available. Typewise Nova's core promise is end-to-end resolution without losing control. It replaces deflection-focused chatbots with a resolution engine that completes real requests across channels and languages, is built and improved by an AI operator in plain language, tests itself before going live, and keeps humans in the loop through logged actions, approvals and one-click pause. For customer teams that want to boost satisfaction and reduce costs with AI they can trust, Nova offers a fast, self-improving path to first-class customer experience with zero busywork.
