Image

The Age Of Altair

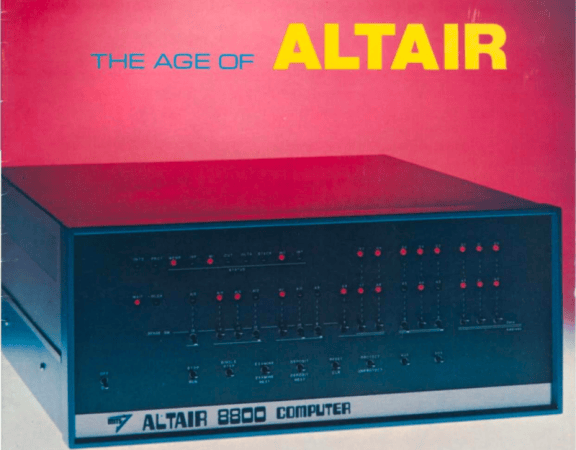
I recently got the Amazon Christmas toy book in the mail, and it is definitely the modern version of the Sears Christmas Wish Book for last century’s youth. Or at least the majority of last century’s youth. For the true hacker, we had a different set of wishes. Recently, I found something I’ve clung to for over 50 years: the 1975 “The Age of Altair” catalog from MITS. Now that was a wish book!

The poor thing has been dragged around for decades and, I’m sad to say, it looks it. It isn’t totally trash, but I decided I should scan it. Then I realized that Bitsavers has already done it for me and with a much nicer copy, too. The images in this post are from their scan instead.

About the Altair

Image
The magazine that started it all (World Radio History).

If your first computer ran Windows, you might not get the significance of the Altair. Back in 1974, the idea of having your own computer was practically ludicrous. Sure, Radio Electronics had published plans for the Mark 8 in July of that year. But it used an anemic 8008 CPU, and it wasn’t easy to get all the parts you’d need to build one. Other limited computers, like the Kenbak-1 or the occasional surplus minicomputer, ended up in personal hands. But you couldn’t just decide you wanted a real computer, plunk down some money, and have one delivered unless you had extremely deep pockets.

To stay on magazine stands longer, old print mags would come out earlier than their cover date suggested. The January 1975 Popular Electronics arrived, actually, in December of 1974 — just in time for the holidays. It showed a computer you could buy as a kit or assembled: the Altair 8800. Many of us were mesmerized by the idea of owning an actual useful computer.
Continue reading “The Age Of Altair” →

Image

Your Computer Memory Is A Lie

When you first learn to program, memory seems pretty straightforward. You have a bunch of bytes, each with an address. If you want to read or write something, you specify the address, and the computer goes to that place and does your bidding. Sure, some addresses might be reserved for hardware or the operating system, but the general idea is simple: memory is a big array of bytes.

Just like we pretend that a wire is a perfect conductor, the big array of memory model used to be a slight twisting of the truth. On a modern computer, however, it is almost entirely a lie. The address you use probably isn’t a physical address. The data you read might not come from RAM at all. Even if it does, it might be sitting in one of several caches. And if you follow the rabbit hole far enough, you discover that your SSD is arguably just another level in the memory hierarchy.

The Need For Speed

The fundamental problem is that processors have gotten much faster than memory. A modern processor can execute several instructions per clock cycle, but accessing ordinary DRAM can take hundreds of cycles. If the processor had to wait for RAM every time it needed data, much of that impressive computing power would go to waste.

The solution is caching. Keep copies of frequently used data in smaller, faster memories closer to the processor. Most modern desktop processors have at least three levels of cache. The L1 cache is tiny but extremely fast, and often split between instructions and data. L2 is larger and somewhat slower, while L3 is even larger and usually slower as well.

Continue reading “Your Computer Memory Is A Lie” →

Image

If At First You Don’t Succeed…

… at least document what failed and give the failure analysis a good effort. And then later on, you can “try, try again” or let someone else carry on with the work; they’ll have a good basis to start from.

We were talking about a project to use 10 W blue lasers to post-smooth 3D prints when I came up with this not-very-catchy catchphrase. The project itself is very much “in progress”, which is a nice way of saying that it hasn’t yet fully met its goals. But nonetheless I was entirely happy to watch not one, but two, videos where [I changed a thing] discussed the intricacies of laser-smoothing 3D prints, precisely because it sounds easy but absolutely isn’t, and because the problems were laid out so well.

I definitely take for granted how easy the slice-it-into-layers nature of FDM 3D printers makes path planning. After all, you can print interlocking knots, hinges, and even entire sections of chain mail as long as you only have to go one layer at a time. When you print this way, you never have to worry about the print head crashing into something that you’ve printed before, or being unable to reach into a small valley. To smooth two or more layers of a 3D print into each other, you are suddenly out of the comfy flatland. You have to worry about collisions, obstructions, and all the rest of actual 3D.

But those issues and more were carefully documented as [I changed a thing] went through his attempts at writing the software to drive the laser-augmented machine, and honestly that attention to the problems that were confounding him was worth a dozen “success” videos. In that sense, it worked on me a little like nerd sniping.

Those were my takeaways from the video series, then. One, it’s hard to do laser smoothing uniformly. But two, documenting the difficulties, considerations, and failures for your future self, or for others, is not just good practice, but can also encourage other people to help you with your project, or to take it on themselves. The more thought you put into how and why your project failed, the more bait you’re laying out for the next nerd. And that’s at least one part of what makes the open-source ethos work.

Image

Same As It Ever Was

Whether you like it or not, the use of LLMs to write code is kind of a big deal at the moment. We’ve been asking ourselves what, if anything, this means for us here at Hackaday. Should we try to figure out what percentage of a project was done by an actual human and how much was done by a machine? Does it really matter? What is our AI policy anyway?

Clearly, Hackaday is pro-human. We’re in it for the hackers as much as for the hacks. Our community is, like Soylent Green, made of people. It’s your inspirations and innovations that keep us reading and writing every day. And we produce 100% of our content the old-fashioned way, with projects selected through the taste and judgement of our writers, and their own words telling the story.

What about the hacks? We’ve seen a lot of projects recently that were coded with the help of an LLM. Does that diminish the work? In the end, what rings truest to us is what has always been Hackaday’s editorial guiding star: Is there something special in the hack that makes it worth talking about? Then we write about it. Was it written using vim or emacs? Did the author consult friends or a chatbot while working on the project? That’s not really relevant.

But in the past few years, the BS-generation machines have found our hobby, and we’re finding a lot more projects that don’t have any spark to them. We’re seeing circuits that make no sense, and claims that defy physics. Of course, we always have. The LLM-nonsense project is today’s version of the perpetual motion machines of old. Just like we never trust a hardware project that is all renders, seeing only AI-generated images is a huge red flag. It’s our job to separate out the wheat from the chaff for you all, but it’s something that you must be doing everyday as well.

We’ve seen amazing hacks over Hackaday’s 22-year history. Hackaday is older than YouTube and older than Stack Overflow. We’ve seen technology come and go. We’ve seen C-beams glitter in the dark near the Tannhäuser gate. (OK, maybe not.) And in the end, our AI policy is our same-old policy: we write up hacks that inspire us in the hope that they inspire you.

So if you’re using Claude to help you with the UI bits, or if you’re hand-writing it all in assembly, or wiring up the logic in diodes, we just want to see your cool hacks. And we hope that our collective signal will be so loud that we drown out the noise, at least in our own little corner of the hacker universe.

Image

AI Book Scanning: Just What Is A Rare Book?

One of the stories of the last few weeks has been that AI companies have been scanning books in very large numbers in order to train their models with content guaranteed to have been written before 2002, and thus AI free. It’s caused some outrage, because of the size of the operation, and because the scanning process is destructive. In particular the phrase being bandied around is that these are rare books, and it’s this phraseology I find problematic. I think it’s time to unpack why that is the case.

It’s Not Book Burning, Folks

Before I worked for Hackaday I had a long career in and around the publishing industry, mostly on the electronic side, but from time to time crossing paths with my colleagues in the world of paper-based publishing. I understand the appeal of a good book, I’ve spend a lot of my life among bibliophiles, and let’s just say I own a few books myself. In particular I understand the symbolism of destroying books, bringing to mind as it does the actions of repressive regimes. I have stood in Bebelplatz in Berlin where the photo of Nazi student organisation members burning the library of Magnus Hirschfeld’s institute was taken in 1933, and if you know me, you’ll have an idea why that’s close to home. But for all that, what the AI companies are doing is not the same thing.

In this case they’re destroying the books for two reasons. Firstly, as I remember from a previous employer in the publishing world, it’s much easier to digitise a stack of papers than it is a bound book. Thus I’m pretty sure that’s one reason they remove the binding before digitising the pages. Then secondly, as I understand it it’s a copyright issue. If they buy a book, digitise it, and destroy the physical copy, they can legitimately claim that only one copy of it exists, and they hope, sidestep copyright claims from publishers. Continue reading “AI Book Scanning: Just What Is A Rare Book?” →

Image

You Gotta Want It

On Hackaday last week, and on the podcast, we were talking about one of the educational toys of yesteryear that launched a thousand careers, at least if the comment section is to be believed: the Radio Shack 200-in-1 electronics kit. The “toy” itself was basically a bunch of components with spring terminals, but the secret sauce was in in the instruction book, and maybe the marketing.

ImageTom had one of these when he was a kid, and told a great story about wanting it desperately based on the ads he had seen with kids Morse coding to each other. When he got the kit, and found out that “it was just a bunch of wires” he was fully pissed off. But he worked through the examples, learned some basic electronics, and the rest is history.

What I really love about this story is the siren’s call of a good project. Tom was pulled in, and maybe even fooled, by the advertising, but it probably changed his life. It’s funny how many of our folks can remember the first project that got them hooked as well. With me it was some simple audio effects pedals and then maybe later some simple BEAM robots, and for younger hackers maybe it was a 3D printer or Arduino project.

Digital or analog, the common ground here is that we all thought that some project was cool enough to warrant the sweat of learning enough to do it. Good instructions are helpful of course, and having the parts on hand never hurts. But it’s the promise of making something that you really want that I think underlies all good first projects. (And heck, every subsequent project as well.)

So while Tom, and a bunch of our readers, were looking back with nostalgia at the 200-in-1, I’m thinking about how many more than 200 projects I’ve seen made by our community, and even featured here on Hackaday, that are out there to provide the motivation to get someone started. Keep on hacking!

Image

Fully Characterized Systems

A friend from my old hackerspace was in grad school for electrical engineering. He had a professor who would ask, when something went wrong with a student project, “Have you fully characterized the system?” It’s a good, if lofty, goal, but it also became an inside joke around the hackerspace because YOLO was our MO about 95% of the time. Head crashes on the 3D printer – “not fully characterized”. Forgot to take out the trash last weekend? Was the system fully characterized?

It’s maybe also the difference between theory and practice: In theory, there’s no difference between theory and practice, and all systems can be fully characterized. But in practice, it’s hard to fully characterize a system that you don’t yet fully understand.

Case in point: we have nine small saplings growing in our front yard, and I have to water them. It’s boring moving the hose from tree to tree, so I thought I’d take a length of hose, stopper it at one end, and drill enough holes in it so that it could irrigate all of the trees at once. I kinda characterized the system: I figured out how much water flows per minute through our hose, and divided that up into a reasonable outflow in my mind, and drilled holes that ended up being way too large.

Why? Because a length of hose has a resistance to flow, and the water came pouring out of the first few holes, while the last few were dry. It wasn’t a constant pressure system like I thought it would be. I hadn’t even thought that the drag in the hose would matter, so there was no way I would have tried to measure it. But how would I characterize this resistance anyway? You could make a hose with too-large holes and measure the falloff. (Oops, that’s exactly what I did.)

In retrospect, professional drip irrigation systems always have holes that are tiny relative to the pipe diameter, which avoids this pressure-drop phenomenon, which means that they don’t have to worry about characterizing the hose resistance. So that’s what I ended up doing. I cut the hole size in half, and later widened up some of the downstream holes until it looked about right. Not even close to fully characterized, but it works.

So now, in addition to the engineer’s “have you fully characterized the system?”, I have the hacker’s “can you avoid characterizing parts of the system?” in my mind. And a holey chunk of hose in the trashcan.

Supercon News

Just briefly, in case you missed it: Tickets are on sale now for Supercon Ten, and we’ve extended the call for participation by another two weeks. If you’re a Hackaday fan, you owe it to yourself to join us at our annual gathering.